Category: Application Performance Management/Monitoring

  • Keeping NoOps From Going Rogue

    Keeping NoOps From Going Rogue

    “We’re NoOps—everything is in the cloud and we have no infrastructure to manage.” Before running that victory lap and shifting everyone to the dev side, consider several NoOps risks carefully. I’m really thinking about teams using all-SaaS stacks, especially in martech, edtech and other areas. However, the rise in microservices and serverless means more teams are leaning toward NoOps. At least a few people on your team should always watch for rogue issues on the ops side of the equation.

    Locked-in Vendors

    Risk: Cloud-based tools in the same category rarely have the same functionality. Once one is selected, you’re committed to its specific features. Moving away from a tool may mean dropping a popular application feature or changing workflow with coding to recreate functionality.

    Mitigation: Evaluate unique features and customized data fields carefully before use. Solving data format differences is relatively easy for common fields. Look for tools with well-documented APIs and integrations or connector support for analytics. If there are no integrations out there, that’s a red flag.

    Ghosting

    Risk: Lock-in becomes a big problem if the vendor ghosts. SaaS startups often meet one of two fates: they are acquired or they crash and burn. A tool critical to your workflow may disappear overnight. In the acquisition scenario, you may have some time and support in migrating from your tool to its successor.

    Mitigation: Always have a Plan B for every cloud-based tool in your stack. Competitors are introducing new tools frequently. A trade study done two years ago may be completely obsolete on today’s fast-moving landscape. Proactive migration to newer solutions may reduce vendor risk and improve features.

    Limited Observability

    Risk: Overheard in a conference recently—Those who develop the code are more motivated to build in useful observability for those in operations if those folks are the same team. In NoOps, that’s not in play. If a cloud-based tool in your stack is down frequently or providing strange results, it may be very difficult to tell what is happening. Observability is often replaced by faith that the SaaS vendor has done its job and you aren’t experiencing a corner case it hasn’t tested.

    Mitigation: Observability and monitoring aren’t the same, but when you don’t have observability inside SaaS tools, monitoring helps. Application performance management (APM) tools are emerging with new ways to build instrumentation around microservices. Create test cases with synthetic data to check your functionality—you’ll need these to provide evidence for the vendor in any bug report.

    Unoptimized Workloads

    Risk: You’re also often at the mercy of the SaaS vendor when it comes to speed of results. It’s a common tripping point to pilot a SaaS workflow with a few users and test cases, and then find out it doesn’t scale when everyone is brought in.

    Mitigation: This is one the biggest NoOps risks where ops expertise pays off. Where is the problem, exactly? Application problems may be candidates for workload acceleration—such as running on a GPU (or FPGA) enabled cloud instance. Reporting problems may be better-suited for an analytics tool, which can be run offline with extracted data.

    Tangled Analytics

    Risk: Every SaaS tool reports different metrics in different ways. Worse, users in a multi-cloud environment face learning and visiting multiple applications to look at data. Different applications report similar facts using different terms. As the tool stack and data sets grow, it takes longer and longer to analyze data.

    Mitigation: Dashboards pay off early with one destination for data across the stack. Earlier, I mentioned the need for integrations or connectors—this should be a requirement for tool selection, both in the stack and the analytics tool. Deciding on which KPIs to track in the dashboard also focuses conversation and minimizes digging.

    Closing NoOps Risks

    There’s also the big topic of multi-cloud security and compliance, probably worth a series of posts by themselves. An Ops team working proactively in tool selection can comprehend many security risks before committing to tools and exposure. More value unfolds over time, as the security posture evolves with discovery of new threats.

    The tech pendulum is always swinging. For many organizations, NoOps swings the pendulum a bit too far from DevOps and leaves risks open. A better philosophy is MinOps, where a small team is deployed, watching for and even anticipating problems.

    I’d be interested to hear if you’ve tried NoOps and been successful over time, or if you reverted to a MinOps approach.

    — Don Dingee

  • TypeFox Ties Cloud-Based IDE to GitHub

    TypeFox Ties Cloud-Based IDE to GitHub

    TypeFox has launched a GitPod.io service that melds the integrated development environment (IDE) based in the cloud from TypeFox with the open source GitHub repository.

    Sven Efftinge, co-founder of TypeFox, said this level of integration will make it easier for developers to navigate multiple projects from which they pull code from GitHub into an Eclipse-based IDE.

    In addition, when developers open a Gitpod.io workspace, they will find that any build involving an update to an artifact housed in GitHub will have been automatically completed, said Efftinge. That will reduce substantially the amount of time developers spend waiting for build to finish, he noted.

    TypeFox collaborated with Google, Ericsson, Arm and Red Hat to develop the open source Eclipse Theia project, which provides a foundation for building IDEs in the cloud using TypeScript, CSS and HTML for a desktop-like user experience. At the highest level, Theia consists of a front end running in a browser or in the local desktop application and a back end running on any host or locally within the desktop application. Both the front end and back end communicate through JSON RPC over WebSockets. TypeFox then leveraged that project to build its own cloud-based IDE.

    Gitpod.io further advances the collaboration capabilities that are inherent of cloud-based IDE by adding the ability to capture and share snapshots of the development environment.

    Efftinge said following initial support for GitLab, the next effort will be focused on integrating Gitpod.io with the GitLab repository, which is used widely in traditional enterprise IT organizations.

    Regardless of the repository employed, more attention needs to be paid to reducing the daily friction developers encounter when developing applications. While best DevOps practices go a long way to accelerating application development and deployment, there a lot of wasted steps during the development process that, if eliminated, would increase developer productivity substantially. Of course, the more productive developers become, the more applications there are moving through the continuous integration/continuous development (CI/CD) pipeline.

    It’s still a bit unclear to what degree application development will move to the cloud. It’s certainly easier to streamline development process in the cloud. But many developers remain attached to individual workstations because they may not always be in a location that has reliable access to the internet. However, as application development—especially in the age of microservices—becomes more of a team sport, it’s clear that more application development is being pushed into the cloud. Pushing application development into the cloud also provides the benefit of reducing the number of high-end PCs and workstations an organization may need to acquire for its developers.

    Whatever the path chosen, it’s clear repositories such as GitHub and GitLab are now at the center of application development. Very few developers these days are writing raw code. Most of them are combining artifacts stored in repository to build their applications. The challenge organizations now face is bringing some consistency to what otherwise could easily become a chaotic process.

    — Mike Vizard

  • How to Modernize Mainframe Applications

    How to Modernize Mainframe Applications

    It’s easy to understand the current disillusionment around the term “digital transformation,” as it has been thrown around vaguely as the ultimate answer to business innovation without much recognition of the nuances of technological change.

    When it comes to mainframe systems, the issue here most likely can be traced back to the word “transformation.” The perceived challenge inherent in the transformation of a vital business process is that it involves a paradigm-shifting, instantaneous “big-bang” overhaul of IT, with no recognition of the complications involved in modernizing a complex web of intertwined systems and data.

    It is this perceived challenge that has seen large enterprises reluctant to change and modernize legacy technology, as the pressure to throw out the old and bring in the new is seen as simply too risky. Horror stories, such as the infamous failed IT upgrade at UK retail bank TSB in 2018, have dampened the spirit of many enterprises to modernize with the perception that a big transformative leap may be required.

    Many businesses seek a solution to this “all or nothing” conundrum and would benefit from modernizing legacy IT in small steps—carefully considering the modernization of infrastructure and applications as separate processes. This more graceful approach delivers gradual benefits while reducing risk and acknowledges that modernization is a continuum, not a destination.

    What is the Reality of a Modernization Process?

    Applications developed to support business requirements are never static; they change along with the business. Modern development environments, infrastructure and DevOps processes have benefited from tremendous innovation in recent years, enabling IT to more rapidly evolve applications to support these changing business requirements.

    There is mounting pressure to integrate mainframe applications, which house critical business processes with these approaches. The aim of this modernization is to enable legacy applications to take advantage of the innovations spearheaded by the modern world of open source—and, therefore, respond more rapidly to the needs of the business. To achieve this, organizations would benefit from a two-phase approach:

    1. Modernizing IT infrastructure: Moving legacy applications, in their original formats, to an environment where they can benefit from the scalability benefits of cloud deployments, exploit open source solutions and significantly reduce cost once legacy systems are replaced.
    2. Modernizing mainframe applications: Rewriting or transcoding into modern languages only those legacy applications or programs that are most in need of modernization, while enabling them to communicate with those still in legacy languages.

    Infrastructure Modernization

    The foundation of infrastructure modernization is the movement of legacy applications, written and compiled to run on the IBM Z mainframe, to the Linux operating environment running on x86 architecture computer, either on-premises or in the cloud. Using conventional methods to re-host these legacy applications into x86/Linux requires all programs that make up a legacy application to be recompiled and, in many cases, changed. This approach has often resulted in budget overruns and a high risk of failure.

    If an organization is able to move these applications and data to a modern environment without the requirement for recompilation or reformatting, this migration risk is significantly reduced.

    Once moved to a Linux environment, and despite remaining in original languages, these applications can now benefit from a vast array of tooling to optimize their ongoing exploitation. They can take advantage of cost-effective scaling options, modern monitoring, high-availability tools and many other facilities available on Linux on x86. For those legacy applications that continue to be maintained, modern development environments are now available, meaning their management is no longer restricted to a diminishing mainframe workforce.

    Application Modernization

    The goal of many companies is to have their entire application portfolio based on modern languages or packages. Where legacy applications are concerned, attaining this means converting the individual programs from COBOL or PL/1 (and, in some cases, even more arcane languages) into modern languages such as Java. In so doing, an organization can tap into much larger pools of development talent and tooling. Furthermore, the door to an entire world of open source innovation is opened, which alters entirely the trajectory of application development for these legacy applications.

    Yet modernizing mainframe applications in this way, using conventional methods, is not a process to be taken lightly.

    Infrastructure vs. Application: The Chicken or the Egg?

    When looking to modernize an application, many organizations question whether to start with the infrastructure or the application itself. The answer is infrastructure.

    Of course, the organization could attempt to first modernize the applications in place. At a glance this method may seem the least disruptive, but very quickly the effort would run into many of the challenges previously highlighted that have caused the mainframe to be abandoned as a contemporary platform for application modernization. Using a modern programming language such as Java is one way to enable modernization with those programs being completely rewritten. With the whole process conducted on a legacy mainframe, costs and resource contention become practical issues. Organizations that run mainframes carefully control access to mainframe resources due to the punitive costs of exceeding licensed capacity; indeed, this resource contention point is another reason for companies to move ongoing development off the mainframe.

    When taken collectively, it is easy to understand how these factors have conspired to thwart most modernization initiatives that choose to modernize applications first. By modernizing the infrastructure first, the issues identified above are circumvented.

    Once mainframe applications and data are re-hosted on modern, open environments on x86, Linux and the cloud, the real process of application modernization, as outlined above, can begin.

    The modernization journey is not easy, but continuing to depend on a declining skill set and diminishing vendor community in the mainframe world is no longer an acceptable alternative. By breaking up the modernization journey into manageable pieces, moving forward over time to the desired end state is the most realistic approach. After all, to quote a Chinese proverb, “A journey of a thousand miles begins with a single step.”

    — Dale Vecchio

  • Using Spark and Jenkins to Deploy Code into Hadoop Clusters

    Using Spark and Jenkins to Deploy Code into Hadoop Clusters

    This article illustrates how to deploy an application into a Hadoop cluster using GitLab/Jenkins/Spark application.

    In this article, we will cover the following:

    • Auto-triggering Jenkins build when code is committed in Git.
    • Pulling the latest code from the repository through Jenkins.
    • Building, compiling and packaging the “.jar” using SBT tool.
    • Uploading the .jar to the Nexus repository with defined version.
    • Pulling the versioned jar and dependent files from Nexus repository to server.
    • Deploying the versioned “.jar” file through Spark job into Hadoop cluster.

    Getting Started

    The following must be performed first:

    1. Download and install Java 1.8.
    2. Install Jenkins.
    3. Integrate GitLab and Jira.
    4. Install SBT.
    5. Create the Hadoop cluster: Hadoop and Spark.

    End to End Steps in Detail

    When a developer pushes code to GitLab, Jenkins will trigger a predefined job using webhooks.

    The Jenkins job will pull the code from version control using Git; it builds the code and makes the package as .jar file using the build tool SBT. This .jar file can be deployed into a Hadoop cluster with the help of a Spark command.

    Once the deployment is completed in the Hadoop cluster, the application will start running in the background.

    Initially, we can see the current running application in Hadoop (see Figure 1). It has an application ID, which is in a running state.

    Figure 1
    • If we click the tracking UI, which is Application Master, it will navigate into the Spark streaming page.
    Figure 2
    • In Figure 2, we can see batches are running in 40 seconds. For this scenario, we are changing from 40 seconds in the code.
    • When a developer makes changes to the code, he will commit in his local machine and test his code, then push to remote repository. I have updated steaming time from 40 to 50 seconds and committed.
    • If we can specify the Jira task number in the commit message, the same comment will be updated in the Jira task as below.
    Figure 3

    In the Jira application, we can see our commit message as comments.

    Figure 4

    GitLab and Jira integration process:

    • Install Git plugin to pull code from GitHub repository and SBT plugin to build and make a package as a .jar file in Jenkins.
    • Configure the Jenkins job under source code management and provide the Repository URL along with credentials and branch details.
    Figure 5
    • Optional: Set webhooks to automatically trigger the Jenkins job when the push happens in GitLab.
    Figure 6
    • In the “build” section, add the parameters clean compile package in the Actions field, which will build the code and create a .jar file.
    Figure 7
    • Once the job has been triggered in Jenkins, monitor the Jenkins console for the next step and errors, if any.
    Figure 8

    Optional: If we have configured SonarQube, it will analyze the code files and provide the result in the SonarQube dashboard. This allows us to know the code quality, code coverage vulnerabilities and bugs to improve efficiency of code.

    • Optional: To maintain the versioning, we can upload our *.jar into Nexus/Artifactory.
    • Once .jar has been created, we can keep it in a specific folder and trigger a Spark job. This can be performed by triggering a Spark command from Jenkins. Execute the below command to submit spark job:

    # spark-submit –name appName –master yarn –deploy-mode cluster –executor-memory 1g –driver-memory 1g –jars $(echo $dependencyJarDir/*.jar | tr ‘ ‘ ‘,’) –class com.coe.spotter.DQModule –conf spark.driver.extraJavaOptions=../src/main/resources/log4j-yarn.properties –conf spark.sql.warehouse.dir=./spark-warehouse –conf spark.yarn.submit.waitAppCompletion=false app.Jar


    • Once deployed, we can see the application ID number has been increased.
    Figure 9

    Timeout in the Spark streaming job has been increased to 50 seconds.

    Figure 10

    — Nodagala Nagarjuna

  • New Relic Accelerates AIOps with SignifAI Acquisition

    New Relic Accelerates AIOps with SignifAI Acquisition

    New Relic, following its acquisition of SignifAI, is in the process of accelerating its investments in machine learning algorithms and other forms of artificial intelligence (AI) as part of an effort to make it easier to separate the signal from the noise created by all the alerts in an IT environment.

    Aaron Johnson, senior vice president of product management at New Relic, said SignifAI represents an opportunity for New Relic to create a superset platform that can apply advanced analytics to a much wider range of data sources. SignifAI has already created more than 60 integrations spanning open source and commercial monitoring tools that are widely used across DevOps toolchains, he noted, adding that as New Relic moves to add other data sources, there’s an opportunity for the company to distinguish itself beyond providing software-as-a-service (SaaS) tools for monitoring applications and infrastructure.

    It’s obviously still early days for AI in the realm of DevOps. But it’s also clear that with the rise of microservices and containers, soon it will be impracticable for IT organizations to manually manage their IT environments. Various forms of automation based on AIOps platforms infused with machine and deep learning algorithms will be required. As a provider of SaaS-based tools for monitoring applications and infrastructure, New Relic already has access to vast amounts of data required to train AI models on optimizing a specific IT environment.

    Of course, there’s lots of competition across the IT monitoring category, so it remains to be seen which vendors will have the resources required to drive continuing investments in AIOps.

    In the meantime, DevOps teams will need to adjust their processes to take advantage of AIOps. It’s unlikely AIOps platforms will eliminate the need for DevOps teams, but the number of applications and platforms any DevOps team must manage effectively will increase substantially. Rather than replacing humans, AIOps platforms will reduce the pressure to hire additional IT staff when professionals with DevOps skills are already in short supply. The AIOps platform, for all intents and purposes, acts like a co-pilot.

    The biggest issue IT organizations are likely to encounter along that journey is establishing trust with any AIOps platform they implement. It takes a while for most AI models to learn the IT environment before that platform makes any reliable recommendations. In most cases, DevOps teams will have to dedicate staff to train and update AI models continuously as the IT environment changes. It may take years, however, before DevOps teams are comfortable enough to move beyond trusting a recommendation and enable an AIOps platform to automate processes on its own. After all, the only thing worse about being wrong about any IT decision is being wrong about it at scale.

    AI at this point is all but inevitable in DevOps environments. But it doesn’t necessarily follow that just because something is based on AI it always will be smarter than experienced DevOps professionals.

    — Mike Vizard

  • Datadog Acquires App Dev Testing Platform Madumbo

    Datadog Acquires App Dev Testing Platform Madumbo

    Datadog announced it is extending its reach beyond IT monitoring to include application testing by acquiring Madumbo.

    Madumdo CEO Gabriel-James Safar said it’s become increasingly apparent that application testing needs to be more informed by the metrics gathered by IT monitoring tools. The combined Datadog/Madumbo will bring intelligence to automated testing processes using both application and infrastructure data gathered via the Datadog platform.

    The Madumbo platform already makes extensive use of machine learning algorithms and predictive analytics to inject artificial intelligence (AI) into the application testing process. The more data those algorithms can access, the more precise the AI models become over time.

    That approach made it possible for Madumbo to build a bot that checks for errors using code running on a real browser, which Safar said means DevOps teams can capture the same defects as they are experienced by end users. That’s critical because much time is wasted by IT organizations that are unable to prioritize tasks to either identify the root cause of a problem or, arguably more importantly, prevent issues in the first place, said Safar. Because of that issue most organizations lack the time required to develop best-in-class DevOps processes.

    Datadog provides a complimentary set of IT monitoring tools that are consumed as a software-as-a-service (SaaS) application. That data will then become a trusted source for Madumbo, which in turn will increase confidence in the AI recommendations being made by Madumbo, said Safar.

    How many of those customers will wind up replacing whatever application testing tools they currently employ with Madumbo remains to be seen. But if Datadog can provide a more efficient approach to testing, testing tools may wind up driving organizations to replace their monitoring tools. Most organizations spend an inordinate amount of time trying to correlate data across tens of monitoring tools that often generate either conflicting alerts or alerts about issues the IT organization has already been informed of by another tool. Most IT organizations eventually will see the rise of AI platforms that will drive consolidation across the entire DevOps tools category.

    In the meantime, the more issues that get addressed during the application development process, the fewer number of problems that will raise their ugly head in production environments. In fact, it’s arguable the whole point of investing in best-in-class DevOps processes is not just to roll out applications faster, but also make sure those applications are of a markedly higher quality than previous generations of applications. That’s not going to happen, however, unless DevOps teams can derive actionable intelligence from the millions of alerts that get generated up and down the IT stack.

    — Mike Vizard

  • The Changing Role of APM in a Microservices World

    The Changing Role of APM in a Microservices World

    Microservices usage has skyrocketed. Fully 91 percent of organizations are using or have plans to use microservices and 92 percent expect to grow their use of microservices in the coming year. It is no longer if but when: 86 percent of organizations expect microservices to be the default within five years.

    With the growing use of microservices and containers, applications have become orders of magnitude more dynamic. It’s not unusual for containers or building blocks of the application to have a shelf-life of less than a week. However, what is great for application development can create challenges when it comes to monitoring ­and diagnosing performance issues in ever-changing applications. How does application performance monitoring (APM)  change to support microservices and dynamic cloud-native apps?

    More Moving Parts

    Small, specialized microservices may facilitate shorter development cycles, continuous releases and greater agility, but when deployed across dynamic cloud infrastructure, the sheer number of moving parts also makes it much more difficult to troubleshoot application performance. Highly distributed and transient containerized components need to be tracked and measured continuously, demanding a big data approach for APM tools. To be effective, monitoring containers and microservices requires high-definition visibility across all transactions, machine learning to pinpoint problems and a shift in focus to users from servers.

    High-Definition Data

    Because the dynamic, containerized environment is constantly changing, measurement data must be collected at high frequencies—think seconds rather than minutes. Collecting infrastructure performance metrics at one-minute intervals, or longer, can distort the real situation and sometimes miss entire events altogether. For example, at low definition, a pattern of recurring but brief spikes in CPU usage will either be averaged out or not register at all—but if detected would be a tell-tale sign of a systemic configuration issue. High-definition infrastructure metrics, collected at one-second intervals, are crucial for a comprehensive view of resource utilization and shared resource dependency issues.

    However, infrastructure metrics alone are not enough. Building a complete view of the operating environment calls for data from multiple sources, including application traces, system metrics, application logs and network behavior. The resulting data set is very large, necessitating big data collection methods and processes. In-line data compression, NoSQL back-ends, non-intrusive client agents and cloud scaling are foundational technologies for modern APM tools.

    Correlating Data End to End

    Big data analytics and visualizations are necessary to process APM data into human-scale patterns and events. Identifying root cause of a performance problem often involves following a transaction from end to end, through multiple containers, shared resources and downstream infrastructure dependencies. Next-generation APM tools dynamically map the flow of every single transaction, through all intermediate relationships. Machine learning and artificial intelligence, while still in their early stages, are proving essential to finding patterns and anomalies in the data, suggesting probable causes and flagging them for human investigation. Combining the best of machine and human skills results in faster problem identification, diagnosis and resolution. IT operations teams benefit with improved application performance, reduced repair times and higher uptime even in dynamic application environments.

    Putting the Focus on the End User

    Legacy APM tools tend to focus on infrastructure components and resources, monitoring the health and utilization of servers, storage and networks. Organizations today, driven by digital competition and customer satisfaction, need to concentrate on the user’s perspective. This means monitoring multiple types of user devices for health indicators and mapping each transaction to the backend system. Automatic instrumentation delivers real-time end user metrics that trigger alerts much earlier than server-side monitoring, and enables more effective prioritization. End user insights also help DevOps and product owners track feature and application adoption rates, compare performance before and after upgrades and directly relate technical issues and investments to business priorities.

    Monitoring Apps for Today and Tomorrow

    Clouds, containers and microservices require a different approach to performance monitoring that takes into account the speed, size and life cycle of application modules. Effectively watching these distributed and transitory processes demands a big data approach that can handle the scale of end-to-end transaction data in modern enterprise environments.

    Legacy APM tools that only take snapshots result in an incomplete view of application reality and lengthen problem resolution times. Instead, modern APM systems collect a complete data set, enabling DevOps to quickly resolve intermittent and complex issues that impact business productivity and user satisfaction. They augment their skills with machine learning to quickly identify anomalies and guide them to probable causes. The results are better application performance, enhanced competitiveness and perhaps most important, increased user satisfaction.

    — Gayle Levin

  • AppDynamics Applies AIOps to Automate IT

    AppDynamics Applies AIOps to Automate IT

    AppDynamics, a unit of Cisco, today announced it is melding the worlds of AIOps and application performance management (APM) with the launch of Cognition Engine.

    At the same time, AppDynamics is making good on a promise to integrate metrics drawn from Cisco Application Centric Infrastructure (ACI), the software-defined networking (SDN) that Cisco is embedding in all its networking equipment.

    Finally, AppDynamics also announced Serverless Agent for AWS Lambda, which marks the first time the company’s APM platform has been extended to include the ability to capture metrics from every single invocation of a serverless computing framework.

    Matt Chotin, senior director of technology strategy at AppDynamics, said Cognition Engine represents an ambitious effort based on machine learning algorithms and predictive analytics to create a central nervous system for IT spanning applications, infrastructure and the network. The days when applications and infrastructure were managed in isolation are now coming to an end, he said.

    Available at no extra charge to AppDynamics customers, Cognition Engine infuses the Business Transaction data model underpinning the AppDynamics APM services with machine learning algorithms to run diagnostics and automate root-cause analysis in a way that reduces resolution times from minutes to seconds. The machine learning algorithms evolve constantly as data is gathered continuously using streaming analytics to ingest, processes and analyze millions of records per second. The Cognition Engine automatically understands how metrics correlate and instantly knows when there’s been a break in correlation among datasets.

    Cognition Engine also automatically isolates metrics that deviate from normal behavior to identify the top suspects of root cause for any application issue. As an open platform, that information then can be shared with orchestration and automation systems embedded within third-party incident response, intelligent workload placement and cloud cost optimization tools and platforms.

    These types of capabilities are now becoming an absolute requirement because IT in general is becoming too large and dynamic to manage relying on manual processes, said Chotin, adding what’s needed is a shift toward an AIOps mindset that automates the management of routine IT tasks at scale.

    AIOps is, of course, not so much a thing that can be purchased as much as it is a collection of technologies spanning machine learning algorithms, predictive analytics and other technologies that are employed in unison to automate IT operations. It usually takes a while for algorithms to learn a specific IT environment. But once they do, they bring with them the benefits of a more sophisticated approach to managing IT at scale (and they never take a sick day or decide to take another job). Of course, AIOps is not likely to replace the need for IT staff entirely. But roles and functions within IT organizations most certainly will evolve in the months and years ahead.

    In the meantime, organizations will increasingly vet AI models before deploying them in production environments. While AIOps will advance the state of IT as it is known today, the most worrisome thing about any form of current AI technology is being catastrophically wrong at a level of scale that is nearly impossible to recover from.

    — Mike Vizard

  • xMatters Incorporates Stackdriver APM Metrics from Google

    xMatters Incorporates Stackdriver APM Metrics from Google

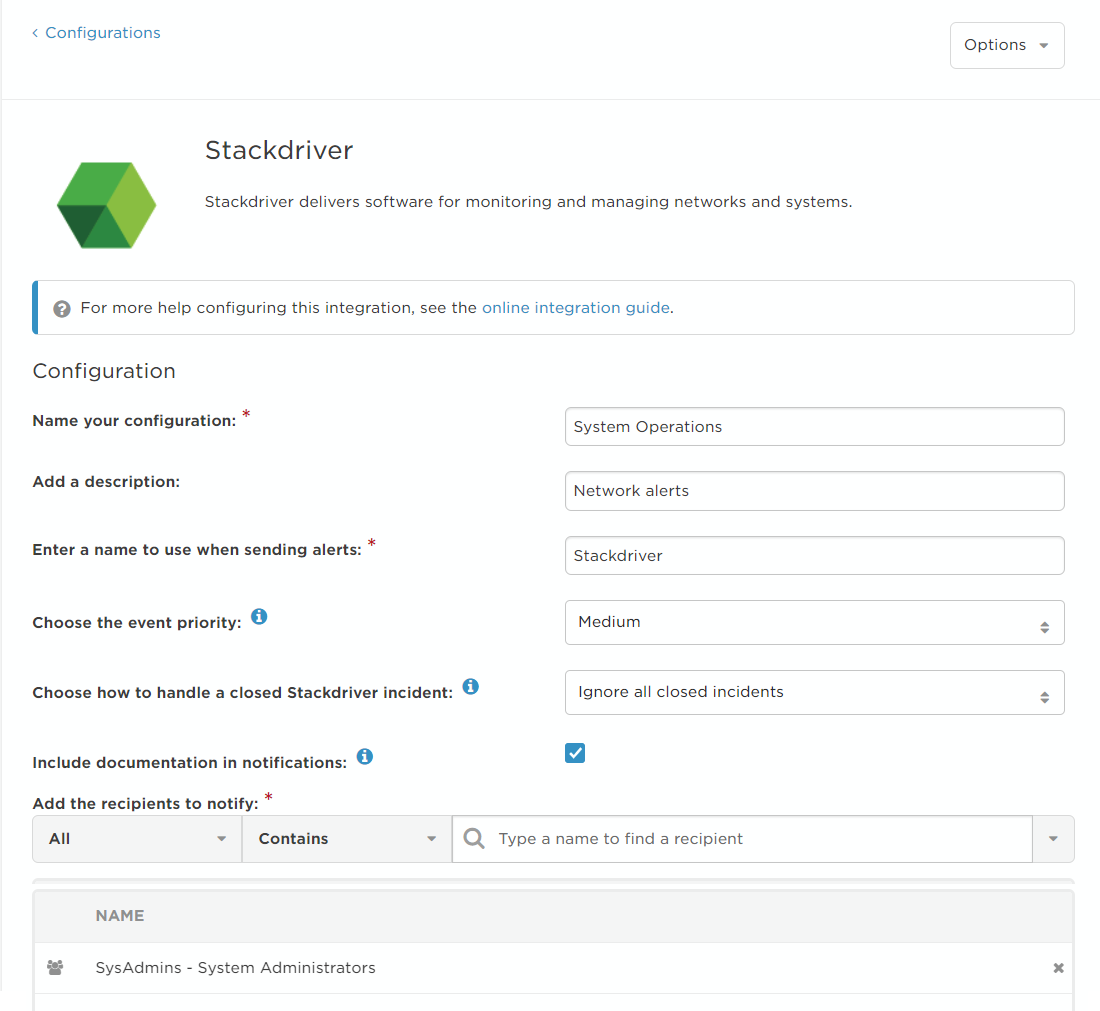
    As a set of application monitoring services on the Google Cloud Platform (GCP) for driving DevOps processes, Stackdriver has been steadily gaining adherents, especially since Google extended the reach of that service into the realm of on-premises systems. Today xMatters, a provider of incident management tools, announced it is integrating alerts and data generated by Stackdriver into its workflow processes.

    Company CTO Abbas Haider Ali said the xMatters incident management software will now automatically relay Stackdriver data to the correct people and systems to help coordinate and resolve incidents faster. Stackdriver insights will be embedded into notifications, collaboration invitations and service management tickets, said Haider Ali.

    The goal, he said, is to provide DevOps teams with more context concerning specific issues directly within the user interface employed to access the incident management platform.

    Google, via Stackdriver, not only provides access to a tool for application performance management (APM), it also effectively embeds best practices for site reliability engineers (SREs) inside the service. While the best practices defined by Google are highly opinionated, they are starting to gain traction as a specific methodology from implementing a DevOps process, said Haider Ali.

    Support for Stackdriver follows the recent release of an update to xMatters that added an Event Flood Control capability to suppress similar requests in close succession as part of an effort to reduce the level of noise generated by a single incident. The company also added an Unlimited Event Visibility feature allows organizations to unlock insights from past incidents to identify a potential root cause of a problem faster.

    Of course, while Google may have invented the SRE concept, it is clear other cloud service providers are coming up with their own flavors and many internal IT operations teams will likely create their own equivalents. But as the SRE concept continues to gain traction, the rate at which DevOps processes are adopted enterprisewide should increase. The challenge most enterprise IT organizations face today is their internal teams are largely made up of administrators rather than engineer that know how to programmatically manage infrastructure as code. Many of those organizations are either hiring former developers to become SREs, or investing in training to up level the skills of their existing IT administrators.

    But as more organizations embrace SRE concepts many of them will be looking to create closed-loop approaches to DevOps that enables them to significantly reduce the amount of time between when an issue or incident is discovered, and it gets assigned within a continuous integration/continuous deployment (CI/CD) environment to be programmatically addressed.

    In the meantime, any gaps that may have existed between DevOps processes and incident management systems are continuing to narrow. Not every organization necessarily has to hire SREs to achieve that goal. But those organizations that can afford to hire and retain SREs should expect they will insist on incorporating incident management with the context of a larger set of sophisticated DevOps processes.

    — Mike Vizard

  • Kong Applies AI to API Management

    Kong Applies AI to API Management

    Kong today announced today two offerings that rely on artificial intelligence (AI) to automate the management of application programming interfaces (APIs).

    The first offering, dubbed Kong Brain, collects data from any existing platform to auto generate documentation, which can then be used to automate the configuration of the Kong Enterprise API management platform.

    The second offering, dubbed Kong Immunity, leverages machine learning algorithms to analyze traffic patterns to first define normal traffic and then train models to automatically detect any anomalies and issue alerts when those anomalies are detected.

    Kong CTO Marco Palladino said Kong Brain is intended to make it easier to manage APIs across a modern IT environment by making it possible to continuously reconfigure APIs as new code is added to any platform connect to Kong Enterprise.

    In addition, Kong Brain makes it simpler to visually map services and their endpoints to provide deeper visibility into API traffic and the health of any given service, said Palladino.

    Kong Immunity, meanwhile, enhances the overall security of the IT environment by identifying potential threats before they proliferate across the API ecosystem, he notes.

    Available under an early access program, Kong Brain and Kong Immunity represent the first steps toward employing AI to layer a central nervous system that automates governance, security ad documentation while increasing the reliability of the overall API ecosystem, Palladino said.

    As microservices specifically and IT in general continue to evolve, the number of dependencies that will exist across the IT environment will far exceed the ability of any IT staff to manage manually. That issue will become especially acute as more organizations embrace applications based on microservices, Palladino said, because each microservice within that application has its own set of APIs that need to be managed. While Kong Enterprise can support both microservices and traditional monolithic applications, Palladino expects the proliferation of microservices across multiple cloud platforms to force the need to adopt API management platforms infused with AI.

    Obviously, the introduction of AI into IT environments will have a profound impact on API management and associated DevOps processes. While developers typically create APIs, responsibility for managing APIs has been shifting to IT operational teams. By adding AI to API management platforms such as Kong Enterprise it should become significantly easier for any enterprise to manage APIs at scale. Of course, AI models don’t work out of the proverbial box. But as the machine learning algorithms that drive those AI models become more familiar with the IT environment, the more automated the management of the APIs distributed across that IT environment becomes.

    What impact AI will have on DevOps processes remains to be seen. But it’s increasingly clear that AI will be applied across the IT operations spectrum. In theory, the more automated IT operations becomes the more resources any organization should be able to shift toward developing more applications, which naturally generates more APIs to be managed. It may take a little more time before most organizations have enough confidence in AI to make that transition. But at this point, it’s not so much a question of whether AI will be applied to IT operations as much as it is to what extent.

    — Mike Vizard