Category: Application Performance Management/Monitoring

  • Cortex Taps GitLab to Help DevOps Teams Manage Microservices

    Cortex Taps GitLab to Help DevOps Teams Manage Microservices

    Cortex, a provider of a platform for tracking ownership of microservices, this week announced its platform can now import services from the GitLab continuous integration/continuous delivery (CI/CD) platform.

    Anish Dhar, Cortex CEO, said the company’s platform is now integrated with more than 30 tools that are regularly employed by DevOps teams, including offerings from GitLab, Datadog, Sonarqube, Snyk and PagerDuty, as well as open source platforms such as the Kubernetes container orchestration engine and the Istio service mesh.

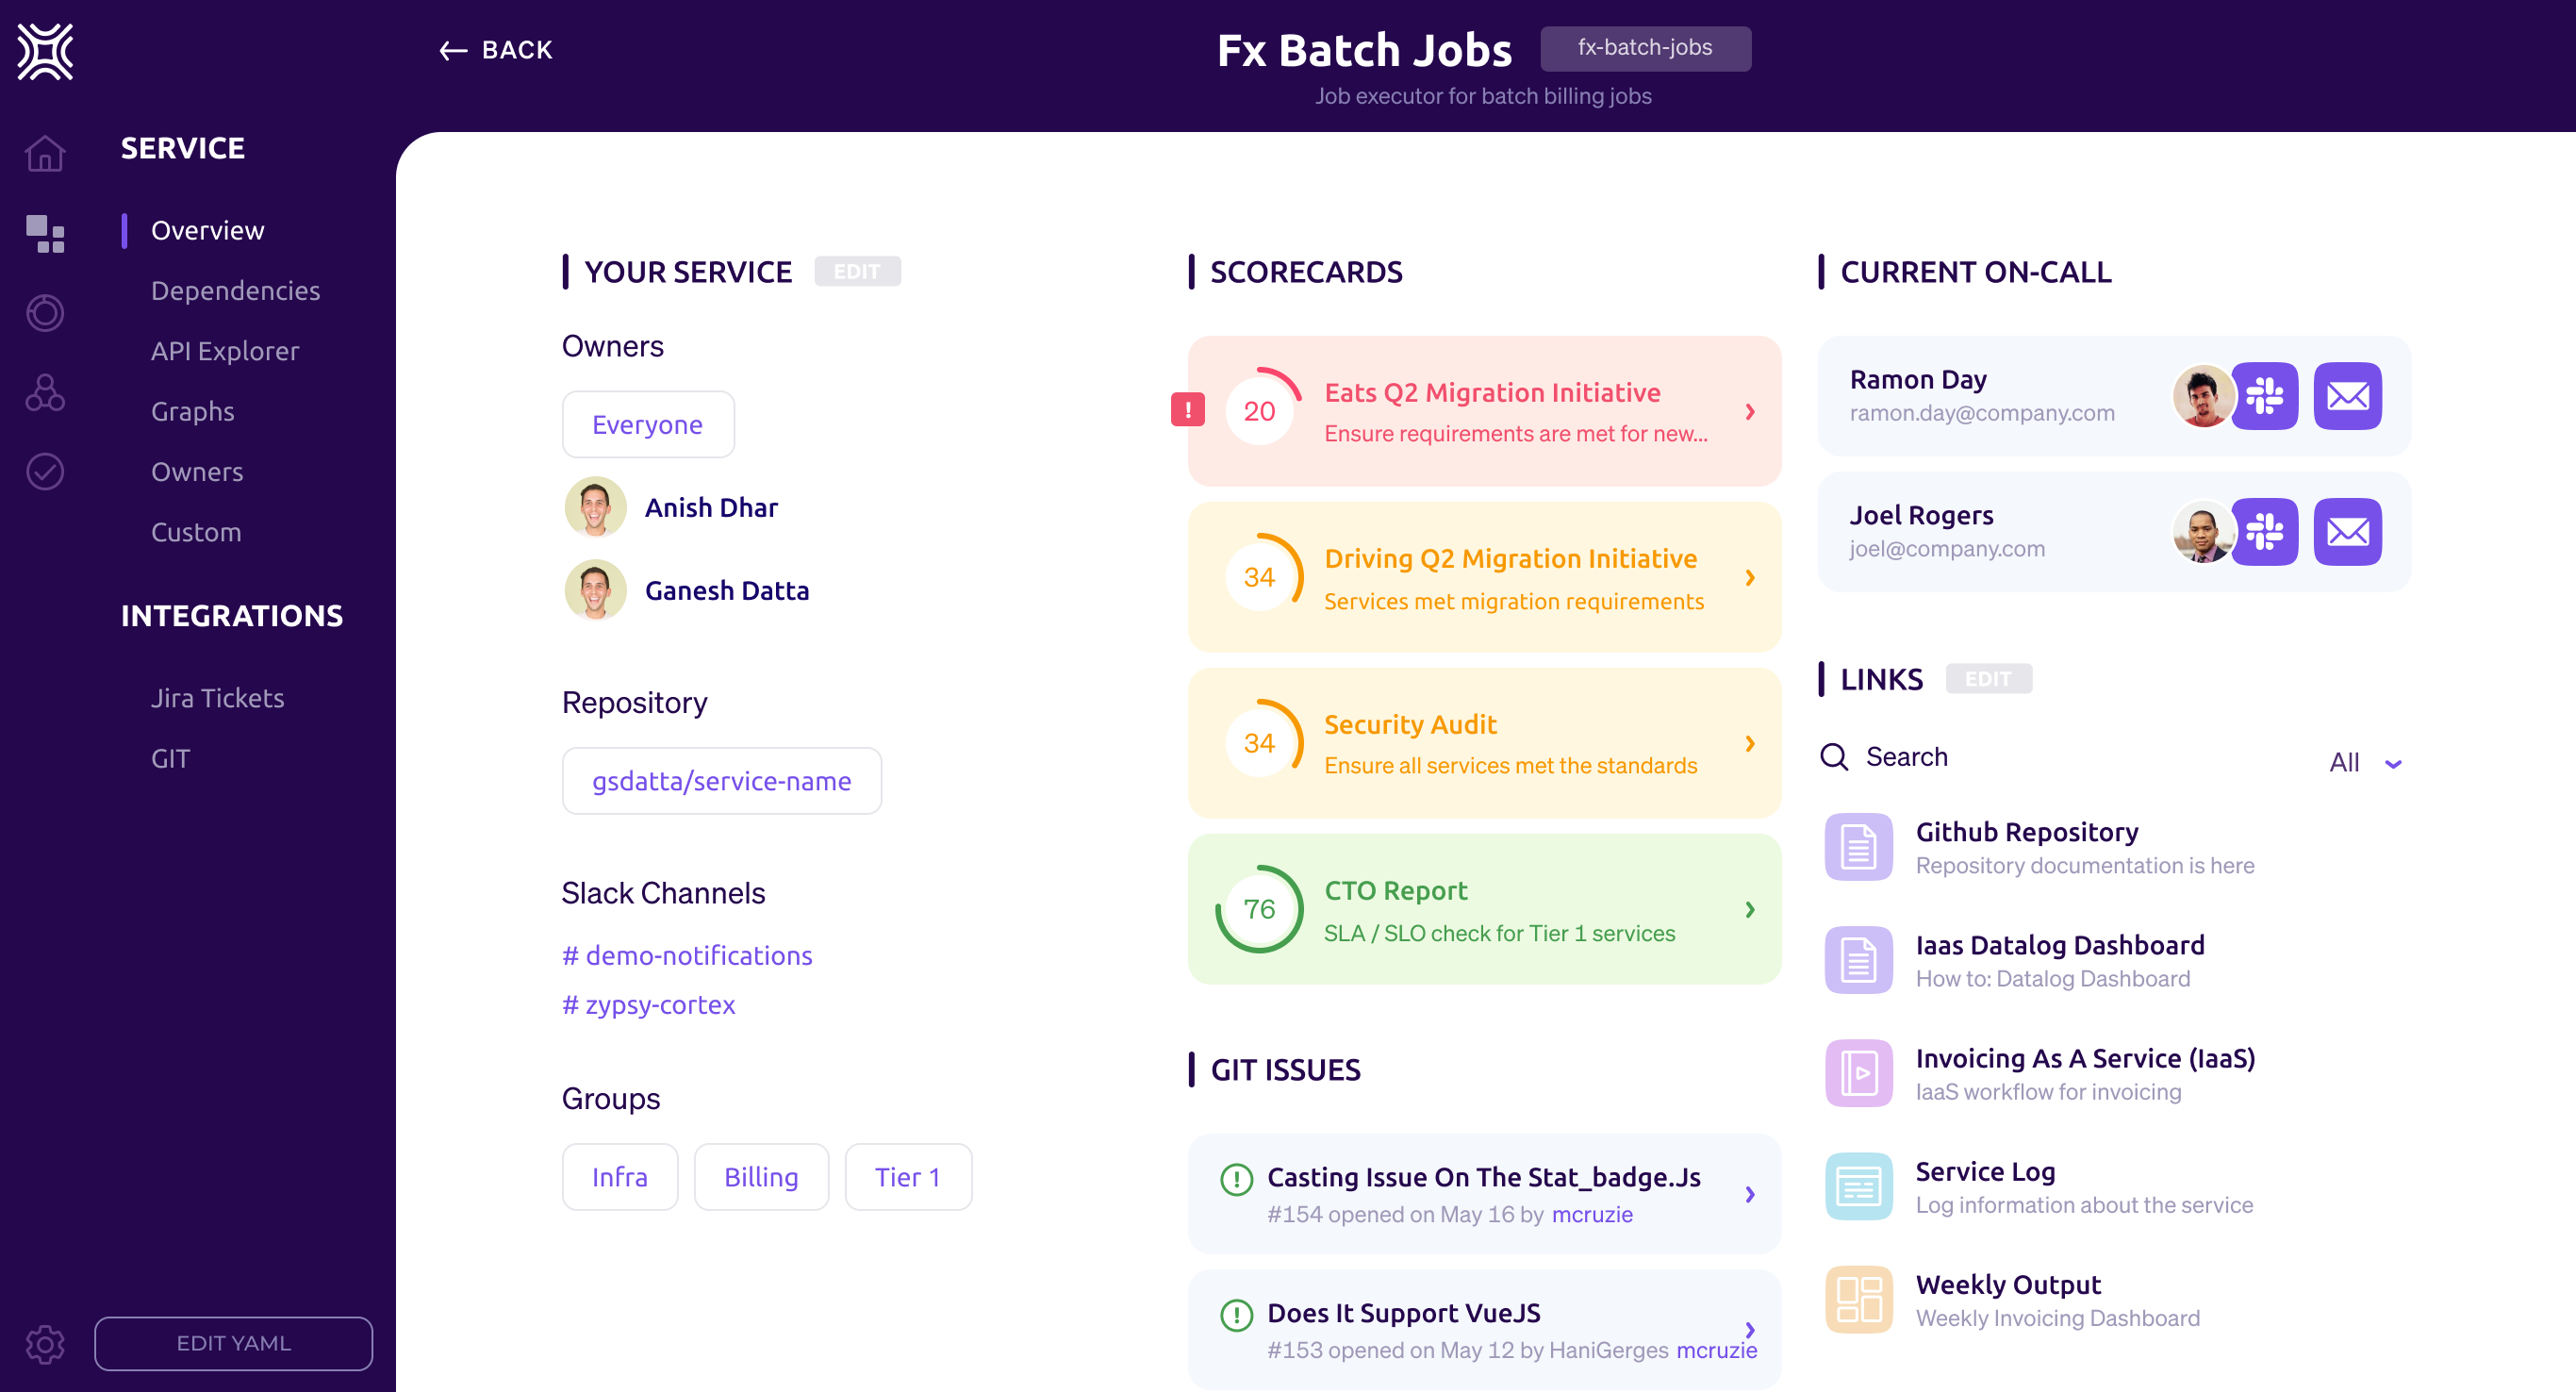
    Designed for site reliability engineers (SREs) and other DevOps professionals, the Cortex platform eliminates the need to rely on spreadsheets to manually track ownership of microservices. Instead, Cortex imports data residing within the tool employed by developers to surface who within an organization is responsible for maintaining which microservices.

    In addition, a Cortex dashboard enables DevOps teams to see which developers are on-call in the event of an unexpected incident, the latency rate microservices are experiencing and which vulnerabilities have yet to be remediated.

    Grades can also be assigned to specific microservices based on metrics that are associated with a specific microservice. That approach allows DevOps teams to apply gamification techniques using a scorecard to encourage developers to continuously improve their microservices, noted Dhar. That approach will also make it apparent to other developers which microservices running in a production environment can be most reliably employed, added Dhar.

    Cortex

    At the core of the platform is Cortex Query Language (CQL), a domain-specific language that allows DevOps teams to define granular rules that can be applied to, for example, on-call rotations, security vulnerabilities, package versions, service level objectives (SLOs) and the overall health of the microservice. Engineers can employ code in the form of YAML files to set reliability standards across teams and types of services through direct integrations with a variety of tools. In effect, Cortex provides a reliability-as-code platform, said Dhar.

    As responsibility for applications shifts further left, each development team is being held accountable for the life cycle of any microservice or application they create. The challenge enterprise DevOps teams are encountering is that when there are hundreds, even thousands, of microservices, it’s difficult to determine who on the development team is responsible for a specific microservice. Rather than trying to keep track of the relationship between development teams and microservices using a spreadsheet, Cortex is making a case for a tool that automates that discovery and tracking process.

    Most organizations today are embracing microservices to build and deploy more flexible applications at varying rates. However, it’s only a matter of time before they find themselves trying to navigate a web of interdependencies between microservices that can’t be managed using spreadsheets. DevOps teams, of course, might be inclined to use their skills to create their own tool for tracking microservices. However, given all the tasks at hand, maintaining a custom platform for discovering and tracking ownership of microservices is likely something better done by a vendor willing to maintain and support a purpose-built tool.

  • How to Gain Greater Value From DevOps

    How to Gain Greater Value From DevOps

    DevOps is more than just deployment and management. Fully leveraging the DevOps team and their activities can actually enhance operations and improve customer satisfaction.

    Be Proactive, Rather Than Reactive

    Say you deploy a new version, encounter some problems and then react. What if you could stay at least a step or two ahead by becoming more proactive?

    Check your metrics and look for trends. You can spot rises in error rates or latencies over time and identify problems just as they are bubbling up. Ideally, you’ll identify them when they are merely minor issues, not when you’re already required to hit the panic button or roll back. Looking ahead to see what’s around the corner puts you in a much better place.

    Use Feedback to Improve Operations

    While it’s true that investing time and resources to automate tasks, such as deployment, is a good thing, it’s even better to focus on another high-value DevOps activity—bringing insights from operations into your development pipeline.

    Incorporating feedback and ideas into your processes puts you in a much better place, especially because there are already tools out there to help you do those deployments and other tasks pretty easily. For example, once you’ve packaged your application into a container, you just need to push a few buttons to set up automatic scaling, load balancing and routing. With all of that automated, you can focus on what’s really important—your application.

    Track Customer Behavior

    Here are two gems—both easy to set up and use, from the same GitHub author—that you can use to track your customers’ behavior, monitor usage and get better insights to improve operations.

    Ahoy—Use this to track user visits to your web page to determine specific named events that you want to add to your code. You can do this from either the server side and a controller, from JavaScript, or via a simple API. It uses two tables that you can easily query, plus some smart built-in data visualization capabilities.
    Blazer—Use this to gain visibility to your database by just adding a mount point to your routes file so that you can access the web application. It provides an easy interface to do SQL queries and show the results.

    Check the Metrics Often

    Once you get these tools set up, don’t stop there. Check the metrics—weekly if possible—and see what the trends are. Ask questions. The cool thing about operations—unlike engineering and writing software where you’re trying to solve one problem—is it’s not always well defined. You may not even know what questions to ask at first. However, diving into the metrics and seeing what patterns emerge from the use and events will not just benefit your customers, but also feed back into your development cycle. This empowers you to go back and reevaluate decisions made earlier on and learn where you should direct your attention and energy going forward.

    Be sure to enhance your focus on where DevOps can actually take you. It’s not just about writing automation and deployment scripts. The synergy of analysis and software is the future of DevOps.

  • Why API Quality Is Top Priority for Developers

    Why API Quality Is Top Priority for Developers

    It is no secret that web APIs have become increasingly important to the operation of modern businesses. According to RapidAPI’s Developer Survey and Insights report, 61% of developers used more APIs in 2020 than 2019, with 71% planning to use even more in 2021. We are no longer tied to a small number of monolithic service providers. Businesses tend to gravitate toward specialized managed services, such as billing and authentication, which are backed by APIs. Business models for new products and services are constructed based on APIs. Trust has become a necessity for APIs. APIs that perform consistently and with high quality earn trust, and those that do not are abandoned for a competitor.

    Why Does Quality Matter?

    If a market exists for an API, it’s a given that there will be competition. To remain competitive, APIs must build and maintain trust with their consumers; sales and marketing can only go so far. The highest quality APIs will inevitably capture the largest slice of market share. Quality isn’t a destination, either—it is a collection of goals that require continuous investment.

    What Does Quality Mean for an API?

    Just like the code that drives an API, the quality of an API itself is quantifiable. The following facets describe some broad categories used to measure API quality. The weight of each facet will vary depending on how business-critical the API will be when in production.

    Resilient. An API is resilient when it continues to operate in the face of adverse conditions. Can an API continue to operate (even at reduced capacity) if the database is down? How does it handle network traffic spikes?

    Robust. A robust API is liberal in what it accepts, but conservative in what it sends. Will it crash when presented with a poorly formatted request, or respond with instructions on how the caller can fix the problem themselves? Can the code be restructured without breaking the API contract?

    Secure. API security is vital in most deployments. Are efforts made to check for OWASP Top 10 Web App security risks? Are open source vulnerabilities known and addressed in a timely manner? Are secure endpoints gated with authentication?

    Discoverable. APIs that are well documented and well structured are much easier to consume and integrate with other services.

    Consistent. A consistent API is one that changes without negatively impacting existing consumers. Changes are backward compatible or versioned as new features are introduced. API consumers should know far in advance if a breaking change will be coming if it cannot be avoided.

    How Do I Get There?

    Processes, tools and, most importantly, culture, are the key to high-quality APIs. Let’s explore how we can approach each API quality facet.

    Resilient. Processes such as chaos engineering, load testing and manual quality assurance can uncover situations where an API is failing to handle unexpected situations. Deploying your API to a cloud provider with a compelling SLA instead of your own hardware and network shifts the burden of infrastructure resiliency to a service, freeing your time to build features for your customers.

    Robust. A comprehensive suite of automated tests isn’t always sufficient to provide a robust API. Edge cases, unexpected code branches and other unplanned behavior may be triggered by requests that were not considered when writing the test suite. Traditional automated tests should be complimented by fuzz testing to help uncover hidden execution paths. Canary and blue-green deployments can further expose your API to the real world in a limited manner and prepare for when even more unexpected requests will hit.

    Secure. API security is a moving target. It is expected that most APIs are built on layers of open source libraries and frameworks. Software composition analysis is a necessity to stay on top of zero-day vulnerabilities by identifying vulnerable dependencies as soon as they are discovered. OWASP guidance is a must-have—directing API developers to implement attack mitigation strategies such as CORS and CSRF protection. Application logic must be well tested for authorization and authentication.

    Discoverable. For REST APIs, the OpenAPI initiative provides a consistent language for describing the API. Many frameworks, such as Spring Boot, can even generate OpenAPI documentation directly from your code. gRPC-based APIs offer similar benefits by providing both instructions for accessing the API and building the clients to communicate with it. Adding support for GraphQL allows developers to connect multiple APIs together with consistent tooling. Whichever direction you choose, it is vital to keep API documentation up to date and accessible.

    Consistent. To be consistent, the API development process should make incompatible changes obvious. Code reviews can catch many breaking changes right at the source. API contract testing and integration testing can be used to discover API changes as part of the build. When working in a microservices environment, staging environments may alert engineers if an API change will cause problems before production.

    Quality Builds Trust

    According to the RapidAPI survey, 58% of executives said participating in the API economy was a top priority for their organization. The figure was even higher in certain industries such as telecommunications, where the number is 89%. Whether you are building APIs for internal use or for public consumption, your goal should be to earn the trust of API consumers. Investing in the culture, tools and processes to build quality APIs will pave the way to building and maintaining that trust.

  • Observe Seeks to Put More IT Metrics in Context

    Observe Seeks to Put More IT Metrics in Context

    Observe, Inc. announced today it has updated it observability platform to add support for metrics based on time series data. In addition, the company is revamping how the platform generates alerts as part of an effort to surface more actionable intelligence.

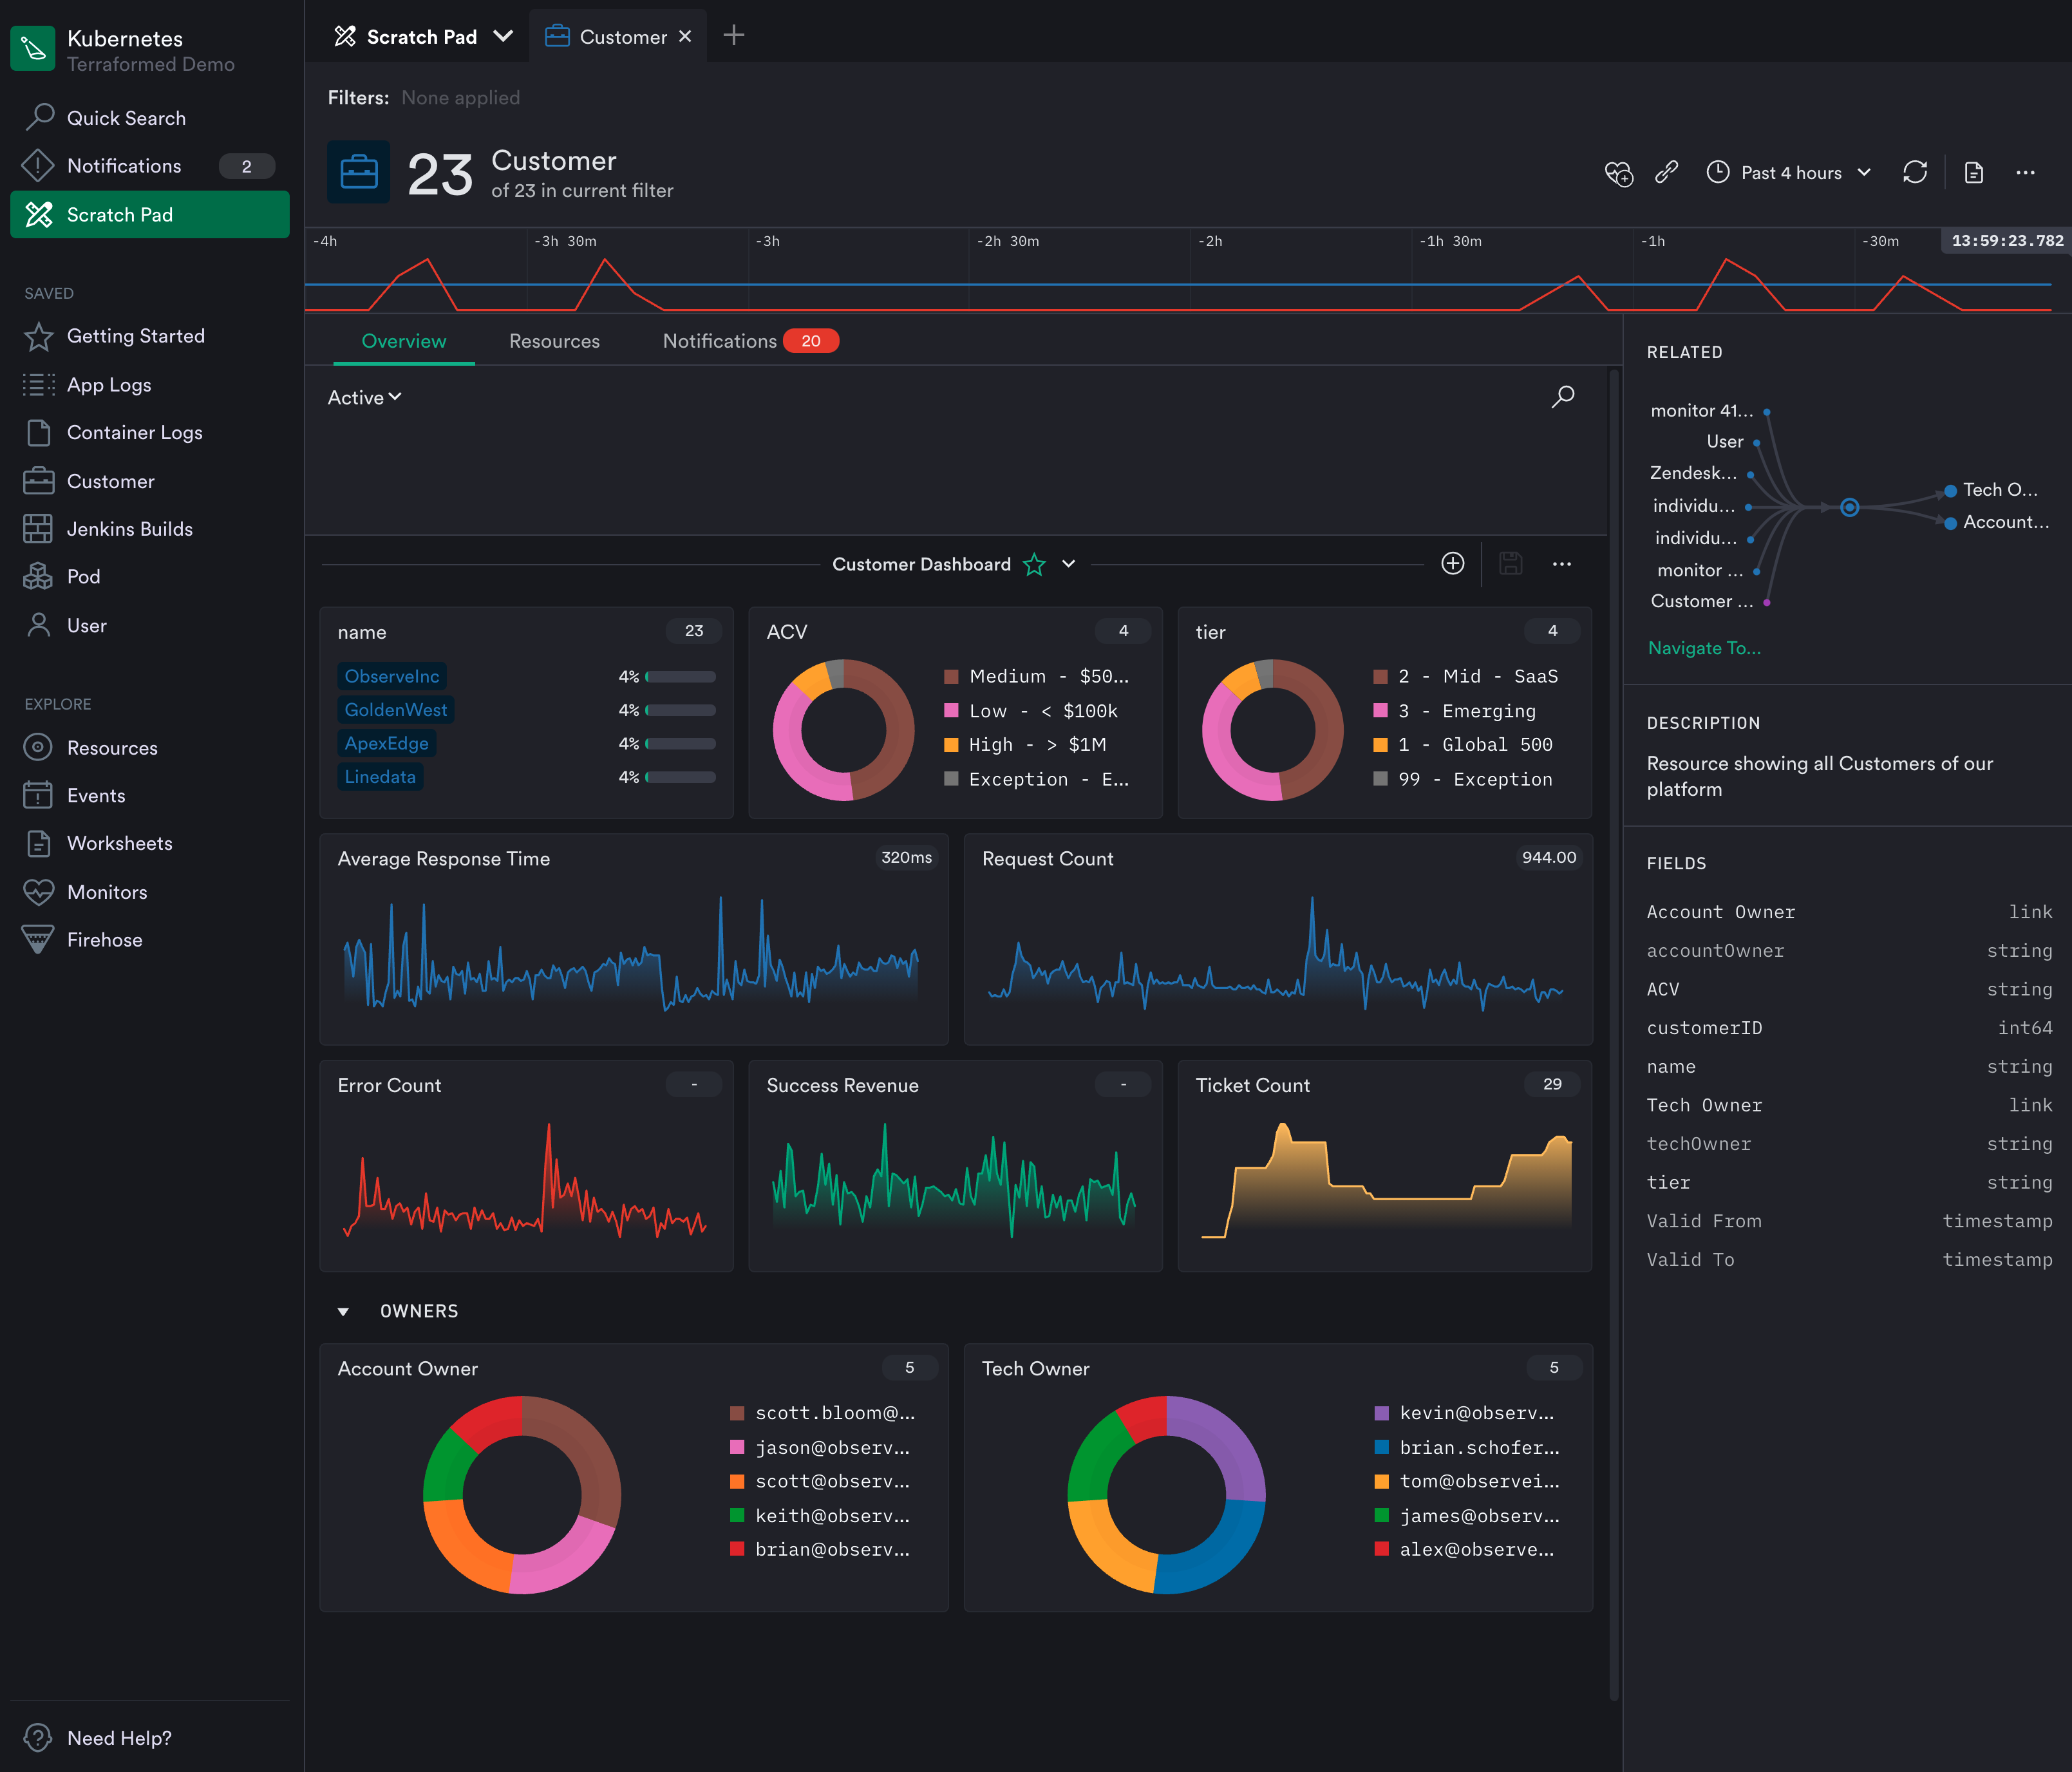
    Jeremy Burton, Observe CEO, said rival observability platforms require IT teams to sift through hundreds of metrics that are generated using elaborate tagging schemes that ultimately drive up the cost of storage. The Observe platform curates metrics by associating them with, for example, a customer, to provide more relevant context, Burton noted.

    That approach eliminates the need to present IT teams with overwhelming lists of metrics in addition to reducing storage costs by removing the need for a complex tagging scheme, added Burton.

    The latest update leverages that approach to metrics to only generate alerts based on curated metrics attached to customers, pods, shopping carts or containers. Rather than simply being alerted to a drop in response times, for example, the IT team can also easily see which customers or pods might be affected. That shift will reduce the volume of alerts that are already overflowing in email inboxes and across other communications platforms.

    Fresh from raising an additional $7 million, Observe today also revealed it has added 20 paying customers since launching the platform on top of the Snowflake cloud service residing on the Amazon Web Services (AWS) public cloud. Rather than reinventing the same core infrastructure, Observe is leveraging a data analytics engine that is already widely employed in IT environments.

    For now, Observe will continue to primarily focus on metrics as part of an effort to deliver insights in a form IT operations teams are prepared to consume today, said Burton. Over time, however, Observe will add support for distributed traces via tools such as OpenTelemetry and Jaeger as it adds additional application performance management (APM) capabilities, added Burton. Rather than telling IT operations teams they are managing IT in the wrong way, the goal is to meet IT operations teams where they are today, noted Burton.

    That strategy also enables the Observe platform to be employed to manage both monolithic and microservices-based applications running on Kubernetes clusters, noted Burton. The immediate goal is to provide IT teams with an alternative to legacy monitoring tools that provide more context at total lower cost by allowing IT organizations to rationalize tools that don’t tend to be especially well integrated, added Burton.

    In the longer term, Observe will also employ machine learning algorithms to collect data more efficiently. However, Burton said the company remains skeptical of visions of an IT future that depend on machine learning algorithms to continuously learn IT environments that are not only unique, but subject to frequent changes.

    Competition among observability platform providers is already fierce. Each IT team will need to decide what type of platform makes the most sense for them based on costs and their preference for specific capabilities one vendor might have that another doesn’t provide. One way or another, however, the way IT environments are managed will soon be changing for the better.

  • Leveraging AI in DevOps for Non-Linear Scaleup

    Leveraging AI in DevOps for Non-Linear Scaleup

    With technology evolving in leaps and bounds, AI is shaping the future of digital transformation for every business seeking speed, scalability, quality and flexibility.

    Since DevOps is on the verge of delivering exceptional software development environments, DevOps in AI is undeniably the next breakthrough in technology. We’ve witnessed every industry racing toward the adoption of AI to transform their business. To support this transformation, smart automation solutions coupled with AI implementations is becoming the new normal.

    So if you’re thinking about reinforcing your enterprise’s DNA by leveraging AI, DevOps principles for artificial intelligence are vital to these efforts. Here’s how businesses can unlock the true potential of AI and stay ahead of the curve.

    DevOps and AI

    DevOps has been s game-changer for numerous businesses. Applying AI can helps DevOps teams achieve the operational efficiency of machine learning (ML) models all the way through the journey from design to production.

    Artificial intelligence undeniably enhances automation and fast-tracks the performance of DevOps. Since the digital transformation process is quite challenging for diverse businesses, DevOps and AI ensures the right processes are in place that can further bring flexibility throughout the journey.

    DevOps enables continuous deployment and quick delivery of AI models via:

    • Speed: Improved overall development and delivery time by reducing unnecessary activities
    • Scalability: On demand and auto-scaling AI models
    • Quality: Boosting cleaning datasets and eventually promotes consistent learning that further enhances AI
    • Data monitoring: Decision making and computing helps handle huge amount of data with precise data monitoring

    Benefits of Integrating AI in DevOps

    There are endless benefits to integrating AI in DevOps.

    Analysis

    Data analysis is the key to business success, especially in times when there’s a huge list of competitors rushing to gain consumer trust. Since DevOps produces an enormous amount of data, it isn’t practical for humans to analyze the data without technological intervention.

    Artificial intelligence’s smart analytics eases the process by identifying and solving problems in a
    more systematic way, resulting in efficiency and increased consumer satisfaction.

    Data Correlation

    In the wider technology environment, development teams have their own set of issues and errors, which arrive while monitoring the processes. Since the communication scope is minimal and there’s a lack of mutual learning across teams, artificial intelligence can help to accelerate the learning cycle.

    Artificial intelligence helps to improve data insights from multiple platforms, which, in turn promotes better communication and establishes better data correlation.

    Failure Handling

    Machine learning is paving the way to better error resolution based on data, and eventually artificial intelligence will be able to predict signs of failure by examining patterns. Since humans cannot match the observation capabilities of AI, certain indicators of failure can only be analyzed through AI. This further enhances the overall development processes, as quick identification helps identify issues before they can impact the software development life cycle.

    Breaks Down Silos

    DevOps with AI has the ability to streamline business processes and establish proper communication among diverse systems, removing barriers that slow down the development and deployment processes. Furthermore, the ability to automate, continuously integrate and enhance communication helps business leaders to focus more on other aspects that can further accelerate business growth.

    Economic Growth

    Since the basic function of an AI-based model is automation, it can help businesses save money and enhance human resources. For any business, eliminating repetitive human work is a tough nut to crack. but a necessity when businesses are demanding continuous innovations. Artificial intelligence could be the best way for enterprises to cut costs and eventually helps the organization to use human resources more creatively and productively.

    Makes Software Intuitive

    Besides endless business benefits, AI-based software is more intuitive and user-friendly, since it prioritizes the reduction of human error. While DevOps is a well-known, reliable, business-driven approach for delivering software, intermingling artificial intelligence could enhance the user experience by integrating technology more deeply into the system.

    The perfect harmony of simplified interactions between humans and AI helps businesses achieve their desired goals of speed, efficiency, scalability and security.

    AI-driven systems are providing promising and scalable solutions for enterprises that are on a hunt
    for innovative and rapid ways to scale business growth. AI in DevOps is undoubtedly the best solution for accelerating growth through precise monitoring, automation and process improvement. This is the right time for businesses to ensure they operationalize artificial intelligence as a core business objective to stay ahead of their competitors.

  • Grafana Labs Advances Open Source Visualization and Observability

    Grafana Labs Advances Open Source Visualization and Observability

    During the online GrafanaCONline conference today, Grafana Labs announced that version 8.0 of its open source visualization software widely employed by DevOps teams is now generally available. In addition, version 1.0 of Grafana Tempo, an open source back end platform for collecting distributed traces that are needed to drive observability across an application environment, is also generally available.

    At the same time, Grafana Labs revealed that Grafana Tempo is now available as a service on Grafana Cloud.

    Version 8.0 of Grafana adds support for additional types of visualizations such as streaming panels, state timeline, status history, bar chart and histograms in addition to a revamped unified alerting system that enables DevOps teams to view and edit alerts generated by Grafana and open source Prometheus monitoring platform via a common user interface. The notification system adopted to achieve that goal is based on a Prometheus alert manager that provides capabilities such as grouping, deduping and silencing of notifications alongside advanced message templates.

    The latest release of Grafana also improves startup and graph rendering performance, thanks to a major reduction in initial download size and graph rendering time.

    The enterprise edition of Grafana has also been updated to provide support for fine-grained access controls, improves caching of back end data sources and improved reporting capabilities such as live dashboard links that can be embedded in email.

    Overall, Grafana Labs claims there are now more than 750,000 active installations of Grafana that organizations are employing to create visualizations that correlate data collected from multiple back end sources.

    In addition to contributing to Grafana and Grafana Tempo, the company is running a cloud service that makes multiple instances of Prometheus running on different clusters accessible from a central console.

    Torkel Ödegaard, creator of the Grafana project and chief Grafana officer for Grafana Labs, said Grafana Tempo promises to further advance observability thanks mainly to its ability to employ object storage to capture complete distributed traces. Rather than only sampling traces, it’s now feasible to trace every request. Grafana Tempo is also compatible with any open source tracing protocol, such as Jaeger, Zipkin and OpenTelemetry, and can be integrated with metrics, logs and dashboards via a managed Grafana Cloud service.

    It’s not quite clear how quickly organizations are embracing distributed traces to improve application observability or, for that matter, to what degree traces might eliminate the need for certain types of metrics or log analytics. The one thing that is certain is DevOps teams require more context than ever to proactively manage complex IT environments. Distributed traces make it simpler to track interactions between application services. The challenge is they can require IT teams to store a lot more data.

    In time, of course, distributed tracing will become more commonly employed as developers more routinely instrument applications based on microservices that tend to have lots of dependencies that are difficult to discover in the absence of some type of distributed tracing capability. Of course, distributed tracing has been around, in some form or another, in application performance management (APM) platforms for some time. The difference now is that, as open source software, it’s becoming more affordable to implement.

  • HashiCorp Increases Terraform’s Enterprise Appeal

    HashiCorp Increases Terraform’s Enterprise Appeal

    During the online HashiConf Europe conference today, HashiCorp debuted the general availability of a 1.0 release of HashiCorp Terraform along with updates to HashiCorp Terraform Cloud service.

    Meghan Liese, senior director of product marketing for HashiCorp, said in both cases HashiCorp is moving to enable organizations to better secure and govern IT infrastructure-as-code provisioned using open source Terraform tools.

    Version 1.0 of HashiCorp Terraform provides access to a stable application programming interface (API) that will foster interoperability and simplify future upgrades.

    The Terraform Cloud service, which eliminates the need for IT teams to set up and manage a Terraform platform, adds workflows enhancements to the Terraform Cloud that include the ability to publish curated modules to a private registry, enhancements that make it easier to visualize elements of a workspace and a preview of an ability to check with third-party tools related to a Terraform run.

    Overall, the goal is to make it simpler for organizations to compose, collaborate and reuse infrastructure-as-code using modules and the public and private registry options, said Liese. The public registry already has more than 5,000 modules. Terraform Cloud now offers a native workflow to publish modules from the public registry directly into an organization’s private registry.

    Terraform, of course, has been widely employed since it first debuted in 2014. There have been 15 major updates prior to the release of Terraform 1.0, which is intended to provide a foundation that ensures backward compatibility between releases going forward.

    In some instances, Terraform can be too much of good thing. It has considerably accelerated the rate at which IT infrastructure can be provisioned within the context of a DevOps workflow. The challenge, though, is developers often lack the security expertise required to prevent infrastructure from being misconfigured at a time when cybercriminals have become more adept at scanning for those vulnerabilities. To enable IT teams to prevent those misconfigurations, HashiCorp makes available both an enterprise edition of Terraform as well as its Terraform Cloud service. Terraform Enterprise is used by more than 1,200 enterprises, while Terraform Cloud has more than 120,000 users that execute more than 30,000 runs per day.

    It’s not clear if security concerns might one day lead to a backlash against the concept of shifting more responsibility left toward developers to improve productivity. In some cases, developers are simply deploying more insecure applications faster. HashiCorp is making a case for Terraform platforms that allow centralized IT teams to exercise more control over how infrastructure is provisioned as code. The need for that approach is becoming more pronounced, as organizations not only employ Terraform to provision cloud infrastructure but also on-premises IT environments.

    Regardless of how infrastructure is provisioned by developers, security of infrastructure, both inside and outside of the cloud, remains a priority as more workloads than ever are deployed. In effect, the attack surface that needs to be defended has dramatically expanded. Of course, the best security issue of all is the one that never happened because infrastructure is being provisioned right the first time and every time thereafter.

  • Fixing Risk Sharing With Observability

    Fixing Risk Sharing With Observability

    Incentives are mismatched among SREs, SecOps, and application developers. These mismatches create challenges around how and what information is shared across siloed teams. This asymmetrical information creates a moral hazard where one team can shift deployment risk to another team, with no accountability back to the originating team. Risk shifting results in unstable applications, inefficient infrastructure, security issues and poor customer experience. All of that impacts your company’s bottom line.

    Closing the Information Gap

    Observability is positioned as a way to fix the information gap between these disparate groups. Observable systems allow users to ask questions about their behavior in an open-ended way, unlike more rigid monitoring systems. SREs and SecOps teams are already reaping benefits from observability, but mismatched incentives limit its effectiveness. Meeting the observability expectations of IT leaders requires pervasive instrumentation across applications, infrastructure and third-party software. Delivering that level of instrumentation has remained out of reach due to incentive mismatches, as well as human and infrastructure costs.

    The main incentive for developers is shipping code quickly at a reasonable level of quality, meaning a low bug count. This contrasts with SREs, who are incentivized around uptime, performance and efficiency, while the incentives for SecOps teams are around risk reduction and breach mitigation.

    risk sharing observability

    Since SREs and SecOps teams don’t have insight into what developers have changed, it’s easy for performance or security problems to get thrown over the fence to operations. A fresh code push might only include minor changes and be harmless to existing operations. Or, it could replace large chunks of logic across the entire codebase, including adding calls to external and third-party applications. To the intrepid SRE and SecOps teams, one change looks like any other. They don’t get a peek behind the curtain because of the mismatched incentives. DevOps wants to deploy quickly. Waiting on approval from other teams slows down deployments, so comprehensive reviews don’t happen. This doesn’t mean DevOps teams are intentionally trying to sabotage partner teams. They’re simply acting in their own interests based on their incentives.

    The challenge is that one party, the developers, has more information than other parties. That information asymmetry is what creates unbalanced risk sharing. Coping with information asymmetry has led to all kinds of new collaborative models, starting with DevOps and evolving into DevSecOps and other permutations like BizDevSecOps.

    True collaboration has been hard to come by. Early DevOps efforts are often successful, but scaling beyond five to seven teams is difficult because teams lack the breadth of experience in IT operations or the SRE capacity to staff multiple product teams. The change velocity DevOps teams can achieve is often far greater than SREs and SecOps can absorb, making information asymmetry worse.

    If teams can’t maintain high levels of collaboration and communication, another option must be developed. Observability practices, like collecting all events, metrics, traces and logs, allow SREs and SecOps teams to interrogate applications about their behavior without knowing which questions they want to ask ahead of time. However, observability only works if applications, and the infrastructure they rely on, are instrumented. This creates another problem: who does the instrumentation?

    The expectation is DevOps teams embed instrumentation into their code as part of the development process. While that’s a nice idea, there are four reasons this falls short. First, the quality of instrumentation varies. Many log statements are terse and only understandable by the developer that wrote them. The message “In function xyx123!” isn’t helpful to an SRE digging into a performance problem that cropped up in the latest release.

    Second, instrumentation libraries vary by implementation, giving inconsistent results across language bindings. OpenTelemetry is trying to improve this, but its progress is slow and still requires developers to do more work that, if we’re honest, doesn’t benefit them; it benefits SREs and SecOps. Now we’re back to those pesky mismatched incentives and information asymmetry problems again.

    The third problem with instrumentation is the volume of data. Each instrumented application can produce terabytes of data each day. When you have robust instrumentation, the amount of data can be overwhelming, and extremely costly to analyze and store.

    Lastly, instrumentation is isolated to the code your team wrote. That represents a fraction of the code you rely on. Vendor-provided services and APIs remain a black box, limiting your observability into those components.

    Resolving information asymmetry across teams requires two things:

    1. Pervasive, pluggable instrumentation capabilities for all code that doesn’t require developer involvement, and
    2. An observability pipeline to filter, redact and enrich data, then route it to your analytics platform of choice.

    Pervasive Instrumentation

    Operations teams need instrumentation without having to go back to developers and beg them to add it to existing code. They need to turn it on and off as needed, and they need readily consumable data. They also need every piece of data they can get, including packet payloads, insight into encrypted data and so on. This goes well beyond what’s possible with today’s instrumentation options.

    AppScope, a newly released open source project, is a new take on instrumentation. AppScope interposes itself between application threads and system libraries, tracking things like file system access, network and HTTP activity, as well as CPU and process activity. It also provides payload data, and because it sits between the application and encryption libraries, it also gives access to users’ cleartext data. Because it works with any Linux binary, SREs and operations teams can instrument anything, even code they didn’t write.

    Observability Pipeline

    The challenge with pervasive instrumentation is dealing with all the data generated by applications. Network, file system, and other system data can easily swamp destination APM and log analytics platforms, driving up licensing and infrastructure costs. While instrumentation data is vital to rebalancing risk sharing in organizations, you need a way to manage that data intelligently to get value out of it. This is where the observability pipeline comes in.

    An observability pipeline sits between the sources of observability data and its target destinations. By acting as a strategic control point, the pipeline gives users control over how data is formatted, filtered, enriched, and redacted before it is routed to one or more destinations.

    Observability pipelines help SREs and operations teams deal with the flood of instrumentation data by routing low value data to low-cost storage, like S3, while higher value information lands in APM and log analytics tools. Later, if you decide you need the data stored in S3 to add more context to your analysis, you can replay it back through the pipeline and enrich your data set.

    Shifting business priorities are accelerating the pace of technology deployment across organizations, and teams are pressured to deliver faster. This faster pace of delivery pushes deployment risk to operations and security teams that lack visibility into changes developers have made across complex distributed systems. This information asymmetry also increases risk to the business as applications become less predictable and reliable over time.

    Traditional methods of resolving the information mismatch haven’t worked because incentives across teams aren’t aligned. Adopting pervasive instrumentation and observability practices will give SREs and operations teams critical visibility into rapidly changing application and infrastructure environments, without disrupting the developer experience and process.

  • Chicken Soup for the SLO

    Chicken Soup for the SLO

    Since time immemorial, humans have struggled to communicate. From myth to the modern era, our most memorable stories often involve individuals or groups seeking to be understood in order to avoid conflict. Be it the biblical allegory of Babel to the more recent Star Trek: The Next Generation episode of “Darmok,” a deep fascination with how people communicate seems to have collectively gripped our imaginations.

    It should come as no surprise, then, that communication between disparate teams and roles in the development of distributed software systems is a fascinating topic. There’s an almost primal struggle in the workplace—a dichotomy between “features” and “stability”—that teams have sought to overcome for decades. Indeed, much of the discipline of software engineering has implicitly evolved as a response to the needs of engineers to communicate with other parts of the business.

    How, then, do we improve this communication and build empathy toward our fellow developers, our coworkers, our PMs, our managers? We need a way to communicate with them, to express “how things are going,” how reliable our service or system is. Let’s step back, though, because this is only a small window we’re looking through—we need to communicate these desires and goals to a greater audience; Our bosses, their bosses, our customers, the entire world. Organizations rise and fall on their ability to communicate effectively.

    In the natural sciences, we observe that the tendency of a system is towards entropy; Energy tends to dissipate in the absence of a constraint. So, too, do human systems lose productivity as their scale and complexity increases. The rise in popularity of Agile methodologies and DevOps thinking tracks with this. They are, ultimately, designed to help us communicate better about needs and priorities. Site reliability engineering (SRE) is the latest in this line of disciplinary developments, providing rigor to the question of, “How do I operate very large scale systems in dynamic environments?”

    One of the more popularized elements of the SRE playbook is the concept of the service level objective, or SLO. To excerpt the excellent Implementing Service Level Objectives by Alex Hidalgo, a SLO is “a proper level of reliability targeted by a service,” a calculation of the amount of ‘bad’ events that can occur as part of the normal operation of a service. As Alex notes, the idea of SLOs and SRE have become almost inseparable in our collective consciousness—organizationally, it’s seen as strange to have one without the other.

    Let’s dive a bit deeper into what an SLO actually is. Again, I will excerpt and paraphrase from Alex’s book (it’s very good; you should read it if you’re interested in this topic). A SLO is simply a target, a set of defined criteria that represent some objective that you’re trying to reach. In a very general sense, the SLO expresses the threshold of ‘good’ to ‘bad’ events that you’re willing to tolerate over a time period. This simple ratio, however, unlocks a great deal of interesting and important ways of thinking about performance and reliability. It gives you, and your team, the ability to reason and communicate about reliability in a very quantitative and qualitative way.

    Now, you may be asking yourself what the qualitative component of a SLO is—after all, aren’t these measurements quantitative by definition? It’s in this dichotomy that I believe the true power and utility of SLOs lie; they’re not just a measurement of what you’re doing, they’re a communication vehicle for how you’re doing. Error budgets come out of this line of thinking—they represent the space between the current state of your SLO and its boundary.

    In plainer terms, it’s a measurement of how much you can miss your target before it becomes a problem. If my SLO targets 99% reliability, I have about three and a half days of unreliability a year to play with—or, about 14 and a half minutes a day. This way of measurement is certainly helpful in driving and determining engineering decisions, as it allows us to make snap judgements about how to prioritize the seemingly opposing buckets of “feature work” and “reliability work.” If we’re getting close to burning up our error budget for the month, do more reliability work. If we’ve got slack, do more feature work. Easy, right?

    How to Make Friends and Influence Budgets

    Reliability, SLOs, error budgets—these are all helpful ways to quantify performance and availability in software. There’s another way to consider them, though, and it’s through the lens of risk. If you’ve earned an MBA, you’re probably familiar with a ‘risk heat map.’
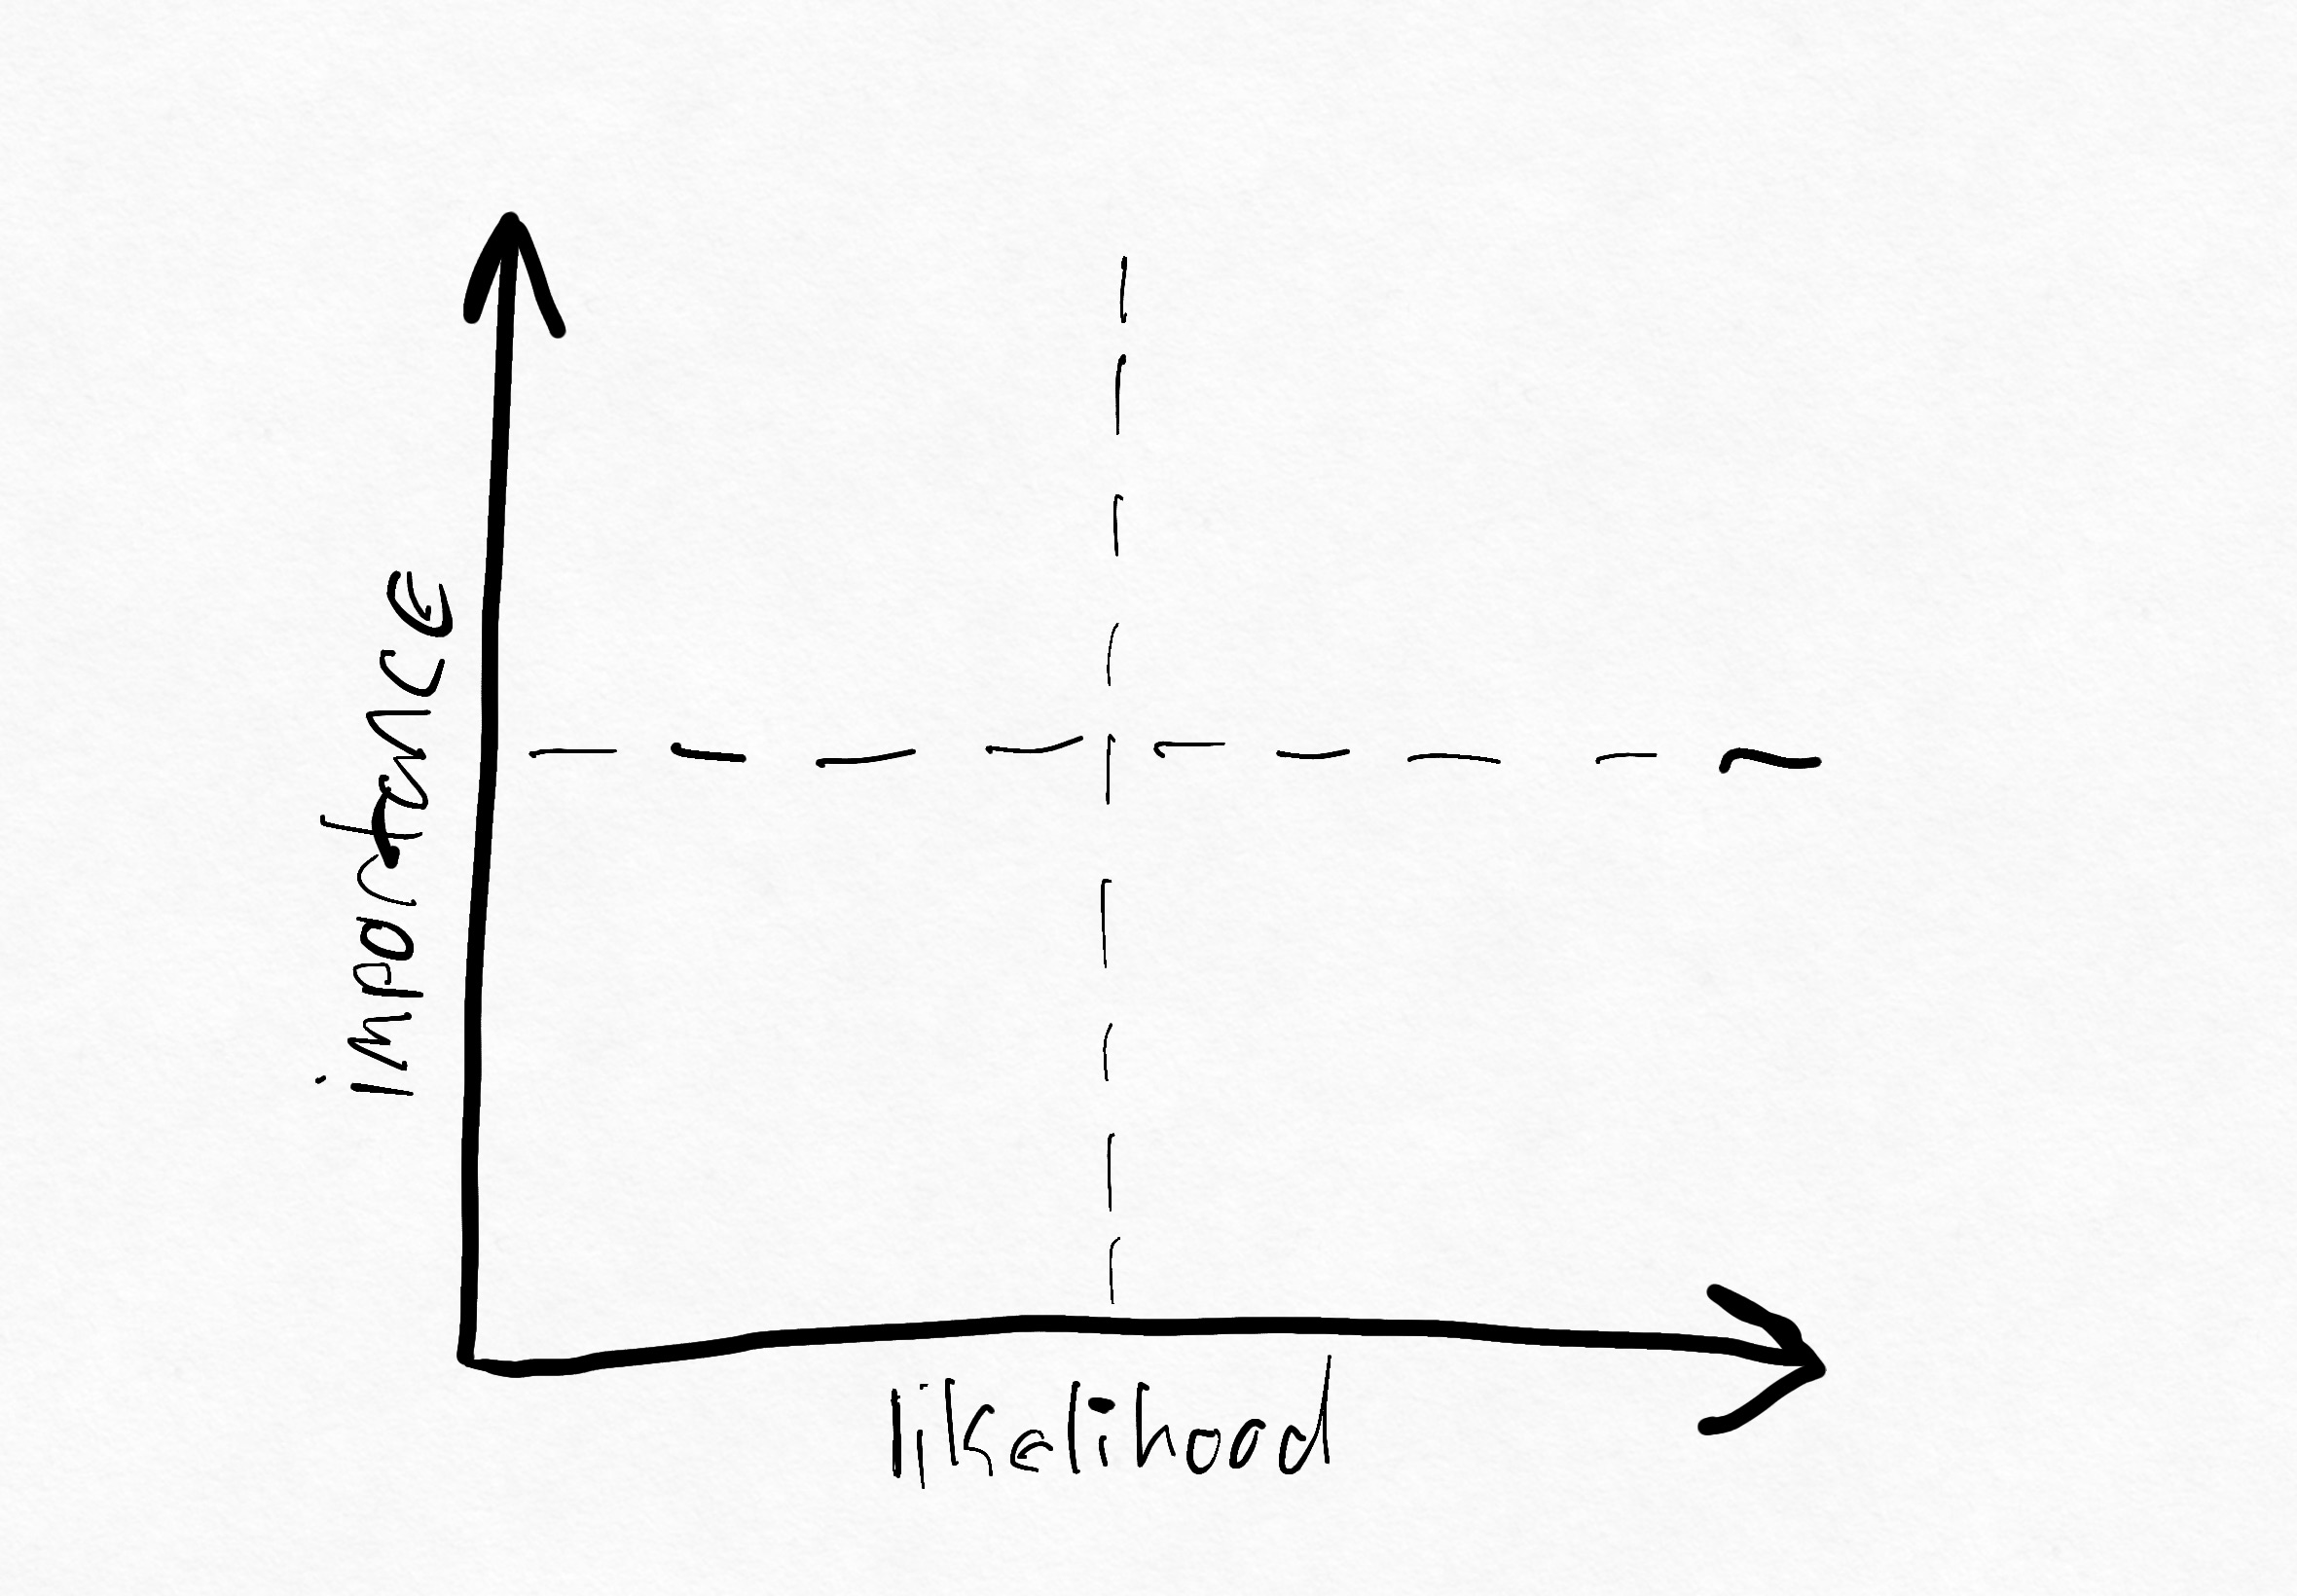
    SLO heatmap

    The x-axis on this quadrant represents the likelihood of a problem occurring; the y-axis represents the importance of that element. This is generally extensible to any element of a business—everything from your sales force to your customer success team to the availability of your data center or cloud resources.

    In many ways, this simple quadrant is responsible for many of the decisions that influence your work. While a business does many things, the business of operating a business can be thought of as an ongoing and unceasing process of risk management and abatement.

    The stuffy, MBA-fueled world of Six Sigma and process management doesn’t play terribly well in the more creative arenas of software development and maintenance, I’ve found. Much of this has to do with—you guessed it—risk. In manufacturing, the costs of failure or defects can be extremely high. Component defects can sideline million or billion dollar supply chains; projection and planning failures can disrupt just-in-time inventory and a single stuck ship or sudden winter storm can cause months or years of disruption to national or global economies. We should count ourselves fortunate that the actual costs of failure in a software system are so light; while us-east-1 going down for an hour would be bad, it probably wouldn’t wreck the global GDP for six months.

    The translation of ‘lower-level’ concerns, such as software system reliability or employee turnover, into ‘higher-level’ risk concerns acts as a curtain between the operational and the managerial aspects of a company. It is this curtain that we must consider when thinking about the true advantages, and the revolutionary potential, of SLOs. Remember, a SLO represents a ratio between ‘good’ and ‘bad’ and gives us a threshold value. These SLOs can be overlaid onto our risk maps extremely easily; SLOs for more critical services and processes rise to the top, newer services move to the right.

    In essence, we can give our SLOs a qualitative score with regard to overall business risk, and use this to shape the overall business direction. This is crucial, as in the absence of better qualitative measurements, businesses will often grasp at quantitative reliability measurements—“pages fired or tickets opened,” to quote Hidalgo. He continued, “[T]hese are prone to be inaccurate due to false positives or the whims of the people opening the tickets.” The types of measurements that we often rely on, such as categorization by severity or ‘mean time to x’ fail to accurately classify reliability or how it impacts the user experience.

    Let’s illustrate by example—a huge part of conversations about SLOs is talking about how they should be framed in terms of users; happier end users, happier engineers, happier managers and so forth. SLOs that correspond to user journeys—for instance, “Adding an item to the cart succeeds 99% of the time.”—are straightforward to understand from the perspective of an end user. We can discuss this in terms of risk by applying an importance and likelihood score to the SLO itself. If our site is an e-commerce platform, then the importance of the cart is very high. Since our threshold is very small (1%), then the likelihood of this risk is also very high—we don’t have a lot of wiggle room!

    A SLO for a targeted ad service might read, “A contextually appropriate display ad is served within 30ms 90% of the time.” In this case, our ad business might not be of high importance in terms of our business risk, so we should reduce the importance of the SLO. In addition, our threshold is very large, so we should reduce the likelihood of violation (since we have a lot more wiggle room). Over time, these positions and scores can (and should) change—perhaps the advertising segment of our business becomes more valuable, so we re-prioritize it on our risk maps.

    By speaking this language and quantifying our data in different ways, we can pull back the curtain between operational and managerial sectors and use it to influence things outside our immediate sphere.

    “Mommy, why is there a SLO in the house?”

    There’s an aphorism about war and fighting that goes, “Generals are always prepared to fight the last war.” I’ve seen this myself at every company I’ve worked for over the years—we tend to be reactive, rather than proactive, in planning and preparing for strategic business challenges. Some of this is due to the fact that none of us are oracles capable of divining the future, but much of it simply has to do with the aforementioned cycle of risk management that drives business planning and decision making. When introducing SLOs to a wider audience, you need to be able to plan for the pushback that executives and managers will almost certainly have to this new way of thinking.

    When you think about it, though, there’s not a lot of difference between what an SLO is trying to represent, and what an OKR or KPI or any other goal-oriented system is trying to represent. In each case, we’re creating some heuristic to sort events into ‘good’ and ‘bad’ cases, then creating a threshold of ‘Now there is a problem’ based on the ratio between them. In essence, this is, really, how you measure anything as a percentage.

    You could translate goals for your sales, marketing, customer success or people ops teams into SLOs. For example, “30% of POCs should convert into closed-won opportunities” is, basically, an SLO already, and is perhaps an existing goal for your salesforce. There are two big advantages to thinking about these as SLOs: consistent reporting and error budgets.

    Consistently reporting on SLOs means that you can express team and company goals in the same format and language across the entire organization. This brings teams together in a shared purpose, and allows for a shared language about how reliability benefits everyone. Being able to roll up reporting about how things are going not only encourages more shared ownership of goals, it helps you build connections and linkage between how different types of work align with each other towards a shared prosperity. More importantly, SLO reporting gives extremely clear signals about how teams—regardless of their function—should be addressing failure.

    If a consistent language around reliability is what builds empathy, error budgets are what unlocks creativity and problem solving for addressing issues in the business. In too many cases, organizations are loathe to give individual contributors, or even teams, the flexibility to experiment and measure the results of those experiments due to inertia, top-down command-and-control style processes or just the fear of screwing up.

    Let me give you an example—suppose your marketing team has a demo that generates a certain percentage of leads every month. Without a defined SLO for this demo’s performance, it becomes extremely difficult to change anything about how this demo works. Why? Because there’s a tendency for things to settle at their current state—we’re all so consumed with moment-to-moment crises or new work that evaluating the performance of existing things can be challenging.

    The work required to justify a change eventually outweighs the actual work being done to make the change, and so change withers on the vine and processes stagnate. Now, imagine that this demo flow had an SLO associated with it, something like “10% of clicks to our demo should result in a valid email capture.” Suddenly, we can report on this in a consistent fashion and, more importantly, we have a massive amount of headroom for experimentation. We can justify work being done to improve this flow in the context of not only its current status (are we running better or worse than our target?) but also in the context of our other goals (are we producing enough MQLs, in general, to support the sales funnel?) and prioritize appropriately.

    Ultimately, we can’t change the fact that there’s a bias towards dealing with the last thing that happened, but that’s not really the point. What we can change is how we think about expressing what’s happening now, and building a consistent language and verbiage around addressing these problems. SLOs are designed, broadly, as a way to communicate the reliability goals of complex distributed software systems. What is a business of people other than a complex distributed human system?

    As thinking, tooling, and processes around SLOs continue to mature (such as the recently announced OpenSLO specification), I’m excited to see what the future has in store for us. At the end of the day, we should be striving to reduce hierarchy, increase autonimity, and build collective ownership in the socio-technical systems that we rely on as human beings; SLOs are just another piece of this ever-evolving puzzle.

  • Cribl Automates Observability Efforts

    Cribl Automates Observability Efforts

    Cribl today announced it has updated the Cribl LogStream observability tool in addition to generally making available a software-as-a-service (SaaS) offering dubbed LogStream Cloud.

    Nick Heudecker, senior director for market strategy and competitive intelligence at Cribl, said Cribl LogStream provides the means to aggregate log data collected from multiple platforms and applications in a format any observability or monitoring tool can access.

    The challenge with observability platforms today is they leave it up to IT organization to copy and paste data into the platform. LogStream automates that process via a log router that collects and optimizes data streams from existing installed agent software and then shapes and routes that data on to analytics platform.

    Version 3.0 adds LogStream Packs, a framework for accelerating deployments of the log router. Alternatively, DevOps teams can employ LogStream Cloud to build and share LogStream configuration models.

    Heudecker said the goal is to reduce the cost of achieving observability by reducing the time and effort required to set up and manage data pipelines. No customization effort on the part of a DevOps team is required to collect and send data from hundreds of sources to any number of destinations, noted Heudecker.

    While observability is a core DevOps tenet, achieving it has been a major challenge. In addition to deploying and managing agent software to instrument IT environments, there’s a significant amount of time and data engineering effort needed to set up the pipelines employed to transfer data to a platform where it can be analyzed. Cribl is making a case for automating those data engineering tasks using a tier of software that abstracts data into a format that can be consumed by multiple observability and monitoring platforms.

    It’s not clear yet to what degree IT organizations perceive observability to be an evolution of monitoring, or simply the next logical evolution of monitoring. One way or another, IT teams need a lot more context than they have historically been able to attain using legacy monitoring tools. Each platform employed within an enterprise typically comes with its own monitoring tools that are used by the IT teams tasked with managing it. Whenever there is an issue, however, IT teams will spend hours correlating data from multiple tools to ascertain the root cause of a problem.

    Observability platforms promise to reduce that time and effort by applying analytics to data collected from multiple platforms. The challenge now is finding a way to efficiently collect all that data.

    It may be a while before IT organizations start to abandon all the monitoring tools they have in place in favor of observability platforms. However, as IT environments continue to become more complex (thanks, in part, to the rise of cloud-native computing platform based on microservices) the need for those platforms becomes more acute. The issue is enabling DevOps teams to achieve that goal without having to wait for an overworked data engineer to find the time to build a pipeline.