Category: Infrastructure/Networking

  • Making the Move to Edge Computing? Consider This 

    Making the Move to Edge Computing? Consider This 

    Edge computing has exciting potential, but there are certain considerations to thrive in today’s competitive landscape

    Data is king, especially in the current era of the data-driven business, where a data mindset and analytical capabilities are significant factors in determining future success. With so much data to be mined and monetized, more companies are recognizing the competitive advantages of edge computing, which can also jump-start the journey to becoming an autonomous digital enterprise. That said, a variety of security and infrastructure challenges may prevent some IT professionals from making the move, according to a recent survey by Volterra and Propeller Insights.

    Distributed models such as edge computing have always been attractive because of their ability to minimize network latency issues with large data and put essential functions closer to the technology consumer. Now, they’re even more attractive with new compute and application architectures and so many new data sources—network-connected and internet of things (IoT) devices, social media, customer engagement systems, transactional systems and systems of record—dramatically expanding the volume of data and changing the nature of the data collected. Edge computing also helps solve the traditional issues of optimizing for network capacity and performance and addresses new areas such as the localized pre-processing of all data sources (telemetry, video, mobile, etc.).

    It’s no surprise, then, that 54% of the IT leaders surveyed said they prefer edge to the cloud for operators who need to control and analyze data for local use cases, and to avoid the latency that can occur when sending edge data to public cloud-based apps. By moving certain workloads to the edge of the network instead, devices spend less time on the cloud, react faster to local changes, and operate reliably–even in extended offline periods.

    Edge computing still has its challenges and difficulties to overcome. Among them are key concerns such as a lack of resources or time for long-term upkeep of application and infrastructure, and managing distributed clusters as siloed instances rather than a single resource.

    Taking IT to the Edge – Edge Computing, That Is

    Despite the roadblocks, the value of edge computing is clear. This is why many companies are including edge computing models in their business plan. However, the performance, control and governance challenges that come with distributed models of compute, applications and data should be considered carefully beforehand.

    Innovative, data-driven companies that want to stay on the cutting edge and are planning an edge migration should develop a plan and long-term vision for their mix of data center, cloud and edge resources that consider their current and future use cases. Partnerships will also prove useful. By leveraging multi-vendor, commercial off-the-shelf solutions, enterprises can be more successful yielding value from edge computing than they would with single-vendor niche products. An ecosystem of seamlessly integrated solutions will help companies harness data and translate information into insight and actions that can optimize assets.

    As today’s enterprises seek to become more data-driven and evolve into the autonomous digital enterprises of tomorrow, it’s important to think about edge use cases as part of an overall automation strategy. Companies should consider how edge applications and distributed architectures will support them from a capacity, monitoring, deployment and service management perspective.

    Finally, edge computing’s advantages also come with the risk of security vulnerabilities if they’re not addressed from the outset, since the “attack surface” of a company’s IT estate becomes much larger. Organizations must deploy a multi-layer security approach that aligns with their edge initiatives while factoring in service-level needs to ensure assets are adequately protected.

    Edge computing has exciting potential, and the enterprises that make strategic investments and take a holistic, outlook-driven, secure approach to migration will thrive in tomorrow’s competitive landscape and years into the future.

  • Juniper Networks Brings AI to SD-WANs

    Juniper Networks Brings AI to SD-WANs

    Juniper Networks today announced it can now apply the same artificial intelligence (AI) engine it uses to automate the management of wireless local area networks (LANs) to software-defined wide area networks (SD-WANs).

    Based on an AI engine that Juniper Networks gained when it acquired Mist Systems, the Juniper Mist WAN Assurance cloud service streams telemetry data gathered from Juniper SRX devices to an AI engine that advises IT teams on how to best set WAN service levels as part of a larger transition to intent-based networking.

    As part of that initiative, Juniper Networks is also providing access to a Marvis conversational interface originally developed by Mist to enable IT teams to verbally issue commands, replacing the traditional command-line interface (CLI).

    Christian Gilby, director of product marketing for Juniper Networks, said as the number of remote branch offices that IT organizations need to manage increases at a time when travel is limited, the need to apply AI to SD-WANs has never been more apparent.

    Rather than return to central offices in the wake of the COVID-19 pandemic, Gilby noted, many organizations are shifting staff to smaller remote offices to enable collaboration while continuing to minimize potential exposure to anyone who might be infected.

    The challenge is that many IT teams tasked with managing the WANs that connect those remote offices aren’t growing during the downturn caused by the pandemic. AI provides a way to troubleshoot and optimize WAN performance without having to increase network operations headcount, Gilby said.

    Platforms such as the Juniper Mist WAN Assurance cloud service provides the added benefit of never forgetting anything they learn or taking a day off.

    Gilby said it’s not likely AI systems will replace the need for network operations teams anytime soon. However, Juniper Mist WAN Assurance is part of a larger wave of AIOps technologies that are augmenting existing IT staff. It may take a while for them to trust the optimizations being made by AIOps platforms, but the more data those systems collect, the more accurate they become over time.

    In the case of a cloud service, the machine learning algorithms that drive the AI models are being trained continually using anonymized data collected from thousands of systems.

    The launch of Juniper Mist WAN Assurance comes at a time when more organizations are looking to embrace SD-WANs as a way to more easily scale the delivery of network services when employees are working from home for the foreseeable future. In many cases, IT teams are now dropping Mist wireless routers into home offices to extend the reach of SD-WAN services in a way that can be managed and optimized using the same core AI technologies, said Gilby. In its most recent quarter, Juniper Networks reported a 170% rise in orders year-over-year for Mist wireless LANs.

    It remains to be seen how much or how quickly networking operations will be transformed by AI. However, at this point, that transformation is all but inevitable.

  • RackN Transforms Bare-Metal Servers Into a Cloud

    RackN Transforms Bare-Metal Servers Into a Cloud

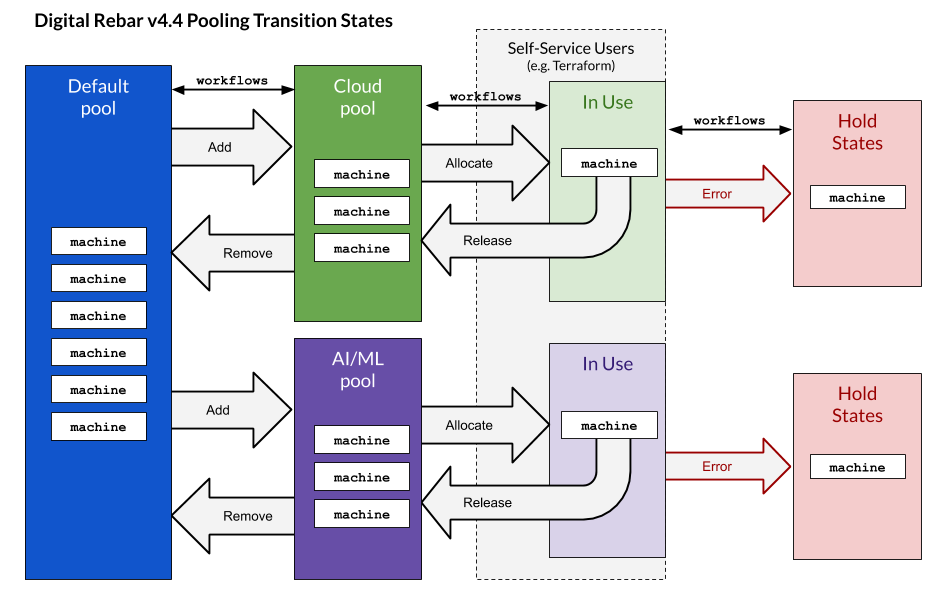
    RackN is making available an update to the RackN Digital Rebar Platform that will make it easier to employ tools such as Terraform to configure bare-metal servers.

    Company CEO Rob Hirschfeld said version 4.4 of the platform adds an application programming interface (API) that enables bare-metal servers to be abstracted into resource groups. IT administrators can request a machine based on an attribute map to provision a collection of bare-metal servers as if they were a cloud platform, he said, noting RackN is also making available workflows to enable IT teams to automate the allocation and reallocation processes more easily.

    At the same time, the latest release of RackN Digital Rebar Platform adds support for Trusted Platform Module (TPM) Secure Boot, an industry standard that ensures only software that is trusted can be loaded onto a machine. Most automation platforms don’t support TPM Secure Boot, which forces IT teams to choose between the benefits of automation and having a secure platform. RackN Digital Rebar Platform is the only automation framework to support (TPM) Secure Boot in VMware environments, Hirschfeld claimed.

    Out-of-band management passwords, TLS certificates and VLANs will also be secure by default with this latest release, he said.

    Hirschfeld said IT teams want to be able to provision bare-metal servers as if they were code in much the same way they provision virtual machines. Just as importantly, they require an automation tool that enables them to just as easily de-provision those machines when it comes time to reallocate them to another workload.

    Achieving that goal, however, should not require IT organizations to hire a site reliability engineer (SRE), he said, noting the RackN Digital Rebar Platform is designed to be employed by the average IT administrator. An SRE could define workflows within the RackN Digital Rebar Platform that are reused by IT administrators; in fact, RackN plans to add support for Git repositories that will make it easier to share workflows, Hirschfeld added.

    While the reasons for deploying workloads in the cloud versus on-premises IT environments are varied, the automation advantage cloud platforms historically have enjoyed over on-premises IT environments is narrowing at a time when interest in deploying Kubernetes clusters on bare-metal servers is rising. It may be a while before most IT teams are able to manage bare-metal servers as if they were just another cloud resource. The main obstacle for achieving that goal now, however, is likely to be a lot more cultural than it is technical.

    In the meantime, IT teams should expect to see bare-metal servers employed more widely in the age of containers. There will, of course, always be a need for virtual machines, at least in the foreseeable future. The challenge is the IT infrastructure environment itself is becoming more diverse as new classes of cloud-native application workloads emerge.

  • Xen Project Team Updates Open Source Hypervisor Project

    Xen Project Team Updates Open Source Hypervisor Project

    The team behind the open source Xen hypervisor announced today provided an update to the project that adds better nested performance, more robust live patching capabilities, improved security and support for Linux subdomains that make it possible to execute code within a specialized domain.

    In addition, Xen Project Hypervisor 4.14 adds the ability to run Xen as a guest under Hyper-V, the hypervisor Microsoft employs on the Azure cloud.

    George Dunlap, Xen Project Advisory Board Chair, said that latter capability will make it easier to create centrally managed hybrid cloud computing environments that span lightweight instances of Xen at the network edge and instances of Xen running in the Microsoft Azure Cloud. Xen is a core component of the Edge Virtualization Engine (EVE) being developed by LF Edge, which, like the Xen Project, is being developed under the auspices of The Linux Foundation.

    Dunlap also noted IT teams can employ Xen Project Hypervisor to run containers on top of virtual machines, which makes it possible to centrally manage the deployment of containerized applications from the edge to the cloud.

    Xen Project Hypervisor 4.14 also extends Raspberry Pi 4 support for devices with 4GB and 8GB of RAM, in addition to supporting the next-generation AMD EPYC processor, codenamed Milan.

    Finally, Xen Project Hypervisor 4.14 adds support for faster introspection of malware; the ability to live-patch security fixes in a way that ensures they are implemented in the right order; and control flow tools to combat Return-Oriented Programming (ROP) attacks.

    Dunlap noted the Xen team continues to work on Secret-free Xen, which prevents memory from being mapped as part of a side-channel attack.

    Golang bindings are also been expanded to make it easier to develop code on top of Xen using the Go programming language, and add the ability to migrate virtual machines with no drivers or broken drivers.

    While there is no shortage of options when it comes to virtual machines, Dunlap said the more they are viewed as a commodity the more likely organizations will opt to rely on an open source project, as many organizations are deciding there isn’t enough differentiated value to warrant paying for a commercial license.

    It’s too early to say how much organizations will continue to rely on virtual machines. Many IT teams do so now to provide a layer of isolation that is often deemed critical for security. Other IT teams are starting to rely more on containers deployed on bare-metal servers or a lighter-weight instance of a virtual machine that serves only to isolate workloads.

    Regardless of the path forward, the more platforms that run a common layer of virtual infrastructure, the easier it is to manage a hybrid IT environment. The real challenge is being able to enforce that level of IT discipline in an era where developers often spin up virtual machines wherever they find them.

  • Arrcus Expands Network Services Spanning Hybrid Clouds

    Arrcus Expands Network Services Spanning Hybrid Clouds

    Arrcus has added virtualized distributed routing (VDR) and multi-cloud networking (MCN) capabilities to ArcOS, a network operating system (NOS) that can be deployed on-premises or in the cloud.

    Company CEO Devesh Garg said these additional capabilities provide the programmatic network services that IT organizations require to foster deployments of hybrid cloud computing environments.

    Arrcus MCN provides the ability to securely connect workloads and data across any cloud, while VDR eliminates the need to rely on physical routers that require their own chassis, he said.

    Arrcus has been making the case for a disaggregated approach to networking that eliminates dependencies on physical infrastructure. Instead, IT teams can deploy ArcOS on a cloud service or any white-box appliance they choose in an on-premises IT environment. That approach eliminates the possibility of becoming locked into specific network hardware platforms, he said.

    Garg added it also provides DevOps teams with a consistent foundation on which to deploy distributed applications. Rather than having to navigate different NOSes running in the cloud and on-premises IT environments, ArcOS presents a consistent set of application programming interfaces (APIs) for accessing network services.

    In fact, the need to programmatically invoke those network services is what’s driving the convergence of network operations and DevOps teams, he noted. As applications become more distributed in the age of the cloud, IT organizations are looking for more efficient ways to expose network services on-demand.

    That convergence, however, will take time. Many networking teams still tend to prefer to acquire routers and switches as physical devices that include a NOS rather than deploying an operating system on infrastructure they select and manage. However, as DevOps teams continue to push for access to network services that can more easily scale up and down as required, it’s now only a matter of time before software-defined networking services become a default requirement.

    In fact, Garg said, the rise of microservices will force that issue as DevOps teams look to deploy applications that will be updated frequently.

    In addition, he noted, the rise of edge computing platforms and 5G wireless networking services will simultaneously push organizations toward virtualized network services.

    It’s not clear at what rate network services are being transformed. Software-defined networking services are already readily available in the cloud. Progress in on-premises IT environments has been tied to the willingness of IT organizations to fund upgrades to core network infrastructure. The challenge many IT organizations now face in the wake of the economic downturn brought on by the COVID-19 pandemic is finding a way to achieve that goal cost-effectively. White-boxes provide a less costly alternative to switches from vendors such as Cisco Systems and Arista Networks. At the same time, the total cost of delivering network services across a hybrid cloud computing environment can decline when a common NOS is employed across all platforms.

    Regardless of the path forward, the one thing that is certain is legacy network infrastructure has become a major bottleneck at a time when IT organizations need to be more agile than ever.

  • DevOps Chat: Software-Defined Storage, With StorPool

    DevOps Chat: Software-Defined Storage, With StorPool

    The whole Data/DataOps space is becoming very hot. For StorPool, it is more of a case of the rest of the world catching up to what the company has been doing for a while now. It is the leading distributed block storage provider globally.

    In this DevOps Chat, we speak with Boyan Krosnov, co-founder and chief of product at StorPool. Boyan gives us the background on StorPool as well as a good look at the state of the distributed storage/data market.

    As usual, the streaming audio is immediately below, followed by the transcript of our conversation.

    Transcript

    Alan Shimel: Hey, everyone, this is Alan Shimel. You’re listening to a DevOps Chat here on devopsy.kinsta.cloud, and my guest in this DevOps Chat is Boyan Krosnov from StorPool.

    Boyan Krosnov: Hi, Alan.

    Shimel: Boyan, I know it’s not perfect, but it’s the best I could do with your name, I apologize. But why don’t you say it for our audience?

    Krosnov: Sorry—repeat, please? I did not hear.

    Shimel: Why don’t you say your name for our audience?

    Krosnov: Yeah, so, my name is Boyan—Boyan Krosnov, but in, kind of for English speakers, most people say Boyan Krosnov, like, with the stresses at the wrong places, but it’s perfectly okay, you know, I understand.

    Shimel: As long as they don’t call you late for dinner, as we say here, right?

    Krosnov: Yeah, okay.

    Shimel: So, Boyan, your company is StorPool, yes?

    Krosnov: Yeah.

    Shimel: And what’s your position with StorPool?

    Krosnov: In StorPool, I am one of the Co-founders, one of the three Founders in the company, and my role as a Co-founder from the very beginning has been kind of the glue between technology and business and the product person in the company, the Chief of Product of StorPool.

    Shimel: Sure.

    Krosnov: And the other two Co-founders, you know, respectively take, are focused on technology development and the other Co-founder on strictly business, who is our CEO, right.

    Shimel: Someone has to do that. Okay.

    Krosnov: Someone has to do the business stuff, yes.

    Shimel: Someone has to. Before we jump in, Boyan, to what StorPool is about and what you guys do, why don’t we talk a little bit about your own personal journey? How did you come to found StorPool? What’s your background?

    Krosnov: Yeah, right. So, back in the ‘90s, I used to do competitive programming, so like, from a fairly early age, I got very interested in informatics or computer science, right? And from that, later on, I went into networking and ISPs, later on, I had a startup around something called packet processing and nowadays software-defined networking.

    And from that, at the later stages of that startup before we folded that, we found this gem of an idea of software-defined storage before it was called software-defined storage, right? So, we didn’t know it was called software-defined storage; the term wasn’t coined yet. That’s, like, in 2011.

    Shimel: Mm-hmm.

    Krosnov: And, from that, we founded StorPool. So, I got with the other founders and did, like, a whiteboard exercise of what an ideal storage system would look like. And that became the architecture of our product afterwards and we’ve been building on that for the last years, right? It’s eight years now.

    Shimel: Yeah.

    Krosnov: And along the way, we got—yeah, so, I’ve lived in a few places, not just in Bulgaria. I’ve lived in Iceland and the U.K. and Malaysia and a few others. And so, in StorPool, you know, we started with the idea, implemented it, got it to first production use some five, six years ago, right, and since then, we’ve been expanding it in a very kind of real business organic way, meaning pretty high growth, but at the same time, very customer-oriented. So, it’s very—the things we build into the product are things that our customers demand, right? It’s not like a completely greenfield.

    Shimel: Yeah, everyone already has some data.

    Krosnov: We do stuff that matters for our customers, right?

    Shimel: So, Boyan, listening to your story, I’m reminded of my own. You know, I got into technology in the mid-‘90s when the web first started coming in, it was just starting to get commercial, and we were storing websites. It wasn’t called hosting. I thought I was a virtual real estate person, [Laughter] because as I needed more land, I put another hard drive in the machine, right?

    Krosnov: Yeah.

    Shimel: And by about 1997, people started calling that web hosting.

    Krosnov: Yeah.

    Shimel: And we sold the company in 1998, we ended up doing a whole IPO and that whole thing. But, you know, at the end of the day, what we were doing is, we were just, we were storing people’s websites. I was selling virtual real estate, renting virtual real estate out. And it sounds like a similar thing you, before there was a thing called software-defined storage, you recognized that there was a need in the market for people to do, to be able to store stuff without the expensive, I mean, you know, back—I remember in those days buying EMC boxes, right?

    Krosnov: Yeah, yeah.

    Shimel: And some of the Sun and IBM—was it IBM Sharp? I forget. But all of these huge SAN—you remember the days.

    Krosnov: Yeah.

    Shimel: Millions—millions of dollars in SANs and all of that. And then, [Snaps fingers] it was like a flip—like a switch flipped. People started saying, “Wait a second, we could do this in software, for a lot less money with a lot more advantages.”

    Krosnov: Yeah, yeah.

    Shimel: And it sounds like StorPool happened to be right there at the right time when this was coming together.

    Krosnov: Yep, so, kind of the reason we started it was a few conversations with, actually, hosting companies.

    Shimel: Really?

    Krosnov: Actually hosting companies and some banks, but it started with hosting companies, and at that time, there was this big movement in hosting—everyone wanted to be the next DigitalOcean, right?

    Shimel: Right.

    Krosnov: Everyone wanted to have, like, a public cloud service with virtual machines and be like Amazon and DigitalOcean. And there were architects in these companies that were trying to figure out how to do it and they couldn’t and the one piece that was missing was software-defined storage. It was, like—they couldn’t make the business model work with standard SAN from HP or IBM or EMC, right? And we had to find a solution that worked for them which runs on standard servers—like, it’s not a proprietary box.

    Shimel: Understood, understood. So—I mean, but that was 2012. Now, here we are, 2020. Software-defined storage is a much better-understood term.

    Krosnov: Mm-hmm.

    Shimel: You know, I think it’s gone mainstream, if you will, right? People understand it and use that.

    Krosnov: Yeah.

  • Serverless Computing: Taking DevOps to the Next Level

    Serverless Computing: Taking DevOps to the Next Level

    Serverless computing enables you to outsource information, thus freeing teams to focus on front-end work. Organizations choose serverless when they look for faster and easier ways to release updates and patches. DevOps teams often use serverless when they are looking to automate infrastructure tasks. However, each provider offers different capabilities, and each service does require a level of training pre-adoption.

    What Is Serverless Computing?

    Serverless computing is a method that outsources infrastructure and infrastructure tasks to external providers. Organizations choose serverless computing because it enables development and operations teams to focus on the front-end of products and services.

    There are a few traits that distinguish serverless infrastructures from traditional cloud automation models:

    • Serverless computing services eliminate user responsibility for the management or operation of infrastructure.
    • Serverless computing services enable users to run code on-demand according to requests or event triggers. Infrastructure use scales transparently based on how many requests or events occur.
    • Serverless computing is pay-for-use and can be used to ensure that users pay only for actively used resources.

    The benefits of serverless in enterprise environments include:

    • Better control over production deployments.
    • Faster and easier updates or patches.
    • Increased productivity and easier release rollouts.

    Popular Serverless Computing Services

    All three major cloud providers offer serverless computing services. Below you can learn about these services and how each operates.

    AWS Lambda

    AWS Lambda is a service for serverless computing with other AWS services or via API. It can be connected to applications or run as standalone code. When using Lambda, users pay for active compute time although instances can be reserved to ensure their code runs with menial latency.

    Lambda can be triggered by a variety of AWS services, including Kinesis and DynamoDB. It can be monitored through Amazon Cloud Watch. Common use cases for Lambda include data processing, stream processing, machine learning and application backends.

    Azure Functions

    Azure Functions is Microsoft’s serverless service. You can use it for end-to-end development, including building, testing and deploying code. Functions can be used with a variety of Azure services and integrate with Visual Studio and Visual Studio Code for easy use.

    In addition to Functions, Azure offers Logic Apps, a service for creating visual design workflows and orchestrating Functions activities, and Event Grid, a message routing service to integrate Functions with other Azure services.

    Google Cloud Functions

    Cloud Functions is Google Cloud Platform’s functions as a service (FaaS) (i.e. serverless) offering. It can be used in the cloud or with hybrid deployments and it includes built-in monitoring, logging and debugging features.

    Cloud Functions supports a variety of environments including Cloud Run, Kubernetes and other Knative-based environments. Use cases for Cloud Functions include integration with third-party services, application backends, real-time processing, virtual assistants and machine learning.

    Why Serverless for DevOps

    If you are already using a DevOps approach or are considering adopting one, serverless can be a good option. Many DevOps teams, especially those operating in the cloud, are already working with modular components managed via a pipeline. Moving these modular services to serverless can enable teams to eliminate some of the tasks related to pipeline management and focus on development and deployment.

    This capability is especially valuable for teams that are just getting started or are looking to switch to DevOps practices. Serverless systems can enable teams to get started with development and testing right away on a comfortable scale. Then, as productivity increases, the serverless infrastructure can smoothly scale with minimal to no effort on the part of operations.

    Another benefit of serverless infrastructures is the ability to easily enable DevOps automation. With serverless, you can deploy your pipeline without hosted solutions. You are only responsible for “glue code.” This infrastructure is flexible and you can easily modify it as needed using infrastructure as code (IaC) solutions and automated events.

    Despite these benefits, there is a potential downside to serverless. Your DevOps team does not have the same visibility into or control of the functioning of the infrastructure. While you can integrate monitoring, teams are limited in how much of the infrastructure can be customized or manually affected.

    How Serverless Can Take DevOps to the Next Level

    There are several ways serverless deployments can be leveraged to improve DevOps productivity. Below are a few examples to consider.

    Infrastructure as Code

    Provisioning infrastructure is often a significant portion of deployment processes. Many applications use a variety of serverless services as building blocks through all stages of development and release. Making sure that these services are correctly connected and configured is key to a successful deployment.

    IaC can help users accomplish these tasks smoothly by leveraging declarative languages and tools such as Terraform. With these solutions, users can version your infrastructure along with their code, keeping tasks in sync and deployments consistent.

    Flexible Deployments

    With serverless services, infrastructure is immutable. Any changes result in new instances being spun up and activated. This means both old and new versions can run simultaneously.

    This immutability can be used to perform flexible deployments that are not possible or are much more difficult with traditional infrastructures; for example, canary or blue-green deployments. With serverless infrastructure, users can switch from one version to another with minimal fear of service interruptions and the ability to easily rollback updates.

    Distributed DevOps

    Serverless services can enable DevOps teams to work across a variety of environments and locations with minimal impact on others. These services allow the distribution of workloads at scale and can ensure that infrastructure is always available.

    The catch is that greater distribution and the ephemeral nature of serverless can make infrastructure much more difficult to monitor effectively. To account for this, teams need to ensure centralized monitoring with real-time alerts. Teams should also periodically audit infrastructure availability and performance to ensure that resources are functioning as expected.

    Conclusion

    Serverless computing enables DevOps teams to eliminate time and cost on the back end. Each serverless provider offers different services that can help achieve different capabilities. The main capabilities are provided via the use of functions, which enable the automation of infrastructure. However, in most cases, teams do need to learn how to use functions to properly configure customized IaC workflows. Once teams understand how to use the software, they can create flexible deployments and a distributed DevOps pipeline.

  • IaC and Kubernetes: A Natural Pairing

    IaC and Kubernetes: A Natural Pairing

    Using IaC with Kubernetes helps standardize Kubernetes cluster configuration and manage add-ons

    Infrastructure as code (IaC) is the ability to provision and manage infrastructure using a configuration language. It offers repeatability, transparency and the application of modern software development practices to the management of infrastructure including networks, load balancers, virtual machines, Kubernetes clusters and monitoring.

    IaC helps to reduce error and configuration drift while allowing engineers to spend time on higher-value tasks. IaC defines what the end state of infrastructure should look like, instead of defining a process to be executed.

    So Why Aren’t All Companies Using IaC?

    There are three main reasons why companies may not yet be embracing IaC.

    Many industries and engineers have not fully embraced or adapted to the paradigm shift of infrastructure APIs and code

    A lot of us think about infrastructure as touchable, involving physical installation and cabling. It’s only relatively recently in enterprise IT years that the industry has adopted APIs that allow borrowing and configuring infrastructure on-demand without the physicality. Engineers are good at standing up infrastructure using a time-tested, battle-hardened process. Incremental learning and integrating IaC into processes and culture helps to digest an otherwise daunting and challenging project.

    Industries are hard at work adapting security controls and regulations to incorporate the opportunity of cloud and automation without compromising high standards for privacy, safety and security. Engineers using IaC to improve their own efficiency can help champion its use in wider circles. One such example of this success is the 18F office which helps improve how the government serves the public through technology.

    IaC may feel like a loss of security or control

    Increasing the awareness of how and why infrastructure is configured can invite questions or feedback that initially may feel uncomfortable to those who have made infrastructure decisions. The ease with which others can make changes to infrastructure may feel dangerous or devaluing to engineers who have always pushed those buttons.

    IaC provides an opportunity for improving single human points of failure and knowledge bottlenecks without jeopardizing necessary controls. Access to infrastructure code and IaC tools can still match organizational structure, culture and approval processes. Infrastructure engineers remain integral to its evolution and success, and they are more available to tackle next-level problem-solving.

    ‘We move too quickly to take the time to ramp up with IaC, and we’re fast at clicking in user interfaces’

    The repeatability achieved by IaC means artisanally created infrastructure does not need to be kept around because it may be needed next month and parallel infrastructure can be created for testing and destroyed tomorrow. Start using IaC for something small such as spinning up that occasional temporary VM, then create a limited-access service account that someone else can use along with your IaC when they need that VM. Your IaC efficiency will grow with your organization’s body of IaC knowledge and code.

    Kubernetes and IaC

    Using IaC with Kubernetes helps standardize Kubernetes cluster configuration and manage add-ons. Infrastructure now can be versioned and committed to a Git repository, and it can more easily be “stood up” elsewhere when the company needs to expand to new regions or clouds. IaC benefits are vast and include:

    • Reduced human error and increased predictability: Create new test environments without impacting production and make changes across multiple environments using code review processes. Focus and attention to detail are less impacted by repetitive manual work.
    • Consistency: The repeatability of IaC with Kubernetes allows for the rapid creation of consistent infrastructure. This frees up time to address other challenges.
    • Improved changed tracking and auditability: When infrastructure is represented in a versioned repository such as Git, commits to the Git repository can reflect who, when and why changes were made. The code provides a record of how environments were built and evolved.
    • Faster speed to recovery: The reliability of an application is impacted by the ability to pivot and the speed to redeploy. Infrastructure as code can help you know what the recovery process looks like and practice that process more often.

    Start Using IaC and Kubernetes

    As a company moves into the world of containers, cloud-native apps and Kubernetes, IaC will help teams improve application reliability and stability, streamline development and operations and support a better user experience.

    In a Kubernetes environment, reliability becomes much easier to achieve with IaC because teams are deploying standard configurations. DevOps teams can use IaC to embrace the ephemeral nature of containers and Kubernetes pods, as well as avoid single points of failure.

  • Barracuda Networks Partners With Microsoft on SD-WAN Service

    Barracuda Networks Partners With Microsoft on SD-WAN Service

    Barracuda Networks today launched a software-defined wide area network (SD-WAN) service that runs natively on the Microsoft Azure cloud.

    Klaus Gheri, vice president of network security for Barracuda Networks, said Microsoft has made it possible to launch an SD-WAN service using Azure Virtual WAN Hubs, a networking service based on a hub-and-spoke architecture that unifies networking services such as security and routing under a common interface. Those services span branch connectivity, multiple types of virtual private networks, cloud interconnects, firewalls and encryption services.

    Gheri said rather than having to replicate all those networking services, Barracuda Networks is layering a Barracuda CloudGen WAN service on top of the Azure Virtual WAN Hubs to provide a service that, like any other cloud service, can be consumed per billable hour.

    Developed in collaboration with Microsoft, the Barracuda CloudGen WAN service provides the management framework needed to convert Azure Virtual WAN Hubs into an SD-WAN service that IT teams can employ to securely connect remote offices to cloud applications or on-premises IT environments, he said.

    SD-WAN services today come in four basic forms. IT teams can deploy and manage their own SD-WAN appliances. Alternatively, telecommunications carriers make SD-WAN services available on their networks or a managed service provider (MSP) can create its own SD-WAN service by deploying the appliance on points of presence (PoP) on a global network it manages. More recently, cloud service providers have been making SD-WAN services available via the networks they built to connect all their data centers.

    Gheri said Microsoft is now taking that SD-WAN capability a step further by adding a management portal created by Barracuda Networks.

    A recent survey of 750 business and IT professionals conducted by Vanson Bourne on behalf of Barracuda Networks finds more than half (52%) are looking to employ SD-WAN services delivered via the cloud. In comparison, the survey finds 16% prefer to get SD-WAN from an independent vendor, 15% would opt for a telecommunications partner and 12% would rely on a value-added reseller.

    With more application workloads moving into the cloud, the way networks are deployed and managed is evolving rapidly. Instead of connecting branch offices to local data centers to access cloud applications, more organizations are employing SD-WANs to provide direct access to cloud applications without having to backhaul network traffic through a local data center. That approach significantly improves overall application latency and, in many cases, reduces the need to rely on leased MPLS lines from a telecommunications carrier.

    Rather than build those SD-WANs themselves, many IT organizations want to be able to access and manage them via a portal through which they can allocate bandwidth to applications as they best see fit. It’s not clear to what degree IT organizations will continue to prefer to deploy appliances versus consuming SD-WAN as a service. However, given the complexity of managing SD-WANs, there’s a high probability that SD-WAN services delivered via existing cloud networking infrastructure will soon become a widely employed alternative.

  • Collibra Employs Microservices for Data Management

    Collibra Employs Microservices for Data Management

    Collibra has launched a Collibra Data Intelligence Cloud based on a microservices architecture that promises to alter the way data is managed in enterprise IT environments.

    Jim Cushman, chief product officer for Collibra, said its approach sets the stage for leveraging microservices to create data workflows made up of reusable components. In fact, there may come a day soon when some data sets are accessed and managed as a reusable microservice, he said.

    The Collibra Data Intelligence Cloud provides a catalog for managing metadata that, in addition to making it possible to build workflows, ensures the integrity and security of data being accessed and stored. End users can then analyze that data using a wide variety of third-party tools, said Cushman.

    At the same time, Collibra enables metadata ingestion from data sources such as data lakes and data warehouses, which means IT teams don’t have to move all the data they need to manage into Collibra Data Intelligence Cloud to create a workflow.

    Collibra is also making available a beta version of its Data Matching tool for qualified customers. That tool identifies duplication within a data source and how that data might overlap with other data sources.

    Finally, Collibra has added a data scoring component to its catalog to identify the most relevant data sets; provide enhanced support for third-party business intelligence (BI) and extract, transform and load (ETL) tools; and strengthened rights management capabilities to make it easier to enforce compliance requirements.

    Cushman said the goal is to provide organizations with an easier approach to storing and organizing trusted data. As the amount of data an organization collects grows, so, too, does the opportunity for conflicting data to be incorporated in applications. The Collibra Data Intelligence Cloud creates an opportunity to make data universally available to applications without requiring them to copy it, he said, noting that approach reduces not only the amount of data that might be in conflict as data sources are updated but also the amount of infrastructure that would have been required to process and store duplicate data.

    Organizations have been struggling with data management since the dawn of IT. That’s become a more pressing issue as more organizations seek to turn data into a strategic asset that drives digital business transformation initiatives. However, those initiatives are often derailed because so much of the data is either conflicting or simply too stale to be relevant. Collibra is making the case for a single platform to bring order to what historically has been a chaotic process.

    It’s not clear to what degree organizations will be focusing more on data quality and management in the months ahead. In the wake of the economic downturn brought on by the COVID-19 pandemic, it’s clear digital business transformation has become a necessity. The challenge is that unifying how data is managed in any enterprise requires a massive amount of political capital. Each business unit within an enterprise IT environment tends to guard its data privileges jealously.

    However, as microservices make it possible to make the business a lot more agile, the day when organizations finally confront their longstanding data management issues may finally be at hand.