Category: Cloud Management

  • Cloud Orchestration Language Roundup: A Comparison

    Cloud Orchestration Language Roundup: A Comparison

    What cloud providers do you work with? Google Cloud Platform (GCP)? Amazon AWS? Microsoft Azure? Which services? Are you using a managed Kubernetes such as GKE, AKS, Openshift or EKS? How do you manage your cloud resources? How do you manage the release cycle of the infrastructure and applications that you deploy?

    If the above questions are the basic introduction to describe your work, then you are probably also familiar with the console, API or both of a major cloud provider. You probably know how to use a configuration management tool such as Ansible or Chef, Terraform or CloudFormation, or some other similar tool. Additionally, you are familiar with the languages of one of these tools. You probably have opinions on those languages, which inform your attraction to the tools you choose.

    Kubernetes and Ansible use YAML. CloudFormation and Azure ARM can be JSON or YAML. Chef and Terraform have their own languages. (To be precise, Terraform can also be expressed in JSON.)

    cloudify orchestration language comparison
    A comparison of cloud orchestration languages

    Whenever you start learning a new tool, it is helpful to already know the tool’s language. The strength of using a standard language is that new users will feel more at home learning to use a language if they already understand the basics of its syntax. In the same way that many English speakers will relate to cognates in French, German or Latin than in Greek or Sanskrit without using transliteration, developers that know YAML will find it easier to learn Ansible than a tool that relies on XML. However, just because you know the language doesn’t mean you know the DSL. A DSL might use a language in a novel or even strange way that contradicts what you believe is proper.

    A number of variables may come into play when a user develops an opinion of a tool. The most important is, “How simple is it for me to create something that does what I want and minimizes frustration later on?” The next often are, “Which I venture is dependent on the first, are apparent scientific and analytical reflections? Does it lend itself to convoluted data structures? Do efforts to remain readable flounder because of inefficient use of space or punctuation?”

    Some projects, such as HashiCorp’s (Terraform), abandon a standard language to avoid such issues and instead create their own languages. The main drawback here is that it is more difficult to integrate the tool with existing projects and software libraries (although, providing for input and output in standard languages such as JSON can alleviate such problems).

    Cloudify has a DSL, which is based on YAML. Cloudify uses YAML, because it is easier to read than JSON, but powerful enough to define new types when necessary.

    Whether using a general language such as YAML or a proprietary one, certain designations are necessary: the type of resource, the name of the resource and often even whether the line refers to a resource, a parameter or a dependency.

    To illustrate the differences between the languages, and associated products that have been mentioned, let’s take a look at a few examples. Let’s use a relatively simple example, an AWS VPC, named “myVPC.” This is a simple resource to define in any language because it has relatively few parameters and no dependencies aside from an AWS account.

    Terraform:


      resource “aws_vpc” “myVPC” {

        cidr_block       = “10.0.0.0/16”

        instance_tenancy = “dedicated”

        tags = {

          foo = “bar”

        }

      }


    Terraform, or HCL, is notable for two reasons. First, the HCL “block” syntax recalls method definition syntax in a number of familiar programming languages. This is a nod to how Terraform, among all of these tools, relates to packaging infrastructure definition as code. Second, Terraform is the most concise. It only takes seven lines.

    Also, Terraform syntax infers significance from string position through the use of identifiers, such as “resource,” “aws_vpc” and “main.” HCL knows that block type comes first, followed by type and then name. For readability, this may be an ideal and certainly elegant method for defining components. Inside of the block definition is the API payload accepted by AWS EC2 Service for the creation of a VPC.

    One drawback of HCL is the punctuation requirements. Braces are required to enclose blocks as well as dictionaries. Arrays require square brackets.

    Let’s compare HCL/Terraform to CloudFormation:


      myVPC:

        Type: AWS::EC2::VPC

        Properties:

          CidrBlock: 10.0.0.0/16

          InstanceTenancy: dedicated

          Tags:

           – Key: foo

             Value: bar


    CloudFormation utilitizes YAML as well as JSON. These are data serialization languages. So, we are looking at our resource definition, less as code and more as information. This results in greater verbosity and decreased readability. Less concise, CloudFormation is eight lines.

    Whereas HCL uses “blocks” for resources. CloudFormation templates just call them “resources.” Instead of positional arguments, we have keys and values. “Type” defines the type. Properties introduce the resource API payload accepted by AWS EC2 service. However, YAML reduces the need for punctuation. Dictionaries are introduced by indentation and lists with hyphens. This can result in improved readability, and if someone really likes to use braces and brackets, no one is forcing them not to. However, it increases the number of lines and characters needed, because even abstract sections of the DSL require keys for introduction. This is because YAML accepts JSON.

    Ansible also has a module for creating a VPC in AWS.


      – name: create VPC.

        ec2_vpc_net:

          name: myVPC

          cidr_block: 10.10.0.0/16

          region: us-east-1

          tags:

            foo: bar

          tenancy: dedicated


    Ansible also uses YAML; however, there is no separation between API payload and other parameters. For example, authentication parameters are on the same level as payload parameters. Ansible uses modules for infrastructure management the way it uses modules for managing applications, which, while novel, is implemented in a clunky and relatively useless way. For example, you need a playbook for creation and a playbook for deletion.

    Cloudify:


      myVPC:

        type: cloudify.nodes.aws.ec2.Vpc

        properties:

          resource_config:

            CidrBlock: 10.10.0.0/16

            InstanceTenancy: dedicated

            Tags:

              – Key: foo

              – Value: bar


    Cloudify also uses YAML. It also works with key-value pairs. Cloudify is even more verbose than CloudFormation.

    A node template can be a resource or a group of resources. In Cloudify, there are three types of properties. The resource_config, which contains the API Payload; the client_config, which contains the API Authentication; and orchestration properties,which are additional properties that enable you to describe how Cloudify will interact with the resource. For example, all resources have the use_external_resource, which means that Cloudify can use resources that Cloudify did not create.

    Whereas Terraform/HCL uses “resource blocks” and CloudFormation uses “resources,” Cloudify uses “node templates.” Node templates can be a VPC or other cloud resource, or even a CloudFormation Template or a Terraform template.

    Azure also sports an orchestrator, Azure ARM, and has its own DSL to describe Azure resources. This is how a virtual network is defined in Azure ARM:


      type: Microsoft.Network/virtualNetworks

      apiVersion: ‘2019-11-01’

      name: myVPC

      location: “[parameters(‘location’)]”

      properties:

        addressSpace:

          addressPrefixes:

          – 10.0.0.0/24

        subnets:

        – name: “[parameters(‘subnet_name’)]”

          properties:

            addressPrefix: 10.0.0.0/24


    One notable difference in Azure ARM is that the resource entry in the YAML does not have a key name with the definition being the value of the name key; instead, the entire dictionary is a list item. This is perhaps more concise, but it may forfeit a modest amount of readability. Also, Azure is similar to Cloudify in that the resource definition “properties” is not on the same level as other more general details, such as “apiVersion” or “location.”

    The syntax for accessing a parameter is also a tad obtuse. Accessing a key in a dictionary via square brackets and parentheses is probably one of the most unreadable methods in the DSLs we are looking at.

    Like Cloud Formation, ARM can be written in JSON or YAML.

    Terraform can define the same Azure resource using fewer lines.


      resource “myVPC” “example” {

        name                = “virtualNetwork1”

        location            = azurerm_resource_group.example.location

        resource_group_name = azurerm_resource_group.example.name

        address_space       = [“10.0.0.0/16”]

        subnet {

          name           = “subnet1”

          address_prefix = “10.0.1.0/24”

        }

      }


    Cloudify will define the same resource in 14 lines. However, this could be shortened using default values.


      network:

        type: cloudify.azure.nodes.network.VirtualNetwork

        properties:

          resource_group_name: { get_input: resource_group_name }

          name: { get_input: network_name }

          location: { get_input: location }

          resource_config:

            addressSpace:

              addressPrefixes:

                – 10.10.0.0/16

            subnets:

              – name: subnet1

                address_prefix: 10.0.1.0/24


    Azure and Amazon expose ARM and CloudFormation as API objects respectively. This enables orchestrators to manage those resource stacks as single resources.

    You can define an ARM deployment in Terraform like this:


      resource “azurerm_template_deployment” “deployment” {

        name                = “myArmDeployment”

        resource_group_name = azurerm_resource_group.example.name

        template_body = file(“${path.module}/environment.json”)

      }


    The type requires deployment name, resource group name and template body. The latter can be supplied inline or using Terraform’s file function.

    Ansible can also define ARM templates:


      – name: Create Azure Deploy

        azure_rm_deployment:

          resource_group: myResourceGroup

          name: myDeployment

          template_link: ‘https://…/azuredeploy.json’

          parameters_link: ‘https://…/azuredeploy.parameters.json’


    Cloudify can also orchestrate ARM deployments. Here is a simple infrastructure stack in ARM using Cloudify:


      deployment:

        type: cloudify.azure.Deployment

        properties:

          location: { get_input: location }

          name: { get_input: resource_group_name }

          template_file: ‘resources/arm/environment.json’


    Cloudify can also accept a file or inline JSON (or YAML).

    Having defined the source code for our infrastructure components, we can now connect other resources and processes to this infrastructure dependency. We can use the Terraform template to a CICD workflow or a networking application.

    Using the same approach, Cloudify can also call Terraform stacks:


      infrastructure:

        type: cloudify.nodes.terraform.Module

        properties:

          resource_config:

            source: resources/terraform/template.zip

            variables:

              access_key: { get_secret: aws_access_key_id }

              secret_key: { get_secret: aws_secret_access_key }

              aws_region: { get_input: aws_region_name }

              aws_zone: { get_input: aws_zone_name }

              admin_user: { get_input: agent_user }

              admin_key_public: { get_input: public_key }


    Cloudify also utilizes other Cloudify deployment stacks as service components:


      infrastructure:

        type: cloudify.nodes.Component

        properties:

          resource_config:

            blueprint:

              id: my_deployment

              blueprint_archive: { get_input: infra_archive }

              main_file_name: infra.yaml

            deployment:

              id: my_deployment


    To summarize, there are many DSLs for orchestrating cloud resources. Each has its own focus: Terraform on simplicity and repeatability, CloudFormation on Amazon, ARM on Azure, Ansible on setting up applications and Cloudify on enabling users to automate any task, including automating Cloudify. We call this “orchestrating the orchestrator.”

  • How To Build Out a Successful Multi-Cloud Strategy

    How To Build Out a Successful Multi-Cloud Strategy

    Navigating even just a single cloud environment can be complicated enough for any startup. Between understanding the range of features on offer, planning for expenditure and ensuring you have the right expertise to leverage the tool to its full potential, the thought of managing multiple clouds can seem daunting.

    However, whether your company is just starting out or has been around for years, the rewards to be reaped from a multi-cloud approach make it a worthy investment. Adopting a multi-cloud strategy offers a whole host of benefits and can allow you to optimize costs when implemented correctly. In fact, a recent Gartner survey of public cloud users found that 81% of respondents are working with two or more providers. In addition, the amount of business applications, services and workloads is set to double over the next two years.

    Here’s what companies of all sizes can gain from going multi-cloud, and how they can do so.

    Why Opt for Multicloud?

    For startups, adopting a multi-cloud strategy can be rewarding from day one. If you’re building your proof-of-concept or are in the design stage of building your infrastructure, leveraging multiple environments at once can help you develop faster and with more advanced tools.

    With access to multiple clouds, you can play around with the strengths of each provider and combine them to get the “best of all worlds,” increasing agility and eliminating vendor lock-in. Having immediate access to more than one cloud also means being able to take advantage of these features as and when you need them, without having to fully migrate to another cloud, which can be a costly and lengthy process. In fact, Gartner analyst Michael Warrilow stated that “most organizations adopt a multi-cloud strategy out of a desire to avoid vendor lock-in or to take advantage of best-of-breed solutions.”

    Opting for a multi-cloud environment also boosts security and disaster recovery and ensures easier migration for some data and applications. Cybersecurity is heightened as spreading applications across different providers means an attack is less likely to bring your entire infrastructure down at once. Furthermore, sticking with one provider inevitably runs the risk of losing control of a mission-critical application during an outage. All of this adds to the overall resiliency of your system’s infrastructure.

    So, how exactly can you get started with your multi-cloud journey?

    Making the Right Cloud Choices

    While a multi-cloud approach can deliver serious value in terms of resiliency, flexibility and cost savings, making sure you’re choosing the right providers requires a comprehensive assessment.

    Luckily, all main cloud vendors offer free trial services so you can establish which ones best fit your needs and see how they work with each other. It will pay to conduct proofs-of-concept using the free trials and run your data and code on each provider. You also need to make sure that you’re able to move your data and code around easily during the trials.

    It’s also important to remember that each cloud provider has different strengths—one company’s best option is not necessarily the best choice for you. For example, if your startup is heavily reliant on running artificial intelligence (AI) and machine learning (ML) applications, you might opt for Google Cloud’s AI open source platform.

    Or perhaps you require an international network of data centers, minimal latency and data privacy compliance for certain geographies for your globally used app. Here’s where AWS could step in. On the other hand, you might need your cloud applications to seamlessly integrate with the various Microsoft tools that you already use. This would make the case for Microsoft Azure.

    There are multiple factors at play that you have to carefully consider to ensure ROI of your multi-cloud investment. According to a 2019 Spiceworks study, AWS comes out top for maximum uptime, Azure wins on compatibility and Google Cloud proves to be the best for manageability.

    However, it’s also crucial to remember that there are far more cloud providers than the “big three.” For example, Aliyun is Chinese conglomerate Alibaba’s cloud computing offering, while Oracle and IBM also have their own services. Many startups turn to more niche vendors that can better suit their individual needs, so it could pay to explore alternative options, too.

    Ultimately, you need to understand not only what your current needs are but also how your business goals align with the capabilities of your cloud strategy. Consider what you might need in the future that your current cloud provider doesn’t provide.

    Avoiding vendor lock-in—being able to dip into different features as and when you please—is one of the key benefits of multi-cloud adoption. However, it requires careful planning and assessment of your short- and long-term business goals and how these relate to your cloud infrastructure needs.

    Managing Multiple Cloud Environments Requires Expertise

    There’s no doubt that leveraging a single cloud environment requires team members with experience and know-how of that particular cloud vendor. So, moving to a multi-cloud approach means there’s an even higher demand with regards to the expertise you need at your disposal.

    If your team only has engineers who are experienced with working with Azure, it wouldn’t be a wise move to immediately adopt AWS without recruiting more talent. This is especially true as AWS is the most complex and mature of all of the main cloud providers and requires the relevant knowledge to be able to take full advantage of the tools and applications available. Hence, you need to consult your team at every step of the way on what kind of cloud environment is within their capabilities when crafting your multi-cloud strategy.

    Another vital aspect of multi-cloud adoption is managing the integration of the databases from each cloud provider. This means aligning your data management strategy across each cloud environment, otherwise you risk creating data silos and databases that don’t communicate with each other. Fortunately, many cloud providers include features that let you create clusters and manage and deploy databases. A team that understands the need for this is essential.

    Finally, a DevOps culture is crucial for any successful multicloud strategy. The purpose of multicloud adoption is not only to build out your infrastructure, but also to power continuous delivery and integration when it comes to product development. To ensure you select the best features and determine the right capacity according to your needs and expertise, you need to get the input of your entire DevOps team, including cloud experts, software developers and QA engineers, too. In fact, going one step further, many companies are even building out Cloud Centers of Excellence (CCoE), aa team of cloud experts who drive cloud-based digital transformation across an organization.

    The Balance of Controlling Multi-Cloud Costs

    Controlling and managing your expenditure while adopting a multi-cloud environment is no easy task, especially as your personalized use of the tool, which scales up and down, will result in fluctuating costs. In fact, controlling these expenses can be so difficult that cloud cost management vendor ParkMyCloud predicted that companies spent more than $14 billion on unnecessary cloud infrastructure costs in 2019.

    From a cost-saving perspective, Google Cloud is the best option as it offers more flexible contracts, lower starting costs and clearer visibility into expenditures compared to the other big providers. However, the decision should be taken against the potential ROI of the multicloud strategy you adopt, so calculating the financial optimization that will come from accessing multiple cloud environments can help guide you.

    If possible, it’s a good idea to consult with an expert partner on the ways in which you can best manage costs and maximize ROI. If this isn’t an option, you can use different tools that allow you to create estimates around expenditures.

    As the growing numbers around multi-cloud adoption suggest, it’s a trend that’s delivering value and is here to stay. With a multi-cloud environment, startups and enterprises alike can have flexibility around the features they need, optimize costs, increase security and protect themselves against outages. However, embarking on a multi-cloud strategy is no straightforward task: It requires research, planning and consultation with your technical team. By aligning your business goals with your cloud requirements and democratizing your decision process, you can ensure you get the most out of your multi-cloud investment.

  • Optimize Performance, Cut Costs With AWS Autoscaling Services

    Optimize Performance, Cut Costs With AWS Autoscaling Services

    A very easy (and free) way to get the get your money’s worth on the AWS Cloud platform is autoscaling. Autoscaling allows for better fault tolerance, better availability and better cost management, quickly scaling up and down to meet traffic demands while keeping your costs within budget by detecting and replacing the components that are not healthy enough to be present in the infrastructure.

    Some of the key benefits of autoscaling are:

    1. Meeting the traffic requirement on-demand and scaling accordingly.
    2. Adjusting scaling group capacity through the scheduled actions on the autoscaling groups.
    3. Reducing resources and costs.
    4. Increasing application availability by deploying across the availability zones.

    AWS has several services that help autoscaling the infrastructure components and reduce the management associated with scaling. They are mediated through the CloudWatch monitoring and observability service. CloudWatch provides up to 1-second visibility of metrics, 15 months of data retention (metrics) and the ability to perform calculations on metrics. This allows digital engineering teams to perform historical analysis for things such as cost optimization, for instance. On top of the specified metrics, teams can create alarms and alarm trigger the autoscaling policy to perform predefined steps, either to scale out or scale in.

    Autoscaling Services on AWS Cloud Platform

    EC2 Instance Auto Scaling

    EC2 instance autoscaling helps us to keep the correct number of EC2 instances available to handle incoming traffic requests for the application. We can create an EC2 autoscaling group, which is a collection of EC2 instances. In that group, we can specify a minimum, making sure that the group never goes below a specified size. We can also specify a maximum number of EC2 instances, which ensures that the group never goes above the specified size. This keeps capacity at a minimum and maximum range and ensures that your autoscaling group has EC2 instances specified in the desired capacity. Autoscaling also allows us to configure scheduled actions that can change the minimum, maximum and desired auto-scaling group capacity at a specified time.

    EC2 instance autoscaling allows for the configuration of scaling policies that will scale up or down according to the policy to increase or decrease EC2 instances in your infrastructure.

    There are two types of scaling: manual, in which we can attach and detach EC2 instances from the autoscaling group, and dynamic scaling, in which we can define how to scale the autoscaling group capacity in response to the incoming request or changing demand in terms of specific resource utilization. This allows us to configure policies that can take care of scale-up and scale-down and acts according to the policy for factors such as the number of requests, CPU and memory utilization.

    Below are the three types of dynamic scaling policies:

    • Target-tracking: This policy will increase or decrease the autoscaling group’s current desired capacity based on the target value for the specific metric. This policy maintains the capacity to match specified target metrics like CPU or memory utilization. Let’s assume that you have set 60% utilization of your autoscaling group—the target-tracking policy will add or remove EC2 instances to meet the specified utilization.
    • Step Scaling: This policy increases or decreases the current capacity of the autoscaling group based on a set of scaling adjustments (EC2 instances) that vary based on the size of the alarm breach. Let’s assume that the autoscaling group has three stages for tracking CPU utilization—the first alarm would be triggered when 40% is reached and would add one EC2 instance, the second alarm would be triggered when 60% is reached and two EC2 instances are added, and the third alarm is triggered when 80% is reached and three EC2 instances would be added.
    • Simple Scaling: This is a simple scaling policy option that increases or decreases the current autoscaling group capacity based on a single scaling adjustment. Here we can add one EC2 instance when specified alarm breaches.

    EC2 autoscaling provides on-demand instance scaling and spot fleet instance autoscaling, through which we can automatically increase or decrease the current capacity of the spot fleet based on the demand. It can launch (scale out) or terminate (scale in), within the specified range.

    ECS Container Service Auto Scaling

    Elastic Container Service (ECS) Auto Scaling works on published container CloudWatch metrics such as CPU and memory usage. It increases or decreases the desired capacity of container tasks in ECS service automatically. CloudWatch metrics can be used to scale out (add more tasks) to handle a high degree of incoming requests and scale in (remove tasks) during low utilization.

    ECS Auto Scaling allows us to configure policies including target tracking, step scaling and scheduled scaling actions.

     RDS Storage Auto Scaling

    Amazon Relational Database Services (RDS) for MariaDB, MySQL, PostgreSQL, SQL Server and Oracle support storage autoscaling, with zero-downtime RDS storage autoscaling automatically to scale the backend storage volume attached to the RDS database in response to growing database size.

    RDS monitors current storage consumption and scales storage capacity up when current consumption reaches near the actual provisioned size, without affecting current database operation and disturbing current database transections.

    Aurora Auto Scaling

    AWS Aurora autoscaling adjusts the number of Aurora replicas dynamically. You can define the scaling policy and Aurora acts accordingly. It scales Aurora replicas to handle a sudden increase in the database connectivity or the workload. As and when database connections or workload decreases, Aurora Auto Scaling removes unwanted Aurora replicas automatically, so customers are not charged for the unwanted replica instances.

    Just as we were able to define scaling policies in other services, so we can define them in Aurora Auto Scaling, and it also allows us to configure the minimum and the maximum number of Aurora replicas that can be managed. Aurora Auto Scaling is available for both of the Aurora engines MySQL and PostgreSQL.

    DynamoDB Auto Scaling

    The most difficult part of the DynamoDB workload is to predict the read and write capacity units. If an application needs high throughput for a specific period, it is not necessary to overprovision capacity units for the entire time. Amazon DynamoDB Auto Scaling dynamically adjusts provisioned throughput capacity on your behalf in response to actual incoming traffic request patterns.

    As and when the workload decreases, application autoscaling decreases the provisioned throughput capacity units, so that customers do not pay for any unnecessary capacity.

    With DynamoDB Auto Scaling, we can create scaling policies on the table or global secondary index. We can specify within the scaling policy whether we want to scale read capacity or write capacity (both), and the minimum and maximum provisioned capacity unit settings for the table or index.

    Prime Your Infrastructure For Autoscaling

    For these AWS autoscaling services to function as they should, organizations need to ensure they have:

    • Specified application user session state and persistence when using EC2 instances.
    • Tested, monitored and tuned their autoscaling strategy to ensure that it functions as expected.
    • Decision-making logic in place that evaluates these metrics against predefined thresholds or schedules and decides whether to scale out or scale in.
    • Service-specific limits in place before configuring autoscaling.
    • While using EC2 autoscaling, teams have specified cooldown time as well as which application to start up, and are ready to serve in a defined time.
  • Are We There Yet? The Long, Hot Road Trip to the Cloud

    Are We There Yet? The Long, Hot Road Trip to the Cloud

     “If I have to pull this car over, there will be trouble!” Does this sentence evoke childhood memories of summer adventures in the family car? It’s the same sort of dread we get when the IT budget-holder turns around and threatens to pull over on our journey to the cloud or hybrid cloud. The family summer road trip may be filled with great expectations, but the last thing we want is an unforeseen disruption along the way. And migration to the cloud is no different. To continue this analogy, the bumps on the road to avoid are the ones around cost, performance and risk. So, here are some thoughts on how to identify the challenges and navigate to your destination smoothly.

    The Line of Business Needs To Pee (They Think) …

    Or even worse—“we just stopped, why didn’t you go then?!?!” Planning business needs is always a challenge—especially at the speed of change in today’s disruptive markets. The unforeseen impact of the COVID-19 pandemic is one example. We hear it a lot in our industry: “We don’t know which applications are using the most bandwidth and how much they are costing us.” And with 59% of infrastructure managers citing infrastructure cost overruns as their biggest concern, there’s definitely room for immediate improvement. Having clarity into your application topology with a clear map to performance is mission-critical for a successful hybrid cloud journey.

    Because this is such a dynamic process, it needs to be mapped and measured daily, in real-time. But simply automating VMs to workload balance does not give you the clarity needed to understand what and when to move in your hybrid journey. You need the ability to understand why and when things changed so you can effectively plan or resolve the issues. According to Gartner Research, on average, AWS deployments are 40% over-provisioned to meet unexpected capacity and performance issues, which defeats the purpose of moving to the public cloud. “Know before you go” should be a mantra for every hybrid journey manager—and parent managing backseat bladder needs.

    IT Just Hit a Major Pothole and Now Has a Flat Tire

    A flat tire only ruins a trip if you don’t have a spare, the tools and the knowledge required to fix it. For most, the actual solution is to call AAA or in this case, get a third-party systems integrator (SI). Calling an SI to help solve an unforeseen problem is not a bad idea, but it does come with a hefty price tag and a level of dependency that doesn’t mirror the model of moving to a public cloud.

    With the right solutions in place, even a pandemic like COVID-19 should not disrupt your business. Every IT leader should have confidence in their infrastructure systems. That said, it takes time and effort to get there, and no journey worth taking is easy. Having integrated solutions and partners are critical to the hybrid cloud journey. And so is knowing when to fix it yourself and when to call in support to save you millions.

    Too Much Luggage From the DBAs

    Packing the back of the family Ford “Wagon Queen Family Truckster” is a special skill set. It’s like playing Tetris with your family’s luggage. Right-sizing infrastructure capacity while supporting applications is like making sure all the luggage fits in the car and that you still have room to move your feet. Sure, you could buy a bigger car to manage the payload, but the expense doesn’t justify the performance. You need the clarity to act across your private and public cloud infrastructure in a single solution without disruption is required. That level of optimization is a constant to remaining competitive, enabling you to transform your infrastructure from being seen as a cost of business to being recognized as a revenue generator.

    Compliance Just Gave You a Speeding Ticket

    No matter how well-intentioned and on the right side of the law your compliance team is, it can feel like you are being chased by Sheriff Rosco P. Coltrane. And while you don’t mean any harm, the law is the law. In the rush to the cloud, you’re not often asked how you will manage the migration, you’re simply asked how fast you can move—reminiscent of another epic journey: “We’ve got a long way to go and a short time to get there.” Regardless of whether you identify with Smokey or the Bandit, you cannot deny that Sheriff Buford T. Justice (aka, Compliance/Security Officer) will slow you down. So, work early and often with your compliance team to ensure that where you store your data and who has access to your data always remains in compliance.

    Leadership Just Ran Out of Gas on the Migration Budget …

    … and now they want to know when the cost of running applications is best on-premises versus across the public clouds? Don’t break out your abacus just yet. Cost is all about transparency to the needs of the application infrastructure. Too many enterprises are finding that the rush to the cloud was expensive and not well-planned and are shifting critical apps back to the private infrastructure. But you need to go beyond just resourcing noisy neighbors with VM automation. A long-term solution is to optimize the application performance with an integrated APM and infrastructure solution. A more immediate and tactical solution is to leverage a hybrid infrastructure platform that works across multiple on-premises vendors and public cloud vendors to give you the cost analysis you need.

    Application Managers Are Fighting Over the Music  

    On-premises versus public cloud, VMs versus containers, AWS versus Google versus Azure. Where should those applications be running and how can they migrate them? These may seem like the most trivial of issues to be concerned about, but DevOps, architects and managers have deep loyalties way beyond rational factors such as cost, performance and control. Having the ability to manage and plan cost across a multi-vendor hybrid infrastructure to maintain your performance SLAs is critical. Don’t let blind loyalty or the loudest voice control your path. Your hybrid optimization platform should afford you real-time planning and cloud brokerage to ensure you are optimized for cost and performance.

    Your Early Talent Team Has Been Doing the Same TikTok Dance in the Backseat for the Past 8 Hours

    Hearing the same story about why the journey is behind schedule or the same ask for more budget to meet performance SLAs, or even a repeated request to deviate from the existing road map, can wear you down or dilute your focus. It’s important to have a multi-department/cross-functional plan and mapped roles and to measure performance. Keeping the entire team (multiple owners of the “cloud” in a large enterprise) engaged and on the same plan to avoid going into a loop of burned resources and nerves.

    Are We There Yet?

    As with most family trips to magical destinations, the road to a successful cloud migration is fraught with unexpected disruptions—but a good plan can avoid most common challenges. So, no matter what stage you might be at in your hybrid cloud journey, we hope you will reach out to us before you feel the need to pull over when the going gets tough.

    Hope you are all happy and healthy. Please, during this increased time of need, remember to give back to your community as you can.

  • The Rise of the Cloud Economist: The Other CFO

    The Rise of the Cloud Economist: The Other CFO

    The new Cloud Economist job title wrangles runaway cloud costs

    Have you ever forgotten about a subscription? Maybe it was that Amazon Fresh upgrade you never used, charging you monthly payments. Or, your phone carrier slyly tacked on a feature and it went unnoticed for years. All these charges may seem insignificant, but they mount up over time.

    The same is true for cloud IT tools. Many Ops engineers know all too well the surprising bills that accompany cloud infrastructure. While cloud prices may start low, they often rise unexpectedly with hidden server costs, data replication charges, escalating API fees and other fun add-on expenses.

    Conversely, remaining at a low service tier could cause latency and a loss of revenue. Drowning in a sea of hybrid trends and feeling pressure to deploy at lightning speed, it can be difficult to keep track of which cloud models actually advance business objectives.

    Some believe an entirely new role is needed to rectify the gap between cloud and business repercussions—a Cloud Financial Officer, or the Other CFO (OCFO). An OCFO could act as a Cloud Economist, a tech-savvy ambassador who both understands the financial implications of a cloud strategy and optimizes service tiers to their necessary levels.

    I recently chatted with Leon Adato, Head Geek at SolarWinds, on how businesses could better drive cloud cost optimizations. Like a determined accountant sent in to save a struggling city (h/t to Ben Wyatt in Parks and Recreation), the OCFO may be the star companies need to slash the budget and balance the cloud checkbook.

    Why Do We Need a Cloud Economist?

    According to the “Flexera 2020 State of the Cloud Report,” 74% of companies report their annual cloud spending exceeds $1.2 million each year. At 20% of companies, it’s more than $12 million. As cloud spending skyrockets, balancing these expenses becomes business-critical.

    Yet, forecasting cloud costs is tricky. Unexpected complexities often arise with the cloud, skewing initial cost projections. Maintaining cloud oversight becomes especially complex as COVID–19 accelerates more cloud adoption across the board. Budgets are shrinking, and some companies are undertaking extreme measures to remain lean.

    Simultaneously, the ones that advocate for new technology don’t always consider cost implications. “Three clicks and you’re done means a DevOps engineer in the driver’s seat may not be aware of the cost considerations,” said Adato. In recent years, SaaS companies have stressed easy onboarding and developer experience as a top priority. The staying power of developers to adopt new tools is arguably at an all-time high. But while it’s important to improve developer workflows, developers don’t necessarily have business acumen. “Finance is a lexicon of itself,” noted Adato.

    Thus, some view a Cloud Economist role as necessary for translation across divisions. “IT divisions shouldn’t be encountering sticker shock when they view their cloud infrastructure bills,” he said. “We need IT folks to be able to pay attention to cloud costs in a meaningful way.”

    What Does a Cloud Economist Do?

    A Cloud Economist is an expert that specializes in cloud-spending and cloud cost optimizations. Such a role could help teams realize the efficiency benefits of cloud-native architecture while keeping costs lean.

    This job title truly requires “hands for code and a head for money,” described Adato. He laid out three simple goals of a Cloud Economist:

    1. Increase revenue.
    2. Decrease cost.
    3. Remove risk.

    A Cloud Economist understands the technical underpinnings behind cloud tools and how they support each other within a cloud-native ecosystem. They also appreciate maintenance realities, asking tough questions such as: Will it take 200 code pushes per day to support this microservices integration pipeline? How will server costs change as bandwidth scales? Which plan is most optimized for our needs?

    Specific Cloud Economist Duties

    A Cloud Economist must manage runaway costs associated with cloud adoption. They see the bigger picture and understand the repercussions behind cloud technologies. In terms of specific duties, the role may wear many hats.

    For example, a Cloud Economist may encourage a CSP migration, such as from AWS to GCP. Or, they may foresee the implications of future feature introduction, such as limitations across geographic zones, and advise IT teams accordingly.

    An avid Cloud Economist should also interface with monitoring and testing teams. “API testing before launch can mean the difference between a $25 cloud database bill and a $30k bill,” wrote Rapid API’s Chris McCallister in a separate blog post.

    Other Cloud Economist duties could include:

    • Logging and forecasting rising cloud costs.
    • Becoming Terms of Service (ToS) experts.
    • Avoiding costly data replications.
    • Upgrading servers.
    • Discontinuing unused instances and features.
    • Ensuring elasticity of applications.
    • Database scalability.
    • Increasing CPU power or data loads.
    • Optimizing subscription plans.
    • Considering implications behind feature updates.
    • Limiting the intake of new cloud tooling.
    • Acting as an ambassador between a company and CSPs.

    Traditional IT, or information services, as it was originally called, “has been able to avoid the need to integrate with business,” said Adato. That will likely change drastically as cloud costs escalate and thousands of very small charges amount to “death from a thousand cuts.” It appears that any business size, from startup to enterprise, could benefit from more cloud expense forethought.

    Inherently, DevOps is a cultural movement, not a technical movement, Adato noted. Assigning a Cloud Economist encourages specialization and de-siloing between disciplines, freeing up DevOps engineers to work on projects that matter to them. The role of a Cloud Economist “offloads responsibility that has always been there that may have been ignored,” he said.

    Avoid Ice Town With a Cloud Accountant

    Software architects are often sold on the idea that cloud infrastructure is a cheaper alternative to on-premises. “That statement is false,” Adato said. As an organization cloud evolves out of freemium tiers, where it began cost-wise is often far from where it ends up.

    To navigate the opaque cloud, “we need someone that has fluency and familiarity with tech, understands the platform, understands how code is updated and maintained, and can right-size the cloud platform,” said Adato. Cloud-native certainly has its benefits, but if runaway cloud costs aren’t wrangled, they could equate to revenue loss.

    As author Bob Lewis wrote: “There’s no such thing as an IT project.” We don’t do technology for the sake of doing technology. Rather, we do it in service to the business. A Cloud Economist could help ensure technology answers the business call, not vice versa.

    As of now, the OCFO is mostly a theoretical title; it could materialize as an internal team member or contract hire. Regardless, such a role could advocate for the business and keep operational overhead as lean as possible.

    In general, it may require a dash of hard realism to learn how to avoid plunging the books into a debt-ridden Ice Town.

  • Custom Coding: An Obstacle Along the Hybrid Cloud Journey

    Custom Coding: An Obstacle Along the Hybrid Cloud Journey

    If you’re like 80% of enterprises, you’re somewhere along a hybrid cloud journey. The imperatives of digital transformation, the emergence of DevOps as the de facto enterprise development methodology and the rapidly growing demand for continuous innovation have made hybrid cloud the go-to infrastructure for competitive enterprises.

    Hybrid Cloud Governance Requires Automation

    Despite hybrid cloud becoming the new normal, there are inherent challenges to managing these infrastructures. Not only do IT departments (and those they serve) need to adapt to different processes for provisioning public and private clouds, but they also need to ensure security and compliance across an increasingly heterogeneous cloud landscape. On top of these challenges, IT departments also need to monitor and control cloud costs and manage day-2 operations while seamlessly orchestrating private, public and on-prem systems.

    To tackle these new complex challenges, you need management and automation tools, which help alleviate the security, governance, and cost-control challenges that hybrid clouds inevitably bring. But integrating them with your existing IT infrastructure (e.g., networking, security, backup, etc.) burdens your IT team with significant custom coding requirements.

    The Dreaded ‘Custom Code Tax’

    So, you have your hybrid cloud, and you have your automation tools to optimize it. But now, each one of these tools—whether it’s for simple use cases such as resource naming or complex tasks such as multi-tier workload provisioning—requires integrations with dozens of underlying networking, security and backup endpoints, typically from dozens of vendors.

    These integrations often require custom coding, which is arduous and time-consuming. Your IT people will be stuck writing and maintaining thousands of lines of custom code to integrate your automation tools with all of these endpoints. It’s also expensive. Research by the Standish Group shows that over half of custom-coded projects cost almost double their original estimate, while about one-fifth of custom-coded projects will be canceled before they are completed.

    And the tax doesn’t end there. Governance and security become increasingly complicated and expensive because the proliferation of new tools and processes prevents IT from having a unified view of integration policies, automation playbooks and role-based access. Without the end-to-end visibility necessary to manage and monitor this proliferation of tools and processes or standardized provisioning across all IT platforms and tools, costs are only going to compound over time. Since 60% of all infrastructure outages are caused by human error, end-to-end automation and visibility are now mission-critical for enterprise organizations

    But what is to be done? Organizations need hybrid cloud to meet the demands of digital transformation, and they need automation tools to effectively manage and secure hybrid clouds. Your monetary costs and governance burdens will scale along with your IT, and as your organization invests in new automation platforms, the “custom code tax” will only keep increasing. But if you want your hybrid cloud to work right, there really is no choice but to pay it.

    Hybrid Cloud Management with Codeless Integrations

    Enterprise IT departments need to implement cloud management solutions that offer an alternative to custom coding. Cloud management that takes a policy-based, codeless approach to these integrations eliminates the need to custom-code, thus repealing the custom code tax.

    Take the example of cloud management platforms (CMPs). In the past, CMPs mainly focused on management. However, the complexity of hybrid clouds now requires an equal focus on both management and integration. Software-based, low-code/no-code methods for integrating automation solutions with relevant systems not only eliminate the high costs associated with custom coding but also ensure a governed, standardized approach to integrating automation tools with networking, security and backup endpoints.

    Not only will you save valuable time and budget dollars, but when your integrations are software-based and no longer rely on custom code, you will be able to apply advanced intelligence tools more easily as your organization grows and evolves. If your company wants to integrate certain tools that utilize artificial intelligence (AI) and machine learning, for example, you will run into obstacles trying to abstract data from custom-coded workflows. You can’t apply AI to a language that is unique in business logic because it has been custom-written. There could be a hundred thousand lines of custom code, so you would have to manually go through it all and try to figure out what’s there, who built it, why they built it and what the business logic behind it is.

    Codeless Will Rule the Day

    In a world where multi-tool reigns supreme, the more tools you want to use, the more custom coding you have to do. Enterprises today must be able to use their tools of choice in a best-of-breed approach while maintaining standardization through a robust integration layer. Going forward, this means that cloud management platforms will need to be built around extensibility and make integration a core capability, not an expensive afterthought.

    Forward-looking CIOs are choosing software-based solutions to enable multi-tool to work seamlessly in hybrid cloud environments. This results in lowers costs, better governance, and more robust security, especially as organizations advance their hybrid cloud journey.

  • Micro Focus Strengthens Hybrid Cloud Hand

    Micro Focus Strengthens Hybrid Cloud Hand

    Micro Focus has made available a multi-tenant cloud management platform that can be deployed in a public cloud or on-premises IT environment.

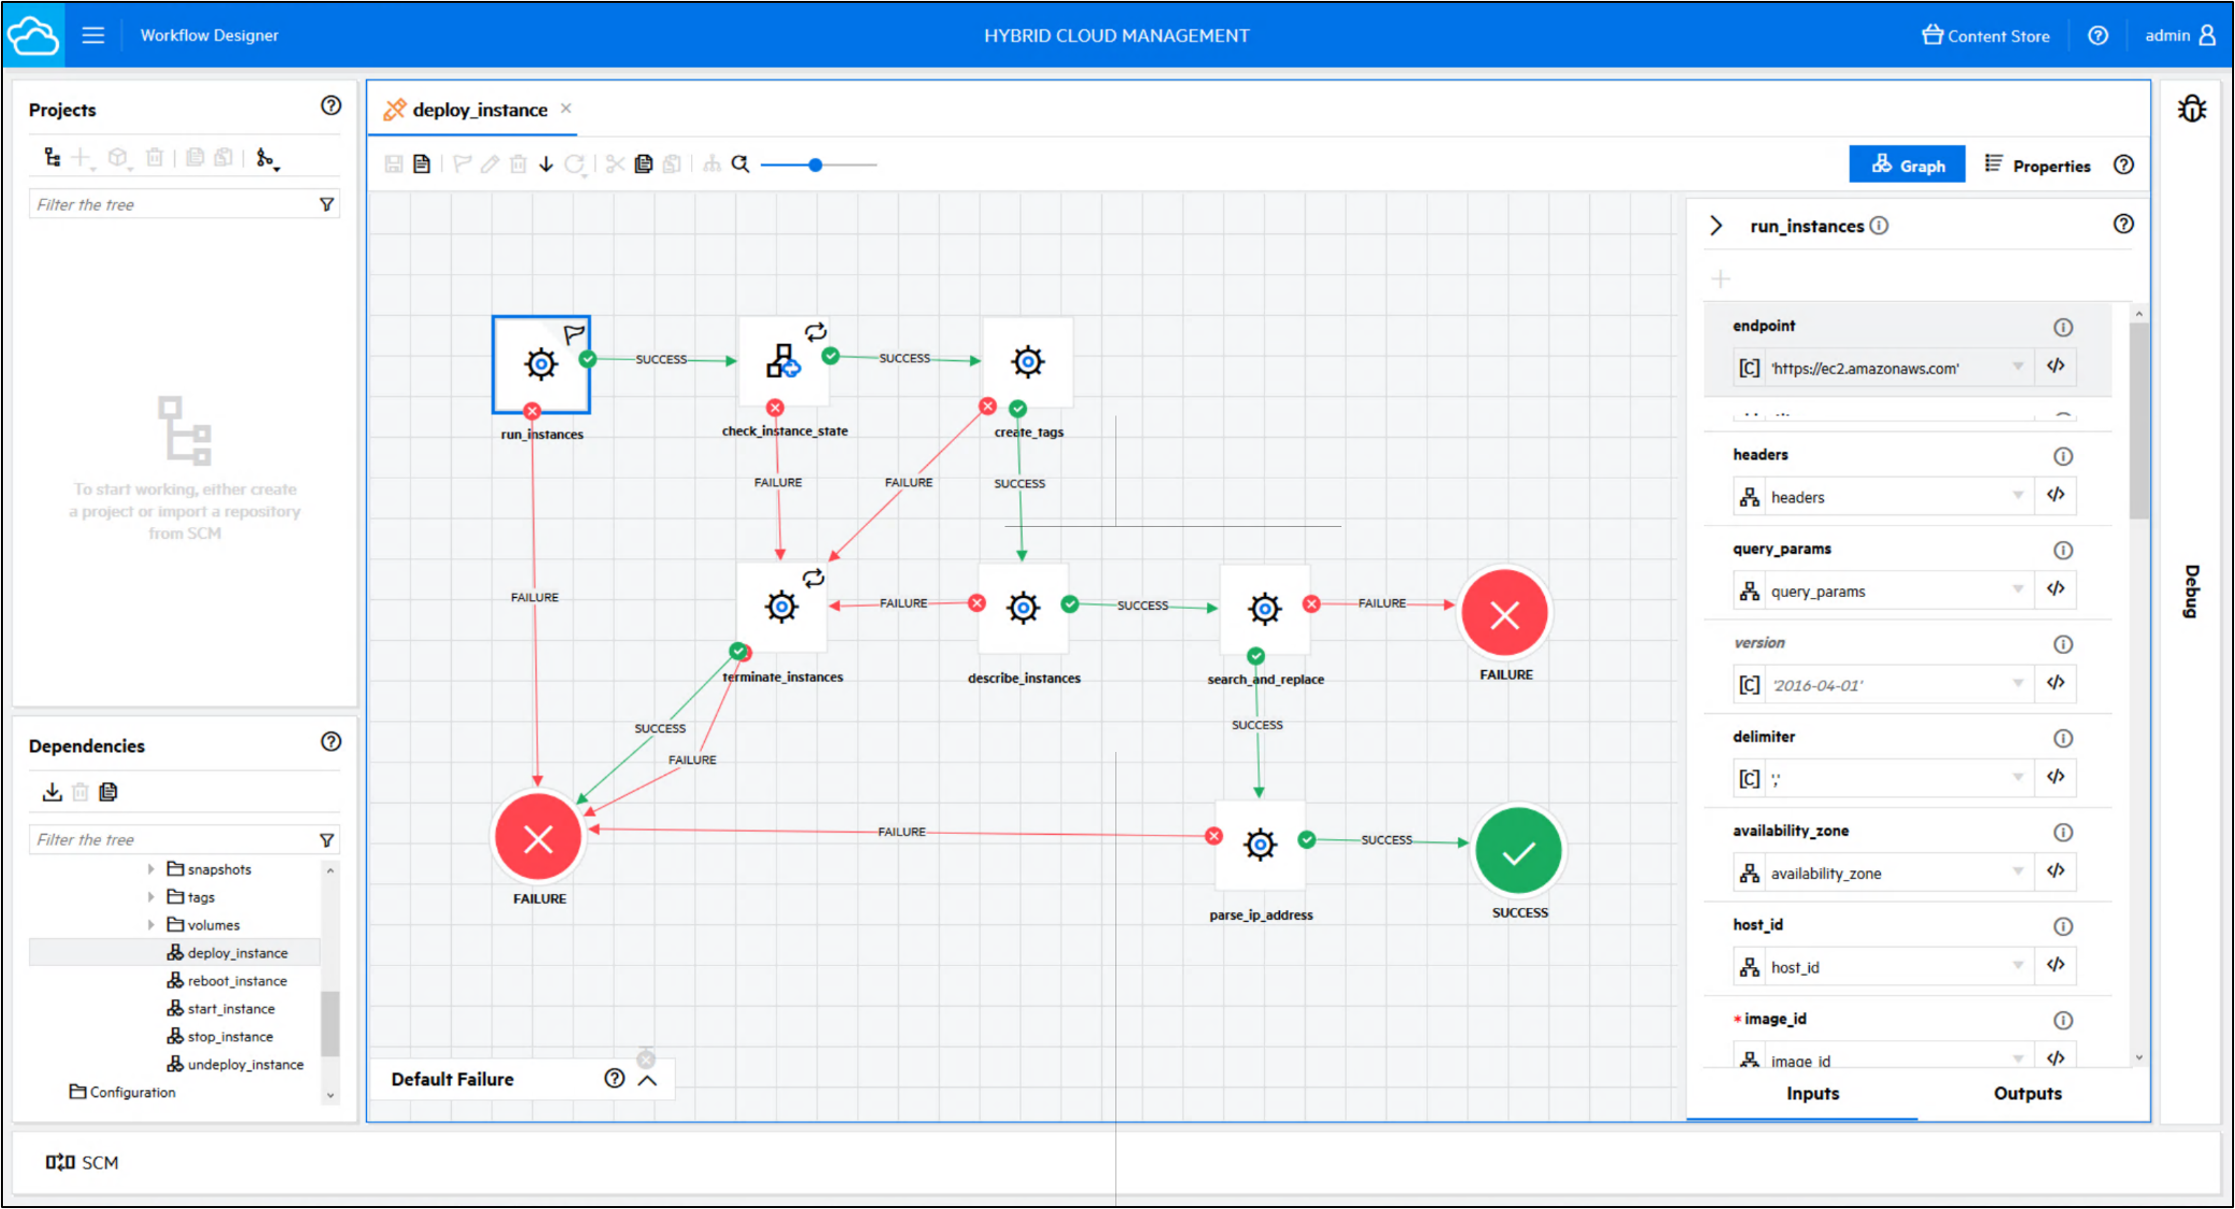
    Travis Greene, senior director for IT operations management at Micro Focus, said the Hybrid Cloud Management X (HCMX) platform makes it possible to unify the management of IT services across a hybrid cloud computing environment spanning a diverse range of platforms, including public clouds and VMware environments.

    At its core, HCMX is a unified portal and service catalog through which IT teams can find, request and consume information and enterprise services. It is built on the same framework as Service Automation Framework, X (SMAX), an IT service management (ITSM) platform also offered by Micro Focus. As such, HCMX can also leverage the same natural language engine, search and virtual agent technologies that Micro Focus makes available on SMAX.

    HCMX also provides a library of reusable workflows through which IT teams can automate processes along with a set of governance policies that automatically trigger workflows based on events or input from an IT administrator that would, for example, limit usage of a specific cloud service.

    In the wake of the economic downturn brought on by the COVID-19 pandemic, there is more pressure than ever to rein in IT costs. One way to reduce those costs in the multi-cloud era is to centralize the management of those environments under a common control plane. Most IT organizations today rely on separate tools and consoles to manage IT platforms in isolation from one another. Not only are licensing fees incurred for each management platform, but also IT often has to hire specialists to manage each individual platform. As hybrid cloud computing platforms continue to mature, it becomes possible to rely on a fewer number of IT generalists to centralize the management of IT.

    Of course, transitioning to a single hybrid cloud computing environment requires a significant amount of time and effort. IT organizations need to make a multiyear commitment to a single platform to reduce the total cost of IT. Many organizations simply lack the ability to enforce the adoption of a single management platform across multiple divisions within an organization regardless of potential savings. However, organizations that do make the transition should be able to not only reduce the total cost of IT but also more flexibly choose where to deploy their next generation of application workloads based on the cost and merits of one platform over another.

    In addition, at a time when the parent company of any one of the major cloud service providers might become a direct competitor overnight, many organizations now prefer to keep their IT options open. The challenge, of course, is making sure workloads deployed on any of those platforms are not dependent on a proprietary interface that doesn’t exist anywhere else.

    Micro Focus, of course, is not the only provider of IT management tools focused on hybrid cloud computing. The decision IT organizations need to come to terms with is determining which of these platforms provides the greatest amount of flexibility at a cost that organizations can absorb.

  • Challenging Cloud Migration Myths in the Wake of COVID-19

    Challenging Cloud Migration Myths in the Wake of COVID-19

    The COVID-19 push to cloud migration, unfortunately, is riddled with myths. Here are some worth busting

    With a substantial increase in the number of businesses now operating from their employees’ homes, and organization leaders realizing that their office buildings are now somewhat unnecessary until a vaccination against the coronavirus is widely distributed, the cloud has played an increasingly important role in IT operations.

    For many, migrating to the cloud has had to happen quickly and at a large scale to cope with the increased pressure on IT infrastructure during the pandemic. At such a turbulent and challenging time, it’s never been more important for businesses to ensure they have the correct IT infrastructure in place.

    As more businesses of different shapes and sizes begin to use cloud computing technology, the realization that greater flexibility, efficiency and scalability can be achieved is being understood by the majority. However, there are still a significant number of enterprises that have misconceptions about how cloud technology can enhance or replace their current IT environment. The outsourcing of IT infrastructure to a dedicated provider can make it difficult for organizations to understand where and how their operations are running and can become a breeding ground for misunderstanding and myths.

    To help clear up some of these myths, I’ve put together a guide to support organizations in the decision-making process and help them understand whether moving to the cloud is the right option for their business.

    Myth 1: Companies should hold tight and do nothing in the wake of COVID-19 as moving IT operations to the cloud is too risky

    This is absolutely not true. While it might seem scary to overhaul IT operations at such an uncertain time and invest in cloud computing technology, there is no doubt that it will be worth it in the long run. Business leaders and IT directors are understandably apprehensive about buying into a cloud migration platform when their budgets are already strapped and the future of their business is uncertain, however, our own research has proven migrating to the cloud can have significant financial benefits.

    Our recent Forrester Consulting TEI (Total Economic Impact) study examined the potential return on investment enterprises may realize by deploying hybrid infrastructure optimization solutions for both the public and private cloud platforms, and found those that have already deployed a cloud migration service have seen a 145% return on investment across a three-year period. Businesses shouldn’t fear that moving into the cloud will have a negative impact to their company economics even though things are difficult in a post-COVID environment, as in fact, deploying a cloud migration strategy will have the opposite result.

    Our Current State of Hybrid Cloud and IT report found that companies that decided to halt their cloud migration altogether as a result of the pandemic are 2.5 times more likely to experience detrimental outages that can hurt company KPIs, as opposed to those that have continued their journey to the cloud over the last four months.

    Myth 2: Cloud migration has to be a quick, ‘one and done’ process if organizations are to cope with the infrastructure demands that remote working practices create

    The term “one and done” cannot be applied when migrating to the cloud. The fact is that cloud migration is a process, and being able to scale up accordingly first requires the right technologies in place. While the pandemic has exacerbated some significant IT challenges across businesses, it has placed a greater focus on ensuring employees can effectively work from home instead of a faster migration to the cloud, which has, understandably, been put on the backburner. For some organizations, remote working has never been part of their practices, but with government guidelines and lockdown restrictions, working side by side has not been an effective way to continue to keep employees safe.

    The immediacy of the shift to remote working has meant ensuring operations could continue as a priority focus for businesses. But as we begin to settle into the “new normal” and most employees are now accustomed to working from their home, vision can be turned to a digital transformation process and ensuring the correct technologies are in place for companies to thrive.

    Myth 3: Halting your cloud migration during COVID-19 will save you time and money and won’t impact your IT systems’ performance

    This is in fact an untrue statement, as businesses that have halted their cloud migration journey because of the pandemic have already experienced significant issues in their IT systems. Our report, which was conducted to better understand how businesses were coping with their migration strategies during the pandemic, has revealed that more than three-quarters (77%) of respondents have reported a lack of access to the correct tools. In addition, 81% of those surveyed have said they have spent more time working across multiple systems to create a single report on IT bandwidth and resources, increasing the amount of time spent on a singular task.

    There is no doubt that deciding to halt a cloud migration strategy because of the pandemic will have impacted organizations’ information technology systems. But that’s not to say it’s too late. Businesses can get back on track and ensure the move to the cloud is just as effective in post-COVID operations.

    Myth 4: COVID-19 has made system transparency and measuring performance more complicated than ever before, especially when factoring in cloud migration

    Measuring performance and system transparency post-COVID can only seem complicated if the appropriate resources aren’t put in place. If businesses and IT decision-makers ensure the correct technologies are readily available and accessible, measuring the performance of a cloud migration strategy should be relatively simple.

    Our survey reveals that access to the correct tools and support services has a direct correlation to business cloud performance. More than three-quarters of those who experienced performance issues during the beginning of the pandemic also say they lack sufficient access to tools. However, companies that had already begun (or actually completed) their migration process at the onset of global lockdowns experienced fewer IT outages. In fact, for more than half of businesses, having impacted access to the correct support services has created a significant hurdle to overcome at a time when they’re already trying to cope with a number of challenges. Comparing this to those that maintained good performance, just under half said access to either type was not an issue.

    As with most things at the moment, apprehension in investment is unsurprising. For businesses, attempting to get sales, productivity and efficiency back on track is the most critical post-COVID action. But, beginning to understand how a digital transformation and cloud migration strategy should be adopted or continue at this time is crucial for survival.

  • What It Takes to Succeed in a Multi-Cloud Environment 

    What It Takes to Succeed in a Multi-Cloud Environment 

    A multi-cloud strategy offers the best possible scenario for ensuring business continuity and helping improve innovation

    Business problems are not “one size fits all,” and neither are cloud architectures. Organizations are looking for specific solutions that deliver on their bespoke needs—a driver for many of them shifting from one cloud provider to working with multiple providers. In fact, 84% of organizations have a multi-cloud strategy. This offers them additional resilience and security when it comes to ensuring business continuity and protecting their business and customer data.

    Having a multi-cloud strategy could mean many things. It could mean using different cloud data warehouse (CDW) providers such as Amazon Redshift and Snowflake. It might mean hosting operational data stores in AWS, but transferring and performing analytics on that data in Azure. Or, the underlying cloud platforms could differ, such as two different Snowflake instances—one on Google Cloud Platform and a second on Microsoft Azure. These different CDWs could be hosted in different parts of the world. Sometimes, having a multi-cloud strategy means all of these at once.

    Common Mistakes

    Organizations often lock themselves in (often inadvertently) to a single cloud vendor by choosing tools or technologies that are very difficult to make portable. It can be very tempting to go for the most simple, seamlessly integrated piece of technology that a cloud vendor has to offer, but if that limits your choice of vendor later and does not interoperate with other clouds, it can lead to regret.

    While there is an uptick of adoption for multi-cloud strategies, it is still in the early days—especially for many organizations that are still coming to grips with moving on-premises workloads to the cloud. Expect a lot more in this area as more customers demand that clouds work better together and resist services that lock them in.

    Another mistake organizations make is that they do not account for the complex challenges that come with more data and differing technologies. Integration between data sources and solutions will be tough since not all providers offer seamless connections with other tools. That is why it is so important that organizations use technology that is cloud-agnostic, saves on costs and seamlessly provides better transition between clouds.

    Enterprises need to have the right technical expertise, technologies and tools in place or they run the risk of failure. As businesses increasingly move to a multi-cloud strategy, the specialized skills they need to turn data into value are changing at staggering speed. Managed tools that leverage the power of the cloud enable us to handle more varieties of data, in larger amounts, at greater speed and scale than ever before. But the platform and the tools aren’t the only things that have changed—the techniques and resources on data teams are also shifting.

    A data team focused on hand-coding and retrofitting technologies for cloud migration is not necessarily one that is prepared for modernizing data architecture and implementing a multi-cloud strategy. The data team needs to include people with the ability to organize data for cost-effective analysis and reporting that leads to intelligent conclusions—that is, data engineers with cloud training and experience as well as the ability to understand the data itself.

    How to Gain Control Over a Multi-Cloud Channel

    Organizations adopt multi-cloud strategies for a multitude of reasons. They may be sensitive to cost, have preferred partners, have adopted different grassroots technology in different departments and so on. However, sometimes the strategy is about the capabilities that are available. Cloud computing is an innovative space. While core cloud platforms for the major clouds such as Amazon AWS, Microsoft Azure and Google Cloud Platform are very similar in functionality for their core services such as storage, compute and databases, when it comes to the more advanced services such as machine learning (ML), artificial intelligence (AI) and advanced analytics, there are real advantages to being able to work across multiple clouds. For example, you might find that the data warehouse platform that best suits your needs is on AWS but the best ML tool for processing that data and inferring meaning is on Google Cloud Platform.

    To have a successful multi-cloud strategy, companies need to use cloud-agnostic tools and technology that works with more than one cloud data warehouse and are able to support all the different environments with as little friction as possible.

    Enterprises will need to embrace the best of what cloud technology vendors have to offer as opposed to watering down their offerings for a lowest-common-denominator, works-everywhere-but-limits-functionality-approach.

    With a multi-cloud approach, all the advantages of cloud remain but you avoid many of the pitfalls. You still have the cloud scaling and cloud pricing to keep costs down. However, there is danger in being limited to a single cloud vendor and their ecosystem. Particularly for companies that want to lead by innovation, especially innovation with data, where the accelerating pace of technical improvement continues across all the major cloud vendors. Maintaining the flexibility to work on the best cloud platform to solve a particular business problem or process will give them the competitive edge.

    Working With Multi-Cloud Environments

    Here are some tips for making multi-cloud environments more manageable:

    • In general, work with existing, open, and emerging standards wherever possible.

    • Use containers for compute—ideally on Docker or Kubernetes.

    • Cloud storage such as Amazon s3 or Azure Blob Store are usually quite simple and migration is manageable. However, stick to common open data standards such as AVRO, Parquet or even CSV.

    • Security is a place where cloud vendors would love to lock you into their technology and can be painful to move. Use a third-party security provider such as Auth0 or PingIdentity.

    • For more cloud-agnostic and future-proof configuration management, consider Terraform over Cloudformation and other templating systems.

    • Writing serverless functions can be a huge advantage in terms of simplifying management; however, it’s also a place where a cloud vendor can heavily lock you in. Think carefully and keep your logic in a widely supported language such as Python or Node (Javascript).

    • When running images avoid cloud vendor operating systems over popular third parties such as CentOS or Ubuntu.

    • Whenever you engineer software that interacts with cloud APIs, design the layers of abstraction from the start and think about how you could migrate to another cloud. Once an application has been written to operate in two clouds, adding support for the third and fourth becomes incrementally easier.

    • Choose tools that are built specifically for and also enhance the major cloud platform to ensure you have the right strategies aligned to the right platform. As mentioned above, different cloud providers do certain things better. Make sure to understand what tools work best in which cloud environment—or better yet, find solutions that are purpose-built for cloud data warehouses to maximize your ROI.

    • Implement tooling to track usage across clouds for budgeting and resource allocations and latency to identify architectural pain points that may need remediation.

    •  Evaluate independent software vendors’ offerings that extend the capabilities and scope of what is available in a native cloud service provider offering.

    • Select a solution that extends the cloud object store to multiple clouds, as a default multi-cloud deployment tier, to allow for the greatest degree of flexibility.

    While a multi-cloud strategy may seem overwhelming and difficult to manage at first, it ultimately offers the best possible scenario for ensuring business continuity. Having the right tools in place will ensure manageability while empowering you to lead in innovation, ensuring the best possible return for your investment.

  • Accurics Adds Compliance Control Support to Code Analyzer

    Accurics Adds Compliance Control Support to Code Analyzer

    Accurics, at the online KubeCon + CloudNativeCon 2020 conference today, launched an update to its open source Terrascan static code analyzer that adds support for Open Policy Agent (OPA) engine to make it easier for developers to create custom compliance policies in addition to leveraging more than 500 out-of-the-box policies based on the CIS Benchmark.

    In addition, Terrascan is now available as a GitHub Action and is included in the popular Super-Linter GitHub Action. It can be installed as a pre-commit hook to help detect issues before code is pushed into a repository as part of a DevOps workflow.

    Cesar Rodriguez, head of developer advocacy at Accurics, said the latest version of Terrascan has also been rewritten in the Go programming language to improve overall performance.

    Terrascan analyzes the code created to manage infrastructure as code for vulnerabilities as well as indicators of drift. It then creates a threat model for cloud application workloads and, if necessary, will share data with third-party tools to automatically roll back cloud settings to their last known approved state. Once the model is constructed, Accurics monitors the application workload for changes that introduce risks and generates a topology for each workload in real-time to identify any potential indicators of drift.

    A recent report based on an analysis of cloud services published by Accurics finds misconfigured cloud storage services are commonplace in a stunning 93% of the cloud deployments analyzed, with most also having at least one network exposure in which a security group was left wide open.

    The report also finds hardcoded private keys turned up in 72% of the deployments analyzed. Unprotected credentials stored in container configuration files were found in half of these deployments. A total of 41% of the organizations had high privileges associated with hardcoded keys. In 100% of deployments, an altered routing rule exposed a private subnet containing sensitive resources such as databases to the internet.

    Overall, the report suggests that only 6% of cloud configuration issues are being addressed using manual remediation processes.

    Ideally, developers should be implementing cybersecurity and compliance controls as they deploy applications in the cloud. The challenge is that while developers have ready access to tools to automate the configuration of those services, not many of them have tools to verify whether those services have been implemented properly.

    IT organizations will still need to scan for vulnerabilities in runtime environments. However, tools such as Terrascan will enable IT teams to advance the adoption of best DevSecOps practices by providing developers with access to scanning tools that can be incorporated easily with a continuous integration (CI) workflow.

    Of course, the biggest DevSecOps issue remains culture. However, most developers don’t intentionally want to deploy insecure cloud applications. If given access to the right tools, most developers will do the right thing as long as it feels like a natural extension of an existing workflow rather than an unnatural act that was defined by a cybersecurity team that has little to no idea how applications are actually constructed.