Category: DevOps Practice

  • Top 5 Best Practices for DevOps Monitoring

    Top 5 Best Practices for DevOps Monitoring

    Today organizations are required to deliver on higher levels of customer satisfaction for their online services. Many, however, are forced to support these initiatives with an interrupt-driven approach as they react to fix things after they break. However, for a more proactive approach and to manage expected high levels of SLAs, organizations can opt to reduce their amount of unscheduled downtime by implementing a continuous delivery (CD) model to their development efforts.

    What is critical in the CD model is the ability to monitor and manage systems in a structured way, getting early detection of problems so organizations can make changes before the system is impacted. While unexpected failures make interrupt-driven work unavoidable at times, organizations can become more proactive by examining their current approach and toolset against business needs to help create a path to continuous service delivery optimization.

    Effective CD Models Need Effective Monitoring

    As a starting point, organizations need control and visibility into their DevOps environment by collecting and instrumenting everything. Considering the amounts of data, this can be an insurmountable challenge for most organizations. To get started, follow these five best practices to perform DevOps monitoring efficiently and quickly in a measurable and scalable way.

    Step 1: Collect the Data. You can’t manage what you don’t measure! It is important to take inventory of what is being collected today and align with business and executive teams to collaborate on the aim of the services delivered. Analyze the inventory collection of metrics with questions such as: “Why aren’t we collecting this? How does this fit into our goals? Have you ever seen a failure in X? How often should we be measuring this? How long should we keep it for? Is that important?” Teams also should evaluate how they are collecting the information and consider the best architectural approach for collecting their metrics, including whether pull, push or pull collection methods are better. Once goals are understood and the inventory of data is collected, look at what else your organization should consider collecting.

    Step 2: Correlate and Triage. Correlation of data is needed to understand it, but data comes in at different frequencies, in different time frames and from different sources. Work to normalize the data to understand it, perform comparisons against the different incoming metrics and establish baselines for basic service availability. Since organizations aim to go beyond basic service level agreements (SLAs) and offer a high-performing solution, constantly ask what the organization is missing from a data perspective and how it relates to business initiatives. Asking that question from the collection, correlation and triage perspective is critical.

    Step 3: Identify Trends. Organizations need to examine historical data to identify trends and take action before issues arise and customers complain. Establish alerting thresholds by outlining what a normal day looks like from a monitoring performance and customer perspective, and then identifying examples of what makes an abnormal day. This ties in with managing infrastructure inventory and understanding safety thresholds for each of the components that potentially could impact the service offering. It’s critical to communicate these findings with teams and business-line managers to prevent service delivery problems from happening and optimize offerings based on identified trends.

    Step 4: Notify and Act (Automation). In manual mode, a notification is delivered and then the team reacts. But teams are continually pushed to do things faster, and automation can help. To get to that point, organizations must understand where best to add more automation. How do you gather the right telemetry that delivers consistent answers that the machine can operate rules against, and do you leverage an automated process or notify a person? The desire to improve to a faster process requires a shift from manual to automated practices.

    Step 5: Predict (What-if Analysis). If you don’t take the time to go through the first four steps in a methodical way, it’s very difficult to reach this final step without always remaining in a manual mode. To balance costs and availability, it’s critical to discuss with the executive team how to predict customer service consumption (revenue) against the amount your services are going to cost the business.

    For example, developing a service that can alert customers of a potential service disruption due to disk space can be accomplished only by clearly setting business goals, then using the right metrics and events platform leveraging a time series database. In this case, the business goal is to ensure no service disruption due to failures such as low disk space; the metric monitoring is for disk space for each customer instance with the appropriate threshold alert set off by an automated trigger; and the action is an email to the customer letting them know of the situation and what action they can take (reduce load or upgrade for more disk space). In this example, it is important to marry business logic with the monitoring practice to make service a successful experience for customers. Furthermore, this approach will help teams to not only predict user experience but also help to predict OpEx and CapEx better into the future.

    That’s the benefit of the ability to predict with the right monitoring approach—to make informed business decisions based on results. Customers appreciate that, and proactive support is much better than being reactive.

    Emerging trends such as microservices, containerization, elastic storage, software defined networking and hybrid clouds are pushing the boundaries of DevOps monitoring. The right monitoring plan can identify and resolve problems before they affect critical business processes and enables customers to plan for upgrades before outdated systems begin to cause failures and outages for users.

    About the Author / Mark Herring

    Mark Herring is CMO at InfluxData. He is a well-rounded silicon-valley executive with proven experience in taking complex technology and making it understandable to the broader audience. His deep developer roots are never far from his mind as he looks at trends and asks the tough questions on whether the technology is here to stay or just another fad. Currently Mark is Chief Marketing Officer at InfluxData. Follow him on Twitter and connect with him on LinkedIn.

  • Building a Services and IoT Platform with DevOps, Part 4

    Building a Services and IoT Platform with DevOps, Part 4

    IoT platforms and their solution development have crossed different maturity levels. At first, devices were primitive, isolated and working with limited functions before slowly evolving to communicate and connect with other devices using lightweight communication protocols, and then stepping into advanced level with remote management of devices, harvesting the data from devices and smart decisioning and analytics. Beyond that, IoT has moved to optimized levels of using multiple technology options and adopting cloud and DevOps disciplines to build intelligent IoT solutions.

    This article focuses on giving insights on choice for IoT platforms and factors influencing build or buy options for IoT solutions, different hosting options, factors on IoT development in the cloud and more.

    IoT Platforms: Build, Buy or Both?

    The dilemma of whether to build an IoT system from scratch or buy an off-the-shelf platform still continues. Below are some of the key factors to consider before making the critical decision.

    1. Price: If you plan to build an IoT platform, the infrastructure setup and operation costs can be high. And, as you plan to scale, there will be additional infrastructure cost in setting up additional data centers in that region. If you buy an IoT platform, prebuilt infrastructure is available across global data centers to scale out on a per-usage basis. Plus, you get the the benefit of buying devices from a certified partner ecosystem with discounted device prices. You can buy a few devices from cloud vendors or other device manufacturers, and use mix of devices, mix of cloud/multi-clouds or on-premises, using mix of platform as a service (PaaS)/infrastructure as a service (IaaS) at competitive prices.
    2. Time to Market: A house-built IoT systems will typically take about six to 12 months to complete, including infrastructure setup, device development and software development and testing. Depending on the complexity of the business case, the release cycle may take even more time to get to production, especially with ongoing device technology updates, lack of protocol standards and new business demands.
      Under the buy option, you can buy preconfigured end-to-end solutions available for common IoT use cases such as remote monitoring, predictive maintenance and connected factory, and these solutions can be customized based on need. You can even try to build only few components of IoT solution which may not be available from the vendor, such as the devices/edge, build a field gateway and use preconfigured solutions for data ingestion and data processing, data analytics and data storage components. There are starter kits available to quickly prototype, evaluate and deploy, eliminating spending more cost and effort, before hitting to the ground.
    3. Skillset/Expertise: Building an IoT platform requires a skilled team with expert knowledge of software and hardware and development, which costs more. Currently there is lack of skilled IoT experts with a mix of software and hardware knowledge in traditional industrial-based enterprises.
      When buying a IoT solution from vendors, the solutions are prebuilt and guided by standards and best practices. The platforms are built by experts who are proven with cloud infrastructure, based on their experience working with large customer base and customer support—necessary for IoT platform development.
    4. Scalability: When you plan to scale your business, you need to scale your infrastructure as well. With millions of devices connecting to your infrastructure to send and receive data and firmware updates, monitor the devices, support multiple range of network providers and store large volumes of data being collected and processed, you need a scalable infrastructure on-premises or in the cloud to meet those demands. Setting up a scalable infrastructure on your own requires skilled labor, effort and cost.
      Real-time streaming and data processing capability is available for large volumes of data workload, enabling scaling of individual components of IoT solution, as well scaling as scale units (group of components for data ingestion, data processing and data storage). Choices of different cloud vendors give you options to scale based on demand, horizontally or vertically, adding/removing devices with portability options and providing on-demand simulated test environments with the flexibility to choose multiple clouds or a mix of PaaS/IaaS options from different clouds or hybrid infrastructure.
    5. Security: For in-house IoT development, teams should be aware of various security attacks and develop systems with current security strategies and technologies to both protect data and devices and maintain data privacy. A large infrastructure is needed to support the sandboxed hosting of data in separate geographic regions for secure data storage, device security and user security.
      IoT platform vendors provide security standards. For example, Microsoft provides SDL (Security Development Lifecycle), which enables developers to follow the standards during device development and ensures development happens with security built at all parts of system. These platform providers have prebuilt infrastructure for secure data storage, cloud security, user security, application security and device security, and has separate security teams to protect the data at all levels.
    6. Analysis & Visualization: It’s estimated that 90 percent of the large volumes of data collected from millions of devices remains unused in most enterprises. To tap the data for valuable business metrics, data analysis/algorithms should be updated as industry and device requirements change and extensions are needed to integrate data with data analysis tools to churn the data. There are open-source and proprietary tools available for data mining and data analytics and custom dashboards must be built to monitor the telemetry, setup rules and actions.
      Preconfigured solutions and most IoT platform providers have out-of-box data analysis tools integrated and rules can be defined to analyze data with customizable dashboards, enabling you to focus more on business outcomes and how to churn/mine data, rather than focusing on building algorithms/tools/dashboards from the scratch.

    Factors Driving Cloud-based IoT Development

    Considering the various factors, a hybrid option with mix of buy and build for IoT platform components is better compared to building the platform from scratch, as you get out-of-the-box features from the off-the-shelf platforms that are customizable and extensible to business needs.

    The following are some of the factors driving more and more IoT development in cloud (single/multi-cloud/hybrid), making IoT grow exponentially:

    1. Increasing number of devices – billions/trillions of devices interconnected
    2. Need for remote processing power and high compute
    3. Need for hyperscale systems for processing hot/cold/warm/fast data pipeline with low latency
    4. Need a platform that can quickly evaluate, prototype and deploy IoT applications
    5. Need a platform that provides security by design across devices, gateways, networks, data processing, users and applications
    6. Usage of advanced analytics and monitoring solutions available in cloud
    7. Leverage interdevice communications, interservice communications
    8. Utilize preconfigured IoT solutions for most of the popular use cases such as remote monitoring, predictive maintenance, with proven practices/patterns.
    9. High data storage, highly scalable with minimum cost to deploy
    10. QoS features in cloud—security, performance, usability, backup, etc.
    11. Cloud gateway providers have support for various devices and provides extensibility
    12. Cost of devices, cost to deploy and internet usage has dropped
    13. Out-of-box support and availability of big data and machine learning techniques in the cloud with mobile data visualization
    14. Ease of integration with DevOps tools in cloud, end-to-end testing with simulated devices as containerized environments in cloud

    Expanded internet connectivity, reduced cost of devices, increased spread adoption of remote devices such as smartphones, usage of big data, machine learning techniques and cloud adoption, competitive pricing models and more are the key drivers for IoT’s growth in cloud.

    About the Author / Lavanya Subbarayalu

    Lavanya Subbarayalu is Senior Architect working with Technology Office in HCL Technologies. She has expertise in IOT, Azure, DevOps consulting & Microsoft technologies. She is associated with DevOps COE, working on design and Development of DevOps solutions and consulting tools. Connect with her on LinkedIn.

  • Gene Kim, DOES17 Speakers Discuss the Deployment Age

    Gene Kim, DOES17 Speakers Discuss the Deployment Age

    In a special episode of Electric Cloud’s Continuous Discussions (#c9d9), Gene Kim and speakers from the upcoming DevOps Enterprise Summit San Francisco (DOES17) discussed the deployment age, and how DevOps practices and automation can unburden teams and boost productivity.

    The panel included: Mik Kersten, CEO of Tasktop; Robin Yeman, fellow at Lockheed Martin; Courtney Kissler, VP of digital platform engineering at Nike; and, our very own Sam Fell and Anders Wallgren.
    Continue reading for some of their top takeaways:

    Kersten discusses the importance of spreading the word about DevOps tooling: “I think the best thing we can do is accelerate this turning point by giving the rest of those 15 million developers working in all of those other companies the tools that they need to apply these technical practice and to reorient their organizations to actually leverage them.”

    Yeman on the multiplier effect of automation: “DevOps is definitely all about the people, but the automation enables people to have such a higher outcome and better business results. It’s almost like a force multiplier for companies.”

    It’s crucial to look at the bigger picture of software delivery, advises Wallgren: “If you don’t have a big picture of what your value stream is from one end to the other, it’s hard to convince people that the problem they’re looking at is in fact not the right problem to be focusing on, or whether that is the right or wrong problem.”

    Organizations that employ transformational leaders succeed, claims Kim: “We see people driving DevOps transformations in large complex organizations, specifically the DevOps enterprise community, and my claim would be that these people are being promoted at a rate far higher than the population at large. My interpretation of this is that the value that’s being created by these leaders is appreciated and they’re being put into roles where they’re being asked to make an even greater contribution across even a broader portion of the organization.”

    You can’t just optimize for cost and efficiency anymore, explains Kissler: “There’s this realization that we’re all shipping software and really embracing that and understanding that organizations that have typically optimized for cost and efficiency are not going to win. And so, optimizing for speed to value, the value stream is a huge shift as well.”

    Yeman explains the awesome leadership structure at Lockheed Martin: “At Lockheed, most business leaders were engineers at one point in time. So, if you’re looking at the President or the Vice President, they started out in software, or systems, or as a tester. They have to have depth in their area because then they can really empathize with what we’re building and with, you know, the people that are building it.”

    More on the wonders of automation, per Kersten: “Agile has scaled up, but it kind of hit a brick wall until automation came into play and organizations realized that they needed reliable, predictable, and safe ways to deploy. I think one of the most interesting things that happened when the technical practice matured around that automation layer is all of the other gaps it uncovered.”

    Wallgren on the ironic manual nature of the software delivery industry: “I think that one of the paradoxes of what we do in software teams is we don’t use software at all, most of the time, to help us produce our own software. We use people.”

    Kim reflects on revelations after reading “Disrupt or Die” by Jedediah Yueh: “The real value that DevOps will create is not going to be in the FAANGs, the Facebook’s, Amazon’s, Apple’s, Netflix’s, and Google’s of the world, but it really is in the large brands in every industry vertical as they either disrupt, get digitally disrupted, or digitally disrupt themselves.”

    Kissler on how to respond to the exponential growth of digital disruption: “I think the acknowledgement of where we’re at and where we need to go and how fast we can get there is a huge component of responding to the digital disruption.”

    Watch the full episode:

    Want more Continuous Discussions (#c9d9)? We hold our #c9d9 podcast every other Tuesday at 10 a.m. Pacific. Each episode features expert panelists talking about DevOps, Continuous Delivery, Agile and more.

    Check out all past episodes and panelists here.

    About the Author / Anders Wallgren

    Anders Wallgren is chief technology officer at Electric Cloud. Anders has over 25 years’ experience designing and building commercial software. Prior to joining Electric Cloud, he held executive positions at Aceva, Archistra, and Impresse and management positions at Macromedia (MACR), Common Ground Software, and Verity (VRTY), where he played critical technical leadership roles in delivering award winning technologies such as Macromedia’s Director 7. Anders holds a B.SC from MIT.

  • How to Make Your Software HIPAA-Compliant

    How to Make Your Software HIPAA-Compliant

    Creating software for the healthcare industry must always follow strict requirements and limits set by both state regulators and medical organizations. In this article, we will focus on becoming compliant with HIPAA (the Health Insurance Portability and Accountability Act of 1996) by building a proper IT solution for corresponding institutions, while also considering the HIPAA compliance software checklist.

    By the end of 2017, the North American healthcare IT market is forecast to value $31.3 billion. According to Healthcare IT News, the annual growth rate is about 7.4 percent, which will allow the market to become almost $10 billion bigger than it was in 2012. Why has the market grown so fast? The main reason is the need to implement more IT systems in medical organizations, thus creating a higher demand. Of course, there are also other factors that drive market growth.

    Other factors that increase the healthcare IT market include:

    • A growing pressure to cut medical costs;
    • A high demand for healthcare system integrations;
    • A higher ROI due to implementing IT systems in health care;
    • Serious governmental financial support;
    • The need for computerized physician order entry (CPOE) adoption; and
    • Aging populations.

    Healthcare IT tools must correspond to all HIPAA requirements to make medical institutions integrate them. Let’s talk about the major aspects of software development in this industry.

    How to Become HIPAA-Compliant

    Here, we will cover the elements that must be implemented in software for medical organizations to ensure HIPAA IT compliance. Based on the following recommendations, developers can adopt the features they need to adhere to all requirements.

    Audits

    According to the Act, healthcare providers must perform regular audits to identify possible risks for data breaches or privacy violation. A HIPAA-compliant software should utilize these audits to analyze the compliance level of a particular medical organization and provide it with detailed information concerning risks and current errors, including recommendations. The audits may include a form of quizzes, which will make them easy to use for medical staff.

    Recovery Plan

    The above-mentioned audits will help forecast risks or detect errors related to HIPAA compliance. On the other hand, a remediation plan will allow healthcare providers to correct mistakes and prevent their reappearance. That is why such plans have to be included in medical software. Furthermore, every medical institution has to develop its own recovery plan, taking into account its specialization and implemented systems. The software should be able to initiate a particular plan for a specific situation.

    Documentation

    The main task of any medical software is to work with documents. Since the software helps facilitate documentation processing, many healthcare providers implement such systems in their organizations.

    Required principles, which software development organization Archer Software uses in its own projects, for medical software in documentation processing include:

    • Comprehensibility;
    • Simplicity;
    • Strict structure; and
    • Secure data storage

    HIPAA violation fees are huge. The price of breaking a rule can reach up to $1 million. Reliable data storage, which protects from hacker attacks, will allow organizations to save money and ensure electronic protected health information (ePHI) security.

    Managing Relationships with Business Associates

    HIPAA-compliant software must also handle the company’s relationships with its business associates, including contractors responsible for managing ePHI. A system must monitor the execution of specific agreements regulated by the Omnibus Rule of HIPAA. This will help healthcare providers ensure the security of PHI while entrusting it to business associates.

    Security

    It is almost impossible to fully exclude the risk of data breaches in any medical organization. Software must be able to detect those breaches, create a corresponding report and apply preliminary measures to avoid further data “sharing.” It also has to prevent data breaches by blocking the use of portable data storage devices.

    HIPAA Compliance Checklist for Software Development

    Below is a list of all the necessary elements for HIPAA-compliant software, based on the safeguards listed in the HIPAA Security Rule. The implementation of these elements will allow your software to ensure both ePHI security and privacy.

    The necessary features for HIPAA-compliant software include:

    • User authorization;
    • Access control;
    • Authorization monitoring;
    • Data backup;
    • Remediation plan;
    • Emergency mode;
    • Automatic log off; and
    • Data encryption and decryption.

    Now that we’ve covered off the requirements for IT solutions designed for medical organizations, let’s proceed to the aspects of hospital management software development.

    Hospital Management System Development

    Besides HIPAA rules, custom hospital management systems (HMSs) have to correspond to other internal requirements that will allow medical staff to get as many advantages as possible from using the medical software without compromising patient privacy or data security.

    The requirements for HMSs are as follows:

    • An HMS has to be comprehensive for any medical employee.
    • The UI must be highly informative and laconic.
    • The system has to have a user access control based on employee responsibilities.
    • An HMS must contain a reliable security system that encrypts stored data.
    • The software has to provide functionality for extending or improving clinic automation.

    Taking into account the tremendous financial penalties for violation of HIPAA principles, healthcare institutions strive to implement IT systems that fully correspond to the requirements of the Act. That is why software developers have to be aware of new state requirements in the healthcare industry to offer medical organizations convenient IT solutions at a reasonable cost. This is especially crucial for startups just entering this market. This knowledge will allow healthcare providers to get HIPAA compliant software and help IT outsourcing companies grow their business.

    About the Author / Adam Edmond

    Adam Edmond is a technology writer, interested in the cloud, app and software developing niche. However, he can’t stand mathematics. Edmond has also lead courses in visual effects, animation and digital marketing for both the Western Australia School of Art and Design and Murdoch University. Connect with him directly.

  • How to Succeed with DevOps by Outsourcing Software Development

    How to Succeed with DevOps by Outsourcing Software Development

    The DevOps journey can be successful when you use offshore outsourcing software partners, but it requires careful attention from your IT leaders.

    The old saying, “The only constant is change,” has never been more true for software development, whether your company is a SaaS provider or a manufacturer of discrete products that rely heavily on software delivered by your IT department. For the past several years we have seen four key movements:

    1. The continued adoption of outsourced software development. As far back as 2013, it was reported that 2 out of 5 CIOs surveyed planned some sort of outsourced software development for the coming year.
    2. Increased outsourcing options. While outsourcing to India is still a legitimate option today, it’s certainly not the only viable option available. Companies are now able to answer the question: “What country will provide my outsourced programming team?” in multiple ways.
    3. Agile as a mainstream methodology. Software development teams continue to embrace Agile as the preferred methodology for software development projects.   
    4. Interest in—or adoption of—DevOps. Since the term “DevOps” was introduced by Andrew Shafer and Patrick Debois at the 2008 Agile conference in Toronto, large and small companies alike have shown increased interest in embracing DevOps and the promise it holds for rapid software deployment.

    The current state of tools and service provider capabilities should entice IT leaders to adopt (or continue to adopt) DevOps methods for software development. More than ever before, there are capable teams of programmers across the globe that you can tap into for a successful software.

    There is No Substitute for Good Process

    The goals of higher output and greater efficiencies and even “continuous deployment” through DevOps have their roots in elite manufacturing methods such as kanban and lean manufacturing. Like its manufacturing method cousins, DevOps success hinges on good process. To see improvements through the use of DevOps, you must have clear understanding (and description of) your current software development process. You need to communicate your processes clearly in words and pictures with your outsourcing partner. Issues that are birthed out of shortcomings in your DevOps process will be exponential when you add the variable of outsourced development into your work steps.

    Key Takeaway: DevOps is only possible through good process. If you’re not committed to good analysis and continual improvement of your processes, then the use of an outsourced software developer will only allow you to create flawed software and generate chaos more rapidly.

    Tools Create Speed

    If good process is the engine of DevOps, then automation tools are the gasoline that makes the well-designed process run with speed. Automation of good process makes it possible to eliminate bottlenecks in the software development cycle—you can truly “sprint through your sprints.” Perform an inventory of your tools:

    • Are you able to seamlessly (and automatically) promote code?
    • Can you perform test-driven design?
    • Can you perform test-driven development?
    • Can you easily associate features and fixes with promoted code?
    • How do you perform regression testing?

    Key Takeaway: Automation tools must be used with consistency by you and your outsourcing partner. These tools will enable the process that you all follow daily in the development activities of your project.

    Choose Wisely

    Having the right outsourcing partner for software development is important. To outsource successfully in a DevOps approach, you must be very selective in your choice of an outsourced software development team.

    • The best partners employ a programming staff that have achieved the major certifications that are important for your DevOps project needs. Moreover, a good partner invests in its programming staff’s training on a continual basis. We like to see evidence that its programming staff regularly renews their certifications.
    • Experience. Equally important is having a software outsourcing team with demonstrated experience in your business vertical (example: discrete manufacturing, banking, etc.) and expertise in the system functional area (e.g. finance, e-business order processing, warehouse management, etc.). Of course, the software development team also should be versant and have demonstrable experience in the use of Agile and DevOps techniques.
    • The right partner should be neither too large nor too small. The outsourcing company needs a pool of programmers large enough to keep with the intended work pace of your project. Conversely, we caution IT managers to be wary of extremely large outsourcing companies. Your project and company must be “big enough to matter” to the partner you select. If you are seen as too small in terms of the revenue opportunity, the outsourcing company will defer attention and its top talent to larger customers, who are more able to influence decision-making.

    Key Takeaway: To succeed with DevOps outsourcing, you need the right partner, based on attributes of skills, demonstrable experience, and a size that’s proper for your company.

    Metrics Matter

    John Adams, the second U.S. president, once famously said, “Facts are stubborn things.” DevOps presumes a culture of continuous improvement—and our metrics help demonstrate that improvement. We collect metrics so we can accurately measure pace of work, quality of software produced, level of effort and so on. We measure events over time to see if we are improving, worsening or stagnant. Metrics are a critical means of communication and mutual accountability between your company staff (IT and business) and the outsourcing partner who is writing your software. In a DevOps-driven outsourcing relationship, you’ll regularly capture and report on metrics (estimated and actual) such as:

    • Lead Time: In software development, you need to measure the time elapsed from concept to the point delivery of the completed software. From project to project or even epic to epic, you want to see an increase in speed to deliver software.
    • Sprint Time: Teams using Agile will have sprints measured in a few days, instead of months, for the typical time for work grouped in “phases” or “activities,” using traditional development methods. Be sure to track metrics for your sprints.
    • Sprint Volume: How many sprints are needed to complete a story? How many sprints are needed for a version? For each of these metrics, look for consistent volume (i.e. number of sprints produced) over time.
    • Issues and Open/Close Rates: Measure how many production issues are reported AND closed within a specific time frame. Observe and take action on trends rather than establishing a hard and fast number; there’s no “right answer.”

    Key Takeaway: Metrics allow you and your outsourcing partner to objectively assess the pace and quality of rapid work being performed in a DevOps/Agile-driven development project.

    Collaboration is Key

    It almost goes without saying that you and your outsourcing partner will need to have good, regular rhythms of communication. This continuous collaboration is essential because you and your vendor-partner team are:

    • Operating in a common disciplined way using DevOps methods.
    • Performing work through a common set of tools.
    • Progressing through the project goals in a series of rapid sprints.
    • Capturing and analyzing team metrics to ensure project health.

    Honestly assess what barriers might exist to good collaboration. Do you need to ramp up your real-time collaboration tools? Do you have a master calendar of formal meetings where the agenda will drive good information-sharing, decision-making and issue resolution?

    Are time zone differences an issue? This may affect the geographic location from which you will select your outsourced development team. In a recent survey, one-third of U.S. companies that outsourced to India considered the 10-hour (or more) time difference to be a big challenge. Very often the “core team” in an outsourcing software provider will be working hours that are completely opposite of normal U.S. business hours. Some companies find that a “nearshore” outsourcing partner helps optimize collaboration. Because the outsourcing partner is in the same time zone as your IT leadership team, it’s easier to schedule meetings or even have impromptu discussions, which are so important in software-development methodologies such as Agile.

    Key Takeaway: DevOps and Agile require high collaboration. Set yourself up for success by ensuring there will be no reasonable impediments to good collaboration.

    A Perfect Storm – and Opportunity

    The recent evolution in best thinking and adoption of DevOps, and the parallel growth in options for software development outsourcing together create a kind of perfect storm in software development. The potential of DevOps is augmented by the inherent continuous-change nature of Agile. We see the ability to transfer work across the “virtual shop floor” of development without geographic constraints. This new programming paradigm of DevOps, partnered with Agile, is now matched by equally exciting (and relevant) growth in the options for delivering high-quality code from anywhere across the globe.

    About the Author / Steve Mezak

    Steve Mezak is founder and CEO of Accelerance, a leader in global software development outsourcing, as well as the author of “Software Without Borders,” co-author of, “Outsource or Else: How a VP of Software Saved His Company,” and a CIO columnist.


  • Puppet CEO Sanjay Mirchandani Reflects on a Year at Puppet

    Puppet CEO Sanjay Mirchandani Reflects on a Year at Puppet

    As Mike Vizard detailed, this year’s Puppet Conference featured an impressive lineup of new products and services brought to market. The company appears to be firing on all Puppet CEOcylinders. The event also marked the first anniversary of Sanjay Mirchandani as Puppet CEO. I had a chance to sit down with him to review the past year, as well as the announcements at the conference.

    I will leave the product stuff to Mike’s article, but I asked Sanjay what he thought was his greatest accomplishment over the last year. He said that hands down it was assembling the great team he has put together. To be frank, I agree with him. In a time when execs at tech companies seem to hop around like fleas, Sanjay has assembled a world-class, enterprise-proven leadership team.

    In my opinion, this builds on Puppet’s greatest strength, which is its community. Puppet, like many successful DevOps companies, builds on its free, open-source roots and is nourished by a passionate, involved worldwide community. This was once again in full view at Puppet Conference. Frankly, my favorite time of the day was lunch (no surprise there, but not for the obvious reasons), where I would get a chance to sit down with “strangers” and listen to their experiences, what challenges they face at their jobs and where they see things going. I love those opportunities for unfiltered dialogue with real practitioners. The feedback I heard was pretty consistent.

    They enjoy using Puppet and they appreciate what the company is doing. They noted was that even though the company is developing products that compete with other tools they are using currently, they like the fact that Puppet doesn’t force them to make an either/or decision. They can continue using the tools they are comfortable with or start adopting Puppet’s new tools, all the while using Puppet for what they have always used it for.

    I asked Sanjay another key question: “What is your biggest failure or disappointment this year?” The answer was surprising. He said he failed to understand that some people really were not clear whether they could use Puppet in a cloud environment. Mind you, this is during a conference in which several relationships with cloud providers were announced. But evidently, some people did not understand that it works in cloud environments as well as on-premises—and, for that matter, in a hybrid environment as well.

    Mirchandani is not underestimating this view any longer. Puppet is emphasizing its cloud chops at every turn. As I mentioned, I was not aware of this view either, so it is interesting.

    In any event, this year’s Puppet Conference was the biggest (about 1,200 people) and best yet. I thought the company did a great job trumpeting a number of new products, ideas, partnerships and a clear path forward. As one of the founding and leading DevOps tools providers, its future continues to look bright.

    — Alan Shimel

  • Building a Services and IoT Platform with DevOps, Part 3

    Building a Services and IoT Platform with DevOps, Part 3

    Business needs and IoT demands are taking new dimensions in connecting millions of devices, people, process, tools and systems. With endless possibilities of creating new IoT solutions, DevOps teams are the key players who handle the challenges in successfully rolling out a IoT solution while handling the business, development, operations and infrastructure demands in the background. This article focuses on some of the DevOps best practices to adopt during IoT development, enabling faster time to market.

    DevOps practices to adopt during IoT development

    1. Adopt Security by design – Teams need to be educated and made aware of security threats. Use threat models mitigation techniques such as using authentication; storing secrets separately and protecting those secrets; using tamper-resistant protocols, digital signatures, timestamps, audit trails, encryption, authorization policies, filtering; and running services with least privileges during security design and development.
    2. Shift left security analysis and security testing – Integrate security analysis tools, customize security compliance rules and run security testing as part of continuous integration pipeline, generate security threat reports on vulnerabilities and act on these threat reports to fix issues early in the development phase and minimize the security risks.
    3. Follow security standards during development such as security development life cycle (SDL), which has guidelines and measures for building the software for devices and application components of IoT platform.
    4. Perform code reviews for device software, application software, PaaS rules and configurations, as quality assurance can become a huge risk given the complexity of the infrastructure, millions of devices connecting and dynamic environment configurations. Code review tools need to be integrated to the CI pipeline with pull request code review.
    5. Use the right branching policies in a version control repository, including precommit/preflight builds, pull requests for merging the code changes and access control for maintaining branches and using the right branching strategies, as there will be multiple fragmented development and deployment pipelines for devices and application developments to reduce the overhead. Use distributed repository/central repository with traceability and auditability based on the requirements.
    6. Automate deployments and create deployment pipelines for device development, application development, infra-automation scripts development with build and deployment pipelines targeting for different target endpoints.
    7. Customize the builds and release pipelines to pull the packages from multiple build and deployment pipelines to integrate and deploy as units of deployment.
    8. Plan for frequent release cadences—say, monthly—for application rollouts. Release cadences for firmware update rollouts can be planned for three to six months, as device updates cannot be pushed so often.
    9. Continuously monitor deployments – Use a release management tool for orchestrating the releases and release coordination activities, with gated checks and approvals with a view of what is getting deployed to each environment, as well as traceability and audit.
    10. Enable feedback loops and automated alerts if firmware deployments or application updates fail.
    11. DevOps teams can define key tenets, criteria to be met and standards to be followed for the devices; infrastructure to be provisioned; device protocols usage and standards in connecting to existing/new devices and services. This can reduce the complexity in development and deploying to multiple varied devices by following the same protocols for connectivity and communication.
    12. Train the team of developers, QA and hardware developers on how to do continuous integration for IoT development, follow agile and lean practices and ensure security criteria for all layers of the application and in process.
    13. Adopt user-centric test automation and end-to-end testing approaches and build robust test cases in perspective of testing a complete flow, with devices/services that may not be in your scope but will be part of your overall IoT platform ecosystem.
    14. Create/utilize container based test environments and device simulators coupled with service virtualization for functional testing.
    15. Automated infrastructure provisioning – Use the right configuration management tools to automate the infrastructure along with dependencies to create environments through code instead of provisioning basic VMs.
    16. Use container and cluster management tools such as Docker Swarm or Kubernetes for service discovery, auto-scaling, self-healing and scheduling.
    17. Use RBAC, service accounts and security access controls in the infrastructure templates/scripts that are created instead of individual user credentials to limit the risk of unauthorized users provisioning the environments using scripts. Build security in devices, cloud security, application security and infrastructure automation templates. Use secrets, key vaults, encryption methods and certificates to secure the credentials and access control.
    18. Configure individual build and deployment pipeline jobs for application development and infra-automation development, as there will be a huge development effort involved in automating the infrastructure.
    19. Create infrastructure verification tests with scripting tools such as Python or use testing frameworks such as Pester or any other open-source tools and integrate the infrastructure tests with the CI/CD pipeline. Ensure to run these tests every time the infrastructure is provisioned.
    20. Version-control the infrastructure templates, scripts, user profiles, environment configurations and device configurations apart from source code.
    21. Set up a centralized dashboard of monitoring tools to monitor the clusters, nodes, firewall rules, VMs, applications, devices and services. Feedback should flow back to developers/QA/DevOps teams.
    22. Configure applications to provide logging about exceptions, memory leakages and response times and push the logs to the monitoring tools or the dashboards in monitoring tools.
    23. Use the telemetry from the applications and devices to derive the analytics graphs/trends and set up KPIs/metrics to measure application performance/availability, as well from derive business metrics to set SLAs for DevOps and operations, to improve productivity.
    24. Ensure DevOps teams have close coordination with dev/QA teams of both software and hardware teams, as managing IoT platforms need more skill and expertise in hardware and software in the IoT domain.
    25. Manage legacy and cloud infrastructure with multicloud management platforms, and monitor and optimize the infrastructure usage.
    26. Create a DevOps governance plan/guide, with clearly defined access control policies, access rights for devices, control limits on infrastructure provisioning in different clouds, limits on PaaS/IaaS services to be used, etc., and standardize the process to be followed in DevOps/development/testing/operations, tools, etc.

    Following DevOps practices for application development has become quite streamlined in recent years. However, in IoT, where traditional methodologies and practices are followed in industrial enterprises, adapting to agile methodologies and following DevOps practices coupled with right DevOps-skilled team, tools and expertise can streamline and simplify IoT developments.

    About the Author / Lavanya Subbarayalu

    Lavanya Subbarayalu is Senior Architect working with Technology Office in HCL Technologies. She has expertise in IOT, Azure, DevOps consulting & Microsoft technologies. She is associated with DevOps COE, working on design and Development of DevOps solutions and consulting tools. Connect with her on LinkedIn.

  • Digital Transformation Survey: Help Us, Help You

    Digital Transformation Survey: Help Us, Help You

    The term digital transformation is probably one of the most overused, if not abused, terms in the tech/DevOps world today. Everyone is doing it, but what is it? Is it a synonym for adopting DevOps? What are its effects on you, your job and organization? What does it mean for software development and deployment? So many questions. Actually, they’re only a few minutes’ worth of questions in our new survey, Digital Transformation and Your Organization.

    digital transformation surveyThese surveys really help us understand where the market is, what our readers and community members are dealing with and what we can do to serve them better. You helping us by taking the survey allows us to help you—not only you, but the wider community as well. Your opinion is important and it counts. So please take a few minutes and help us. Take this survey now.

    You still here? OK, if our words didn’t persuade you, let me go one better: We are willing to pay you to take this survey. We will give one in every 10 people who take the survey a $50 Amazon gift card. To be eligible for the gift card, you need to enter your email address in the optional last question of the survey. Otherwise, we don’t know who to send it to. So that is another reason to take the survey.

    We will make the report of the survey findings available as well, and everyone who registers will receive a copy. The survey is open to anyone, so please feel free to share the link with your colleagues.

    Beyond taking the survey, I don’t want to minimize the importance of digital transformation. While for some—especially in our DevOps audience—digital transformation means DevOps transformation, that is not its only use or meaning. For many businesses, just adopting a digital footprint, using the internet as an active part of their business or adopting modern methods, software, Agile methodologies, etc., opens up unimagined new ways of business. At the end of the day, digital transformation may, in fact, be one of the biggest agents of change in our world over the last 20 years.

    We’re looking forward to analyzing the responses and seeing your digital transformation experiences. Please help us help you by taking the survey.

    — Alan Shimel

  • 3 Practical Steps to Employing DevOps

    3 Practical Steps to Employing DevOps

    Everyone seems to be talking about DevOps but, if you are new to it, it might all seem a little overwhelming. One of the hardest things about DevOps is knowing where to begin. This is because to “do DevOps” its seems you have to suddenly start using a lot of new processes and tools at once.

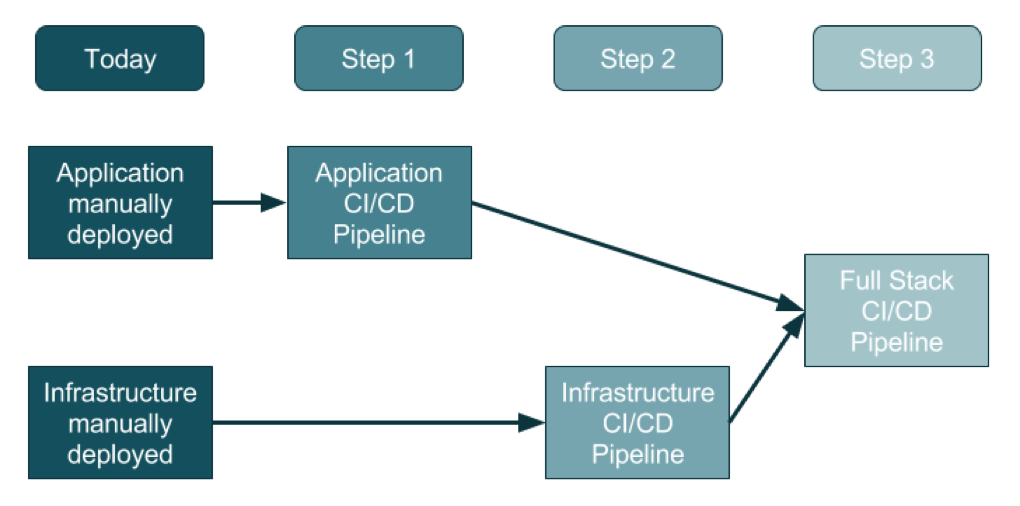
    For an organization that doesn’t use DevOps today, the adoption of this three-step method will promise a generally clean approach.

    Source: https://ukcloud.pro/

    Step 1: Creating the Application Pipeline

    Regardless of the type of application, the pipeline looks—at a distance—very similar. The goal is to weave application releases into a new coordinated process that looks something like this:

    1. The developer makes changes locally to their laptop/PC/Mac, and upon completion (including testing, etc.) issues a Pull Request.
    2. Code review kicks in, the developer changes are reviewed and accepted and a new release can be created.
    3. Someone, or the system, runs a procedure to create a release artifact, which could be a Java JAR file, a Docker file or any other kind of unit of deployment.
    4. Someone, or the system, copies the artifact to the web or application servers and restarts the instances.
    5. Database migrations/updates may be additionally applied, although the database is often left outside of the application release process.

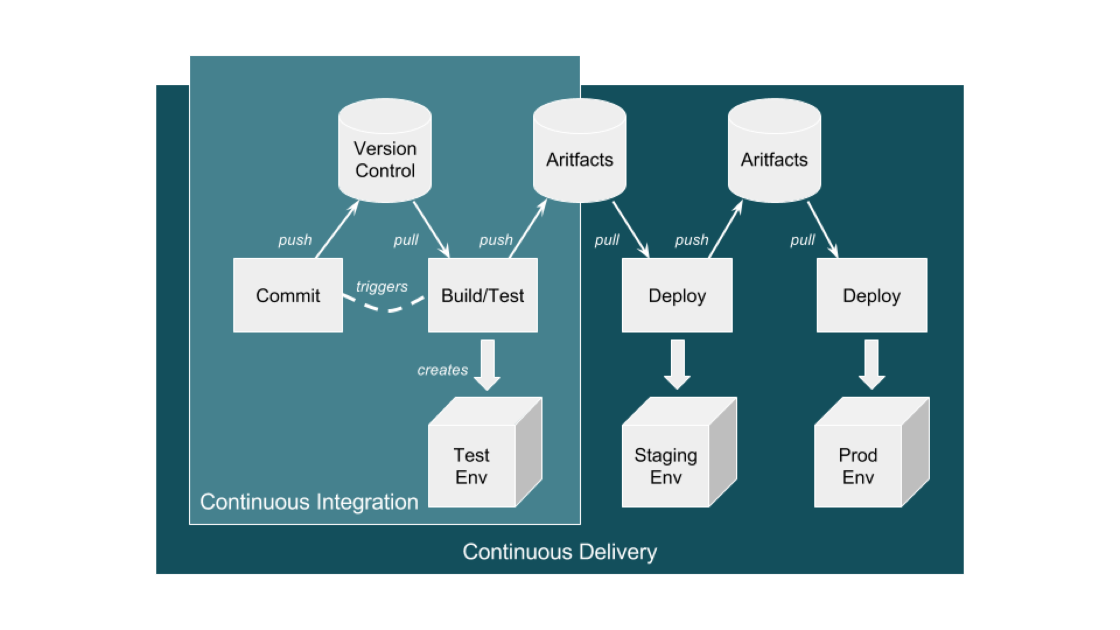
    This process evolves into an automated application-only continuous integration and continuous deployment (CI/CD) pipeline by using a toolset to automate the process as shown in the diagram below:

    Source: https://ukcloud.pro/

    A Typical CI/CD Pipeline


    However, be aware that this isn’t ideal (yet), because at this point the application alone is being released (injected) into existing environments.

    Why is this potentially an issue? If the developer has altered the local environment as well as the application but these local environment changes are not part of the release, then they’re not in version control. And, if they are not applied at the same time as the application, then the application will break and the common argument occurs: “Well, it works on my machine!” The solution is for application and infrastructure releases to be synced—and hence steps 2 and 3.

    Step 2: Creating the Infrastructure Pipeline

    Ideally, the infrastructure team has learned from the developer team’s DevOps and CI/CD pipeline journey and can expand and adapt it for the infrastructure (which increasingly is a public cloud).

    There are some differences with the infrastructure pipeline, specifically around units of deployment that are now the infrastructure layers in environments, the things that surround an application such as the DNS, load balancers, the virtual machines and/or containers, databases and a plethora of other complex and interconnected components.

    The big difference here is that the infrastructure is no longer described in a Visio diagram: it is brought to life in code, in a configuration file, in version control—this is infrastructure as code (IAC).

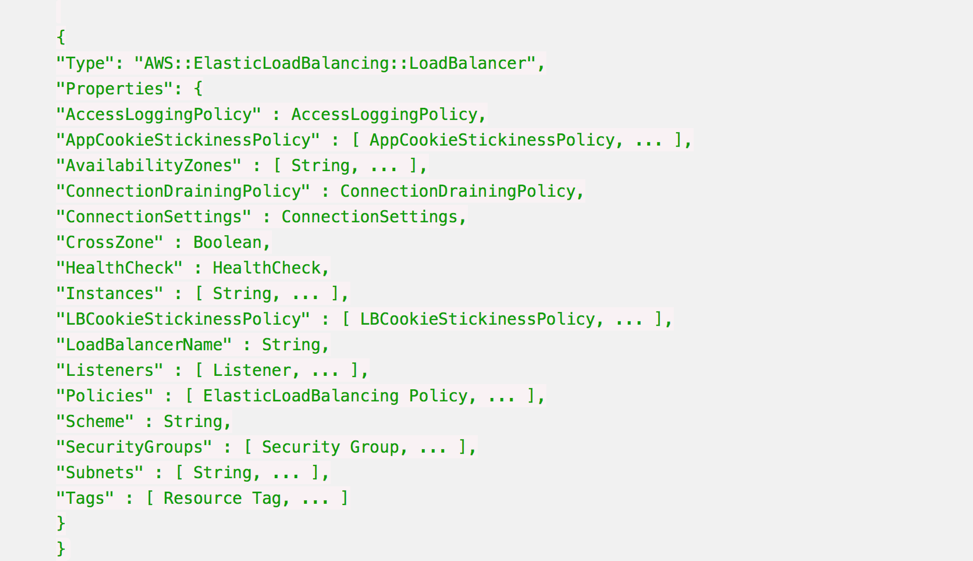
    Before this, a load balancer was described in Visio diagrams, Word documents and Excel spreadsheets of IPs and configurations. This is now swapped to describe everything about the load balancer in a configuration file.

    Here’s an example AWS CloudFormation Configuration for a Load Balancer:

    Whenever this file is changed in Version Control, such as changing the subnets a load balancer can point to, then the automation engine can update an existing infrastructure environment to reflect that one change, and any dependencies that change.

    It also means that you can apply this template to multiple environments just by changing the environment name from staging to production, for example, and be very confident that all environments are consistent, from the developer laptop to production.

    It is also possible to make the templates dynamic to change their behavior according to the environment, so in production the environment will scale out across three datacenters, but on a developer’s laptop it will use a local VirtualBox single-system.

    Step 3: Creating the Full-Stack Pipeline

    The goal of a full-stack pipeline is to ensure that the application and infrastructure changes over time are in sync, both in version control and the release deployments across each pipeline stage. And a developer should never say, “It worked on my laptop!” when a release fails in production.

    The popular CI/CD tools can now automate the full stack because everything is programmable. This means everything can be captured in version control, and the same configuration can use dynamic input parameters to build an environment on a developer’s laptop, or a QA system in the cloud or updates to production.

    Imagine a developer makes an application change that also requires a change to the database, the web instance scaling configuration and the DNS. All of these changes are captured in one version control branch and the developer builds a system on their laptop from this branch, and tests it.

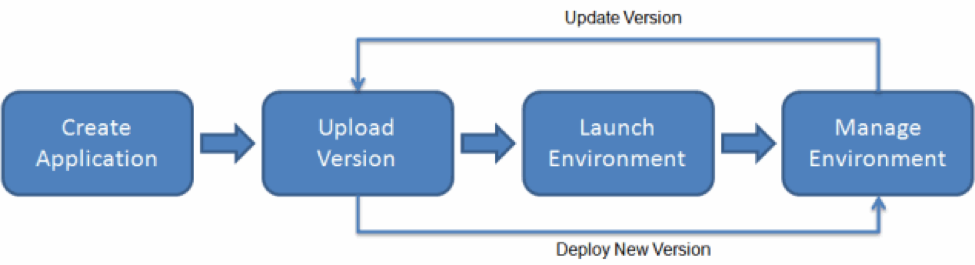
    This is what platform-as-a-service systems can do. By adding an environment configuration file inside the same code base as your application, you can ensure that you have bound your application to the infrastructure. 

    AWS Elastic Beanstalk Example

    This is the target end goal, though it takes a lot of practice, and learning, to get there. It can be very satisfying to watch a build and a deployment, seeing the automation use tags and dynamic configurations to build, or update, the target environment with application and infrastructure changes.

    About the Author / Sarah Lahav

    Sarah Lahav is CEO of SysAid Technologies. As the company’s first employee, Sarah Lahav has remained the vital link between SysAid Technologies and its customers since 2003. She is the current CEO and former VP of Customer Relations at SysAid – two positions that have fueled her passion in customer service. Connect with her on LinkedIn and Twitter.


  • Tips for Creating Unit Tests for Mobile Apps

    Tips for Creating Unit Tests for Mobile Apps

    Mobile app testing ensures your application is working perfectly without any freezes, bugs or crashes. There are unit, auto, system and acceptance tests, and in this article we will talk about unit testing for mobile apps.

    First, let’s discuss what unit tests are in general. Unit testing checks whether certain parts of the code work correctly. In other words, it helps us produce more robust and maintainable code. Each one small test is dedicated to a small feature. All of them are connected, however, so you get a kind of chain. If any part of this chain fail, the whole chain will fail as well.

    As a part of mobile application testing unit tests may be written at any phase of development or even before development (test-driven development, or TDD, is one of the iOS unit testing best practices). With this kind of development, you let your tests drive the development process. They indicate what you do, what you should do next and what the result should be. Testing controls the design.

    Thus, unit testing is the first step to perfectly working code. But it also is the primary means for your software quality assurance. In this article we’ll explain how to do mobile apps unit testing on an iOS example and give you a small iOS unit testing tutorial.

    Do I Need to Conduct Unit Testing?

    Does everyone need to do unit testing? The short answer is no. The long answer is that it  is a very good tool, though it isn’t necessary in all situations.

    You don’t need unit testing if:

    1. your app is very small and simple. If your app is small, it will be faster to check everything manually because there’s not that much logic to be checked.
    2. you don’t plan your app to work in the long term and you need it only for a demonstration.
    3. you’re a super-human who writes perfect code without any mistakes.

    If you don’t fall into any of these categories, then unit testing is what you need. At first, this kind of testing may seem too time-consuming. Lack of time is mentioned as one of the most serious problems related to testing, but actually performing unit testing can save a lot of time and improve development speed. In addition, it can serve as a kind of documentation for your library. We at Mobindustry spend up to 30 percent of our development time on testing.

    Unit tests have two main purposes:

    1. Reduce the number of bugs by making sure that our class/module/component is working as expected with all possible inputs.
    2. Reduce the number of regressions by making sure that our new functionality, bug fixes or refactoring hasn’t broken any existing functionality.

    How Do Unit Tests Work?

    How to create iOS unit testing? Xcode has built-in support for unit tests and works as an iOS unit test framework. You can use Xcode by pressing cmd+U or via the menu by selecting Product -> Test. xCode will run all active tests and generate a report with results (passed/failed). All failed assertions are indicated. Code coverage data is also generated in this framework, which allows you to get to any class and check which lines of code were called and how many times they were called.

    Types of Unit Tests

    Unit test for iOS can either check the UI or the logic of the application. Logic ones have a few subtypes:

    • Regular ones are used to check straightforward functionality.

    func testExample() {

    let account = Account()

    account.amount = 100.0


    account.withdraw(20.0)


    XCTAssert(account.amount == 80.0, "Account should have current amount of 80.0 but has

    (account.amount)")

    }

    This is used to simply check if the withdraw() method is working correctly.

    • Asynchronous tests use XCTestExpectation to check for expected outcomes.

    func testExample() {

    let url = URL(string: "http://www.google.com")

    let expectation = XCTestExpectation(description: "expectation_description")


    let task = URLSession.shared.dataTask(with: url) { (data, response, error) in

    if let error = error {

    XCTFail("Error: (error.localizedDescription)")

    return

    } else if let statusCode = (response as? HTTPURLResponse)?.statusCode {

    if statusCode == 200 {

    expectation.fulfill()

    } else {


    XCTFail("Request failed with status code (statusCode)")

    expectation.fulfill()

    }

    }

    }

    task.resume()


    waitForExpectations(timeout: 10) { (error) in

    XCTFail("Expectation (expectation.description) has failed")

    }

    }


    This one will check if Google’s website is available (i.e. if it returns status code 200).

    XCTestExpactation is used to wait for the async task to finish. An Expectation will either finish successfully by calling the fulfill() method or will fail if the timeout time has passed but fulfill() hasn’t been called.

    • Measure ones check heavy logic:


    func testExample() {

    self.measure {

    let lotOfObjects = []

    for obj in lotOfObjects {

    obj.makeCalculations()

    }

    }

    }


    You can create this test to measure how much time and how many resources are spent on particular calculations inside the measure() block.

    Tips on Unit Testing for Mobile Apps

    • Remember the structure

    The common AAA approach to structuring is the most common and convenient way to write tests. AAA stands for:

    1. Arrange – the part that allocates all necessary objects and sets up initial parameters
    2. Act – the part that executes the logic
    3. Assert – the part that checks if the obtained results match the expected results

    Сode written this way is easy to read and use, which means it’s easier to maintain.

    • Cover only necessary things with tests

    Some people think it’s necessary to cover every single part of your code with a unit test. This approach is actually time-consuming, complex and completely useless.

    There are four types of code you may have in your project. Let’s look at them starting with the most extreme options:

    1. Simple code without any dependencies: Probably everything is already clear with this kind of code and there’s no point in assessing it.
    2. Complex code with lots of dependencies: If you have this kind of code, it’s a good idea to refactor. There’s no need to cover this code because we’ll rewrite it, which means new classes will appear and method signatures will change. Why write something that won’t be used? Of course, such code also needs quality assessment, only on a higher level.
    3. Complex code without dependencies: This code contains algorithms or business logic. This is the perfect kind of code for testing because these are very important parts of the system.
    4. Moderately complex code with dependencies: Such code links different components together. Tests are very important here; they tell how exactly components must interact.

    Usually, they cover the following areas of code:

    • Common functionality, core models, classes and their interaction
    • Main UI workflows
    • Crucial logic
    • Bug fixes

    Unit tests may be applied not only for these areas. They can actually be used for testing almost any functionality.

    Don’t cover trivial functions and system functions.

    • Test only one thing at a time

    The idea is to divide your application into different independent modules that are able to work by themselves without interacting with other parts of the application. This allows you to work on each module separately and simplify the code. If you check several things at the same time, sooner or later your code will become overloaded and too complex. It will become difficult to support it and use.

    • Name your tests logically

    It’s very important to name your tests properly and assign them to the correct parts of your project. Many projects have tests that no one is running because of inconvenient placement and naming. Here are some tips for logical structure:

    1. Choose a logical location in your version control system: They have to be part of your version control. Depending on your needs they can be organized differently, but here’s a common recommendation—if your app is monolithic, put all of them in a Tests folder; if it has many components, store relevant tests in each component’s folder.
    1. Choose a convention for naming: One of the best ways to do this is to add a test project to each project you build.
    1. Use the same convention for naming test classes that you use for naming project classes: If you have a class ProblemResolver, it’s a good idea to add a class called ProblemResolverTests. Each class should work only on one thing; otherwise, your tests will be very hard to manage.
    • Work with mocking objects

    You can use different fake objects to make the testing process easier. There’s no need to allocate and manage a huge class or component just to use a single method from it. Such fake objects can be divided into two groups:

    • Stubs
    • Mocks

    Stubs are fake methods for returning a predetermined response. The main use for stubs is when interacting with an API. The idea is not to wait for the actual connection to finish but to return predefined data or a predefined error instantly.

    Let’s assume we have an app where you can add a friend connection. There’s a FriendListViewController that displays a list of all your friends. This friend list can be downloaded from the backend, so there’s an ApiManager class with a method like this:

    ApiManager.shared.getListOfFriends(withCompletion: { (friends) in

    let friendsListVC = FriendListViewController.init(friends: friends)


    //Present friendsListVC

    }) { (error) in

    //Display error


    }

    This method has a completion handler, and we need to wait till it finishes.

    But we actually don’t need to wait because we don’t need any APIs or even an internet connection. We need to make sure FriendListViewController is working correctly, and all we need for that is some list of friends; it doesn’t matter where they come from. So we’ll introduce an ApiManagerStubs class that will duplicate methods from the actual ApiManager but will not perform any actual API requests.

    For this particular test, we’ll write a method for getting a list of friends:

    func getListOfFriends() -> [Friend] {

    let friend1 = Friend.init(name: "Bob", surname: "Barker", age:34);

    let friend2 = Friend.init(name: "John", surname: "Doe", age:30);


    return [friend1, friend2];

    }

    After that we can easily allocate and test FriendListViewController.

    func testExample() {

    let friends = ApiManagerStubs.shared..getListOfFriends()


    let friendsListVC = FriendListViewController.init(friends: friends)


    //Testing friendsListVC.tableView

    }

    Mocks are fake objects that partially duplicate real objects, allowing you to check if a method was called or a property was set after certain events.

    In the example above, when a friend is deleted we need to clear the chat history for this friend. We have some class like ChatManager for this functionality. But again, for this, we don’t need to actually delete any data or call any APIs; we just need to check if the corresponding callbacks are triggered. So we’ll introduce the mock object ChatManagerMock, which behaves like ChatManager, only instead of deleting data it just remembers which callbacks were triggered.

    class ChatsManagerMock {

    var deleteFriendWasCalled = false


    func clearChatHistoryForFriend(_ friend: Friend) {

    deleteFriendWasCalled = true

    }

    }

    Now we can implement our test as follows:

    func testExample() {

    let friends = ApiManagerStubs.shared.getListOfFriends()


    let friendsListVC = FriendListViewController.init(friends: friends)


    let mock = ChatsManagerMock()

    friendsListVC.chatsManager = mock


    //Trigger Delete action for first friend in the list

    friendsListVC.deleteFriendButtonAction(nil, index: 0)


    XCTAssert(mock.deleteFriendWasCalled, "deleteFriendWasCalled should have been called")

    }

    Conclusion

    Unit tests are a very powerful tool to help developers avoid bugs and spot them quickly when they do appear. They help you maintain your code, but at the same time they need maintenance as well. The big problem of many projects is tests that no one uses, and to avoid it you need to stick to some rules. Your tests must:

    • be reliable;
    • not depend on the environment they’re run in;
    • be easy to maintain;
    • be easy to read and understand (even a beginner QA has to be able to understand what’s going on);
    • have a standard naming convention; and
    • be launched regularly and be automated.

    Following these basic rules will help you get a working system. Each test will check only one thing. Your tests will be specifications for class method; it will tell all about what input they expect and what other system components expect as the output. There are very few systems like this. Such systems have an actual specification, and there’s usually not very much text in it—only basic features, server schemes and a “getting started” guideline. The life of such projects no longer depends on people; developers may come and go while the system is reliably tested and tells all about itself with the help of its own tests.

    About the Author / Svetlana Cherednichenko

    Svetlana Cherednichenko is a content writer. Currently she is a part of Mobindustry marketing team. She is an active member of the debate movement and she is a winner of two regional tournaments. Now she is in the process of improving her skills in graphic design and learning new frameworks. She graduated from the Dnipropetrovsk National University. Svetlana likes to travel, read about tech news and play video games. Connect with her on LinkedIn.