Category: DevOps Practice

  • EP 15: Why Testing is so Frustrating

    EP 15: Why Testing is so Frustrating

    In this episode of DevOps Unbound, hosts Alan Shimel and Mitch Ashley are joined by Adam Kalsey of Tricentis, Brian Dawson of the Linux Foundation and Caroline Wong of Cobalt to discuss why testing is considered the most frustrating bottleneck for developers and engineers. Panelists will explain the benefits of testing early on in the SDLC and how to accelerate the feedback cycle with automated and continuous testing, as well the pros and cons of testing, the value of shift-left testing and how to effectively balance quality and speed. The video is below, followed by a transcript.

    DevOps Unbound is sponsored by Tricentis, the world wide leader in automated testing. DevOps Unbound airs biweekly on TechStrong TV, with all episodes available on Digital Anarchist. There is also a live monthly roundtable open to audience participation.


    Alan Shimel: Hey, everyone. I’m Alan Shimel, and you’re watching DevOps Unbound. DevOps Unbound is sponsored by our good friends at Tricentis, and it consists of a biweekly, 40, 45 minute video panel on relevant topics within the DevOps sphere, and featuring a panel of experts that rotates every other show, and really great people, and something I personally really enjoy doing.

    And then, about once a month or once every six weeks, we actually have a live studio audience—or there is no studio audiences in COVID, actually, but we have a live virtual audience that participates in our show. Today’s show is just our panel, though, without a live audience, and I’m really looking forward to our discussion.

    Our discussion today is around testing. You know, with the pressure on developers to deliver code faster, sometimes testing is considered a road bump in the way. Testing is considered slowing down the whole process. There are a lot of developers who’d like to push testing off that plate. Of course, no one wants to go back to testing after we’ve deployed software, primarily, but there is that tension there.

    Let me introduce you to our panel today; we’re gonna discuss this in depth. First of all, making his first appearance as a member of The Linux Foundation on our Tech Strong TV network is our old friend, Brian Dawson. Brian, welcome to DevOps Unbound.

    Brian Dawson: Thank you, Alan. Thank you, Alan. And it’s fitting that the first panel, first webinar I do since joining The Linux Foundation is with you.

    Shimel: It’s our pleasure to have you on. Brian, what’s your position at Linux Foundation now?

    Dawson: So, at The Linux Foundation, I am functioning as the VP of Developer Relations and Ecosystem Development. So, just to help, we’re gonna help The Linux Foundation to the development community while driving more of a DevOps opinion into a growing ecosystem of solutions that support open source development.

    Shimel: Fantastic. Next up is my good friend, Caroline Wong. Caroline is—oh, she’s an anchor on many of our different shows here at MediaOps and Tech Strong. Caroline, it’s great to see you again. A little background, maybe, for people who aren’t familiar with you?

    Caroline Wong: Great to be here. Thank you so much. My name’s Caroline Wong, I’m the Chief Strategy Officer at Cobalt. We’re a pen test as a service company.

    I actually started my DevSecOps career 16 years ago leading information security teams at eBay and Zynga. So, in both cases, we were running online operations 24/7 with millions of simultaneous users daily. And now, at Cobalt, we build security software. And, like many DevOps companies, we’ve got data driven, product based teams. We value automation and failing fast, and super excited or today’s conversation.

    Shimel: Fantastic. Welcome. Great to have you, Caroline. Our third panel member is another returning DevOps Unbound veteran, and that’s Adam Kalsey of Tricentis. Adam, welcome.

    Adam Kalsey: Thanks. Thanks for having me. I lead Developer Relations for Tricentis. I’ve been building web applications since 1995, and have always had a soft spot in my heart for bad applications and broken things. And so, I love to help developers build higher quality software and do it in a more efficient, faster way.

    Shimel: Absolutely, and thanks for being on with us today, Adam. Last but not least, in his Florida outfit here, visiting me in Florida, is my Co-host of DevOps Unbound, Mitch Ashley. Mitchell, welcome.

    Mitch Ashley: Coming to you from the MediaOps Studio B.

    Shimel: Yes.

    Ashley: Great to be here. I’m a former product, both security and software SaaS, CTO as well as a CIO, and now I run Accelerated Strategies Group, an analyst firm that focuses on those things.

    Shimel: Absolutely. Hey, Mitch, thank you.

    So, let’s get started. Adam, you’re with Tricentis, the sponsor of DevOps Unbound, and they’re a testing company, probably the leaders, one of the leaders worldwide in automated testing, continuous testing. Have we put too many straws on the developers’ camel’s back by making them, you know, be more responsible for testing to say we need to test more of our code earlier.

    Is it a bridge too far for many developers? Is it making them resent testing? You know, what’s the current state?

    Kalsey: I think where we’re failing developers is by handing them lots of more things to do without giving them any—without giving them what tools, and I don’t mean just necessarily software tools, but without giving them the things that they need to do it effectively. If we just pile things on developers and say, “Oh, this is your job now” but we don’t give them the support, we don’t give them the training, we don’t give them the expertise, we don’t give them anything to make that better—sure, it’s just gonna be harder on ‘em.

    Shimel: To play devil’s advocate—oh, those poor little testers making a quarter of a million dollars a year each. Do we want ‘em to do testing, too? Right? Is there some of that here, Brian? Or—go ahead, Adam?

    Kalsey: No, no, Brian—please, please, jump in.

    Shimel: Well, he’s from The Linux Foundation, he now represents these folks. [Laughter]

    Dawson: Well, first, not all of them make a quarter of a million dollars a year, right? But I do think what you raise is important when you bring up the investment, right? We are hiring talent with a particular expertise in a particular domain, a particular ability to solve problems and innovate.

    And there is an argument to be said, Alan, that, “Do I want to spend this money, this quarter of a million dollars plus 200,000 in RSUs on having somebody write test harnesses?” Now, I think—you know, that can be balanced by what Adam said. Well, first of all, yes, because we want everybody thinking about quality. But you know what, if we want a return on that investment, we wanna free the cognitive load, then you know what? We need to invest in automation, we need to invest in better collaboration and reducing friction from the process.

    Shimel: Agreed, agreed. Caroline, you know, it’s been a big—this whole DevSecOps movement and shift left has been about shifting security testing left and getting developers more involved in security testing, right? Yet another camel on the—yet another straw on the camel’s back. Should we be doing that?

    Wong: So, I—oh, my Internet is awful. Can you hear me?

    Shimel: Yes, we hear you fine.

    Wong: Okay, fantastic, awesome. I’ll just—I know that there’s post editing, so it’s okay for me to say that.

    Shimel: Mm-hmm.

    Wong: So, Alan, I bring a particularly unique perspective to this group in the sense that I actually oversee people at our company, I oversee Human Resources. And I’ve been with the company since we were 10 people, and today we’re 200. And one of the super interesting things that happens is, naturally, as a company grows, what people do, they specialize and then we have to figure out how to communicate more effectively.

    And I think that if you’ve got an engineering team and you say, “Okay, now you’re responsible for Development and you’re responsible for Ops, and your responsible for security, then there’s got to be some level, depending on the maturity and the size of the organization and what the organization’s trying to accomplish of specialized roles and protocols for engagement.”

    And I think that when, either number one, those roles are not clear to, I think Adam was making a point earlier about security folks need to be providing guidance to engineers where—because engineers are not expected to be security experts, frankly. Security experts are not expected to be engineers. And then, at the point where information is being handed off where the responsibility for taking an action, those, all of those sort of procedures, they have to be clear, otherwise they’re simply not going to happen.

    Shimel: Yeah, agreed. I think they have to be clear. But even if we make them as clear as we possibly can, is it just—are we putting too much on developers? I mean, I think fundamentally, that’s the question here, right?

    Wong: There’s—

    Ashley: Alan, it’s not only—sorry, I’m just gonna jump in. It’s not only quantity of work—is it the right work?

    Shimel: Right.

    Ashley: Because I know from writing software and being part of software teams for so many years, there’s this thing called unintended consequences or unintended use. Well, you’re not supposed to use it that way, but the person who designed it intended it to be used a certain way, but one of the important functions of tests is not just to uncover bugs and elicit those things or security issues, it’s also to push the boundaries about how you might use the software and essentially stretch it to try to find where it’s gonna break where they can. And oftentimes, that’s a different mentality than or perspective, certainly, than the person that wrote the code.

    Dawson: And if I may jump in and say maybe part of the discussion can get to generalist versus specialist, right? There is this idea, Alan, that when you talk about putting a lot in the developer’s hands, this idea that there is this prolific person called the full stack developer that can separate themselves from what they develop to look for security vulnerabilities, to test it, then ultimately deploy and run it, right? And I think we need to give thought to, are we trying to build a bunch of generalists, which doesn’t potentially enable them to do any job the best, or are we enabling specialists to better work together, share information, and crowdsource quality and crowdsource security?

    And I’m just curious if any of the other panelists have an opinion on this concept of full stack developers versus, say, needing traditional, lifelong quality experts.

    Kalsey: Yeah, I like to say that we decided to create cross-functional teams and we did it by removing all of the functions, and we centralized them all in a single person—and that’s not a cross-functional team. That’s—

    Shimel: That’s a cross-functional person.

    Kalsey: Yes. Well, and you end up with the jack of all trades, master of none problem. You have to have the specialists on even a cross-functional team. You have to have, there’s a lack of testers, there’s a lack of UX people, there’s a lack of security people. They have to be part of that team. You have to have people that, dedicated folks to do the hard work. A developer may be able, and a generalist may be able to do a lot of the easy things and a lot of the, “Oh, yeah, we’ve done this before or we’ve seen this, and this is a known know, let’s go fix that.”

    It’s the hard work of figuring out—what don’t we know, and then having the expertise to be able to know what that hard work is, even, to go after it. And without that, of course the developers are going to be overloaded, they’re being asked to do everything and they don’t know what everything is.

    Shimel: Agreed, agreed. I mean, I think, again, security is the poster child for this, right? We’re asking developers to be security people or to make security a priority. Now, you ask most security people four or five years ago, they’d tell you you’re smoking your socks. Developers don’t care about security. They never did. Only we care about security.

    It’s changed. It’s changed a little bit. We do think other—no one wants to develop insecure code. But we can’t ask them to be security people—or can we, Caroline?

    Wong: I sort of think we have to. I think that, you know, the big, bad thing that no one wants to happen is a security breach, and a security breach cripples an engineering team’s ability to execute on a roadmap. You know, if something big and bad happens, then entire teams have to rush and commit to fixing this problem sometimes for months, you know, time which, of course, could be invested more profitably elsewhere.

    I have a quote that I’d love to share from a colleague. Denali Lumma is the VP of Engineering over at Project Ronin, and she also makes a really good point about tech debt. She says, at a certain point, it’s too late, there’s too much tech debt, too much complexity, the code base is too big, and it becomes impossible to do anything about it. What you see there is a business will slowly die because shipping features becomes harder and harder, critical vulnerabilities and bugs are introduced more frequently, and eventually it kills the business.

    You know, I often think of software as a living organism, right? Whether you think of it as a tree or as an animal, there is this balance between making sure you’re doing sort of your fun things, your running, but you’re also resting when you need to heal. You’re also—you know, if we’re talking about a human being, you’re also sort of going to the doctor once a year.

    Shimel: Agreed.

    Wong: Yeah.

    Shimel: Agreed. Thoughts?

    Kalsey: Quality has to be a mindset, security has to be a mindset, user experience has to be a mindset on the developer time, among everybody there. The user experience person needs to understand and have a mindset of developing and of creating a secure experience and not, “Well, we’re gonna get rid of all the security because that’s hard for people to use.” Everybody has to have that mindset, but you still need the experts and you still need the expertise to be able to do things well. Just having a mindset doesn’t make you fantastic at it. You can say, “Oh, I love to get out and I’ve got an exercise mindset, so I’m gonna go run a triathlon tomorrow.” It’s probably not going to work.

    Shimel: Probably not.

    Ashley: You know, it’s interesting—we could’ve had this conversation 20 years ago, 10 years ago.

    Shimel: Absolutely.

    Ashley: You know, why are we still frustrated with tests? What is it with tests that is, you know, it used to be sort of the orphan of the development process, you know, the only thing that happens later than test is documentation. Well, now, [Laughter] it’s still an issue. Why is that? Why are we so frustrated with tests today? I’m curious what folks think.

    Dawson: I’m gonna start with one not very complex thought—it’s actually hard.

    Shimel: It damn right is.

    Ashley: A little more respect—we need a little more respect for tests. [Laughter]

    Shimel: Well, but this was like, I remember when we first launched DevOps.com, a popular theme was that, you know, DevOps would kill the testing star, right? That there would be less QA jobs because everything was gonna be automated continuously and shift left, we wouldn’t need testers—poppycock, right? We have as many testers as we ever had, if not more. It didn’t kill off testing jobs. I think it was Adam that said we’ve made testing part of the DevOps team. So, we have people on the DevOps team who are responsible for the various, you know, styles and types of testing that we do, including security.

    I think what’s happened, though, is, these DevOps teams—when I first started DevOps.com, if you spoke to developers, they’d say, “Oh, this DevOps is all about the Ops.” And then you’d talk to the Ops people and they’d say, “This is DevOps, it’s all about Dev, it’s Dev-centric,” right? And that’s the sign of a good compromise when they’re both pointing the finger at that.

    But it has come—at least as far as testing goes, from what I see, it has sort of tilted where, you know, as we’ve shifted testing left, we’ve shifted responsibility left as well, which kinda winds up closer to the Dev, or certainly to the DevOps teams.

    However, though, let’s look at the alternative, and I’m gonna ask all three of you—all four of you have been around the block once or twice. My personal feeling is, is that we do a much better job of test coverage today than we did 7 or 10 years ago, and I think DevOps and continuous automated testing is a big reason for that.

    Thoughts? Anybody disagree? Show me wrong.

    Wong: I will challenge you, Alan.

    Shimel: Okay. I was hoping someone did.

    Wong: I’ll challenge you, and the reason is because—so, we’re all familiar with the OWASP Top Ten.

    Shimel: Very much.

    Wong: There have been a handful of versions of the OWASP Top Ten since the first was produced in 2003. I believe we’re gonna see another version later this year. The current version is from 2017, and if you take the 2017 version of the OWASP Top Ten and you put it right next to the 2003 version, it is sort of mind blowing how similar they are.

    Shimel: Yeah.

    Wong: And what that says to me is, we actually know exactly what the problems are. We know how to find them, we know how to fix them, and we know how to prevent them, but they’re still around, and so I think that’s—

    Shimel: They are, but are there as many of them, right?

    Wong: Absolutely. [Laughter]

    Shimel: You think there’s as many cross-site scripting or buffer overflows than there was 10 or 15 years ago?

    Wong: So, there are some categories that have been eliminated. You know, there are some categories that, for which we can define a secure pattern, and we can encourage folks to use that secure pattern, and for which we can actually eliminate some of these things.

    But there’s others or which we cannot. You know, I think about—I recently visited my sister’s home, and they have two young children, a 2-year-old and a 4-year-old. And at night, what they do is, they run a Roomba, which is brilliant, you know? If you could spend your weekend playing at the park with your kids instead of vacuuming, of course you’d wanna do that. And the Roomba works because they sort of take the time to get all the toys off the floor and make sure everything’s clear and once they use the Roomba, they clean it. There is this different work involved in effectively using a Roomba that’s different from sort of manually using a vacuum.

    And I do think there are these two distinct categories of testing, one category which you could say is known, repeatable, and automatable, and another for which manual testing, I believe, will always need to exist. There are types of security flaws like business logic flaws, race conditions, chained exploits that I don’t believe that in my lifetime, we will be able to figure out how to teach a computer to find these particular types of issues.

    Kalsey: And it’s beyond just security testing. I mean, exploratory testing, from a tester, your automated tests are not going to find, “This error message makes no sense in this context. I did this, I expected—I don’t know what this error message is trying to tell me to do.”

    Your automated tools aren’t going to find that. All they’re going to be able to find is, “It didn’t work, we sent an error message. We had the things we wanted to put in the error message there.” You can test that your code is doing the right thing, but if you didn’t design it to do it right, you’re not gonna find that with an automated test.

    Shimel: Fair.

    Dawson: I would tend to say, for the surveys that we’ve issued and I’ve read, your original statement, “Has test coverage improved significantly?”—yes, I think all indications are, we are getting better at automated testing, we are getting better at that pursuit of that thing we call test coverage.

    But I think what’s more important is, has the quality of test improved? Are we testing the right things, right, from functional testing to security testing, various shades of security testing? And I’d say (1) yes, we have improved there by sort of the qualitative and quantitative measures that I’ve seen. But I also think, as we truly start to focus more on quality, we start to achieve more coverage, we start to implement better tests, it becomes more clear, as I think Adam and Caroline are speaking to how much more work there is to do, how much other things there are to improve testing on. Pair that with a constantly changing technological landscape, right? We’ve gotta learn new stacks, we’ve gotta figure out how to test new stacks. We’ve got half of our put in in a SaaS platform, but then we deploy on prem, et cetera, et cetera, et cetera. And then you add to that that, at the same time, we’re trying to transform organizations.

    So, Adam, you talked about exploratory testing; Caroline, the human element. I think one of the things that pursuit of the full stack Dev, that pursuit of the fully automated processes failed to do in a lot of orgs I speak to is, we talk quality first, but oftentimes, the DevOps transformation doesn’t involve quality engineering first, right? And I think one of the things we need to get better at is engaging with and partnering with Quality and establishing our automated and modern processes.

    Kalsey: Yeah. We talk good in the testing industry a lot about shift left and that testing is moving earlier in in the process, and too many organizations have taken that as, “Well, the developers are the ones that are early in the process, so that means the developers do it.” No! Shift your damn testers left. Get them involved in the design phase. Get them involved in talking about the architecture. Get them involved in the entire thing, not shift the task to the people who are earlier in the process. Shift the whole process, please.

    Dawson: Or to a script, yeah.

    Ashley: I’m gonna take a whole ‘nother tack, and I thought you were gonna go here, Brian, is, I think we need to shift tests down. We need full stack testing. It’s not application testing anymore. Most of the security errors that we have are due to configuration errors. And what Caroline said was absolutely true. We still have SQL injection, cross-site scripting, and overflows may be less so. But why? It’s because it’s not just in the app layer that those things happen, it’s in that software stack. And I know not every tester can be an expert at the stack itself, but maybe that’s, instead of kinda dividing the DAST and SAST and the different kinds of testing that we do and just deciding, can we shift those in one direction is, let’s think about it from a depth perspective, because that’s where a lot of those errors are coming from. It’s not just the app.

    Kalsey: Oh, yeah, and the tooling on this is also, can be super fragmented. You need one thing to test your infrastructure code, you need another thing to test your UI, you need another thing to do the security—and they’re not, consolidating those reports and combining them and figuring out what worked and everything is hard work and there’s nothing that does that. This is a place that Tricentis could definitely improve and improve our own tooling here.

    And then, once you’ve done that testing, the results are often in a silo. Okay, I found out I had a problem—how do I fix it? How do I go see the data behind what was going on in the system to understand this and solve this? And now I’ve gotta dive into a monitoring tool or my logs or an observability tool instead of just having everything all in one place.

    Shimel: So, I think there’s a—I’m sorry, Caroline, you go.

    Wong: No worries, and thank you, Alan. So, we’ve talked about shift left, shift right. Mitch is kinda talking about shift up and down. I think there’s another axis, if you will, which is sort of what I’ll call shift in and shift out. So, you can test things in and out of band, and that’s gonna make sort of a wildly different difference in terms of how those processes run.

    You know, I think 10 years ago, security people appreciated the power that came with being a gate in the process, being an end band process. You know, today, it actually makes sense, I think, for a lot of security testing to be out of band, but that removes the sort of power and authority of security people to say something like, “You must fix this, otherwise you’re not gonna go live if it’s happening out of band.”

    Shimel: Fair. So, I’m getting a little dizzy, we’re going left, right, up, down, in, out. But—

    Ashley: It’s a circle. [Laughter]

    Shimel: Yeah, you know, shake it all about. But here, fundamentally, though, are we just kinda dancing—no pun intended—are we just dancing around the real issue, which is, we wanna do more pre-deploy, we wanna do more, we want better quality software, right? I think we could all wrap our heads around that idea and vote for that. We all want better quality software. Security people are at a premium. We can’t shift security people left or en masse. Testing people are also at a premium, though we’ve integrated them into the DevOps teams. Developers are at a huge premium, they’re probably our most expensive resource in terms of humans.

    What do we need to do to make everyone’s job easier here, to make this function better? Is it a question we’ve gotta automate more? I mean, maybe that’s what it is, if we automate more, or is it a cultural thing, right, where—

    Ashley: There’s also test-driven design, right, which is, as you’re designing it, you talk about, you put together your test strategy of, “Okay, we do it this way. Let’s talk about how we are going to test it, start to lay out the framework for how we think this can be validated.” I mean, it’s not the only thing to do, but I think—so, if you start with that in mind, now you’ve got a path to pursue as opposed to, “Here’s a chunk of software, you folks figure out how to test it, right? We built it, you test it.”

    Dawson: Yeah, and I’d add, I think there’s no—again, not only is the practice of testing harder than we often like to admit, but the, you know, the path to kind of getting to where we fully wanna be, where we don’t dread testing, complex, hard path, and I’d say it’s the DevOps trinity, you know, Alan, and we all can probably hit a few points on each.

    But you have to address people and culture, as Adam brought in earlier. There’s no getting away from, security needs to be a thought for everybody, right? I can install all the locks I want on the front of my door. Actually, over 24 years—today is my anniversary—my wife has programmed me to lock the door when I come in the house without thinking, right? She’s kind of impressed a security culture on me.

    You do have to address people and culture, process, practice, tools and technology. Automation alone will not solve it. A mindset alone will not solve it. All of that needs to come to fruition.

    Shimel: Mitch, make a note—invite Brian’s wife to our next security panel.

    Dawson: [Laughter]

    Ashley: I’ve already looked up her e-mail address—thank you, Brian, appreciate it.

    Shimel: Happy anniversary, by the way, too, Brian.

    Dawson: Thank you, thank you.

    Kalsey: This is one of the places where I think what Caroline said is so important, that this in bound, out of bound—if you’re trying to do everything in line, of course, it’s gonna be harder. In shifting that mindset to doing things continually in the background, we already do so much stuff and process automation in the background where we don’t have people check, “Here’s a step in the process.” No, this is going along in the background, dependency watching and that sort of thing and updates.

    We can be doing testing in the background as well for a lot of it, and identifying what needs to be in the foreground and what needs to be in the background. Look, I’ve seen CI/CD pipelines that take hours and hours and hours to run because the tests take six hours to execute and to build. That can’t work in any sort of a reasonable DevOps system.

    Wong: I think there’s two parts to a solution, and I’m really, frankly, just parroting what Brian said. I think there’s a collaboration piece between the people. You know, to an earlier part of our conversation, you’ve gotta have the folks with those specialized skill sets. Ideally, you’re able to get access to those folks on demand, which historically has not been something that’s been possible, but that’s beginning to happen.

    The second thing is—so, you’ve got your people collaborating, you’ve also gotta have your technology integrated. So, for whatever security tool or processors, how do those outputs actually get to the engineers? What we need is bidirectional integrations for things like Dev ticketing systems. We need things like APIs for test results. I think collaboration at the people place and integration at the technology place—both of which we could call processes—then it’s just, it’s really a repeat of what [Audio skips].

    Shimel: Mm-hmm. I mean, but wasn’t this one of the promises of DevOps? I mean, I got into DevOps because I thought it was a better way to do security, truth be told. But one of the promises of DevOps is, we’re gonna automate more, so we could go faster with more quality—two out of three ain’t bad, right? And, you know, did we lose that somewhere? Is that no longer a goal, or have we taken that as far as it goes?

    Kalsey: We keep trying to solve it with technology instead of by looking at the culture and changing how people think. And you can’t think the same way and apply new technology to it and expect the technology just to magically solve all your problems.

     Shimel: Brian, you agree, or Caroline?

    Dawson: I absolutely 100 percent agree, and I’ll agree and then I’ll just add a point. And I know I’m being a bit nebulous about it, but there’s a human element to this. At the end of the day, it’s humans developing software for humans, right? Whether it’s the code on your electronic control module in your car or Waze on your phone or the OS, at the end of the day, the final endpoint is a human. And you know what? At least now, and I know we’re improving, there’s no way that we can ensure—and I don’t mean to accept security here, but to test the quality of the human experience, right?

    And think about this—at the end of the day, knowing that the language on a screen is self-descriptive and informs me what to do. Testing the fact that, or ensuring that when I submit my credit card number it’s not vulnerable, right? Whether we’re talking API testing, whether we’re talking security testing, all of this at the end of the day boils up to customer or user experience testing.

    And I guess what I’m gonna posit is that we can never entirely automate that. And where we’ve hurt ourselves and possibly made a false promise is, we’re gonna create a bunch of full stack engineers, we’re gonna get rid of, away from operations functions, testing functions, and we’re gonna use TDD and automate everything from the start, Gherkin, yadda yadda yadda. And I believe—look, that has enabled us to go faster, but our impedance mismatch, the limit we’ve hit right now is where we’ve failed to better connect people and enable them to collaborate and share knowledge. So, not just security, not just back end, not just data, but the entire customer experience is of quality. Dev can’t do that alone.

    Shimel: No, sir.

    Dawson: I’m sorry, Alan, did I get, did I—

    Alan Shimel: No, no, that’s all—I’m saying no, sir, you’re 100 percent correct, but I know Caroline wanted to say something.

    Wong: So, I do have a comment about automation. I think that DevOps has figured out how to do automation when it comes to defect discovery. I think we’re sort of good at that. I think what we’re still trying to figure out is automation when it comes to workflow and process so that, actually, again, to Brian’s point, the collaboration can happen automatically, rather than due to a human who’s involved and making it happen. How do we get the right information to the right people in the easiest, most efficient way at the right time, and how do we make it super easy for them to do their jobs?

    I do think that there remains—I do think that the next evolution of automation and DevOps is gonna go from defect discovery automation, which I think we’ve gotten quite good at, to workflow and process automation.

    Shimel: Fair enough. Adam, thoughts?

    Kalsey: I like it. I mean, identifying what you’re automating and what’s working in that automation is important, but also identifying what’s not being automated or what in your automation is broken. And not broken from the standpoint of, it doesn’t execute or it doesn’t run to completion, but broken in, it’s not solving the problem you wanted it to solve.

    Shimel: Fair enough. Guys, we have time for maybe one more question. I’m gonna pose it and throw it out there to you. Is it possible we’ve shifted too far left or that you can shift too far left and we need a little rubber band, here, going the other way, a little pendulum swing? Or you think we just scratched the surface? Caroline, you look like you wanna say something.

    Wong: I think that’s a great question. I do think it’s possible to shift too far left, and the reason is because, while we, I think, are all familiar with the statistics and the studies that say if you fix something earlier in the cycle, it’s cheaper—there’s stuff that exists to the right that doesn’t exist yet on the left. Software development is, you know, to sort of a little analogy that we talked about earlier, I think it’s a dance. I think it’s a dance between people. I think software comes about as a result of the behaviors and the actions and the decisions that various folks take together. And security and quality are emergent properties. They’re not Band-Aids, they’re not vitamins, they’re not painkillers. They have been, as a result of this dance. So, there are some things for which, if you try to test it too early, it doesn’t actually exist in its final form yet. If I take my 6-year-old to the doctor and then I don’t when she’s 21, you know, might we have caught something super important as a 6-year-old that we were able to step in and address right away that would’ve been great? Yes, but as a 21-year-old—guess what? She’s gonna have different problems that were not apparent at age six.

    Shimel: Spoken like a true mom and parent, right? Parents, we worry about that. Anyone else? Thoughts on that? Can we go too far left, or have we gone too far left?

    Dawson: I, Alan, think it just depends. I think we’ve interpreted left different ways. I think it’s a good, catchy term. It’s an important and powerful catchy term, but as I’ve heard others discuss, we sort of overemphasized this idea of left. One, to Caroline’s point, right, we just do everything here and we’re done, good to go, right? But then this idea that we can put everything in Dev? Well, no, I think—I think, for what it’s meant to communicate, shifting left is an apt term.

    I think in terms of ensuring that we’re doing everything we can as far left or as early in the process to mitigate issues later—great. Right? But we don’t just shift security left. Right? Like Caroline said, inbound, out of bound. Actually, we need to shift security everywhere. We don’t just shift quality left, we need to shift quality everywhere.

    So, I think there are—we need to be ensuring that it’s almost zero trust software delivery, right? At every stage of the process, from concept where you should be sitting down with QA and the security team to capture the requirements to test, to deploy, to run, we need to be thinking about it, also.

    Alan, I’d say shift left is good—shift everywhere is really what we meant to be doing, right?

    Shimel: It’s better. Great.

    Kalsey: Any time we engage in sloganeering, there’s gonna be people that pick the wrong things from the slogan. I mean, “Hey, we have DevOps. That means we don’t need Ops anymore!” And that’s not what it meant, and there’s people that have taken the wrong cues from shift left, and instead of shifting the processes left, they shifted the tasks onto the people who were left already, and that’s not gonna work.

    Shimel: Absolutely. Hey, Mitchell, you wanna tie a bow on this?

    Ashley: I’ll put a bow on this. You know, there are admittedly many, many things that I don’t know, but one of the things that I do know is that, if a developer says it’s tested, it’s ready and a QA person says it’s tested and it’s ready, five out of six dentists will choose the QA person. I will, too.

    So, there’s something there. There’s a reason why we don’t have DevQA or DevTest. We don’t talk about it that way, we talk about DevOps or DevSecOps. QA is extremely valid and necessary, and we can’t live without it, and I think we need to invest in helping, elevating how we test and how we think about our software applications to test in. So, those dentists will be happy.

    Shimel: And Crest, the Crest test for QA. Thanks very much, Mitchell. Caroline, Brian, Adam—thanks for joining us on this episode of DevOps Unbound. Great conversation. For our audience out there, do check it out. We have another episode coming up in—well, not next week, the week after, and then I think we have a roundtable the two weeks after that.

    But for now, though, we’re gonna wrap. Many thanks again to Tricentis for sponsoring DevOps Unbound. Thank you for watching, thanks to our panel. This is Alan Shimel, we’re out.

    [End of Audio]
  • Improving Security with Mapping, Automation and DevOps

    Improving Security with Mapping, Automation and DevOps

    Strong cybersecurity is paramount for every organization. But all too often, security teams are disconnected from ongoing development processes and viewed either as an impediment to bringing products to market or as an afterthought. This leads to increased costs and possible gaps in the attack surfaces of new platforms.

    While many organizations are turning to security automation to help them manage and mitigate their expanding threat landscape, quick fixes rarely work. Planning is required to help organizations determine their pain points, add security early in the software development process, and determine where automation can deliver the best ROI.

    What Should Be Automated?

    Security automation can programmatically test, institute guardrails, provide feedback and remediate cyberthreats by executing tasks as part of the continuous improvement pipeline. This, in turn, can help understaffed security teams by streamlining complicated and time-consuming testing processes, enabling teams to maximize their time, be more productive and focus on risk priorities. Once the manual process is removed, the automated workflows can then carry out a variety of more minute actions using intelligence and logical decision-making.

    Security-focused areas that may benefit from automation technology include but are not limited to:

    • Static and dynamic code analysis used to discover security vulnerabilities
    • Test harnesses for software configured to run a program unit under varying conditions to discover and monitor its behavior and outputs
    • Upstream code analysis that examines code such as complete code blocks or patches
    • Vulnerability testing, management and remediation to discover and fix weaknesses that may be susceptible to attacks
    • Penetration testing used to simulate cyberattacks on an organization’s computer systems and evaluate security posture
    • Automated enforcement based on data classification and tagging strategy
    • Deployment and management of infrastructure components

    Focus on ROI

    Despite the benefits, many organizations face substantial hurdles in developing, implementing, testing and optimizing the comprehensive, integrative, long-term approach needed to use security automation to cope with the evolving threat landscape. It’s all too common for organizations to begin projects that start with automation as the outcome rather than rigorously mapping the processes and determining where value from automation can be gained.

    Consider an organization that decides to automate the process of deploying a firewall to an AWS cloud. A team spends several weeks developing and testing an automation playbook that can spin up virtual firewalls, license them, connect them to a central manager, deploy configurations and apply them and send logs to the appropriate places. Testing proves the automation works.

    But when asked how many firewalls they expect to spin up this year, the answer is two–maybe. How many next year? None. The team, therefore, spent more time automating this function than it would have taken to just deploy the systems and the organization won’t likely realize any direct return on this work for at least two years.

    Value Stream Mapping

    The first step in achieving real value is to understand that automation is a second-order operation that relies on a thorough assessment and plan of all the steps required to achieve real technical and business outcomes. That means conducting value stream mapping to analyze, design and manage workflows that best suit your environment.

    Mapping will help you analyze and define security processes. Without analyzing your processes, you’ll have no idea of where the bottlenecks are or how they can be removed. Better understanding the processes will also allow you to refine them as needed. Without doing all this, you’ll have no way to prove the value of the automation you’re implementing, and no compelling business justification for it.

    The Role of DevOps

    Few organizations are able to effectively realize the benefits of automation right out of the gate. Value stream mapping enables organizations to determine their pain points, pinpoint exactly where they want to use automation and identify processes that cannot or should not be automated. Clear-eyed planning and assessment will help teams define a process and determine the value of return on automating certain processes.

    In addition, for security to be effective, we have to shift security left in the software development life cycle (SDLC). Security practitioners should be engaged in the development pipeline, including collaborating on automation initiatives and building harness and test cases as the work progresses. This will save time, improve quality and ultimately add value, ensuring the success of security automation projects.

  • Harness Updates Cloud Cost Control Tool for DevOps Teams

    Harness Updates Cloud Cost Control Tool for DevOps Teams

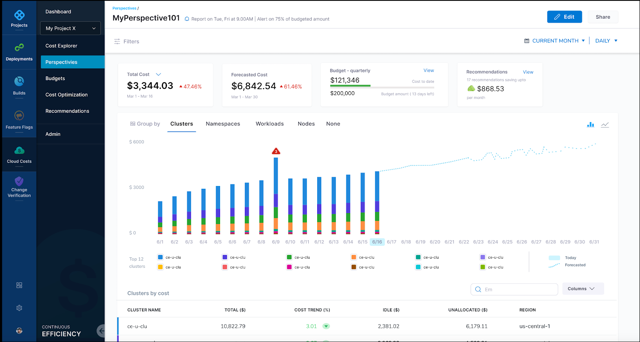
    Harness today announced that it has updated its cloud cost management (CCM) module for its namesake continuous integration/continuous delivery (CI/CD) platform to add support for Kubernetes at the node level in addition to providing business intelligence tools to analyze overall cloud costs.

    Harish Doddala, senior director of product management for Harness, said the update surfaces more granular insights into cloud costs that DevOps teams are incurring because cloud resources are being wasted. The latest version of CCM enables DevOps teams to create their own customized views of those resources.

    As the overall economy continues to recover from the COVID-19 pandemic, more organizations are looking to exercise greater control over IT costs. In the immediate aftermath of the pandemic, many DevOps teams consumed cloud resources without much regard to cost to enable organizations to advance various digital business transformation initiatives. Now, finance teams are requiring DevOps teams to account for those cloud costs.

    The goal is not only to reduce costs whenever possible—by, for example, quickly identifying a sudden spike in cloud resources consumption—but to accurately forecast budget costs on a monthly basis so that both IT and finance teams can collaboratively track spending. The typical finance team is just as concerned about accurately predicting costs as they are the total amount spent.

    Harness Cloud Cost

    Ultimately, Doddala says Harness’ CCM enables organizations to better assess which software development projects to prioritize based on the cloud resources allocated. It’s not uncommon for organizations to suddenly have to shift software development priorities as business conditions change and evolve. A project that may be a top priority today can easily be downgraded because, for example, a rival has been able to launch some new capability that an organization now needs to quickly match.

    DevOps teams, unfortunately, don’t always pay as much attention to infrastructure costs. Harness’ CCM helps reduce those costs by automatically stopping idle resources running on Amazon Web Services (AWS), Microsoft Azure, Google Cloud Platform (GCP) or any Kubernetes cluster, said Doddala.

    There are, of course, any number of existing tools that cloud service providers make available to enable IT teams to reduce costs. CCM, however, provides that capability within the context of a DevOps platform that can span multiple cloud computing environments, noted Doddala. DevOps teams, for example, can create and enforce cost policies for cloud infrastructure into a CI/CD pipeline and prevent an organization from being surprised by a bill from their cloud service provider at the end of the month.

    It’s not clear the degree to which cost control modules will influence the selection of one CI/CD platform over another. However, it’s apparent the days when organizations consumed cloud resources with little regard to cost are ending. In fact, there may soon be more cost controls imposed on software development projects than there were prior to the pandemic. The challenge, of course, is finding a way to automate the implementation of those controls and minimize the impact on software development velocity.

  • EP 14: What Have We Learned?

    EP 14: What Have We Learned?

    The past year-plus has brought disruption and opportunity to businesses and software teams all over the world. Change is inevitable, but 2020 was a year of massive change: businesses pivoted, supply chains were disrupted, customer expectations shifted to contactless services, digital transformation projects accelerated, new digital experiences were created, the move to the cloud jumped into high gear and our ability to create and deliver software was elevated to an essential capability for business.

    It’s time to pause and ask ourselves, what did we learn from all of this disruption and change? What lessons can we carry forward? How do those experiences inform how we prepare for 2021 and beyond?

    Cornelia Davis from Weaveworks, Kurt Chase from Tricentis and Sanjeev Sharma from Truist join hosts Alan Shimel and Mitch Ashley in this episode of DevOps Unbound to discuss lessons learned, how to overcome the obstacles we’ve faced over the past year and how to improve business processes and make better decisions. The video is below, followed by a transcript of the conversation.

    DevOps Unbound is sponsored by Tricentis, the world wide leader in automated testing. DevOps Unbound airs biweekly on TechStrong TV, with all episodes available on Digital Anarchist. There is also a live monthly roundtable open to audience participation.

    Alan Shimel: Hey, everyone, this is Alan Shimel, and you’re watching DevOps Unbound. For those of you watching for the first time, DevOps Unbound is a biweekly video series where we tackle interesting topics related to DevOps. Once every four to six weeks, we do a live roundtable with a live audience questions and live audience participation, and we invite you to our next one. You can find that scheduling at DevOpsUnbound.com.

    Today, though, is a session just with our panel, and what a panel it is. Let me introduce you to them. First off, let me introduce our friend, Sanjeev Sharma of Truist. Sanjeev, maybe you wanna introduce yourself to the audience.

    Sanjeev Sharma: Sure. Thanks, Alan. First of all, thanks. Great to see you all. Hopefully, we will be able to meet in person soon, but thanks for having me on. I am the Head of Automation and Platform Engineering at Truist Bank. Truist, for those of you who might not know, is the new bank that was created last year by the merger of BB&T and SunTrust. I have various hats I wear at Truist, but my background is mostly in the DevOps and cloudware adoption space.

    Shimel: Excellent. Thank you, Sanjeev, and welcome. Sanjeev, I should mention, is also the author of The DevOps Adoption Playbook.

    Next, we’re really, really pleased and honored to have Cornelia Davis with us. Cornelia is, of course, a pretty well-known thought leader and leader at the DevOps space, but is also at Weaveworks. Cornelia, welcome. If you wanna give a little background?

    Cornelia Davis: Sure, yeah. Thank you so much, Alan. It’s so great to be on again. Yeah, I am the CTO at Weaveworks, and you might know Weaveworks as the company that coined the term GitOps, that has been kind of driving that movement. And GitOps is just an element of a broader category, which is really developer platforms, which is what we’re talking about many, many times when we talk about DevOps.

    And so, prior to Weaveworks, I’ve been here for about a year and a half, I was at Pivotal, where I worked on Cloud Foundry and Kubernetes based developer platforms, you know, platform teams for enterprises for quite some time. And I’m also the author of a book called Cloud Native Patterns, which is a book aimed at architects and software developers, helping them learn how to build software for this highly changing, highly distributed—constantly changing, highly distributed environment that is the cloud.

    Shimel: Absolutely, thank you. It’s a pleasure to have you here. Last but not least on our panel today is our friend Kurt Chase with Tricentis. I should mention Tricentis is a sponsor of DevOps Unbound, and thank you, Tricentis, for sponsoring. But Kurt, why don’t you give them your background?

    Chase: Yeah, thanks, Alan. Great to be here today with Cornelia and Sanjeev. Nice to meet both of you. I’m currently running Release Management and Engineering Services at Tricentis, which, Engineering Services is a group that provides cross cutting services primarily for internal engineering, but effectively for the whole corporation as well.

    Prior to Tricentis, I spent years at Splunk, again, supporting the engineering function, all the CI/CD builds and releases and things like that. And then prior to that, I spent almost two decades at Autodesk, producing the AutoCAD, multiple releases of the AutoCAD software product.

    So, again, it’s great to be here today with all of you. Excited to talk about some of the things we’ve learned over the last year, year and a half—and what a year it’s been, holy cow. [Laughter]

    Shimel: Yes, it has. Then let me finally introduce my co-host here at DevOps Unbound, my good friend and partner, Mitchel Ashley. Mitch, why don’t you give a little background?

    Mitch Ashley: Thanks, Alan, and of course, I’m excited to have our panel—thank you for joining us, all of you, today.

    I’m Mitch Ashley, CEO of Accelerated Strategies, an analyst firm that focuses on DevOps and cloud native, cyber security, digital transformation. I also work with Alan as part of MediaOps, the folks that put on this event, with the CTO of that organization. So, it’s a lot of DevOps practicing and observing what others are doing, so I’m excited to hear what Sanjeev and Cornelia and Kurt have to say, too.

    Shimel: Alright. Thank you, Mitchell. And as I mentioned, DevOps Unbound is sponsored by Tricentis, so—many thanks to them.

    Today’s episode, folks, as I mentioned off camera, I don’t wanna jinx anyone or anything, but at least here in the U.S., we seem to, at least we hope that we’re seeing this whole COVID life sort of starting to recede in our rearview mirror. We are returning to normal or a new normal, some may say recklessly too quickly, or some may say not quickly enough, but certainly, the return to normal is on, and accelerating.

    But, you know, there have been many, many lessons, many, many experiences, some painful—extremely painful—from a business and a humanity point of view over this last 14, 15 months or whatever it’s been. There’s also been a tremendous amount of success, a tremendous amount of acceleration, a tremendous amount of, “Jeez, this really—this worked. We didn’t know if it would work, but it worked,” probably the Internet being the first thing, right? Where would we be with this without an Internet?

    But can we—let’s take a moment, and let’s, as I say, hope and pray that this is in our rearview mirror or starting to move to the rearview mirror. What are the lessons? What can we learn, what will we take forward from this? And, you know, I don’t wanna boil the ocean, because I think there’s a lot, but if I asked each of you to give me three things that you really, you think—not just you personally or your organization, but the tech industry has learned, the business world has learned, perhaps society in general, humanity has learned, what would you say some of those things are?

    I don’t wanna put anyone on the spot, but Kurt, you always have something to say. I introduced you last, we’ll start with you.

    Chase: Sure. I’ll jump right in, and one thing that’s amazing to me, not so much from the technology or engineering or R&D side, let’s talk about business, here—the other aspects of the business that were able to adapt to remote work, that, to me, was pretty incredible.

    When COVID really took hold, I wasn’t too worried about software engineers and folks producing software working from home, doing their coding, testing, and all that. The other functions—finance, legal, things that are required to ship your products—seeing those go remote at the pace they did, that was pretty incredible. I think they definitely took advantage of some of the learnings from their individual engineering teams. But to me, that’s one thing that sticks out right away is the speed at which businesses adapted to working remotely and the success they achieved across the functions in the business. That was incredible to me.

    Shimel: Agreed. I mean, the speed of adoption was something. Cornelia, did you wanna say something?

    Davis: Yeah, sorry, I was muted there. I did wanna chime in, because I agree, and one of the ones that really knocked my socks off was how quickly call centers went remote.

    Chase: Yeah. [Laughter]

    Davis: Because that isn’t something I would’ve expected. I would’ve expected them to still be kind of really tied into their telephony services and, you know, the phones that are on their desks.

    But I spoke with many, many people, you know, various customer service people from the banks and from, you know, the Amazon.com—well, there’s not that much of a call in center there, but from all of these different organizations where, when you chatted with these folks, they were like, “Yep.” Within a week, they were able to move everything, move everybody remote in these traditionally really physical call center based systems. Which means that there had to be some preparation. I don’t know if it was intentional, but there had to be something that allowed them to flip that switch so quickly. Is it just forwarding phones? Is it just VPNs? I don’t know.

    Shimel: No, no, it was—so, I have some info on that, if I can. I interviewed a fellow down here in Florida, I think he was out of Tampa, and he operated multiple call centers, like in Costa Rica, which is actually a call center capital, believe it or not, that’s a big business down there. It turned out that the software they used, right, people in call centers, they don’t just—Kurt just doesn’t call someone randomly. Everyone gets assigned their calls or their inbound when a call comes in and gets assigned.

    The software they used within the call center itself worked just as well, the person didn’t have to be in the desk next to you, he could’ve been anywhere, it turns out, or she could’ve been anywhere. And so, it worked just as well in a remote thing. So, they still used the software they were using that tracked how many calls they did, who they spoke to, the notes, putting it into the central database. Yes, they had to be cloud-based, right, because there was no one in the call center to kinda run that infrastructure. But the software, it turned out, worked remotely as well as it worked on everyone’s desk in the call center. It was an amazing thing.

    And so, what they found—again, and this is gonna be, I think, something that’s gonna be a recurring theme—who needs the physical call center? They don’t need that infrastructure anymore. They could have people working at home just as well.

    And so, the more advanced ones—and you’ve probably seen this yourselves—you call someone, they may be very well at home, but they’re giving you the same mediocre service that you get when you call the call center itself, right? [Laughter] But yeah, no—

    Chase: And that’s the point. I think with a business, it’s applicable across functions there, it’s amazing. And business learned that they can still be extremely successful, even if everyone’s remote. And having that pool of remote talent—that changes everything. [Cross talk]

    Sharma: I think a couple of things to be noted there, right? First of all—sorry, Cornelia, I think I spoke over you. You know, one is, the pendulum also needs to swing back from that extreme.

    Chase: That’s the challenge, yeah. [Laughter]

    Sharma: Right? Because, while we have people who are able to work from home because the technology is there, from an equity perspective, one has to look at people who cannot work from home who are being forced to.

    Chase: Yeah.

    Sharma: And we experienced that when we opened up our offices. We are just beginning to open up our offices. June 1st was the first day folks would come back. And I was surprised to see some people had jumped at the opportunity and said, “I want to go back.”

    Chase: Yeah.

    Sharma: Then when you look under the hood and you talk to them, you realize, you know, they’ve been struggling. They’ve been operating out of a tiny closet, right, because they don’t have the space or because they have toddlers or they’ve been struggling with Internet issues, and it is worse overseas than it is here in the U.S.

    So, I think the pendulum needs to swing back to a more normal position, but hopefully, it won’t swing all the way back to where they say everybody has to be on site, on premises, right? So, I think that is definitely, some balance has to happen to recognize—some people do need a workplace, where they can work comfortably.

    Chase: You’re absolutely right.

    Davis: Yeah.

    Chase: I know a story of one individual who was in a one bedroom apartment in San Francisco and after three weeks, he couldn’t handle it. It’s like—I don’t have no space.

    Davis: Yeah.

    Shimel: It happens. Cornelia?

    Davis: And, you know, honestly, I have space, and I have a wonderful office and I’m super comfortable, and I’m also desperate to get back into the office.

    Chase: Yeah.

    Davis: Because—and I love, Sanjeev, that you called out the equity thing, because that’s something that is so painfully obvious in the whole pandemic is that this has only broadened the inequities that we have across society, and we need to absolutely focus on that.

    But then the other lesson, you know, with me, I’m extremely privileged, I live this super comfortable, I never really had to worry about catching COVID, I could just choose to stay home. But humans need humans and, you know, we’re all coming to you on your two-dimensional screen. I am super fortunate that last week, I had the opportunity to have my first face to face with a couple of colleagues in over a year, and it was rejuvenating. I’ve been saying, it’s a 3D work world again instead of a 2D work world.

    Shimel: Yeah.

    Davis: And so, I mean, humans need humans. But you’re right, Sanjeev, I think that the even bigger thing is that we really, really need to look at the inequities. And in the beginning, in the early parts of the pandemic, without getting too political here, we had all of this narrative around these people who we considered essential workers who were kind of the forgotten, like, taken for granted folks, and they were put on a pedestal, and that, unfortunately, didn’t last that long.

    Chase: Yep.

    Sharma: Yeah.

    Davis: And so, we need to bring that back.

    Shimel: And they weren’t paid like they were that essential, either, but that’s [Cross talk]—yeah, it was a pretty low pedestal. But let me, you know what, you bring two things—I’m sorry, Mitch, I just wanna make two quick points.

    Number one, when we talk about the inequality, let’s be really clear. This has affected women and mothers especially, more than men, right?

    Ashley: Mm-hmm.

    Davis: Absolutely.

    Shimel: Mothers have had—because not only have they had to work from home, but they’ve had to take care of the kids who are not in school. And it’s very hard being a teacher, a home care provider, and doing your work at work. And so, how many women have had to work out of the workforce because they had to take care of their kids and their kids are home and they didn’t have an option, there was no child care for them. So, I think—

    Ashley: And the challenges of re-entering the workforce.

    Shimel: Right, and now they’ve gotta re-enter after, you know, months off, and that’s never easy. People wanna know, “Well, why the gap in your résumé?” Well, there’s a gap in my résumé because I have this beautiful child that I’m raising, you know, and how dare you? That’s number one.

    Number two, it is a case of the rich get richer, right? Companies that, not only individuals as you say, Cornelia, but companies that were able to leverage this. Man, they accelerated, but they accelerated at the expense of their competitors who couldn’t, right? Think about all the open retail shops in the malls near you and the strips, right?

    Davis: And this is a place where I’d love to pull DevOps into the conversation, because we are, of course, as a part of DevOps Unbound. One of the things that I thought was impressive—and I’ve worked with some of these companies. In, you know, my previous life at Pivotal, I worked with The Home Depot, for example. When you had The Home Depot and you had these other organizations that, in a matter of weeks, updated their software so that you could do things like curbside pickup? That right there is DevOps in action.

    Shimel: Yep.

    Davis: It is the ability to release software, get feedback, release software, and there was no six-week testing cycle that we used to do, or eight-week testing cycle.

    Shimel: Mm-hmm.

    Davis: It was like, “You know what? We are gonna be testing in production, because we didn’t have time to test this for six weeks.” So, it brings in all of these tools that Kurt, I’m sure, you have day to day experience with, which is these things that allow us to put safety nets in place to be able to release all the time. I mean, that is something where the people who were along their DevOps journey already had a leg up on those that didn’t.

    Ashley: You know, Cornelia, I had that exact experience where I couldn’t get a computer, you couldn’t get one shipped to you, they just weren’t there, so I had to build a computer for some video work, and did it solely from parts from Best Buy, by curbside pickup, two Best Buys in town.

    Davis: Yeah.

    Ashley: So, it literally was, like, a week later, all of a sudden, I could do this, and I was pretty shocked by it.

    One of the things I wanna say, though, about what we’re discussing is, the people dimension of it is extremely important. I think there’s a whole other set of lessons for the business. I think we’ve pressed reset on a lot of assumptions about how businesses have to operate, that you have to be in an office. And essentially, we’ve kinda globalized the business by just taking the location out of it now. And yes, there are privileged and underserved and people who aren’t privileged. And those inequities probably are gonna get bigger, not smaller, because I don’t think we’re gonna all slap back into the office immediately.

    But what the businesses learned is that lesson you just talked about with Home Depot and you with Best Buy is—you know what? We can decide we’re gonna pick Team or Slack in two days instead of two years. We can get a software release out in a few days if we have to. Talk about constraint based management—you know, we now have this constraint and everything else comes off.

    So, I think what it’s done overall, though, is for DevOps and for all of us is, it’s moved software from maybe second or third to number one. Our ability to get software out the door that’s effective, meets what we need it to do, but that is a strategic advantage, maybe even a survival advantage of what we’ve seen happen in this past year.

    Chase: Yeah. I think some of it is, you know, businesses like that were forced to do it or die, basically, you know? And I 100 percent agree with Cornelia that I think they look to DevOps and some of the practices that they’re all used to. You know, the collaboration we need across functions to move forward and all those things are key, some of the foundations of automation, you know? That has been key in the DevOps space, and I think they learned, they need to take advantage of automation to do these things as well.

    So, yeah, it’s been fascinating to see that. And that was a point I brought up to see how businesses transformed and our world changed. And I think it’s opened up endless opportunities for us moving forward. And to Sanjeev’s point, I hope when that pendulum swings back, corporations take a look, that this is no longer a corporate decision where people work, it has to be more joint. It has to be more personal, because every situation’s different, and if you wanna maximize all your programs in HR, diversity and all those things, you have to take that into account. I don’t think you can do a one size fits all any longer.

    I still wonder if all those big office buildings, I worked in downtown San Francisco for many, many years—are we gonna fill those up again, ever? I really wonder now if that’ll ever happen. I could see it not happening, quite honestly.

    Ashley: I’m curious, Sanjeev, you’ve been in the middle of this bringing two companies together with this new bank in the middle of all of this. What in God’s name was that like? [Laughter] What are the additional challenges you’ve had for that, or maybe what opportunities has it created?

    Sharma: Yeah, so, I think it—you know, I joined in the middle of the merger, right, so we were in the middle of it when I joined. So, what I can tell you in the 10 months I’ve been there, we have shifted a lot of the priorities because of the pandemic, right? A lot of things which we would have done later on, we did first. We were able to do things.

    But the flexibility has definitely opened up. I can tell you, between the time I joined and between now, the ability to hire people who are not local to one of our offices has gone through the roof. It used to be an exception, now it’s the norm, right? The last three people I hired, two are in the West Coast and one is in Minneapolis, right, so Midwest. It doesn’t matter anymore, right? The same way there are—the operation has opened up a lot.

    And when I look at it broadly, outside of who I’m working with, when I’m talking to other companies where I have friends or colleagues, they are seeing more offshoring happen, right? Because they’re going, “Why do I need to hire somebody in L.A. if they’re never going to see the person ever anyway, does it matter whether he’s in Bangor or Bangalore, right? Let’s put the person, let’s hire the right person at the right place.” So, I think a lot of that has opened up. It has, of course, shifted some of the salaries, also.

    So, you know, a lot of things are going on, interesting dynamics are happening, and we’ll see how that all pans out. But from a perspective of, you know, doing the transformation, it is hard when you can’t have people in the same room on a white board and things which could have just drawn on a white board and knocked out in a 1 hour or 90 minute working session, now it’s like 15, you know, Zoom views, WebEx or Teams calls, which could have been, and it’s like, “Where is that white board we made up? Was it on Miro or was it on Mural or was it on this or was it on that? You know, and who can edit it, who can’t edit it?” All those—you know, dang it, if we just had a white board and all of us in the same room, we could have knocked this out in half a day.

    So, it is difficult to do certain things remotely. I think there has to be a balance, which needs to happen. And yeah, during a merger just made it more complex, because we are going through change every day, right? People’s networks are changing, people’s—how we are doing things are changing, we are updating stuff. It’s been a very interesting few months and we’re not done yet. You know, the merger isn’t over. We’ve still got a long way to go. So, it’ll be more fun going forward, I think.

    Shimel: I think it brings up the issue, though, of how much of this sticks, right? Because, I mean, look what Sanjeev just described. We’ve all had similar experiences, I’m sure, hiring people from all over the world—what difference does it make? They don’t have to come in the office.

    Does that stick? Because if it sticks, there are profound implications for society in general. Why live in San Francisco unless you love the view of the Bay. It’s a beautiful bay, right, the bridge is nice, but pay $4,000.00 for a closet-sized one bedroom apartment? Maybe not. I mean, on the other hand, I live in South Florida. Housing market is insane because of people moving here from New York and California and spending a fortune—Colorado, right?

    So, does this—that’s one example. Does the ability to work from anywhere, it makes no difference, is that something that sticks around, or do we, as Sanjeev said in the beginning, see a pendulum start to swing back? What do you think?

    Chase: Well, for me, like I said, I think elements of it have to exist and remain. I think there needs to be a balance, as Sanjeev said. I no longer think it’ll entirely be a corporate decision where employees are located. I think for some roles and groups in organizations, there needs to be a deeper conversation on where is the best talent, what’s the best way to use them? You know, having people sit—just the commute. The one thing I don’t miss is the commute. Oh, my God, you know, those three hours a day commuting, you know, that, to me, we have to somehow retain that benefit, you know, from working remotely somehow. I’m not sure how.

    But that’s a very good question, Alan, I don’t know. It’s like, will those office buildings ever be full again? I don’t know. I’m not sure.

    Sharma: On that point, I’ve been remote since 2013. In 2013, I was at IBM. I moved to a global role, and since then, I haven’t had an office. I’ve worked out of this room since then. But I used to travel 150 to 175,000 miles a year.

    Chase: Got it, yeah.

    Sharma: Right? So, for me, the office was a place to go collaborate, whether it was my office or my company, IBM—

    Shimel: And for all of us.

    Sharma: – right, or a client’s office, it was not a place to go and have a desk, right? My desk is here, right, my books are here—you know what I mean, right?

    Chase: Yeah.

    Sharma: I think we should, I would like to see us go to that model where offices become more of a collaboration space rather than a place you have to show up and work alone in a cubicle. What’s the point of that?

    Ashley: I agree.

    Sharma: Unless somebody needs it, right? That’s different if they don’t have space at home and the need a cubicle to work in—fine, put them in a WeWork next to where they live, right, close to where they live rather than have them commute to the other, you know, 45 minutes one way.

    I think that’s the model we should head towards.

    Chase: I agree.

    Sharma: And, you know, the tools to enable that are there, we’ve proved it. We’ve proved, during the lock down, during the pandemic that the tools are there, but I hope it goes that way. I hope it doesn’t go back to, “You have to show up in this cubicle” even if you are, you know, like the guy from Office Space protecting the stapler and never talking to anybody.

    Ashley: The butts in seats model, right? [Laughter]

    Chase: We’ve seen some large organizations [Cross talk] make those calls already and say you can be remote forever now, you know, things like that. So, I think that’ll become a bit more selective, but I still hope, when that pendulum does swing back, that the employee has a say, you know, and his voice is a little bit taken more seriously.

    Shimel: Or her voice.

    Davis: Or hers.

    Chase: Or hers—or hers, [Cross talk].

    Davis: Exactly, that’s where I’d like to chime—I’d like to chime in there, because Alan teed this up earlier and then, because you had two things, Alan, we followed thread number two.

    I wanna come back to thread number one, which is that this has affected women in the workforce, and it’s not just us technologists, but it’s a broad spectrum, and it’s probably even more so in other working arrangements. And so, I love what you’re saying there, Kurt, about it being a partnership between the corporation and the employee and determining what’s best for them. And then Sanjeev, you, I think, just teed up—is that the survival answer for WeWork is that part of that negotiation between the corporation and the employee, she or he, includes having the ability to move into a workplace that is close to your office but allows you that space that you need, for example, not to be on call for child care.

    Of course, the other thing I can’t help but say—and I’m very fortunate, I have one son, he’s 26, I’m not tying shoes or going to PTSA meetings anymore—

    Shimel: I hope not. [Laughter]

    Davis: – so, I wasn’t affected in that way. Yeah, [Laughter] I wasn’t affected in that way in the last year, but I was a working mother and I worked from home that whole time. And I just wanna remind everyone, men and women, that you’re right, women take on that burden, but it doesn’t have to be that way, fathers.

    Shimel: Amen.

    Chase: Mm-hmm.

    Cornelia Davis: So, please pitch in even more than you think, just because it’s been kind of the standard operating procedure. If nothing else, I hope the last year has maybe, in some cases, resulted in a, hey, a need-based way of rebalancing responsibilities. That is something that every single individual, male or female, can participate in kind of these societal expectations and challenging those.

    Ashley: I think something happens—

    Shimel: You know what? Oh, go ahead, Mitch, I’m sorry.

    Mitch Ashley: When things open up, when opportunity happens and things make that shift, it’s different when there’s opportunity there, but when things have shifted and made a shift, they don’t snap back to the old way automatically. It transforms sort of the landscape going forward, and there’s so many things about this—and you mentioned women in the workplace, we also have people of color—and we think about the emphasis of diversity that’s happened over the last year and a half, which is fantastic. And we see so much more bringing to the forefront of women in leadership positions, people of color being involved in security more, whatever it might be. You know, I don’t think that that changes.

    So, hopefully, those people who now are getting to participate in a bigger, broader way or have more opportunity to do that, (a) I don’t think this is gonna go away, (b) that’s gonna change things for us, right? You know, maybe, Cornelia—[Laughter] here, I’m speaking about what I don’t know about—but maybe more women in leadership positions make some of those, it’s assumed that the woman at home does the child care or whatever is part of our societal transformation, that it isn’t necessarily an assumption. Hopefully we can get past that and remove that barrier for people so there is more opportunity.

    Shimel: So, Mitch, on that front, though, here’s the deal. Number one, I think the move to diversity is not necessarily COVID related, I think it’s just an idea that its time had come, it has been a long time coming, number one.

    Ashley: I totally agree.

    Shimel: Number two, I think one of the positive things that happened is, it wasn’t just the woman stuck at home taking care of the kid. She was stuck at home taking care of the kid while the husband was trying to carve out a desk space in his bedroom somewhere to try to do a meeting or something, right?

    But what often happened, at least among my friends—look, my kids, also, Cornelia, they went away to college even though their college was online, just to get out of the house from their mother and father who wouldn’t let them breathe. But most—like, people I know whose kids were younger, the mother and father were home. They had to split up, delegate duties. You did the wash, I cook the meals, you clean the table, I took the kids here, you took the kids there or entertained them now because you had work to do, I had work to do.

    In a best case scenario, it became very much a shared responsibility. Of course, not every scenario or every instance has that best case outcome. There’s a lot of people [Cross talk], you know?

    Ashley: I think it’s been a journey to share. It may not be quite as, like, “Okay,” [Cross talk].

    Davis: Yeah, yeah.

    Shimel: Well, that goes, this is—

    Davis: I mean, you’ve painted a fairly ideal picture.

    Shimel: That is an ideal picture, you’re right.

    Davis: Yeah. You know, this conversation is making me wonder, and I don’t have these stats, but I wonder if anybody else has heard the stats—you’re right, absolutely, that this shift towards more underrepresented folks in leadership positions, women, people of color, and so on, that absolutely started before COVID.

    I wonder how COVID has affected that. Have the numbers accelerated, have they decelerated? I think—I suspect the latter, and I’m pretty much an optimist, but I’m also a bit of a realist, and I wonder whether the last year has slowed down progress when it comes to diversity at the leadership level. I don’t know. It’s just a gut feeling. I’d love to see some metrics on that.

    Sharma: I can tell you, Cornelia, in IT roles, it has always been very difficult to hire people from minorities, right, underrepresented minorities.

    Davis: Yeah, of course.

    Sharma: It always has been. I personally believe it has gotten worse, because if you look at especially leadership roles, senior roles—we’re not talking fresh college grads—most of those roles, no matter what anybody says, happen through referrals and connections, through your network.

    Davis: That’s right.

    Sharma: And that network stalled. That network stalled during the pandemic, right?

    Shimel: Yeah, networking, yeah.

    Sharma: Right? It is as big as it was then or grew slightly, right, that networking opportunities were gone.

    Davis: Yep.

    Sharma: No Meetups, no conferences, no lunches, no power breakfasts, no women in technology meet ups—nothing. The network stalled—you only knew the people you knew, right?

    Davis: Yep.

    Sharma: And I think that hurt, bad. I find when I’m trying to hire, when my peers are trying to hire, we are struggling more to have—see, you can’t hire when you don’t receive the résumés. When there are no résumés coming in, how do you hire, right? And I’m struggling, and if anybody has, if either one of you could—any one of you has any suggestions on how to fix that, I’m all in. Please, I’m all ears.

    Davis: I think—

    Chase: Yeah, I was gonna say, you pointed out an anti-pattern to what I was gonna say, Sanjeev. I was gonna say, at least with COVID and all the remote work, our talent pool has opened up worldwide, but you’re saying that hasn’t helped in that regard.

    It has for me with some of the roles I’m hiring. Now granted, they’re not Director, Senior Director, VP level roles yet. But for the other roles, having the world as my talent, you know, the talent pool versus the United States, that makes it [Cross talk].

    Sharma: Well, I look at it a bit differently. I look at it a bit differently, Kurt. You know, hiring—how do I, I wanna make sure I say this properly. Hiring an Indian in India is not hiring a minority.

    Chase: Yeah, true. Yeah, true.

    Sharma: Hiring an Egyptian in Egypt is not hiring a minority. Hiring a Turkish person in Turkey is not a minority, right?

    Shimel: Right.

    Sharma: They have to be a minority in where you’re hiring them, that’s the only way it works.

    Shimel: Agreed.

    Davis: Yeah, I think, [Cross talk] I wanted to comment on your remarks, Sanjeev. I think that you’re spot on. Because there were opportunities, and some of the techniques that we have used in corporations to source diversity candidates or underrepresented candidates, those things went away. So, being able to go to a historically black university or go have your recruiter show up at Women Who Code meet ups, those went away, and those aren’t the same.

    Sure, Women Who Code still had meet ups line, but it’s not the same as walking around during the social hour and saying—or, I’ve been at many meet ups where, before they start the program, they say, “Okay, who’s hiring?” And everybody stands up and then, “Who’s looking?” Everybody stands up. “Alright, you folks, talk.” That was a very organic thing that was not just so easy to say, “How do you do that in an online setting?”

    You’re right, it’s—I hadn’t even thought of that, but that whole network is the same now as it was a year ago is remarkable, especially when it comes to leadership.

    Sharma: Exactly. That’s why hiring from a historically black university, we can still do that today, because the recruiters still know the counselors there, they still know the placement office or whoever does—you know, those networks are still there. It’s just that the network hasn’t grown. The higher you go, right, the air gets, you know, rarer, right, and those jobs are fewer and you are not screening 100 résumés to do that. You’re relying on the network more than often, no matter what anybody else says, right?

    And that network stalled. I mean, who have we met at a conference who we didn’t know before? Now, when I go to a meet up and I see somebody I know—

    Davis: Yeah, but I think what you’re pointing out—

    Sanjeev Sharma: – I am IM-ing that person, not some stranger who I’ve never met, right? Unless there’s something really, some reason to do that. Then—no, no, it is the opposite, it has really hurt. I think we need to fix this.

    Davis: Yeah.

    Sharma: We need to put this [Cross talk] the moment we come back.

    Davis: Yeah, but I wanna suggest that—yeah, but I wanna challenge that assumption, which is that I hire leadership from within my network. Maybe that right there is the thing that we need to work on.

    Sharma: Well, I’m with you. We need to work on it. What I’m saying is—that’s what I was saying. I was saying that what we tend to go, tend to—we tend to grow our network to find leadership role people, right? People in leadership.

    Davis: Yeah.

    Sharma: When you can’t grow your network, you’re reliant on what’s already in your network, right? I mean, otherwise, you’re scouring LinkedIn or some other website or pinging people in your network asking for referrals.

    Davis: Yeah.

    Sharma: But that network stalled. That network didn’t grow. I can’t point to 50 people I met in the last year who were cool and interesting who I did not know before who were underrepresented minorities have I would have met, had I gone to Reinvent or IBM Think or, you know, DevOps World or KubeCon or whatever. All the people I would have met, I didn’t meet them.

    Shimel: So, that’s a whole other thing. Virtual events, right?

    Ashley: Mm-hmm.

    Shimel: We’ve all spent significant portions of our lives at conferences. Cornelia, that’s where I usually see you is at conferences—Sanjeev, as well. Virtual events are cool. We put on one a month here at MediaOps. Gene Kim does his DevOps Enterprise Summit virtually, people even paid money to attend it.

    And all of the virtual events, they try to do a social thing to it. It’s just not very good, frankly. It just—it’s just not the same as being in the hallway or grabbing a drink at the bar or a soda or whatever, you don’t have to be drinking. But, you know, just not—it’s not that, someone said it before, face to face, person to person. I think it was Cornelia, you recently had an in person. It’s not the same, it’s not the same.

    I mean, so, different than the three of you, Mitchell and I have had a chance to meet hundreds of new people this year. I do three to four to five of these interviews a day. My day starts with talking to people in Asia or Israel and goes to Europe and through the Americas, all the way to the West Coast. And what I’ve found is that I’ve become a resource for people like you, Sanjeev, who say, “Hey, I’m looking for someone to head up cloud or DevOps or testing” or what have you. And I go through, who have I interviewed recently?

    But that’s not the way it’s supposed to be. And the question is—and we’re getting near on time—I wanna bring it back to DevOps and software, right? And, you know, what—

    Chase: I think you touched upon it from the beginning, Alan, it’s the Internet. You know, the fact that our technology infrastructure was able to shoulder the burden, that was pretty incredible to me, too. You know, I expected Zoom to go out for weeks, if you will. But I think it demonstrated that the technology infrastructure we have is pretty solid. You know, it allowed us to scale up pretty quickly, pretty massively and, you know, there were outages here and there, but I would’ve expected a lot more.

    Shimel: Minimal—minimal. Even counting all the DDoS attacks and the ransomware and all of that nonsense, it was still minimal.

    So, we had that infrastructure, but we also had this incredible capability to accelerate, to automate that DevOps kind of has been teaching us for seven, eight, nine years or more now, right? And that really helped. Curbside pickup and the—it’s not just curbside pickup, it’s the back end, obviously, right, that allows you to pull into that parking space and hit the button and say, “I’m here, and this is the car I’m in,” right? That kinda stuff, how many companies and jobs were saved by that kind of capability.

    Chase: The other thing for me internally is, I think it also opened up the ability to question everything, just because—at all levels, you know? Whether you’re designing a new feature, adding something to a product, designing a new process—is that the right thing, just because we’ve done it like that? I mean, really question it, because I think it, I mentioned this before. I think the opportunities ________ are endless now, really.

    We haven’t even started to take advantage of the things we’ve learned. I believe we’re starting to now, as Sanjeev mentioned, the pendulum coming back. Part of that is some massive learnings that we’ve also had forced upon us, if you will. But I think we’re gonna come through it even stronger and better, for sure.

    Davis: Yeah.

    Sharma: I think the—

    Davis: You know, I wanna, I’d love to chime in on—

    Shimel: Go ahead, Cornelia.

    Davis: – yeah, I’d love to chime in on that scale. You used the word scale and these systems were able to scale and handle just a tremendous surge in traffic.

    Shimel: Oh, yeah.

    Davis: And when you said that, it took me immediately back to a DevOps Enterprise Summit where Nicole Forsgren and Jez Humble—and those of you who don’t know them, you should know them.

    Chase: Yeah, we know them.

    Davis: State of the DevOps Report, State of the DevOps Report, the book Accelerate. I remember this moment where they were on stage, and Jez Humble, in his very humble way, hand in his pockets, says, “Turns out, architecture matters.”

    Shimel: Yeah. Right.

    Davis: And so, it’s having these systems that are designed to scale, and we find so many enterprises that have said, “Oh, well, you know what? Google scale, Amazon scale, that’s not a problem that I need to face.” Well, surprise—

    Chase: Yeah, it is.

    Shimel: It is.

    Davis: – maybe it is. And so, architecture matters, and so I can’t help, as a software architect, coming back to that and saying, “Yep, there ya go.” [Laughter]

    Shimel: Yep, [Cross talk].

    Sharma: And I think we’ve seen companies who were—there’s two ways to look at it. One way is to look at it from a scale perspective. The other way is to look at it from a resilience and reliability perspective.

    Davis: Right, yeah.

    Sharma: Right? Which are two aspects of the same thing. It’s all architecture. And I think companies realize very early that reliability and resilience are critical—resilience to be able to make changes rapidly, right? Today, I have, I don’t have curbside pickup, tomorrow I have. Today, I had 10 people doing this, tomorrow I’m gonna have 200 people doing this.

    Ashley: Right.

    Sharma: Today, I had a teller sitting in front of her terminal, so the user interface didn’t need to be that cool. You know, the things could hang and the teller could, you know, make sense, make small talk while the system is catching up. Well, nobody’s accepting that on the mobile app when they’re directly dealing with the website or the mobile.

    So, I think that whole shift on resilience and reliability are real, are important, and all that goes back to your point, Cornelia, to architecture. That was front and center to people, and I think [Cross talk]—

    Chase: Yeah. And I think along with that, Sanjeev, is security. I think security, this really exposed—we have to do more in security. We have to do more, you know?

    Ashley: We have to rethink security.

    Chase: I think that’s one of the chief learnings.

    Shimel: No doubt about that. Guys, I hate to do this to you, but I need to pull the plug on this. We already have people in my waiting room for our next interview.

    What a great panel this is. We’re gonna have to rerun this again and go to a part two, because there’s things I wanna talk to about this as well. I spoke to a guy today who started a new, he calls it the mobile cloud for gaming, it’s called Now.gg. Because their research is that our kids, you know, these digital natives, if they don’t get a response in half a second, they’re gone, they’re onto the next thing. And so, what does that mean for your banking apps? What does it mean for we’re doing?

    But we need to end this. Sanjeev, Cornelia, Kurt—man, thank you, guys, so much. Thank you, all, so much for making this an amazing panel. Thank all of our viewers out here for watching this; we hope you enjoyed it. Mitchell, I’m gonna let you take it home.

    Ashley: Well, I think—what a fascinating group and wonderful things to say. I think the biggest learning for me—and I really appreciate Cornelia and Sanjeev talking about the lost opportunity we had through networking to help people come together and expand their networks. So, let’s invest in that going forward. We need to rebuild those and make that happen. So, I appreciate—I really wanna thank you for helping me understand that better.

    Shimel: Absolutely. Many thanks to Tricentis for sponsoring this episode of DevOps Unbound. We’ll be back in two weeks with a fresh episode, a new panel, a new topic, but hopefully it’s just as interesting a conversation.

    This is Alan Shimel for MediaOps. Until next time, be safe and be well.

    [End of Audio]

  • Accelerate Your SDLC With DevSecOps

    Accelerate Your SDLC With DevSecOps

    DevOps has been the answer to rising software development complexity, but the granularity and multiplicity of actors, technologies and environments brings added security requirements. Moving to DevSecOps will not only help with these requirements but also accelerate the software development life cycle (SDLC).

    As development projects mature, more developers get involved, the code base grows and architecture becomes more complex; consequently, the SDLC slows down. This is why Agile, microservices and DevOps have emerged—to solve this specific problem by separating big teams into smaller ones and monoliths into more nimble components.

    But this granularity and multiplicity of teams, work environment, technologies, services and repositories makes integrating security even more complex. In fact, developers now face multiple SDLCs and often, the gains achieved in velocity can be nullified by security issues. You want a process that works, and preferably, a process that works fast.

    This is what DevSecOps attempts to solve; adding security into DevOps actually accelerates the SDLC. Here’s why and how.

    DevSecOps During the Planning Phase

    The planning phase is key as it answers essential questions at the time when architectural decisions are made. Some of these decisions are relative to access control, network infrastructure and data security. For each, adding automation—and therefore, security—allows fast replication.

    For access control, you can leverage infrastructure-as-code (IaC) tools (Terraform, for example) to easily define different groups, roles and permissions with code. By adding various plugins, you can even use your IaC tool to manage users on other platforms, as in GitHub. When you have all the groups, roles and permissions defined as code, you are only one commit away from access control updates.

    If you need to onboard a new team member not only to, say, a specific AWS group but also to a GitHub group, instead of doing it manually in two places, you can do it “as-code” to both with minimal changes.

    The complexity of organizations and the need for better security implies the need for more role-based access controls, but automation tools exist, and they are also less error-prone.

    When it comes to network infrastructure, you can also use IaC, but you will also need to add a security layer on top of it to mitigate any errors in the code. As an example, you can use tfsec and terrascan on Terraform. This will scan your code statically and, based on predefined rules, generate alerts and give you advice on improving your security. If you prefer CloudFormation, use cfnlint, which even allows you to define your own security rules.

    When you have your infrastructure ready, the next big thing to think about is your data. You need to put data encryption in place to make sure data is securely stored at rest. You also need to add transport layer security (TLS) for the databases to secure the traffic in transit. Besides using static code analysis tools and ready-to-use services, you can even automate your own pipeline. This is very useful when you have multiple agile teams.

    Let’s take S3 buckets as an example. You could build a generic solution where the S3 event triggers a serverless function that checks the bucket’s permission. If a policy is violated, it can be fixed right away and the owner notified automatically.

    Moving to Development

    During the development phase, you need to address three major security areas: Code repository security, continuous integration (CI) security and container image security.

    Code repository security needs to address questions around the repository access control, considering the principle of least privilege but also checking that no repository is made public by accident or that they do not contain sensitive elements, such as secrets.
    With a multi-team, agile and microservices setup, you need automation to skip time-consuming and error-prone tasks but also to avoid slowing your SDLC to a crawl. We already mentioned git user management automation, but there are also a number of tools for static code analysis and secrets detection. You can even include this detection in your CI pipeline and integrate it with your alerting workflow to eliminate the risk from the origin.

    CI security is often overlooked, but this is a very important element; if your CI is not set up correctly it can generate data leaks. Access to your CI needs to be controlled to give the proper permissions and access rights. Doing this manually will definitely impact your SDLC velocity so, again, there’s a need to automate. You can integrate your CI with your Git or company single sign-on (SSO) solution for authentication. For authorization, you may rely on the groups’ information provided by those SSO services.

    Secrets are also critical for CI. Modern CI pipelines allow you to store secrets at a project level. Once configured, you can use it directly in the build without putting the sensitive data in clear text format. Even if you try to print the variable containing sensitive data, it will not show up. For instance, to use secrets directly from a Jenkins pipeline, you can store your secrets in a Kubernetes cluster and use Kubernetes Credentials Provider or HashiCorp Vault Plugin.

    Now, let’s talk about containers. While containers have simplified the deployment, scaling and failover capabilities within the SDLC, they also introduce some challenges. If the container image has some known vulnerabilities, your containers could be exploited, and the integrity of the whole machine—or even the entire system—can be compromised. Automation is, again, the go-to solution to ensure the images you build don’t contain vulnerabilities. Some CLI-based tools like Trivy can be easily integrated into your CI pipelines.

    Automation will significantly reduce your operational overhead. No more managing machines (physical or virtual), no more configuration management, no more patching. If everything is automated, that means less toil—and that means all means your SDLC is not only more secure but also faster.

    Integration and Deployment

    Kubernetes (container orchestration) is the current solution to streamline integration and deployment in our agile world. But Kubernetes is a complex system and comes with its own security challenges, of which the most important is secrets.

    The worst thing you could do is define secrets in YAML files and store them in Git repos. You could use Kubernetes’ secrets as the single source of truth, but what about secrets created by people who don’t need access to Kubernetes? This is where a secrets manager is a good choice: It acts as a single source of truth to store your sensitive data. You will get an automated process that eliminates the toil of manual labor but also guarantees security and speed.

    DevSecOps for Incident Response

    Incident response playbooks are a crucial component of DevSecOps. Playbooks are a set of generalized and summarized processes that provide a consistent way of handling issues for quicker response and resolution. Learning from every incident is also part of the playbook, whether it’s a security issue or a new vulnerability.

    The content can include everything from runbooks and checklists to templates, training exercises, security attack scenarios and simulation drills. The goal is simple: A set of policies, processes and practices for quickly responding to and resolving unplanned outages, thus helping teams fix online issues more quickly to reduce the size of the blast radius.

    We have only scratched the surface of security automation capabilities and their potential impact on the SDLC. But it’s clear that adding (automated) security into DevOps has a positive impact on the overall velocity of the SDLC and, of course, on its security posture.

  • EP 13: Observability and Performance Testing

    EP 13: Observability and Performance Testing

    In this episode of DevOps Unbound, Alan Shimel is joined by Christine Yen of Honeycomb, Paul Bruce of Tricentis and Mitch Ashley from ASG/MediaOps to discuss how to effectively test the performance of your applications and how bringing observability into testing environments helps DevOps teams identify and resolve issues early in the SDLC. The video is below, followed by a transcript of the conversation.


    Alan Shimel: Hey, everyone. I’m Alan Shimel, CEO of MediaOps, Editor-in-chief of DevOps.com, Security Boulevard, Container Journal, and you’re watching DevOps Unbound. DevOps Unbound is a biweekly video series where we have some of the leading lights in our community talk about topics of interest around DevOps. We’re lucky enough to be sponsored, DevOps Unbound, by our friends at Tricentis, so many thanks to Tricentis for their sponsorships. But this is a media ops event.

    Let me introduce you to today’s panel and then we’re going to jump into our topic. Let me first introduce the guy with all the robots in his background there: Paul Bruce, with a 404 shirt. Paul, welcome. Why don’t you introduce yourself to our audience?

    Paul Bruce: Sure. Thanks, Alan. So, my name is Paul Bruce, as you said. I’m on the nerdy side. I’m a performance and reliability geek. That’s just a place of complexity that I love to – it’s just what – it’s just my bag; it’s just what I like to do. On the other side I’m a community organizer. I work with DevOpsDays Boston and the Boston DevOps Meetup. I am hosting an event along with Liz Fong-Jones this year called o11yfest around observability, a vendor-neutral and also – community-focused but also the open telemetry project-focused two-day event. It’s half days so that we don’t burn people out. And I work with the Tricentis team since the NeoLoad acquisition – again, performance reliability. I was with Neotys and NeoLoad for years now. I really loved that team. And I love my new one, the broader one at Tricentis. So, that’s me.

    Shimel: Very cool. Thanks, Paul. And then, joining Paul today is – we’re very lucky to have her – someone I’ve had the pleasure of interviewing more than several times now over this past year of Covid but hopefully soon to see in person, my friend Christine Yen. Christine is CEO of Honeycomb. Christine, welcome.

    Christine Yen: Hello. It’s wonderful to be here. Alan, you shared my title, but my background is as a product engineer. Honeycomb, for anyone who isn’t familiar, is a tool who – a tool for observability. And I love working on it and I love talking about this topic because even though I tend more towards the software engineering side I have done my fair share of breaking production, and so this topic is near and dear to my heart for software engineers to do that less and find out what their code really did more quickly.

    Shimel: Very cool. Thanks, Christine. It’s great to have you here. And then last but not least is my cohost of DevOps Unbound. We’ve worked together for probably longer than either of us want to admit, but it’s hard to believe we’re both only 25. But CTO here at MediaOps, CEO of the Accelerated Strategies Group, Mitch Ashley. Hey, Mitch. Welcome.

    Mitch Ashley: Thank you, Alan. But the best 25 – this year again. Twenty-five again, right?

    Shimel: Yeah, 25 again again.

    Ashley: Good to be here.

    Shimel: Anyway – yep. Thanks, Mitch. So, today’s show, really, we’re going to explore the intersection – or maybe it’s a border between performance, performance testing, and observability. What – how do they play with each other nicely? What is the interaction? What is the relationship? And for those in our audience, you may be looking at it and saying, “Well, observability is kind of almost post-deployment. Hopefully we’re doing some performance testing pre-deployment and then post-deployment.” But how – I don’t know if I see a nexus right away but there’s – in my mind anyway there’s an obvious nexus. There’s an obvious connection.

    So, let’s talk about it at a high level. How is observability and performance testing connected? And how can they – how can we get a one plus one equals five or four out of performance testing and observability? Christine, if it’s okay, I’m going to ask you to kick off with that and kind of lay out the framework, the ground rules, the – and we’ll all jump from there.

    Yen: Well, laying out the framework and ground rules is a little bit of a big ask for early in the morning, but I’ll do what I can.

    Shimel: Okay. I’m sure you’ll do great.

    Yen: I’m wearing the wrong shirt for this. I often – I think I’ve come on one of these interviews with my “test in production” shirt, but it’s a phrase that too many folks – it can be interpreted in many ways. What does testing in production mean? There is a version of it that means, well, I’m not going to run tests beforehand; I’m just going to see what breaks in production and try to fix it after it’s impacted users. Obviously, that’s not what any of us mean. And there’s a version of it that means, hey, look, when you write preproduction tests, when you write any sort of tests, what you’re trying to do is you’re trying to compare actuals versus expected. You’re trying to form a hypothesis, observe reality, and then think about that difference. Isn’t that really just a different phrasing of what we’re trying to do when we’re looking at production, where we’re using our logging or monitoring or observability tools to see what actually happened when our code is in production?

    And so, I love – I think it’s a huge intersection, a huge overlap between things like performance testing and observability because we are all using the same skill set, we’re all using the same brain sequence, but there’s – people seem to think that observability is – can be more exciting because it’s incidents and downtime and alarms are going off. I don’t think it is. I think it’s all the same. It’s just at different points in the development life cycle. It’s on different timelines. It’s with a different level of urgency. But it’s the same thing we’re all just trying to do to come up with hypotheses, validate them, and learn.

    Ashley: I really like, Christine, the way you kind of intersected them together because the environment that we’re doing all of this has changed substantially. It wasn’t that long ago where it was kind of a static flow of writing codes, we’d test it, we’d CI/CD, we’d test it, we’d deploy it into production. And DevOps helped speed that up with automation and tools, and of course tools of automation for testing. But now the software stack is fluid. The infrastructure is fluid. The code is fluid because we may have introduced three new changes to containers, for example, in a cloud-native application since we’ve really had an opportunity to go and debug or determine what the source of that was. We also have dynamic applications that start up and go away, and those things may be long gone by the time we actually look at them. So, I think this key to observability is also giving you insight into an environment that may not exist at the time that happened, and so you need that information to be able to understand “This is really something I need to fix, address” – a bug, a feature, whatever it might be.

    Bruce: Yeah, and I think there’s a lot of intersection between putting pressure on systems, whether that’s through actual users and risking revenues and all sorts of things or doing prerelease type testing or testing in production. There’s a – performance is about how does this system perform to expectations? And there are a number of different people with a number of different expectations. There’s the technical expectation, maybe articulated – hopefully articulated in something as legitimate as an SLO or an – and then measuring them with SLIs and stuff. But there’s also user expectation. There’s the CEO expectation. There’s B2B. If you’re in some kind of regulated industry and that SLA is actually part of a legal requirement that becomes really important. Like, we saw that unemployment sites – I don’t mean to pick on that kind of work, but that was a mess. Same thing with various different – trying to get the vaccines scheduled and stuff. And it’s like why are we still suffering from these systems that are out there and they’re good enough maybe for the day to day but have never been exercised, have never been – the concept of that being – that scaling has never really come about for that system.

    Okay, well, what about systems that do by default have scalability as a first class citizen? Going back to some of the stuff that Christine said – and actually, Christine, I love – your cofounder Charity has a phrase and I’m going to butcher it, but “It’s never not a good idea to have your glasses on when you go driving.” That idea that if you can’t see what’s going on that’s a big problem.

    So, a lot of people traditionally would have used something like “Let’s just throw all our APM tools at production.” And that’s great. But going back to that original thing where I was saying pressure on systems really shows us how well we’re doing engineering, the impact of that pressure matters too. So, as a performance engineer, performance and reliability engineer, I’m constantly not just trying to – as my French team would say – make load on a system, put load, put pressure on a system, but I also care deeply about being able to measure the impact of that.

    I’ll pause there because we probably some other questions. But there’s more to go into about that. It’s not an either-or. And it’s not about just production or preproduction. It’s about what’s not a good idea to have visibility. Isn’t it a good idea to have visibility on a thing, whether it’s putting pressure before release and having visibility or doing that in production? We’ve got a lot of customers who do testing – who do load testing in production on production systems. This is not an impossible thing, folks, you know?

    Shimel: So, let me try to put this in some kind of context that we can jump on. So, here’s what I say Christine saying, which is – and maybe I’m taking it up a couple notches, getting out of the SLO woods – at the end of the day what do we all want? We all want our apps, our infrastructure to run better. We want to have good predictability, visibility into how things are performing. And whether that is an aspect of performance testing, or you want to call it performance monitoring, or do you want to call it observability, at the end of the day the aim is the same, which is let’s understand how our stuff is running and make sure it’s running the way we think it should be running. So, at a very high level it’s almost equating performance or observability – I mean, it’s all with the same goal, which is let’s make sure our stuff’s running good, as the best we can.

    In my mind – and Christine, I’ll defer to you – certainly over the last year, year and a half, maybe two even, observability has taken on – as it’s become more hyped and a real word, a real thing out there, has taken on almost an even bigger mission than that, where it just doesn’t equate with – the goal may be “Hey, let’s make sure things are running the best we can make them run and how we expect them to run,” but there – observability has a whole uber mission of things that people want to do with it or use it for. Paul, you mentioned APM. Kind of observability subsumed APM, AI ops, all of these things. But yet, wait, there’s more. Observability does more than that. It’s become this whole big thing out there. And maybe it – maybe that’s right, maybe that’s wrong. I’m not here to judge.

    But that, I think, is really the crux of this. Yeah, we all have the same goals. Is observability – part of what observability does helping the performance engineer? Absolutely. Is there more to observability? I think so. Christine, you’re the observability expert. I’m going to ask you.

    Yen: You know when you say a word enough times and it starts to lose its meaning and you’re like “This is starting to sound funny”?

    Shimel: Yeah.

    Yen: We – I think you’re – there’s – we are definitely approaching that with observability a little bit. And whenever I get to that point I like to pause and remind folks “Let’s look at the – let’s take a deep breath and look at the English word we are using to describe this. It’s not a bucket full of buzzwords. It’s not a bucket full of types of data. It is an ability to see. And it’s the ability to see into our production systems. What do you want to do with that? What can you do with that if you have an improved ability to see?”

    Okay, well, now we have the laundry list of all the things that we can do once we have the ability to see into these systems that, as Mitchell mentioned, are so different than they were five or ten years ago.

    Shimel: Oh, yeah.

    Yen: And that to me is – that zooming out behavior is what re-centers me when it feels like we’re trying to do all the things. And you’re like “Well, it kind of makes sense. I want to have my glasses on when I’m driving.”

    Shimel: Yeah. Paul?

    Bruce: Christine, you’re definitely right about a buzzword merry-go-round. I have experienced that with “DevOps.” I have experienced that with – oh, man, I can’t believe I’m saying it again but I’ve got to because people will know – “shift left.” These terms that just get all the things. And we go at these things, these different terms, we latch onto them, we try to make it our own. Oh, man, vendors love to do that. We’ll take a word and we’ll make it ours and we’ll try to align it to our product strategy. And at the end of the day it’s like there’s 150,000 different versions of this thing, which as a performance guy I’m kind of like “Well, it’s not bad to have a big sample set,” but the sample set of what’s going on in the delivery chain from good idea to working software that’s making you money is not just in production.

    Let’s take an example of Nike, for instance. This is a known thing that they ship the watch, the watch that you open up on Christmas Day, and you go to connect to the internet and because the servers were swamped you don’t have a good Christmas experience. That’s not the only – I’m just picking on… But that kind of situation is a situation where there’s a lot of stuff you can do to prevent obvious faults from getting to the point where that’s the bad experience. And you also need visibility on the day where your production is having problems. And it’s not just the day; it’s every day. Every day you have a certain un-zero amount of events and issues in your production systems. How do you address those things? Well, there are plenty of situations where if you’re only thinking about observability as it only applies to production – which, by the way, production is where – what makes you money. If code is not sitting in production doing something useful for people you are not making money off of it necessarily. And production isn’t just out for consumers. It could be all the different constituents in your larger organization. So, even private systems are production. And so, if something is not out there then it’s not making money.

    So, is that the only place where we should pay attention, where we should have good visibility on logs, traces, and metrics, on understanding how the business is impacted, long and complicated queues and delays in these systems? No. I mean, yes, in our edge and final production systems, yes, of course we will want that because we don’t want to be in a bad situation not having the right visibility into problems when they’re happening in production. But how do you think problems come about in production? Well, there’s the emergent ones that we can’t possibly know about. Ooh, there’s just so much time in the day. But then there’s a whole bunch of other stuff. Every line of code is not just an asset; it’s a liability. So, as you’re constantly shipping these things out there’s plenty of things you can do to prevent obvious – and I mean dumb and stupid and obvious things from getting out there, causing toil, waste, risk, and loss of brand, revenue, and all that stuff.

    So, I think the observability for me is not just in production. It’s really useful to have classic monitoring in preproduction environments except for that it’s super expensive. Oops. And then, observability, pieces of observability, which Christine would probably be better to go into, all those things that you can do and what you get out of that, and now we can have use cases, that also applies to preproduction situations. That’s why I’m so excited about that open telemetry project and the community over there, this notion of being able to emit information from your systems, to either build it in directly from your systems or put it on sort of after the fact, sort of replacing some of the obvious early agent type stuff that monitoring used to be the only thing that could do. That open telemetry stuff now makes it a standard that we can all benefit from no matter which environment. How about all environments? That would be super nice. And to get tracing and traceability from – all the way from the Web app that somebody is touching all the way down to the database and the 30 different APIs that it touches.

    That’s really useful, not only to firefight in production but to see “Am I risking dependencies? Am I go wildly off my architecture diagrams?” You know what I mean? Those things slide. Your conceived architecture diagram is never what’s actually running in production. So, to actually be able to have visibility on that is really important.

    Ashley: Well, you know, Paul, the lines between production and, let’s say, tests are blurred, to use a phrase – are really kind of blurred, and oftentimes when we adopt whatever new technologies or approaches we’ll attempt to do what we used to do just using a new technology to do it. So, we’ll test the way we used to. And just what sort of clicked with me with cloud early on was how Netflix was doing their rolling upgrades and being able to flip back and forth. The same is really true for testing and performance testing because your availability to resources generally is not an issue, or not the issue it would be normally in an environment where you’re not in the cloud or at least partially in the cloud. So, there’s a lot of things you can do not just in your current testing environment but to set a pretty elaborate – with resources to do different load tests, performance test scenarios, in addition to what you experience in production.

    And I think one of the points that you made is salient, is if you’re paying attention to this you now understand your systems, your applications, your environment enough to identify “Well, we may be able to handle the number of unemployment claims we’re getting today but I know when we reach the next peak these are the three things it’s going to impact. I know those are the things we have to go adjust or fix or whatever it might be.” Because you’ve already instrumented it well enough and you have the information through observability to be able to do that. So, I think that’s a different mindset of how we think about performance testing.

    Shimel: Yeah. So, I tell you, I think one of the big breakthroughs of DevOps has been to create our “testing environments” to be more lifelike, to be more real lifelike. I mean, because prior to DevOps, the world I grew up in, the classic thing is the developer developed, gave it to the ops guy, the ops guy puts it up and says, “Wait a second, this stuff don’t run.” And he says, “Hey, developer, this doesn’t run.” And the developer says, “I don’t know, dude. It ran on my machine.” And so, there was that disconnect between what the developer wrote and ran it on or they tested it on versus the real life production environment. And one of the great things about cloud and virtualization and all of this stuff is that we can theoretically really duplicate our production environments and test environments and we can increase loads and we can do all those things theoretically so that there’s no or less surprises when we go live in production. And that – look, that’s – thank you, DevOps. That’s part of what this whole DevOps thing, I think, was.

    But I don’t know, is – Christine, is that really – does that dog hunt or is that just DevOps urban myth? You know?

    Yen: I think you’re on – right on the ball. I mean, when Charity and I started Honeycomb she came right – that story you told, I was that dev; she was that ops. I did the whole “It works on my machine; I don’t know what you’re talking about.” And when we started Honeycomb we thought honestly we were going to be talking to more of the Charities of the world. We were like “Oh, this is a tool for ops people. They’re the ones who understand the pain.” And as Honeycomb grew and as observability grew it became more and more obvious: “No, this is for the Christines of the world too.” This is for the people who need to understand what happens beyond that testing environment. This is – the boundaries are blurring or – I like to think of it as dev and production are coming closer together because there are more and more things we just can’t test in a test environment. As good as we make the test environment, we just can’t.

    Shimel: I totally agree.

    Yen: And there are so many things that can be learned – the same – by thinking of production as part of the development environment. With feature flags we can start to take code that is really not quite ready for production but test it out in a safe way and learn from it. And that’s so cool. It’s – there’s so much for developers to be able to learn when everyone kind of gets over this mindset of “Well, there’s a wall between development and production.” There isn’t. There shouldn’t be between people or the software. And that’s where all the exciting parts live.

    Shimel: I don’t disagree. I don’t disagree.

    Bruce: So, Alan, one thing that you said – you painted sort of the stage so that we could have part of this conversation. I’m not a big fan of setting up huge staging environments. In classic world it was like, okay, well, here’s production and it uses 36 Oracle back-ends and – if we were going to run a proper performance test of course we needed 36 on our side. And before the cloud that was incredibly expensive and you’d fax your IT person and they’d get back six months later with the right hardware. And I think there’s a myth that, well, yeah, you need to be realistic at some point, especially when you’re putting pressure on a system, to answer the final question, which is – what? – is it ready enough for me to be – what? – confident enough that this thing is going to transition like we talk about in standards, the transition process, that that’s actually going to go smoothly? And not in a waterfall way, just in a – to get away from this notion of “It worked on my machine” and now the ops person is putting out fires and doesn’t know how to operate the thing.

    But I’m not a big fan on spending a ton of money on this staging system which ultimately even if – even if at a very root level it’s exactly the same as the production system there’s always that jerk in the corner going “Yeah, but it’s not production.” And it’s like “Okay, you have a point but you don’t know what goes on.” And the point is I think almost like a – I’m going to do my idiot thing and pull in a mathematical and then probably get it wrong, a mathematical concept of the limit. You remember limits? And the idea is we need to be able to express are we talking about the very ends of things? No, it’s a continuum.

    So, there’s a lot of companies that I work with that actually do have requirements, that they go through a particular amount of testing and particular things before they can transition this to production. They don’t have the luxury of treating production like a dev system. There is a ton of people in the world, and it’s not their dysfunction – that’s not a dysfunction, just because the unicorns can fart rainbows and sneeze glitter and launch whatever they want. I see that happening in Boston all the time in some of the startups, and they do actually put themselves at risk. And even when you don’t do that, when you have an extreme amount of maturity and you’re working with relatively complicated technologies like Kafka things can go wrong pretty quickly. And the question is do you have the people and the process and the technology and the knowledge and the experience and the expertise to handle those when those things do come up in real time?

    How do you get there? How do you get to people who know how to use your monitoring and observability tools really effectively? How do you know what those systems, how close to your perceived architecture versus your actual in production, how do you know how much delta there is there? How often do you exercise the process of disaster recovery is one of those other classic questions you might ask yourself.

    And it gets back to who would be involved when there is a firefight or a last-minute thing like what we’ve done with some of the companies that I worked with very closely through the NeoLoad side of things, is when the education system, when colleges shut down and they finally said, “We are shutting our doors to the people that are paying us money,” that was a scary and real and significant flag for the rest of our US education system to go “Holy crap. We’re going – we have to provide virtual not as a stopgap for the past few months but this is going to be a serious reality for us for the next year.”

    And so, a lot of the vendors that help the education system have the right platforms in place. They go “Holy crap. We really need to test for 10X the size that we’ve ever tested before.” So, they’re testing in production on nights and weekends in various different places and doing it at a smaller pace. But who do they have on the call? Not just the Ghostbusters, but the devs, the ops. There’s people from infrastructure, the DBA teams. They have 20-plus people white-knuckled on the call, like [makes quivering sound] – white-knuckled on the call, and that’s a lot of money. And by the way, you’re asking them to do from 10:00 PM to 2:00 AM to 3:00 AM work. And so, they’re not going to be available for all those fancy meetings, architecture meetings that they should be stakeholders at.

    So, when you get to the point where you’re doing those massive things sometimes it’s necessary to go massive. But the vast majority of the exercises, you go to the gym – not so much me, but you go to the gym to exercise. You go and you get on your bike and that’s an exercise. You don’t expect to run a race without exercising first, without knowing that path a little bit before you just run a 5K race. So, why would you expect to do that with your systems and your teams?

    And that’s where some of the testing, the lower order performance testing comes into play. It’s systematizing the stuff, making a process that can be executed and re-executed no matter which environment it’s pointing to. And the telemetry that you’re getting out of it aligns in each of those environments. If all of a sudden we have really great telemetry in a pre-prod environment but we don’t have it in prod that would be a big problem. Why was it put in here and it’s not represented in production? What if we need that? Or vice-versa: We’re only doing things in production, and so now there’s only – there’s stuff that’s only in production that has no representation of how it would show up in lower environments.

    So, keeping those things in synchronous but also keeping the process and the exercised skills in place is why this isn’t just a big environment at the end kind of a situation.

    Shimel: Again, I think “Thank you, DevOps” where we have been able to say, okay, not only do we need those or can we use those testing dev environments, but as Christine said, with things like feature flags and some of the other technologies, processes that we use, it is possible to continue that – the feedback loops and iterations in real time while using the – while in production. And that again is one of the things that allows us to continually update, continually iterate, continually – and feedback loops was kind of an original concept as part of this DevOps thing. We’re going to have those feedback loops and we’re going to iterate and reiterate.

    But where we’ve gone with observability with that and with performance testing and these things with that have really just opened the floodgates in how we do these things now. I mean, just think about how – when I first started DevOps.com eight years ago, I mean, there were the unicorns who were updating multiple times a day. But for many people in the world, for many organizations in the world, look, moving from once a year to twice a year, twice a year to quarterly, quarterly to monthly was huge. It was huge. It’s not so huge anymore. It’s common for people to be updating their code daily or more than once a day now.

    I saw – I did an interview this week, a recent survey of developers who they claim that they have sped up their deployments by over 100 percent in the last year and a half. That was – something like 70 percent of developers said that. Think about it. I mean, that’s – a billion here, a billion there, you’re talking real money. Seventy percent of developers say they’re going 100 percent faster. Wow. Wow. What a golden great time to be living. And it’s because of things like observability, DevOps, our better performance testing. Anyway.

    Guys, we’re coming up on our time limit here. I wanted to kind of – let’s wrap it up. Let’s – what advice – for our folks listening in, watching in here, what can we give them? What can we tell them about this nexus of observability and performance that will make their life better? Paul, I’m going to – if you don’t mind, I’m going to put you on the hot seat and ask you to go first.

    Bruce: Sure. Well, there’s a couple things I’ve been working on for a while and then there’s a couple things that I just want to give a shout out to. I’ll start with – Christine doesn’t get to do the pitch thing but I do. Honeycomb is awesome. You see that thing in play and it’s awesome because the team behind it is awesome. You know what I mean? It’s kind of the Conway’s law situation where – the version of it I hear most is the systems are a result of the teams that build them. So, definitely check that out.

    Same thing with some of the other tools around there. But don’t get too bought up into the whole observability – don’t just Google “observability” and look at the first one because most people are paying through the nose for SEO placement there. Really actually look at what’s available, and then also dig into the team, the blog, the spirit behind that thing.

    The second thing I’d suggest is we just released – I was one of the members of a working group for a standard on DevOps principles and practices that applies to highly regulated industries. It’s IEEE 2675-2021, which we’re hoping to get adopted in ISO so it’s global as well. And what it does is really align what is – how are each of the important processes that can be applied continuously through many different life cycles as they’re going along? You know, that DevOps eternity symbol means we’re all going to be stuck in hell forever, that thing is happening, all the things are happening all the time but there are precise things that need to go on in highly regulated industries, and even not. So, we’ve been working on that for four years. And you can reach out to me on LinkedIn, on Twitter – although LinkedIn is probably a better way to go – if you want to know more about that.

    But essentially it’s a body of work that a lot of people have been putting time and effort into to really say, “Hey, look, this is not about what DevOps is. This is about how to do this in these complicated situations.” And you know me; as a performance geek I tried to – I was involved in QM/QA, verification, validation, risk management process, those kind of things. And I tried to make sure that evidence-based decisions, that – which is a hook to basically say visibility, telemetry, the proper SLOs in place, those are definitely in the standard along with other things.

    So, definitely check those two things out: Honeycomb and the IEEE 2675.

    Shimel: Excellent, Paul. Christine.

    Yen: Thank you for that plug, Paul. The one piece of advice I’d like folks to internalize, we’ve talked quite a bit about – or, I’ve talked a bit about developers in production and developers in observability. An asterisk there is that that is not – the practice – the muscles and the practices should transfer well but there are a lot of things in the DevOps world in production that are, well, in some cases outright hostile to developers and in many cases just kind of scary and unfamiliar. And so, if this is something that’s interesting to you, if you’re like “Ah, yes, I would also like to bring development and production closer together,” take a step back and look for things like that. Do your production tools primarily talk about AWS instances and CPU and memory use? Those may be things that might scare your developers off. How can you make the vocabulary that your production tools talk about more familiar to developers? How can you help them bring the concepts and nouns that they’re used to in testing – customer ID or endpoint or logic, something that feels more familiar to the developer world, how can you have that exist in your production tooling as well so that developers can show up and be like “Oh – oh, this isn’t so different”?

    I think that there’s a lot of things that are encoded in certain practices because we assume that a certain persona is the one using them. And those walls are blurring – or those walls are coming down; those edges are blurring. There’s a little bit of work left to do to facilitate it.

    Shimel: Absolutely. Hey, Mitchell, you want to bring it home?

    Ashley: Yeah, I’m going to wrap it up this way because there’s some great practical advice – and by the way, both companies have fantastic products, so please check them out. I think we have this mental model, this habit of thinking of things in one state. Matter has four states – well, five states if you count Higgs boson – Bose higgson. It’s not just solid. It is also fluid. I mean, think of our systems. Don’t think of it as software tools, all the layers of it. Combined together they operate more like a fluid, in a state that’s changing, constantly moving. Things are happening. And that causes you to rethink developers and production, doing production – doing performance testing in a production environment. And the flow of software through that DevOps tool chain is really part of that – the fluidity of that state.

    So, I think we like to think things – of things like “Let’s make everything a solid so it doesn’t change, so we can look at it, observe it, do something with it.” It’s not really that way. That’s not the world we live in today. But if you think about it as something that’s under constant change like a fluid, then I think we have a much better chance of figuring out better ways, whether it’s through technology, new paradigms, new ways of working, of how to make our software the best it can absolutely be.

    Shimel: And at the end of the day that’s what we all strive for. Right?

    All right. What a great way to end this, then. This is a wrap. I think it’s episode 13 of DevOps Unbound. But it’s a wrap on whatever number this was because it’s fluid anyway. It’s a wrap on this episode of DevOps Unbound. Many thanks to Tricentis for sponsoring us on DevOps Unbound. We will be back in two weeks with another great episode. Stay tuned. We also have a big roundtable coming up this month; check that out.

    Paul, hey man, congratulations on joining the Tricentis team as part of the acquisition there.

    Bruce: Thank you.

    Shimel: Christine, they’ve all said great things about Honeycomb, but well deserved. Say hello to Charity for us as well.

    Yen: I will. Thank you.

    Shimel: Keep doing what you’re doing. I hope to see you all soon or a couple months from now in person. Maybe we will do a live DevOps Unbound at some time somewhere. But until then, this is Alan Shimel for MediaOps. You’ve just watched DevOps Unbound.

    [End of Audio]

  • How to Build an Options-Based Observability Strategy

    How to Build an Options-Based Observability Strategy

    The global pandemic forced companies to accelerate their digital transformations, pushing them toward new technologies and architectures as they struggled to adapt to a changing world. Companies wanted fast development and deployment and were happy to trade off efficiency, reliability and sometimes, security, to pursue their goals. Now that the pandemic is receding in many parts of the world, the priorities are rebalancing as companies grapple with choices they made under fire.

    Observability has emerged as a way for enterprises to better understand sprawling infrastructure and application environments. According to Gartner, “Observability enables organizations to reduce the time it takes to identify the root cause of performance-impacting problems. In particular, and in contrast to traditional monitoring, operators can freely interrogate data post-hoc without the need to pre-program dashboards.”

    This sounds promising and the market responded quickly, but predictably. Large and monolithic monitoring platforms embraced the term and added new features, making them even larger and more monolithic. These monolithic platforms represent a failed choice-based strategy. They assume that all observability data is collected, centralized, integrated and only analyzed by a single tool. Enterprises following a choice-based observability strategy find themselves locked-in to multi-year investments without the flexibility to react to evolving technologies.

    While this has been good for vendors in the incumbent monitoring space, end users haven’t benefited from these enormous platform deployments because the choice-based strategy is built on the faulty assumption that a single pane of glass serves all of your monitoring and observability audiences, from SREs to DevOps and SecOps.

    A choice-based strategy also forces customers into limited options in the future as technology continues to evolve and requirements change. Defaulting to choice-based strategies also leaves little leverage for contract negotiations, data integrations and data access.

    Infrastructure and operations teams need to take a different approach to their observability strategy. Instead of focusing on buying products and making choices, teams need to shift their thinking to creating options. The choices you make today limit your options tomorrow. Tomorrow is unpredictable and uncertain. Taking an options-based approach allows you to be flexible and adaptable today and into the future.

    An options-based observability strategy is built on three pillars:

    • Establishing your observability strategy principles
    • Building composable environments
    • Staging your commitments

    Let’s look at each of these.

    Establish the Principles of Your Observability Strategy

    When asked about their observability strategy, many often leap into detailed plans covering every imaginable use case. They talk about the current state of their infrastructure and how things will be at the end of three or five years, including the skills and functions they’ll need in that time. If you’ve read the above, you’ll recognize this as a choice-based strategy: All the choices they need to make over the next several years are already laid out. This leaves little room for adaptation and options as the world evolves around you.

    Instead, think of your observability strategy as a single principle, or a collection of principles, guiding your observability strategy. Let’s say your core principle is that observability is a key enabler of operational efficiency across SREs and DevOps. We can build on that operational efficiency principle to define what key elements of our strategy has to include:

    • Data sources have utility-like accessibility; always on and available across tools.
    • Metrics are primarily driven by total cost of ownership and optimization.
    • Governance is centralized to the team distributing data to downstream systems.

    These elements are different if your core principle is something like customer intimacy or risk management.

    With principles and strategy in hand, we can focus on the next phase: Composing the observability environment.

    Compose your observability environment

    In an options-based strategy, the key success factor is avoiding large ecosystems that limit flexibility. Many vendors take a “give us everything” approach to observability. These approaches appear to start and end at the destination platform, but they begin even earlier, at data origination. It’s common to see agents only sending data to one destination, limiting the usefulness of the data by locking it into a silo.

    Staying modular means selecting tooling that abstracts the data sources from destinations and puts the power back into your hands. By using an abstraction like an observability pipeline, you can send data from one source to multiple destinations, while managing that data in any way you see fit. For example, this is where your centralized governance can occur.

    When new tools are introduced, upgraded or deprecated, an observability pipeline insulates the rest of your environment and users from those changes. A modular approach also gives you more power in contract negotiations with your other vendors because you’re less reliant on one vendor for all of your observability needs.

    Stage Your Commitments

    A choice-based observability strategy is a large commitment, often taking years. Once you start, stopping becomes impossible. That’s simply unacceptable in today’s environment of uncertainty. Choice-based strategies limit your ability to test, experiment, and learn. At the same time, our infrastructure is critical and it must be reliable.

    An options-preserving approach may involve experimenting with freemium products; only paying once the product’s value has been proven. Cloud-based options are another consideration since they are commonly subscription-based and offer easy try-before-you-buy purchasing styles. Even better, cloud-based options don’t require using your own infrastructure to test new options.

    Every IT team feels the need to react and respond to demands from the business. That urgency to make choices, to solve the immediate problem, can have long-term implications for future flexibility and agility. By structuring your observability strategy around a long-term vision based on preserving options, your team can remain adaptable as technologies and business requirements evolve.

  • Multi-Cloud Is Not About Lift and Shift

    Multi-Cloud Is Not About Lift and Shift

    Multi-cloud is often framed from the perspective of “lift and shift.” In other words, an organization takes a computing environment previously running on one cloud and transfers it over to a different service provider. Cloud migration may make sense for cost savings or performance benefits and such a shift may be necessary when migrating on-premises data centers to a public cloud.

    In theory, lift and shift sounds like it would empower cloud consumers with more choice in the marketplace. However, according to John Gentry, CTO of Virtana, lift and shift is quite rare in practice; it may not be the true driver behind multi-cloud strategies. Moving resources between clouds can result in costly egress fees. Plus, culturally-ingrained cloud preferences become challenging to shake. Unique configurations and add-on software-as-a-service (SaaS) make each cloud more nuanced, requiring new skills and procedures with every migration.

    Instead, Gentry advocates for a “fit-for-purpose cloud” strategy. This attitude is less about moving similar workloads between clouds but, instead, pairing particular types of workloads with the appropriate cloud types. According to Gentry, using multiple clouds simultaneously could still help organizations strategically align their digital resources and reduce dependency on a single cloud service provider (CSP). But, the real value of a hybrid multi-cloud setup lies in matching computing environments to different business layers.

    Fit-For-Purpose Cloud

    At first glance, the ability to move between clouds appears to be driving a new multi-cloud economy where cloud strategists can swiftly migrate resources and optimize intercloud utilization. However, when organizations attempt to shift, they usually experience many hidden costs, Gentry warned. These often pop up around data egress. Or, new data storage costs may take a surprising toll, Gentry added. “A lot of companies look at it from a computing perspective and they don’t account for the storage footprint.”

    DevOps in the cloud also introduces new responsibilities and processes that may differ between clouds, continued Gentry. From unique storage operations to managing the life cycle of a virtual machine, each cloud carries unique configuration methods. This makes it more difficult to abandon established procedures in favor of a different computing arrangement.

    Nevertheless, Gentry recognizes that we’re starting to see a maturing effect of the multi-cloud concept, especially among large enterprises. “Companies have a multi-cloud strategy—it’s less about moving between clouds than about picking a cloud that has specific advantages for a given workload,” he said. In a fit-for-purpose cloud approach, different workloads correspond to different layers of the business. For example, an organization may require a local data center or private cloud for high-security data. Certain applications may benefit from a distributed global public cloud, whereas other workloads could reap performance benefits and cost savings from a cloud-adjacent edge model. “These specific areas may not have anything to do with one another other than supporting the overall business,” explained Gentry.

    Matching Cloud Types to Business Units

    So how do we match the workload at hand to the ideal computing arrangement? Gentry identified three emerging cloud types:

    • Private cloud: A private core for particular functions that can’t be replatformed or rearchitected. Business areas such as financial records or patient care hold sensitive data that must be stored properly to meet regulations and SLAs.
    • Public cloud: End customer-facing, where sensitive data is not an issue. Public distributed cloud is ideal for delivering a highly available front end for customer-facing digital experiences.
    • Cloud adjacent/edge: When an environment is kept in a cloud adjacent facility with relatively local geographies. This may sit alongside the public cloud or connect to a front end in a cloud.

    For example, Gentry described how a large health care company uses a hybrid multi-cloud setup to support various business divisions. The organization is keeping traditional patient care workloads exclusively on-premises; due to regulatory reasons, it will never see the inside of a cloud. Yet, they are simultaneously building the next generation of applications in a public cloud, using Google Cloud to scale a clinical trial division. Simultaneously they began using Microsoft Azure for their back office. This scenario highlights one peculiar advantage of late-stage cloud adoption, noted Gentry: “They had the advantage of being able to take a more thoughtful approach.”

    Gentry described another case of an organization performing genomic sequencing. For data-heavy applications like this, where there is a high dependency on input and output, syncing with a public cloud could be extremely costly and introduce latency. For them, the most cost-effective method was to use a cloud-adjacent or edge model alongside a public cloud.

    How to Leverage Fit-For-Purpose Cloud

    One situation that may warrant cloud migration is a complete replatforming, noted Gentry. He described one early cloud adopter that rushed into AWS, only to find it wasn’t cost-effective for their needs. Architects then had to make tough decisions to determine what would be repatriated back to local data centers and what should remain in the cloud. “Their only motive going from cloud to cloud was, ‘We made a bad choice and we want to move.’”

    Clearly, to match cloud use with business requirements, you must choose the appropriate cloud. AWS is widely adopted for elastic computing and offers a wide product catalog. GCP is offering feature innovation and cost reduction to compete and is going after un- and under-penetrated regions. Azure, on the other hand, will offer licensing advantages if you are a Microsoft shop.

    Secondly, to unite IT around a hybrid multi-cloud strategy, you must remove the adversarial state between traditional ops and cloud ops. Classic ops is typically very safety-oriented, using a slow approach with endless tests in pre-production. Traditional ops may produce yearly updates. This is directly opposed to the new cloud ops approach, which emphasizes agility, speed and constant deployment. “They sit in different silos,” Gentry explained.

    To solve this dilemma, companies must share technical skillsets between the three main cloud types. “DevOps must become a continuum for all types,” Gentry said. In addition to cultural change, DevOps tools must evolve to monitor workloads across a hybrid multi-cloud estate. This will require integration to tie together tools and deeper observability.

  • 5 Ways to Reduce DevOps Toil

    5 Ways to Reduce DevOps Toil

    Over the last several years, DevOps has become a bit of a buzzword. It has become simultaneously a practice, a culture, a team, a job title and a vendor product. You can hire some DevOps, buy some DevOps, adopt DevOps and sprinkle a little bit of DevOps on top for good measure.

    But, at its core, DevOps is about service ownership: having a single team with end-to-end ownership of software running in production. You should not have one team building software and another team deploying and operating it. That’s slow. DevOps is literally combining development and operations into a single consolidated team. DevOps means embracing the mantra of “you build it, you own it.”

    The primary benefit of DevOps is increased speed and agility of engineering teams. With DevOps, exactly one team is responsible for a given piece of production software. There are no handoffs or knowledge silos. Practices like continuous delivery can emerge. Features can be put in front of your customers’ eyes with a shorter turnaround time. A secondary benefit is increased reliability and security. With “you build it, you own it,” it is no longer someone else’s job to ensure that software is correct or performant or reliable or secure. These responsibilities are “shifted left” onto exactly one team.

    So, where do things go off the rails?

    Service ownership and DevOps mean giving teams the agency to make whatever changes are necessary to their software. That can and will come at the expense of product functionality at times. So, the first place things go off the rails is when there is not a healthy balance between product needs and engineering needs. If teams are constantly working on new features but do not have the capacity to fix operational issues that are affecting them, product quality will eventually suffer. Ultimately, product-engineering imbalance generally comes from misaligned incentives or poorly defined goals from management.

    The second place where things go off the rails is insufficient training. Especially with organizations early in their journey to adopting DevOps, which may have separate development and operations teams, there is a lot of training on new technologies and processes. Developers need to learn about observability, responding to incidents and debugging production applications. Operators and sysadmins need to learn about coding and the principles of software design. These are new skills for both camps and investment in training and mentorship is required.

    What are some best practices for keeping DevOps on track?

    There are lots of these best practices. It really depends on your starting point as an engineering organization, but here are five important ones:

    1. Track Service Ownership

    If DevOps is about “you build it, you own it,” you need an authoritative list of a) what’s running in production and b) which team owns it. If a piece of software goes down, you do not want to find out that the last person to work on it was the intern who left three years ago. Many folks start tracking this kind of information in spreadsheets or wikis, but keeping the data up-to-date becomes challenging. SaaS service catalogs have emerged as the easiest way to automatically keep this data accurate, complete and consistent.

    2. Adopt Continuous Integration, Continuous Delivery and Feature Flags

    Committing small changes multiple times per day is superior to release trains where one large change is committed on an infrequent basis. CI/CD allows for new features and improvements to be tested faster and put in front of customers more quickly. Feature flag tools let you easily test new functionality and product hypotheses for different segments of customers.

    3. Embrace Incident Management

    Software breaks sometimes. Having a robust process for how to triage and respond to both alerts and incidents is important. Within the context of DevOps, the team that owns a piece of software should be responsible for being on-call to respond to associated incidents. If the software breaks or behaves in some unexpected way, the team is expected to fix it. The team is also responsible for identifying what happened and investing in ways to ensure the same error does not occur again.

    4. Treat Everything as Code, Then Automate all the Things

    Applications and microservices? That’s code. Infrastructure? That’s code, too. Security policies? Also code. Deployments? You guessed it–code.

    Treating everything as code allows for processes like “code review” to emerge beyond just your applications. You can have multiple eyes on every change, which catches bugs sooner and spreads knowledge to others. As well, version control systems (like Git) are a natural audit log, allowing anyone to see what was changed, when, and by whom.

    With everything defined as code, the next step is to invest in automation. How many steps does it take for a developer to deploy new code to production? Or to spin up new infrastructure? Or to hook up monitoring or error tracking tools?

    Your goal should be “one step:” run a command. It can be a shell script, a Slack bot or a button with a nice web UI. But it should always be one step. If there are more, you’re now in “manual steps” territory, and that’s brittle. You have no guarantees that successive individuals will run whatever sequence of steps in the same order, which can lead to divergence in how various parts of production are set up.

    Another example is maintaining a list of a) what’s running in production and b) who owns it. Manually keeping that list up-to-date is impossible as the size of your production infrastructure or engineering team scales. You’re better off investing in service catalog tooling that can automatically integrate and capture this information.

    5. Invest in Reducing Toil

    Service ownership and DevOps are two-way streets between management and their engineering teams. On one hand, consolidated ownership will lead to faster delivery and more reliable software. That’s good for management. But, on the other hand, teams require actual empowerment and agency to make decisions about their software. Part of that is having capacity on their roadmaps to make improvements to issues that are causing toil.

    For example, if a particular service is paging a lot or experiencing load issues, service ownership means giving the owning team the time to make any necessary changes. That will come at the short-term expense of new production functionality.

    There’s no free lunch on this last point. Engineering management can’t just combine dev and ops responsibilities and magically expect results. Service ownership is a two-way street. Otherwise, toil will kill your teams in the long term.

  • CircleCI Survey Shows the Need to Prioritize DevOps

    CircleCI Survey Shows the Need to Prioritize DevOps

    A CircleCI survey of 2,013 business leaders in the U.S. and UK published today finds nearly all respondents (97%) recognize that the success of their business within the next year depends on their software development teams. Despite those findings, well over one-third of respondents (39%) admit their organization is challenged when it comes to innovation and acquiring and maintaining developer skills.

    A full 89% of respondents said they also have a good understanding of how to measure the performance of their engineering teams. However, 40% of companies are still using antiquated metrics such as the number of lines of code written, while another 37% measure story points.

    More troubling still, less than one-third of respondents (30%) said they plan to make adoption of DevOps best practices a priority. On the plus side, only 15% of respondents said they are implementing a continuous integration/continuous delivery (CI/CD) platform for the first time.

    The CircleCI survey suggests that improvements in how software is delivered could be worth, on average, up to $126 million per year. Nearly two-thirds of respondents (65%) said their business is involved in digital business transformation initiatives of one kind or another. Another 20% said they have completed one.

    Jim Rose, CircleCI CEO, said it appears that while more organizations now realize how dependent they are on software, many of them have yet to address issues that fundamentally impact developer productivity. For example, more than half (52%) of respondents don’t allow their software developers to choose their own tools, noted Rose. While there is a clear need for a consistent approach to building and deploying applications, Rose noted that DevOps best practices should not require developers to employ a specific set of tools. Developers are only able to truly innovate when they are able to experiment with different tools, said Rose.

    In general, Rose said DevOps adoption tends to go through various cycles. Many organizations today are looking to reduce the number of tools that make up a toolchain. However, those efforts shouldn’t curtail the ability of developers to innovate. A CI/CD platform that provides the foundation for DevOps workflows needs to be easily extensible, noted Rose.

    It’s not clear to what degree adoption of DevOps best practices have stagnated, but the number of organizations that have implemented DevOps across their entire enterprise remains limited. Most organizations have individual teams that might have adopted DevOps to one degree or another. In many cases, those teams are using disparate tools and platforms.

    Most organizations clearly want to be able to build and deploy applications faster. The challenge isn’t so much mastering DevOps platforms as overcoming many of the cultural issues that conspire to limit DevOps adoption. In time, however, the need to rely more on digital processes will force the DevOps issue. As one organization makes advances—thanks in part to their ability to effectively employ DevOps processes—the more keen rival organizations will be to make sure they don’t lose ground. It may be a while before business executives connect the dots between their ability to compete and the degree to which organizations have mastered DevOps, but it’s increasingly apparent that day is not too far off.