Category: DevOps Practice

  • The State of DevOps Is Just Fine

    The State of DevOps Is Just Fine

    There is a growing amount of hand-wringing about the state of DevOps; that adoption is not progressing apace, or that the full benefits of the methodology are not being realized by the majority of adherents. That we can and must do more and do it better, etc.

    That is just stupid. Or, my first reaction: “Bunk!”

    Yeah, I called an idea stupid. No, I didn’t call you stupid. Don’t give me a reason to. The world is full of stupid ideas, and this is one of them. Here’s why.

    DevOps has seen a decade of unprecedented adoption – yes, unprecedented. PCs were not adopted by businesses at the rate that DevOps was adopted, once it caught on. Virtualization took the business world by storm and, frankly, wasn’t even close to the adoption rate of DevOps. Agile greased the wheels and got people thinking about better ways; we all knew the weaknesses of how we were doing things, and DevOps gave us an option that addressed those weaknesses. We took it. We ran with it.

    So talking about how it is stalled, when adoption is darned near-ubiquitous? Silly.

    Those concerned are further zeroed in on one aspect of DevOps – not enough culture change. Let’s face it—automation is easier, the ROI is more obvious and even when ROI is vague, the elimination of busywork from the schedule of developers and operations alike is huge. Some organizations were never going to move beyond that point; others eventually will, but aren’t in a rush. Organizational changes do not define DevOps any more than automation does—DevOps is the process of streamlining software creation and delivery—and both automation and culture change contribute.

    The “full benefits” of DevOps are … what, exactly? That is another silly part of the proposition that a slowing of DevOps adoption is negative. Automation improves the creation and delivery of software, silo elimination improves the creation and delivery of software… The full benefits of DevOps are improvement. That has always been the stated goal—to make it better, smoother, more repeatable. Wherever an organization is on implementation, it is almost guaranteed that their creation and delivery is “better, smoother, more repeatable.” So, benefits are accruing.

    And each organization has different needs. DevOps is a methodology. It has never been the perfect solution to every IT problem—though there are still pundits that will try to tell you it is. Automation is always a positive; Agile and DevOps—well, that is less true. You know your organization and your apps, so the “right methodology for the job” is absolutely your call, not some vendor’s or pundit’s. So, “adoption slowing” partially represents orgs/projects/apps that have opted not to pursue some of the more radical changes DevOps implies (yes, radical. Automation is just a logical extension of scripting; redesigning team organization and reporting relationships is absolutely radical by comparison).

    Which is a good place to leave off. Your apps, your org, your environment. You know what is going to do the most good. So keep doing it. Push for it if the org isn’t there yet, be the change that is needed. But be aware of cost/benefit. Sometimes, the changes being asked for just aren’t worth it. So make sure they are before you push too hard, and if they’re not, make sure you’re comfortable with why and can defend that decision.

    And keep rocking it. Those apps are delivering to users, no matter where you are in DevOps adoption. And that says it all about you and the team. Thanks, for all of your users that never think to say it.

  • From One-Click Deployment to One-Click Feedback

    From One-Click Deployment to One-Click Feedback

    What makes a group of individual contributors a team?

    You can look at today’s product development teams as an ensemble of craftspeople from different disciplines. Code builders, design artists, storytellers, and an orchestrator. Similar to an orchestra, their output is based on the ability of each and every one of them to work together in harmony, continuously and collaboratively.

    Let’s dig a bit deeper into today’s development methodology to see what this means in a practical sense.

    At a high level, we see three major steps: planning, development and release.

    1. Planning = Empower design craft
    2. Development = Empower code building craft
    3. Release = Optimize time-to-market (since there is no more time for nonsense!)

    Despite the fact that teams are supposed to work together and be very in tune with each other, when we look at the reality, it’s very different. We actually work in silos, nurturing black-box thinking. Instead of collaboration, often there are three separate units that comprise a whole, solely with interfacing endpoints.

    In such a configuration, it’s unavoidable that one unit’s priorities will be disruptive to another’s work, or flow. Without better integration of the actual collaborative parts of the work, in the form of frictionless and ongoing feedback throughout and during the end-to-end planning, development and release processes, eventually, your own unit’s priorities will take precedence over another’s.

    Engineering IRL

    A typical engineering process, whether it’s a new feature being developed, a bug fix or any other kind of collaborative work, usually looks like this:

    • A developer receives a design handoff and, from that moment on, is expected to deliver a working manifestation of the design specifications.
    • The developer gets to work (whether solo or on the dev team; independent of product or design, at this point) based on the specifications and starts writing the code.
    • Once completed, the code is deployed to a pre-release staging environment, where the designer actually experiences the result of their craft for the very first time.

    If you’ve been through similar processes, you’ll agree that, by this point, there is rarely time or tolerance in the process to iterate or provide feedback, nor correct much at all. More often than not, the mindset in fast-moving organizations is to stick with what we have ready to ship and just move forward. The actual “collaborative” part of the work is essentially bypassed. It’s really just a relay race of passing the baton downstream.

    But this engineering paradigm has its consequences. Ever tried to dissuade an artist from providing their feedback? Expect a pretty bad vibe in the room (or virtual room in today’s hybrid and remote team structure).

    This example, of course, is actually a virtual utopia of the development process. In reality, most organizations today have a far more destructive culture of continuous disruptions.

    Now, let’s spice up the scenario with some real-world interruptions that often break the ongoing individual flow.

    When a craftsperson is in the zone and creating, don’t interrupt! But what can you do when there are so many things happening in parallel? In small organizations that are just ramping up, most people are juggling much more work simultaneously.

    What often happens looks a lot like this:

    Jolene from sales requires a specific version for customizing a demo for a super important customer; Marko from support has opened 31 tickets you have yet to handle since it is a production issue that affects end users; your beloved single staging environment broke and you can’t review any new feature—oh, and don’t forget to attend the three meetings scheduled for today.

    Frustration, anyone? I like to call it the ‘multi-context bad habit.’

    Okay, I can already sense some eyebrows being raised, and I can almost hear you saying, “Yeah?! So what? We’ve always worked this way—what’s the issue??” Allow me to show you some numbers that may surprise you.

    “Finding flow is key, and interruptions are a drag. Minimal or no interruptions give developers an 82% chance of having a good day, but interruptions throughout the day decrease the chance of a good day to just 7%.”

    Eirini Kalliamvakou

    “Meetings are both awesome and terrible. Collaboration improves our work, but too many meetings can be a blocker; going from two to three meetings per day lowered the chances of making progress toward their goals by 60%.”

    Dr. Nicole Forsgren

    To summarize, these data points basically indicate that disruptions, interruptions and the “multi-context bad habit” ultimately have a tangible, detrimental impact on results and outcomes. They diminish successful outcomes and delivery times by orders of magnitude.

    Zero-Click Deployments as a Culture

    Fortunately, there are multiple practices and tools today that can be leveraged to dissipate the friction, break down the silos and improve the flow.

    This can be achieved by evolving from one-click deployment to zero-click deployments. Allow me to explain.

    Today, we have enough working examples that could (and should) be replicated more widely in engineering practices. Here are some examples.

    Preview Environments

    Preview environments (sometimes referred to as ephemeral or PR environments) provide, well, the opportunity to preview products. By allowing multiple stakeholders to review and experience the product throughout the development process, you shift-left the way you manage your development processes and are able to provide the relevant feedback and fixes earlier in the process. This basically means that for any PR you get a live environment that is shareable and independent from your staging environment. (I like to call this an in-development feedback loop).

    The JAMStack

    Another good example can be taken from JAMstack. When JAMstacking, consider using Netlify, Vercel or AWS Amplify to gain this capability for your team.

    Infrastructure-as-Code (IaC)

    If your project is non-JAMstack, you can consider building a similar preview environment through IaC solutions like Terraform or Pulumi. The downside here is that this comes with quite a bit of hassle, as you have to build automation for every single PR to have a dedicated shareable URL of the environment for review.

    This is great, though, because it democratizes the PR approval cycle by being more inclusive. Project managers, designers—practically anyone can review and approve the PR in development without having to wait until the end of the process to provide input. It’s easy to manage as it is isolated and independent of staging, which also provides always-on issue reproduction ability in the event that some kind of bug was discovered or tests need to be run during the development phase.

    But it also isn’t all roses and sunshine.

    There are some gaps and challenges that still need to be overcome for this to work. Some examples:

    How do we streamline feedback?

    Developers are used to getting comments from peers during code review in a language they can understand easily (for the most part) and quickly merge the input into their project. They don’t lose context by navigating away from the tool they’re working in (e.g. to Slack or Acme Corp. Task Manager), as it keeps them in their source code management environment (SCM). We need to think about how can we offer the same developer experience for everyone in the process to minimize PR turnover.

    How do we provide actionable and quality feedback?

    For example, UI and behavioral issue reporting are time-consuming, since you have to document and explain what, exactly, needs to be changed in order for it to be effective. Any wanted change likely involves the developer, which adds yet another disruption and interruption to their day.

    Taking Zero-Click Deployments to Single-Click Feedback

    If we want to optimize the developers’ flow, the next phase after simplifying the deployment aspects is to see how we add in the feedback layer in a way that isn’t intrusive.

    We need to now take this mindset and empower what I like to call one-click feedback.

    This isn’t a new concept, of course. Let’s take some inspiration from collaboration tools we all love like Figma, Miro and Notion.

    What’s magical about each and every one of these tools is the ability to provide contextual feedback. This is important as it enables contextual collaboration. Any user is basically one click away from sharing their feedback while remaining in-context, increasing the potential for feedback to be dealt with frictionlessly.

    This makes possible the following core values:

    1. Any person can easily point out something which requires the creator’s attention.
    2. The creator can instantly understand the feedback within the context of the project and what they are working on, and reply or tag another relevant peer for their point of view.
    3. The creator doesn’t leave their main work environment to prioritize the new task or give it the attention it requires. Just as designers do not leave Figma to apply feedback, PMs don’t need to leave Miro to apply theirs, and so on.

    These tools welcome feedback in an inclusive manner while enforcing a frictionless workflow. No one is messing with the creator’s flow as it is also happening asynchronously—no need for meetings, syncs or coordination of multiple stakeholders. This is also much more inclusive and relevant for today’s remote work culture, which requires investment in team communication through asynchronous channels and processes to be effective. (Here’s a great talk to watch on this topic; yes, the irony of interrupting your flow to watch this video is not lost. No, Really, Don’t Chuck Everything in Slack: Communications for Distributed Teams – from Florian Haas)

    Assuming you find some truth in this, I’d like to address the now apparent elephant in the room: Why don’t we introduce the same abilities for in-development collaboration?

    One-Click Feedback-as-Code

    We’re starting to see a trend where framework-coupled companies like Netlify and Vercel, for example, are adding collaboration aspects to their offering. Netlify, in fact, is acquiring a company, FeaturePeek, to embed collaboration features on top of their preview environments, and Next.js starting an early access rollout of their Next.js Live product.

    Imagine developers getting inclusive feedback during the PR approval cycle; not only comments about their code from peers but also UI, design and behavior comments with all of the needed assets and context to move forward without leaving their work environment! Such a shift will have a measurable impact on time-to-market, quality and velocity when employing such a workflow.

    The main premise here is that to achieve better metrics associated with flow (as noted above by Dr. Nicole Forsgren), we should not mess with the flow. The benefits of reducing the friction and interruptions in creators’ flow are exponential and will enable us to get closer to working in tune and in harmony (if we stick with the orchestral references) or simply more collaboratively, as a team where each individual is always maximizing the time they are able to be in creation mode, without silos or black boxes.

    What do you think? What’s your view of how teams should work together? How do you handle flow within your organization?

  • DevOps Database Platforms Slash DX Bottlenecks

    DevOps Database Platforms Slash DX Bottlenecks

    An enterprise with many databases and various data requirements for DevOps continuous delivery presents a problem. For example, test data provisioning is a challenge today, particularly in pre-release testing of database updates. Standard practices involve shared database environments that need to be maintained from one test to the next, slowing test cycles and generally not fitting into an automated CI pipeline. As I explained in A New DevOps Database Platform is Needed, at best, it makes things chaotic; at worst, problems with database integrations with DevOps is a gross impediment to overall organization agility—which undermines the very purpose that DevOps is meant to serve.

    A recent whitepaper, A New Kind of DevOps Database Platform, indicates that there are multiple reasons why a new kind of DevOps database platform is needed, which are:

    • Compatibility requirements
    • Integration with current CI/CD pipelines
    • Integration with portfolios of value stream management
    • Infrastructure cost efficiency
    • Productivity for developers, testers and operations
    • Security and governance
    • DevOps performance

    The paper explained that a DevOps database platform requires the following capabilities to satisfy these requirements.

    • Automated database provisioning: the ability to deploy a database using automated procedures.
    • Database cloning: writable database environments are delivered on demand, based on a built versioned image.
    • Distributed repository: database images can reside on Linux and Windows servers, as well as storage systems.
    • Simple declarative builds: a simple, predefined method to make the creation of versioned data images simple, while enabling user/group access controls, data masking and other data engineering functions.
    • Scalable data cloning: database clones are served on demand, with many simultaneous clones served from a single image.
    • Comprehensive database support: the repo supports all common relational, NoSQL, machine learning and file-based data stores.
    • Versioned databases: each image becomes a versioned, immutable DevOps artifact.
    • Deploys equally to all cloud environments: DevOps databases can be deployed and operated on any on-premises infrastructure or cloud.
    • Cross-platform:  DevOps databases can be deployed and operated on common operating system environments such as Windows and Linux.
    • Security features including access management, data masking and encryption: database images easily incorporate access control, data masking and synthetic test data via SQL scripts, batch files or command line tools.
    • Compatible with CI/CD platforms:  DevOps databases can be deployed and operated equally well in multiple CI/CD platform tools such as Azure DevOps, Jenkins and CloudBees.
    • Compatible with containers and container orchestrators: DevOps databases can be deployed and operated equally well in multiple container environments such as Docker, Kubernetes and Red Hat OpenShift.
    • Deliver writeable data at the speed of DevOps: Deliver writable databases in seconds.
    • API for easy integration with DevOps tools: An API is available to enable integration of the DevOps database control plane with other tools.
    • Audit logging: The DevOps database includes a complete audit log of operations.

    Transforming to the New Database DevOps Platform

    A DevOps database platform in an enterprise requires more than simply buying and installing software and telling everyone to use it. With multiple entrenched database platforms already in place, there are practical and political considerations that must be overcome. Introducing any change to a large group of applications in an enterprise can be chaotic, and will often be more costly and take too much time if the changes are not compelling.

    To be sufficiently compelling, the database DevOps platform needs to be affordable, easy to understand, easy to set up and use with a wide variety of CI/CD pipelines. The following will be sufficiently compelling benefits to drive adoption:

    • Versioned, secure database environments or images managed as a DevOps artifact.
    • Images can be built and managed by the DevOps team, without requiring new infrastructure.
    • Multi-DB and multi-TB data environments in seconds.
    • Database environments can be served on demand for a CI/CD pipeline.
    • Lower-level database environment infrastructure is streamlined, with a single VM capable of supporting many simultaneous database environments which drives an immediate cost savings and positive ROI.
    • Data security and governance benefits with versioned database environments, with built-in and auditable security policies.

    What This Means

    Digital transformation is imperative for modern enterprises and organizations to remain competitive. However, the transformations of many enterprises and organizations are seriously impeded by the challenges of integrating databases into their DevOps application pipelines and value streams. A new DevOps database platform can allow the databases to be treated like any other DevOps artifacts that are orchestrated and automated within the DevOps toolchains.

    Suggested resources for automating database environment delivery include Windocks, Cohesity and other storage appliances that provide virtualized (cloned) database environments that can be adapted for DevOps purposes. I want to particularly acknowledge input from Windocks, who has introduced a DevOps data repo that features database virtualization on standard Linux and Windows servers, for versioned data environments and CI pipelines and cloud-native support for data delivery for containers, Kubernetes and conventional instances.

  • Stop Hiding the Cloud From Your Developers

    Stop Hiding the Cloud From Your Developers

    If you say a person or organization “goes to great lengths” to achieve something, it means they try very hard and perhaps do extreme things to accomplish their goal. One example I’ve seen is that of more traditional companies “going to great lengths” to “hide” the cloud from their pool of potential technical consumers doing work like development. Instead of saying, “Here it is,” they block or restrict users from direct consumption. Under this model, developers don’t directly login to Azure or AWS, they go to the “internal corporate portal” and fill out a request form for the resources they want and submit it. Then, someone eventually processes the request and creates what is needed.

    In extreme cases, organizations create “cloud teams” and staff those groups with people who build cloud resources on behalf of downstream technical consumers, like developers. Potential consumers must submit a request with a detailed design document specifying everything they want. Then, the cloud team schedules the project and delivers it at a future point. The whole process mimics the historical waterfall approach to software development or systems implementation.

    Why do things this way? It always seems to come down to four distinct drivers:

    Costs: “If we give open access, we will end up with a huge bill!”
    Compliance: “Everything built must meet our security standards.”
    Complexity: “Most users will waste time trying to figure it out.”
    Control: “Our group has always coordinated access to resources.”

    In traditional companies, the reasons for this restricted access always seem to be some variation of those on the list. And when you rebut with something like “Do you think Facebook, Twilio, Netflix, etc. restrict their developers’ cloud access?” the answer is usually something like, “Well, those are elite tech companies; we’ve always done it the way we do it now …”

    In most cases, there is no singular argument you can make to change someone’s mind, or expand the range of possibilities. But you can offer facts. So, let’s take on their arguments one at a time and see if we can rebut them.

    Costs

    Argument: “If we open up the cloud to everyone, then all the developers will endlessly create virtual machines (VMs) and associated resources and services, and we will end up with a huge bill.”

    Rebuttal: There are certainly examples of this; do a search for some variation of “unexpected cloud costs,” and they’ll pop up, especially from a few years ago when cloud adoption was just taking off. But what about today? What can be done to control costs? Even though there are lots of tips and ideas on how to control cloud costs, I’ll offer one simple possibility that directly applies to developers and development groups that is not often mentioned in many articles: implement a cloud resource quota per developer or dev group.

    In AWS, for example, you can allocate via IAM; with Azure, you can use resource groups. The upshot is that there is a way to restrict the number and amount of resources that a single user can consume. So, whether you have 10 or 1,000 developers, you can use these built-in mechanisms to limit and then estimate what your consumption will be. If I have 100 developers and I put a limit on the number of VMs, the number of GB of RAM they can allocate and the amount of storage each developer can consume, then haven’t I just created a “cap” on consumption? The quota concept gives you a path to a “predictable” bill every month.

    Compliance

    Argument: “If we open up access to everyone, they’ll create VMs that don’t adhere to all our internal security standards.”

    Rebuttal: Aren’t developers just looking for a VM (or VMs) to do dev work? We aren’t talking about building production-hardened VMs to host applications. We are talking about giving developers the proper sandbox in which to do their work. So, from this perspective, requiring that developers only create VMs that adhere to strict compliance standards reserved for production servers doesn’t make sense.

    For example, maybe one of your compliance standards is that all production servers have a monitoring agent installed on them. Fine, that makes sense; what about dev/test? In dev/test, I might be spinning up a VM or a container that only exists for a short time, maybe even less than an hour while some tests are running. Does it make sense to require that a monitoring agent be installed on a VM that will only have a one-hour shelf life? Just throwing out the term “compliance” as a catch-all is not a real solid objection. Perhaps for dev/test, there are minimum standards you would want to follow regarding OS levels, patches, etc., but the VM(s) you use in dev/test do(es)n’t necessarily need to have all the additional security requirements reserved for production servers.

    The other part of this objection we hinted at earlier is that you have to transition to “cloud thinking.” Resources that exist for the next 10 minutes in the cloud could intentionally be gone shortly after that. In the cloud, you can quickly create and destroy VMs, or entire environments of VMs. That is what makes the cloud a game-changer versus traditional on-premises methods. You can’t apply the same on-premises considerations to the cloud one-to-one. You need to come up with a new thinking model that takes into account what it means to use the cloud versus how you did it before on-premises.

    Complexity

    Argument: “It’s too hard to figure out some of these cloud architectures, and developers will waste time trying to do so versus having a central team do all the work correctly the first time.”

    Rebuttal: Without the commitment to being a “learning organization,” there can be no DevOps, no transition/migration to the cloud, no digital transformation. Check out item number six on this list of 7 Ways to Make Developers Happy. (Spoiler alert: it’s ‘promote continuous learning.’)

    If “complexity of learning” is one reason why you restrict your teams’ access to the cloud, then you are missing the point of what it means to be a technical expert. Developers partially define themselves by the depth and the range of knowledge that they have accumulated, so continuous learning is a significant component of keeping developers “happy.” Not to mention that happy developers are more engaged and tend to stick around longer at companies that keep them that way; you’re risking losing the technical talent you do have, which has a host of detriments to your organization.

    Control

    Argument: “If developers are creating their own servers, what does our team do?”

    Rebuttal: This one is the toughest of all to rebut. Many organizations have one or more infrastructure teams who are responsible for creating servers and resources and giving access to downstream consumers. These groups control the resources. Now, along comes the cloud where everything can be self-service. And the natural reaction is, “If developers are creating on their own, what do we do?”

    For many traditional companies making the transition to the cloud, there will still be many opportunities for participation. Instead of “architect,” now we need “cloud architect.” Instead of “engineer,” now we need “cloud engineer.” Also, what other higher-value work could you be doing for the company if you weren’t spending all your time provisioning and maintaining on-premises servers? Do you think all of the existing on-premises applications are going to go away overnight? Will your company become “cloud-native” in the next six months? What about all of the AIX, IBMi, Solaris and other legacy components that are in the data center? There will always be plenty of work for everyone to do. And it’s always an opportunity to learn some new skills.

    The reality is that giving developers direct access to the cloud (with controls) frees up many other corporate resources to work on things that are, strategically, more important. If your company is not cloud-native right now, then guess what? It won’t be for a long time. Maybe in the short term, you’ll be hybrid-cloud and then in the long term, cloud-native. Along the way, there will be opportunities for everyone to rethink how things get done and maybe learn something new along the way.

    If you are hiding the cloud from your internal customers, ask yourself, “Why?” Are the original reasons still relevant, or are they holdovers from a time long past? Maybe it is time to re-examine your original rationale for why developers don’t have direct access to the cloud. If the goal of your organization is to “service the customer,” “do more,” “move faster,” etc., then removing internal barriers to accessing the cloud is one way to make progress.

  • Programmability is Key to Agile Transformation

    Programmability is Key to Agile Transformation

    Enterprise agility has rapidly become one of the most crucial variables for a business’s long-term resiliency. With the COVID-19 pandemic, never-ending disruptions to the global supply chain and nearly every industry’s typical processes flipped upside down, there has never been a more important time to prioritize agility than now.

    While the rewards of agility are high, organizations are struggling to implement key technologies and adhere to the methodologies that can get them there. In fact, the 14th Annual State of Agile Report notes that 59% of organizations are following agile principles, but only 4% of these organizations are getting the full benefit. But the ability to adapt quickly, seize new opportunities, and reduce costs is critical for survival in the ever-evolving and hypercompetitive digital age.

    Agility is about adapting quickly to changes and increasing productivity. Importantly, agile methodologies are not agile themselves and therefore will not magically transform enterprises into agile organizations. Instead, the focus needs to be on practicing the correct principles to become truly agile. With this in mind, let’s look at how two of these critical principles—programmability and observability—can increase productivity and allow for innovation across the business.

    Programmability

    Programmability describes the capability of hardware and software to change and accept a new set of instructions that alter its behavior. Let’s look at each of these two forms.

    One way programmability is used is to connect analog devices with software, for example, software-supported network routers. More recently, programmability has been extended to use networking to control the hardware involved and bridge with software systems. The rising popularity of infrastructure-as-a-service (IaaS) has increased the demand for programmability and brought concepts, such as infrastructure-as-code (IaC), into the realm of reality.

    The other use of programmability is to extend existing software capabilities. The two most widely known examples of this are application programming interfaces (APIs) and software development kits (SDKs). Using both approaches, a developer can extend the default capabilities of an existing program. The rebirth of APIs as business APIs has significantly extended the introduction of programmability into application software systems. The approach is particularly popular with application service providers since it enables end users to extend and customize the core capabilities provided by a product or service.

    Connecting Agility and Programmability

    So how are these two concepts connected? Agility requires a foundation and the right kind of environment to provide optimal results. Programmability is an enabler for creating an adequate path for agility. An organization with highly programmable components increases the ability to automate repeatable tasks. Let’s look at two scenarios: a business use case and a technical use case.

    Programmability in Business

    When a purchase order (PO) arrives, the customer care representative must verify the organization’s ability to fulfill the request and then create an order in the back-end customer relationship management (CRM) system. Traditionally, this process has required a good deal of manual effort: first, extract the PO data; then verify the details using other systems or spreadsheets and, finally, type the data into the CRM system.

    By contrast, consider a person working in a modern environment with high programmability. The PO can be received in an electronic format, such as JavaScript object notation (JSON), extensible markup language (XML) or electronic data interchange (EDI). Then it can be validated by connecting to other systems and reference data repositories, prompting the user to verify it and feed the data into the CRM system.

    Programmability in a Technical Environment

    In a typical technical use case, software developers will finish writing code; quality assurance (QA) engineers have to test the release; release engineers have to verify it and the DevSecOps team has to deploy the released artifacts. Similar to the business use case, this technical workflow has traditionally required extensive, tedious, manual work.

    However, the process becomes significantly more streamlined when the development organization makes the environment programmable. In this case, once developers commit the code, the automation flow will kick in, exert the committed code, run through the life cycle stages and deploy it into production.

    Through automation, which is enabled and extended by programmability, organizations can streamline their repeatable tasks and provide more time and space for users to work on essential or innovative tasks.

    Now, let’s look at the implementation details of the two use cases.

    Programmability in the Digital Supply Chain

    In the business use case, the automation of a workflow, such as PO processing, is treated as part of a modern digital supply chain initiative. The systems, messaging and data involved in such a flow are linked together using integration technologies.

    Integration approaches first involved point-to-point connections and then evolved to the use of centralized enterprise service buses (ESBs). More recent, modern approaches have centered around API-centric, integration microservices and integration platform-as-a-service (iPaaS) solutions that use decentralized models and cloud-native technologies.

    Now, organizations build or acquire digital platforms by combining APIs, integration and security technologies to create digital supply chain flows. Critical to the success of any digital supply chain is the ability to select systems with built-in API capabilities and enable existing systems to expose applications and services as APIs and make the entire enterprise programmable.

    Programmability in a Secured Software Supply Chain

    In the technical use case discussed earlier, DevSecOps automation provides the foundation for automating various aspects of the software life cycle. Here, development tools, testing tools and governance-related tools are all connected using a pipeline.

    IaC and automated build servers are two popular technologies used in automating such flow, which we call a secured software supply chain. Puppet, Chef and Ansible are widely adopted IaC scripting languages while Bamboo and Jenkins are popular build servers. However, as the DevOps space has evolved with cloud-native and decentralized technologies, GitHub and GitOps are also playing a vital role in building effective pipelines.

    Similar to the business use case, the components involved here need to connect to the build pipeline, and therefore the programmability of each element involved plays a significant role in automating the workflow. Furthermore, in order to build a comprehensive pipeline, the code quality, unit test, automated test, infrastructure provisioning, artifact building, dependency management and deployment tools involved have to connect using APIs and extend the required capabilities using IaC.

    Observability

    By analyzing both the business and technical use cases, we have a clear idea about the impact of automation and how it is enabled by programmability. However, we have missed one important element: observability. Let’s examine this here.

    The environment created by automation and programmability provides a good playground for teams to be practice being more agile, experiment with new ideas and take them to production rapidly. While agility increases, the responsibility of running healthy systems that provide a continuous digital experience is vital.

    Observability helps detect and predict issues using analytics, machine learning (ML) and artificial intelligence (AI). Modern cloud infrastructure provides a certain level of observability at the operational level. Meanwhile, some modern programming languages, such as BallerinaLang, have built-in support for application-level observability associated with the specific language. When working with languages that lack this functionality, developers will have to either use a third-party tracing library that is compatible with the programming model or directly insert observability instructions along with tracing and debugging instructions.

    Enterprises today are on a journey towards agility as they seek to optimize their digital strategies. However, organizational agility needs to catch up with project agility—and then, with each individual’s agility—to be more effective. This is the concept of “structured agility,” which is being fueled by “two-pizza teams” or self-organized teams.

    APIs are the foundation of programmability, which makes it possible to connect analog and digital systems, as well as extend software systems. Programmability increases the speed of delivery, enables an enterprise to become “composable” with high reusability and allows a flexible environment by opening it up for innovation—the core principles of agility.

  • Could Full-Stack Observability Help Lessen IT’s Burden?

    Could Full-Stack Observability Help Lessen IT’s Burden?

    The year 2020 was a landmark year for many reasons, other than the obvious. The IT world saw the first time that cloud service revenues dwarfed spending on data centers. Across the board, budgets have been increasing around cloud adoption. And in this ‘new normal,’ digital experiences are slated to remain just as crucial of a touchpoint as ever. In fact, new findings show that for 85% of users, digital applications are absolutely essential to their daily lives.

    Rising digital demands mean reliance on the cloud is here to stay. But if organizations don’t right-size their cloud workloads, expenses could get out of control. Plus, maintaining world-class user experiences requires a keen insight into the overall performance of apps, systems and solutions. If teams aren’t continually monitoring application performance and business KPIs, the bottom line could suffer.

    I recently met with Joe Byrne, AppDynamics Regional CTO, to discover what full-stack observability (FSO) means for today’s cloud-heavy applications. According to Byrne, DevOps and SRE teams should be maintaining a holistic view of the entire pulse of the application—including non-functional metrics (NFM) alongside traditional security and functional monitoring. Doing so could reduce time spent on root cause analysis and help ensure code is continually meeting business objectives.

    What is Full-Stack Observability (FSO)?

    In the classic definition, observability focuses on measuring the internal status of a system based on external outputs. Application performance monitoring (APM) typically tracks telemetry around logs, metrics and dependencies. IBM, for example, calls the observability trend “a natural evolution of APM data collection methods.”

    Full-stack observability (FSO), said Byrne, takes this one step further to track business-related key performance indicators (KPIs) alongside additional, more traditional software metrics. “FSO helps understand that software is performing optimally and that it is meeting business objectives,” said Byrne. In this way, FSO takes a holistic view to determine not only if an application is functionally sound but if it’s meeting its end goals.

    FSO would consider critical performance actions, such as user experience telemetry. For example, Byrne explains, an e-commerce website could find value in tracking performance levels such as login time, check out time and payment initiation. Tracking such metrics is necessary to pinpoint roadblocks and create actionable steps to remediate holes in the user journey, said Byrne. Increased visibility here could also help engineers quickly respond to issues to better optimize the user experience. In addition, aggregating information at a higher level—to view total products sold per day or total revenue per day, for instance—could inform overall progress.

    How FSO Could Reduce IT Stress

    “We’ve reached a point where people have moved away from brick and mortar and are going online,” said Byrne. These online spaces are more omnipresent — and valuable — than ever. The AppDynamics 2021 App Attention Index found that the average digital consumer uses 42 applications daily. Furthermore, 85% of people now say digital services are a critical part of how they get by in life.

    Mounting digital reliance has resulted in rising digital complexity. Therefore, said Byrne, companies have been moving to the cloud for the ease of scalability, elasticity and the capability of cloud functions. Cloud-native abilities like serverless, Kubernetes, identity and access management (IAM) and other add-on services are helpful perks to avoid reinventing the wheel.

    But of course, lifting and shifting all your current architecture to the cloud is costly; plus, it won’t necessarily eliminate application bugs. The user journey is increasingly vast, and broken touchpoints along the way could hinder performance. This is complicated by increasing third-party dependencies. Yet, more often than not, it is the application’s custom code that is having the issue, explained Byrne.

    Perhaps the most significant benefit of full-stack observability is a reduction of remediation time. “If you don’t have perspective, it can take a long time to run down an issue,” said Byrne. “The cost of finding a root cause can be so expensive.” Having a quick window into network, application and infrastructure hiccups is necessary to quickly address issues and save potentially lost revenue.

    Shifting Performance Monitoring Left

    An Amazon study found that every 100ms of latency costs companies a 1% loss in sales. Knowing the reality of high user expectations, software companies must be especially proactive in how they scale to meet the needs of consumers. As 72% of users believe application problems are the brand’s responsibility, the onus is on companies to avoid negative brand reputation.

    To spot performance hangups early on, Byrne encourages a shift-left attitude toward observability around business outcomes. To date, the shift-left mantra has focused more on code validation and security—necessary elements to rapidly deploy software updates. Now, adding performance testing could be the next iteration to further correlate each software push with end business outcomes.

    “You want to see and validate as much as possible before production,” said Byrne. “Performance testing is a key piece in the overall success of an application.”

    This could involve testing the load time for a specific endpoint—if a key action doesn’t meet a certain threshold, then it would not be promoted. Incorporating performance monitoring within a CI/CD process is a burgeoning practice also referred to as BizDevSecOps.

    There’s No Going Back

    The new normal is upon us, and it’s hard to imagine going back to any semblance of a world where there’s a decreased reliance on technology. From airline bookings to banking and grocery orders—software applications are now intrinsic to nearly every facet of modern life. To compete in such an economy, finely-tuned modular customer experiences that continually optimize business outcomes will truly set companies apart from the rest.

    In short, to maintain high software standards, it’s essential to break down operational silos and work together as a team—the DevOps creed. End-to-end ecosystem visibility could help enable that, ensuring, in Byrne’s words, that “applications perform in a way that meets the needs of the business.”

  • Puppet Survey Suggests DevOps Adoption is Stagnant

    Puppet Survey Suggests DevOps Adoption is Stagnant

    Puppet today published an annual State of DevOps report that suggests overall adoption of DevOps practices has stagnated.

    The survey of 2,650 IT, development and information security professionals finds 83% are implementing DevOps practices, to a degree. However, only 18% of respondents are working for organizations that have highly evolved, automated DevOps processes in place. More than three-quarters of respondents (78%) are somewhere along the path toward achieving that goal.

    A full 90% of highly evolved DevOps teams have automated most repetitive tasks compared to only 67% of mid-level organizations, the survey found. In addition, 91% of highly evolved teams report a clear understanding of their responsibilities.

    Not surprisingly, the biggest hurdles identified are more cultural than technical. The most common culture blockers at mid-level organizations include a culture that discourages risk (21%), unclear responsibilities (20%), deprioritizing fast flow optimization (18%) and insufficient feedback loops (17%). In contrast, less than 2% of highly evolved organizations report resistance to DevOps from the executive level, the Puppet report found.

    Nigel Kersten, a field CTO at Puppet, said during an online panel that, after more than a decade of DevOps advocacy, people continue to be the biggest limiting factor when it comes to adoption. Specifically, from a compensation perspective, many IT operations personnel tend to feel undervalued compared to developers, noted Kersten.

    Another challenge enterprises encounter is trying to balance the need to create a standardized IT environment that can be managed and secured consistently and the desire of DevOps teams to embrace new tools as they see fit. Senior IT executives often tend to make platform decisions based on cost criteria that don’t always account for the need to enable agile development methodologies. Most of those platforms are designed to be managed by an IT administrator using a graphical tool rather than via a command line interface (CLI) and application programming interfaces (APIs) that appeal to DevOps teams.

    As a result, individual pockets of DevOps teams that select and maintain a platform of their choosing are emerging within enterprise IT organizations. Those teams often view their chosen platform as a better alternative for advancing developer productivity. Finding and retaining site reliability engineers (SREs), for example, to manage those DevOps platforms is a major challenge for most enterprise IT organizations. Most IT administrators lack the programming skills needed to become an SRE, and it’s not clear how many IT administers are inclined to acquire those skills.

    Conversely, it’s not clear how many programmers want to programmatically manage IT infrastructure at the expense of time they would otherwise devote to writing code. Organizations that can only hire a limited number of developers may not want to shift responsibility for managing IT operations to the proverbial left simply because they need more code to be written faster. Finding and retaining developers, in many cases, is just as much a challenge as hiring and retaining SREs.

    Advances in automation and artificial intelligence (AI) should make it easier for organizations to embrace DevOps best practices in the months and years ahead. However, it should be apparent to all that adoption of those best practices across an entire enterprise still requires a significant amount of time and effort, and will for many years to come.

  • Cycloid Brings Open DevOps Framework to the US and UK

    Cycloid Brings Open DevOps Framework to the US and UK

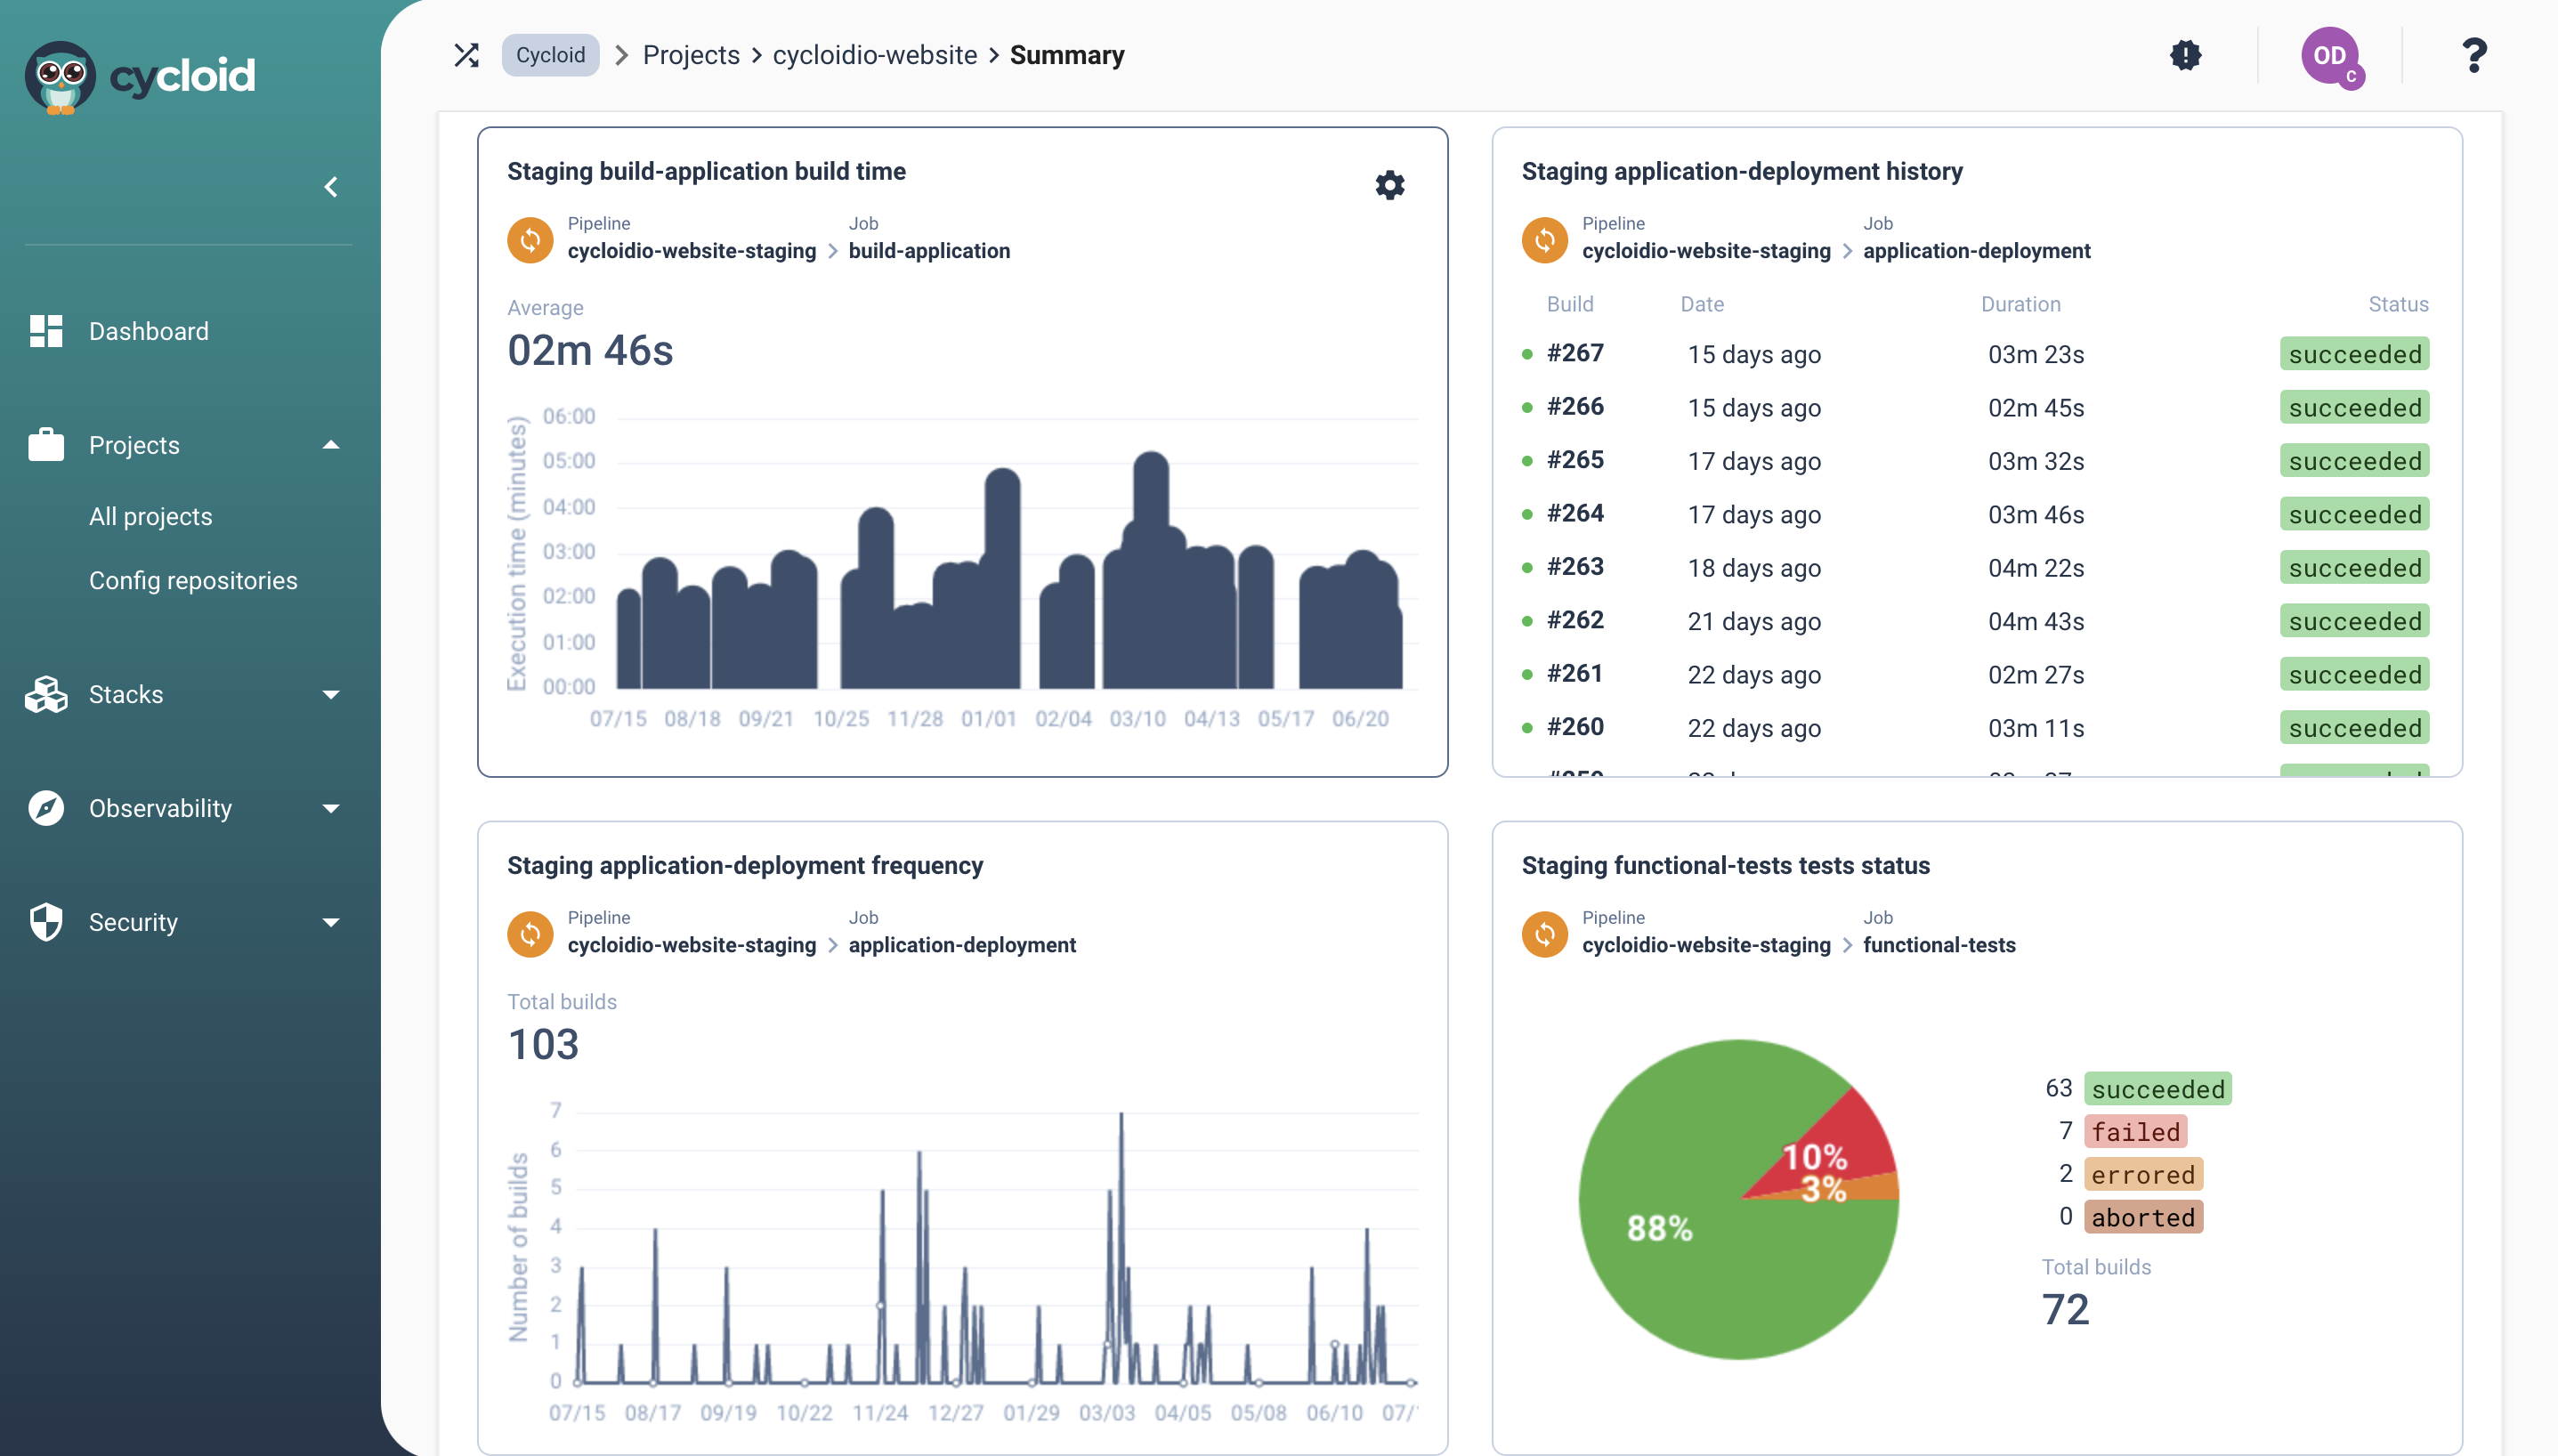
    Cycloid, a Paris, France-based provider of an open framework for implementing DevOps best practices, today announced it is expanding its operations into the U.S. and United Kingdom.

    Benjamin Brial, founder of Cycloid, said the Cycloid framework provides a lightweight approach to striking a balance between enabling developers to employ the tools they prefer and the need for centralized governance. The framework allows roles and policies to be pre-defined to ensure governance while service catalogs are used to deploy software using a set of drag-and-drop visual interfaces. There are also a set of management tools and features that provide additional visibility, automation, monitoring and financial controls to DevOps workflows.

    In effect, the portal that Cycloid provides to manage those workflows also serves to make DevOps more accessible to a wider range of IT professionals, added Brial.

    Cycloid

    Many organizations that embrace DevOps wind up building their own custom portal to achieve that same functionality. Rather than devoting resources to building and maintaining such a portal, Brial said Cycloid maintains and updates a portal platform that can be employed across any combination of tools that developers prefer. Other DevOps frameworks are often rejected because they require developers to adopt a specific set of tools, noted Brial. Without support from developers, it becomes nearly impossible to adopt DevOps best practices at scale, he added.

    After more than a decade of advocacy, adoption of DevOps within most organizations remains spotty. A significant factor in the lack of adoption is cultural issues involving skillsets. Many IT administrators lack the programming skills required to programmatically manage DevOps workflows. Cycloid is trying to establish a middle ground that enables IT operations teams to manage and govern DevOps workflows without having to acquire programming skills. The goal is to make it simpler for developers and IT operations teams to collaborate, said Brial.

    It’s not clear to what degree such an approach might increase adoption of DevOps best practices within enterprise IT organizations. However, it’s already apparent that the cost of hiring and retaining, for example, a small army of site reliability engineers (SREs) to manage IT environments at scale is often cost-prohibitive for many organizations.

    There’s no shortage of DevOps frameworks, but most organizations generally wind up crafting their own as part of an effort to tailor a DevOps workflow to meet their specific requirements. However, if there is a readily available framework that is highly customizable, Cycloid is betting more organizations would rather buy than build and maintain the entire framework themselves. Otherwise, DevOps teams would spend half their time performing the same repetitive manual tasks over and over, said Brial.

    One way or another, DevOps as a methodology for building and deploying applications needs to become more accessible. Proponents of DevOps have made a case for the methodology for the better part of a decade, with mixed success. The challenge continues to be finding a way to scale DevOps processes across the entire enterprise versus allowing each individual development team to define application development and deployment processes that, today, vary widely in terms of efficiency.

  • 3 Reasons Your Digital Transformation Stalled

    3 Reasons Your Digital Transformation Stalled

    The more a company modernizes, the more value it gets from the cloud, but not all digital transformation efforts are created—and executed—equally. According to Gartner, “87% of senior business leaders say digitalization is a company priority, yet only 40% of organizations have brought digital initiatives to scale … [and] without a shared vision across the organization, digital transformation efforts will continue to stall.”

    CIOs and other senior technology leaders are constantly looking for the best way to lead and scale modernization efforts that positively impact the business and generate the most value from the cloud. Here are three factors to consider to make sure digital transformation efforts don’t start to slow or stall out entirely.

    The Price of Ignoring Technical Debt

    Any CIO should be able to say how much of their development efforts are invested in innovation and how much is going into maintenance. A harder number to take into account is how much their innovation development effort is slowed down by technical debt.

    A good way to gauge this for CIOs—if you can say that your development organization dedicates more than 50% of its effort to innovation and that your development velocity is exactly where it was a couple of years back, then technical debt is not dragging you down. However, chances are that’s not the case.

    Why is that? A major reason is that the vast majority of business applications and business logic still reside on-premises in legacy applications and infrastructure with a once-solid software architecture that is now showing signs of wear.

    The technical debt these applications accumulated takes a toll. It is a ‘tax’ that many CIOs know they need to pay; know what is required, but choose to ignore until it’s too late.

    Many organizations delay modernization because they believe that it reduces the capacity for effort that can be spent on innovation, assuming that legacy maintenance can just carry on as usual. With the potential for a lengthy and risky modernization project, delaying innovation for that length of time is not even an option. The only way to stop ignoring technical debt is to find a way to reduce the risk of modernization and accelerate the modernization project so you can go back to doing what you love about tech: innovating.

    Managing App Modernization as a Tactical Project

    It’s amazing that application modernization is so often viewed as a tactical project—time- and materials-based, cost-focused—versus a strategic imperative driven by business goals. This approach also explains why many projects fail to meet expectations, are half-finished or abandoned or never even get started in the first place.

    The business logic and processes embedded in your legacy application estate are your core intellectual property and competitive advantage, and they need to be treated as such. These applications, and the business processes they encapsulate, require a strategy that continually modernizes them, starting now and continuing into the future. A one-and-done approach is a recipe for disaster and disappointment.

    So be strategic, make sure your modernization plan is aimed at reducing technical debt, restoring velocity and focusing on innovation. Once you get there, make sure you continuously manage your technical debt and keep your velocity high.

    Reliance on Lift and Shift for Cloud Migrations

    Cloud migration projects are most often critical parts of digital transformation initiatives, and yet, many outside advisors or quick-win focused insiders will push for the “easiest” approach.

    A rational plan to transform and modernize your applications for the cloud requires a critical assessment of your application estate to determine which applications should be refactored, lifted and shifted (rehosted or platformed), rewritten or just retired. Skipping this critical step and categorizing the majority of your apps into the “lift and shift” category is a common mistake that too many enterprises later regret. A lift and shift strategy may be fine for a subset of your applications, but for the most important ones it will result in a transfer of your technical debt to the cloud, increase your maintenance costs and take another bite out of your organization’s ability to innovate.

    Digital transformations are getting bogged down by technical debt, tactical decisions and modernization shortcuts. Organizations need to directly address these issues and reduce the significant drag they are incurring on modern transformation initiatives. By attacking them head-on, enterprises can accelerate their cloud migrations, application modernizations and business agility goals.

  • Don’t Look at This! IT’S A SECRET!

    Don’t Look at This! IT’S A SECRET!

    To continue the discussion about secrets after perusing this excellent report by GitGuardian—last time I went a little nuts about the number of secrets exposed in IT folks’ personal repositories. And it is a lot. I mean a lot of secrets. But you know what is scarier than, “A lot of secrets are leaked in personal repositories of people rushing to get this week’s sprint in”? The fact that 30,000 secrets were leaked via corporate public repositories in 2020. That’s thirty thousand.

    This is not some poor DevOps person in a rush to meet deadlines and with no real security support for personal repositories who dropped some secrets into a public personal repository.

    This is a system set up by your organization that should have security awareness, should be getting scanned regularly and that should never be a source of information for hackers. Instead, it is a source of information, perhaps even critical information, that hackers can easily snag. Because there are secrets in this public repository.

    The first step to avoiding this problem is to acknowledge that IT can’t serve every need, and ask business units (BUs) to come forward with any apps they’ve developed behind your back so that (non-invasive) security can be applied to those apps.

    You’ll either get some apps, or people won’t trust you and you won’t get any. In the latter case, truthfully explain about secrets hiding in public repositories and ask them to validate their own. It’s the best you can do if people won’t share what they’ve done, and there are still people out there that think IT involvement is a huge impediment to their software. ::Shrug:: As long as you can get them to check their apps for vulnerabilities, it shouldn’t matter too much. But I’m more concerned about getting the secrets, so I won’t debate the centralized-versus-distributed-app philosophies in this blog beyond saying, For secrets, if you can get them to scan/clean them up, the question of who is managing the app and the process isn’t very important.

    I’m still shaking my head—30,000! That is more than 100 secrets checked into public, corporate repositories each day (on average, of course). Please, go through your org, make sure you are not contributing to this total. That is wild; even if you account for the fact that if an app has one secret out there, it probably has multiple; even assuming each vulnerable app had four, that’s still 7,500 apps exposing secrets in the most preventable way possible.

    So, if you’re not certain about your public repos, go get certain. The ROI on “a few minutes for a scan, or a couple hours for a person to search for them” versus “our AWS secret was compromised,” or, “our API key was discovered and abused,” is pretty high.

    And keep rocking it. The sheer volume of apps out there is part of the shared-secrets problem, as is the growth in use of secrets as automation and DevOps have taken over. But you’ve got the solution, just make sure they’re not hanging out there in a public repo. And then go back to doing what keeps the business alive.