Category: DevOps Practice

  • Why IT Should Focus on Quality Over Velocity

    Why IT Should Focus on Quality Over Velocity

    Quality assurance (QA) isn’t a new phrase for developers. Most know it as a staple part of the software process that is crucial for producing quality code. But throughout the pandemic, with extreme pressure for businesses to digitally transform quickly, it’s a discipline at risk of being dismissed by organizations and tech leaders as a last-minute, box-ticking exercise – but at what cost? Many have neglected QA in search of that quick app launch or new digital service, leading to an unwanted surprise or customer disappointment when the apps and features don’t work.

    We all know the old adage: ‘quality over quantity,’ but when considering software development, CIOs should have quality over velocity in mind. Although producing software at speed is clearly a necessity for business success–whether startups pivoting during a pandemic or enterprises keeping up with these nimbler competitors–QA must become more than a forgotten principle for internal IT teams. To achieve the necessary standards at the speed required, tech leadership must embed QA as a specified requirement of any software project, rather than an afterthought.

    Quality Assurance = Customer Satisfaction

    Quality assurance is about monitoring the software development process and method to ensure that the output adheres to the project requirements, as well as industry security and compliance standards. With QA at the core, businesses can gain a better understanding of the status of their product, which allows them to assess, improve and consistently enhance its output for better outcomes and know whether the output meets the business requirements.

    In order to draw out a strategy that ensures quality at each step, businesses need to understand their customers’ needs, user journey, expected target markets, and how they expect the software to perform. Without this, businesses will struggle to not only meet and ensure customer requirements but also business goals and expectations.

    Without QA, it is difficult for businesses to assess the functionality of the product or service and it becomes extremely difficult to track critical defects that become costly to address once found post-production. Poor QA can also lead to several other challenges, including delayed product releases, unhappy customers, reduced brand reputation and increased technical debt.

    Quality Shouldn’t be Assumed

    In its infancy, software development took on the best practices used in the hardware/manufacturing industry, which largely relies on assessing quality at the end of the product life cycle before release. As a result, much of the technology sector adopted outdated strategies which then became common practice. In fact, there are still hundreds of CIOs and CTOs I speak to that expect QA processes to be an add-on at the end of the software development process.

    Many technical leads believe it’s developers who drive quality in a software project throughout its life cycle. And this is true, to an extent – there are some fantastic, talented developers out there! But this perspective can teach bad habits and can mean QA is an expectation of individual developers rather than a specified requirement for the entire project.

    That’s because it’s easy to forget that developers aren’t quality engineers; those are, in fact, two entirely separate roles that should be working side-by-side throughout any digital project. A developer’s role involves writing and maintaining the source code, which usually includes implementing unit and integration testing to ensure that the code matches the requirements. However, they are not involved in performing functional and non-functional testing or reporting defects to the development team.

    It’s a People Problem

    Any business embarking on a digital project based on software needs both developers and QA testers—you can’t have one without the other. But tech leaders can struggle to hire both good developer talent and QA engineers—whether due to expense or lack of availability of skilled workers. Recruitment is a lengthy and costly process, especially when recruiting skills that are already in high demand.

    In light of this landscape and paired with the impacts of the COVID-19 pandemic, which has caused many businesses to slim down their in-house teams, IT departments are increasingly stretched. This means processes like QA, which many companies don’t view as a necessity or a priority, can be neglected. But putting quality assurance at the heart of the software life cycle can actually save time, helping to avoid clearing code with errors that will end up coming back to be updated.

    Ultimately, businesses don’t just need to build software, they need to improve it and make it work and evolve with its needs and goals. Quality assurance makes this possible.
  • Engineering Applications for DevOps (Part 6)

    Engineering Applications for DevOps (Part 6)

    This blog series explains how to engineer applications for DevOps.

    Topics covered in this blog series include:

    • Factors used to decide whether an application is a good candidate for DevOps.
    • Practices to engineer designs for DevOps.
    • DevOps applied to enterprise apps and software services.
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • Five levels of application maturity.

    This blog covers five levels of application maturity. You can read part one here, part two here, part three here, part four here and part five here.

    Five Levels of Application Maturity

    Why is it that younger applications are more mature than older applications? DevOps works best with incremental changes rather than large complex changes that are time-consuming to change, build, test and deploy. DevOps also works best in ephemeral cloud computing infrastructures that can be scaled up and down quickly depending on short-term workload demands of supporting build, test and deployment requirements.

    While existing applications will eventually be modernized to take advantage of the cloud, greenfield applications should be designed to exploit recent advancements in cloud-based platforms and application delivery.

    The following paragraphs describe the characteristics of five levels of application maturity.

    Spaghetti applications are older, monolithic legacy application designs that tend to be large and complex, like a big messy bowl of spaghetti. This complexity occurs partly because these older apps accumulate a massive amount of code and patches over time and partly because the architectural approaches at the time they were conceived did not have modular, cloud-oriented requirements in mind. Spaghetti applications are the least capable of taking advantage of cloud infrastructures.

    Modular applications emphasize architecture designs that separate application components into functionally independent, interchangeable modules, such that each contains everything necessary to execute only one aspect of the desired functionality.

    A module interface expresses the elements that are provided and required by the module. The elements defined in the interface are detectable by other modules. Modules often use a design style known as service-oriented architecture (SOA), where services are self-contained black boxes that provide capabilities to the other application modules, as a service, through a network protocol. SOA may be confused with microservices architecture.

    There are key differences between SOA and microservices architecture that are important to DevOps. Microservices are preferred over SOA architecture because microservices are more fine-grained and restricted in what they can do. SOA uses an enterprise service bus for communication, whereas microservices use more lightweight stateless protocols and APIs managed as a product.

    Changes to SOA modules usually require a new application release, while a change to a microservice usually only requires the microservice to be replaced. Migration of modular applications to the cloud may require rework to take advantage of cloud features such as autoscaling.

    Cloud-ready applications that use the twelve-factor application modular design principles are more advanced. These modular designs emphasize declarative formats for automation, clean contracts with the underlying operating system and portability between execution environments. Deployment on modern cloud platforms obviates the need for servers and systems administration, minimizing divergence between development and production and enabling continuous deployment for maximum agility.

    These characteristics and capabilities enable the application to scale up without significant changes to tooling, architecture or development practices. Cloud-ready applications can be easily mapped to virtual machines (VMs) available through cloud infrastructure services (IaaS) for VMs based on VMware vSphere or Microsoft Hyper-V.

    Cloud-ready apps do not require rearchitecting or refactoring. They offer least-effort migration to the cloud with a lower availability rate. However, workloads such as legacy databases, third-party applications and homegrown business applications that are typically not designed for clustering or high availability suffer from a single point of failure.

    Cloud-ready apps are expensive to maintain. This is primarily due to the way they consume computing, storage and network resources, even when idle. Each component of an app runs in a dedicated VM with no scope for optimization. Upgrading or patching results in downtime and makes maintenance complex and expensive. Ultimately, cloud-ready apps derive less value from the cloud than cloud-optimized or cloud-native applications.

    Cloud-optimized applications take advantage of managed services offered by cloud providers. For example, instead of running a database in a VM, they consume database-as-a-service (DBaaS). Cloud-optimized apps typically target the platform-as-a-service (PaaS) delivery model of the cloud. They are portable and can be deployed in IaaS or PaaS. This reduces the deployment footprint, offering flexibility to IT teams. These apps are elastic, with the ability to easily scale in and scale out which results in optimal utilization of resources. Upgrading, patching and maintaining cloud-optimized apps is more manageable when compared to cloud-ready apps.

    The downside of cloud-optimized apps is the learning curve involved in migrating to the cloud. Developers, operators and system administrators will have to learn new ways of deploying and managing workloads. Line-of-business applications with access to source code are great candidates for being cloud-optimized apps. They can be redesigned and rearchitected to take advantage of the cloud. Cloud-optimized apps can integrate and interoperate with cloud-ready applications.

    Cloud-native applications are the most recent iteration of applications that are born in the cloud. They take full advantage of the cloud by exploiting capabilities such as elasticity, event-driven resource optimization and faster release cycles. Apps that are in the early stages of design and architecture are perfect candidates for cloud-native.

    Cloud-native applications are designed as federated microservices, packaged and deployed as containers and managed through modern DevOps processes. When your organization needs to scale to thousands of services in the cloud, microservices application architectures offer major benefits over monolithic modular architectures, including the following:

    • Separate microservices are better suited to different technology stacks.
    • Federated microservices enable independent deployment of different parts of the system.
    • Isolated deployments add to the resilience and fault-tolerance of the system.
    • Scaling characteristics may be different for each microservice.
    • APIs are used as connectors.
    • Stateless protocols help assure seamless recovery.
    • Event-driven programming reduces overhead and process latency.
    • Antifragile practices inoculate against unanticipated failure modes.

    The target deployment environment for cloud-native applications includes containers-as-a-service (CaaS) and functions-as-a-service (FaaS). This breed of apps delivers ultimate scalability and availability. Combined with continuous integration and continuous deployment, software is delivered rapidly, which accelerates time-to-market. It brings closed-loop feedback among developers, testers, operators and end users.

    Cloud-native apps demand new skills of containerization, microservices and build and release management. However, the ROI is higher when compared to other app models. Greenfield applications that are still in the design phase are ideal for adopting the cloud-native pattern.

    Diverse Applications for Cloud Migrations

    Large enterprises moving to the cloud will deal with a diverse set of applications. Through hybrid connectivity and integration, spaghetti, modular, cloud-ready, cloud-optimized and cloud-native applications will co-exist and interoperate with each other. If you are after the benefits of modularity, make sure you do not trick yourself into a microservices-only mindset.

    Explore the in-process modularity features or frameworks of your favorite technology stack. You will get support to enforce modular design instead of having to just rely on conventions to avoid spaghetti code. Then, make a deliberate choice whether you want to incur the complexity penalty of microservices. Sometimes you have no choice, but often, you can find a better way forward.

    What This Means

    This blog is one of a series that explained how to engineer applications to be most suitable for DevOps. Topics covered in this blog series include:

    • Factors used to decide whether an application is a good candidate for DevOps.
    • Practices to engineer designs for DevOps.
    • DevOps applied to enterprise apps and software services.
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • Five levels of application maturity.

    This blog covers five levels of application maturity. You can read part one here, part two here, part three here, part four here and part five here.

    For more information regarding how to engineer applications for DevOps refer to my book Engineering DevOps.

  • Visualize Logs to Get More Value from Data

    Visualize Logs to Get More Value from Data

    Why do you keep logs? Regardless of the type of logs we’re talking about, you keep them because you expect them to provide some value for the organization. Maybe the logs will help you improve profitability; perhaps they will help you recover from downtime or perhaps they are expected to alert you to a security incident in progress. If you’re a system administrator or someone tasked with infrastructure reliability and maintenance, you’d agree that logs are critical. They represent the source of truth you go to for information about your server status and activity, website traffic, application performance and much more.

    No matter the intended purpose of logs or how you use them, the information in these logs should be easy to access and interpret. Today’s complex systems generate enormous amounts of log data, making it almost impossible to dig through tons of data in raw text files to find important information. Finding valuable information is immensely difficult in text logs but not in the visual world. This is precisely where log visualization comes into play. What if the data in your logs could transform into graphic shapes and patterns? Wouldn’t it be much easier and faster to decipher information from log data and understand it better?

    What are Logs, and What are They Used For?

    Before going any further, let’s make sure everyone is on the same page about the meaning of logs. A log is a textual, timestamped record that tells us what happened and when. DevOps engineers have to rely on a combination of logs from various system components and data sources to understand why an event occurred, and perhaps even predict future events.

    logs value unknown


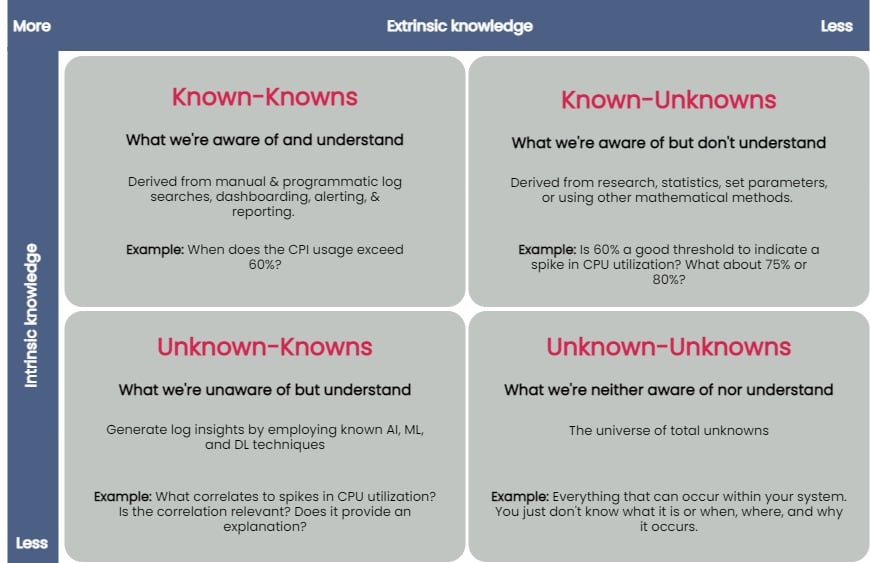
    You can taxonomize knowledge extracted from log data into four key groups: known-knowns, known-unknowns, unknown-knowns and unknown-unknowns. Manual and programmatic log searches, dashboarding, alerting and reporting manually extracted log fields are common ways to extract and analyze known-knowns. These methods assume that the engineer is already familiar with the data and knows where to look for answers. You can use statistics or other mathematical means to algorithmically resolve the known-unknowns, such as search terms and thresholds. The unknown-knowns are taken care of using AI/ML/DL techniques that generate log insights such as event correlations, log pattern clustering and known anomaly detection. But what about the unknown-unknowns?

    Uncovering Unknown-Unknowns

    With raw text logs, it’s relatively simple for engineers to conduct machine searches or set alerts upon encountering certain specific errors or specific types of behavior. However, to search through logs or even set up alerting parameters requires you to know what you’re looking for. If you have no idea what kind of errors or threshold limits for which you need to be alerted, it’s impossible to set these up.

    Modern applications are incredibly complicated, and one can not honestly understand everything about how they work or even always ask the right questions when things go wrong. But if an engineer reviewing logs doesn’t even know what to search for, it becomes impossible to figure out without an assistance tool like a purpose-built log visualization solution.

    For the most part, none of the techniques used to uncover the known-knowns, known-unknowns, and unknown-knowns of log data can help reveal the unknown-unknowns. An effective way of unraveling them is to rely on human intelligence to explore the unknown-unknowns space. Supplementing human intellect with a purpose-built log visualization tool can significantly help analyze the unknown-unknowns. Once you’ve recognized the unknown-unknowns, you can quickly feed this knowledge back into the appropriate, less esoteric groups (known-knowns, known-unknowns and unknown-knowns) and get more value from your log data.

    A good log visualization tool can aid in gathering knowledge from unknown-unknowns and can inform proactive log analysis or fast reactive log analysis use cases. Current log analysis practices center around reactiveness; the focus is to minimize and resolve issues after a problem has occurred. Using a log visualization tool, you can quickly isolate subtle and anomalous changes within a system by visualizing patterns generated from log data and exploring unknown-unknowns before an incident occurs.

    Current log visualizations are limited in display log count distribution and its variations. They do not visualize other log attributes or log combination attributes.

    All the UIs shown have similar function usage and displays. Drilling into an example of UI windows gives one the feeling of a typical log analytics practice. The figure below annotates different log analysis functions in the labeled, boxed area. None-visual log analytics functions such as search, tag, and log display are all required time-range input.

    log metrics annotate UI

    An ideal log visualization tool should not rely on just one information type. Log data is multifaceted. A log visualization tool can only begin to be valuable when it lets you focus on as many facets of log data as you can derive.

    Log Visual Pattern Discrimination

    The power of log visualizations comes from humans’ ability to recognize visual patterns. It’s hard to spot a pattern among raw log data, but it becomes easier once you can visualize that data.

    When an experienced DevOps operator looks at a log visualization, they can easily see where the anomaly is, even with no previous understanding of how the system works or where the anomaly might be coming from.

    Visualizations allow engineers to identify visual patterns and quickly understand what is going on in the system—whether it’s a hack in progress or an error causing a poor user experience. Visualizations are compelling, as they help shed light on important events, even if the engineer has no idea where to look or had no idea there was a hack going on in the first place.

    For instance, consider a scenario where a complex system generates millions of logs daily. Suppose we were to establish a baseline of the number of logs the system would generate when functioning normally. In that case, we’d have to take a daily count over a couple of weeks, or at least a month, to deduce a good-enough baseline.

    Even if we derive an acceptable baseline, we’d have to keep recording daily counts and compare it with this baseline to detect an anomaly. Doing this can be time-consuming and counterproductive as you might end up discovering an anomaly when it’s already too late to take any action.

    Once we plot logs daily on a graph, we can immediately figure out the baseline by observing it visually. Once we’ve visually established a baseline, we can instantly identify anomalies when we see values plotted above or below that established baseline. The following image visualizes logs ingested over ten days, illustrating how simple it is to establish baselines and identify when a system is doing something outside its usual behavior. This graph can deduce the baseline to be around 38,000 log records, with anything above denoting abnormal behavior within the system.

    log visualization

    Better Log Visualizations

    There are a few essential criteria for creating good log visualization analytics. They are:

    Use original log data. Data strategy is important. Most log data is unstructured by default, and many organizations tend to convert it to structured data before doing anything else with it. Doing so is a mistake, as you can lose vital pieces of information in the process. Good visualizations should be based directly on the logs exactly as the system produces them.

    Log data consistency. The format for the visualization should be consistent because if there are constantly changing variables, it becomes harder for humans involved to spot patterns.

    Choose robust log attributes and use them wisely. Instead of using just one log attribute for visualization (such as time distributed log density), you should look at visualizing more facets. Doing so gives analysts a better grasp of—and an intuitive understanding of—the log data set. For example, multiple pictures of an elephant taken from different angles help people understand elephants better than showing them only a single photo of an elephant taken from one angle. Similarly, if we break down logs by each of their attributes and then plot their frequency, we can better visualize how a system is performing. However, the attributes you pick are critical to providing valuable visualizations.

    With modern systems becoming even more complex, deciphering logs and uncovering unknown-unknowns will never be easy. The time is right to introduce new log visualization techniques to handle these unknown-unknowns. With log visualization becoming more user-friendly, you no longer need to count on people to be familiar with log interpretation or be aware of statistical, mathematical or AI techniques to analyze log data. Visualizing log data is not just a decision-making aid to human intelligence, discriminating between what is and isn’t acceptable and quickly identifying and remediating issues—the knowledge gained from unraveling the unknown-unknowns also helps advance AI/ML and automation techniques used to ascertain the knowns of your log data.

  • Engineering Applications for DevOps (Part 5)

    Engineering Applications for DevOps (Part 5)

    This blog series explains how to engineer applications for DevOps.

    Topics covered in this blog series:

    • Factors to decide whether an application is a good candidate for DevOps.
    • Practices to engineer designs for DevOps.
    • DevOps applied to enterprise apps and software services.
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • Five levels of application maturity.

    This blog covers DevOps applied to manufactured (embedded) systems software. You can read part one here, part two here, part three here and part four here.

    DevOps Applied to Manufactured (Embedded) Systems Software

    In the late 1970s (yes, forty years ago!) as a young engineer, I was given an assignment to figure out how to accelerate the software development and delivery cycles for an innovative packet switch called SL-10, (predecessor to the more recent model called Data Packet Node [DPN]) manufactured by Northern Telecom. Each SL-10 “node” consisted of millions of lines of original embedded software source code and custom hardware configured with many interconnected processors and protocols interfacing with other nodes, host devices, and terminal devices.

    Given the complexity of the system and lack of automated build, test and deployment tools, it was taking more than twelve months to generate each release of the system, and there typically were lots of bugs even after the release. Without knowing much about DevOps (the word “DevOps” was not invented for another twenty-nine years), we proceeded to implement a continuous delivery system that included automated build, test and delivery tools and workflows.

    The result was remarkable. Lead times for releases to manufacturing were reduced more than tenfold, from twelve months to one month, and quality, measured as defects found by customers per release, also reduced tenfold. This dramatic shift in performance and capabilities made it possible for the engineering and manufacturing teams to accelerate the rate of innovation and trample the competition. The SL-10 product, and its rebranded DPN version, quickly dominated the connection-oriented packet switch market, and it became the pride of the Nortel corporation and the Canadian nation. Even cooler, I got a nifty president’s pin and promotion which paved the way for my career that led to writing a book and this series of blogs! If this real-life example is not sufficient to demonstrate that DevOps can be applied to manufactured embedded software products, then I don’t know what is.

    There have been many other examples published that show how DevOps practices applied to embedded manufactured systems have reaped similar benefits. A notable example was published in 2013 by Gary Gruver in A Practical Approach to Large-Scale Agile Development: How HP Transformed LaserJet FutureSmart Firmware.

    That is not to say that DevOps applied to manufactured software embedded systems is the same as applying DevOps to enterprise applications or COTS systems. A paper published on the CloudBees blog, Five Aspects that Make Continuous Delivery for Embedded Different, explained some of the key DevOps practices used with embedded systems.

    DevOps Benefits for Embedded Systems

    Benefits of DevOps for embedded systems are summarized as follows:

    • Retrofitting the huge code base typically found in legacy embedded software systems into a DevOps model is not easy. It is likely to be expensive, but it is almost guaranteed to be a worthwhile effort, especially if you have a longer-term vision and intend for your product to stay competitive in the future.
    • Developers of embedded software need access to massive amounts of computer resources for testing their real-time embedded code on powerful hardware simulators.
    • Developers and testers need access to physical product hardware to run their binaries for system tests that cannot be run on simulators alone. Lab-as-a-service (LaaS) systems that orchestrate testing topologies of real devices can improve sharing of critical resources. LaaS systems provide a test framework that can be integrated through APIs into a continuous delivery pipeline.
    • Long build and test processes may need to be reengineered to reduce serialized lead times into quicker build times made possible by scaling build and test resources.
    • Long compliance and conformance test processes for embedded systems need to be accelerated with automation and resource scaling.
    • Focus on continuous delivery rather than continuous deployments in which shippable product versions are frequently delivered to manufacturing for verification, but the frequency of deployments to end customers is determined by other business factors.

    What This Means

    This blog is one of a series explaining how to engineer applications to be most suitable for DevOps. This blog series explains how to engineer applications for DevOps including:

    • Factors to decide whether an application is a good candidate for DevOps.
    • Practices to engineer designs for DevOps.
    • DevOps applied to enterprise apps and software services.
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • Five levels of application maturity.

    This blog covers DevOps applied to manufactured (embedded) systems software. You can read part one here, part two here, part three here and part four here.

    For more information regarding how to engineer applications for DevOps refer to my book Engineering DevOps.

  • Engineering Applications for DevOps (Part 4)

    Engineering Applications for DevOps (Part 4)

    This blog series explains how to engineer applications for DevOps.

    Topics covered in this blog series:
    • Factors to decide whether an application is a good candidate for DevOps.
    • Practices to engineer designs for DevOps.
    • DevOps applied to enterprise apps and software services.
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • Five levels of application maturity.

    This blog covers DevOps applied to commercial off-the-shelf (COTS) systems. You can read part one here, part two here and part three here.

    DevOps Applied to COTS Systems

    I often hear that DevOps does not apply to systems that use commercial off-the-shelf (COTS) software. The idea that DevOps cannot be used with COTS systems is, frankly, a cop-out. Just because someone else designed and developed an application’s source code is not a sufficient reason to avoid engineering a DevOps solution.

    Consider the value stream chain of activities from the source vendor through integration and deployment in your environment. There are limitations and constraints to the level of automation allowed, the return on investment in automation and influence over the development life cycle that DevOps practices can introduce when dealing with COTS applications.

    COTS applications will typically have predefined and supported interfaces for managing configuration or accessing data. These endpoints may not be accessible or compatible with your existing toolchain or automated change management practices.

    Types of COTS Applications

    COTS applications typically come in one of three flavors; namely, closed, open and platform, and each should be evaluated differently.

    Closed COTS applications allow little to no customization to their functionality and/or interfaces. They typically have predefined management consoles and a published list of commands or APIs that will allow external applications to interact with the COTS applications. A good example of a closed COTS application is Microsoft Exchange.

    Key considerations for DevOps with closed COTS applications are as follows:

    • Can configurations be scripted and integrated with existing automation and orchestration toolchains?
    • Can configuration scripts be managed and maintained in external version control systems?
    • How are updates, patches and service packs applied and managed? Can these practices be automated?
    • What developer tools (APIs, software development kits [SDKs], etc.) are available to extend and/or interact with the application and/or data?
    • Are these tools compatible with existing tools and expertise in the enterprise?
    • Can these developer tools be integrated within the existing toolchain?
    • How frequently are changes made to the base product?

    If these applications can be managed by external systems and code developed to automate deployment and configuration and/or integration can be managed through a version-controlled pipeline, closed COTS applications make good candidates for DevOps and continuous delivery (CD). By applying CD principles, COTS binaries are versioned and stored in an artifact repository; installation and configuration scripts are managed through version control and IaaS workflows and applications and integration endpoints are auto-tested through deployment pipelines.

    This is only made possible when consumers of the COTS application collaborate with operators of the COTS platform to ensure that the solution is aligned with enterprise goals, objectives and standards related to portfolio management.

    Open COTS applications allow significant modifications to functionality, data and/or interfaces. These platforms typically have rich SDKs, APIs and embedded developer utilities that enable users and developers to modify all layers of the applications; namely presentation, business logic and data. Open COTS applications typically have a large, complex footprint consisting of core services, data and/or GUI customizations, embedded applications, etc. Classic examples of open COTS solutions include ERP/ CRM platforms (like SAP or Oracle) or portal platforms (like SharePoint, ServiceNow or WebSphere).

    Key questions to ask when considering whether DevOps can be applied to an open COTS application:
    • How are customizations (created through internal design editors, logic builders or data schema extensions) version controlled? Are these configurations stored in a database or code?
    • How are customizations created through internal tools and packaged, installed and configured in higher-level environments like staging or production?
    • What does the development life cycle for customization created with internal tools look like? What quality gates are required? How about architectural standards?
    • How are custom, embedded applications/applets packaged, installed and configured?
    • Can these custom applications/applets be run and tested separately from the underlying COTS application?
    • What does the development life cycle for customizations created with external tools look like? What quality gates are required? How about architectural standards?
    • Does the COTS application provide testing frameworks, mocks and/or stubs for testing external dependencies?
    • What automated test suites are supported by the platform (unit, functional, regression, capacity tests, etc.)?
    • What is the upgrade path for customizations (historically)? As you can imagine, open COTS applications add layers of complexity.

    When considering DevOps and CD with open COTS solutions, it is recommended that you build multiple pipelines to support each layer of the application in the dev or continuous integration (CI) stage of the value stream. Subsequent stages, like staging and production, will use a converged pipeline built from known good artifacts of the dev and CI stages.

    Before implementing a solution, it is important to study the development life cycle and practices of the target COTS application before building your toolchain. Understanding how the end-state platform is created and how change is introduced will strongly influence your toolchain and pipeline design.

    Platform COTS Applications provide a set of services and tools, as well as proprietary runtimes, that enable users to build and run custom applications on the platform. These are the most difficult type of applications to integrate into existing DevOps practices and CD toolchains because common practices like version control, testing and build are done through the platform rather than using external tools.

    Platform COTS are packaged applications that enable customers to build applications on top of the base platform. As a blend of closed and open systems, all the previous considerations are valid. In most cases, the base platform acts as a closed system, whereas the custom-developed applications on top act like open systems.

    For this type of application, it is critical to understand what hooks and services are available to support DevOps practices and CD. Many of these platforms are not going to fit within your existing toolchain and may not be able to employ the workflows, dashboards and reporting you have grown accustomed to from your current toolchain.

    What This Means

    This blog one of a series that explains how to engineer applications to be most suitable for DevOps. This blog series explains how to engineer applications for DevOps including:

    • Factors used to decide whether an application is a good candidate for DevOps.
    • Practices to engineer designs for DevOps.
    • DevOps applied to enterprise apps and software services.
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • Five levels of application maturity.

    This blog covered DevOps applied to COTS systems. You can read part one here, part two here and part three here.

    For more information regarding how to engineer applications for DevOps refer to my book Engineering DevOps.

  • Engineering Applications for DevOps (Part 3)

    Engineering Applications for DevOps (Part 3)

    This blog series explains how to engineer applications for DevOps.

    Topics covered in this blog series:

    • Factors used to decide whether an application is a good candidate for DevOps.
    • Practices to engineer designs for DevOps.
    • DevOps applied to enterprise apps and software services.
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • DevOps applied to software services.
    • Five levels of application maturity.

    This blog covers the topic of DevOps applied to enterprise apps and software services; part three in the series. You can read part one here and part two here.

    DevOps Applied to Enterprise Apps

    An enterprise application assists an organization in solving business problems. Enterprise applications are typically designed to interface or integrate with other enterprise applications used within the organization and to be deployed across a variety of networks (internet, intranet and corporate networks) while meeting strict requirements for security and administration management.

    Proprietary enterprise applications are usually designed and deployed in-house by specialized IT development teams within the organization. However, an enterprise may outsource some or all the development of the application and bring it back in-house for deployment.

    The size and complexity of large enterprise applications, especially older monolithic-architected applications that are not designed in modules, are a challenge when it comes to implementing DevOps. Given the large scale and distributed nature of the people, process and technology components of enterprise applications, it is recommended that enterprises engage very experienced DevOps consultants to determine strategic requirements, roadmaps and plans for DevOps that fully consider all three dimensions (people, processes and technologies) and nine pillars of DevOps before embarking on a major DevOps transformation journey.

    Despite the complexity, with the right strategy and plan, DevOps can deliver enormous ROI for enterprise applications. Amazon and Adobe are just two of many examples of large corporations that have benefited enormously from applying DevOps across the enterprise.

    DevOps Applied to Software Services

    I often hear people ask, “Does DevOps apply to software services as well as it does products?” These are usually people who have only worked in product-oriented organizations, such as companies that manufacture things that have embedded software.

    Ironically, I often hear people ask the opposite question, “Does DevOps apply to products with embedded software as well as it does to services?” These are usually people who have only worked organizations in which software is consumed as a service over an intranet or internet for a price or for free. Examples of these organizations are IT departments (even the IT departments of manufacturers!), government agencies and enterprises such as banks, insurance companies, hospitals and financial trading companies.

    You already know the answer to these two questions if you read the earlier parts of this blog series. The answer to both is clearly ‘Yes!’ Cloud services are doubly interesting to DevOps because not only are cloud services used by DevOps as a preferred infrastructure, as described in the next chapter, but cloud services also use DevOps in the process of creating and deploying software for the implementation of cloud components.

    While we are on the topic of DevOps and services, I want to help clarify some confusion regarding whether “newer” DevOps renders “older” IT service management (ITSM) obsolete or less important. This confusion exists because ITSM has often been regarded as a gatekeeper run by Ops to prevent Dev from getting out of control. While some organizations may have, in fact, implemented ITSM that way, this is not the purpose of ITSM.

    “DevOps tends to focus on the software delivery life cycle and on building and delivering software,” said Jayne Groll, president of the ITSM Academy. For its part, ITSM tends to have a broader focus; it is really looking at all aspects of customer engagement, from fulfilling standard services to ongoing support and operations activities. So, ITSM is “almost like the left and right ends of DevOps.”

    Using ITSM With DevOps

    Here are some recommended engineering practices for using ITSM with DevOps:

    • Training to help DevOps professionals gain an understanding of ITSM, and vice versa, will help both teams find points of integration—not just in technology, but in process, as well.
    • Find ways to automate service change approvals implementation of known, good changes to allow for agility, iteration and innovation. At the same time, hold back high-risk, high-impact changes that might need more than just an individual contributor to sign off on before they make it in front of a customer.
    • Self-service requests, automation flows and IT orchestration are now the front door to IT service management actions. These can and should be happening in the background, automagically created, maintained and measured by our DevOps tools.
    • Embrace Agile service management to take Agile values and apply Scrum-like development practices to process design and improvement. Aim to make more frequent incremental changes rather than design and implement a total end-to-end process in the traditional way.

    What This Means

    This blog is part three of a series to explain how to engineer applications to be most suitable for DevOps. This blog series explains how to engineer applications for DevOps including:

    • Factors to decide whether an application is a good candidate for DevOps.
    • Practices to engineer designs for DevOps.
    • DevOps applied to enterprise apps and software services.
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • Five levels of application maturity.

    This blog covered how DevOps can be applied to enterprise apps and software services. You can read part one here and part two here.

    For more information regarding how to engineer applications for DevOps refer to my book Engineering DevOps.

  • 4 Ways to Manage Up for Automation

    4 Ways to Manage Up for Automation

    IT decision-makers understand how important a role process automation can play in a post-pandemic recovery. In a recent survey, 68% of these leaders said remote work caused key business processes in their organizations to break down. In the same survey, 97% described process automation as being vital to digital transformation and an important factor in achieving business outcomes.

    So, full speed ahead? Not exactly. While process automation’s benefits are well documented, many organizations remain hesitant to automate too many tasks because they’re afraid they’ll further complicate an already complex IT environment.

    This is where developers can help process automation initiatives get off the ground. They don’t control their organizations’ purse strings and they often don’t take the lead on planning new IT initiatives. But developers are the ones responsible for designing and building the software and tools that drive real business results. In a large sense, they occupy a key role at the heart of digital transformation.

    For organizations to gain the full benefit of process automation, developers need to be more intimately involved in automation projects. They need to have more say in how these initiatives are constructed, how they’re carried out and how they’re improved.

    Automation initiatives aren’t set-it-and-forget-it projects. They must tie in with end-to-end organizational processes, which will evolve over time. Organizations don’t want to bake in processes that won’t suit them two months or two years from now. With this in mind, process automation needs to be nimble, adaptable and smart–and it’s developers who have the skills and the insights needed to drive these initiatives forward, impacting broader organizational success. 

    To take on this larger role, though, developers must be given the right resources, tools and access to make their voices heard. Part of this is empowering them to manage up to senior leaders–on both the IT and business sides–to advocate for the types of automation projects that can drive true digital transformation.

    Here are four ways they can do it.

    Build Automation Demos

    The biggest enemy of a process automation project is time. The C-suite and senior IT leaders don’t want to spend months–if not years–debating the merits and feasibility of automating a series of tasks. They want to know quickly whether a project is viable and whether they should commit resources to it.

    Developers can set a project on the right course by creating a basic demo. It doesn’t need to integrate the complicated set of dependencies planned for the finished project; it just has to show people in power that the project will work. Demonstrate how a manual calculation project gets triggered by a quarterly deadline and estimate the time it will save a department on an ongoing basis. Show the leadership that the pain point workers have cited on feedback reports can be solved.

    Show Proven Examples

    While a demo visualizes how a process can work, a use case can illustrate how such a process has worked in another setting. Examples can be found in any number of places–in a formal case study, a tech article, a GitHub posting, a developer message board or materials supplied by a technology partner. Developers should tap their networks to get advice and run scenarios by peers. The goal is to find a situation where someone solved a similar problem with a manageable set of procedures–and it worked. Having a solid example takes the initiative out of the theoretical realm and gives the developer more credibility.  

    Get an Enterprise Architect on Board

    Once the demo and the use case are secured, the next step is getting buy-in on the vision for the automation initiative. This is the domain of the enterprise architect. It’s important for a developer to get this person on board as an ally. They should work with the enterprise architect to ensure that the set of tasks fits into the company’s architecture – today and in the future. If the company is pursuing a microservices strategy, the developer needs to show how automating a series of product quality checks can be accomplished inside this technology infrastructure.

    Keep Things Simple

    While organizations try hard to operate in an agile manner, sometimes that’s easier said than done. The people developers report to like to plan. Enterprise architects like to define perfect, future-proof architectures. The C-suite likes to envision scenarios and debate ramifications. Developers can break logjams by encouraging others to avoid the temptation to drown in detail. They should get comfortable with the concept, the demo, the use case and the vision–in that order–and then roll it out to the larger organization. 

    While process automation is widely seen as being vital to business transformation, building a project is often more challenging than it needs to be. Encouraging developers to take on larger roles can help organizations move automation initiatives past square one and on the path to digital transformation. 

  • Engineering Applications for DevOps (Part 2)

    Engineering Applications for DevOps (Part 2)

    This blog series explains how to engineer applications for DevOps.

    Topics covered in this blog series:
    • Factors to consider when deciding whether an application is a good candidate for DevOps.
    • Best practices for engineering designs for DevOps.
    • DevOps applied to enterprise apps and software services.
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • Five levels of application maturity.

    This blog is part two, and covers best practices for engineering designs for DevOps. You can read part one here.

    Poor design practices severely limit the potential for improvements provided by DevOps. As stated in my blog post Design for DevOps—Recommended Engineering Practices, “Without good design practices, a DevOps implementation has no hope of delivering on its promise of accelerating innovation with high quality and scale.”

    Following DevOps-recommended engineering practices for application design is important for legacy, greenfield or brownfield products, platform projects, feature enhancements or repairs. It is important for enterprise three-tier applications or multilayer products. And it is true whether the developers are using Agile, waterfall or ITIL development processes. In every application design case, designers face tough challenges and are expected to balance conflicting goals.

    Designers are expected to rapidly drive down the work backlog yet produce quality products that avoid costly rejections and rollbacks. In addition, there is pressure to increase the percentage of effort spent on creative content rather than corrective content and do so with limited time and resources. Balancing these conflicting goals is a tall order. If not supported by recommended engineering practices, the overall design experience is a cauldron of stress and a fast route to burnout.

    Recommended Engineering Practices

    The following recommended engineering practices improve the design experience and the products of that design in a way that is streamlined for the DevOps pipeline:

    • Designers must thoroughly understand customer use cases.
    • Usability, reliability, scaling, availability, testability and supportability are more important than individual features! Quality over quantity is recommended. Designs that anticipate actual customer use are the most successful.
    • The culture needs to support designers.
    • Leaders must support the designers with motivation, mentoring and training.
    • No designer can be expected to know everything. It is OK for designers to make some mistakes if lessons are learned and improvement quickly follows. Continuous monitoring and quick remediation are examples of good DevOps practices that help minimize the impact of any mistakes.

    Design Coding Practices

    Design coding practices are critical in the following ways:

    • Products are architected to support modular independent packaging, testing and releases. In other words, the product itself is partitioned into modules with minimal dependencies between modules. In this way, the modules can be built, tested and released without requiring the entire product to be built, tested and released all at once.
    • Where possible, applications are architected as modular, immutable microservices ready for deployment in cloud infrastructure, in accordance with the tenets of twelve-factor immutable non-monolithic apps, rather than monolithic mutable architectures.
    • Software code changes are pre-checked using peer code reviews prior to commit to the integration/trunk branch.
    • Software changes are integrated in a private environment together with the most recent integration branch version and tested using functional testing prior to committing the software changes to the integration/trunk branch.
    • Developers commit their code changes regularly—at least once per day.

    Good Design Practices Support QA and Ops

    Good DevOps design practices support QA in the following ways:

    • Design practices consider and understand the QA process.
    • Software code changes are pre-checked with unit tests prior to commit to the integration/trunk branch.
    • Software source code changes are pre-checked with static analysis tools prior to commit to the integration branch. Static analysis tools are used to ensure the modified source code does not introduce critical software faults such as memory leaks, uninitialized variables, and array-boundary problems.
    • Software code changes are pre-checked with dynamic analysis and regression tests prior to commit to the integration/trunk branch to ensure software performance has not degraded.

    Good DevOps design practices support Ops in the following ways:

    • Design practices consider and understand delivery and deployment pipeline processes.
    • Software features are tagged with software switches (i.e., feature tags or toggles) during check-in to enable selective feature-level testing, promotion and reverts.
    • Automated test cases are checked in to the integration branch when code changes are checked in. Evidence that the tests passed are included with the check-in.
    • Tests are conducted in a pre-fight test environment that is a close facsimile of the production environment.

    Supporting Tools

    The following supporting tools are needed to realize design for DevOps best practices:

    • Elastic infrastructure that can be easily orchestrated, created and released, as needed, to support designers’ tasks on-demand with minimal delay.
    • Design, code management, monitoring and test tools are readily available and scalable with minimal delay.
    • Monitoring tools that track application process performance and report the results to designers in easily consumable formats without delay.

    Applications for Which DevOps Does Not Apply

    “If you build it, they will come,” made for a great movie idea in Field of Dreams, but the reality is that many DevOps journeys led to nowhere despite the excellence of the people, processes and technology involved. As indicated above, applications that will not benefit from faster lead times, incur insufficient costs to justify investment in DevOps or that are too rigid to accept change are not good candidates for DevOps.

    What This Means

    This blog is part two of a series explaining how to engineer applications to be most suitable for DevOps. This blog series explains how to engineer applications for DevOps, and covers topics including:

    • Factors used to decide whether an application is a good candidate for DevOps.
    • Practices to engineer designs for DevOps.
    • DevOps applied to enterprise apps and software services.
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • Five levels of application maturity.

    This blog covered practices used to engineer designs for DevOps. You can read part one here.

    For more information on how to engineer applications for DevOps, refer to my book Engineering DevOps.

  • Engineering Applications for DevOps (Part 1)

    Engineering Applications for DevOps (Part 1)

    This blog series explains how to engineer applications for DevOps.

    Topics covered in this blog series:
    • Factors to consider when deciding whether an application is a good candidate for DevOps.
    • Best practices for engineering designs for DevOps
    • DevOps applied to enterprise apps and software services
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • Five levels of application maturity

    This blog covers factors to consider when deciding whether an application is a good candidate for DevOps.

    Factors to Consider for Engineering Applications

    The extreme worldwide hype around DevOps products and services seems to suggest that DevOps is good for everybody and applies equally well to every software-based product or service in every organization. Here is my experience with that assumption: It is not true!

    On the other hand, I have heard people say that DevOps does not apply to applications for which it absolutely does! Before you go a step further in your DevOps journey—or decide that your application does not qualify for DevOps—you should consider carefully how well your application is engineered to become a model for DevOps implementations.

    Best Practices for DevOps Determination

    The following are important factors you can use to decide whether an application is a good candidate for DevOps:
    • The application will benefit from faster lead times.
    • Leaders with responsibility for this application are open to collaboration and will be sponsors of change.
    • Team players that are associated with the application team (product owners, Dev, QA, Ops, infrastructure, security, PM) are open to collaboration and change.
    • The application is currently using or planning to use service-oriented, modular architectures or microservices.
    • There are at least ten people associated with the application including product owners, Dev, QA, Ops, infrastructure, security, PM. Smaller projects with smaller teams may not show sufficient impact or justify substantive DevOps investment.
    • The application is expected to undergo changes for more than a year. Less time would not likely yield return on the investment required for DevOps.
    • The application represents a good level of business impact and visibility but does not involve an extreme amount of risk for the business.
    • The application experiences frequent demands for changes from the business.
    • Not all tools used with the application need to be replaced to implement a DevOps toolchain. The costs of changing out all tools can negatively affect the ROI and business case for DevOps transformations.
    • Efforts to build, test or deploy releases of the application are substantial and could be reduced significantly by automation.

    It is not necessary for an application to perfectly fit all the factors, but the more closely it fits the more likely your application will benefit from using DevOps and will, therefore, be worth the cost to implement a well-engineered DevOps practice.

    DevOps can be used with all types of software applications and services. However, not all applications and services should be engineered to use DevOps. The factors that determine whether to engineer DevOps for an application have more to do with business factors than technology differences between different types of applications. Applications must be engineered in specific ways for DevOps to operate effectively.

    What This Means

    This blog is part one of a series explaining how to engineer applications to be most suitable for DevOps. This blog series explains how to engineer applications for DevOps including:

    • Factors to consider when deciding whether an application is a good candidate for DevOps.
    • Best practices to engineer designs for DevOps.
    • DevOps applied to enterprise apps and software services
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • Five levels of application maturity

    This blog covers the first two topics: factors to decide whether an application is a good candidate for DevOps and best practices to use when engineering designs for DevOps.

    For more information on engineering applications for DevOps, refer to my book Engineering DevOps.

  • A Data-Driven Approach to DevOps: Tips for Improving Speed and Scale

    A Data-Driven Approach to DevOps: Tips for Improving Speed and Scale

    Data has an undeniable power in a business context — it can sway stakeholders, help identify pain points, and demonstrate how changes are making an impact on the company. As the creator of Jenkins, Kohsuke Kawaguchi has noticed from his conversations with business leaders in the industry that implementing a data-driven mindset can be a game changer in the DevOps journey. 

    While data may not initially seem like it provides a full enough picture for businesses to work with, it carries invaluable insights and a certain level of objectivity that allows for a smoother transition in the DevOps process. Additionally, adopting a data-driven approach helps to showcase the small wins in your DevOps journey that can help build more confidence and trust in the process. 

    In the interview below, Kohsuke teases his session, “Go Data Driven With Your DevOps: 5 Tips for Improving Speed and Scale,” at TechStrong Con.  On July 15, Kohsuke, along with fellow Launchable Co-Founder Harpreet Singh, will provide tips on how a data-driven approach to DevOps can help improve speed and scale. 

    To see the full agenda and secure your free spot at the virtual event, visit the TechStrong Con website.