Category: DevOps Practice

  • Nobl9 Adds Hydrogen Platform to Surface Technical Debt Issues

    Nobl9 Adds Hydrogen Platform to Surface Technical Debt Issues

    Nobl9 today unveiled a Hydrogen platform that makes it simpler for DevOps teams to identify technical debt issues as they manage service level objectives (SLOs) as code.

    Hydrogen enables DevOps teams to define SLOs using a simple wizard or by embedding code within their application as part of a DevOps workflow. That code is then used to automatically collect data from platforms such as Datadog, New Relic, Prometheus, Splunk and others with requiring any additional instrumentation.

    Nobl9 COO Kit Merker said that approach also makes it possible to surface technical debt that inhibits achieving those goals via the Hydrogen platform. Armed with those insights, it then becomes easier for DevOps teams to focus on reducing or eliminating that technical debt because Hydrogen automatically generates a ticket in the Jira project management application—widely used by DevOps teams—to make sure the issue is addressed. Otherwise, in the heat of a DevOps sprint, the issue is likely to be forgotten as the application development project continues to move forward, noted Merker.

    The ability to identify that technical debt is an outgrowth of the ability to manage SLOs as code that is enabled by the core Nobl9 software-as-a-service (SaaS) platform. Hydrogen extends that capability by automating workflows whenever a specific service shows indications that it cannot meet objectives because of a dependency on a legacy platform that needs to be upgraded, added Merker.

    There is also a service health dashboard that organizes SLOs into logical groups that are mapped to features via labels, which Merker noted makes it possible for multiple stakeholders to easily identify which issues affect a particular service most. Hydrogen can also trigger a variety of automated workflows to prompt additional investigations that escalate as services worsen.

    Overall, Hydrogen is designed to provide engineering teams with more accurate context that can be used to prioritize which issues should be addressed first during any technical debt planning cycle, said Merker. Hydrogen can enforce code release policies based on technical debt budgets that are enforced via integrations with continuous integration/continuous delivery (CI/CD) platforms.

    Technical debt generally refers to any code change that is required to optimize a service that is not immediately addressed. The more legacy platforms there are in an IT environment, the higher that technical debt tends to become. At a time when more organizations are building and deploying microservices-based applications, that technical debt, over time, tends to adversely affect applications that are much more dependent on external services than a traditional monolithic application. A single technical debt issue can have a cascading impact on multiple microservices-based applications that would, otherwise, would be difficult to detect.

    The challenge, of course, is that technical debt doesn’t always get the attention it deserves when most of the IT team is focused on rolling out the next great application. However, as application environments become more complex it may only be a matter of time before all the technical debt that is being accumulated becomes unsustainable.

  • Stopping Mobile Fraud With Automation and DevSecOps

    Stopping Mobile Fraud With Automation and DevSecOps

    Mobile fraud is a multibillion-dollar problem that’s only getting worse. One study showed that mobile click fraud alone rose 64% during the first few months of the COVID-19 pandemic. In fact, during the pandemic, about one in five mobile ad clicks were fraudulent. And that’s just one form of mobile fraud.

    Weaponized botnets, mobile malware, mobile Trojans and mobile cheat engines and dynamic instrumentation tool abuse—the methods that fraudsters use to defraud companies and consumers via mobile devices—are constantly expanding in number and scale. 

    Historically, organizations have fought against fraud through monitoring and data analysis. As transactions and data come in, analytics and AI work to discern legitimate events from fraudulent ones. These systems require training and a lot of data to become proficient at identifying fraud, and they can become very accurate. But fraudsters are always changing their tactics to evade these systems, and, as many of us have experienced, false positives are still a big problem. If you’ve travelled enough overseas, likely you’ve had your bank account or credit card frozen until you could call your financial institution to let them know that your purchases were genuine. 

    Another challenge with existing mobile fraud prevention solutions is that they are designed to protect networks and network resources first. As a result, while fraud is occurring and fraud prevention systems are learning, mobile end users are still being affected. Also, when a bad act is identified and a system enforces protections against fraud, these enforcement points typically block network traffic. That protects the network, but the consumer and their mobile app remain at risk. Once a fraudster compromises a mobile app, they may be able to attack through other vectors, even if one network is shut down. For instance, if a consumer unwittingly downloads and launches EventBot to their mobile device thinking it was a legitimate app, it may compromise multiple banking apps. If one bank shuts down its network after detecting fraud, EventBot may have other opportunities on the device.

    DevSecOps

    As this chart shows, once fraud takes place, damage to a brand, customers and the bottom line begins immediately. Even if it is detected and halted, the harm it has already caused can’t be undone. Mobile app publishers and developers need to stop mobile fraud where it starts, and that means implementing mobile fraud prevention inside the app within a DevSecOps framework. By blocking the technical methods used to carry out fraud via mobile apps, organizations can make massive inroads toward stopping fraud before it ever gets to the network level, preventing both customers and organizations from getting scammed.

    Why Traditional Security Approaches Don’t Work in Mobile Apps

    To achieve a multi-layered defense against fraud, a mobile app should include app shielding, anti-tampering, code obfuscation, data encryption (including strings, resources, preferences), jailbreak/rooting prevention and man-in-the-middle prevention (such as certificate pinning or certificate validation). Certainly, there are commercial SDKs and third-party libraries that can provide these functions, with some limitations. But these approaches typically still require extensive development work and introduce additional frameworks or programming language dependencies and incompatibilities. 

    They don’t solve the fundamental problem of implementing fraud prevention inside a mobile app—it’s too expensive and time-consuming.  The root of the problem rests in the way mobile apps are developed, released and updated in a modern agile organization. DevOps depends on processes that are dynamic, automated, agile, integrated, iterative and continuous. Mobile app security has traditionally been very different: Static with manual, line-by-line coding. This way of implementing manual security will never work in an agile delivery model.

    The promise of DevSecOps is built-in security, delivered as a fundamental part of a release process where security is designed into the process at each and every phase of the life cycle. The security model can be delivered and evolved atomically, iteratively and dynamically so that it adapts to fit the app.

    The future of fraud prevention lies in the mobile app, but to make this possible, the industry needs to apply AI and ML to automate fraud prevention and security implementation into mobile apps on time within an agile, fast-moving and iterative app life cycle and release process.

  • Building and Leading Product Teams in Uncertain Times

    Building and Leading Product Teams in Uncertain Times

    The world seems to be changing faster than ever, and there’s no reason to believe it will slow down anytime soon. The pandemic has compounded this sense of constant flux, with customer priorities shifting overnight. Against this backdrop, product teams need to constantly evolve their development work without losing focus or feeling they need to react to every small change in the market. 

    This requires team leads to throw out their old playbooks and develop a new strategy that allows them to deliver continuous innovation without creating chaos for their teams or losing sight of their north star. Road maps are shrinking from years to months, and are now being created with the understanding that they may become outdated or redundant at any time.

    Building and maintaining an organization that can not only survive but thrive in these conditions is a daunting task. It requires a structured, programmatic approach that also supports agility and adaptability. Those requirements may feel at odds, but they actually are not. Here are five tactics to help your product strategy evolve with the times. 

    Keep That “Day One” Mentality

    It’s important to keep the soul of your product top of mind. It helps to retain a “day one” mentality which means constantly reminding yourself why you started in the first place and what problem you set out to solve. That founding problem statement should serve as your guiding light, especially through times of rapid growth and change.

    Customer requests are, of course, a high priority and should always be thoughtfully considered. But ask yourself if the request is aligned with that day one problem you set out to solve. If it’s not, work with the customer to identify the underlying issue they’re really trying to solve for versus focusing on the symptom they’re experiencing. 

    Cultivate a Culture That Thrives on Change Without Succumbing to Chaos

    It takes a combination of strong organizational capability and the right culture to build a team that can thrive on ambiguity. Strong organizational capability is achieved through talent, architecture and execution skills. 

    Great product teams build an architecture that supports iteration and are able to execute toward their north star in small, rapid steps. Team leaders should build a culture that takes failure in stride and learns from it to improve each subsequent iteration in the product journey. 

    Change is inevitable, but chaos is avoidable. Leaders must create an environment that feels psychologically safe and supportive, so that team members feel confident in changing priorities and making rapid decisions. 

    Build an “Innovation Factory” or a System that Reduces the Potential for Chaos

    Innovation and agility require well-planned foundational resources. Following are the key steps that can help put these building blocks in place.

    • Think of velocity as a part of your product. Teams should be broken into small groups to autonomously drive the product forward, but in such a way that the overall experience feels seamless to end users.
    • Democratize the product concept phase by creating conditions for a large number of ideas. Everyone involved should be inspired to contribute, including employees, partners and customers.
    • Create a system for product development excellence. Fully automate your product development life cycle by approaching developer infrastructure as if it were a service, with clear service-level objectives within a CI/CD framework. Digitize each step in the product concept, development and deployment journey, with a focus on measurement, learning and iteration in every phase. Ask who and how many people are building versus approving at each stage and ruthlessly optimize and automate where possible. 

    Bring a Service Mindset to Everything you Do

    If you’re building a SaaS product, as many startups today are, you’re no longer delivering a product in the traditional sense. You’re delivering a service, and you’re responsible for the entire experience from start to finish. This means you’re in full control over when to release new features and how you measure user engagement. You can see where the friction points are, and where customers are delighted. We have a philosophy at my company of “less input, more output”—simplicity is the name of the game, where the output and value your service creates for customers is the only measure that matters. 

    The outcomes required may change as customer priorities evolve and new requirements flow in, but adapting quickly and effectively should just be a matter of (re)connecting well-built services within your platform to prioritize and address those changes. Leverage the cloud ecosystem in a way that allows you to safely bet on other players and partners who are moving as quickly as you are. Focus on making sure your foundation is strong; one that can provide a service at scale even as the outcomes customers want change over time. This allows you to stay laser-focused on the task at hand: Maximizing value for users. 

    Incorporate Users in the Product Development Cycle and Learn as you Go

    The cloud has transformed the way organizations build products and integrate feedback. The entire life cycle is digitized and measured. Product teams can move at a much higher velocity and in smaller increments, with the ability to make near-real-time adjustments along the way. But the greatest advantage a cloud environment offers is that we can now include users in the entire product life cycle, every step of the way. It gives us the ability to measure outcomes quickly and take action on the information that immediately benefits customers.

    It sounds counterintuitive, but product teams can prepare for the unknown. There’s no way to see what’s over the horizon, but with the right people, processes and tools in place, there’s no reason that uncertainty should derail you. There has never been a more exciting time to be an innovator or a builder. Meet the uncertainty ahead with open arms and a strategic eye.

  • Prioritizing Scalability, Reliability and Security in Engineering

    Prioritizing Scalability, Reliability and Security in Engineering

    As digital products and services are more deeply embedded in critical industries and infrastructure and the implications of problems grow in scope, engineering organizations are renewing their focus on building platforms that are scalable, reliable and secure. More importantly, they are recognizing that this isn’t the responsibility of an SRE or CSO, it’s an ethos that must be carried each day by every engineer on the team. This is an important shift—from teams and cultures that valued speed of delivery above all else to teams and cultures that make high-quality systems the foundation of everything they do.

    This isn’t easy, and big cultural changes don’t happen overnight. There are many things that can go wrong when the team is operating in the legacy mode of prioritizing quick time-to-market but there are also some strategies and best practices for beginning the process of cultural change across your engineering organization.

    The Old Way of Doing Things

    You’re the engineer on call, and you get woken up at 3:00 a.m. by an alert that tells you an app is down. Groggy and annoyed, you look at the message and have no idea what service it’s referring to or where to begin.

    After nearly an hour, you can’t figure out who owns the service or how to get it up and running. So, you call that senior engineer on your team—you know the one—the person who gets called every time there’s a tricky question or problem. Thankfully, they answer your call in the middle of the night and help you bring the app back up. But in a month, the same scenario happens again; only this time, when you go to call that senior engineer, they’re no longer there. They quit to go work at a company that cares about reliability.

    Best Practices for Today

    How can you avoid this vicious cycle? Here are some best practices you can implement to begin shifting focus away from speed and toward scalability, reliability and security.

    1. Evangelize the Narrative That the Systems you Work on Matter

    At the end of the day, your systems are there to serve your customers and users. Leadership and teammates who embody these values are incredibly important. People should worry about letting their customers down, not about being yelled at by their manager or receiving a bad performance review.

    2. Set Explicit Expectations about Uptime

    When you say that your app needs to have 99.99% uptime, it doesn’t have the same impact as saying 52.6 minutes of downtime a year. Translate uptime numbers so they’re tangible—and on people’s minds every time there’s an outage.

    3. Don’t Sweep Problems Under the Rug

    After the dust settles from an incident, it’s important to get together and talk about it. Be transparent about what happened, which person or team made the error and what the implications to users were. The idea isn’t to point fingers or assign blame but to bring the team together so that you can learn, evolve and figure out how to prevent this from happening in the future.

    Here are some questions you can use:

    1. Who wrote the code?
    2. How was it tested?
    3. Should our automated testing have caught this?
    4. Who reviewed this code?
    5. Were they the right people to review the code?
    6. Why wasn’t it caught in the staging environment?
    7. Who released it and who went through the release validation checklist?

    Formalizing this process lets everyone on the team know that mistakes are part of the job and that there’s a standard way that problems are handled. This is a great way to help engineers feel free to do their best work without fear or avoidance.

    4. Define Individual Owners for Every Piece of the System

    If there’s any confusion about who owns what within your engineering org, you need to address that right away; it’s a massive problem. Not only do you need an owner for every part of the system, but they must also be empowered to fix issues and know that they’re the ones on the hook.

    5. Invest in Documentation, Runbooks and Logs

    The owner of each piece of the application is also responsible for making sure that documentation is up to date, runbooks are clear and easy to follow and logs are readily accessible. When you’re getting paged at 3:00 a.m. about a service you’ve never heard of before, these resources are key.

    6. Prioritize the Delivery Pipeline Like it’s a Key Feature

    You should always be thinking about how to build safeguards around your workflows, like automated testing or new tools. This may mean you need to go toe-to-toe with product managers to make sure the work required to build a robust delivery system isn’t getting kicked down to the backlog.

    7. Get Business Buy-In by Using Terms They Understand

    Unreliable code is technical debt. And debt is something all leaders understand, regardless of their technical abilities. Stripe published a survey in 2018 that found the average developer spends more than 17 hours a week dealing with maintenance issues, costing $300 billion per year globally. If you’re pushing to invest in SRE practices, those numbers might help you make your case.

    Culture comes first, but the right tools can reinforce the culture and drive accountability over time. Tools that help teams keep track of critical information such as service owners, documentation and runbooks can help tremendously. Additionally, having easily available dependency maps of the architecture are key to quickly understanding complex systems. Lastly, setting organization-wide standards for best practices and providing templates for spinning up new services that follow these can help ensure that these things are not forgotten.


    This article was based on a talk given by the author at Conf42: SRE 2021. 

  • Google Makes Fuzz Testing Integration Tool Available

    Google Makes Fuzz Testing Integration Tool Available

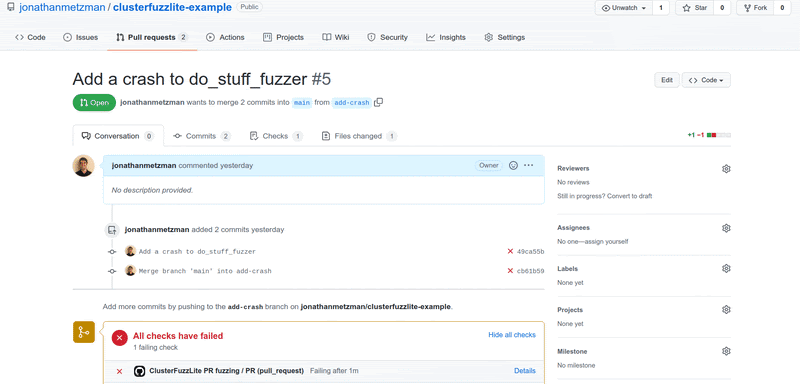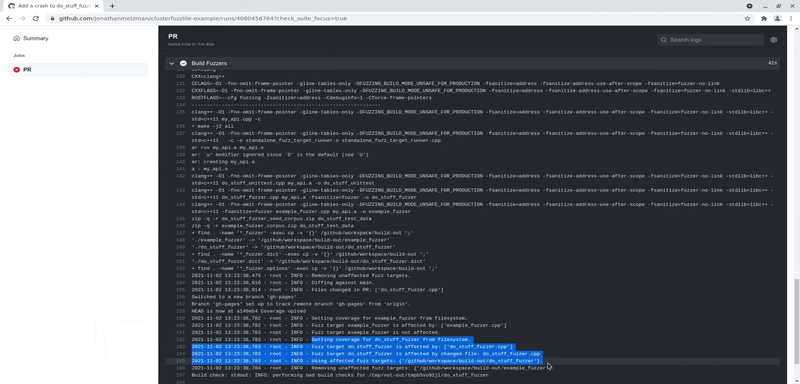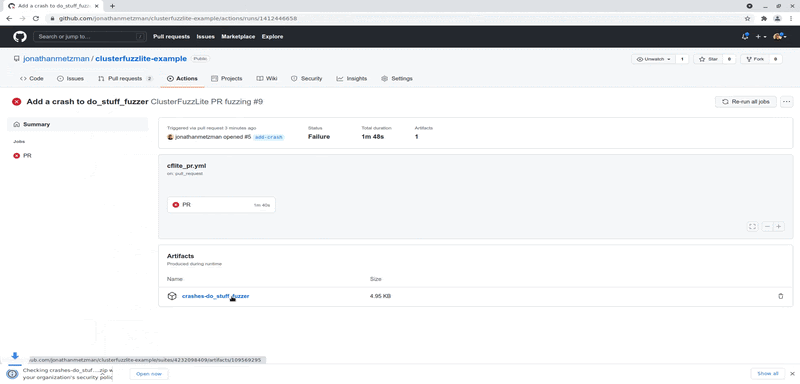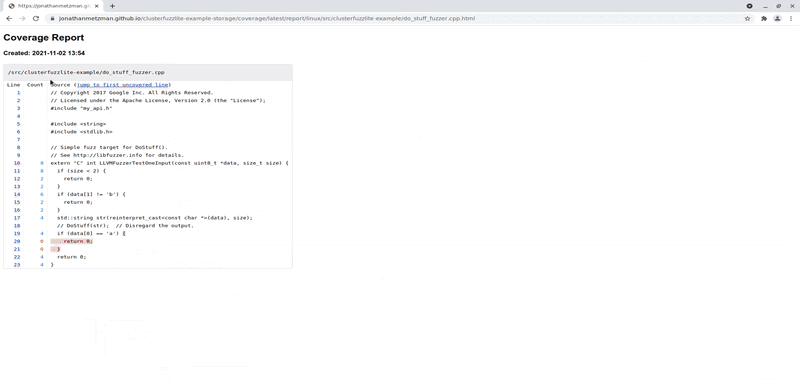
    Google today made available a ClusterFuzzLite tool that makes it simpler to incorporate fuzz testing into a DevOps workflow.

    Fuzz testing refers to an automated software testing technique that involves providing invalid, unexpected or random data as inputs to an application to discover issues such as potential memory leaks.

    Jonathan Metzman, a senior software engineer for Google, said ClusterFuzzLite is a lighter-weight version of a tool that Google makes available to its internal development teams. It is not a fuzz testing tool itself, but rather a tool that makes it easier to surface the results of a fuzz test within a DevOps workflow. Once those results are surfaced, it then becomes easier for developers to address issues before an application is deployed in a production environment.

    Core capabilities enabled by ClusterFuzzLite include continuous fuzzing, sanitizer support, corpus management and report generation tools. The goal is to make fuzz testing more accessible to a broader range of developers as part of an overall effort to embrace DevSecOps best practices, noted Metzman.

    ClusterFuzzLite currently supports GitHub Actions and Google Cloud Build, but Metzman said it is easily extensible to other DevOps platforms. It is designed to run as part of a DevOps workflow by adding a few lines of code to a continuous integration/continuous delivery (CI/CD) workflow.

    Google has already made ClusterFuzzLite available to open source projects, but is now providing additional access for commercial developers. Since its release in 2016, over 500 critical open source projects have integrated into the Google fuzz testing program for open source software, resulting in over 6,500 vulnerabilities and 21,000 functional bugs being fixed.

    In the wake of recent guidelines issued by the U.S. National Institute of Standards and Technology (NIST) that were themselves in response to an executive order issued by president Biden, the number of organizations using fuzz testing is expected to increase now that NIST has determined that fuzz testing is a minimum standard requirement for code verification.

    For several years, Google has been making a concerted effort to improve the security of open source software. The challenge for all developers is finding a way to build more secure applications without slowing down the rate at which they are deployed. Fuzz testing makes it possible to identify issues much earlier in the application development life cycle versus just before an application is deployed.

    Less clear, of course, is whether developers are starting to use these tools on their own or if the increased adoption is because of a concerted effort by their organization to embrace DevSecOps best practices. Regardless of the motivation, however, the overall state of application security should continue to improve as it becomes simpler for developers to invoke more advanced testing tools.

    In the meantime, organizations of all sizes are reviewing how they construct software in the wake of a series of high-profile security breaches. In theory, at least, increased focus on software supply chains should prevent issues from arising after deployment when they become much more costly to remediate.

  • Akamai Brings Web Application and API Security Together

    Akamai Brings Web Application and API Security Together

    Akamai Technologies, Inc. this week launched a service that consolidates the process of securing both web applications and application programming interfaces (APIs).

    Amol Mathur, vice president of product management and strategy for Akamai, said with the launch of App & API Protector the managed security services provider is making it easier for IT teams to embrace DevSecOps best practices via a converged web application and API (WAAP) service rather than using separate tools and services to secure them individually.

    The service is also designed to continuously discover API requests that are then automatically inspected for malicious code. Optional API security controls can be enforced based on policies defined by internal IT teams.

    In addition, the company provides access to a multidimensional threat scoring model, dubbed Adaptive, that combines data collected by Akamai with data and metadata from each web and API request to help organizations better understand which threats require immediate attention. Security events are also continuously analyzed using machine learning algorithms to deliver highly accurate policy-by-policy tuning recommendations that can be implemented via a single click.

    Akamai security researchers also make use of machine learning and data mining techniques to continuously analyze over 303TB of daily attack data that is used to automatically update protections. Alternatively, organizations can opt to manually evaluate that data themselves to minimize any unexpected impacts those updates might have on their applications.

    Other capabilities include built-in bot mitigation tools that are informed by a directory of more than 1,500 known bots, integrations with the Akamai command-line interface (CLI), Terraform or scripts used to drive automated pipelines spanning a continuous integration/continuous delivery (CI/CD) platform.

    Akamai

    A recent report published by Akamai found that between January 2020 and June 2021 there were more than 11 billion total attempted attacks made over an 18-month period. The most common attack vector was SQL injection (SQLi) at 6 billion attacks, followed by local file inclusion (LFI) with 3.3 billion attacks and cross-site scripting (XSS) with 1.019 billion attacks.

    The report also found credential stuffing attacks reached more than one billion attacks and peaked between January 2021 and May 2021. Distributed denial-of-service (DDoS) attacks reached a peak of 90 in January of 2021.

    Akamai has been making a case for outsourcing the management of web application and API security via the content delivery network (CDN) it created. Its CDN provides a layer of isolation between web-facing applications and the rest of the enterprise. The challenge organizations now routinely face is that, as they move to deploy cloud-native applications based on microservices, responsibility for security has become more decentralized. The security services provided by Akamai create an opportunity to better manage application security via a single pane of glass at a time when there is more focus than ever on securing software supply chains, said Mathur.

    It’s not clear to what degree organizations are going to rely more on managed security services as part of a larger effort to embrace DevSecOps best practices. However, at a time when application security expertise is hard to come by, it’s becoming apparent that, in many instances, relying on an external service provider to secure application environments is the simplest way to quickly improve the overall security posture of any organization.

  • Low-Code and the Rise of the Citizen Developer

    Low-Code and the Rise of the Citizen Developer

    Low-code technologies have become increasingly popular for helping businesses adapt to ever-changing environments quickly by allowing them to build, customize and deploy apps with little to no coding. At Low-Code/No-Code Virtual Summit, taking place on Nov. 18 at 9 a.m. ET, luminaries of leading organizations in the low-code community will share valuable insights on their digital transformation journeys and the role of low-code/no-code in their digital strategies.

    Attendees will get an intimate look at how organizations are embracing low-code technologies to advance their business while improving user experience. The virtual event explores the vast and growing ecosystem of technologies that are changing the face of application development, featuring sessions on:

    • The rise of the citizen developer
    • Security and compliance in low-code applications
    • How low-code is transforming software development
    • Low-code versus no-code
    • Low-code trends

    Low-Code/No-Code Virtual Summit features an exceptional lineup of low-code and industry experts, including:

    • Derya Sousa, co-founder and COO at Kianda Technologies
    • Venkat Thiruvengadam, CEO at DuploCloud, Inc.
    • Andrew Manby, head of product management at HCL Software
    • Asna Javed, hybrid cloud build team and developer advocacy leader at IBM
    • Eren Akbaba, cloud architect at IBM
    • Charles Kolodgy, cybersecurity strategist, advisor and educator at Techstrong Research
    • Daniel Topham, CEM for digital, strategic solution architect at Everbridge
    • Bala Madhusoodhanan, principal architect at TJX
    • Paul Porter, VP of sales engineering at Everbridge
    • Gunndarr Dotter, regional sales director at HCL Software
    • Amy Hart-Koullapis, communications systems specialist, global marketing and communications at World Vision International

    The virtual environment features an auditorium where attendees can watch the sessions by the experts and an exhibit hall lined with booths showcasing the latest solutions from leading low-code companies. In the exhibit hall, attendees can download resources and interact with partner sponsors.

    To start off the event on a high note, we have scheduled a yoga class at 9 a.m. with a certified instructor.

    Registered attendees will receive a link to access the virtual environment on-demand for up to 30 days after the live event.

    To check out the full agenda and to register for free, visit the Low-Code/No-Code Virtual Summit website.

  • Data Theorem Adds Runtime Protection Enabled by Observability

    Data Theorem Adds Runtime Protection Enabled by Observability

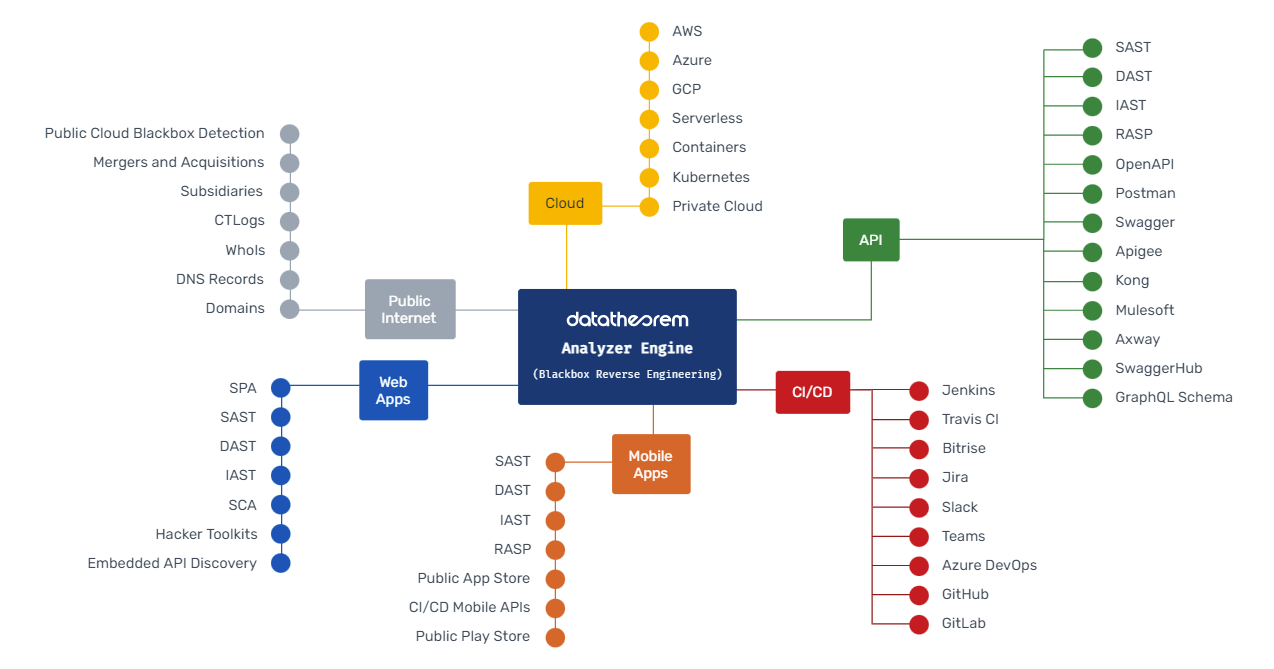
    Data Theorem, Inc. this week added an Active Protection offering to its portfolio of application security services that makes it possible for DevOps teams to embed observability and runtime defenses in their applications via a software development kit (SDK).

    The Data Theorem cloud services are based on Trustkit, an open source framework the company created to make it easier to employ secure socket layer (SSL) to encrypt connections and Analyzer Engine, its runtime analytics engine.

    The company is now extending its services to make it possible to embed observability capabilities by collecting logs and traces. Those logs and traces are then used to enforce runtime security policies that protect applications from known attacks from malicious sources and other common attack vectors as defined by the Open Web Application Security Project (OWASP) Foundation. It also prevents violations of encryption levels, authentication types and authorization rules along with a variety of custom rule checks, including preventing broken object-level authorization (BOLA) attacks.

    Doug Dooley, Data Theorem COO, said Active Protection can be applied across any application stack, including microservices applications based on cloud-native frameworks. In contrast, existing approaches to securing application runtimes based on web application firewalls (WAFs), runtime application self-protection (RASPs) or endpoint detection and response (EDR) agents cannot be applied to cloud-native applications based on containers and serverless computing frameworks.

    Active Protection solves that issue because it is designed to be applied via the Data Theorem software development kit (SDK) or using application extensions made available via a serverless computing framework or as a container sidecar.

    Dooley noted that the Active Protection service is also designed to be fully integrated with DevSecOps workflows that are increasingly being driven via continuous integration/continuous delivery (CI/CD) platforms to enable continuous, automated security inspection and remediation. The company claims to have detected more than one billion application incidents and is currently used by more than 8,000 applications.

    Developers don’t generally set out to build and deploy insecure applications. The issue is most developers don’t have a lot of security expertise, so it’s easy for mistakes to be made. Organizations looking to embrace DevSecOps best practices need to find a way to achieve that goal in a way that developers can easily embrace. The more automated the checks for security issues become during the application development process, the more likely it is developers will make additional efforts to remediate vulnerabilities long before an application is ever deployed in a production environment. In effect, DevSecOps is easier to achieve when addressed from the bottom up rather than via an edict from above without any real implementation plan in place.

    It’s still early days as far as DevSecOps is concerned, but as best practices for DevOps continue to evolve, there may come a day when security is just another gate that needs to be passed within the context of a larger DevOps workflow. In the meantime, DevOps teams and cybersecurity teams should put aside their differences and work together as the number of attacks launched against applications increases.

  • 4 Strategies to Manage Freelancers with In-House Dev Teams

    4 Strategies to Manage Freelancers with In-House Dev Teams

    Remote workers are a growing segment of the global workforce. Freelancers account for a big part of that segment, especially when development teams need to bring in specialized skillsets for upcoming projects. Working with freelancers offers many benefits, but there can also be challenges when integrating freelancers with in-house teams.

    Here are four strategies to help in-house developers effectively manage freelancers in their development teams:

    1.    Keep Remote Workers in the Loop

    Don’t leave freelancers and remote workers in the dark about your overall business direction and goals. If a freelancer is only joining the team temporarily to handle one part of a project, it might not seem necessary to give them the full details about the project’s goals and the reasons behind your decisions.

    However, providing this information enables every member of the team to fully understand what you need from the products and features they are working on and how they will serve the end user. It also helps to create common goals and motivations that the team can work toward together, rather than keeping your remote workers’ tasks separate from other members of the development team.

    2.    Make Consistent Feedback a Priority

    In an OfficeVibe survey, 96% of employees said they wanted to get regular feedback from their managers, but 32% said they receive feedback less than once every three months. Freelancers and remote workers arguably need more feedback than in-office employees, for several reasons.

    Freelancers and remote workers are often less exposed to the wider business context in which they are developing products and features. This can make it harder to assess and optimize their output from the viewpoint of an end user. Just as importantly, it can make it less clear what the other members of the team are working on and how their output affects their colleagues’ work.

    “Without consistent feedback, even the most talented developers in a team can invest a lot of time in a non-feasible solution. An ongoing feedback loop is one of the best ways to support a team and enable them to put their skills to use,” said Irene Avdus, a product manager at TextMagic, which has offices in multiple countries and which regularly brings on freelance talent.

    Giving freelancers and remote workers consistent and regular feedback doesn’t just help them improve their output for a better end result. It also helps them to fit in with the workflow of the rest of the team, enabling the project to go more smoothly for everyone.

    3.    Provide Growth Opportunities

    “Great leaders invest in their employee’s career development and steer them from being a one-trick pony,” said Phidelia Johnson, Pac-J Investment Services executive director of HR.

    When it comes to upgrading a team’s skillset, companies tend to skip over freelancers and remote workers in favor of employees they see as more permanent. However, opportunities to develop skills and advance their career are just as important to remote workers and freelancers as they are to any other employee.

    As a result, the perception of remote workers and freelancers as more temporary team members can be a bit of a self-fulfilling prophecy. When companies don’t invest in developing employees’ skills outside of their in-house teams, it is to be expected that remote workers will move on after the project is done to advance their careers.

    Often, treating remote workers as temporary doesn’t result in any less training, anyway. Whenever you add a new freelancer to your development team, there will be a certain amount of training and onboarding necessary to get them up to speed with how your team works. In fact, this can often be a major time and resources investment

    “In a lot of situations, the biggest challenge of working in data engineering or BI is not learning technology X or Y—it is being able to pick up quickly all the business rules and processes of the department you are building your pipeline or dashboard for,” said Mohamed Khalil Ouachikh, ArmedAngels data engineer and BI specialist.

    Rather than spending time onboarding new remote workers with each development cycle, investing in upgrading and expanding the skills of current team members and freelancers can result in a more capable team that is already familiar and comfortable with your business and the needs of your clients.

    4.    Informal Team Meetings

    Making people feel like part of a team is important to ensure they can collaborate and coordinate effectively with other members. Both of these factors are crucial to developing any successful product.

    Why is this relevant to managing freelancers in your development team?

    Remote workers don’t have the same opportunities to connect with colleagues as in-house employees unless you provide them. As many as 20% of remote workers say they feel isolated from their colleagues. This can take a toll on their emotional well-being, and that lack of social connection to coworkers will also affect their ability to collaborate.

     As a result, they may not be able to communicate as effectively with other team members. Building connections between team members let them understand each other more easily and reduce miscommunications that could lead to development mistakes and delays.

    Informal meetings via webinar platforms or video conferencing solutions can have a significant positive impact in this area. A weekly meeting gives everyone a chance to talk about what they are working on and their challenges. As a result, every team member, including freelancers, has the chance to lend their skills to a colleague’s work and help the team pull together toward achieving a common goal.

    Just as importantly, it gives remote workers a much-needed opportunity to connect with their colleagues socially and chat about things other than work. Besides the importance of team-building, this develops more of a connection between remote workers and your business. Inviting freelance developers to all meetings and social events is a great way to ensure greater inclusivity, and it can pay off if freelancers later take full-time positions at the company.

    Make Freelancers Part of the Team

    Keeping freelancers in the loop and ensuring they have the same opportunities and voice as other employees ensure they have the same level of investment in a project’s success as every other member of the team. The tools and the opportunity to coordinate with colleagues and receive feedback are critical parts of this. Following these strategies will help you integrate and manage your freelancers more effectively.


  • Observability Matters. But Are You Observing the Right Things? 

    Observability Matters. But Are You Observing the Right Things? 

    It’s like clockwork. Every few months, a new buzzword descends on the tech industry, and soon it’s on everyone’s lips. Take your pick from the graveyard of buzzwords past: “Big data,” “internet of everything,” “hacktivism,” “gamification.” It’s not that these terms are meaningless—just that they go from relatively obscure to ubiquitous seemingly overnight. We can add a new one to the list in the digital monitoring space: “Observability.”

    Unlike some trendy buzzwords, observability captures something that’s actually quite important about how we monitor digital systems and how current approaches differ from those of the past. So, it’s a good and useful concept. But where I take issue is with the way many analysts, technologists and vendors seem to use it. Whether or not they mean to, they often paint a far too narrow a picture of what observability is or ought to be, and that linguistic oversight can have real-world consequences. If enterprises invest in observability without understanding what, exactly, they’re observing—and what they’re not—they risk leaving themselves vulnerable to some serious blind spots. 

    What is Observability and Why Does it Matter?

    Technically, observability is an approach with the goal of understanding how a system is doing. The distinction lies in what the system is and how it is being observed. The monitoring tools of yesterday typically focused on one or more domains to identify typical and known problems. Usually, that entailed collecting metrics directly from those domains and measuring them against predefined thresholds. For example, storage levels shouldn’t exceed a certain threshold; if they do, send me an alert so I can investigate what’s happening. 

    On the other hand, observability takes a more holistic approach, examining multiple outputs of the system to infer system health. For example, suppose you were trying to gauge a car’s condition. In that case, traditional monitoring might track engine temperature or idle speed RPMs, while observability would examine things like power output, engine leaks, transmission noise, emissions and fuel efficiency to infer the car’s overall health. 

    This output or outcome-focused approach to managing performance maps well to today’s complex and distributed digital systems. Even if you wanted to, you couldn’t pull real-time metrics from every relevant component of a system when those components consist of thousands of microservices running in any number of physical servers across multiple clouds. However, the bigger problem with more antiquated monitoring models is that they only capture the specific metrics they’re designed to track. If you’re encountering a problem you’ve never seen before, your monitoring dashboard might look perfectly healthy while actual system performance is terrible. 

    Observability and APM 

    So then, observability should give you everything you need to track the health of a modern digital business, right? Well, not so fast. Because for today, people seem to use “system observability” interchangeably with “application performance monitoring,” or APM. And they are not at all the same. 

    Yes, you want an observability-based approach to tracking your application environment, and modern APM tools provide a great way to do it. But knowing the health of your application environment is not the same as knowing the health of your overall digital systems as experienced by users. And at the end of the day, if you’re not gauging performance from your users’ perspective—whether that’s customers, employees or other devices relying on your systems—then what’s the point? It’s unfortunately not uncommon to forget that the most important key performance indicator (KPI) of any digital system is the quality of its intended output or outcome. In the case of any application, the most important KPI is the user experience.

    The outputs that APM tools track do contribute to the user experience—and you want to be monitoring them. But so do many, many other things. There’s the user access itself (browsers, virtual or physical user devices loading the application). There are local, regional and global networks connecting those users to your application environment. And then, of course, there are the dozens, sometimes hundreds of third-party digital services running between and among users and applications. Problems in any link of that digital chain can seriously impact the user experience—even if your application environment itself looks healthy. 

    Observing End-to-End, from User to App and Everything in Between 

    To get the full picture of the health and performance of your digital assets, you should be tracking outputs from across the end-to-end digital service chain. That includes telemetry (logs, infra metrics, traces) from your application hosting environment. It should include actively and passively observing at the point of consumption—that is, outputs from customer browsers and worker devices. It must include active and passive monitoring of network connectivity. And it should include continuous active monitoring of all the disparate services—APIs, content delivery networks (CDNs), DNS services, cloud-based security services and every other cloud and web service that contributes to what the user is experiencing. (And by the way, you should look for independent, objective telemetry whenever possible rather than taking what your various service providers report at face value.) 

    When you approach observability from this outcome-based, holistic perspective, you can capture a real and truthful picture of the performance of your full digital business, not just pieces of it. Just as important, when you do identify a problem, you’re in a much better position to do something about it. Because now you have outputs to measure from all the many systems and services that contribute to the user’s application experience instead of just a subset of them, which means it’s much easier to zero in on which piece of the puzzle isn’t behaving the way it should. 

    A Smarter Approach to Observability

    So, should you take all the hype about observability seriously? Yes. As tech buzzwords go, you could do a lot worse. This one actually means something important. But make sure you’re keeping the big picture in mind as you do. 

    Observability that ignores the outcome begins and ends with the application environment and is nowhere near sufficient. We need to expand our sense of observability, begin with the user experience and encompass every link in the chain of the end-to-end digital business. When we do, we create a much more holistic, useful and actionable picture of the health of our digital systems. And we can make sure we’re continually monitoring digital performance in the way that matters most: As experienced by users.