Category: DevOps Practice

  • DevOps Teams Struggling to Keep Secrets

    DevOps Teams Struggling to Keep Secrets

    A growing number of organizations are suffering security incidents related to exposed secrets in DevOps CI/CD pipelines, according to a recent ThycoticCentrify report.

    The study paints a troubling picture: Only 5% of survey respondents said most of their development teams use the same secrets management processes and tools.

    The incidents run the gamut, from secrets published in the clear in public cloud code repositories to insecure third-party code to vulnerabilities in the organization’s own code or configurations.

    The problem is often made worse by security teams not knowing what to protect because development teams have their own cloud infrastructure or the ability to create internet-facing applications directly without security teams’ knowledge.

    “The reason why we see so many security incidents related to exposed secrets in DevOps is that using hardcoded passwords and keys is the easy path to getting things to work,” said Joseph Carson, chief security scientist and Advisory CISO at ThycoticCentrify. “We need to make it just as easy for DevOps to use secrets vaults so even when secrets get compromised they are no longer usable, valid or expired.”

    Carson said moving away from persistent privileges to just-in-time, on-demand privileges will reduce these types of misconfigurations and attacks.

    “Unfortunately, many developers continue to use hardcoded passwords or static keys that, when compromised, allow an attacker to gain control of the application resulting in either data exposure, ability to change the application configuration or move laterally around the network,” he added.

    John Bambenek, principal threat hunter at Netenrich, said the fundamental problem is that when organizations go to agile and DevOps, they remove all friction to moving code quickly—and that almost always includes removing security.

    “That means security is inherently reactive instead of being embedded into engineering, and that’s assuming security even knows what to protect in the first place,” he said. “It’s the natural consequence of removing security from the equation and expecting that it’ll just work on the backend. That approach hasn’t worked for decades; a JIRA board isn’t going to suddenly fix that problem.”

    From Carson’s perspective, secrets management is the ability to move away from hardcoded passwords or static keys to just-in-time privileges or one-time-use passwords so even when comprised they cannot be used.

    “Many privileged access management solutions that protected privileged access for years have extended functionality to developers to help move the value into DevOps so they can manage credentials for applications, databases, CI/CD tools and services without causing friction in the development process,” he said.

    Approaches like privileged access security helps enable API-as-a-service and provides instant availability of secrets, SSH keys, certificates, API keys and tokens.

    Secrets Management

    Bambenek added the problem isn’t choosing a secrets management process or tool, but rather that they aren’t in place at all.

    “Pick something that will keep keys and secrets out of public cloud repositories that developers will use that allows for quick and easy rotation of keys as the need arises,” he said. “The most important thing is that it’s the same tool everywhere that operates in a near-invisible process for developers. Four decades of software vulnerabilities have taught me that if you rely on the developers to do the secure thing, you’ll consistently be disappointed.”

    One Wrong Step

    Davis McCarthy, principal security researcher at Valtix, pointed out developers are not security practitioners by trade.
    “Developers are building new ideas, and no good idea comes without experimentation,” he said. “Experimenting with a new technology stack may lead to misconfigurations that unintentionally expose data.”

    McCarthy said shared SSH keys between users create a larger attack surface, and users will store secrets differently creating multiple attack vectors.

    If one user’s endpoint becomes compromised and their SSH keys are exfiltrated, it’s difficult to know what the first mitigation steps are. Between insider threats and malware, the wrong step could lead to a breach.

    “Whereas a software engineer may hold great knowledge of secure coding methodologies, web application attacks and encryption, they are still focused on executing their craft,” he said. “Organizations that do not build security into the development life cycle create a systemic risk that leads to failures in best practices.”

    McCarthy added organizations can centralize and embed secrets management into the tools already in use in CI/CD pipelines by creating an inventory, auditing it and frequently rotating secrets to sensitive environments.

    Bambenek said the short answer is to make sure the infrastructure of CI/CD pipelines is centrally managed and controlled without the ability of engineering teams to ‘roll their own.’

    “No security control will remain intact if someone can pick their own tools without any real governance,” he said. “CI/CD processes don’t require engineering teams to manage the backend of the deployment pipeline which means someone can ensure those functions are in place to begin with.”

  • Ensuring Network Connectivity With SD-WAN and AIOps

    Ensuring Network Connectivity With SD-WAN and AIOps

    Recently, Facebook experienced an outage. If companies relied on that app to do business, their IT teams were likely swamped with end-user complaint calls. 

    How would teams traditionally respond? They’d dive deep into the rabbit hole, analyzing issues on a case-by-case basis, asking countless questions, including: 

    • Could there be a problem with the enterprise network?
    • Is the service provider experiencing issues?
    • Are just a few users affected or is the issue more systemic?

    Traditionally, this manual process requires significant knowledge sharing and time to complete as teams break the problem into smaller pieces to triangulate an issue’s root cause.

    Oftentimes, it’s an enterprise network that experiences connectivity issues—not apps like Facebook. 

    Some companies pay an arm and a leg to leverage highly reliable WAN links, such as MPLS, for connecting to the internet and connecting branches to their data centers. Conversely, they may save a buck or two by using commodity links, like cable or DSL, which deliver less reliability. Both choices introduce tough tradeoffs—could there be a better way to ensure enterprise-wide connectivity?

    Enter SD-WAN. 

    Combining the same service-level agreement (SLA) as a dependable WAN link with the affordability of a commodity link, SD-WAN specializes in handling brownout situations, rerouting link traffic to maintain network connectivity — ensuring users’ access to their must-have apps. 

    And by incorporating artificial intelligence for IT operations (AIOps), teams can harness the power of analytics to radically reduce their response time, ensuring that if problems do happen, they get fixed fast. In fact, 90% of IT professionals acknowledge that powering network management with AIOps will improve their companies’ business outcomes.

    Drowning in Data: Understanding Traditional Network Issue Investigation Headaches

    To determine the root cause of a service disruption, teams spend considerable time assessing the landscape of all the different apps that people use and the links they follow to use them. These apps could be located anywhere—forcing teams to find needles across vast haystacks of data to determine what went wrong.

    And this data is exploding at such an extraordinarily high rate that it’s practically impossible for anyone to keep track of it all. Only by leveraging an advanced analytics system like AIOps can teams gain the necessary insights to swiftly solve problems. 

    SD-WAN and AIOps: A Problem-Solving Dream Team

    How do SD-WAN and AIOps work together to enable a highly reliable, always-connected network?

    SD-WAN quickly addresses all potential local issues and optimizes performance and connectivity across multiple WAN links—or even just a single WAN link that may be unreliable. SD-WAN also ensures that business-critical apps are prioritized correctly and are offered the precise amount of error correction that avoids any issues or disruptions as much as possible over the WAN. 

    Where does AIOps come into play? It analyzes data at a far more granular level for extended periods over a global topology. What is it looking for? Everything. It’s examining emerging patterns that are impacting individual apps. It’s searching for systemic issues that affect multiple SD-WAN edge devices simultaneously, worldwide. It could also be investigating how edges or apps are being affected over a particular time period. 

    By surfacing all that data, AIOps analyzes much more than SD-WAN can. And by deriving insights from that data, it highlights issues affecting everything from a lone user on a single application to a systemic issue that’s impacting an app across a far broader cohort of users. In certain cases, AIOps can cue the SD-WAN to heal itself and automatically fix the problem, then verify that the issue was fixed. As a result, end-users remain connected to their network.

    Inside a Wholly Adopted SD-WAN/AIOps Environment

    Imagine you’re an IT admin, supporting an extremely complex enterprise network, spanning thousands of different sites that use diverse security services for connecting to apps. Even if you’re on a huge team that’s charged with monitoring the network, it would be nearly impossible to have full visibility across the network to solve problems as they occur.

    By adopting SD-WAN together with AIOps, you gain a superpower. No, you won’t be able to fly or become invisible, but AIOps will make you omniscient, enabling you to:

    • Harness powerful analytics firepower to find and fix network trouble spots instantly and precisely before users complain—in some cases before they even notice
    • Understand which sites perform better than others to pinpoint where improvements can be made
    • Propose configuration changes that help the network self-optimize and self-heal
    • Detect and optimize degraded links to boost user experience

    And if issues ever do arise, AIOps advises you immediately as it monitors the network 24/7, providing you with full situational awareness and insights, solving problems as they occur.

    SD-WAN & AIOps: Maintaining Connectivity by Self-Healing

    The Facebook event was unusual in that it globally impacted the world’s users, who couldn’t access the app through any Facebook data center. In that scenario, AIOps simply identified the app disruption and noted the root cause.

    But what if the situation had been different? For example, imagine if Facebook’s U.S. west coast datacenters were deemed unavailable but its east coast datacenters were operational. By combining SD-WAN with AIOps, a similarly affected company could have performed diagnosis and ensured app connectivity. 

    How could that have played out? 

    First, AIOps would have detected the issue and its root cause. It would have reported that the application was unreachable to users on the west coast but available to users on the east coast. Finally, SD-WAN would have self-healed by rerouting end-user application traffic to the eastern data centers to maintain app connectivity.

    Using the old-school method of manually monitoring and troubleshooting networks is nearly impossible for most IT teams. Instead, teams are relying on SD-WAN and AIOps. This combined capability gives teams an unbeatable superpower, enabling them to substantially improve connectivity across the enterprise and rapidly respond to issues as they occur.

  • Rethinking Programmer Education for Today’s Coders

    Rethinking Programmer Education for Today’s Coders

    The proliferation of low-code and no-code applications are changing the landscape for software. In the past decade, growth in these areas has empowered employees to generate solutions at the speed of a digital world, regardless of their technical background.

    This raises several questions: What kind of programmers do businesses really need? Should they still rely on programmers formally trained at four-year universities—what you might call “white-collar” programmers? Or, instead, are blue-collar programmers with self-taught skills or those who learned from a bootcamp more valuable? What will get organizations the right mix of programming skills?

    The short answer is that all programmers can be of great value. In general, blue-collar programmers, after all, connect things within the computing environment, while white-collar programmers create the things that are connected. The essence of low-code is that it allows more people to connect things and use their creativity to become more productive. But it doesn’t eliminate the need for professional programming and tools at its foundation.

    At their core, low-code and no-code are about democratization. They allow people without technical skills to work creatively in ways that essentially make everyone a programmer. A parallel from an earlier computing generation is the Excel spreadsheet, which lets people with no programming background perform computational tasks and eventually work their way up from simple formatting to full-fledged programming. But at some point, polished programming skills are still necessary, no matter how easy no-code or low-code can make some of those elements.

    In the breakneck pace of cloud-based computing environments with new services constantly being developed and deployed to the edge, it’s worth considering the distinctions between the white- and blue-collar programmers and what kinds of education are appropriate for each.

    Four-Year Colleges Vs. Boot Camps

    A career as a programmer can seem intimidating for onlookers. This is particularly true when these jobs involve complex languages such as C++ and Java, which are often used in large projects that can take years to develop and involve millions of lines of code. Some of that is still true, but the evolution of programming over the years toward languages that require less code, such as Python, and to domain-specific languages (DSLs), has also started to lower the barriers to entry for programming.

    It’s true that you’ve never needed a four-year computer science degree to be a programmer. In fact, many that have dropped out of college—or never attended at all—have made significant contributions to the industry. However, universities do provide a foundation in theory and algorithms that have always served programmers well and enable them to branch out into new areas, such as artificial intelligence or other disciplines, such as bioinformatics. Coding bootcamps, for their part, can provide intensive training on DSLs or frameworks like Rails or React.js that can benefit companies’ plans, giving blue-collar programmers the practical skills that white-collar programmers may not have. They also attract career-changing attendees with four-year degrees in other subjects, including the humanities and the sciences, which brings badly needed new ways of thinking into the profession.

    While each method is valid, both four-year institutions and bootcamps also have their shortcomings. Universities delve deep into software development theory but often don’t emphasize critical aspects of doing the job, such as teamwork, testing and agile processes. Nor do they focus much on core areas of businesses today, like cloud computing. Boot camps, by targeting specific areas and emerging technologies and languages, can help people get internships or entry-level jobs, but don’t provide a broader theoretical knowledge of programming. And they can be hit-or-miss, with some of them using sketchy practices for payments and job placement.

    The inherent weaknesses in both white- and blue-collar training can be addressed through apprenticeships and internships, but only to a point. The question remains: Who will train low-code programmers on modern development and coding practices? A lot of companies throw around terms like Agile and CI/CD, but they’re often just new labels on old, inefficient practices. Companies will need white-collar programmers to bring blue-collar programmers up to speed.

    Programming for the Masses

    No-code software is a great enabler, allowing people with no formal education or experience to become proficient in a programming environment. On the other hand, for people who do have formal training—whether a formal education or boot camp experience—low-code simplifies their work, leaving time to focus on more complex projects. But programmer or not, users of no-code and low-code solutions need to understand more than just deployment and testing if they want their software to be reliable and useful.

    Professional developers can make a difference by creating and maintaining the pipelines used to build, test, archive and deploy low-code software; they will need to build new tools to accommodate low-code frameworks. And while familiarizing themselves with current development techniques, they could become the teachers of essential computing practices that don’t involve coding.

    A cooperative, productive relationship between white-collar and blue-collar programmers is essential to moving forward with software development, as it will allow both to continue acquiring new skills and experience outside of low-code, which is only a product of programming, no matter how ubiquitous it may be.

    Making the Connection

    Today, we’re entering a business world where practically everyone will need to code, making low-code and no-code frameworks necessary, especially for users without formal training. However, the importance of professional programmers will remain, too.

    We’re likely to see a proliferation of DSLs created to solve specific problems, which will eventually evolve toward general-purpose programming languages. Programmers will need to build web frameworks, cloud capabilities and more, including everything from web widgets to the high-level tools that let users work. That may be the only way we can begin to meet the demand for more people who can program as more devices come online, more connections are made and the world becomes increasingly reliant on automation.

  • How to Build Healthy Engineering Teams

    How to Build Healthy Engineering Teams

    A common challenge today for engineering teams is the increasing complexity of their jobs and figuring out how to make it both productive and enjoyable without burning out.

    Over the last 10 years, the role of a software engineer has evolved drastically. Software continues to reach unprecedented scale, it is becoming more complex and customer expectations are higher than ever. Organizations from all industries are now becoming software companies and, with the pandemic, everyone is feeling the effects of burnout.

    There are close to a million unfilled IT jobs in the United States. To ensure organizations are able to continue innovating, the industry needs the tools, state of mind and reliable practices to make this career sustainable.

    Creating an industry with healthy productivity is paramount. But too much of a focus on going faster without addressing burnout is a recipe for disaster. Engineering managers need to constantly balance both. Here are some things they should keep in mind:

    Invest in Engineering Productivity

    Companies are increasingly hiring for roles focused on engineering productivity—there are currently hundreds of open job postings from organizations looking for these skills. These jobs are aimed at making developers and engineers’ lives and work easier by focusing on streamlining how things are done within the engineering organization—including improving developer workflow processes, execution efficiency and product quality. They are often responsible for building internal tools that support cross-functional and developer workflows. Even with a relatively small engineering team, organizations can start thinking about bringing on a team member dedicated to making engineers’ roles within the company easier.

    Focusing on Healthy Productivity

    Productivity is, and will always be, extremely important, but potential burnout should also be seriously considered in the process. Remote work during the quarantine and the pandemic has brought this front and center. When people don’t have enough deep work time, they often work longer hours which can eventually lead to burnout. An average employee has 11 minutes to focus between distractions at work and then, after an interruption, it can take around 23 minutes to return to the original task. In addition, the average worker attends 15 meetings per week.

    There are many questions about how workers’ productivity has been impacted since early 2020, and research has found that developer productivity isn’t a problem—but burnout is. From March to December 2020 the study found:

    • Deep work time—a two-hour period of uninterrupted work—decreased by 22% between March and December 2020.
    • Average time in meetings went up by 67% from March to December 2020.
    • Pre-pandemic, 10% of developers were showing “always-on” behaviors at work, but that percentage went up to 15% and then to 20% by the end of the year.

    Focusing on driving healthy productivity—where developers are productive but not overworked—is key to keeping your employees.

    Strengthening Engineering Managers

    Managers play a key role in keeping engineering burnout in check. Ensuring that managers ‘manage well’ is not a new idea, but today there are particular complexities that make the engineering manager role both uniquely challenging and especially important.

    It is now widely acknowledged that culture is a considerable part of what gets employees to stick around. But culture isn’t only employee benefits like trendy offices, great snacks and other relatively superficial—though still important—benefits. What really matters is identifying and building teams that really care about one another on a personal level and making sure that incoming employees feel the same.

    With engineering teams, there is a tendency to focus primarily on the technology being created rather than the people who are creating it. While this approach can absolutely result in successful products, it is often the default management style for managers who don’t have the tools to do otherwise. Moving from software engineer to manager requires a whole new skill set that involves different communication styles, time management, organization, tools and software, scoping work, learning how to effectively delegate and identifying the right people to complete the team.

    As challenges continue to evolve, organizations need to ensure that engineering managers are able to support each individual on their team. It is so important to make sure that people feel aligned with a mission they care about and that their career interests and goals are being met. Not all of those can be measured with data, so managers have an all-important role in keeping up with the pulse of the team.

    Building Helpful Tools and Growing Developer Communities

    In the last decade, the speed of innovation in enterprise technology has skyrocketed and the amount of code and tools developers need to master has increased. At the same time, the number of unfilled job openings continues to grow. There are a lot of great trends that are helping to close this gap including low-code and no-code tools as well as a massive increase in community resources.

    No-code/low-code tools: As both technical and non-technical organizations hire an increasing number of developers, low-code and no-code have become more prevalent. With frameworks that allow even those without a technical background to deploy software, no-code tools open development capabilities to an increasingly diverse subset of people. While these tools will not replace developers, they will make it possible for more people to enter the field of software development and help companies continue to innovate.

    Developer community: The amount of resources available to new and existing developers has also skyrocketed in the last several years from open source communities to Stack Overflow to the ability to simply Google how to do something in code. The Linux Foundation’s extensive training catalog is one example; even Medium has a wealth of basic technical info, how-tos and deep dives available. If you’re looking to adopt a new tool, one of your main priorities should be to look at the size of the community so that you can easily troubleshoot problems if they arise. Having access to resources from community members that have gone through the exact same problems you encounter is priceless.

    The above are all just a start. Teams can go even further by finding and adopting analytics tools to dive deeper into specific productivity metrics. These can give managers and executive teams the hard data they need to make educated decisions that will help them keep their teams and drive innovation. It is worth investing the time and the tools to maintain your engineering resources. By doing these things, organizations can reach and maintain healthy productivity.

  • Nvidia/ARM Wavering | Google Outage Outrage | Backblaze IPO on Fire

    Nvidia/ARM Wavering | Google Outage Outrage | Backblaze IPO on Fire

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    Nvidia Can’t be Allowed to Buy Arm

    First up this week: Nvidia’s faltering attempt to buy Arm: Regulators around the world are alarmed by the idea. And now the UK—the legal home of the company—has taken the next step, which could nix the deal.

    Analysis: RISCy home for ARM

    This matters because ownership of the ARM ISA and the core designs would be a huge strategic stick to beat Nvidia’s competition with. Arm doesn’t make chips—it licenses technology to Nvidia and many of its competitors—AMD, Apple, Broadcom, Samsung and Qualcomm, to name but five. So this deal really shouldn’t go through, regardless of Nvidia’s fluffy PR reassurances.

    ARM chips aren’t just found in 99% of smartphones, but are an increasing fixture in the datacenter—especially where “performance per Watt” is important. They’re even found in exascale iron, including the Riken Fugaku, the world’s fastest supercomputer.

    Helen Thomas: Nvidia faces tough Arm wrestle

    It is one thing for a regulator to give your deal a thorough going-over. It is another for it to imply publicly that your assurances [aren’t] credible. … Nvidia got both from the UK’s Competition and Markets Authority. … The CMA’s full phase 1 report doesn’t make for easy reading.
    …
    The transaction, which was announced in September 2020, is bogged down in regulatory reviews around the world: … Arm’s “neutral” business model has always made it a difficult acquisition. … Arm licenses its designs to other chipmakers, providing scope to restrict rivals’ access.
    …
    Arm was a political talking point in 2016, when its sale to SoftBank … was waved through with embarrassing ease. There is now a much more muscular political take on UK national security concerns with a particular focus on tech.


    But if it’s owned by a Japanese company, why is the UK getting involved? Glad you asked—Aighearach answers:

    What did they buy? Shares of a UK company. … Then it is a UK company! … Buying shares is buying ownership, but it doesn’t move the company to another jurisdiction.
    …
    This blathering about “sold to a Japanese firm” is getting old.


    Nvidia claims, “The transaction will … boost competition and innovation.” Falmari finds that hilarious:

    Did Nvidia’s spokesperson previously work as a stand-up comedian? Because as jokes go, “boost competition” is a whopper. [Do you think] that’s what a company like Nvidia wants—to boost the competition?


    Google Cloud Outage has Ripple Effect

    Google’s load balancers all went offline for two hours on Tuesday. Aside from the knock-on Google Cloud failures, DevOps tools such as BigCommerce, Datadog, Deno, Discord, Egnyte, Evernote, Linear, Netlify and Toggl were reported to be affected. But perhaps the worst impact was felt by the poor, unfortunate users of Pokémon GO.

    Analysis: Paralysis

    In theory, putting all your eggs in one basket is okay—so long as that basket can reliably stop your eggs smashing on the pavement. But this isn’t the first time we’ve seen Google Cloud issues such as this; I can’t imagine it’s the last.

    Steven J. Vaughan-Nichols: Google glitch triggers major internet outage

    The result? Many of us have seen 404 errors when trying to get to some of our favorite web pages. … There appears to be more major sites having problems than not.
    …
    The specific problem seems to be with the GCP load balancers. These, working with Google’s Cloud Delivery Network (CDN) [are] designed to stop website failures and Distributed Denial of Service (DDoS) attacks by putting your website behind a single anycast IP.


    Are you feeling a touch of déjà vu? jeffbee, too:

    This is a sort of repetitive outage for Google. They’ve wiped out the GSLB configs before.

    A year ago there was also that big outage where they blanked out the whole Gmail delivery config and started rejecting all mail. … Config safety is not their strong suit.


    The #3 IaaS provider won’t get to #2 if it keeps this up. Here’s u/totopapa:

    I’m trying to convince my company to switch from AWS to GCP but an outage like this one is definitely a showstopper.


    Backblaze IPO Burns Brightly

    Backblaze is now NAS:BLZE. In its first week, the stock jumped 60%.

    Backblaze is well known for its tiny-margin consumer backup product and its open-source “storage pod” hardware—but is less well known for its DevOps-focused “B2” cloud storage service.

    Analysis: Can it Avoid Death-by-Packrats?

    Backblaze is trying to grow this newer DevOps business, without losing its classic consumer chops. But many of its former competitors have essentially dumped their “unlimited” offerings—it’s the old tragedy-of-the-commons problem.

    Jordan Novet: Backblaze [goes] public on small valuation and minimal funding

    In an era of blockbuster market debuts preceded by astronomical private financing rounds, Backblaze … a cloud service for backing up data … is a throwback to a time when sub-billion-dollar companies routinely went public to raise capital and build their profile … to win the trust of customers.
    …
    Backblaze shares climbed 24% in their debut on Thursday and another 12% on Friday, lifting the price to $22.31 and giving the company a market cap of around $650 million. … By the standards of its peers, Backblaze is a micro-cap.
    …
    One of Backblaze’s competitors is Amazon, the world’s fourth most valuable U.S. company. … Backblaze currently stores two exabytes of data — that’s 2 million terabytes — and has a half-million paying customers.


    Donovan Jones: Backblaze Targets $100 Million IPO

    The firm provides cloud-based storage services to small businesses and individuals worldwide. BLZE has grown revenue and gross profit impressively through the 2020 pandemic period and the IPO appears fairly valued, so is worth a close look.
    …
    The firm’s financials show strong revenue and gross profit growth. … The firm’s dollar-based net revenue retention rate for 2020 was 114%—a solid result. … The market opportunity for providing cloud-based storage services to small businesses and individuals is large and expected to grow at a material rate. … As for valuation, compared to partial competitor Dropbox, management is seeking the same Enterprise Value/Revenue multiple. [However] the combined revenue growth rate and EBITDA percentage rate … was 3% as of June 30, 2021, so the firm needs improvement in this regard.


    But there’s a long way to go, opines John Kozubik (aka rsync):

    Of the ~500,000 customers, 70,000 are B2 customers and 430,000 are “backup” customers—which are flat-rate “unlimited” users. … Roughly 85% of the user-base are paying $7/mo for “unlimited backup.”
    …
    These flat-rate users are very fickle and price-sensitive. … Roughly 85% of the user-base are paying $7/mo for “unlimited backup.” … It’s a fools errand to pursue this market and I assume the pivot to B2 was to build something more sustainable with a much higher price and usage ceiling.


    The Moral of the Story: Success is a journey, not a destination


    You have been reading The Long View by Richi Jennings. You can contact him at @RiCHi or tlv@richi.uk.

    Image: Kristin Wilson (via Unsplash)

  • Cortex Expands Microservices Catalog to Improve Collaboration

    Cortex Expands Microservices Catalog to Improve Collaboration

    Cortex, a provider of a catalog for tracking the ownership of microservices, today announced it has added a service creation capability that enables developers to use templates to scaffold new services in five minutes.

    In addition, the company has added a Cortex Teams offering that improves collaboration across teams of developers working on interdependent microservices.

    Fresh from raising an additional $2.5 million in funding, Cortex claimed it has increased its customer base by a factor of 10 since initially launching last May. Those customers include Rappi, Grammarly and 8×8.

    Cortex CTO Ganesh Datta said the company’s microservices catalog makes it simpler for teams of developers, DevOps engineers and security professionals to collaborate at a time when software development is becoming more complex. While microservices-based applications are easier to update and generally more resilient than monolithic applications, composing an application based on interdependent microservices created by different development teams can be more challenging to build and maintain.

    In some cases, organizations can even discover that different teams within their organization have built redundant microservices. Part of the reason that occurs is many IT teams still rely on spreadsheets to keep track of what microservices are being built and which ones are already deployed in a production environment.

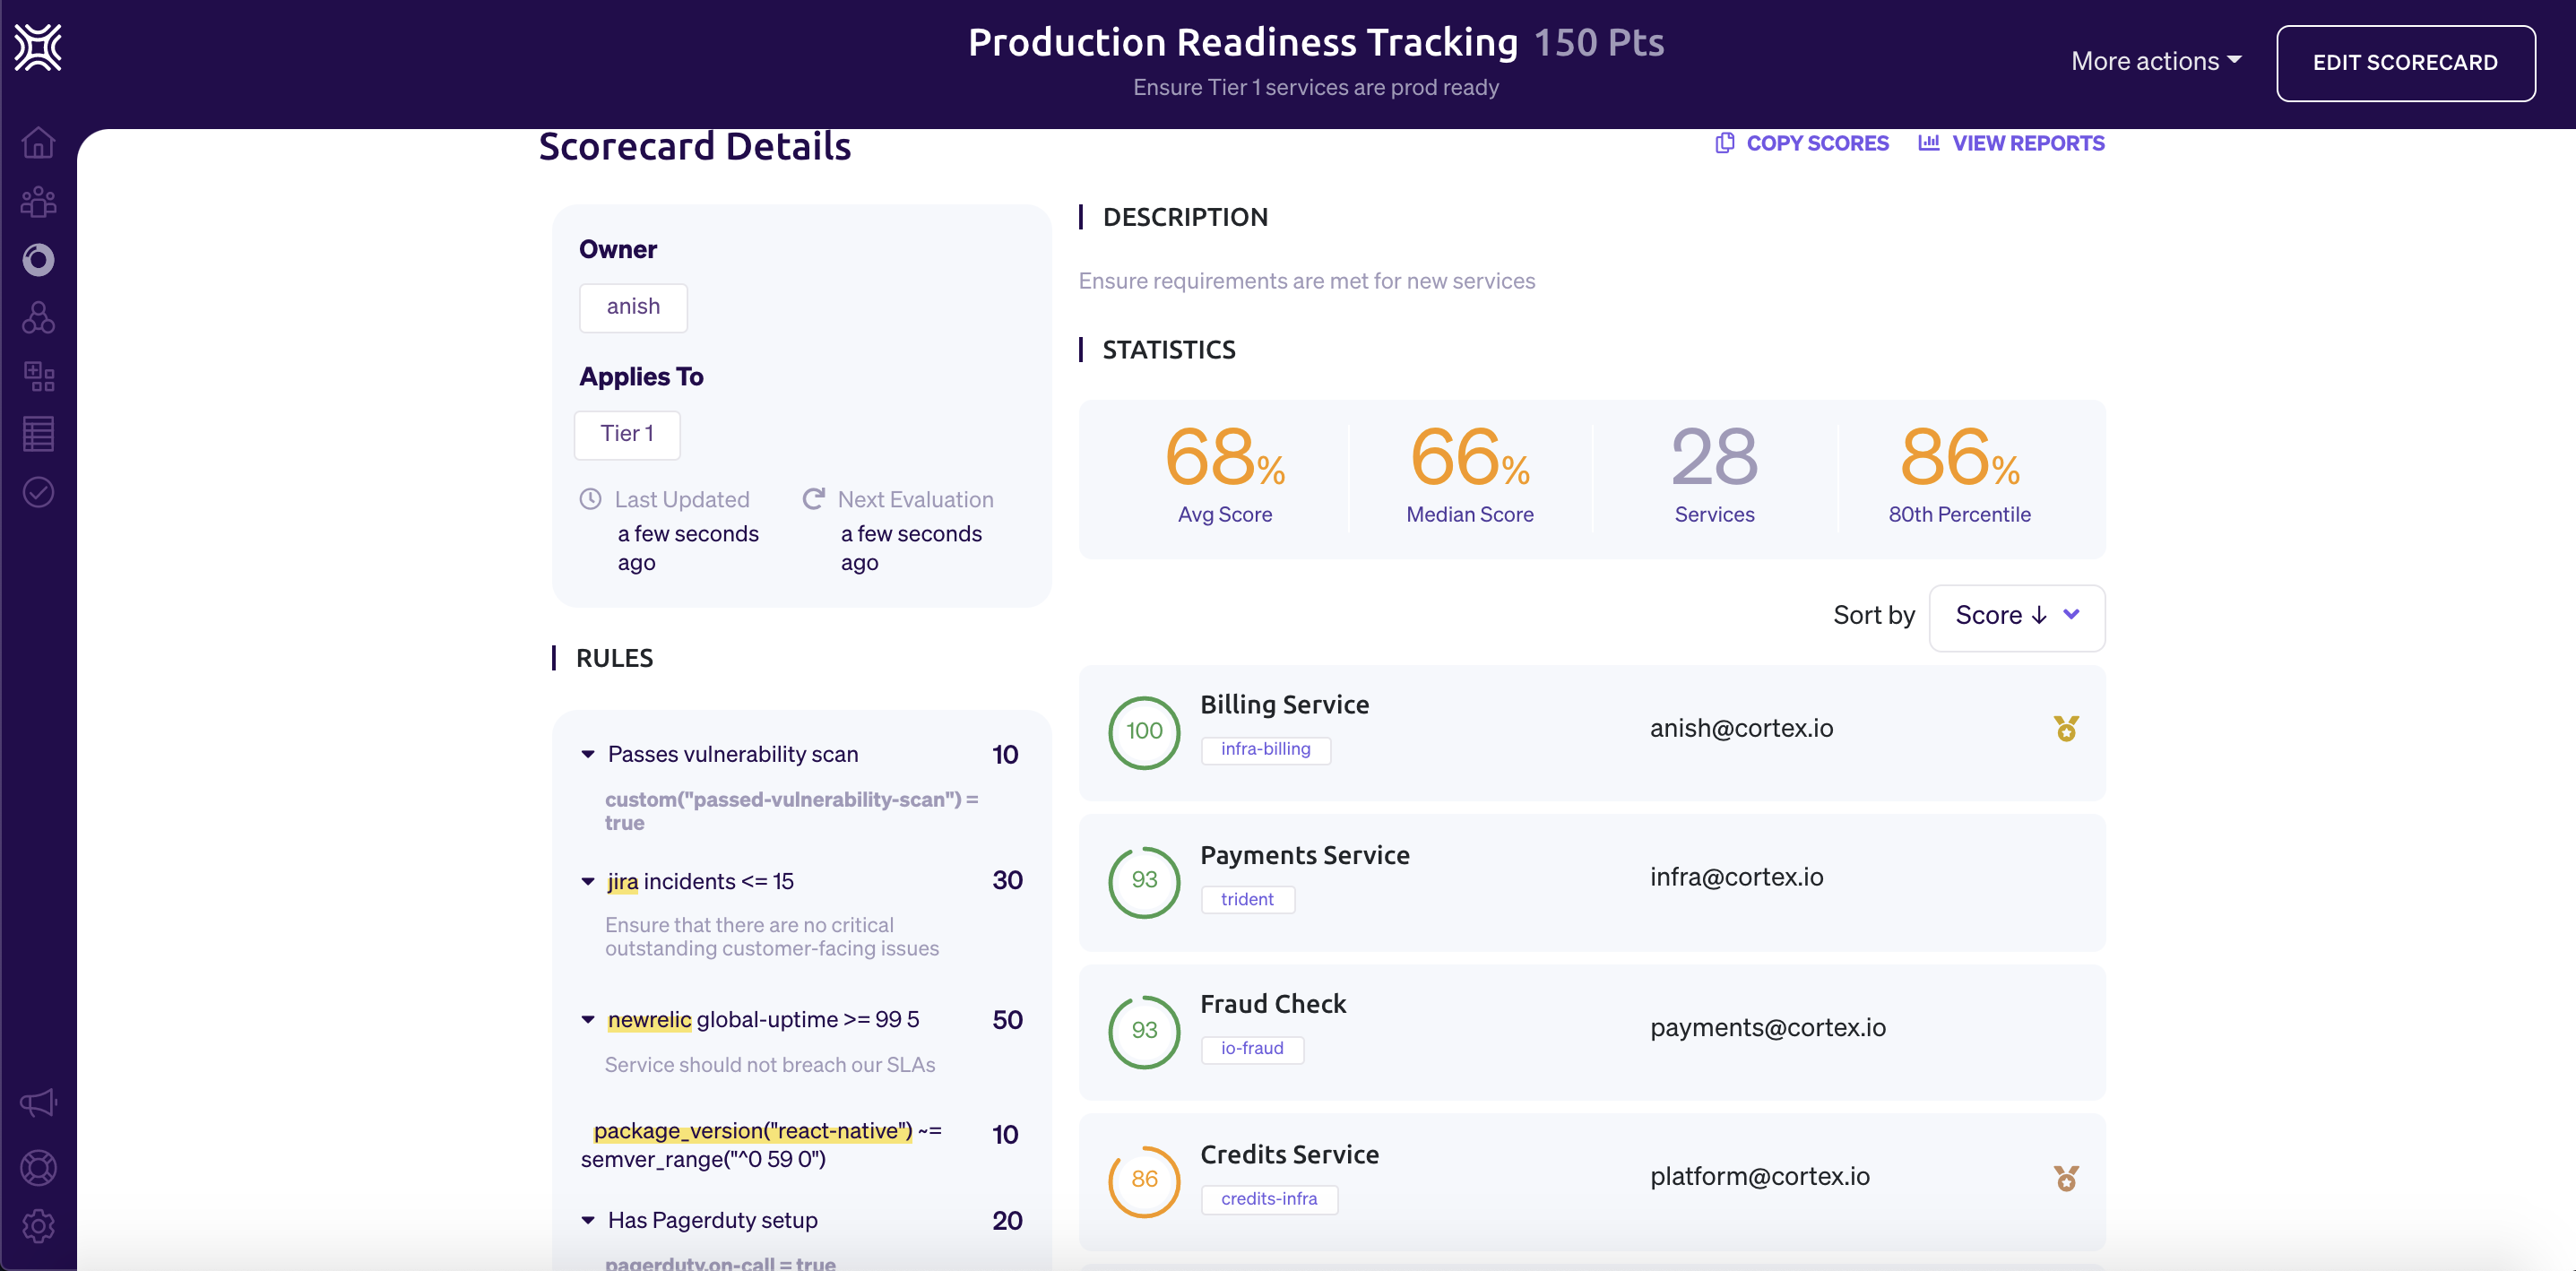
    Cortex, in contrast, automatically imports data residing in developer tools to surface who within an organization is responsible for maintaining which microservices. A Cortex dashboard also enables DevOps teams to see which developers are on-call in the event of an unexpected incident as well as monitor and track the latency rate microservices are experiencing and which vulnerabilities have yet to be remediated.

    At the core of the platform is Cortex Query Language (CQL), a domain-specific language that allows DevOps teams to define granular rules that can be applied to, for example, on-call rotations, security vulnerabilities, package versions, service level objectives (SLOs) and the overall health of the microservice. Engineers can employ code in the form of YAML files to set reliability standards across teams and types of services.

    Grades can also be assigned to specific microservices based on associated metrics. That approach allows DevOps teams to apply gamification techniques using a scorecard to encourage developers to continuously improve their microservices. That capability makes it apparent to other developers which microservices can be most reliably employed.

    It may be a while before microservices-based applications dominate the enterprise landscape. Monolithic applications will be running in production environments well into the next decade. However, many of those monolithic applications are essentially being converted into a larger microservice that other applications can invoke via application programming interfaces (APIs) before being eventually being re-engineered into a set of logically connected microservices.

    The one thing that is clear, however, is that as the number of microservices expands, it becomes more difficult to determine precisely what capabilities are already available to highly distributed application development teams.

  • Are You Feeling the Hiring Crunch?

    Are You Feeling the Hiring Crunch?

    After years of experience, we can now definitively say one thing about information technology: There is always a hiring crunch, and it will always be better soon.

    I first noticed this trend in InfoSec years ago. Everyone was short-staffed and looking for available candidates. Everyone wrote their recruitment text like there was no shortage and they could ask for the moon and everyone was certain that this temporary staffing shortage would end soon.

    It didn’t. It still hasn’t. And it has spread. DevOps in general, development in particular are acting exactly the same these days. And it’s not going to get better.

    So, my advice? If you absolutely must have a person, write your recruitment copy to reflect the actual skills you must have. No bells and whistles, no “We always include…” no “But what if we…” Hire for what you need. Or hire with an eye to training what you need. And offer competitive pay. No one here will argue that IT is underpaid, but when there is a shortage of people, or more are leaving than coming in, then the cost of employees goes up. That’s just the way it is. If you are only hiring the ones you must have, then you can afford to pay them a bit more.

    Meanwhile, invest in even more automation. Let’s face it; again, we can learn from InfoSec. They are doing more with less staff—even if “more” is not “everything that everyone wishes they could”.  They have at least partially conquered their staffing woes by increasing the use of automation. DevSecOps is automating even more of the space, so we really will eventually get over the InfoSec staffing shortage.

    We can do this for all of IT, too—just follow their lead. Invest in automation, take the risk and turn on automated actions. Start small, but get started. Relatively high turnover and lower qualified applicant counts are likely to be the status quo for the foreseeable future, so automating processes as much as possible is not taking away jobs at this point, it is improving response in light of a lack of people for the available jobs.

    So, to sum up:

    • Hire when you can, but be focused. Don’t ask for experience in all three big cloud providers if you’re looking for an Azure person. Don’t ask for fifteen years of experience in Go for that entry-level position. Be realistic, be laser-focused and get the person you need in.
    • Train when you can’t hire. Let’s face it, there are going to be people who are massively familiar with application security but who have never done DevSecOps specifically or never used your DevSecOps solution. Train them—whether they are internal or hired with an eye toward training.
    • For non-critical, long-term needs, explore automation options. That includes both things that are being done manually today and things that are not being done at all. Find a way to get it done in the absence of hiring someone.

    And keep rocking it. You are already getting the job done—I’m just recommending ways to stay on top of it and deliver more while you try to find the additional people you need. A balance of automation and hiring will help you sleep at night and make the rest of the org certain that IT is on the ball.

  • Managing GraphQL at Scale

    Managing GraphQL at Scale

    GraphQL, the query language invented by Facebook, has attracted a lot of interest as a means to conveniently access data programmatically. GraphQL structures internal services with a unified schema for data, empowering product engineers to easily grab what they want from many microservices to populate the user interfaces (UIs) they’re creating. By unifying company data into a single graph, GraphQL combines the benefits of SQL with the ubiquity of API access.

    However, GraphQL does introduce some challenges when you’re trying to scale it across a large enterprise and partner ecosystem. For example, since GraphQL channels all requests through a single endpoint, security must carefully segment access to all the underlying infrastructure to avoid data overexposure. Matt DeBergalis, Apollo’s co-founder and CTO, also identified potential issues around changeability and performance when adopting a graph at scale.

    As the use of GraphQL within large organizations grows, development teams will have to overcome these obstacles—especially if companies intend to productize public APIs and reuse the same single graph company-wide. I recently met with DeBergalis for an update on managing GraphQL at scale. According to DeBergalis, we’re still in the early days of the graph revolution. And, future GraphQL maturity will require more rules-based declarative architecture, efficiency improvements and the adaptability to enact agile iteration of graph schemas.

    State of GraphQL Adoption

    So, what is driving the rise of GraphQL? Well, DeBergalis noted three key contributing factors:

    1. Many many microservices. In recent years, there has been an explosion of microservices. These modular services can be challenging to wrangle and are often exposed inconsistently throughout a software ecosystem.
    2. The rise of omnichannel platforms. Product engineers must now port the same data across disparate devices, whether streaming in a browser or on a Peloton screen.
    3. Users expect a hefty, data-rich experience. Expectations are at an all-time high. It’s now expected that an e-commerce shop, for example, will include product recommendations, auto-fill keyword search, pricing by geography and many more advanced features.

    Juggling all these factors creates a “complexity bottleneck,” DeBergalis explained.

    GraphQL responds to such complexity, helping unify the backend to enable product developers to fetch precisely what their client applications require. And, GraphQL adoption took off pretty quickly, particularly among product engineering teams, DeBergalis added. GaphQL plays nicely with familiar languages and frameworks like JavaScript, React and Relay. It’s also a bit different than previous trends, with demand being driven more by the database folks; “query people are really leading the charge,” he said.

    With the right technology stack, developers can add a graph layer between the underlying core APIs and the UI they are building, creating a universal API with a self-documenting schema. “For the developer, the amazing thing about GraphQL is throwing away all this boiler code,” DeBargalis said. GraphQL acts as “a foundation for tomorrow” to help deliver future business requirements, he said.

    With regard to architectural styles for APIs, 94% still use REST and 31% use GraphQL, according to the 2021 State of API Report from Postman. Though this percentage may seem small now, GraphQL adoption is steadily growing among large companies, such as PayPal, Netflix, Shopify, GitHub and Airbnb.

    Three Issues When Scaling GraphQL

    Using GraphQL is like using a mobile phone. You wouldn’t want to use a different phone every time you called a different number, would you? You would rather have all your contacts accessible from the same device. Similarly, GraphQL excels the more functionality is added.

    “Due to the network effect, a graph becomes more interesting as we publish more into it,” said DeBergalis. “What we have found is that GraphQL is most interesting and valuable at scale.” So, what are some inevitable consequences of GraphQL at scale? DeBergalis outlines three main architectural issues.

    Performance

    Performance downsides are one disadvantage that developers often cite when considering GraphQL. GraphQL has no built-in caching features, and the payload query could introduce additional latencies. Mitigating lower-level issues around throughput and reliability will likely require additional tooling from the community, DeBargalis said. This is partially why the Apollo team has begun to embrace Rust in new attempts to make infrastructure for GraphQL routing hyperefficient.

    Changeability

    A second problem enterprises may encounter when scaling GraphQL is embracing agility for such an all-encompassing fabric. “The companies that do GraphQL really well change it all the time—they treat it like a product,” said DeBergalis. This agility is at odds with the traditional REST API approach of building for longevity, which makes that approach extremely averse to breaking change.

    The reality is that when a company embraces a single graph, it may be pushing hundreds of schema changes every day. Different internal teams may maintain their own slice of the graph, defining it differently. Plus, maintenance roles may shift from team to team over time, noted DeBergalis. “If you try to waterfall what your inventory model should look like, you won’t get anywhere,” he said.

    Balancing change and stability will likely require a two-pronged approach to GraphQL. You want to continually iterate the graph with experimental features but also depend on certain functionality to preserve backward compatibility for client integrations. Satisfying both sides will likely require a change management strategy for iterating quickly, as well as enterprise-grade service level agreements (SLAs) to retain a firm bedrock on which to build more permanent data models.

    DeBergalis also described how observability is important for obtaining a clear picture of graph environments. This is one area where GraphQL shines—since clients request precisely what they need, you are never left wondering which methods are fetched but not implemented in production, as could happen with REST API management. According to DeBargalis, tracking fine-grained GraphQL usage with KPIs can help direct how the data model should evolve over time.

    Authorization

    Finally, perhaps the most significant concern surrounding GraphQL at scale is apportioning the appropriate access to users and devices. As a single unified endpoint can connect to a vast array of data behind the scenes, large GraphQL implementations will require a strategy for how that one unified graph can be implemented in parts.

    Without the proper access control, GraphQL could improperly expose personally identifiable information (PII). For example, a FinTech company may have a rule that requires a customer service representative to only have visibility into a customer’s transaction history if the customer has filed a support ticket in the last few days. Or consider data custody—a business working in the EU must comply with regulations on where data can and can’t live.

    Safeguarding GraphQL will require a declarative setting that integrates authorization control and context into GraphQL queries. To implement this, DeBergalis advocated for a command-and-control style. First, you build the schema around the data and problem statement. Next, you integrate rules field-by-field, marking sensitive touchpoints as PII.

    With rules baked into the query, you can have a more solid understanding of the surrounding context. “Authorization is actually a lot better at graph level,” said DeBergalis. “It’s the layer that has semantic understanding.”

    Future of GraphQL Scalability

    “Once you have a graph, you want to use it for everything,” said DeBergalis. The heritage of GraphQL is JavaScript, the language of the product world. And, the graph approach delivers an excellent experience for product engineers. The sheer usability and productivity benefits of GraphQL indicate incredible potential for projected use in the years to come.

    As we’ve discussed, scaling GraphQL across an enterprise will likely require performance improvements, a path for schema adaptability, policies to handle authorization for queries and greater accountability for business metrics. While GraphQL certainly has existing momentum among a subgroup of engineers, there are plenty of opportunities to introduce more training and educational curriculum to spread greater awareness.

    Furthermore, for those coming from a traditional REST API mindset, GraphQL is a bit of a new paradigm that will require some massaging to expose graph endpoints as a productized API. Doing so will likely involve marking select parts of the larger graph to expose to partners. “Starting with an internal GraphQL use case works really well, but productization around GraphQL is coming,” said DeBergalis.

    The value of a unified graph is so strong, and the bottom-up hunger for a graph environment is so intense that increased GraphQL adoption feels like a given. “At this stage, the focus is on expansion,” said DeBergalis. “How do we roll this out to more teams?”

    “We know there’s going to be a graph in every company—not a lot of little ones,” said DeBergalis. “Every company’s going to need a graph.” When that day comes, the architectural challenge will be breaking apart the graph into pieces. “That’s the next big frontier.”

  • LogicMonitor Introduces Unlimited Log Data Retention

    LogicMonitor Introduces Unlimited Log Data Retention

    LogicMonitor today announced it will provide an option that allows IT organizations to retain an unlimited amount of log data on its software-as-a-service (SaaS) platform.

    Tej Redkar, chief product officer at LogicMonitor, said one of the issues that is holding back advances in observability is the cost of storing log data. LogicMonitor has decided to remove that issue by allowing IT teams to store log data on its LM Logs service for as long as they require, Redkar said.

    That data will also always be readily available as hot storage with no need to wait for data that has been stored offline to be rehydrated, he noted. Instead, that data is readily accessible alongside the metrics and distributed tracing data that LogicMonitor also collects, said Redkar.

    In general, LogicMonitor is making a case for centralizing observability for the entire IT organization via a SaaS platform infused with machine learning algorithms that automatically surface anomalies in real-time based on millions of events captured via log data. The issue many organizations encounter today is silos of decentralized observability data that are more complex to maintain while providing less visibility at a higher total cost, said Redkar.

    The LogicMonitor platform, in contrast, is designed to be equally accessible to, for example, a network operations team as it is to a DevOps team, he noted.

    Not every organization needs to store log data forever, but Redkar said as IT management continues to evolve, more organizations are moving toward storing metrics, traces and logs for longer periods of time. The rise of open source agent software is also making it less costly for organizations to capture that data in the first place.

    It’s not clear to what degree other providers of observability platforms will provide unlimited retention of data, but as the cost of storing data in the cloud continues to drop it’s apparent that billing IT organizations for storage costs is becoming untenable. There is always going to be some cost associated with storage, but it’s not enough to charge extra beyond the core cost of the service. The only thing accomplished by billing separately for storage is discouraging IT teams from storing the data required to both attain observability and better train the machine learning algorithms that surface anomalies.

    Observability, in one form or another, has been a core tenet of DevOps best practices for years. Initially, DevOps teams focused on continuous monitoring as the most effective way to proactively manage application environments. Observability platforms infused with machine learning algorithms make it possible to correlate events so that analytics tools can more easily identify anomalous behavior in real-time. Armed with those insights, it becomes a lot simpler for IT teams to resolve issues faster.

    In fact, there may even come a day when the so-called “war room” meetings that are convened to identify the cause of an IT issue via a painstaking process of elimination are no longer required. In the meantime, however, the total number of IT incidents that actually lead to disruption should steadily decline, even as IT environments become more complex.

  • Plutora Enhances VSM Platform with Release Insights

    Plutora Enhances VSM Platform with Release Insights

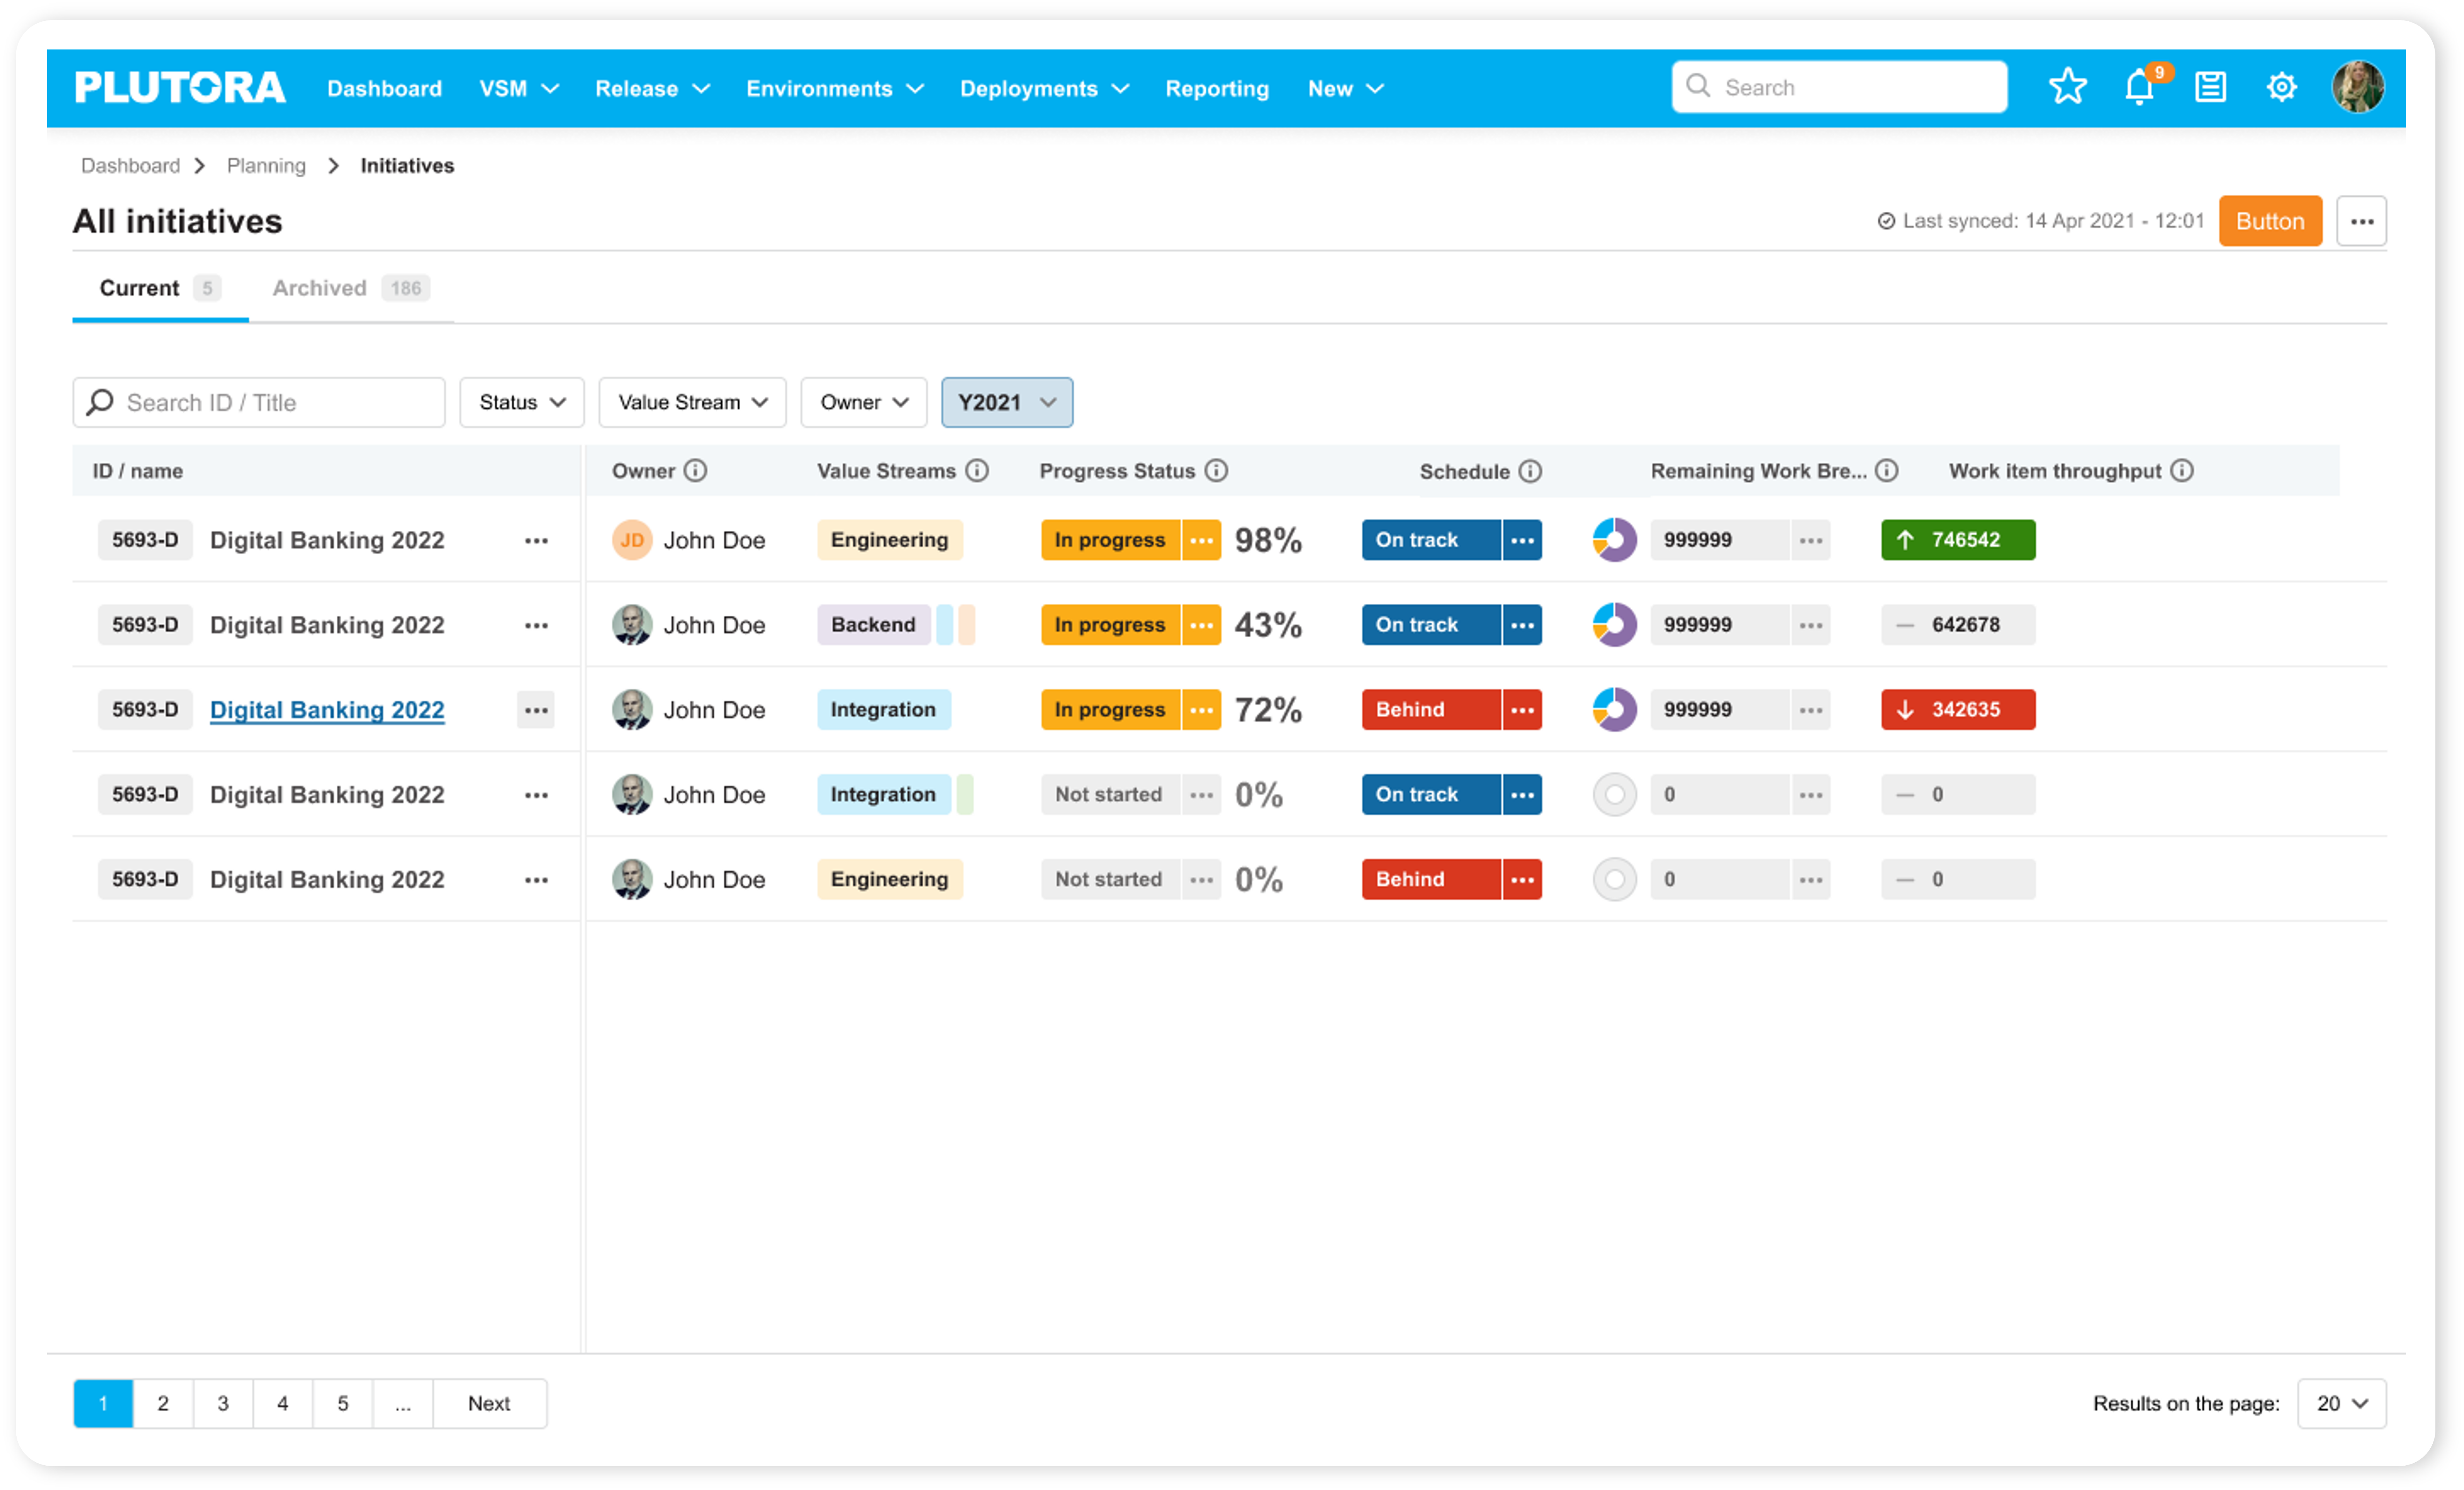
    Plutora has enhanced its value stream management (VSM) platform to provide dashboards that enable DevOps teams to better optimize application delivery.

    Jeff Keyes, vice president of product marketing and strategy for Plutora, said dashboards added to the platform will make it possible for application release managers to leverage predictive analytics to manage application delivery in a more progressive way rather than always having to react to an unexpected event.

    To enable that approach, Plutora has revamped its release insights dashboard that surfaces problem areas and hot spots in addition to adding analytics that track both software builds and larger project initiatives.

    That latter capability is especially critical for executives that currently find it challenging to keep track of multiple software development initiatives, especially those that may have fallen behind schedule without senior leaders being aware of the implications, said Keyes.

    While VSM platforms are typically used by senior IT and business leaders to keep track of how software deadlines are impacting key performance indicators (KPIs) for the business, Keyes said it’s become apparent that application release managers need access to more advanced analytics to optimize application deployment schedules. The Progressive Release Management capability surfaces insights via dashboards in the Plutora platform; that makes it simpler for application delivery managers to optimally orchestrate allocation of resources.

    Release managers, of course, already have access to a wide range of platforms for automating the application delivery process. However, Keyes said, those platforms don’t provide enough insights into how to optimize application delivery across a DevOps workflow made up of disparate tools and platforms. Plutora enables release managers to employ value stream flow metrics and more traditional DevOps metrics to reduce cycle times and improve overall DevOps throughput.

    Keyes said once organizations are provided with that insight, they should also be able to reduce the overall fatigue level many DevOps teams currently experience by removing friction within those workflows. In fact, that fatigue level is a major reason why there is so much turnover in many DevOps teams, he noted.

    It’s not clear how many organizations have a dedicated application release team, but optimizing the software delivery process is a major challenge for almost every DevOps team. While many organizations routinely make use of continuous integration (CI) tools to build applications faster, continuous delivery of applications has proven to be a more elusive goal. This is largely because each platform on which applications are deployed tends to be unique. As a result, many DevOps teams still rely on spreadsheets to manually manage application deployments.

    However, as the pace at which applications are being built continues to accelerate, it’s clear that application delivery is becoming a bottleneck. VSM platforms provide a means of applying analytics to optimize a process that can then be used to make better-informed decisions that might convince more organizations to automate application delivery. That assumes, of course, that the organization had the foresight to invest in a VSM platform capable of surfacing those insights in the first place.