Tag: operations

  • The Whole Nine Yards with DevOps and Agile Operations

    The Whole Nine Yards with DevOps and Agile Operations

    Growing up as a boy in Manchester, UK, football (ok, soccer to US readers) was everything to me. I vividly remember being herded into the stadium stands on cold rainy Saturday afternoons to watch my team (#MCFC) win, draw or lose. Back then, football was for the die-hards – no frills or fancy tech, just hot tea and a suspect meat pie at half-time.

    How things have changed. Now sporting events have undergone a complete transformation – all digitally-driven.

    High Tech Sports

    Take Levi Stadium, home of the San Francisco 49ers for example; considered by many to be the most high-tech stadium in the world. There’s too much tech to describe in detail, but you can be sure that all the Wi-Fi beacons, 400 miles of cable, photo voltaic energy and a funky mobile app have been designed with one thing in mind – enhancing the fan experience. So no ‘cattle-herding’ at a 49ers game – nope, a personalized digital experience that’ll find you your seat, food concessions, the closest bathroom — and of course the shortest beer line (#1 feature in my opinion).

    Levi Stadium isn’t just another example of technical wizardry. It’s more an exercise in an organization deeply connecting with its customers through the delivery of highly experiential services. Understanding the needs, motivations and desires of their loyal fan base and servicing them accordingly.

    It’s a pity this same thinking isn’t always applied in IT Operations – that is, deeply understanding what Ops ‘fans’ need if they’re to ensure a good business user and customer experience across new highly dynamic agile environments.

    High Stakes IT Operations

    Similar to the Manchester game day experience years ago, IT Operations has often done it tough. They’ve worked in isolated NOC’s and service centers, been placed on 24/7 call; working weekends and missing their kid’s birthdays. They have been served specialized ‘team merchandise’ in the shape of complex tools and processes – always counting on their loyalty to save the day when the next mega release comes over the wall. No great surprise then that Operations in many organizations is seen as uncommunicative and uncompromising – almost, well – tribal.

    But IT tribalism doesn’t win matches in the software-driven economy game. Now, digital business realities means IT Operations must supplement its traditional fixation on reliability and resilience with a willingness to drive change – Operations must itself become more Agile. But how do you start? Thinking back to the innovation at Levi Stadium, here are three good ways.

    1. Gaining Loyal Supporters – Development and Operations aren’t enemies, but like rival UK football team supporters the teams are often segregated. Dev and their tools to the left, Ops with theirs to the right. From a business perspective this is plain dumb – especially when it comes to getting the most value from technologies like application performance management. Rather than frantically monitor applications as problems manifest in production and then call Dev for help, wouldn’t it be better to incorporate operational intelligence much earlier in the software lifecycle? So when code is released, monitoring could immediately provide development with an early warning on operational issues. Conversely, Ops practitioners gain accurate and timely insights into production performance requirements and KPI’s – that’s not only a DevOps style win-win, it’s an agile like best practice to increase quality and avoid technical debt.
    1. Filling the Business Stadium – The goal of Operations has always been keeping the business lights on, but Agile Operations now means making them shine brighter. Cloud, Microservices architecture and containers all give businesses the technical clout needed to support speed at scale, but it comes at a cost. Today’s sophisticated applications rely on specialized technologies, so it’s perhaps understandable that Operations chase the technology down the proverbial rabbit hole with more specialized tools. But the real truth is that any monitoring system which doesn’t deliver true business value by providing unified insight into how customers are actually experiencing IT services is of no use to anyone. Remember too that technology scale is about future proofing your business, so look for scalable monitoring to match it.
    1. Delivering a Complete Experience – The digital experience for a 49ers fan doesn’t start and end on game day. It is delivered by a linked series of services – a digital journey comprising seat selection, ticketing, parking, entry, action replays, and player stats reviews – every one of which can positively or negatively impact the fans experience. Whatever your industry, IT Operations will be called upon to support similar services, meaning deep and uninterrupted visibility across the myriad of front and back technologies underpinning every customer interaction, engagement and transaction will become essential.

    Successful digital transformation needs more DevOps and agile operations, agile development, faster release cycles and higher quality software. It’s time for IT Operations to stop fixing production problems and become an active participant in supporting these goals. Without Agile Operations, your role in the software-driven business game ferociously being played out will be like that meat pie I ate many years ago – suspect.

  • Beyond the Darkness of Shadow IT

    Beyond the Darkness of Shadow IT

    The concept of consumerization of IT, Bring Your Own Everything (BYOx) and self-service technologies has amplified the amount of ‘Shadow IT’ in development shops. Developers can procure, setup, and start using new components, and developer tools in hours. This is a trend that lurks in the dark. C-suite executives can either ban the trend altogether to stay on the safe side, or venture into new waters and embrace innovations that open doors to unforeseen opportunities, efficiencies and productivity standards.

    (more…)

  • Service virtualization – The hows and the whys.

    Service virtualization – The hows and the whys.

    Close your eyes and take a deep breath. You are on an island, smelling the iodine coming from the sea, the sun is gently caressing your cheeks and you are sipping on a cocktail in the middle of the afternoon. Your phone is off, in a place you forgot and you do not have direct access to the internet. You are a sysdamin and for the first time since the beginning of your career, you take a break, an actual break to reload your batteries and you are not even thinking about work because you KNOW. You know it is all going to be alright, as it has been since you implemented service virtualization in a really DevOps oriented way.

    What is service virtualization?

    First of all, let me say that service virtualization is not something new but many are still unaware of what it actually is and only a few good products are available.

    You can find a really good explanation of what it is in this post from Chris Riley: https://devopsy.kinsta.cloud/blogs/service-virtualization-window-advanced-devops/ but I will try to sum it up.

    In order to avoid confusion, it is also necessary to briefly explain mocks and stubs. Mocks are usually programmers written tests that check the behaviour of a specific piece of code like which methods are called, in which order and if sub processes were created. Stubs on the other hand check that for any given input, the expected result is outed. I often refer to them as logic tests and I/O tests.

    Service virtualization has nothing to do with mocks or stubs. It mimics the entire behaviour of an application as if it was an actual one deployed on a server and connected to a database, backend etc. In order to enable this, data will be recorded from QA (and anonymized) and the whole behaviour of the application will be recorded. Going through security layers, calls to a database, updating some values, even timings can be recorded for performance testing. Absolutely every single operation is stored and if the test data is well chosen at the time of recording, all cases can be covered.

    For those of you who are into gaming, think of it as an emulator. You do not need a SNES, Genesis or Neo Geo to play your favourite oldies, instead, all you need is an emulator software and the ROMS. The emulator will behave like a gaming console on your computer, reproducing inputs and outputs with high fidelity and translating CPU instructions into different ones your computer can understand.

    If you are not into gaming, and that is a shame if you ask me, think about virtual machines. When you install a Fedora in a confined environment on top of your favourite edition of Windows (or Mac OS), what you do is pretty similar to service virtualization as well. Your Guest OS will send instructions to the different components of your computer which the virtual machine will catch, translate into commands your Host OS can understand and send to the concerned components. It sounds complicated but it works like a charm.

    What it can do for you.

    As it operates on local servers or even better, on containers (check out Docker if you have not done so yet), it is virtually always on. Downtime is a thing from the past and updates can be scheduled and performed when people are not at work. How much of your project you want to cover is up to you and your needs but once you have started the process, why not go all the automated way? If you do, that means that your programmers will have access 100 percent of the time to environments that are up, running and that reflect actual services.

    What is the point of having test environments then you might ask. And here is the answer you can give stakeholders: none. You can achieve good environment resilience, actual data tests and higher-than-ever response time through service virtualization. If well applied, and I really want to emphasize on that, service virtualization makes good ol’ test-environments obsolete.

    Once again here, the benefits mentionned by Chris Riley will speak for themselves: https://devopsy.kinsta.cloud/blogs/service-virtualization-window-advanced-devops/

    Taking DevOps one step further.

    Like all great things, service virtualization comes at a cost. In order to fine tune it to your requirements, it is going to take great efforts. You have to decide which services, ideally all of them, you will provide your programmers, which data sets are representatives of a functional application and of course, install and configure it all. The biggest benefit that you can identify here already is that developers, testers and operations have to be involved and work in a close collaboration. This is your opportunity to make different teams understand what others do. Get them all together, make them work together in a form they are not necessarily familiar with: cross-teams brainstorming.

    Brainstorming, if well done, can be a very powerful tool to come up with creative solutions to problems that were not identified as such beforehand. It has to be directed though. To brainstorm doesn’t mean talking nonsense about non topic related things. Having a neutral person in the room who focuses the discussion around a few pre-established points and who keeps track of time is the way to go. Scrum masters are generally good at this since they have an overview of the project and its problems and can quickly identify the right persons for a task.

    Getting developers to update their own service virtualization server with the latest data from QA means better communication with testers. Operations have a critical role here too since they setup the environments and give the how-to to the different teams.

    Another glass sir?

    Once your teams work together on an almost 24/7 available server and understand how it works, all you have to do as a sysadmin, is to relax a bit for once and focus your brain and time on how to improve processes even more, enhance the quality of deliverables and tighten up the now-existing bonds with your colleagues. Oh yeah, and if you’re on holidays, stop worrying about that potential catastrophic phone call, just worry about yours and yourself.

  • Enter at your own risk: DevOps isn’t for everybody

    Enter at your own risk: DevOps isn’t for everybody

    There’s always a sexy new tech buzzword flying around, and it’s easy to fall into the trap of assuming that if a concept or technology is hot you need to hurry up and jump on board so you don’t miss anything. DevOps is hot, and seems to be almost ubiquitous these days. But that doesn’t mean that every organization should rush out and embrace DevOps.

    Defining what it is exactly that you think you’re embracing can be a challenge. The concept of DevOps is a bit broad and ethereal in the first place. The number of vendors calling their products or services “DevOps” just because it’s sexy marketing muddies the waters and makes it more difficult to figure out what DevOps is, and how it’s supposed to benefit your organization.

    Even if you think you have a fair grasp on what DevOps is, though, it still isn’t necessarily right for every organization. It CAN be right for most organizations, but there’s some introspection, and due diligence that has to come up front. More precisely, it isn’t necessarily right for every organization without a solid foundation of the right skills and resources, and an understanding of what you hope to accomplish, and how you plan to get there.

    Nathen Harvey, community director at Chef, shared some insight on this topic. “Through immense feedback from our community, customers and contributors we’ve learned a lot about how and when an organization should begin a DevOps transition. In short, everyone should not immediately jump on the DevOps bandwagon.”

    Harvey added, “DevOps is full of big ideas and big changes and therefore development and operations teams need to be prepared to work together through challenges and to collaborate toward a common goal.”

    James Bottomley, CTO of server virtualization at Parallels, cautions, “DevOps processes are supposed to be accessible to anyone. However, since current DevOps lifecycles are based on virtual machines, they are really only accessible to those with the skills to manage virtual images and, to make use of the live VM, administer base systems and platforms.”

    Bottomley explains that larger organizations often have the necessary skills available, and just have to marshal them toward a DevOps strategy. Small and medium businesses, on the other hand, often lack the appropriate resources.

    “If you are a SMB you should consider carefully whether you have the necessary Ops skills in-house and if not, how you are going to obtain them (whether from a [service provider] or other form of management). Ongoing Ops skills are vital to proper VM maintenance (fixing security issues and the like), so you have to make sure you have an ongoing Ops capability, not just a one-time one when the virtual system was created.”

    According to Chef’s Harvey, there are three specific areas organizations need to consider before embarking on a journey to embrace DevOps. They are the “Three C’s”: Character, Communications, and Community.

    · Character requires trust, respect, empathy, learning and perseverance.

    · Communication is meant to align objectives—such as setting metrics for everyone, and sitting close enough to easily collaborate with one another.

    · Community can take many forms, whether engaging in podcasts, conferences, sharing code and more.

    Don’t make the mistake of jumping on the DevOps bandwagon prematurely just for the sake of jumping on the DevOps bandwagon. It will be a frustrating experience almost doomed to fail and leave a bad taste in your mouth. Instead, take the time necessary to understand what DevOps means to you, figure out what you hope to accomplish by embracing DevOps, consider whether or not you actually have the skills and resources to make it happen, and develop a plan that includes the “Three C’s” so your DevOps journey can be a successful one.

  • Expanding DevOps Beyond Dev and Ops

    Expanding DevOps Beyond Dev and Ops

    I’ve been involved in software delivery for longer than I care to admit, and since DevOps has come onto the scene I’ve witnessed the deconstruction of silos that were once actively built to contain separate projects and team functions. Central to this deconstruction is collaboration between Dev and Ops, ushering in new innovation paradigms. What’s exciting is that in just the past five years since DevOps has started permeating organizations, other areas within the enterprise—including technical and marketing teams—have started to recognize the high-value that comes from embracing collaborative tools and processes. DevOps has quickly evolved from sideline projects to a state of mind rapidly adopted by leading companies across various business units.

    DevOps and Culture

    Accompanying this notion of greater collaboration and cross-silo participation is the need for new tools to help facilitate the pace of change and collaboration. Although there are no silver bullets, you can take steps and implement technologies to help make the odds of success more favorable.

    Before DevOps, hostility between Dev and Ops teams was not unusual. Dev and Ops had conflicting goals: Development to introduce change and Operations to maintain stability. The common bond was a love of technology rather than delivering quality products to customers. In my experience, technology employees care more about the technology they can experiment with than the value something they’re working on brings to customers. However, in the five years that DevOps has been on the scene, those of us who follow DevOps closely have noticed staff on both sides becoming much more customer-focused.

    Common Goals

    Many organizations publish their core values and say that they expect employees to live up to those values. But are those values something that employees are measured against? In my experience, they are not. Organizational values tend to end up being words to make people feel good. But what if every manager in an organization had a common goal of delivering quality products or services to customers, with the goal defined in a measurable way? Then everyone in the organization contributes to delivering the products to customers. It’s a goal is not and should not be department specific.

    The departments that often see considerable delays due to red tape are:

    • Human Resources
    • Budgeting
    • Procurement
    • Marketing

    Any one of these departments can result in projects getting stuck in the mud, usually due to large amounts of lead time required to fulfill a request.  Delivering quality products and services frequently obviously doesn’t mean having no process, but when things need to be done quickly, procedures should be flexible enough to accommodate such requirements. The need for agility applies to all parts of an organization. It’s not just a technology problem.

    Consider trying to hire someone new to work on a project. Adding an employee could involve HR, Finance and Procurement, each with their own processes and requests for lead time. The multitude of steps in their respective processes frequently take weeks, if not months. This applies to almost any department of the organization and it’s highly likely that there are processes that add significant delays to reacting to business needs.

    Setting common goals and measurements is a sure way to cut red tape. Employees don’t want to be the reason something could not be done. Processes will become streamlined and departments will collaborate out of necessity, if not for the good of the organization, then at least as an act of self-preservation.

    While this high-level overview makes it sound simple, most organizations outside of Silicon Valley don’t set common goals for employees. It’s up to the Unicorns to spread the word.

    Using Technology to Facilitate Collaboration

    The DevOps movement resulted in advances in tools and technologies that aided in Dev and Ops collaboration, and took advantage of the opportunities created by this frictionless new environment.

    In order for all departments in an organization to be able to take advantage of similar opportunities, other teams will need to look at ways to optimize their workflows and tool chains.

    One area where tools have reduced friction and increased collaboration is code review. Code review has a lot in common with collaborating on any other kind of content. Code review used to be done with people sitting in a room with printouts of source code receiving feedback that often resulted in holy wars about coding styles. It wasn’t effective and that was even within the same department.

    Tools now allow documents to be reviewed asynchronously with in-line comments, no matter where in the world the reviewers are located. It’s one of the few examples where communicating via text rather than voice lowers tensions, which is surprising given how easy it is to accidentally upset someone via email!

    A great example of this is how my working style changed once I started working with Gene Kim, the award-winning author of The Phoenix Project: A Novel About IT, DevOps, and Helping Your Business Win and The Visible Ops Handbook. Rather than email documents back and forth, we’d collaborate via Google Docs. No matter what our schedules were or where we were in the world, we worked together effectively. The first time I worked like this with Gene changed the way I think about collaborating on non-technical content.

    A key element of collaboration on a single set of artifacts is not having multiple copies in different systems in an organization. In fact, the 2014 DevOps Survey by PuppetLabs found that versioning production artifacts in one place was a key indicator of high-performing organizations. Imagine being able to store all artifacts involved in a project–Including requirements docs, marketing campaigns, and spreadsheets–In a single location accessible via tools that fit your needs. Collaboration, passing audits, applying for tax credits, and disaster recovery would be so much easier.

    We’re not there yet. As mentioned, tools such as code review, Google Docs, wikis, version control systems, and email all help with collaboration but they are often still silos of information. Just as breaking down silos between teams has been revolutionary, breaking down the walls of data will one day have an equally profound impact.


    About the Author

    2014-11-12 23.09.11Before joining Perforce as a Technical Marketing Manager focused on Continuous Delivery and DevOps, Jonathan Thorpe held technical marketing roles at CFEngine, Serena, and Electric Cloud, where he specialized in DevOps culture and automation technologies. In his spare time you can find him reading, playing with all of the current video game consoles, dabbling with mobile software development, and playing with the Raspberry Pi.


  • Automation, Operations, DevOps – What We Thought Was Missing

    Automation, Operations, DevOps – What We Thought Was Missing

    stackstorm-brandStackstorm is a new company focused on automation, operations and DevOps. It’s co-founder and CEO Evan Powell has been keeping a running journal as the company made ready to emerge from stealth. Over the next few days we will share Powell’s thoughts and experiences as a new DevOps company comes to market.

    Over the next few posts I’ll be sharing my thoughts on why StackStorm – a new company focused on DevOps based automation – was still needed. My first comment is that the users will decide how we overlap or complement existing automation solutions.  So far they are confirming our belief – that we are strongly complementary to trail blazers like Chef, Puppet and of course CF engine and more recently Salt.  Our approach is to focus on operations automation that wires together the data center and that – in the case of systems like Facebook’s FBAR and our own beta level software – learns over time. With that as some context, over the next five days I’ll unpack our key drivers for us starting StackStorm – starting with something I think all readers of devopsy.kinsta.cloud should agree with:

    DevOps and the shift to the cloud is much bigger than generally assumed. Over the last few years, my co-founder Dmitri and I have met with thousands of enterprises, service providers, government agencies, integrators and sundry analysts and experts. And I’ve been speaking about the inevitability of the shift to Software Defined Data Centers for many years while helping to create the software defined storage market as founding CEO of Nexenta Systems. More recently, as StackStormers, Dmitri and I have met with approximately 100 DevOps practitioners with OpenStack projects either ongoing or kicking off. The shift to DevOps – sometimes lumped in with the shift to Software Defined Data Centers and also the shift to the cloud – is the biggest shift in IT we’ve seen in our careers. The top DevOps practitioners are 10-100x more productive than your legacy siloed IT operations department. Software is “eating everything” AND the approach to building and operating software has improved radically. Nearly every company and government in the world must either leverage this step function improvement in productivity of software development and operations or face disruption. It might be worth discussing the 10-100x productivity improvement:
    a. Is it real? Organizations like PayPal and eBay have published their own data showing at least a 7x improvement in development velocity. And of course the DevOps surveys by folks like Puppet Labs have shown even higher improvements in the speed and quality of development. And, again, our own experience indicates it is very real.  One operator tells us that they went from building and deploying 1 new service a year before DevOps to 54 in the 12 months after they got up to speed with a DevOps approach. Revolutionary.
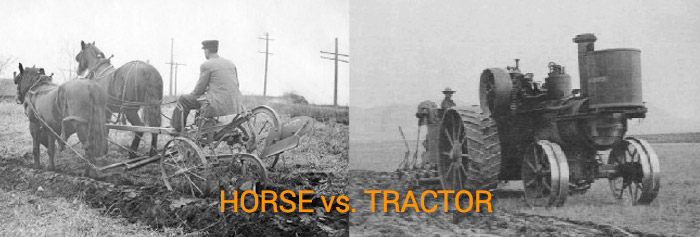
    b. Is 10x a lot? Software getting built and operated 10x better is changing the world. A comparison that Dmitri made in his talk at SCALE12x this past February was to the tractor. As I think any casual student of the 20th century knows, the tractor changed the world by enabling urbanization and more. According to most economic historians, the tractor was about 4x more productive as measured by crops produced vs. input in human and machine energy. IT fairly suddenly figuring out how to develop and operate software 10-100x more productively compares favorably with the most important improvements in human history.
    horse-tractor-1
    So – GREAT. The world is changing. What do we and other DevOps solution providers have to do with this? Ask yourself – why don’t we ALL just jump on the DevOps bandwagon and start building and operating software in this new way? I’ll take on that question tomorrow as the second driver that led us to start StackStorm.
    Feedback welcome.  Comment below please.
  • Meet Infrastructure as Code

    Meet Infrastructure as Code

    Maybe you have already heard the terms “Programmable Infrastructure” and “Infrastructure as code”.  But even if you have not, if you are interested in DevOps it’s something you need to know.   Most new lingo causes me to roll my eyes.  But in this case, it’s not just new lingo, it’s an entirely new concept. Besides making the nerdy feel cool when they say it, these terms describe a new idea of what an application consists of. (more…)

  • An outage war room primer

    An outage war room primer

    One aspect of the DevOps movement I’ve seen adopted at numerous companies is the idea that everyone supports their products by being on-call for any incidents that occur in the production environment. This responsibility often leads to participation in the outage war room. For those of you who may be new to this experience, I’m offering this primer from a grey-hair ops guy who’s served countless hours in every manner of war room you could imagine, some that stretch the bounds of that imagination, and a few that I just still can’t talk about. Been there. Done that. Still doing it.

    In all that time, however, I’ve observed  four distinct war room dynamics that can cause conflict. Understanding how that conflict arises is key to mitigating it.

    The war room is a stressful place

    This statement sounds obvious, but it’s fundamental to understanding the tensions that can arise in a war room. The clock is ticking. In fact, the clock has already been ticking for some time when you join the room. These things don’t happen instantaneously. When you get the call to join a war room, the problem has already manifested and is causing an impact. Even with automation, it takes time to notify people and have them connect to the war room, in whatever form that takes. In environments with a very high SLA target, the set up time for the war room alone can exceed the monthly allowance for downtime. So once you get into the war room, it’s serious business. The clock keeps ticking.

    The war room is often a stressful place as a result. Tensions, and even tempers, can run high. But each and every person in the war room has an obligation to keep themselves under control. Tension and stress feed on each other, and if you succumb, it makes it worse for everyone. Even more important, if you get angry, emotional, or display some other decidedly not cool way of coping with the situation, you are likely to lose the confidence of your peers. That really sucks, so it’s important to force yourself to project calm confidence and be deliberate and measured in your actions. If you have the opportunity (and the ability) and can help to disperse some of that tension, do it. Those are the kinds of moments that build credibility.

    And there is another very personal connection to the outage that can be stressful. A professional, worst-case scenario. In the worst case, you are actually responsible for the whole mess. When that happens, you are going to be in your own special hell in the war room. But you should know exactly what is expected of you – the one thing you can do that will really make a difference. You need to tell everyone exactly what you did, without skipping anything, and without regard to how stupid it might sound in hindsight. As in, “I continued to run through all the commands in the procedure even though they were failing with errors and even though I had guidance to stop and seek help if they failed.” To help prop you up in this most difficult of tasks, consider this: everyone else in the room has done the same thing. We’ve all been there. If we haven’t, it’s probably just a matter of time. So you have to swallow your pride, tell the whole story and then get actively involved in fixing things, because that’s what the war room is all about.

    The goal of the war room is to restore service as quickly as possible

    A war room is bad. If you are in one, it probably means that your customers are impacted. You have an obligation, working with the rest of the team, to recover the service in the most effective and least risky way. In a perfect world, that method is also fast, but life doesn’t always work out that way. If there is no obvious and simple solution, though, things can slow down a bit and we see different approaches forming across groups of people in the war room. Some, traditionally the operations staff, want a way to restore service quickly by a reboot, reset or other “big red button” kind of operation. Others feel it’s important to fully understand the nature of the problem before taking action. These are clearly often opposing goals.

    One way this manifests in war rooms is when, in order to further analyze the problem, someone asks to run some experiments, or capture data, or otherwise use the production environment to debug the problem. If there is no method available to recover service with a reasonable level of risk, such experiments may be justified. Otherwise, the team has an obligation to execute whatever procedure they have to bring the system back up, even if that destroys information that might be helpful to the root cause investigation.

    Another thing I see happen frequently is when the someone jumps the gun in trying to fix things. It plays out like this:

    Jane: Do you think we should reboot the server?

    Dick: I’ll get set up for it.

    Jane: I think we should do it.

    Dick: Done!

    Jane: Wait…

    A good war room manager will easily spot and work through these kinds of conflicts. If there is such a person on your war room, listen to them and obey them. The war rooms I’ve participated in are not democracies. They are run by a strong leader who is empowered to make extremely critical decisions. It’s crucial to respect that authority in the heat of the moment rather than try to be the hero. Not so coincidentally, this is my next point.

    We need solutions, not heroes

    In a war room, you need to separate your ego from your idea. The war room does not need heroes. The war room needs solutions. Be advised that no matter what part of the organization you come from, your idea is probably going to go up against some alternative ideas. They will not be judged, generally speaking, on how clever or elegant they are. They will be judged on how effectively they can recover the service and how much risk there is. And if yours is not the chosen idea, it does not mean that you suck. The only people who really suck in a war room are those who interfere with the process of service recovery. You know, the people who interrupt the flow of a critical conversation to ask for a status update, or who won’t stop debating a relatively minor point when the team really needs to focus on a larger issue. That kind of thing. But I digress.

    Sometimes, the right path forward does not actually address the root cause of the problem.

    Sometimes, the right path forward precludes ever figuring out what the root cause is.

    Heroes have a hard time coping with that.

    You must accept that you may never know why

    The incident and problem management processes in most reasonably mature organizations are designed to recover the service, find the root cause and then ensure that it never happens again. But reality is often different than these goals. Incidents sometimes last a lot longer than you like, as when you discover that something has been broken for a long time and you did not know about it. And we should all know by this point that sometimes you never really know why it happened. You just can’t figure it out. It sucks, but again, it doesn’t mean that you suck. It means that the cost of determining the root cause has crossed the point at which it is feasible to continue, given the impact of the problem when it manifests. That’s just common business acumen, but it’s worth stating. Because when you realize that this is a possible outcome, it can give you a better perspective on evaluating your options. Suddenly, restarting the system and walking away from any run-time state information that might be helpful in root cause determination seems more viable. And those are the kinds of trade-offs that everyone in the war room has to come to terms with.

    Conclusion

    It sucks being called into a war room due to an outage. It is the very definition of failure in the SaaS world. But you can make a bad situation into a great and positive experience if you handle it properly. You can take an event that should mean that you suck and turn it into something that demonstrates your excellence. Being an effective member of the war room is a way for you, as an individual contributor, to demonstrate that awesomeness. You do it through calm, reasoned action and sound leadership. That builds confidence and trust. I guarantee you that your peers in the war room will notice and respect you for it and your customers will benefit from it. Let’s not let any of them down.