Tag: machine learning

  • XebiaLabs Injects Predictive Analytics Into DevOps Platform

    XebiaLabs Injects Predictive Analytics Into DevOps Platform

    XebiaLabs is moving to take the guesswork out of DevOps following the launch of a set of tools that leverage machine learning algorithms to predict when and how the release of an application is most likely to go awry.

    The Risk Prediction Module being added to the XebiaLabs DevOps platform comes on the heels of XebiaLabs’ move to make its XL JetPack software for automating application deployments available on the Amazon Web Services (AWS) Marketplace. XL JetPack is an automation framework based on YAML files and a declarative programming framework that enable DevOps teams to push applications into production on a cloud platform in as little as 15 minutes.

    XebiaLabs CEO Derek Langone said that while DevOps advancements have been made in terms of achieving continuous integration, the goal of achieving continuous delivery has proven to be more elusive. As automation frameworks such as XL JetPack become more accessible, however, IT operations teams will be better able to keep pace with the rate at which organizations want to be to deploy and update applications, he said.

    It’s becoming increasingly apparent that a combination of automation frameworks and machine learning algorithms will enable DevOps teams to make a significant leap forward in terms of application release lifecycle management. Because of all the nuances of the different platforms that IT organizations are trying to leverage, it’s become a major challenge to roll out an application manually. As the number of applications that need to be released at roughly the same time increases, managing the release cycle process is moving beyond the capabilities of an IT team made up of mere mortals.

    The Risk Prediction Model from XebiaLabs promises to increase the odds of success by applying predictive analytics infused with machine learning and other proprietary XebiaLabs algorithms to identify DevOps bottlenecks before they are encountered. Capabilities provided by that module include alerts that warn the team when a release is likely to be delayed or to fail before the release pipeline starts running; a Risk Forecast view that summarizes predicted delays and failures for every task in the release process; an overview of statistics for similar releases to provide historical context; and forensics tools that uncover flaky automated tests, problematic build setups, long-running deployments and time-consuming manual tasks. That Risk Prediction Module is meant to complement the risk scoring capability that XebiaLabs already includes in its platform.

    Arguably, the biggest barrier to DevOps adoption today continues to be the level of expertise required to succeed. But as the combination of predictive analytics infused with machine learning algorithms and algorithms that can discern instantly how changes to the IT environment will impact applications become more common, the level of expertise required to master DevOps processes should decline. As that transition occurs, the number of organizations embracing DevOps more broadly should increase.

    In the meantime, DevOps teams would be well-advised to consider to what degree they might next want to rely on predictive analytics to prescriptively automate processes with eye toward eliminating the need for as much human intervention as possible.

    — Mike Vizard

  • Developing Simple and Stable Machine Learning Models

    Developing Simple and Stable Machine Learning Models

    A current challenge and debate in artificial intelligence is building simple and stable machine learning models capable of identifying patterns and even objects. Is it possible to know which models will work best or to simply see the data? It is possible, and the question is figuring out how to get there.

    Simple models are popular because they are easy to understand, trustworthy and tend to be more resilient to change than complex models. Simple models also have the benefit of overcoming transfer learning pains. While everyone wants simple models, they also want accurate models. In practice, there are always transfer learning issues when applying learning from the past, into future practice.

    An issue arises when trying to fit a model from a known family to the available data and hoping it will generalize effectively. It could be any proposed family: linear models, trees or trained deep neural networks.

    There remains a fundamental problem with any overly complicated model—linear, tree or neural network—in the risk of “overfitting” the data resulting in poor generalization and results. At the same time, an overly simple model risks missing the nuances of the data and sacrificing accuracy. There are techniques to handle this problem.

    First is to reduce the size of the set of models. This works well with the PAC model. For example, reduce the number of parameters, reduce the depth of the tree and reduce the nodes in the network. Reducing the size of the set means it’s easier to understand, and with fewer possibilities built into the model, it’s less likely to overfit the data.

    Next, add L1 or L2 regularization. Models with small weight, or many zero weights, are preferable and will help the model generalize. The question is, why? Why do we use trees or neural networks rather than another hypothesis family? Why do we want models with small weights? Why do some network topologies work well?

    These questions bring in the actual world we live in and the types of problems that likely need solving. There is no learning when any function is allowed, and the model family isn’t limited. It is well-known that when the family of allowed hypotheses is too large, the model overfits the data ad-absurdum and becomes useless. Thus, machine learning almost always optimizes along a well-understood family of hypotheses while human feature engineering and representation construction captures our prior knowledge about the world. The question is how to exploit such knowledge when automating machine learning. Arbitrary limiting is better than not limiting at all, but we can do better.

    The world has patterns repeating themselves across many domains. Different applications will use similar building blocks to analyze rocket movement or medical sensors, or to solve a predictive maintenance task. But we are all experts in the world we live in. Even studying a domain where we don’t have specific expertise, we still recognize some patterns and rules.

    For example, take a look at this ring-tailed lemur. Even if you’ve never seen one before, you are now likely to identify this type of primate if you come across one. My 5-year-old son was shown this picture and he could visit the zoo and identify a ring-tailed lemur. It only took one photo.

    Compare that result to modern neural network research which typically requires many examples—often into the millions—when training to identify objects, and still they suffer from embarrassing mistakes when new data differs from the data the network was trained on.

    How did my 5-year-old son learn to identify ring-tailed lemurs from a single picture? He’s an expert. Not a lemur or primate expert, but an expert in the world we live in. He understands identifying an object from its background. What a tail, eyes, ears, legs and fur look like. He knows how to imagine a 3D object from different directions. At 5, he already brought a ton of knowledge with him when learning to identify lemurs.

    This is the essence of learning. We understand the notion of simplicity is not in number of nodes in the network or number of lines of code, but that it relates to simplicity when explaining human language.

    This process can be formalized by codifying human knowledge to solve tough problems. We can formalize the many patterns seen before in various domains and in the various tools data scientists use when constructing features. Then we can look for patterns that make sense and are similar to what we’ve seen before.

    We can also look for more novel patterns represented within the complex combinations of things we’ve seen before. As an industry, we need to do exactly this: Codify human knowledge in curated code libraries, and in structured knowledge and facts, use them to search for patterns in data and build highly accurate resilient models. This will bring simplicity and stability to machine learning models without sacrificing accuracy by leveraging humanity’s existing knowledge.

    — Meir Maor

  • 5 DevOps Trends Worth Knowing in 2019

    5 DevOps Trends Worth Knowing in 2019

    DevOps today is more than the buzzword it was 10 years ago. Back then, the idea of combining development with production in your IT infrastructure was not common; the logistics were nonexistent and most of the time businesses decided it was far too much effort.

    However, if the last nine years has taught us anything, it’s that DevOps is worth every penny businesses invest. It helps companies streamline production, keep customers happy and provide agile services to attract new audiences.

    But as with anything in the IT field, there is a paradigm of change. This article discusses some of the top DevOps trends happening now and how to implement them in your own system.

    Automation Will Be a Bigger Focus

    Automation has always been the way for businesses. Whether it’s speeding up the pipeline with machines, providing better response times for angry customers with chatbots or better inventory management with tracking and logging system, automation is behind it all.

    DevOps is no exception.

    But as with everything, there can be too much automation. The best thing to do is break down processes and find simple, redundant tasks that can save time if automated and apply the changes.

    The most important aspect of automating DevOps is to understand the six pillars in the DevOps cycle, which are:

    • Continuous business planning
    • Collaborative development
    • Continuous testing
    • Continuous release and deployment
    • Continuous monitoring
    • Collaborative customer feedback and optimization

    DevOps Assembly Lines: The Next Big Thing


    To track the development of your application, we have pipelines. These visually represent the product from its initial stage right through until final development and release.

    However, continuous integration (CI) is no longer the priority focus when it comes to effective monitoring and implementation. Continuous delivery and automation are a major part that businesses have already started delving into in 2019.

    This is where DevOps assembly lines enter the picture.

    Assembly lines are focused on bridging the gap between manual and automated tasks, ensuring there is no redundancy while providing several tools for teams to implement, to ensure apps are hitting the production lines as reasonably quickly as possible.

    Microservices Architecture Adoption Taking Off


    Microservices architecture may as well be that new kid in school trying to fit in. These smaller services compound into agile, implementable tools that DevOps teams can use to scale and test software over the course of weeks—not years.

    As you can imagine, this can help some businesses streamline their development and production lines, setting them way ahead of their original production estimates—which is never a bad thing.

    Implementing microservices into your DevOps team can also help companies focus on the runtime and efficient delivery of new development sources, without the hassle of creating dependency errors when something decides to bug out for no apparent reason.

    Security Needs to Step Up

    Cybercrime is on the rise—we all know that’s old news. But as a business, cybercrime can either make or break your sales and weigh down your DevOps team.

    That’s why more companies are hopping onto enterprise security options. Although there are third-party programmers for almost every situation you need, none of them have the same security levels as the tools from the enterprise version provides. Safeguarding both your company and your clientele.

    Riding the Artificial Intelligence Wave

    Finally, we have artificial intelligence (AI) and machine learning (ML). When you think about it, these two elements are literally the sum of everything we want in the DevOps community—the ability to crunch out hours upon hours of menial labor and saving your teams hours to focus on higher-priority tasks.

    The combination of AI, used to predict algorithmic influencers, and ML’s ability to adapt to new situations will be key for DevOps teams to get to the next level in 2019.

    — Gil Artmoore

  • SolarWinds IT Trends Report 2019: Measuring the Skills Priority in DevOps

    SolarWinds IT Trends Report 2019: Measuring the Skills Priority in DevOps

    Although historically technology professionals were among the most adaptive specialists in the job market, a recent survey from SolarWinds found that DevOps teams, web product managers (WPMs) and developers lacked confidence in their current ability to effectively manage their current environments while engaging in future technologies. This balancing of current trends with future innovations is a necessity of having any technical role, as things change quickly in technology.

    SolarWinds recently published the latest edition of its annual IT Trends Report, IT Trends Report 2019: Skills for Tech Pros of Tomorrow, which explores confidence, current and future skill sets, career development and barriers to career success to reveal how DevOps teams, developers, WPMs and the businesses they serve can better manage future technology realities. How do these tech pros personally feel about their current and future skill sets? Coinciding with SolarWinds Cloud Confessions: The Trouble with Troubleshooting,the IT Trends Report found that tech pros have an appetite to prioritize career development on a weekly basis, but are hindered by factors such as time and cost. How can they prioritize career development while confronting the barriers to career success and develop the skills necessary to make future tech implementation a reality?

    The DevOps findings are based on a survey fielded in December 2018, which yielded responses from 100 DevOps practitioners (teams, developers and WPMs), managers and directors in the United States and Canada from public and private-sector small, midsize and enterprise companies.

    Among many other key findings, this year’s survey revealed:

    Most tech professionals in DevOps, web product managers and developer roles are not fully confident they have all the skills needed to manage their environments into the near future, especially when it comes to emerging tech. 

    • 75% of all DevOps teams, developers and WPMs surveyed are not “completely confident” in having all the necessary skills to successfully manage their IT environments over the next three to five years—even though 98% have worked to develop a skill over the past 12 months.
    • When it comes to the idea of implementing or managing specific technologies, emerging tech is a pain point (despite how much mindshare these buzz-worthy technologies get in headlines). The top three technologies DevOps teams, developers and WPMs feel unequipped to manage with their current skill sets are:
      1. AI (55%)
      2. Blockchain (50%) and quantum computing (50%)
      3. Machine and/or deep learning (45%)
    • According to the Gartner list of strategic technology trends that have the potential to disrupt and are on the verge of becoming more widely used in the next five years, AI, blockchain and quantum computing all rank in the top 10.
    • There is a great opportunity for DevOps teams, developers and WPMs to increase their knowledge of these technologies and to have productive conversations with businesses on the reality of implementation in the near future.

    DevOps teams, developers and WPMs will continue building skills in daily operations with an eye toward areas such as data science. 

    • In the past 12 months, DevOps teams, developers and WPMs have prioritized skills in coding and scripting (54%), systems and infrastructure management (43%) and database management (41%).
    • In the next three to five years, the top two skills developers and WPMs plan to develop are security management (45%), data science and analytics (41%).
    • DevOps teams’, developers’ and WPMs’ instincts are correct when it comes to the top skill set area as they’re expected to see continued growth. Gartner research analysts estimate that global revenue for the information security market will grow at a compound annual growth rate (CAGR) of 7.8% between 2017 and 2022, reaching $143 billion in constant currency terms.
    • Hybrid IT deployment monitoring and management rounds out the top three skill sets DevOps teams, developers and WPMs plan to develop in the next three to five years.
    • Gartner also predicts that the worldwide public cloud services market will grow by 17.33% in 2019, going from $175.8 billion in 2018 to $206.2 billion this year.

    DevOps teams, developers and WPMs say cloud and/or hybrid IT, big data analytics and AI are the key technologies for career development, which will help achieve higher goals such as innovation.

    • DevOps teams, developers and WPMs say the most important technologies for their career development are (by weighted rank) aligned with the top three technologies for organizations’ transformation over the next three to five years.
      1. Cloud and/or hybrid IT (59%)
      2. Big data and analytics (55%)
      3. AI (54%)
    • When it comes to career development goals over the next three to five years, DevOps teams, developers and WPMs will look to prioritize (by weighted rank):
      1. Technology innovation (49%)
      2. Programming, coding and/or scripting (33%)
      3. Data analytics and/or data science (38%)
    • Management/leadership skills (people management) and IT security protocol and/or processes round out the top five career development goals for the next three to five years.

    DevOps teams, developers and WPMs have an appetite to prioritize career development on a weekly basis but are hindered by factors such as time and cost.

    • Nearly 8 in 10 DevOps teams, developers and WPMs (79%) say their day-to-day IT tasks extend into time earmarked for career development, with 20% saying this always happens.
    • This is alarming considering DevOps teams, developers and WPMs enjoy technology skills training, with 49% finding it informative, 32% saying it’s engaging and interactive and 27% reporting it’s not long enough.
    • Currently, DevOps teams, developers and WPMs engage in IT skills training and/or career development programs ranging from a few times a year (25%) to monthly (23%) and weekly (19%); however, if there were no schedule or workload restrictions, most (42%) would prefer weekly training.
    • Developers and WPMs cite time and availability (48%) and cost (25%) as the biggest barriers affecting their current ability to participate in IT skills training and career development programs at the frequency they would like.
    • When it comes to their primary sources for training, DevOps teams, developers and WPMs turn to:
      1. My organization and/or coworkers (20%) and online communities/forums (20%)
      2. Industry events/trade shows (17%)
      3. Vendor training sessions (16%) and industry publications (16%)
    • However, the ideal delivery format for IT skills training according to DevOps teams, developers and WPMs is (by weighted rank):
      1. Self-guided online course
      2. In-person workshop/user conference (full-day)
      3. Webinar

    Final Thoughts

    For tech pros to continue helping businesses revolutionize current technology while proactively adapting for future disruption, it is imperative that business and technology leaders provide the training that tech pros seek, through courses, self-guided training and webinars.

    SolarWinds 2019 survey results emphasize the importance of empowering tech pros through training and focusing on career development. Emerging tech should not be a pain point for these tech pros—rather, they should have the opportunity to embrace strategic technology trends and have productive conversations with businesses on the reality of implementation in the near future.

    2019 is the year of integrating career growth, skills development and business transformation to empower tech pros with the skills necessary to help lead the business they support into the future of tech innovation.

    — Joe Kim

  • VMware Doubles Down on IT Automation

    VMware Doubles Down on IT Automation

    VMware this week moved to inject application and operating system monitoring capabilities into the VMware vRealize cloud management platform to make it easier to employ dashboards to map the relationships between applications and the underlying IT infrastructure they run on.

    In addition, VMware enhanced its capacity optimization tools to enable IT teams to run “what if” scenarios based on the amount of IT infrastructure available both on-premises and in the cloud. The company also embedded integrated compliance and automated drift remediation capabilities into VMware vSphere.

    Finally, VMware added support for VMware NSX Data Center network virtualization software to the VMware vRealize Automation platform, and instances of Kubernetes clusters can now be seen by VMware vRealize Network Insight tools.

    Taruna Gandhi, director of product marketing for the VMware Cloud Management business unit, said these efforts are part of a continuing initiative to drive intent-based computing that leverages automation across a software-defined data center (SDDC).

    VMware views application and operating system monitoring capabilities as being critical tools for making informed decisions about those intents, said Gandhi. However, these tools are not intended to replace the need for classes of management technologies such as application performance management (APM) platforms, she said. Instead, VMware envisions using dashboards to more efficiently troubleshoot issues based on metrics gathered by Telegraf agents embedded in VMware vRealize. In effect, IT teams will be able to identify anomalies faster versus wasting time in “war rooms” trying to prove the innocence of any element of an IT stack.

    VMware is pursuing a dual strategy where DevOps and automation are concerned. The VMware vRealize framework can be invoked either through application programming interfaces (APIs) or a graphical user interface (GUI), which tends to appeal more to traditional VMware administrators who don’t have extensive programming skills but still need to respond to rapidly changing IT operation environments.

    Thanks to automation, operational costs are falling considerably, according to VMware. A report from Forrester Consulting commissioned by VMware found organizations that have adopted vRealize have seen a 30% productivity improvement and a 93% reduction in unplanned work. That same report also noted that, thanks to capacity optimization, VMware customers have also seen a 20% reduction in hardware cost savings, a 10% reduction in storage costs, and a 50% reduction in database software licensing costs.

    In most cases, VMware is employing machine learning algorithms to automate IT operations whenever possible within its cloud management suite. But Gandhi said VMware is hesitant to embrace the term “AIOps” until it becomes clearer how employing machine learning algorithms represents a new class of IT management tools rather than an ongoing set of enhancements to existing management frameworks.

    Whatever the outcome, it’s apparent that algorithms are here to stay. How much they will be employed to advance adoption of best DevOps practices across the enterprise, however, remains to be seen.

    — Mike Vizard

  • The New AI Overseer Role in DevOps

    The New AI Overseer Role in DevOps

    Robot overlords are the stuff of science fiction fantasy. Today, with more teams implementing artificial intelligence (AI), DevOps teams need a hard, continuous look at reality. An AI overseer watching apps at work could make the difference between sadness and euphoria in your efforts.

    We’re seeing AI misses more and more often. Facebook recently admitted its algorithms failed to stop uploads of a particularly heinous live-streamed video. Autonomous vehicles have struck cars and people. Jaywalkers in China have been misidentified and publicly shamed in error. It’s not for lack of effort in development. The adage “If it were easy, anyone could do it” applies.

    A few weeks back, I was in a Twitter chat session on AI led by Kirk Borne, data scientist at Booz Allen Hamilton. The question came up of what organizations should consider when creating guidelines for use of data and bias-free AI. Here’s my response:

    A4: DevOps teams should have someone whose role is AI oversight—actually watching what it’s doing and constantly testing/validating its findings #MITSMRChat

    — Don Dingee (@StratisetDon) February 14, 2019

    Common Problems

    Most fails are due to fire-and-forget, wherein AI systems are trained, tested against training and turned loose. Even a well-designed AI system is subject to several problems:

    Errors: This is where AI makes a factually incorrect decision. False positives and false negatives are in this category, along with miscategorization problems.

    Gaps: There are situations in which AI understands conflicting options and is unable to choose. Then, there are situations in which the AI doesn’t recognize what it sees.

    Bias: Maybe the system prefers green M&Ms or German shepherds because there was some subtle trend in the training data for “candy” or “dog.”

    Ethics: This can be a higher level of bias, where preference is given based on age, gender or race. Sometimes it’s the classic no-win scenario in which both options are harmful.

    An AI overseer guards against these types of problems in near real-time, every day, for as long as it takes to weed them out. Some problems are easier than others. An example of a more difficult problem came when autonomous vehicle researchers realized that not all traffic signs are brand new and well-lit. Shade, branches, wind, scratches, dings, bullet holes, stickers, graffiti and many more types of defects exist in the real world.

    Increased Complexity

    Inevitably, part of the solution the AI overseer leads is better scenario-planning and more training data. Retraining becomes a way of life and at some point, bigger data sets also lead to more complex implementations and another challenge: speed—after retraining to correct issues, the reloaded real-time classification engine runs like it’s stuck in molasses, producing correct results too late to be useful.

    While the A system is running, a B version should be in development with new training and classifier boxes. For very large data sets, teams should consider designing a workload-optimized training server complex instead of relying on elastic cloud resources. This was behind NVIDIA’s recent acquisition of Mellanox—using InfiniBand for more bandwidth between GPU clusters in AI server complexes.

    Where training systems often scale, real-time systems usually don’t. They are optimized for size and power consumption and can only accept so many additions. When a bottleneck emerges, it can kill the entire application. New generations of CPUs, GPUs and FPGAs keep pushing the envelope for designers tackling AI challenges.

    Human-in-the-Loop

    In many use cases, the job of the AI system is not to make every single decision autonomously. Instead, the system should make routine decisions and lead the AI overseer to look at exception cases. Directing humans quickly to areas needing attention is often more valuable than risking bad decisions. Human-in-the-loop is something DevOps teams should architect into systems more often.

    This may all sound obvious, but it points out a big difference in developing AI versus developing code-based algorithms. If there’s a bug in code, you can debug it and find the offending lines of code to fix. But debugging AI is a lot more difficult. Digital twin implementations come into play using playback of real-work inputs to look at what happens inside the classifier black box. There are usually hints of problems developing before catastrophe strikes. Running data both good and bad can help spot issues.

    Ideally, the AI overseer is a hybrid of a data scientist plus a systems architect. Look for someone who understands both data sets and hardware implementations, at least at a high level. They may have to call in other resources on the team for detailed investigations.

    The last thing you want after all the hard work in developing a system is to have it run amok months or years later. It’s just Murphy’s Law. AI systems will do something entirely unexpected at the worst possible time. An AI overseer can help a DevOps team get ahead of AI problems.

  • Perfecto Applies AI to Writing Test Scripts

    Perfecto Applies AI to Writing Test Scripts

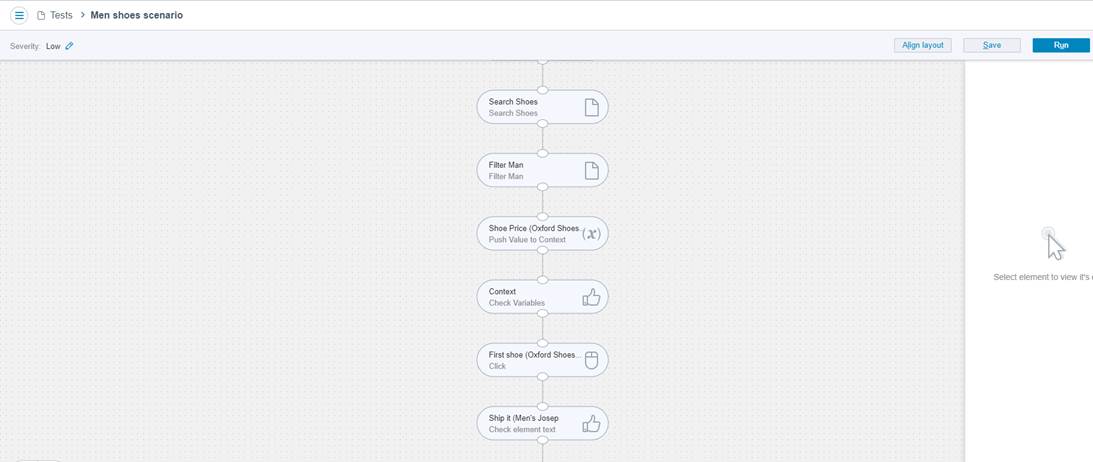
    Artificial intelligence (AI) is starting to be applied to the writing and update test scripts. Perfecto has unfurled Perfecto Codeless, which employs machine learning algorithms to automate writing of test scripts in a way that allows them to not only run continuously, but also adjust to changes made to the application.

    Eran Kinsbruner, chief evangelist for Perfecto, a unit of Perforce, said writing test scripts is still largely a manual process, which means as the number of applications being developed continues to escalate, the testing process becomes highly constrained.

    To address that issue, Perfecto has created a codeless approach delivered via a cloud service as part of the company’s Smart Automation platform. If any code within an application gets deleted, moved or changed, the changes will automatically be reflected in the test script. That capability eliminates the need for DevOps teams to wait for a developer to update the test script.

    Exactly who in an organization is writing those test scripts varies: Kinsbruner noted that many developers now prefer to write their own test scripts during the development process before their code is reviewed by a peer. That approach eliminates many of the more routine errors, enabling more time to be spent on optimizing code. Other organizations employ dedicated testers who spend most of their time writing test scripts. But many of those organizations are finding that testers cannot keep pace with the current rate at which applications are being developed in the DevOps era.

    There’s no doubt machine learning algorithms are about to play a much bigger role in application testing and DevOps at large. AI is not going to replace DevOps teams anytime soon, but many mundane functions such as the writing of test scripts can be automated using machine learning algorithms. Arguably, testing is one of the areas that lends itself most to emerging AI-based platforms and services. After all, if testing becomes a bottleneck, the chances that applications with issues are deployed in a production environment increase substantially. Many of those issues can be fixed easily, but many times at the risk of annoying end users who increasingly are unforgiving when it comes to application experiences. It’s not uncommon for users to discontinue using a mobile app if the first experience isn’t immediately gratifying.

    Of course, many DevOps teams already view machine learning algorithms with a certain amount of skepticism. But the rise machine learning algorithms within DevOps is now all but inevitable. IT leaders, however, should realize it may take a while for those algorithms to learn the environment. The return on investment for any AI project is not likely to be immediate because a significant amount of time needs to be invested in training the algorithms. The good news is, those algorithms never take a day off and suddenly don’t resign one day to take a better-paying job elsewhere.

    — Mike Vizard

  • In Service Management, AI Is Still Aspirational

    In Service Management, AI Is Still Aspirational

    Artificial intelligence (AI) has become a matured concept, the excitement of which is bearing results for a number of sectors and it holds a good deal of promise for a bright future. AI is the act of making possible for machines to learn from “experience” while adjusting to new input and stimuli so they can perform human-like tasks, ultimately leading for more complete automation in many traditionally man-powered processes. Computers can be “trained” to accomplish specific tasks, process data and recognize patterns in the data.

    While the use of service management solutions escalates, so do the potential uses for AI approaches in the sector. Because of this, there are advantages to discuss as well as examples of how AI can help to improve the service management operations of your organizations. But AI is a broad and far-reaching concept that’s often misunderstood and difficult for those that don’t work with the technology to understand its full capabilities.

    Is AI All Hype or Is It Actually Helpful?

    Based on the 2018 Interop ITX AI: Hype or Substance report, in a survey of 182 technology professionals, almost two-thirds of these respondents’ organizations are currently working on AI products or evaluating the technology. However, only 12 percent are using AI in production today. For those who responded during 2018, 6 percent of those using the technology said their budgets for it were set to decrease. The outcome, per the report, is that AI interest is high, but the ability to execute is low.

    Are AI Expectations Too High?

    The return on investment of AI is not clear and nearly one-third of organizations say they lack the budget they need to move forward, Information Week reports. Additionally, despite the desire for AI initiatives to reduce manual processes, these tasks must still be carried out by talent in the organization. A lack of expertise is often cited as a barrier to AI initiatives because there is not enough expertise to push the efforts forward. Alternatively, of those surveyed, more than a quarter said they haven’t defined a business case yet and close to half said they “have no idea” what effect AI may have on their businesses.

    Part of the problem with AI is the broad nature of its concept. Much of what we thought we knew AI was is now standard practice. For example, early AI efforts like IBM’s chess computer, Deep Blue, is part of our computing world now. Currently, demand or desire for AI capabilities is still aspirational, but usually is conflated with “machine learning”—where a computer or programming provides examples for how a machine can “learn” how to complete said task. Machine learning has huge potential to help societies automate previously manual systems. Through this, new economies will be developed and work (and workers) will evolve. Certain jobs, eventually, will become minimized and even discontinued in favor of new process and “ways of doing things.”

    We have seen these cycles before. In the United States, from a macro level, there’s been a major shift from a farming/agricultural society to one of more urban-based manufacturing/industry; into the post-industrial; then global-focused; and web-connected economies. These can be drilled down further but the point is made—major variations in our economies and jobs have taken place in a relatively short period of time. Based on these changes, we’ve had to change; jobs and workers have had to change. Machine learning is another disruptor for the new global economy that will force change.

    Hyped Up

    The hype of machine learning—a technology with huge potential—may not actually be overhyped. That said, how will this technology actually impact our everyday lives, and will machine learning change the work we do in service management? Perhaps we’re now starting to get a better idea of what those realities may look like.

    As far back as 2017, Gartner said that machine learning hype peaked, but expectations remain high. For service managers, there’s going to be more than intelligent chatbots to worry about but for now, much of the anticipation likely will continue. Machine learning can be a beneficial tool for identifying trends and changes in trends. In service management, machine learning means quick responses can help recognize when there is an above average number of calls logged, for example, or an unusual number of calls within one category, which can be acted upon.

    For most pressing trends—a specific cloud service that may no longer be available, for example—meaning machine learning-driven technology can recognize this breakdown by sending a signal to a specialized member of the service team, who can then react to this issue. Long-term problems also can be addressed through machine learning technology, spotting urgent disruptions. This may be particularly important during problem management. A labor-intensive process, machine learning has the capability of being able to recognize patterns in these calls, making the discovery of structural problems much easier.

    Misconceptions About Machine Learning

    Misconception surrounding AI and machine learning is rampant from replacing most of our jobs and replacing massive amounts of humans in the workforce to their surpassing our pre-programmed uses for the technology, in which the machines rise up and enslave us all. The more realistic version of things is a bit more benign. The most common current misconception is that chatbots and virtual assistants will make service desk employees redundant in short order. But this won’t likely be the case for the better part of a half decade or more because the technology isn’t sophisticated enough. Most chatbots are pretty expensive and don’t always work well.

    For now, machine learning will likely only help “answer” direct questions more quickly. More complex issues must still be handled by people. The realized benefit here is that because machine learning technology can help solve the easiest questions service desks face, there’s more time for service desk team members to solve the more complex calls.

    Someday Soon …

    Soon, machine learning technology will become better at finding the right information and offering solutions that actually benefit humans. Then, service desk employees will be able to focus more on the overall customer experience in ways that machine learning likely never could.

    While AI is maturing, excitement surrounding this experiment may need to be tempered for a bit. The technology is in the act of making possible for machines to learn from “experience” while adjusting to new input and stimuli so they can perform human-like tasks, but more complete automation in many traditionally man-powered processes is still needed.

    — Nancy Van Elsacker Louisnord

  • Incidence Avoidance in Action

    Incidence Avoidance in Action

    Today, CIOs are faced with the challenge of making enterprise technologies perform on par with offerings from consumer-facing technology leaders, such as Facebook or Netflix, meaning technology or services being seamlessly available with no performance lag. Of course, these expectations are not always aligned with the realities of managing complex hybrid enterprise systems that were not necessarily designed to deliver this type of performance.

    On the other hand, IT operations supporting new-age “digital” business services are dealing with on-demand resources that are supported by software-defined data centers extending into the public cloud by using serverless computing platforms. This is resulting in a “new generation hybrid enterprise” that must deliver the functionality of, and operate as, real-time infrastructure.

    Lexmark, a U.S.-headquartered global company that manufactures laser printers and imaging products, wanted to achieve zero latency operational performance and enhance its business processes to achieve incidence or error avoidance.

    This article details Lexmark’s IT objective and the solution implemented by Wipro Ltd., a global information technology, consulting and business process services company.

    Problem: Lexmark required a technology solution that would provide visibility into its core business process—managed print services. The solution would also need to factor in other supporting systems and functional processes. The objective was to achieve operational excellence by minimizing errors and risks.

    Solution: To address this critical IT operations problem, Wipro was able to incorporate unique design principles to create an operationally simple, scalable and focused solution that brings IT and business process owners to a common understanding regarding achieving incident avoidance.

    Wipro built a new way of visualizing operations management, based on the fundamentals laid out by IT operational analytics (or AI operations, as it is called now).

    Working only with the tools and data that Lexmark already owned, Wipro and Lexmark created a system that measured the heartbeat of Lexmark’s managed print services business. That heartbeat was synchronized to the printer data collection systems, with the thresholds determined entirely by machine learning techniques. Every underlying system was arranged in a “server room.”  Only out-of-variance conditions are displayed in the main visualization panel, with the root cause just a single click away. This paper provides insights into the challenges faced by IT enterprises to deliver an on-demand solution to clients, similar to the ones offered by digitally evolved B2C companies.

    Digital enterprises that use hybrid environments must respond in real-time and need to achieve incident avoidance, rather than incident management.

    If we look behind the scenes at operation command centers today, we see operations that struggle to keep up the pace. Very few operations have been built from the ground up. In the enterprise world, Severity 1 (incidents that are categorized as high impact by business users) incident resolution times, still run for a couple of hours if IT support is not in a position to find the root cause of the problem. The culprit is often the lack of a proper configuration management database (CMDB), insufficient logging or lack of application discovery and dependency mapping. Every IT professional can recognize these failings, yet projects to correct these flaws never seem to get the necessary capital appropriation. Clearly, a new approach is needed to fix this.

    Identify the Business Process

    The process should start by identifying the key driving force or the heartbeat of the core business operation. Depending on the industry, this heartbeat might be customer orders, service requests or vendor purchase orders. All other systems are connected to this heartbeat. To select the right attribute to monitor as the heartbeat, start with business analysts who have a good feel for the day-to-day struggles of the operation. These analysts often have a series of scripted reports they run to track system health. More advanced analysts might even have automated these with alerts. By leveraging this information and using data discovery techniques, we found that the values can be configured as business KPIs.

    In the case of Lexmark, Wipro streamed the KPI values in real time and used machine and wire data to broadcast the underlying monitoring components by using an existing streaming analytics platform that is supported by AI and machine learning techniques. We found that the amount of data needed to assess process health is time sensitive, and normally less than 24 hours of data is displayed during that time.

    The platform visualization shown above, tracks the creation of sales orders for a business unit. The green line represents the flow of orders through the system. Any anomaly in an underlying system is reflected directly on this flow. This is achieved by streaming analytics and AI techniques that use the business KPIs.

    Apply the Architecture Overlay

    The next step is to subordinate the supporting infrastructure to the business process heartbeat. This feat is accomplished without complex business rules and sophisticated orchestration engines. We call this the “server room” and it is a view of the entire infrastructure on one web page, leveraging a lattice chart format that allows for easy comparison. Each of these underlying components will have a direct impact on the business process.

    Applying the same streaming analytics and AI/ML techniques that identified the anomaly in business process, we identify what is causing that anomaly and can quickly see the problem areas.

    Color coding helps the technician quickly understand the severity of the event. Blue indicates the system performance has not yet violated the set threshold, but an underlying infrastructure issue exists and needs to be proactively addressed. Amber indicates the system has violated the warning threshold. Red indicates the system has violated the critical threshold, a condition that by design we will never allow to happen.

    The user can scroll over any given point and a callout box will display the actual level, as well as a brief note on what has gone wrong and the timestamp.

    Analysts can now instantly focus their efforts on the specific systems that are in an error state, even if an event has not yet created an incident.

    Machine Learning to Define the Thresholds for an Anomaly

    What is normal behavior? This is often the most difficult question to answer because common monitoring and management processes rely on a single data value that was set during implementation. But thresholds must be extremely flexible to capture the ever-changing nature of the business process. Batch jobs that run at midnight, end-of-month closing activities, shift changes and a host of other potential variables must be considered when determining the right thresholds.

    For any component supporting the business process, we need to understand what is normal for right now. To determine that at Lexmark, we applied machine learning to dynamically set the thresholds for each sub-system at the month, day and hour level based on the healthy business KPIs we established.

    Incident Avoidance, Not Incident Management

    To fully understand the potential of this approach, it is necessary to change the way system analysts interact with the system. IT professionals who have been doing system support for several years, may be conditioned to react to the work in their queue. A well-honed incident management process is the enemy of proactive action that can prevent emergencies.

    By aligning the underlying system activity and thresholds with the business process, the IT professional can truly understand the whole environment, not just their individual technical component. The most effective analysts will extend their knowledge into other business areas. At Lexmark, we discovered that we were able to solve “intractable” performance issues by simply adding hardware or capacity.

    Integrated IT operations is not a goal, it is the means by which digital enterprises can be managed in real time. The path to real time management is through service capacity guarantees, performance and availability management and using anomaly detection in the context of the business process to identify issues well before an incident occurs. We advise starting small and building an anomaly detection system for the heartbeat of the process that enables you to see both the forests and the trees.


    This article was co-authored by Murthy Malapaka, general manager, Transformation Services Cloud and Infrastructure Services at Wipro Ltd. He helps enterprises digitally rearchitect their operations to run on hybrid IT environments to achieve incident avoidance instead of incident management. He has assumed various technology leadership roles across application and infrastructure architecture domains, specializing in availability and reliability. Murthy has been providing consulting services to CIOs and CTOs in their journey from client server to on demand infrastructure services.

    — Brad Clay

  • Top Trends in DevOps for 2019

    Top Trends in DevOps for 2019

    DevOps is poised for healthy growth over the next several years, with analysts large and small weighing in with forecasts. For instance, IDC predicts the worldwide DevOps software market will reach $8 billion by 2022, up from $3.9 billion in 2017. Similarly, Grand View Research estimates the global DevOps market will hit $12.85 billion by 2025, registering a CAGR of 18.6 percent.

    Below are some of the most influential trends driving growth in 2019.

    DevOps Instrumentation in AI and Machine Learning will Increase Productivity Gains

    Web-based forms are the nemesis of process automation. Everyone dreads manual forms, but that’s what organizations use when they want to capture data from customers, employees or partners.

    AI and machine learning technologies are mature enough to reliably process voice, video, text and images. That means data-enriched forms could be filled out simply by making a phone call, taking a video, taking a picture or some other natural activity. The analog inputs from the external world are captured digitally and automatically.

    Of course, the error rates in such conversions would depend on how well the AI models have been trained and how well we use the real-world input to enhance the model. DevOps-level instrumentation needs to be introduced in the pipeline. That way, either the customer or the person in-loop will be able to take these errors as inputs for enhancing the accuracy of the models.

    Key Management is Key for DevOps

    In 2019 and beyond, data usage will be closely monitored as GDPR becomes a reality and similar privacy laws are passed across the globe. This is when data tagging becomes critical. Therefore, tools related to data tagging and master data management will become crucial for tracking the origin of data usage.

    Sensitive data will need to be encrypted in rest and in motion. Along with data encryption comes the important responsibility of managing encryption keys. Not only should the keys be stored securely, they also may need to be rotated. Key management services that offer such functionality will become commonplace in the DevOps world.

    Container Adoption Increases with Data Locality Demands

    Data locality is driven by countries that mandate data must reside within their geographical boundaries. Enterprises using SaaS or PaaS will use country-specific public clouds or even private clouds. As a result, critical data and applications will have to be deployed across geographies. Deployments will become more complex due to geographical expansion as well as agile development methodologies.

    In response, container-based development, release and deployment models will become commonplace within the enterprise. While containers offer many advantages by creating siloed workloads, they also increase the demand for sophisticated monitoring tools and technologies that help consolidate the view of these applications.

    The Compiler is the New King of the Data Center

    The demise of Moore’s Law is not helping the CPU keep up with increasing workloads in the data center. To bridge the performance gap, modern hardware such as GPUs, FPGAs and ASICs will infiltrate the data center.

    Developers will start using higher-level languages such as OpenCL and CUDA, and the compilers will generate code to run on the various hardware, depending on deployment-level input including workload, hardware configuration and data size. DevOps practices will have to start befriending compilers so that code can be generated just in time, very close to the point of deployment.

    Technological advancements, security requirements and legislative changes will impact the professionals within this sector, which is growing at a rapid pace that could see it double within five years. As developers prepare to manage a higher volume of sophisticated data, an increasing amount of DevOps solutions will enter the market to further automate processes, accelerate deployments and address the above trends.

    — Shailesh Kumar Davey