Tag: devops

  • The Role of a Traditional NOC in the new DevOps World

    The Role of a Traditional NOC in the new DevOps World

    This new question in the devopsy.kinsta.cloud Enterprise DevOps Q&A series comes from a large business, though not what many would recognize as a traditional or legacy enterprise. This organization, like many high-growth businesses, is in a relatively new market segment that only exists due to the rise of cloud computing and digital media. In their business, the network (especially access to and from their public cloud service) is critical to the value they provide their customers.

    So it is no surprise then that, as they contemplate their transformation to an agile environment built on DevOps principles, they are asking me about the role of the Network Operations Center (NOC).

    1. What Role Does a NOC Play in the DevOps World?

    Despite coming from a ‘new tech’ business, this is another of the questions that is typical in a large enterprise. While smaller startups and even many web-scale businesses may have an Application Support team, not many run their own NOC, and even fewer separate out these roles from the rest of the operations team.

    First, some things do not change in a DevOps world. Fundamentally, the NOC is still tasked with maintaining high quality production networks and systems, detecting potential problems as soon as possible, triaging those problems to find root cause, and remediating problems as fast as they can.

    However, the NOC team will gain additional activities and support a broader interlock beyond just the production environment, especially as networking becomes more embedded in application delivery through capabilities like software-defined networks and cloud computing. They will work more closely with teams like app dev, SQA, pre-prod and release; they will provide input to design and development; and they will contribute earlier in the software cycle. This is the logical outcome of a DevOps approach that emphasizes the need to work more collaboratively across the entire end-to-end SDLC.

    So you should consider bringing these network specialists into:

    • development planning, to help architects and engineers to build applications with operable networking by design, including software-defined networks that help make a truly idempotent application
    • testing and QA, so they can provide engineers and SQA teams with tests and analysis that accurately reflect the reality of the prod network, rather than leaving network testing to after production deployment
    • dev/test support (where they may already be acting), to ensure that the environments that dev/test rely on to create new capabilities are just as stable and reliable as the systems they will eventually be deployed to
    • release and deployment, to ensure they have input into determining and defining ‘known good values’ for production monitoring and for problem diagnosis, triage, and escalation – before release, not just after
    • expanding interoperability and self-service, by exposing ‘known-good’ deployment, triage, and (re-)configuration capabilities as automated software-defined processes (or APIs) that dev/test can use without opening a new service ticket
    • a broader role in ensuring the end-to-end quality of the network, alongside traditional operations/infrastructure support as part of a new role commonly referred to as a ‘Site Reliability Engineer’ (SRE)

    Because DevOps is about improving collaboration, remember too that you should also bring dev, test, QA, etc. into the NOC, and even rotate them onto support, so they have an understanding of the core operations of a production network, how their code acts in a real environment, and how their work affects other teams. This will help to build the empathy between teams that is a core tenet of DevOps.

    You may be concerned that asking your NOC to work more upstream is adding a load of work to those teams that they didn’t have before. That may be true, but a significant outcome of Enterprise DevOps in practice is to reduce the ‘busy work’ of such teams, free them up to do more ‘smart work’, and to do it earlier in the software lifecycle.

    For example, recent research has shown that DevOps is correlated with improving the quality of applications (especially before they hit production), reducing the amount of time and effort the NOC team spends on problem detection, triage, and remediation. In fact, in this research, ‘reduction in time spent fixing and maintaining applications’ is one of the strongest outcomes, with an average 21% reduction in this metric.

    Similarly, standardizing on known-good processes, APIs, configurations etc., and enabling other teams to employ self-service and software-defined networking capabilities will allow the NOC team to spend less time on routine responses to things like servicing provisioning and configuration tickets.

    I cannot guarantee they will not be a zero-sum game, especially in the short-term, but over time a DevOps approach should actually spare workload from the NOC team, freeing them up to ‘shift left,’ moving their talents earlier in the SDLC, as they communicate, collaborate, and integrate more closely with upstream teams like dev, test and QA.

  • Measure Twice. Automate Once.

    Measure Twice. Automate Once.

    “Shipping” code may start with the completion of development but it doesn’t end until after the operational delivery process ends. Just like any fulfillment process, shipping is actually just the kick off of an often arduous journey that ultimately delivers the app to the end user.

    Ship It

    Back in the old days (when they still let me write code) one of our favorite phrases was “ship it” to indicate completeness of a task. That’s because the ultimate goal was, of course, to “ship” the code off to the users so they could start doing whatever it was they were going to do with it*.

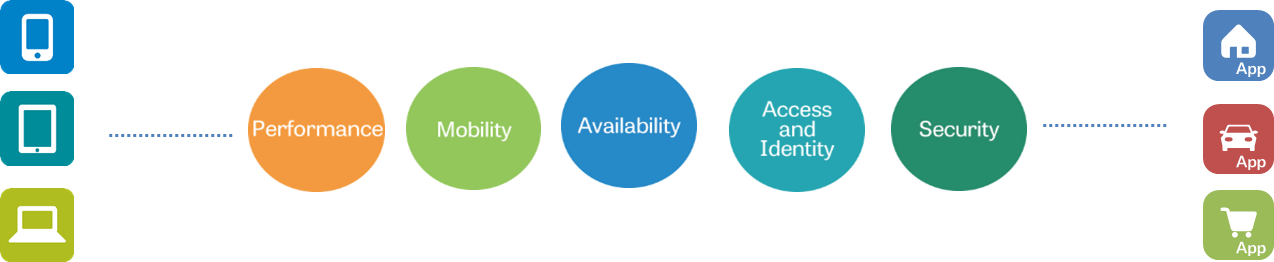
    But the reality was, of course, even when we were really ready to “ship it” to users that it didn’t actually get to users for varying amounts of time. Like shipping anything today, it depends on the shipment method. In terms of today’s enterprise IT, “shipping method” is really a metaphor for the operational approach to deploying all the infrastructure – the “middle boxes” – with the services required to actually deliver a secure, fast and available application to its ultimate users.

    app-services-2

    We know from various studies that this takes time. From days to weeks to even months. And we know we don’t like that and we want to improve it. Which is where DevOps comes in, or NetOps or SDN or SDDC or SDO or whatever you want to call it.

    Speeding up the deployment process is certainly one of the goals of operationalizing the network, but without a baseline how do we know if we’ve gotten faster in the first place?

    That’s a piece of the DevOps puzzle we’ve been ignoring – the need to measure the deployment process. You might notice that “measure” is bolded and in red, that a visual clue meant to reinforce the importance of the measurement aspect of DevOps. If you aren’t measuring how long it takes to deliver that app from dev to its destination – production use by an end-user – then you have no idea which pieces of the process are holding you back. You can’t effectively determine where automation might be applied to improve the time it takes to get to market. You don’t know exactly where the obstacles are that need to be addressed in the first place.

    While we can make some assumptions based on long experience and research and point to handoffs across the IT silos, the reality is that there probably isn’t just one handoff between ops and the network and there may be multiple intra-IT group handoffs. For example, the network ops that handles provisioning network services might not be the same team that handles load balancing and performance services. But they’re both within the “network” silo. There may be multiple handoffs back and forth as various services also need networking services on top of the ones required by the app itself.

    Image Credit: Gaping Void
    Image Credit: Gaping Void

    Without some kind of measurement of how long each of the various steps is taking it’s impossible to determine exactly where the bottlenecks in the app deployment process are in your organization. I can not only determine where that Minecraft Lego set I ordered for my son’s birthday is right now, I can see how long it’s taken to get from each point in the process. I know it goes from point A to point B in X days, and from point B to point C in Y days, and I know if there’s a winter storm that it’s going to cause a slowdown in that second step (which is called a movement in the logistics vernacular, in case you were wondering. I knew you were, you’re welcome!)

    Measure Twice. Automate Once.

    The hidden value in setting out to measure the deployment process is in pulling together an understanding of the process itself. It’s in finding redundancies and discovering sub-processes that are running in serial but could be running in parallel to improve them. It’s not necessarily about automating the whole thing up front, it’s about understanding what the process is and making it more efficient – whether through elimination, reorganization or automation (or all three).

    You don’t simply want to be automating things willy nilly without any idea whether it’s going to do any good. As my dad taught me about working with wood, you measure twice and cut once. With DevOps you want to measure twice (at least) and automate once. Otherwise you may be wasting cycles on one-off tasks or tasks so specific to one application that automation has no real value because it’s not the same across applications.

    The key is to start with defining what you’re going to measure, do the measurement and then analyze it to determine what you need to improve.

    Because automating just for automation’s sake isn’t any more fruitful in the end than adopting technology for technology’s sake.


    * I say “whatever” because over the course of my career I’ve worked on tax software, GIS software, communications and transportation and logistics systems. There’s a lot of variance there in what end users might be doing with “the app”.

  • DevOps: Where are we with that?

    DevOps: Where are we with that?

    There’s a great scene in the Kids in the Hall movie Brain Candy, where the CEO of a major pharmaceutical company informs his executive team that the board has recommended a massive restructuring plan that will cut their research outlay by 60%. Only seconds after first mentioning this undertaking, the CEO turns to his yes man, Marv, and asks:

    “Where are we with that?”

    Marv responds: “The thing you just mentioned just now?”

    And after getting an affirmative response, Marv foolishly, yet not surprisingly answers:

    “Oh, we’re on top of that, Don.”

    It’s not hard to imagine this same scene playing out in real life where the restructuring being recommended is that found in DevOps. Marv and his fellow executives have agreed to a restructuring plan that’s going to dramatically affect the flow of work and the lives of many people at their company, but without having any real idea of why this plan is needed, how much it will cost, or even where to begin. They’ve just been asked to reduce the cost of their product by 60%, and to begin, well, five seconds ago.

    Sound familiar?

    There was a time when DevOps was possibly an even bigger buzzword than it is today, but that doesn’t mean it has gone anywhere, or lost popularity. In fact, its adoption has only increased since the term was coined, and it can be found everywhere from the smallest shops—all the way to massive enterprises.

    So why is it still so hard to successfully pitch DevOps to executive leaders?

    We’ve written before that the ambiguity around DevOps’ definition is one of the primary causes of the confusion surrounding the term, and the debate between whether it’s a “mindset” “practice” or “cultural shift” will likely never die (just don’t let anyone tell you it’s a “tool”).

    Rather than argue the buzzword’s definition, many at last year’s DevOps Enterprise Summit argued that the best way to promote a DevOps initiative at your organization, especially to your executive leaders, is to not call it DevOps at all.

    Since I’ve always liked the term DevOps, it’s taken me a while to come around to this concept, but I think those esteemed speakers are on to something.

    Vendors, analysts, the media, and other stakeholders have all had enough time to develop their own personal assumptions around DevOps. Maybe it was first proposed to them by an overblown consultant, or it was part of the failed vision of a former executive who is now on the outs. All it takes is one negative DevOps word association within your leadership and your noble pursuit of its buy-in could be quickly derailed.

    So if you don’t call it DevOps, what do you call it? “Lean IT?” “Agile Innovation Processes?” “Continuous Flow Delivery?” “ Industrialized Software Development?”

    It’ll take you more words, but I’d recommend using DevOps’ results, and not any perceived buzzworthiness of the term alone, as its primary selling point. While “more words” means “more time”—something your e-staff likely has very little of—you’ll both get and hold their attention much quicker than just saying “DevOps” and expecting the applause and champagne to start flowing.

    Gene Kim’s definition of DevOps supports this concept, and in a recent interview he remarked:

    I would define DevOps by the outcomes. In my mind, DevOps is those set of cultural norms and technology practices that enable the fast flow of planned work from, among others, development, through tests into operations while preserving world class reliability, operation and security. DevOps is not about what you do, but what your outcomes are.

    For those who are somehow just learning about DevOps, or for those who have known of its existence for years now, but who have been hesitant to pitch it to their own leadership, the good news is that the outcomes of DevOps are being proven not just at big names like Disney, GE, and Netflix—they’re even being felt by those who’ve implemented it at non-Dev or Ops fields like Security, and even Design.

    Your VPs of App Dev and QA will likely be impressed by your mention of accelerated feedback loops and reduced defects. Your IT Operations leadership, no matter what distrust they harbor for app dev, would have a hard time arguing against increased visibility into the delivery pipeline, and better quality when the software lands in production. Then when the CEO hears about faster service delivery and improved time to market, you may as well start sketching out your plans for that corner office.

    (Editors note: Author’s promise of a corner office is his own, and is not guaranteed by Skytap)

    About the Author/Noel Wurst

    noel wurst

    Noel Wurst, Managing Editor at Skytap, Noel is responsible for setting and executing Skytap’s content marketing strategy. That includes overseeing the creation and distribution of high-quality, targeted content, and managing the team and external resources associated with those efforts. By leveraging deep online marketing, project management, and editorial experience, Noel plays a crucial role in helping generate and nurture leads with compelling content. You can follow Noel and Skytap at @NoelWurst and LinkedIn and @Skytap, Skytap’s LinkedIn 

  • The Trouble With Enterprise DevOps

    The Trouble With Enterprise DevOps

    The literary world and beyond has been up in arms as of late regarding the use of the word ‘literally’. It seems that many are using the word literally when they mean figuratively. For example, if you say, “I literally split my pants laughing,” it would be plausible for one to look at your pants looking for a tear. Words are funny that way. When used to emphasize the action or outcome, some will take literary privilege. Enterprise is also one of those words that are used to convey emphasis often with disregard to the implied meaning.

    When it comes to DevOps there has been a lot of debate about the modifier ‘enterprise’. Modifiers are supposed to add specificity to the noun it is modifying. Agreeably, enterprise is a horrible modifier for DevOps when used without additional modifiers representing scale. I have been, and continue to be, a big advocate of the concept of Enterprise DevOps. That said, I too have been remiss in my use of the word enterprise to further modify with the term ‘large-scale.’

    I don’t remember exactly what triggered me to seek out if the word enterprise implied large, but when I did I was surprised to find that there is no implied meaning that enterprise means large and, in fact, can be modified with small-, medium- and large-scale to represent the appropriate size. As further evidence to the ambiguity of the use of the word enterprise, I worked for a company that divided their sales organization into enterprise and commercial accounts. Clearly, this organization believes that enterprise connotes large-scale since this group was responsible for selling to a specific class of customer that spent a significant amount of money with them. In this case, scale was identified by how much money the business spent with that vendor versus annual revenues versus number of employees. So, clearly, not only does the word enterprise not imply scale, but it also has different metrics that will determine the scale of an enterprise.

    Merriam-Webster defines Enterprise as follows:

    en·ter·prise


    noun
    \
    ˈen-tə(r)-ˌprīz\

    : a project or activity that involves many people and that is often difficult

    : a business organization

    : the ability or desire to do dangerous or difficult things or to solve problems in new ways

    Obviously, none of these meanings relate to size or scale, but two of the meanings do indicate difficulty. Let’s put that in the parking lot for later.

    Why is this important? With regard to IT, I believe there is a tendency to throw around the word enterprise with no modifiers when we mean large-scale. For example, “Enterprise Software” is a term that is often used to describe very expensive and complex software applications that are designed to operate at the scale of the entire business versus the individual. Typically, the software described by enterprise software is found in mid- to large-scale enterprises where they can afford to acquire, configure and operate this type of software. Likewise, “Enterprise Storage” is a way to describe compute data storage environments for large organizations.

    Likewise, “Enterprise DevOps” is a term that that is often used to represent adoption of DevOps practices in large, complex organizations with many different stakeholders and sub-organizations making it much more difficult to coordinate efforts around efforts like continuous delivery and continuous improvement.

    Interestingly, and I believe accidentally, implementing enterprise software and adopting enterprise DevOps are difficult projects. So, based on our Webster’s definition, enterprise works as a modifier for these nouns. But there’s still the issue that for small-, mid- and large-scale enterprises the challenges and hurdles associated with DevOps adoption vary enough that the constraints and bottlenecks require different approaches to remove. This is especially true of large-scale global enterprises where development exists in four continents, operations data centers exist in multiple countries on four continents and the business operates in six continents with a comprised IT staff of 120,000 people.

    I for one will be very careful in the future to define what I mean when I’m using the word enterprise in the future. If I’m talking about large-scale enterprises, which I usually am, I will make sure that early on in my writings and presentations I specify that when you see enterprise going forward I’m talking about large-scale enterprises.

  • Security Should Be the Top Driver for DevOps

    Security Should Be the Top Driver for DevOps

    I’ve often said that the driving factor for many companies in adopting a comprehensive information security program are the dreaded “F” and “A” words – FUD and Audit. Technically FUD is an acronym for fear, uncertainty and doubt. And it might be better said that audit is the action used to hopefully demonstrate compliance and trust.

    Just a few years ago, the predominant drivers for security spending were regulatory and compliance requirements. While compliance remains a driver today, the primary moving force for many is the concern of cybercrime. Fear of being the next Sony, Target, Chase or countless other victims is driving information security budgets to be readdressed.

    In a recent CA survey the top obstacle (28%) to DevOps in their organization were security or compliance concerns. Yet, in the same study, a huge percentage (88%) already have or plan to adopt DevOps in the next 5 years. The dichotomy of the situation has not escaped me. Organizations are in a situation where they are actively spending money on DevOps and information security, but at the same time view these two initiatives as counter.

    The answer is simple, information security teams need to adopt DevOps principles.

    While a widely agreed upon definition of DevOps is still up for grabs, its safe to say that DevOps is generally inclusive of a few core tools and principles. First, DevOps promotes a culture of cooperation and sharing among different groups in an organization. Second, DevOps promotes the use of heavy automation, decreasing time to market and agile development.

    Information security’s goals are the CIA triad – confidentiality, integrity and availability. Security teams argue that DevOps is the antithesis of good security. Constant change, open culture and automation smack directly in the face of security’s tactics of compartmentalization and tight process control.

    Here is a little secret – DevOps is winning, information security is losing.

    DevOps teams are deploying code faster and faster. They are reducing time to market and increasing revenue. Information security teams, well, lets just say that they continue to be in the news for the wrong reasons.

    The second little secret – the companies which are really winning are using DevOps tools and principles everywhere in their organization. Even in information security. Imagine overseeing infrastructure configurations with code that ensures compliance 24×7 across an entire organization. Or picture being able to instrument thousands of data points to benchmark security performance over time. Conceptualize being in charge of an automatic closed-loop security system which automatically takes action to mitigate attacks based on shared threat intelligence. These are possible with DevOps.

    For all that DevOps provides, security should not be a hinderance to DevOps adoption. Instead, security should be a top driver for adopting DevOps. Using DevOps to create the next generation information security program might just be your only hope in combating the next cyber threat.

  • DevOps needs infrastructure multi-tenancy

    DevOps needs infrastructure multi-tenancy

    DevOps will, under whatever moniker you want to give it – NetOps, DevOps for Networks, operationalization – continue to make inroads into the network infrastructure because ultimately it’s part of the application deployment lifecycle. While DevOps folks call it “application delivery” the reality is that an application is not ready to deliver to a user (internal or external) until all its requisite services have been provisioned and configured.

    Yes, infrastructure and network devices are increasingly API-enabled and supportive of a variety of tools and frameworks most often associated with DevOps – Puppet, Chef, OpenStack, VMware – and those more commonly associated with just the network – Arista, Cisco ACI, and OpenDaylight.

    But it takes more than APIs. APIs do not inherently bestow upon devices the ability to support multi-tenancy. That is, the isolation of services unique to a team (or application) required to effectively deploy application-supporting infrastructure services within what is traditionally a shared environment.

    According to ThoughtWorks Technology Radar (jan 2015) partitioning infrastructure along team bounds is becoming an imperative to removing roadblocks in the application deployment lifecycle:

    Many of our customers have made DevOps a reality in their organization with delivery teams that build, deploy, and support their own applications and services.  Unfortunately, a regular roadblock on that journey is allowing teams to have superuser privileges in production environments.  In most organizations, the production environment is shared, and therefore risky to provide access widely.  It is effective when we can partition infrastructure along team bounds,so that those teams can have safe isolated access to do their work, without risking impact to other systems.  Where cloud environments are used, this is much easier to implement, aligning account structures to team boundaries.  [emphasis mine]

    This has always been an issue where shared services are relied upon. A change to support one application (or team) can be disruptive or cause issues for another application or team. Thus, most infrastructure and network teams staunchly refuse to let anyone in the application or operations side of the house play with their toys.

    They are the network ninjas; guarding their configurations with their very lives.

    It’s this kind of conflict that needs resolution if we – as a unified IT organization – reach goals of improving the time to market and frequency of deployment. It doesn’t matter if the app team can deliver an app in 3 weeks if it takes 3 months to deliver it to the customer because of overloaded network and infrastructure staff.

    There are two good solutions to this problem*.

    1. The governance over more application-affine infrastructure services – load balancing, caching, proxies, etc… – is necessarily moving closer to the application and under the control of app and operations teams. This is supported by concepts like Network Service Virtualization, proposed in Lippis Report 217 as well as the increasing adoption of open source proxy-based (virtual and software) services.  This model assumes continued shared network and infrastructure services as appropriate while migrating per-application services to the more agile, operational architecture.

    2. The introduction of multi-tenancy in infrastructure architecture provides a similar approach while still maintaining shared resources (hardware). A single, high capacity system is able to host multiple, virtual instances of its services, each dedicated to either teams or applications, as is the organization’s need. This approach spreads the cost of the hardware resources across the entire organization while allowing a more per-application approach to provisioning, configuration and ultimately, cost. Isolation addresses the concerns of shared resources and configurations that can cause consternation among network and infrastructure teams because the underlying shared system is managed by them while role-based control over application services is offered to teams or designated responsible individuals.

    Both approaches are valid and in many cases both architectural solutions will be used to resolve the issues caused by traditionally shared infrastructure.

    The key takeaway here is that there are answers to the need for partitioned infrastructure that are supportive of DevOps-driven workflows and processes and can certainly provide a path toward ensuring a more seamless, time-sensitive end-to-end application deployment process.


    * Oh, I’m sure there’s more, but right now these appear to be the best two options.

  • Why DevOps is like fitness or religion

    Why DevOps is like fitness or religion

    What is DevOps?

    I noted in a blog post last summer that limiting DevOps to a single definition is challenging. The Wikipedia entry for DevOps contains a variety of possible explanations that seem to disagree in some ways:

    • It’s a “software development method that stresses communication, collaboration and integration between software developers and information technology (IT) operations professionals.”
    • The goal of DevOps is “to maximize the predictability, efficiency, security and maintainability of operational processes. This objective is very often supported by automation.”
    • It “targets product delivery, quality testing, feature development and maintenance releases in order to improve reliability and security and faster development and deployment cycles.”
    • It “aids in software application release management for a company by standardizing development environments.”

    All of these are true, and yet none of them is necessarily THE definition of DevOps.

    A recent ZDNet post titled Why there will never be one do-it-all DevOps tool proclaims, “There is really no such thing as a specific DevOps “tool”—and don’t buy into the “DevOps” labeling many vendors are attaching to their solutions. Successful DevOps depends upon a multitude of tools and methodologies that can help organizations better align their software development and release cycles.”

    The question, “What is DevOps?” isn’t like asking, “What’s the temperature today in Phoenix, AZ?” or, “What’s the fastest land animal?” Those questions have precise answers that are based on measurable, irrefutable metrics. The answer is the answer and it isn’t really open to debate.

    “What is DevOps?” is more like asking, “What is the best fitness program?” or, “Which religious belief system should I subscribe to?” There is a vast array of answers and passionate beliefs on all sides. But, there really isn’t so much a “right answer” as a “right answer for you”.

    When it comes to fitness, there seems to be as many diet and exercise programs as there are people trying to get fit. Books, magazines, and infomercials are filled with extraordinary examples that “prove” that a given fitness program or philosophy works…at least for the subject of the story. There are some elements that are universal truths like exercise is better than being sedentary, and making healthy eating choices is better than eating an entire cheesecake for dinner. Almost everything else is subjective. There are too many variables involved that make people, and how they respond to different diet and exercise programs, different.

    DevOps is also like religion. Most people don’t choose their faith. They’re raised from birth to follow in the footsteps of their parents, and their religion is more or less predetermined. Religion is also personal. While some will insist that there is only one true faith and that theirs is the only real religion, most people recognize that religious faith is very subjective and it’s a function of finding the belief system that makes sense to you.

    DevOps is like fitness and religion in that what it means to an organization, and how it is first implemented, is influenced by the existing culture and infrastructure—the IT the company was “raised on”. DevOps is also like fitness and religion because there is no “one-size-fits-all” answer to the question “What is DevOps?”

    It isn’t a defined process—it’s more of a concept or philosophy. It isn’t a product or service that can be packaged and sold—it’s more a collection of the products and services that enable you to embrace the concept or philosophy. To some extent, DevOps is whatever works for your organization to automate routine tasks, reduce redundant effort, streamline operations, and remove unnecessary obstacles so people can get things done as efficiently as possible.

  • Webinar: Security & DevOps in 2015

    Webinar: Security & DevOps in 2015

    The intersection of Security and DevOps. What does 2015 hold in store? Organizations are under increasing pressure to do more, faster. But cybersecurity breaches by criminals, hacktivists and state sponsored actors have cast a shadow over large portions of our IT infrastructure. How can security and DevOps in tandem make us safer while allowing us to increase speed and quality? This webinar features a panel of experts in security, development and operations. We will explore what this year and beyond holds in terms of help as well as pitfalls. What can you do to build more security into your processes? How can you be compliant, secure and efficient? This year promises to be a watershed in security and DevOps. Join us in this webinar to hear an expert panels views on what it means to you.

    YouTube playback of the webinar:


     Slides

    [seoslides embed_id=”81ba77e9dda4″ script_src=”https://devopsy.kinsta.cloud/embed-script/security-devops-2015/4126/” overview_src=”https://devopsy.kinsta.cloud/slides/security-devops-2015/4126/” site_src=”https://devopsy.kinsta.cloud” site_title=”devopsy.kinsta.cloud” title=”security-devops-2015-webinar” /]


    Date: Thursday, January 29th, 2015


    Time: 1pm eastern standard time


    REGISTRATION LINK:(CLOSED) 

    About Speakers:

    Moderated by devopsy.kinsta.cloud co-founder and editor-in-chief Alan Shimel, the experts on our panel are:

    james-BrownJames Brown is Chief Experience Officer at JumpCloud. He works with the JumpCloud team to define product strategy, and set the overall usage and support experience. James’ background is in system administration, software development, security, and product management.


    Tim-MatthewsTim Matthews is VP at Incapsula.  Tim brings over 20 years of software sales and marketing experience at security and technology companies to Incapsula. Prior to joining Incapsula, Tim was CMO of CrowdFlower, the leading SaaS crowdsourcing platform. Tim holds a B.S. in Computer Science from Union College in Schenectady, NY.


    Stephen-Coty-headshotStephen Coty is Director of Threat Research at Alert Logic and also the author of the Cloud Security Report.  In his role at Alert Logic, With his wealth of experience in the security space, Stephen is currently in the process of building a premier threat research team that is innovating the industry.  He is also a member of ISSA, Infragard and the HTCIA.

  • Turn IT into a Service Catalog

    Turn IT into a Service Catalog

    Unless you live under a rock in the world of cloud computing, you’re probably aware of a growing generational gap between public clouds and enterprise IT. (more…)

  • Enter at your own risk: DevOps isn’t for everybody

    Enter at your own risk: DevOps isn’t for everybody

    There’s always a sexy new tech buzzword flying around, and it’s easy to fall into the trap of assuming that if a concept or technology is hot you need to hurry up and jump on board so you don’t miss anything. DevOps is hot, and seems to be almost ubiquitous these days. But that doesn’t mean that every organization should rush out and embrace DevOps.

    Defining what it is exactly that you think you’re embracing can be a challenge. The concept of DevOps is a bit broad and ethereal in the first place. The number of vendors calling their products or services “DevOps” just because it’s sexy marketing muddies the waters and makes it more difficult to figure out what DevOps is, and how it’s supposed to benefit your organization.

    Even if you think you have a fair grasp on what DevOps is, though, it still isn’t necessarily right for every organization. It CAN be right for most organizations, but there’s some introspection, and due diligence that has to come up front. More precisely, it isn’t necessarily right for every organization without a solid foundation of the right skills and resources, and an understanding of what you hope to accomplish, and how you plan to get there.

    Nathen Harvey, community director at Chef, shared some insight on this topic. “Through immense feedback from our community, customers and contributors we’ve learned a lot about how and when an organization should begin a DevOps transition. In short, everyone should not immediately jump on the DevOps bandwagon.”

    Harvey added, “DevOps is full of big ideas and big changes and therefore development and operations teams need to be prepared to work together through challenges and to collaborate toward a common goal.”

    James Bottomley, CTO of server virtualization at Parallels, cautions, “DevOps processes are supposed to be accessible to anyone. However, since current DevOps lifecycles are based on virtual machines, they are really only accessible to those with the skills to manage virtual images and, to make use of the live VM, administer base systems and platforms.”

    Bottomley explains that larger organizations often have the necessary skills available, and just have to marshal them toward a DevOps strategy. Small and medium businesses, on the other hand, often lack the appropriate resources.

    “If you are a SMB you should consider carefully whether you have the necessary Ops skills in-house and if not, how you are going to obtain them (whether from a [service provider] or other form of management). Ongoing Ops skills are vital to proper VM maintenance (fixing security issues and the like), so you have to make sure you have an ongoing Ops capability, not just a one-time one when the virtual system was created.”

    According to Chef’s Harvey, there are three specific areas organizations need to consider before embarking on a journey to embrace DevOps. They are the “Three C’s”: Character, Communications, and Community.

    · Character requires trust, respect, empathy, learning and perseverance.

    · Communication is meant to align objectives—such as setting metrics for everyone, and sitting close enough to easily collaborate with one another.

    · Community can take many forms, whether engaging in podcasts, conferences, sharing code and more.

    Don’t make the mistake of jumping on the DevOps bandwagon prematurely just for the sake of jumping on the DevOps bandwagon. It will be a frustrating experience almost doomed to fail and leave a bad taste in your mouth. Instead, take the time necessary to understand what DevOps means to you, figure out what you hope to accomplish by embracing DevOps, consider whether or not you actually have the skills and resources to make it happen, and develop a plan that includes the “Three C’s” so your DevOps journey can be a successful one.