Tag: devops

  • The ROI of Enterprise DevOps

    The ROI of Enterprise DevOps

    Ever since the 1996 film Jerry Maguire, I can never think about any technology development without hearing Cuba Gooding Jr as professional footballer Rod Tidwell screaming out, “Show me the money!” So I was not surprised when the CIO of a large enterprise recently asked me the enterprise exec version of that famous line:

    Q. Where is the ROI in Enterprise DevOps?

    Fortunately there is plenty of evidence to show enterprise executives exactly where to look when trying to determine the ROI of DevOps.

    “Show me the money!”

    Here on devopsy.kinsta.cloud, Rajat Bhargava has posted on talking to your CFO about DevOps, outlining four key areas of financial impact: generating cash, reducing expenses, enabling growth, long-term stability. I also had some ideas about financial aspects of getting executive support for DevOps in a great article by Erica Chickowski. And site editor Alan Shimel has posted some excellent insight on vendor-sponsored research from IDC on the cost-benefit of downtime avoidance.

    “Show me the money!”

    Not enough? Well, we also have several years of research on ROI factors associated with DevOps adoption in both small businesses and large enterprises. The company I work for, CA Technologies, has commissioned independent third party research into enterprise DevOps adoption since 2013; Puppetlabs has run similar research [PDF] with good data on all sized organizations, but especially mid-sized businesses.

    You can see in the chart below the areas where benefit accrues through the adoption of DevOps (taken from CA Technologies/Vanson Bourne research released in November 2014):
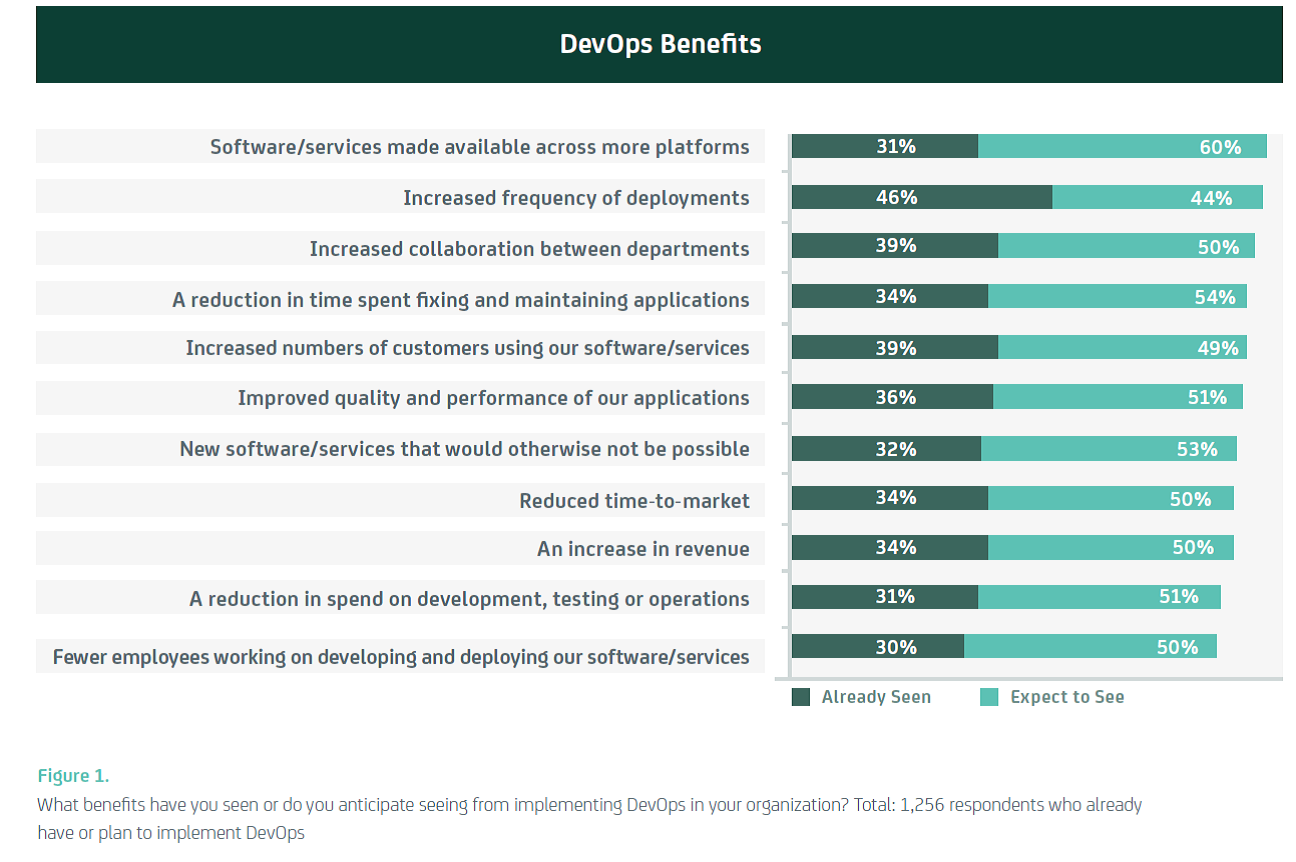
    Image 1

    Still need more? No problem! There is also good data on how much of a return you can expect from DevOps. Again, the following chart is taken from the same CA Technologies/Vanson Bourne research:
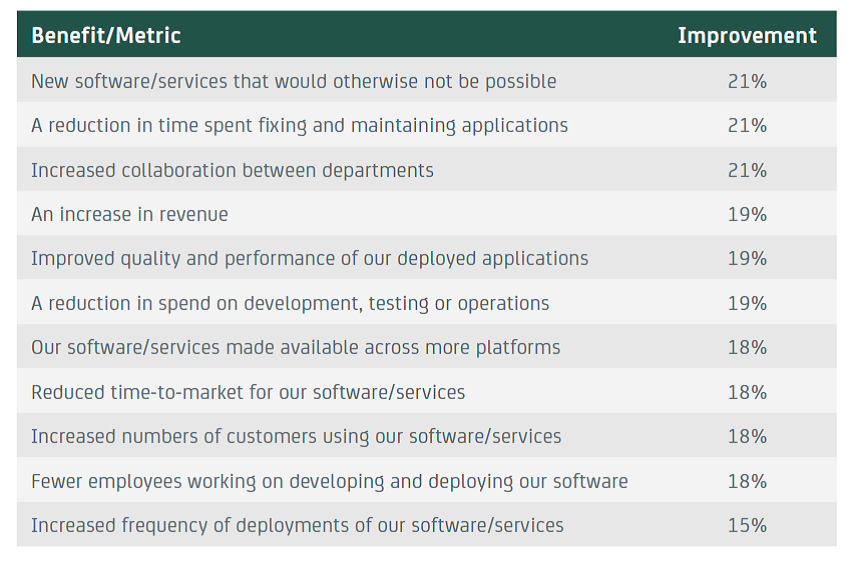
    Image 2

    Figure 2 Respondents report seeing double-digit improvements in key technology and business areas. Total varies by benefit. Figure 1 & 2 Source: Vanson Bourne/CA Technologies 2014

     “Show me the money!”

    Okay, I get it – you still want more, and you want a straight answer – a single, simple heuristic to work with. In talking with many enterprise CxOs, faster application delivery is a pressing goal, so just this one factor can act as a key ROI driver. At the Continuous Delivery (CoDe) conference in Copenhagen in October, Jan Bosch (Professor of Software Engineering at Chalmers University of Technology) showed very elegantly how faster delivery acts to reduce (i.e. shorten) the ROI period.

    His theory is based on the premise that for many (most? all?) businesses, time to revenue is dictated substantially by product release cycles. Maximum revenue accrues around product release, then tails off before spiking again for the next new product release. For example, a smartphone manufacturer will get revenue in 6-month peak and trough cycle as they release a new device twice a year; a software vendor will get a revenue peak with a new game release, which tails off until new DLC is released or a new game hits the stores.

    Because DevOps can accelerate business cycles, Jan theorized, business can bring in revenue faster, which in turn makes a DevOps-based business more profitable over the mid- to long-term. This is especially critical in the modern application economy where almost every business is a software business.

    So, for example, if DevOps allows a business to release twice as fast, they can effectively double their annual revenue, as seen below.
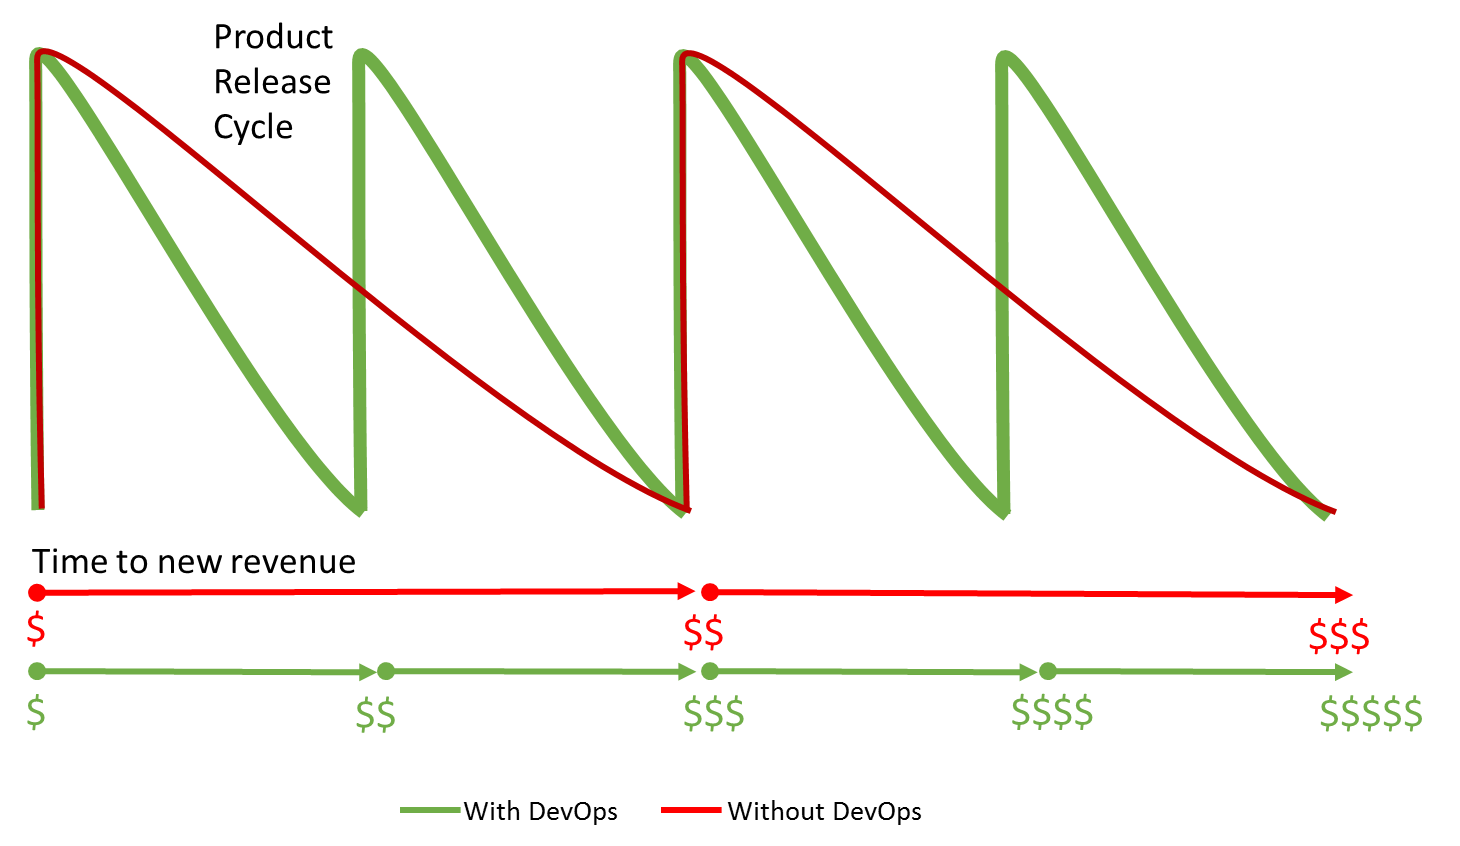
    Image 3

    Figure 3 Proportional revenue acceleration from doubling product release frequency with DevOps

    The impact is exaggerated for this illustration, but based on actual data (see above), a 20% increase in annual revenue would be on par with enterprise averages.

     “Show me the … costs!?”

    Of course, any discussion of ROI must realistically reflect costs too. Adopting DevOps in a large enterprise is not free – it requires investment in people, process, and technology. On the people side, even just a small cultural change often requires new activities and other behavioral shaping. Process change requires training and often impacts short-term revenues. Technology investment includes procurement of automation and measurement solutions – key components of a CAMS (Culture, Automation, Measurement, and Sharing) approach to DevOps, especially in a larger enterprise.

    Many of the investment factors can be seen in the following chart, again using CA Technologies/Vanson Bourne research:
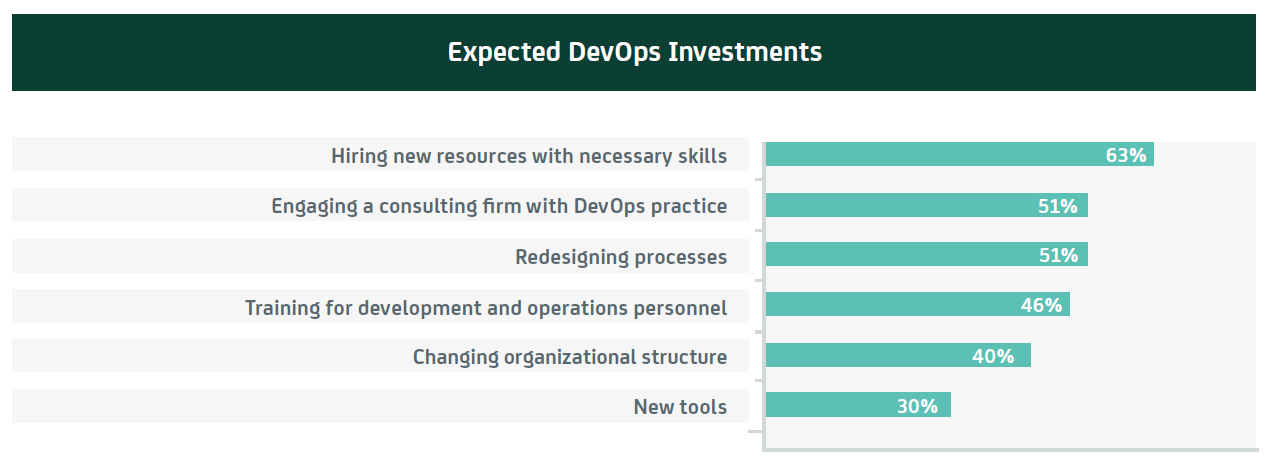
    Image 4

    Figure 4 Which of the following is your organization likely to invest in over the next year as part of your implementation of a DevOps methodology? Total = 499 ITDMs who have already or plan to implement DevOps in the next two years. Source: Vanson Bourne/CA Technologies 2014

     “Show me … my own ROI!”

    These ROI factors are of course a combination of averages, research data points, and anecdotes. As with all generalizations, when it comes to a specific enterprise your mileage may vary. However, this is certainly a good starting point when building a business case to prove the expected ROI for your organization.

    You may find other areas for ROI too – upstream in the PMO, DBA, or downstream in NetSec, training, documentation. If you have additional data points on finding the ROI for DevOps, I would love to hear about it. Add your ideas here in the comments, or connect with me and/or devopsy.kinsta.cloud on Twitter – at @AndiMann and @DevOpsDotCom respectively.


  • DevOps is Agile for the Rest of the Company

    DevOps is Agile for the Rest of the Company

    IBM held its InterConnect 2015 conference last week in Las Vegas. The event covered on a range of topics including hybrid cloud, mobile apps, and DevOps. One session I attended focused on Agile development and the parallels to DevOps were apparent.

    The session I attended at the Mandalay Bay Hotel was titled “How a Major Telco Improved Cycle Time and Business Results by Leveraging Agile”. Elliot Olschwang and Claudio Cozzi—both IBM employees—talked about helping a specific customer reach its goals by introducing Agile development principles. What struck me throughout the presentation were the many ways that the concepts the two talked about implementing at a developer level for this customer are very similar to the concepts companies must embrace on an organizational level to make the transition to DevOps.

    Rosalind Radcliffe actually deserves credit for pointing out the similarities to me. When I spoke to her a few weeks ago she told me that DevOps is just the Agile principle taken to the full enterprise. It provides a more comprehensive end-to-end perspective that enables enterprise-scale transformation.

    Agile development was an evolution from the Waterfall method. The Waterfall methods treats project analysis, design, coding and testing as separate and distinct phases that have to occur in order. There are many inherent problems with Waterfall, such as the fact that you don’t actually develop code until half way through the project. Testing would often be cut in the interest of time, and even if testing is done it’s actually too late. Any issues identified in testing mean you have to go back at least to the coding phase again—possibly back to design or even analysis.

    Agile removed the linear dependencies of Waterfall to enable development to occur more effectively and efficiently. Aside from imposing a more efficient workflow in general, Agile improves quality because testing occurs earlier in the process and more frequently throughout the process. Subsequently the risk to the project is reduced because there is continuous feedback that enables developers to adjust on the fly rather than having to go back to the proverbial drawing board at the end of the project lifecycle.

    DevOps is just a natural extension of Agile. It takes the guiding principles and best practices that Agile brought to developers and applies them on a much broader scale across the organization. As I pointed out in a previous article from IBM InterConnect, “Removing some of the friction between different groups and enabling the organization to function more effectively is one of the primary benefits of DevOps.”

    Part of DevOps is to streamline by automating those things that can be automated. Allowing tools to perform tasks so that other resources—namely the human beings—can provide greater value by performing less mundane work.

    The other part of DevOps, though, is a culture shift. It’s a change in the ruling philosophy of the organization that erases traditional barriers between departments and processes and enables everyone to function more efficiently without unnecessary overhead or “red tape”.

    That second part is where the principles of Agile development come into play. Implementing continuous monitoring for continuous feedback that leads to continuous improvement rather than staying mired in a linear flow that creates hurdles and roadblocks and results in resources sitting idle waiting for other teams to complete a task before the next task can begin.

    DevOps is hot now, but eventually it will mature and evolve into something else just like Agile has. It will be interesting to see in a few years how organizations that have embraced DevOps begin to take it to a whole new level.

  • Isn’t Continuous Testing a Longevity Test Anti-pattern?

    Isn’t Continuous Testing a Longevity Test Anti-pattern?

    Accordingly to Jim Coplien: “an anti-pattern is something that looks like a good idea, but which backfires badly when applied. “ In DevOps context, continuous testing is an attractive solution for the narrow context of testing specific software components quickly (in cycles measured in minutes or hours) but may be “bad” if the system that the software is a component of has failure modes (E.g., effects of memory leaks) that will only be observed during long term testing over several days and if the time between releases is greater than that. In other words, the pattern of quick test cycles prescribed by continuous testing appears to be a contrary Anti-pattern to the fundamental concept of long duration “longevity” testing. So what are the well formulated positive patterns that are applicable in its stead?

    In my prior blog entitled “From QA to Continuous Testing” I indicated “QA test experts that are most skilled in the best practices of test design are valued because they will produce the best quality products.” QA test experts assert that it is unwise to release a software product that has not been tested for durations comparable to the lifecycle of a release. Only tests that are run for a significantly long time compared to the release cadence are deemed sufficient. Just how long is long enough? This is a subject for further discussion beyond the scope of this short article, but my own observation is that best practices test environments run accelerated level load and impulse load traffic patterns on a build candidate for at least 48 hours or more before a release is determined sufficiently tested for at least limited deployment. Even 48 hours is much longer than typical “continuous testing” cycles. So “what positive continuous longevity testing patterns are applicable in its stead?”

    Continuous Longevity Testing Patterns may sound like an oxymoron but in fact longevity testing is compatible within the context of continuous testing principles. Below I describe three Continuous Longevity Testing Patterns that are sometimes used.

    Pattern 1: Longevity testing time windows are reserved such as weekends. In this pattern the regular Continuous Integration/Test cycles are interrupted during the weekend and longevity tests are only run on the build that was last created prior to the weekend time window. This has the advantage of not requiring any special test resources other than the resources used for regular CT tests and does not require any sophisticated scheduling to orchestrate the test environment. The disadvantage is that the longevity test results are only available weekly, it is hard to diagnose which build caused a longevity failure and problems with release candidates will delay the release for a week until the next longevity test run validates the fixes.

    Pattern 2: Longevity parallel testing is scheduled frequently, perhaps as frequently as every few builds, or perhaps daily. This pattern has the advantages that the regular Continuous Integration/Test cycles are not interrupted any time (they run 24/7), the longevity test results are available for more builds than Pattern 1, which reduces diagnostic complexity and may reduce release delays, but has a disadvantage that separate test resources must be reserved for each longevity test in parallel with the regular CT tests. For complex systems under test with many test targets and lots of builds this can be very expensive so there is a tradeoff between test resource costs, and the cost of delays if not done frequently enough.

    Pattern 3: Intelligent longevity testing is scheduled only when certain conditions trigger the longevity tests to be started according to smart rules that correlate software changes to problems with longevity performance. This pattern has the same advantages as Pattern 2 and has the further advantage that the cost of test resources is usually much less than Pattern 2 if the rules for the triggers don’t fire too frequently. The disadvantage is the entire scheme depends on the creation of a rules engine and rules that understand the risk of changes for long duration testing. If the rules are too lenient then this pattern might allow too many longevity failures to escape but if the rules are too tight then this pattern is not any better than pattern 2 and yet more complex to implement.

    So which Continuous Longevity Testing Pattern is best? The best answer is the one that best matches organizations’ goals for release cadence, cost of testing, and risk.

    So indeed, Continuous Testing is a Longevity Test Anti-pattern but fortunately DevOps infrastructures implemented according to best practices have a variety of complementary Continuous Longevity Testing Patterns to choose from.

    At Spirent we think testing has a bright future in DevOps. You can read more about our views at
    Spirent.com/solutions/devops

    What do you think of these patterns or do you have others that should be mentioned?


  • Tuning in to the real pain of customers

    Tuning in to the real pain of customers

    In my product management and marketing experience, I discovered that I carry a deep bias about our product capabilities and why it’s special — before a launch. On a whiteboard, in a spec, or in a usability lab, our product can and will change the world. Post-launch, when customers get their hands on our product, magical things happen. Intended use cases become irrelevant. Intended benefits change. Intended value changes.

    Over the past weeks, I’ve had the privilege of talking to many of our customers and prospects. They educated and helped me reframe the value we deliver to our customers.

    Real pain

    Much has been written about the DevOps revolution, driven by applications moving to the cloud, mobile computing, and the business need to compete. The journey to an agile build-test-release cycle is real, and it’s hard. It’s hard for customers who are cloud-born, and it’s even harder for traditional operations and development teams. Listening to our enterprise customers who are several years into their transformation, I heard a lot about the explosion of technologies and the cultural challenge. The pain of the change is more excruciating than I realized. One large customer told me that two years ago, he (VP of Cloud Operations) and his team couldn’t stand to be in the same room as the development team. Today, they’re collaborating to the point where they now sit together.

    Demanding developers

    Secondly, developers are more demanding. Again, it seems obvious, but hearing firsthand how hard it is to empower developers brings it home. Developers want and require more agile build, release and deployment capabilities, but they don’t want to be infrastructure experts. Enterprises are beginning to offer self-service to their private and public clouds so that developers can have autonomous access to environments and resources. A leading biotech customer told me that he can’t dictate policies and processes anymore, that he needs the researchers and scientists to adopt and embrace what the DevOps team is providing. Finding the appropriate balance between freedom and speed along with control is a common challenge across the board for our customers.

    Delivering value

    At ElasticBox, we talk a lot about the technology and cultural shift in enterprise DevOps teams, and how we can enable greater collaboration by being at the nexus of the transformation. That is what we ultimately deliver to our customers: a new way to deliver applications to the cloud that’s better, faster and more efficient.

    It’s a big promise, and we’re excited to fulfill it. Today, we deliver the foundational tools for self-service provisioning, service catalogs and continuous integration and delivery — wrapped with a flexible box architecture that’s reusable and agnostic to the underlying infrastructure and deployment tools. We approach the problem from a developer mindset to drive speed and autonomy, and at the same time, provide the policies and reporting to ensure scale. We’re hungry to continue learning from you, so check us out and let us know how we can help.

  • Digital Transformation with Agile and DevOps – Something “Wicked” This Way Comes

    Digital Transformation with Agile and DevOps – Something “Wicked” This Way Comes

    Our world is full of wicked problems, like climate change, urban planning and social injustice. They’re called wicked because they’re hard to recognize, define and solve. Furthermore, complex interdependencies mean solving one aspect will just expose or create other problems.

    Today’s digital transformation imperatives are creating wicked problems for IT. So wicked in fact, they make managing technology in the traditional sense look like child’s play.

    Suddenly, businesses are faced with complex dilemmas. How can they compete in a world where their customers place less emphasis on physical products and more on the total experience?  How can we adjust marketing from driving consumer behavior to responding to it? How can they adapt business models in context of the customers’ world? – a world that’s increasingly dependent and driven by digital technology.

    The short answer is of course software, but the problem is our approach to delivering it just isn’t suitable in a wicked business world – why? Well its simple – we keep working on the assumption that we understand the problems we’re trying to solve, when in fact we don’t understand the problems of our customers at all – that is, until we have a solution.

    Head scratching stuff huh, but consider this –

    Did you know you had an entertainment problem before Apple gave you iTunes? Was booking hotel accommodation such a pain before AirBNB introduced the whacky notion of people renting out their own rooms?

    So faced with such wickedness what can we do? Well, we can start by accepting our current IT failings, develop some wickedness of our own, and mitigate against what can derail your efforts.

    Small is Beautiful … really it is!

    In the past we’ve tried to solve business problems with what I call IT “bigness” – big iron, big software applications, big teams, big projects, and big expectations – oh, and let’s not forget big funding. The results, however, haven’t set the world on fire have they? – Big IT white elephants, big budget blowouts and big executive fallouts (literally and through the revolving door).

    But surely we can’t lay the blame squarely on IT. After all, traditional models of software design and project management where we diligently survey the client’s needs are baked in common sense. Add to this the rigor and procedure around sign-offs, budgeting, design, development, testing and deployment – doesn’t this guarantees success?

    Of course it doesn’t. Apart from the big fat fails, we also end up with what I call a big “sucking culture”– your software sucks, IT operations sucks, this job sucks, our business sucks – we’ve all been there, haven’t we?

    All of this isn’t due to bad people and technology. It’s because we work on the premise that the business understands what it wants – it doesn’t. Much better then to put aside “bigness” and start listening (maybe insisting) that the business first lays all the wicked cards on the table, like – what are our markets and how is this changing? What are our target demographics? What are our barriers to entry?

    After all this ‘warts and all’ revelation, it’s time to get busy. Now, with a shared understanding, we can start quickly prototyping elements that perhaps only solve one small problem. Then we continuously develop, test and demo, knowing and accepting other problems will surface that need to be solved. And, as we know from agile development, it’s all a case of ‘rinse-and-repeat’ – hopefully achieving a state of nirvana – giving your customers software answers to problems they don’t know they have. Problems that lead to increased market share, revenue and profitability.

    So is a liberal scoop of Agile or its younger DevOps cousin the answer? Not necessarily — that is until some essential toppings and flavors are added to my somewhat vanilla perspective:

    • Executive Flag Waving – try selling a methodology or philosophy based on the premise you’re trying to solve problems you don’t yet understand. Good luck with that. If executives simply want faster, better, cheaper, it’ll be much easier (and safer) to hold back grandiose talk about experimentation, “failing fast” and continuous improvement. Understand, however, that without tangible commitment, half-assed agile or DevOps is like a fast melting ice-cream cone – messy and hard to handle.
    • Behavioral Hacking – even with executive champions, persistent and rigid organizational behaviors will need to change. Just hiring lots of agile coaches or mandating DevOps won’t work until there’s willingness for people to be engaged around new ideas and fresh thinking. With that in mind, be prepared to do some heavy lifting – socializing and selling new concepts, but also looking for opportunities to show how the smallest of changes (e.g. team refactoring, incentives) lead to improvement.
    • Show me the Money! – So how to you fund agile and DevOps? It’s going to be tricky to cost something exactly when you don’t know the exact outcome of a new project, but businesses may initially insist on this to minimize risk. My advice here is to tread carefully. Stakeholders should be more interested in ROI than coming in under budget, so fixed-cost might not be actually what want anyway. Your job therefore is to convince them by continuously demonstrating ROI – not just from a single project, but also by the accrued savings that agile and DevOps deliver the whole organization when they systematically reduce technical debt and waste.

    Developing the wicked traits I’ve described doesn’t mean IT has suddenly become an evil entity. Nope, it’s just a case of tapping into fantastic business opportunities in a constantly changing digital world. Agile and DevOps can help you solve and even create some wicked problems for your customers, but that involves confronting and challenging entrenched thinking as it relates to just about everything.

  • How Deploy Frequency Impacts Infrastructure Stability

    How Deploy Frequency Impacts Infrastructure Stability

    I recently took some time out from reading the Internet to read a very specific piece of research I found on the Internet from IDC – its “DevOps and the Cost of Downtime” to be exact. Sponsored by AppDynamics, this fascinating read included a variety of statistics that are helpful in understanding the impact of (or a lack of) DevOps on organizations given certain financial and competitive impacts.

    I won’t bore you by repeating what you can so easily read yourself, but I have pulled out a few key stats that are worthy of further investigation – that of the failure of  stability on the business and the predicted increase in deployment frequency.

    • The average hourly cost of an infrastructure failure is $100,000.
    • The average hourly cost of a critical application failure is $500,000 – $1M.
    • The average number of deployments per month is expected to double in 2 years.

    Interestingly, that prediction on deployment frequency is a good thing and carries with it the possibility of making sure the costs associated with the other two rarely (if ever) happen.

    We’ve already gotten to a point where “speed” with respect to DevOps is effectively equivalent to “time to market”. But there’s another measure of “speed” that’s just as critical, particularly when we apply it to maintaining stability in the infrastructure. That measure is MTTR (Mean Time to Resolution).  This measure is very important when you consider that 60% of production failures are caused by human error or lack of automation according to research from ZeroTurnaround. A goal of DevOps, then, should be to reduce that number as much as possible and introduce more stability into the environment. Frequency of deployment can actually be of assistance in realizing that goal.

    So how does frequency of deployments help do that?

    possible points of failureFirst let us consider the number of possible points of failure that might cause downtime – both in the application and core network infrastructure. Then let us consider that each of those possible points of failure also have multiple potential causes of failure. A single service in the logical critical data path within the core service infrastructure, for example, can easily cause “downtime” that, in the case of IDC, would be characterized as “infrastructure failure” and run a tab of $100K per hour.

    If that application is a critical business application, the tab runs much higher per hour.

    Obviously the speed with which we restore stability (service) in such an event is a factor in the overall impact to the business.

    This is where DevOps comes in and where operationalization can play a significant role in mitigating the impact of downtime by aiding in faster time to resolution.

    Consider that one of the most difficult tasks in the network is not provisioning or configuration, but troubleshooting. To be fair, troubleshooting in app dev, too, is one of the more time-consuming and frustrating tasks, consuming 75% of a developer’s time (according to research from InitialState). That’s close to the 65% of network engineers who are dedicated to “break and fix” tasks, who spend their time troubleshooting network issues up and down and all along the network stack. Needless to say, if you just deployed ten or fifteen different configuration changes splayed across the core and per-app service infrastructure and suddenly something is “wrong”, it’s going to take some time to figure out exactly which configuration change caused the problem in the first place.

    The relationship between number of changes and frequency of deployment is no secret; if you’re deploying changes more frequently then it’s likely there are fewer of them. With an average sprint cycle of 3-4 months, the amount of change is logically not going to exceed that of a cycle that takes 12-18 months. The same holds true for the infrastructure; more frequent deployments should mean fewer changes).

    Logic (and math) tells us that the fewer lines of code and configuration that have changed, the less time it should take to identify the culprit should something go wrong, thereby hastening the time to resolution. Assuming that an agile, frequent deploy rate results in fewer changes to the environment it stands to reason that this approach should also reduce both the number of failures and the time to resolve any that do crop up. Frequency is a significant factor  in reducing failures by increasing its overall stability.

    This is backed up anecdotally by Puppet Labs findings in its “State of DevOps” in which organizations adopting a DevOps approach reported 50% fewer failures and a 12x improvement in time to resolution. That’s stability at work and it’s driven in part by the frequency of deployments and its positive impact on MTTR.

    So let’s apply this approach (and logic) to the rest of the services along the critical data path in the data center infrastructure, i.e. apply it to application services like caching, web application security, load balancing, identity management and application access control.  Automation to reduce misconfiguration caused by human error and smaller, more frequent changes that enable a faster time to identity the inevitable issues that will be introduced. No methodology or approach is going to completely eliminate errors, after all. There’s a limit to how perfect we can get and it’s pretty much a Zeno’s Paradox kind of problem. While we keep solving current issues, more config and code is being deployed that is statistically likely to contain yet another error, and so and so forth.

    But the goal is not necessarily to eliminate all errors (though that’d be nice, it’s simply not practical and it’s the primary reason why our goals for uptime are called “5 9s” and not a “1 with two zeros”) it’s to reduce the number of errors and their impact on downtime. And that is something we can achieve without running afoul of Zeno and his paradox.

    Smaller, more frequent deployments can result in a more stable environment in which downtime is reduced to a level consistent with acceptable risk.

    DevOps, whether applied directly to infrastructure or not, will play a role in improving its stability which in turn has a direct and very real impact on the business by eliminating (some) downtime thanks to more frequent deployments.

  • DevOps & Continuous Change

    DevOps & Continuous Change

    A remark by a colleague while waiting for the coffee machine to complete its cycle started my train of thought. “Should we have multiple minor releases or just do a few major ones in a year?”

    In large organizations, due to many factors, the turnaround time for a single successful release is quite extensive; but if the conceptual change which we are talking about bringing whilst using the #DEVOPS methodology would not only reduce these long cycles but deliver quicker and quality software.

    I have already discussed in my earlier article “DEVOPS: Getting our organizations aligned” on the traditional approach and how the combination of this two (DEV & OPS) has been proven beneficial in various organizations and how many are still hesitant in embarking on that path.

    Continuous Change which encompasses both Continuous Integration and Delivery is paramount to achieving this objective. To attain the objective of delivering rapid and consistent value to the stakeholders regularly, we have to have Continuous Change happening.

    I am sure we have already moved out from the Mainframe era to a more Distributed systems state. But unfortunately we have yet to let go of that culture where we pile up components on a single quasi Distributed Application, instead of creating smaller independent, yet interdependent systems.

    So, back to the same question; shall we go with a few Dinosaur sized, labored releases or make multiple short and swifter runs? In my opinion, we should strive towards the leaner model. Easier said than done you say! Agree. If I have to, then I would go about it this way:

    In an environment having a suite of Distributed Applications, start with Analyzing the components which make up the Major release, List out the changes (fixes and new features) which are planned, asses functional and technological impact, Identify dependencies, upstream/downstream connectivity’s, architectural deficiencies, list out the identified subset of components or group of components by functionality, which can go as an independent release.

    I am resisting the urge to say ‘standalone’ as with the current set of complex intervened collection of applications, it would be an incorrect statement. It would rather be a subset of components which can be independently upgraded. Now the big task is to review and decide if this subset or group would add functional value to the overall suite of applications without the rest of components going in.

    Once identified, the success of this release working as expected would be in the extensive testing (Unit/ Regression/Performance) of these components, and as we gain confidence in this split and deploy procedure, we can start with, prioritizing and scheduling critical must have features or bug fixes which also should be backward compatible with other components lagging behind. We can even come up with scenarios where these components are not just getting updated frequently, but would also have multiple independent tracks. Of course it goes without saying the testing and signoff process is strictly followed albeit in a shorter window.

    Deployments to production have always been a source of heartburn to the OPS teams, we have often seen finger pointing and firefights to contain change fails. In order to maintain stability and maximize availability, stricter controls and reduced deployment windows are put in place. In promoting frequent and smaller component level changes, OPS will also be in control of what’s going in, and smaller component level releases can be rolled back quickly within the Green-Zone window if the change is not working as expected. Though I would categorize this rollback, as a process fail than a deployment fail, and should be reviewed very seriously with right mitigation plan and lessons learnt retrospection, Continuous learning after every successful or failed sprint ensures competent and confident releases.

    Another major factor impacting multiple runs of Production releases is the long Green-Zone windows, by moving to the quicker and leaner deployments cycles, these requests can be substantially reduced, and can eventually aim to reach a stage where changes are deployed online without extensive downtime.

    Similarly, frequent maintenance activities when there are no planned deployments, effectively has the same risk on environment unavailability. Analyzing and moving to a state where these activities are conducted online without a Green-Zone would alleviate the maintenance downtimes and ensure seamless availability, adding stakeholder value.

    I have not touched on the Continuous Integration or the Automation of the deployment process for obvious reasons, we can’t achieve the objective of Continuous Change without having the Integration process in place where incremental changes to code are build into a package swiftly and seamlessly, even a sanity or basic testing might be integrated to ensure the quality of the builds. Same goes for automating the deployments, develop & integrate tools required for rapid deployments. We have seen instances where automating a single activity or revisiting a process has created substantial time savings.

    While it’s easy to propose changes to the Release Process or advocate rapid deployment cycles, we have to ensure adequate checks and balances are in place, compliance adherence and audit trails are created.

    Now to the most important measure of this article, Cost Savings!

    Proponents of the Dinosaur Releases would argue that the common activities which entail a single release like the builds, Testing, Release Management, OPS availability or reduced GZ would cut costs and multiple runs to PROD would logically increase costs.

    But it’s definitely the other way around, we wouldn’t need to feed the Dino anymore, it will be a cost worthy rapid delivery with optimized resources, a leaner process where DEV and OPS are working together to ensure quality value added deliverables are made available to business faster.. This cultural change and collaborative effort also creates new vistas of growth and provides a perfect platform to excel. The cost benefit analysis would eventually be in favor of Continuous Delivery.

    Opportunity cost is another variable which has not been considered; an innovation or a new feature available to customers quickly with reduced time to market cycle will provide the much needed edge in these competitive times. I recall some conversations where a few must have’s were pushed out due to various reasons, frustrating the business.

    DEVOPS was never meant to replace the traditional approach to software development; rather it is an efficient use of the existing resources within a collaborative model to rapidly deliver quality software products. A major cultural shift in our approach is required and to reach that goal we need to embrace the shades of grays, many a times over 50 (sorry, couldn’t resist) when it’s not truly black or white.

    Thank you for the time.

    Visit my blog http://askhurram.com/

    Read On, Live On.


  • The Ultimate Endpoint of Enterprise DevOps

    The Ultimate Endpoint of Enterprise DevOps

    There’s a reason we so often use the word “journey” when we talk about DevOps – it is a critical aspect to a practical approach to DevOps. While we focus a lot on culture in the DevOps community, as I have previously said, culture is an output, not an input; it is the destination, not the journey. By contrast, the set of ‘best-practice’ application delivery methods that improve communication, collaboration, and integration between development and operations are the ongoing journey that drives this transformation for continual growth and improvement, and helps us reach the destination.

    Which leads to the question for this next article in the Enterprise DevOps Q&A:

    Q. What is the Ultimate Endpoint of Enterprise DevOps?

    My initial reaction when asked this was to wonder whether the DevOps journey even has a defined endpoint. While many might say ‘culture change’ is the destination, many others would say there is no ultimate endpoint.

    However, for enterprises especially, with their rigorous set of annual, quarterly, and even monthly goals and metrics (and associated performance reviews, bonuses, stack ranking, etc.), it is difficult to absorb such boundless activity. Larger organizations often need, if not one specific endpoint, at least multiple SMART waypoints along the journey.

    If we follow through on the journey analogy, using CAMS (Culture, Automation, Measurement, and Sharing) as a rough roadmap, we may start trying to change the culture by removing structural barriers to collaboration, or attempt to shape new sharing behaviors. For large enterprises with goal-oriented metrics, automation is happening further down the road – which makes it a worthwhile next waypoint for organizations that have started their journey but are asking “What’s next?”

    Waypoint 1: Release Automation

    Release automation is a key technology that integrates dev, test and ops at that precarious gap between them – code release. Release automation solutions work by modeling components (e.g., images, packages, source code, configurations, etc.) of the development, test, pre-prod and production environments for each stage in the application release life cycle, and then fully automating the deployment and promotion of changes across those environments.

    This is important in DevOps because in enterprises where release automation does not occur, dev and ops (and/or test, QA, staging, acceptance, etc.) staff have to perform these release steps manually. This not only limits their productivity and pushes out application delivery dates, but is also highly error prone.

    Here’s an example from a recent case study by Enterprise Management Associates (disclaimer: I worked for EMA a long time ago and think they are excellent people and very strong analysts). During the Christmas season, a consumer electronics company’s website failed to perform as large numbers of customers logged on to configure and provision their new home entertainment systems. The company deployed a cross-functional “WebOps” group to investigate the problem, which was occurring within their software deployment processes. In short, a lack of standardization made it possible for code, configuration or process errors introduced during deployment to create flawed execution environments.

    The company responded by implementing a release automation solution that can execute a given workflow and configurations automatically, so each environment mirrors the last and errors are reduced or eliminated. As a result, the company has moved from a manual deployment method, where IT staff had to execute multiple scripts in sequence by hand, to an automated one in which IT can “deploy with a high state of reliability in 15 minutes with few adverse after-effects.” This allowed the company to standardize its deployment processes, improve the consistency and reliability of its website and ultimately meet the needs of its customers and vendor partners.

    Waypoint 2: Continuous Delivery

    Automating these handoffs is a great waypoint for enterprises to measure their journey. It is also a great starting point to the concept of continuous delivery – end-to-end application delivery that combines an ecosystem of people, processes and technologies into an automated, iterative, ‘assembly line’. In such a scenario, release operations build on release automation to integrate and orchestrate promotion across environments, enabling predictable, monitored and measurable continuous delivery from development to production.

    At a high level, development involves four phases: planning, building, testing and releasing an application. When an organization achieves continuous delivery, every technology and people process that can be automated between these phases is, so for example, development data from a release automation tool could be fed into a portfolio management solution, which would help automate approvals and future planning phases. In addition, if you used shared services in composite architectures, each team didn’t build the same thing over and over. You built it once and all shared it.

    Then, as iterations occur and the portfolio management tool amasses more and more data, IT leaders will see first-hand how different methods led to better results (e.g., when this technology was used, the project was delivered X% faster). And of course, this kind of real-time data can be used to make better, more nimble business decisions that enable companies to differentiate and be more reactive in the marketplace. This is often exactly the type of intermediate measurement that larger enterprises need to justify the changes they are making; to justify the journey, with real business metrics.

    DevOps: A Continuous Journey of Continuous Improvement

    Returning to the question I posed at the beginning of this blog, I can tell you that neither release automation nor continuous delivery are the endpoint of DevOps – but they are certainly significant milestones to shoot for on the journey. So if they’re not the answer, what is?

    To be perfectly honest, I’m not sure DevOps has a concrete endpoint. As the cliché goes, it’s more about the journey than the destination. As I have written in previous blogs, DevOps is all about delivering high-quality applications faster and at lower cost. As long as you’re continuously improving in that direction, the endpoint really doesn’t matter.


  • Inside the mind of a true DevOps evangelist

    Inside the mind of a true DevOps evangelist

    IBM InterConnect is imminent. Next week more than 20,000 people will descend on Las Vegas and take over the north end of the strip for IBM’s massive event. One of the primary topics attendees will be focusing on is DevOps. IBM’s Rosalind Radcliffe—a respected evangelist for DevOps—will be there to share her passion and knowledge as well.

    Rosalind Radcliffe is a Distinguished Engineer, in Rational currently responsible for the driving the System z and Power Systems aspects for the Jazz foundation and Jazz foundation based products—or so her LinkedIn profile indicates. Really she’s just a very smart person who loves to help customers solve problems.

    At InterConnect Radcliffe will be talking about DevOps. She is hosting a number of workshops for DevOps for enterprise systems. She will also be engaging in panel discussions with clients to discuss things like how an organization can transform its current environment and the part that DevOps plays.

    I had an opportunity to speak with Rosalind recently, and gain some insight into her perspective on DevOps and what it means for IBM enterprise customers. Two themes seemed to come up repeatedly: breaking down silos, and finding a common ground.

    Radcliffe stressed that top-down support from executive management is crucial to a smooth transition. “At a business level [executives] understand DevOps is necessary. They know the value and they want to do it,” she explained. The challenge is how to adapt and make that transformation without disrupting business.

    Where do you begin? If you’re Rosalind Radcliffe you start by finding common ground. All the way from the business perspective to deployment and across all platforms it’s important for all parties to see the same point of view and work toward a common goal.

    That’s not always easy to do when you’re dealing with different teams using different tools and platforms, and with separate political agendas. The first step is breaking down silos. Rosalind told me, “Everyone says that, but that’s really what has to happen.”

    She explained that customers don’t have to throw out the organizations structure or retool the teams themselves necessarily. It’s about redefining how the teams interact and work together, not about reorganizing the teams.

    Radcliffe is passionate about DevOps, but her real drive is helping customers achieve their goals. DevOps is hot now, but it’s just an evolution of the tools and processes businesses use to find a competitive advantage. DevOps may pass, but the need to streamline processes and accelerate delivery will live on.

    “A few years from now we won’t be using the word DevOps,” said Radcliffe. She told me that DevOps is just the Agile principle taken to the full enterprise. It provides a more comprehensive end-to-end perspective that enables enterprise-scale transformation.

    The reality, according to Radcliffe, is that customers need to come up with an enterprise strategy, but it helps to start small. She works with customers to find those initial baby steps that help them gain momentum that eventually allows them to make the bigger transformation.

    Vegas isn’t really her scene, but she’ll be there next week for IBM InterConnect. She can do without the flashing and dinging of the slot machines or the Vegas shows. But, she’s driven to engage with and help enterprise customers, so she’ll brave the busy Vegas environment to share her passion for DevOps.

  • Yes, I said “Culture” again

    Yes, I said “Culture” again

    “Culture”. Any time that two or more people get together to do anything  —  whether it’s DevOps, or marketing, or just eating lunch  —  they form a culture. Even if they pointedly ignore each other, it’s a kind of culture (just not a very good one). When we the preachers of DevOps say the word “culture” we are simply stating the fact that people are a big factor in DevOps success or failure.

    There’s no point in trying to get away from it, even if you want to.

    Cultures form naturally.The character of a culture is determined just as naturally by the people who compose it, and the conditions under which they operate. If a development team, for example, has the right mix of people, and they’re working in an environment that allows easy, ongoing communication, they’re likely to develop a culture with some very positive characteristics. If some of the key people on the team have personalities that clash, on the other hand, or if there are major barriers to communication, the culture that develops may be seriously weakened or dysfunctional.

    If you are a manager with responsibility for a DevOps team, it will develop a culture, whether you actively participate in it or not. Either way, you’ll have to deal with the results. 

    At this point, you may be thinking, “Wait a minute!” We’re using agile, and we’re fully committed to the process.  We’re also using the best tools available for DevOps implementation and management.  Shouldn’t a strong, all-encompassing process and a set of first-rate tools be able to override or even turn around a weak team culture? The long and the short answer to that question are both the same: You cannot separate process from culture, and you cannot even separate tools from culture.

    Suppose, for example, that your development team is broken up into cliques with a minimum of communication between them, and that your operations team has long since become resigned to having almost no communication with development. You can have as many meetings as you want, but until you break down the cultural walls, they’re probably going to be very frosty and uncommunicative affairs.

    The success of any process depends on the willingness of the people involved to participate; otherwise a process that requires cooperation is going to be blocked, if any of the key participants are unwilling to engage 

    And it’s the same with tools. Tools can create processes for you, but when they do, they will own you, and not the other way around. Even the best tools are useless in the hands of a culture that has no interest in using them. You might, for instance, implement a well-thought-out, integrated set of DevOps tools, but if your individual team members go around singing “I did it my waaaaay!” and refuse to let go of their existing tools and practices, the new tools won’t amount to much. 

    So what can you do? As it turns out, there’s a lot.

    Culture grows from the top down as much as it grows from the bottom up. Managers can and do have a major influence (whether it’s by commission or omission) on the development of a team’s culture.

    One of the best ways to foster communication, for example, is to be the communicator.  Speak honestly to your team members, listen to what they have to say, draw them out (in a friendly and supportive way) when they appear to be holding back, and when necessary, work with individuals to get them to communicate with each other.  If your team members know that’s what they’ll experience every time they go into a meeting, they will become more communicative  —  and it will show up in their level of day-to-day cooperation.

    It’s the same way with tools. The truth is that people frequently become attached to their old tools. So much so, they disappear into their daily activities. They are often unwilling to give them up, even if those tools make their jobs more difficult. Giving up your existing tools can feel a lot like you’re giving up your independence, particularly if you’re being asked to shift over to a much more integrated and collaborative environment.

    This is also part of a team’s culture, and as a manager you can, and often must, do a considerable amount to shift that culture from one that values autonomy above all other things to one that places a premium on cooperative use of tools. Another way to do this is to create shared objectives. Tangible motivators that cross the entire team, not part of a single one.

    Tools won’t make a culture.  A culture makes use of tools.

    So maybe the place to start is with your own understanding of the culture that is already in place. Are you clear on the nature and the current state of your team’s culture?  Do you have a clear understanding of what your team would be like if it were fully committed to DevOps culture?  How near or how far apart are those two visions?

    Start from there, and take your team where they need to go.

    DevOps tools without a DevOps culture does not create a DevOps environment. They are tools with DevOps capabilities waiting for a committed DevOps team to put them to good use.

    If team members understand the value of having a DevOps culture  —  to them as individuals, and to your organization  —  they will be willing to commit to that culture.  But they need to see that value, and in order for them to see it, you as their team manager must have a clear vision.