Tag: continuous integration

  • OverOps Allies With SonarQube To Improve Application Quality

    OverOps Allies With SonarQube To Improve Application Quality

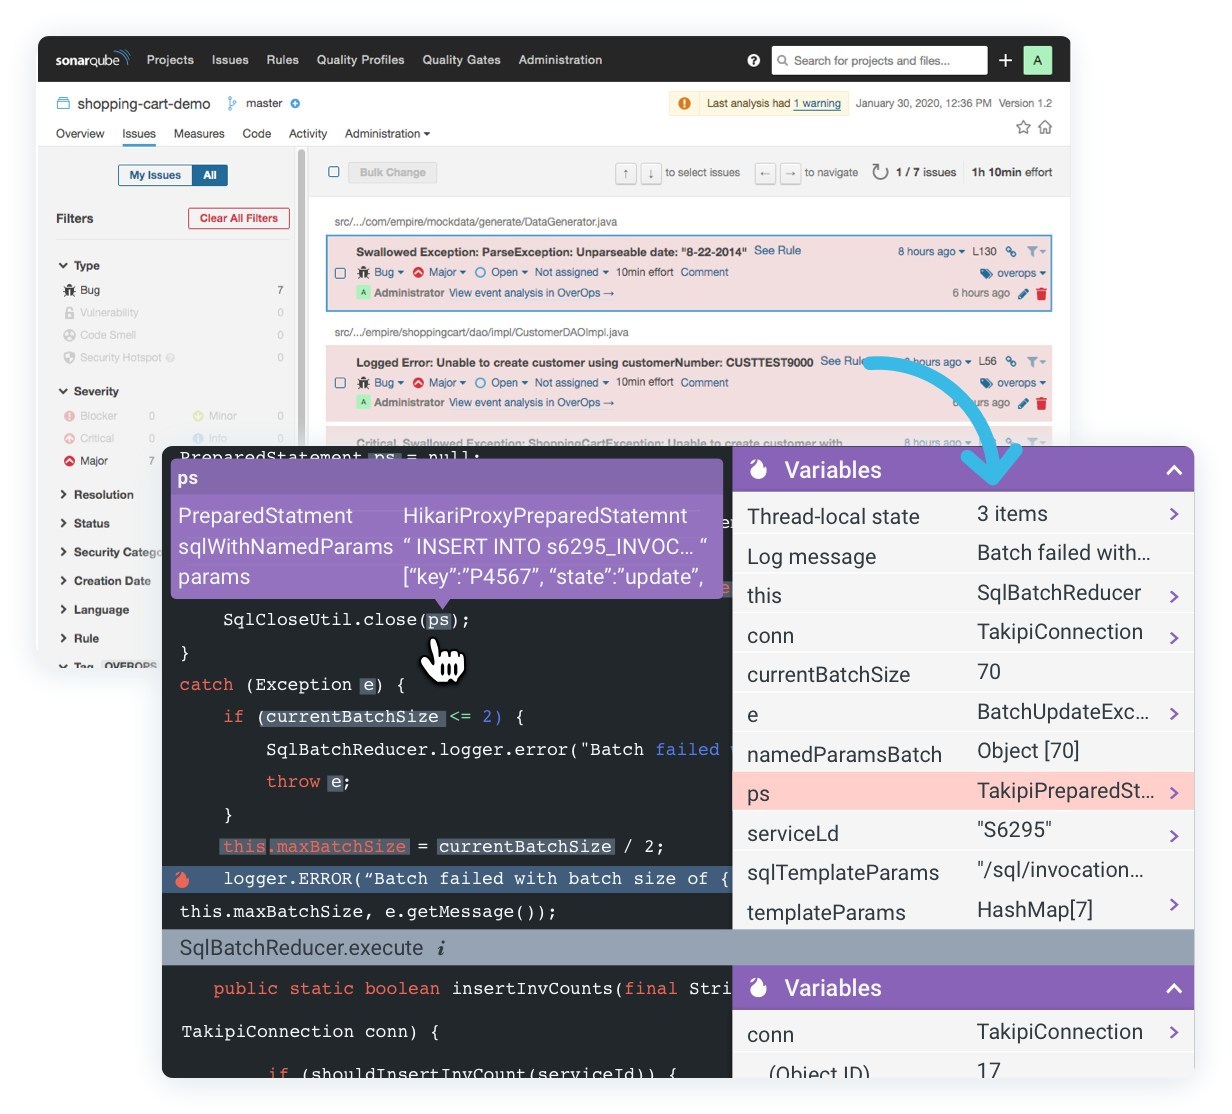
    OverOps, a provider of tools for dynamically analyzing code at runtime, has partnered with SonarQube, a provider of static analysis tools for source code, to enhance application quality by unifying code analytics.

    Chen Harel, vice president of product for OverOps, said the two companies have collaborated to create a plugin through which DevOps teams can now more easily analyze source code before it gets deployed in a production environment.

    The goal is to equip DevOps teams with the tools required to assure application quality as more responsibility for maintaining applications continues to shift left on to the shoulders of developers, said Harel. In the absence of tools to analyze code, he noted, developers are not going to be able to identify, for example, potential vulnerabilities in source code and errors at run-time.

    The plugin also allows issues identified by OverOps at runtime to be fed back into the SonarQube tools for analyzing source code to identify issues that previously would not have been discovered, he added.

    Specifically, when the OverOps plugin is installed, it automatically creates an event rule for Java code based on new, critical, resurfaced and unique runtime errors. When a quality gate fails a release based on these criteria, users can view the issues directly within their SonarQube dashboard. OverOps then provides a direct link to the event analysis containing the full context behind the error, including the stack trace, variable state and system state.

    As a result, Harel said DevOps teams are going to be able to reproduce an issue much faster, which should result in much shorter times to remediation. Without such tools, DevOps teams can spend weeks reproducing an error that only takes a few minutes to actually fix.

    Harel said with both the OverOps and SonarQube tools included as part of the gates set up within a continuous integration/continuous delivery (CI/CD) platform, it becomes possible to substantially improve the overall quality of the applications being developed. That’s critical because developing applications faster often results in more errors having to be addressed, said Harel.

    There’s a lot of debate these days concerning the degree to which the adoption of DevOps might be increasing the total cost of IT. It’s a lot more expensive to fix an application after it’s deployed in a production environment than it is to address issues as they arise in the application development process. As such, there’s a lot more focus on code analytics to help ensure that DevOps processes are churning out not just more code faster but also higher quality applications.

    Of course, the level of DevOps sophistication tends to vary widely by organization. However, as more gates that address application quality assurance are erected on CI/CD platforms, the better the DevOps outcome will become. The challenge is making sure the DevOps culture being fostered prizes application quality as much as it does how much code is being written and deployed how fast.

    — Mike Vizard

  • 2nd Watch Allies With GitLab for Managed DevOps Service

    2nd Watch Allies With GitLab for Managed DevOps Service

    2nd Watch today launched a managed DevOps service based on the continuous integration/continuous deployment (CI/CD) platform from GitLab that it will operate on behalf of customers in addition to coaching them on how to adopt best DevOps practices.

    Stefana Muller, a senior product manager, said the 2nd Watch Managed DevOps service combines the managed and professional services capabilities of 2nd Watch into a single offering. That approach is required because when it comes to DevOps most organizations need as much help transitioning their culture as they will operating their CI/CD environment, she said.

    One of the major challenges organizations face when trying to embrace DevOps is they typically spend a lot of money upfront only to see those efforts flounder when changing the internal culture of the organization becomes too difficult, Muller said. As part of an effort to smooth that transition, 2nd Watch DevOps experts will assess an organization’s readiness to adopt DevOps tools and processes and then train internal teams on DevOps fundamentals such as managing infrastructure as code and Git principles. The assessment is based on a Culture, Automation, Lean Practices, Measurement and Sharing (CALMS) methodology.

    The 2nd Watch service is built around an on-premises edition of the GitLab CI/CD platform that it will host and upgrade on behalf of a customer on either an Amazon Web Services (AWS) or Microsoft public cloud platform. The DevOps service will focus on enabling organizations to build both monolithic and microservices-based applications faster because no organization today has fully transitioned to microservices. The company already provides a managed Kubernetes service for building and deploying applications based on a microservices architecture.

    2nd Watch chose to partner with GitLab because of the completeness of that CI/CD platform, which among other things includes integrated security modules that can be employed to advance DevSecOps practices as well, Muller said, noting that longer-term, 2nd Watch is planning to layer a more robust set of managed DevSecOps services on top of the GitLab platform.

    Managed DevOps offerings are starting to proliferate as the number of services providers that have attained certifications from multiple IT vendors has increased. It’s not clear to what degree organizations will prefer to rely on these services just yet. However, it’s is apparent many organizations are trying to shift as much of their limited resources to building application code versus managing IT infrastructure. It’s also possible that as the COVID-19 coronavirus pandemic becomes more widespread many organizations will need to rely on external service providers to manage their DevOps environments.

    Regardless of the motivation, organizations that are at the beginning of their DevOps journey clearly will need more help than those that are further along the DevOps maturity curve. The decision most organizations will need to make is to what degree will they rely on a managed DevOps service to accelerate their transition versus opting to rely permanently on an external IT service provider to manage one of their most critical IT environments.

    — Mike Vizard

  • How to Successfully Adopt Mobile DevOps Practices

    How to Successfully Adopt Mobile DevOps Practices

    Mobile DevOps is more than simply adopting a new set of tools and practices. It also comes with the need to adopt a completely different mindset, in the form of a cultural-organizational change. The approach is based on the Agile methodology, but takes its practices further— not only by getting other teams more involved, but by replacing function-based teams with product- and project-oriented teams as well. The main idea behind this is that nothing inspires collaboration like having a common goal and working together towards reaching it. 

    Let’s take a look at the key elements of Mobile DevOps practices.

    Continuous Communication and Planning

    The goals and purposes of Mobile DevOps correspond with the original DevOps principles, such as customer satisfaction, sustainability, enhanced teamwork and shortened software development lifecycles. Similarly to DevOps, it aims to resolve problems by using common sense and implementing a culture of shared responsibility, transparency and shorter review cycles. In mobile development, constant and interaction-based communication between developers, website, product and QA teams is particularly important in order to accelerate feedback loops and consequently, resolve issues faster. In Mobile DevOps, there is more focus on transparent, traceable documentation, which can be achieved by using a source control system that helps keep track of documentation of code changes and details of the whole process. Raised visibility also helps teams share the workload—especially when it comes to unexpected work—and to fix incidents, and unblock the release pipeline rapidly. 

    Continuous Integration, Delivery and Deployment

    The Android and iOS operating systems are dominating the current mobile landscape, and both of them—especially Android—are incredibly fragmented. For this reason, it is necessary for developers to maintain separate builds, depending on the many supported versions, device types and platforms. A stable CI/CD tool ensures that the codes created by different teams are compatible with each other and new ones can be integrated into previous ones with no issues. These tools eliminate the manual aspects of app development from planning, code testing, integrations to deployment and monitoring, and automate as much as possible throughout the entire lifecycle of app development, which ensures the seamless merging of codes and reduces the risk of errors. Device fragmentation is the main reason why Mobile DevOps and CI/CD automation are inseparable in any team that wants to automate their app development, their testing and their monitoring processes. 

    Continuous Testing and Monitoring

    Mobile applications have to go through rapid iterations and more frequent releases than web applications. This results in new features in the app which are not always supported in the production environment at the time of the release. To understand the quality level and potential risk of each new release, mobile app companies can conduct different types of tests—ranging from automated unit and UI interaction testing, all the way to manual QA testing—depending on the maturity of the app and the size of the team. Besides implementing an iterative process for testing, adding monitoring and real-time performance tracking tools are all crucial in mobile app development. Not only do these enable teams to find the root cause of failures faster, but to save on hardware costs as well. Adding third-party SDK, performing crash reports and continuously monitoring both the app performance and the feedback in the app stores all help developers constantly improve the quality of the app. 

    Conclusion

    DevOps is just as much about the culture as it is about technology. Successfully adopting Mobile DevOps requires all teams at app companies to make important technical and business decisions, have a hard look at their processes, identify the bottlenecks and be prepared to make significant changes. The essence of Mobile DevOps not only lies in a mindset change and choosing the right tools, but also in close-knit teamwork that allows teams to focus on market needs, user behavior, feedback and other factors that significantly affect the product perception.

    — Nóra Bézi

  • Why Is QA so Important in Executing a DevOps Implementation Strategy?

    Why Is QA so Important in Executing a DevOps Implementation Strategy?

    In a rapidly growing global digital landscape, enterprises are facing many challenges. These include changing customer behavior and the need to be in line with the latest technology trends. To address these challenges and to stay up the competition curve, enterprises are adopting a slew of strategies. These comprise expanding the capacity of processes, quick quality checking and delivery of applications and timely marketing of the applications. This is where DevOps comes as a one-stop solution to the aforementioned requirements. 

    When it comes to assuring the quality of software applications, the Agile and DevOps model of testing is favored over the traditional waterfall model. This is because software applications need to be tested across a swathe of platforms—devices, browsers and operating systems. In the DevOps scheme of things, software builds are continuously integrated and deployed in the development pipeline by using test automation. It involves the development and implementation of new features along with the streamlining of processes. 

    What Is DevOps?

    DevOps is an amalgamation of terms “development” and “operations” and is underpinned on four basic pillars—culture, tools, collaboration and practices. Combining processes and philosophies, the DevOps approach helps enterprises deliver quality builds in the SDLC. Here, development and operations teams no longer work in silos but in close coordination with each other. As a result, quality becomes a shared responsibility and a culture of accountability gains ground. DevOps implementation leads to the quick development and deployment of quality builds, faster solving of critical issues and engendering greater trust and confidence.

    Let us understand the best DevOps implementation strategies to derive outcomes such as continuous integration (CI) and continuous delivery (CD). To begin with, getting the QA basics right the first time and every time should be considered as part of the strategy. This is due to the fact that in a pure DevOps ecosystem, the lines between development and QA are blurred.

    Test Automation

    Since the software needs to have an omnichannel interface with third-party applications to perform optimally, the test process should be automated. There should be a smooth QA-DevOps alignment to detect and mitigate glitches early on in the SDLC. Thus, DevOps testing may involve choosing automated tools that are either open-source or commercial. 

    Teams Merge

    To derive DevOps transformation, the integration of the QA team with other technical specialists becomes important. The final DevOps team should adapt a culture wherein identifying glitches becomes a shared responsibility. 

    Metrics

    Since DevOps testing is all about quick identification and fixing of glitches, the metrics should be defined at the beginning. It will help the DevOps team to stay focused on the challenges and requirements. This calls for the QA engineers to setup test requirements into the workflow and guide the team therein.

    Virtualization

    The software application should be tested across a slew of platforms—devices, browsers or operating systems. Since it is well-nigh impossible to test the codes for numerous users (during usability testing), the same ought to be created virtually. The QA team can virtualize every test requirement to emulate the behavior of software components. Moreover, it helps to do away with the need for dependencies and addresses constraints faced in interdependent environments.

    Choose the Right Tools

    To enable DevOps automation, the QA team should choose the right test automation tool. The main criteria for choosing the tool should be the team’s expertise in using it. The tool should offer the ease of writing the test script in a single programming language. It should allow the testing of applications across operating platforms and browsers.

    Continuous Integration and Continuous Deployment

    These are the outcomes of any DevOps methodology. DevOps continuous integration and deployment encompass adding code changes in a repository and creating automated builds. This leads to an early recovery from failures as well as testing and delivery of products within fast turnarounds. Continuous integration based on test automation leverages regression testing and a version control system when a new code is added. Further, DevOps continuous deployment is about the capability to add new features to the existing applications. This makes enterprises follow a user-driven improvement of software and agile approach.

    Conclusion

    With the quality of software applications becoming the final arbiter in making an enterprise successful, taking the DevOps approach is crucial. However, since the whole process is hinged on executing comprehensive quality testing, the QA basics should be done right.

    — Akshaya Choudhary

  • Predictions 2020: How to Make the Case for Adopting CI/CD in Your Organization

    Predictions 2020: How to Make the Case for Adopting CI/CD in Your Organization

    The practice of continuous integration and continuous delivery (CI/CD) is fundamental to modern software development. And yet, many organizations are still using slow, error-prone, manual processes to build, test and deploy their software. Sometimes, the blocker can be engineers who don’t want to change how they’ve always done things, but most often folks in the trenches are chomping at the bit to automate. All too frequently, it is IT leadership and executives who need to be convinced that making a large investment in updating tools, training and culture will net returns greater than the cost.

    If you want to change management’s mind about an investment in CI/CD, focus on making a strong business case. This may sound daunting, but it’s easier than you think. Learning a bit about how to advocate for budget and organizational change can go a long way. Just think about what life would be like if, instead of sitting in endless change management meetings, you could get your code to production simply by merging to master while automation takes care of the rest.

    This article will get you started with some concrete tips you can use to get CI/CD green-lit by your leadership.

    Start Small

    Agile and DevOps are all about breaking things up into smaller chunks. It may seem counterintuitive, but deploying more frequently equates to less risk because small changes are easier to orchestrate, troubleshoot and roll back than large complicated deployments. In that same way, you can reduce the risk to the organization by taking a DevOps approach to transformation. Rather than trying to upend your entire process, see how you can break the change up into small, iterative chunks.

    Almost every large enterprise that has successfully adopted wide-spread CI/CD started with one lighthouse team. Changing everything is a tough sell. Instead, approach management with a low-risk proposal: “We’d like to run an experiment to see if we can deliver more quickly and reduce costs. We have one team that will take one small project and test CI/CD automation to see what the results will be. We can leverage open source tooling to get started at a low cost.” Even the most stingy budget holder should find the proposal intriguing.

    Measure the Results

    Once you’ve started to conduct your experiment, it’s important to measure what you observe. What are the differences between the old way and the new way? The more concretely you can quantify it, the better. Saying, “We went faster,” doesn’t carry a lot of weight. But if you can quantify it, your message becomes more potent. For example, “Our previous cycle time from the moment a developer begins work on a ticket to the time that code is running in production and useable was 30 days. By automating some of our manual efforts using CI/CD we have cut that to five days.”

    For this part of the process there’s no need for exact numbers. Most likely if you aren’t doing CI/CD today, you likely don’t have the instrumentation in place to accurately measure cycle time. But don’t let that be a blocker. You can give estimates. “From about one month to one week,” is still a powerful story.

    Some other metrics to capture that can help make your case are:

    • Number of tests run.
    • Code coverage in terms of percentage of code tested.
    • Number of people-hours required.
    • Number of defects in production or number of regressions/roll backs needed.
    • Mean time to repair (MTTR): The average time from when a bug/failure is discovered in production to when the fix is running.
    • Frequency of releases—how often new capabilities are available for users.
    • Cost to deploy: This is a very powerful metric if you can estimate it. A good rule of thumb is: (number of people minus hours, times average hourly rate) plus (cost of assets and services required).

    Aim to use three to five metrics to prove your case. You don’t want to overwhelm with data. The point is to show that things are better with CI/CD, not that you’ve gathered a lot of numbers. Use a simple before-and-after format to show the change. State the changes in terms of increased value, reduced cost and/or reduced risk. For example, “We increased value for our users by shipping 10 times more features in the same time frame, reduced deployment costs by 80% and reduced risk by increasing code coverage by 30 points from 40% to 70%.” 

    Couple Your Efforts to Business Outcomes

    A critical element of IT success is how closely you can partner with the business. It can be next to impossible to get initiatives green-lit if the only benefit is to make things better for IT. But if you can show how some extra effort spent on IT modernization can drive results for the business, then you’ll find you start getting enthusiastic approval from leadership.

    Collaborating with people outside of IT or software R&D is a career-enhancing skill every technical practitioner should strive to improve. 

    Get to know what efforts in sales, marketing and product are dependent on IT. For example, the sales department may desperately need additional capabilities in their forecasting tool if they are going to execute strategic deal acceleration, ensure quarterly numbers are consistent and avoid unpredictability with shareholders. In other words, the fact that your slow delivery cycle can’t get those new features on the release calendar for another three months is putting the stock price in jeopardy.

    To avoid this tragedy, you can tie your CI/CD efforts to the sales outcomes. By getting to know the pain points of your sales colleagues, you can craft a powerhouse “ask” to leadership. “We’d like implement CI/CD to automate deployments for our sales data management system. This will allow us to implement new filters in a matter of days rather than months which sales needs to hit their numbers.” 

    Pulling It All Together 

    It can be demoralizing to feel like you are behind the curve. Looking at other businesses who have already adopted CI/CD it can feel like you might never catch up. If this is the case, some axioms are appropriate, such as the famous Chinese proverb from the Tao Te Ching “A journey of a thousand miles begins with a single step.” And as Theodore Roosevelt said, “Comparison is the thief of joy.”

    The reality is that you are not alone. Many organizations, especially large enterprises, are relying on outdated software practices. Convincing leadership to green-light IT modernization efforts can be a challenge. Adopting CI/CD in a meaningful way does require significant investment, but there is a lot you can do to smooth the path for them and earn their support.

    Begin by identifying a small adventurous team who can serve as an experimental testing grounds. Not only will their success help to convince leadership, but their example serves to light the way for other teams to adopt DevOps. Identify metrics you want to capture and be sure to instrument so you can measure the improvement. Pick a few metrics that show increase in value, decrease in cost and decrease in risk. Finally, reach across the org to collaborate with your non-engineering peers. By showing how your modernization effort drives outcomes for the business you’ll be sure to earn respect as well as additional budget to expand your CI/CD efforts.

    Want to learn more about what to expect in 2020? Join us Jan. 23 for our Predict 2020 Virtual Summit  featuring discussions from some of the industry’s best and brightest offering up their visions for the future. Sign up today for this free daylong virtual event.

    — William Chia

  • Extending Automation to Your First Code Commit

    Extending Automation to Your First Code Commit

    I am a big advocate for software reuse, and an even bigger advocate if that reuse comes in the form of software automation. My team and I rely on reusable software processes that accept simple inputs to produce predictable results. We have tight deadlines with requirements that often seem impossible. Automation makes us more efficient and our work more predictable.

    Once upon a time, we used glue and bubble gum to cobble together means by which to build, then test and then eventually deploy application versions. It worked until it didn’t, and industry opportunities arose for mechanization. Enter continuous integration (CI), continuous deployment (CD) and DevOps, in part.

    You likely know this and have already taken advantage of CI/CD platforms such as Jenkins, CircleCI and others. The simplicity of the as-code model allows us to turn easy-to-create declarations into the otherwise complex provisioning of servers, databases, caches and file systems, along with the execution of code to leverage what was provisioned.

    Life as a developer has been made better using these as-code tools in the tool chain. Spinning up a Kubernetes cluster on Google to (re-)deploy an image built, tested and pushed to DockerHub from a CloudBees/CodeShip pipeline is something I rely upon each time I commit to my Git host.

    In this article, I am going to talk about Project-as-Code to extend automation to the first code commit with a working app running through a functional CI/CD pipeline and deployed to a production-like environment.

    Barriers Keeping Enterprise IT Departments from Coming Along for the DevOps Ride

    Unfortunately, basic usage of all these great tools comes with the added complexity and cognitive load cost. Understanding Docker image creation, HashiCorp Terraform syntax for infrastructure-as-code, Kubernetes cluster deployment and more are just a few of the competencies developers and operators need to have.

    Learning a new set of tools every few years comes with the territory, but there’s no reason to ignore new potential avenues for automation. I’ve wondered if there is a better way to abstract and automate the setup of these common pieces in the modern software production pipeline.

    Another common issue I’ve noticed—these pipeline components often get set up sequentially, with the first meaningful code commit being the blocker to setting up all the other pieces of the CI/CD pipeline. Without this commit, these tools sit relatively idle while waiting to provide value.

    For those of us who work on new projects regularly, getting things started has always had its issues, especially for consulting scenarios where requirements and team dynamics differ between clients. We are disciplined enough to first reach in our toolbox to reuse as much as possible. Still, DevOps has yet to be adopted wholesale in a standard way by many enterprises.

    For these situations, I find the benefits of DevOps are easy to explain and understand. Developers like to reuse and fewer barriers, the business likes savings and an enterprise likes productivity and innovation. However, to inject those benefits is still a very manual, time consuming process, making the overall sell of DevOps harder.

    The purpose of DevOps automation is to simplify tedious error prone manual processes. I see another opportunity for automation: entire DevOps projects using the same as-code model we have become accustomed to.

    Generating Your First Meaningful Commit “As-Code”

    Why not use a straightforward declarative model-driven means of not only generating tech-stack specific application source code, but all the config files that lead to DevOps being automated. With this, the toolchain learning curve is minimized, and idle tools now are immediately called to action. The result is a self-sufficient operational DevOps environment working through an application code base that comprises a fully deployable executable first code commit. Developers then get their reusable assets and environment(s), the business sees cost and time savings, and the enterprise gets the productivity and innovation necessary to stay competitive.

    In an article written by Pete Hodge titled “Hello production,” he goes into great detail about the value of quickly standing up a flowing CI/CD pipeline leading to a functioning app deployed to production. He contends deploying even a useless application into production, as soon as you can, is the right way to start a new project because it pulls unknown risk forward, opens up parallel streams of work and establishes good habits. Project-as-Code standardizes this thinking with model-driven automation.

    The next generation of DevOps is unfolding with automation remaining a key component to expand scale, velocity and productivity. As automation has worked its way up the toolchain, automating the automation behind DevOps will shift the paradigm to improve how projects are created, how DevOps is implemented and the quality and features of the first commit into a Git repository. What now takes weeks to months could instead take hours to days, falling in line with our expectations now met by other successfully mechanized aspects of DevOps.

    Hopefully this article will serve as a starting point for your next DevOps project and how Project-as-Code automation can be a part of getting you started easier and faster.

    — Steven Randolph

  • Harness Adds Analytics to CDaaS Platform

    Harness Adds Analytics to CDaaS Platform

    Harness has added an analytics module to its namesake continuous delivery-as-a-service (CDaaS) platform that makes it easier to better align constrained software development resources with business goals.

    Omed Habib, director of product marketing at Harness, said Continuous Insights enables organizations to identify bottlenecks and improve overall software delivery by automatically gathering metrics such as deployment frequency, lead time, mean-time-to-restore (MTTR) and change failure rate.

    The Harness Continuous Insights dashboard

    Habib said the biggest challenge organizations face when it comes to continuous delivery is the delicacy of most IT environments. All the interdependencies between complex systems force IT organizations to rely on manual processes and custom scripts, he said, noting the process of rolling back an application whenever there is an issue can take days and weeks.

    The Harness CDaaS platform provides a more seamless approach to application delivery that automatically detects new builds in GitHub, Bamboo, Jenkins, Artifactory or Nexus repositories or any Git repository. Once the DevOps team is alerted, they can employ graphical tools to not only automate the process of building pipelines using YAML files but also leverage machine learning algorithms to evaluate the quality of a deployment and then automatically roll it back whenever necessary by accessing data from tools such as AppDynamics, New Relic, Splunk, Elastic Search and Sumologic, added Habib.

    Harness comes in three flavors. There is a Professional Edition supported by Harness and a free forever Community Edition. There’s also an Essentials Edition aimed at medium-sized companies that do not require a full set of enterprise and security features. The Continuous Insights analytics module is free for all new and existing customers of the Harness Professional Edition.

    Habib said that despite all the advances being made in terms of DevOps and continuous integration, organizations are still struggling with continuous delivery. Because many of them don’t seem to be able to push code into production as quickly as the code can be built, the pace of innovation within IT environments is being stifled. As business leaders wonder why that pace of innovations has slowed, many of them are now demanding access to application delivery metrics.

    It’s not clear to what degree providing access to those metrics will entice organizations to adopt a CDaaS platform. However, as developers and business leaders alike become more frustrated with the pace of application delivery, a groundswell for change is starting to build. Many IT leaders are now looking to automate as much of the application delivery process to prevent that frustration from morphing into a full-scale mutiny.

    In the meantime, there’s an old adage that says things measured are things done. Not everyone may appreciate all the newfound attention being paid to key performance indicators for application delivery. However, the truth is most organizations are not going to ever really solve the application delivery conundrum until somebody starts producing relevant metrics that enable them to comprehend the true scope of the challenge.

    — Mike Vizard

  • DevOps Chat: 2019 Accelerate Report with Dr. Nicole Forsgren

    DevOps Chat: 2019 Accelerate Report with Dr. Nicole Forsgren

    There are many interviews you do as part of the role as editor in chief of devopsy.kinsta.cloud. Then there are some that make it all worthwhile. Anytime I have the pleasure of speaking with Dr. Nicole Forsgren, it makes all of the other things I do worthwhile. She has a clarity of vision borne from the foundation of verifiable metrics she has measured and surveyed over the last six years.

    Just about every DevOps presentation you will see has some reference to her Accelerate State of DevOps Report. And for good reason. It has become the “authority” on DevOps metrics.

    We sat down with Nicole to go over what she thinks are some of the key findings in this years report. Have a listen and enjoy.

    Transcript

    Alan Shimel: Hey, everyone, it’s Alan Shimel for devopsy.kinsta.cloud, and you’re listening to another DevOps Chat. Lucky you, folks out there, because you’re catching I think what will be one of the best chats of the year. I’m joined by my good friend and DevOps survey expert, guru—just all around great person, Dr. Nicole Forsgren. Nicole, welcome.

    Nicole Forsgren: Hey, thanks for having me.

    Shimel: It’s my pleasure to have you on, Nicole, and you know I always get excited to have you on our show. But Nicole, double whammy reason to be excited in that the survey is out. I know you put your heart, soul and guts into this thing for 10 months a year or so and, you know, between drawing up the questions, getting the responses, analyzing them, doing the report, then talking about the report, it is—it’s a lot of work. I don’t know if people at home realize exactly how much.

    Forsgren: I know, I know. Every year, it’s so much, and every once in a while, I’m like, “No more!” So, I have one week where it’s just crazy and I’m like, “I’m not doing it again!” And two days after release, I’m like, “This is my favorite time of year! It’s the best!” [Laughter]

    Shimel: [Laughter] Absolutely. And, you know, just for folks out there who, I don’t know, maybe they’re not familiar or they are familiar but they don’t know the whole story—you’ve been involved in the State of DevOps Report now, is it six years?

    Forsgren: Yeah! This is six years. I’ve been lead investigator on the report. So, it’s the State of DevOps Reports. It’s the longest running, largest, academically rigorous research into DevOps. And so, when we say DevOps, we’re talking about developing and delivering software with speed and stability, in ways that drive business outcomes and the capabilities and practices that are impactful. And when I say impactful, I mean things that are statistically significant.

    So, when people say, you know, “Does this make a difference? Does CI actually matter? What type of automation is important? Do we care about trunk based development? Everyone says culture is important—does culture matter, and what type of culture?” These are the types of things we’ve been researching for six years now. And it’s—when I say it’s a huge study, we’ve hit over 31,000 data points now.

    And—I keep talking, I’m so excited [Laughter]—

    Shimel: No, no—go.

    Forsgren: —academically rigorous. When I started doing this, I was a professor. So, this has been written up in academic peer review, but because we want to make an impact in industry and because we want everyone to be able to read it and access it and understand it, we translate it, right? We make it accessible.

    So, we put it out in the State of DevOps Report. So, I sometimes joke it’s like an adult picture book. It’s larger font, it’s big print, it’s graphs, it’s charts. We do layout really carefully so that if you want, you know, some people print it out and they put it on the wall. You can screenshot it so you can put it in slide decks.

    And I also keep saying “we.” So, historically, the DORA authors have been myself, Jez Humble, Gene Kim. The authors this year are myself, Dustin Smith—he’s a new researcher who joined me, he’s with the team at Google Cloud—Jez Humble and then this year, we were also joined by Jesse Frizzell.

    Shimel: Yes, absolutely. We ran—we covered that on devopsy.kinsta.cloud, actually, I remember.

    Forsgren: Yes!

    Shimel: A couple things—and, you know, you guys did the research here, but let’s be clear. You could go to any DevOps event the world over—and I do mean the whole world over—

    Forsgren: Yep.

    Shimel: And listen to a presentation and, you know, nine out of 10 dentists agree, nine out of 10 presentations will have some metric from this survey that they use to cite as authority on where we are in DevOps, what is the state of CI/CD, et cetera, et cetera. So, it really is—

    Forsgren: So, it comes out of the survey, or it comes—

    Shimel: From [Cross talk].

    Forsgren: Okay, Accelerate, and it comes out of—so, like you said, it could reference a DevOps event or an agile event or a testing event. Because we do tend to cover so many things and we do cover them in a very, very rigorous way, right? So, it’s not—you know, the joke is “lies, damn lies, and statistics,” right?

    Shimel: Yep.

    Forsgren: We do cover it in a very rigorous way, and we put it forward in the finding, the things that we find, and we say, “This is what we find and these are some of the limitations, and these are the evaluative criteria,” right? Like, it does not include—like, this is not a typical vendor report, right? Like, we don’t—

    Shimel: Right, and that’s important.

    Forsgren: We don’t talk about tools. And why don’t we talk about tools? Some people are like, “Well, what tool should I use?” I’m like, “I don’t know, what tool should you use?” Like, for example, CI. CI is predictive of better continuous delivery and better speed and stability.

    Now, when you do CI, it should—every time you check in code, it should result in an automatic build of the software. It should trigger automated tests. You should get results of your automated build and tests at least every day, and your developers should see that at least every day.

    So, here’s your four evaluative criteria. Now, whatever tools you wanna use to do your CI, look at those four pieces. Now, I don’t run through a set of tools because there’s a million tools, and what happens when your tool comes out with a new release? It could change your, I mean—

    Shimel: Well, not only that. I mean—

    Forsgren: So many things.

    Shimel: You wanna know, Nicole, I’m on the other side, right? I’m running this devopsy.kinsta.cloud, we’re media. We do cover tools. It’s a little—it dirties the water. It muddies the water. Because then right away, people wanna know what’s your bias, who’s sponsoring, you know what I mean?

    Forsgren: Right.

    Shimel: I just, I kinda like it better this—and I think most people do. We’re not looking for you to pick one tool or, this isn’t a magic quadrant nonsense kind of thing.

    Forsgren: Well, and this way, I don’t have to keep up with toolset changes or feature set changes or versioning changes.

    Shimel: Or who bought who and—yeah, all of that stuff.

    Forsgren: Yep. Anyone can take those evaluative criteria, they can apply it to whatever tool they wanna use. Heck, vendors can use it. They can say, “If I’m building a tool, this is what I should be looking at.”

    Shimel: Absolutely, absolutely. Let’s talk, you mentioned lies, damn lies, statistics, math.

    Forsgren: [Laughter] So much math.

    Shimel: You know what, let’s dig in on that a second, because—so, first of all, obviously, you’re a woman, right? And it’s great, we have a woman here talking math and—

    Forsgren: Yeah.

    Shimel: —for my audience out there, you know what, you can grow up and be Nicole, too.

    Forsgren: Uh huh.

    Shimel: So, it’s encouraging. But too many people, Nicole, they see big numbers—and I don’t know if it’s the law of big numbers or what, but their eyes glaze over.

    Forsgren: Yep.

    Shimel: And they won’t recognize something that’s kind of as plain as the nose on their face, right? So, let’s get some of these highlights. Thirty one thousand plus respondents over the last six years.

    Forsgren: Yep.

    Shimel: That’s huge! I mean, that’s a big pool, right?

    Forsgren: We’ve got a lot of data points around the world, all industries. So, it’s helps our data to be more generalizable. So, that’s kind of a research word. What that means is, it means that there’s a high likelihood that any of our findings will work for you—which is important to me, because I used to be an engineer. I also was a consultant for a few years. And so often, I would come forward with a proposal for a solution, and if it sounded hard, many times, my manager or the lead on the project would say, “Oh, well, that won’t work here. That only worked on that other team.” Well, if my results are generalizable, that means it has a high likelihood of working in any team.

    Shimel: Absolutely.

    Forsgren: Yep.

    Shimel: Let me throw some more numbers out at you.

    Forsgren: Yep.

    Shimel: Normalized annual deployments range from 1,460 deploys a year for high performance down to seven for low performers, right? Seven deploys per year for low performers. Elite performers deploy code 208 times more frequently than low performers, according to the report.

    And here’s another one, and from my mind, and I’ll ask you—probably one of the most thought provoking, controversial kind of stats in the report. And that is that 20% of respondents consider their organizations to be elite DevOps performers, up from 7% just last year, right?

    Now, guys—don’t get hung up on the math, here. Look at those numbers. They clearly say something, right—1,460 deploys per year is roughly four a day, right That’s what high performers are doing, four a day. Seven a year, maybe a little under two a quarter, right? This isn’t calculus, okay? This is plain arithmetic.

    Nicole, what about that 20% number, though?

    Forsgren: So, that’s interesting. Let me take it back just a step.

    Shimel: Okay.

    Forsgren: When we asked people—so, how did we come up with this classification of low, medium, high, elite performers? I asked people four questions about how they’re developing and delivering software, what the outcome is, right? And so, I say, “How often do you push code?” Right?

    And the nice thing about that question is, almost everyone can answer it at a very high level. “Can you push code on demand?” Right? “Can you do it when you want to?” So, that’s kind of deploying on demand, multiple per day-ish. “Can you do it on demand? Do you do it about, between once a week—between once a week and once a month?” Sometimes people are like, “That’s a really rough number.” And I’m like, “Yeah, it’s a rough number, but pretty much anyone can answer that. Are you between once a week and once a month?”

    Shimel: Right.

    Forsgren: You know, notice this is—for people who are kinda into math, this is a log scale. What I mean by log scale is, it’s increasing in big pieces. On demand between once a day and once a week, between once a week and once per month, between once a month and once per six months, right?

    Shimel: Yep.

    Forsgren: These are getting bigger in big chunks.

    Shimel: Yeah.

    Forsgren: Which is nice, because it gives me pretty good reliability. I’m not asking for, “Are you deploying between one minute and two minutes, between two minutes and three minutes?” People aren’t good at that. Systems are good at that, people are not. So, I’m asking in big pieces.

    Shimel: Yeah, these are big buckets.

    Forsgren: Yeah, these are—and they’re large, increasing buckets.

    Shimel: Yes, agreed.

    Forsgren: Okay, yeah. Okay, so then lead time for changes—that’s the next question I ask. “How long does it take to get from I commit code to code runs in production?” Same type of buckets. It takes less than a day, it takes between a day and a week, it takes between a week and a month, it takes one to six months. People can about answer that question.

    Okay, then I have two stability related questions. When something’s broken or when something needs attention, how long does it take to fix? Less than an hour, less than a day, less than a week, between one and six months? Same types of buckets, right?

    Now, change/fail rate. When we introduce something to production, what’s the likelihood that something goes wrong? Now, these buckets are basically like, we put into about six buckets, right? So, like, 0% to 15%, 15 to 30, right, 30 to 45, 56 to 60. And people can generally bucket that in their heads.

    Then what we do is, I take those four numbers and I throw it into the stats hopper, the stats bucket. And then I—it’s actually called a cluster analysis, because we wanna see how they cluster. So, for people who answer those four questions, I say, “How does those four questions, at the team level”—this is not at the organization level. Because why? Let’s think about organizations. Organizations have teams that operate at very different levels, right?

    Shimel: Mm-hmm.

    Forsgren: If we think about, especially big organizations, you have some teams that are super, super fast, and you have some teams that are kind of on the struggle bus. Which is fine, because we do things differently.

    So, I analyze this at the team level, and the we say, “Okay, how do these four things fall out?” And it’s important to investigate this, because for a long time, for decades, a couple decades, we were always told that in order to be stable, we had to slow down, right? So, remember I said, we had the speed metrics—how often do you deploy, ____ changes? Those are speed, those are throughput. And then we had stability, which is time to restore and what’s your change/fail rate.

    Now, here’s the interesting thing—for six years in a row now, those four things have always clustered together. They’ve always grouped together. Now, occasionally, I have people say, “You’re mistaking correlation for causation.” This is not correlation, this is not causation. We are observing in the data, no one—there are no trade-offs. Those things always group together. They are always clustering together.

    Shimel: Yep.

    Forsgren: For six years in a row. Now, you also commented on—now, how do we get there? Everyone put a pin in that in your head—how do you get to better speed and stability together? Or, conversely, how do you suck at all the things at the same time? Okay, we’ll get there.

    But, now, you noted—and this is super interesting and super important—we went from 7 percent of people being amazing at optimizing and speed and stability to 20 percent. That’s an almost tripling. Now, some people are saying, “How are they elite performers? I don’t see 20 percent of people being elite.” Now, this is a definitional thing. This is very much a research definitional thing. This doesn’t mean that—this is me also being a very nice mother. Like, I love all of my children. Everyone is—I love everyone equally. All of my children are special, right?

    Shimel: Equally. Right. [Laughter]

    Forsgren: Not everyone is going to be a Netflix type of, you know—

    Shimel: Organization.

    Forsgren: —deploying a thousand times a day. Remember, that definition of elite was, you can deploy on demand, multiple times a day. It could be two or three or four times a day, which was how we did the math, because we were like, “We’re gonna be conservative. We’ll call it four times a day.” And I say this in the report, I randomly picked a number, I said four. Four seems reasonable. Some of these companies are deploying thousands of times a day. I picked four instead of five.

    Shimel: Look, I personally think four times a day is amazing, if you’re deploying four times a day—

    Forsgren: Yeah, oh, that seems amazing. But some companies are doing thousands, okay? So, when I say elite, I’m not saying elite is thousands, I’m saying on demand and four seems fine. Making time for changes, it’s less than a day. I didn’t say it had to be 10 seconds, right? But that is also my upper limit, because of how I’m collecting my data. I’m not collecting my data from systems, I’m not saying that elite is 5 seconds versus 10 seconds, because I cannot ask a person, right—

    Shimel: And who is—right, you’ll never be able to measure that.

    Forsgren:—or I can’t ask a person five seconds versus 10 seconds. I can only ask—less than a day.

    Shimel: But let’s put that in context.

    Forsgren: Yep.

    Shimel: So, elite performers do it in less than a day. Low performers are something like 2,500 hours.

    Forsgren: Yes, low performers are between one month and six months. This is still a huge—

    Shimel: You’re talking a day—so, we don’t need computer precision to the millisecond.

    Forsgren: Nope, nope, nope.

    Shimel: We’re talking a day versus months.

    Forsgren: Months.

    Shimel: And people, you don’t have to be a genius to see the difference there.

    Forsgren: Exactly. And the great thing is that this is absolutely achievable. And think about what this means for your companies. If you go from deploying code two, three times a year to being able to push code in less than a day and every single day? Some people are like, “Oh, I don’t need to push features that often to my customers.” That’s great, but you know what you probably do need to do is keep up with compliance and regulatory changes.

    Shimel: Yep.

    Forsgren: You need to keep up with security threats. You need to keep up with infrastructure. This allows you to pivot any time you need to pivot. This allows you to keep up with so many things in your environment.

    I gave a great talk at Black Hat with Kelly Shortridge, and she pointed out that one of the best things you can do to be a pain in the butt for security is to re-roll your infrastructure. Because every time you re-roll a container or re-roll your IP is—an attacker has to completely start over from scratch, now.

    Shimel: Yeah.

    Forsgren: This is so smart, and so good.

    Shimel: Well, and that was one of the great things about immutable infrastructure, right?

    Forsgren: Exactly!

    Shimel: Is, you can absolutely just start from, let them start back—you know, pull the rug out from under the hacker. I mean, but it’s such a—these numbers, like you said, you see these clusters always come together.

    Forsgren: Yep, yep.

    Shimel: They always follow each other. So, time to remediation, right, becomes such a huge thing. Failure rates drop through the floor when you start doing this.

    Forsgren: Yep.

    Shimel: You know—

    Forsgren: And I love that you point out, when we compare the high and the low performers, our speed metrics, our elite performers are 208 times—they’re seeing 208 times more frequent code deployments. They’re 106 times faster, code commit to deploy. The stability metrics are hug. The elite performers are over 2,600 times faster recovering from incidents. And they see seven times lower change/fail rate. This—this is huge.

    Shimel: The numbers are real. Can I throw one other thing at you?

    Forsgren: Yeah, yeah, of course.

    Shimel: These people who tell you, “Our customers don’t care if we update frequently, it’s not important”—I used to believe them, Nicole. But I’ve come to the conclusion that they’re full of crap. That’s arrogant elitism at its worst, and if you don’t think your customers want you to stay on top of things and be current and constantly improving—show me who you are, because I can’t wait to disrupt you and take your customers from you.

    Forsgren: Well, and it’s interesting—

    Shimel: But I don’t buy that any more.

    Forsgren: I have spoken with one or two government and military contractors who have said, “We live in a different space. I do not have a customer”—

    Shimel: Yes, they do.

    Forsgren: Well, and they have said, “I have a customer that doesn’t require a feature change.” And I’ve said [Cross talk]—

    Shimel: No, they do. I’ve sold to the military for years.

    Forsgren: Sure, sure.

    Shimel: They want—you know what? And as counterintuitive as it may be, the military—and I’ve sold to all of our armed service divisions as well as the Secretary of Defense at the Pentagon—they, in a lot of ways, lead. Because their requirements are constant. This is why they have things like DISA and they have things like In-Q-Tel that are investing in the next gen.

    Forsgren: Oh, absolutely.

    Shimel: Because their requirements are constantly pushing the envelope.

    Forsgren: Oh, sure. But to that person in particular, I did have someone come up to me after a talk and say, “I actually do not have any competitors. I do not have feature changes.”

    Shimel: No, they do. It’s a single world. [Cross talk]

    Forsgren: Well, but, to him, I said, “Okay, sure, but you do have compliance and regulatory changes, and you do have security changes.”

    Shimel: And you have changing missions.

    Forsgren: Yep.

    Shimel: Their mission changes. They need—so, again, I just, I don’t buy those people. I think that arrogance is misplaced.

    Forsgren: Well, but, it was interesting, because as soon as I pointed out compliance and regulatory and security, he said, “Oh, well, that’s right.”

    Shimel: Oh, yeah, yeah.

    Forsgren: And that’s what we struggle with.

    Shimel: Yep, I agree with you. So, a couple other things, and we’re running low on time, I apologize.

    Forsgren: Yep, yep. [Laughter]

    Shimel: We could go all day. So, you know, this is the first year that it was Google Cloud involved. Well, Google Cloud was a major sponsor last year.

    Forsgren: Yep, we collaborated with them this year—or last year, and then this is the first year that we’ve joined Google Cloud.

    Shimel: So, let’s talk about what they brought to the party.

    Forsgren: So, they were just a wonderful partner this year. What I really appreciated about working with them this year is, they still allowed me full research independence, and it was fantastic to work with them.

    Shimel: Yeah. Well, and it also seems like they’ve brought, they’ve given you the ability to add more resources, perhaps, to the whole process.

    Forsgren: Yeah. I really loved being able to work and collaborate with Dustin Smith this year. He brought a fantastic eye for research and analysis this year. He has a phenomenal, phenomenal statistics background. And it was almost like being back in academia again where I could have another academic—he has a Ph.D.

    Shimel: Collaborator.

    Forsgren: Yeah! So, I had, like, a full academic peer where I used to be able, when I was a professor, to walk next door and bounce ideas off of someone and have someone replicate every single one of my analyses.

    Now, in the past, I used to pull former Ph.D. students to replicate a handful of my findings. But, as a tiny startup, you’re real scrappy.

    Shimel: Yeah.

    Forsgren: This year, I had Dustin, and he replicated every single one of my findings, and then he came up with new ideas, and we could really spitball off of each other and we had full peer review on every single one of our analyses. It was, like, it was just this academic research dream. It was wonderful.

    Shimel: No, it’s great. I mean, but this is, for entrepreneurs out there, for people in startups listening to this, this is one of the great things about when you do do a merger or acquisition or whatever. The idea that you now have peers—

    Forsgren: Yes!

    Shimel: —to bounce around stuff with, to collaborate with. Because, you know, startups, we run lean and mean.

    Forsgren: [Laughter]

    Shimel: But sometimes, it’s—that’s the code word for by yourself. [Laughter]

    Forsgren: Yep, yep. [Laughter]

    Shimel: And so, it’s not as cool. I just wanted to mention, you know, quick commercial—we’re doing The DevOps Experience, that’s coming on, I think it’s October 10th. Nicole, you’re headlining. You’re gonna go into greater detail on this, so if anyone’s listening—

    Forsgren: Yes, yes! And this year, for the first time—so, in years previous, we’ve always investigated performance. How to make software development and delivery both fast and stable. This year, in 2019, for the first time, we also dug into productivity. So, we have two full research models. So, I will be sure to dig into that.

    Shimel: Absolutely. So, you can check that out on DevOpsExperience.io. This is a virtual event, guys, you can watch it from your desktop.

    Secondly, Nicole, I guess the obvious question is—alright, what’s the time frame for next year?

    Forsgren: Oh, well, I need to take a nap first. [Laughter]

    Shimel: Okay. [Laughter]

    Forsgren: But we tend to release the report late August, so I’m guessing that neighborhood, that time frame.

    Shimel: Well, that’ll be the report, but when do we start, when do the next year’s survey questions come out and all of that good stuff?

    Forsgren: So, we usually release the survey and collect data in the March/April time frame.

    Shimel: Yep.

    Forsgren: So, I’m guessing that as well.

    Shimel: So, are you already working on next year’s questions?

    Forsgren: I mean, I’ve got a couple ideas in the back of my head, but research is a very creative process, so I try to take at least a month to just unwind my brain.

    Shimel: Totally [Cross talk].

    Forsgren: Yep, and then—

    Shimel: Well, it’s well deserved.

    Forsgren: Dustin and I and the team will start kind of opening our brains again. Luckily, we will be at DevOps Enterprise Summit, where we’ll be giving a talk, Dustin and I are speaking, and then that’s one of the best places—

    Shimel: And that is October 28th and 29th at the Cosmopolitan in Las Vegas.

    Forsgren: Yep.

    Shimel: And you can get information, I guess, at IT Revolution.

    Forsgren: Yep. And that’s a fantastic opportunity for us to attend talks, speak to everyone who’s really involved in transformation, the wins, the questions, the challenges—that’s where I get so much inspiration. I get all of it, year ‘round. I’ve got, like, my favorite Google Doc where I keep track of ideas. [Laughter] But that’s where I get a lot of the stuff that people don’t necessarily share out in the wild. That’s where I get a lot of my really great research ideas.

    Shimel: We’ll be broadcasting live from there, so you’ll have to come down and do a quick little live interview—

    Forsgren: Yeah, for sure!

    Shimel: —with Digital Anarchist. Very cool. Can’t wait to see you there. So, Nicole, I apologize. I told you this was gonna be 15 minutes and I think we ran 30-something. [Laughter]

    Forsgren: Sorry, everyone!

    Shimel: But it was well worth it, it was well worth it. Hey, we’ll see you on DevOps Experience, I will see you in person at The DevOps Enterprise Summit in Vegas at the end of October, but in the meantime, go take some well-deserved rest time, my friend. You did good.

    Forsgren: Thanks so much.

    Shimel: Thank you. Dr. Nicole Forsgren, Founder, CEO of DORA, part of Google Cloud, our guest on this DevOps Chat. This is Alan Shimel for DevOps Chat, devopsy.kinsta.cloud. Have a great day, everyone.

    — Alan Shimel

  • DevOps Chat: CI/CD Scalability Lessons with CircleCI

    DevOps Chat: CI/CD Scalability Lessons with CircleCI

    The software development tool needs of a two to three person team can be much different than those of a large enterprise. CI/CD is a common approach nearly all software teams establish. But what needs of a larger software organization do you adopt early on and which simply add more complexity than benefit?

    Rob Zuber, CTO of CircleCI, began tackling this problem in the mobile space and then moved to CircleCI to help create what is now a well established SaaS-based CI/CD offering to software teams of all sizes. Join us on this episode of DevOps Chat to take away some valuable CI/CD lessons for your organization.

    Transcript

    Mitch Ashley: Hi, everyone. This is Mitch Ashley with devopsy.kinsta.cloud, and you’re listening to another DevOps Chat podcast. Today, I’m joined by Rob Zuber, CTO of CircleCI, and our topic is software innovation at scale. Rob, welcome to DevOps Chat.

    Rob Zuber: Thanks so much, Mitch, it’s great to be here. Thanks for having me.

    Ashley: Would you start by introducing yourself, tell us a little bit about what you do and tell us a little bit about CircleCI.

    Zuber: So, I’m Rob, as you said. I’m the CTO here at CircleCI. I’ve been with the company almost five years now, and I’ll talk a little bit about how I got here once I talk a little bit about what CircleCI does. I think that’s probably the right order.

    So, CircleCI, our big focus is helping every software engineering team be better at what they do. So, be better at getting software from their sort of concept and idea to value delivery in the hands of their customers. So, we sit between the collaboration element and the production deployment element by really being the delivery pipeline. So, we help you take your software from the point that you’ve, again, had an idea, started to write, to making sure that works well, making sure everything everybody’s doing is working well in concert and getting that into a production environment where you can start to realize customer or business value confidently, quickly and being ready to move onto the next thing and to drive value for your customers.

    Ashley: So, this is a pretty big space, a lot of folks in it. I mean, people can download Chef or Puppet or Jenkins and—you know, we could go on and on about different tools within sort of that CI/CD pipeline chain.

    But tell us a little bit about where you uniquely fit into the market.

    Zuber: Yeah, so, a lot has changed in the market over the time that I’ve been here, unsurprisingly—not just at CircleCI, but in the market in general. We’ve seen a lot of people come and go, a lot of companies either snapped up into larger organizations, but maybe they weren’t going to be focused, necessarily, on CI/CD standalone or just not reach sort of critical mass as an organization.

    And the market has also shifted, and what we see now is a lot of people trying to maybe add CI and CD as an extension of something that they’re doing, but not treating it as the core business that they focus on. So, that’s the real thing that separates CircleCI is our focus on CI and CD as a core of what we do. Every day when we get up and get to work, that’s what we’re focusing on, and not tying you into—you know, you’re using this CI and CD capability because it’s part of this other package that you maybe want or don’t want, and really being the choice in this space and giving developers the opportunity to pick the best tool that they want in every different part of their flow, if that makes sense.

    Ashley: Let’s peel back the onion a little bit more. I know that—I mean, it’s a very complex process and CI/CD and all the tools you might use, if I understand correctly, you don’t take a “let’s try to be everything to everybody,” but more of a platform approach with workflow and then you can plug in various tools as part of that workflow package and you pack things into orbs for configuration management, et cetera.

    Can you give us a little bit more detail and meat on the bone about that?

    Zuber: Yeah, that’s exactly right. Well, we believe it’s kind of hard to be wrong about this, I guess, that our customers are software developers, right? And so, they are more than happy to create the capabilities they need if we give them the tools to do that. And orbs is one of those such tools.

    So, it’s basically about realizing that many of our customers are very capable, they’re solving very similar problems, and giving the opportunity to share that, to reuse pieces and then to build. Some of those problems that they’re solving are building integrations with best in breed components of things that we don’t necessarily provide, right? So, that might be something like, I guess, anything from vulnerability scanning or connecting into security systems through to how you do integration with your eventual deployment target, right?

    Ashley: Mm-hmm.

    Zuber: And rather than trying to solve all of those problems and say, “Well, you need to deploy,” like, we’ll also build a cloud and you can deploy to that cloud, or we’re also gonna build all of the tools for all of these parts of your system. We basically give you a really central and easy to use pipeline, effectively, or workflow is the term that we use for it, and the ability to plug into that, those capabilities, right? So, by leveraging orbs which our partners build, you know, to get access to their systems, community members have built, and we’ve built, basically to give you access to the richness of the ecosystem, if you will, using that to really tap into those additional systems, but the ease of central management of all that. So, you have great clarity about what’s happening in your delivery process.

    Ashley: And I understand congratulations are in order. Recently, you had your series D, 56 million led by Owl Rock Capital and NextEquity Partners—congratulations.

    Zuber: Thank you very much. Yes, it’s very exciting.

    Ashley: So, with great power comes great responsibility. What are you gonna do with that money? [Laughter]

    Zuber: Yeah, that’s a great question. I mean, honestly, a lot of it is very much continuing on this trajectory, right? Like, we believe in what we’re doing, we believe we’re doing the right things and we have the success to show for it, but in every one of those areas, we can do more, right? So, we’re continuing to invest in engineering and product development, clearly to add capabilities. I mean, part of that is really building around those types of integration models like orbs that we talked about.

    Also, taking one of the key areas that we’ve really had—well, I guess just through our success over the years, because we’ve been around for about eight years as a company—we’re sitting on a lot of deep understanding of how software engineers are building. We have thousands and thousands of customers building tens or hundreds of thousands of projects. And so, we see that, right? We see the flow, we see what works for them, what doesn’t work.

    We see whether they—basically, the rate at which they’re able to deliver software, the kinds of tools they use, how the ecosystem is supporting them or not, and being able to take all of that rich data and turn it back to our customers as value for them to really help them be better. Like, moving away from just a tool—I mean, a great tool, but really, a tool that not only moves your code through, but helps you understand how you could be doing better and where your opportunities are for improvement. Or, honestly, at the other end, it’s always worth mentioning, if you’re doing great and you can invest your time and energy in something else, because things are really stable and working well, right?

    So, that’s a place that we’re making some investment for our product with that perspective, and then again from a, I guess, the extension that we talked about and just investing everywhere that we’re already investing in core CI and CD. I mean, over the time that I’ve been with CircleCI, the entire process of software delivery and how we package and build product has fundamentally changed, and I expect that to continue to happen. I mean, the pace at which we move in this market is a little crazy sometimes.

    And so, we need to continue to evolve to support how software development is getting done in order to be, really, the best tool, as we are today, for software delivery.

    Ashley: And I should know this, probably—are you running the jobs that you’re seeing in the cloud or is a lot of this on prem for customers? How do you get access to that [Cross talk]?

    Zuber: Yes, great question. So, we offer both. We have a cloud platform, which is, the majority of our customers use that, and the majority of the builds that we’re running are on that platform. We do have an on-prem solution as well for very large customers with complex cases or specific needs where they’re interested in deploying the software and operating it themselves.

    Yeah, and so, one thing I was gonna say about that change, and tying it back to kinda orbs and being able to integrate with other systems that we’ve talked about, we’ve been evolving to support the change in the market, but also evolving to have a more flexible platform because we see this constant change, and not wanting to play catch up or try to stay ahead of it all the time, but rather, create more flexible tools that continue to evolve with changes and how people do software development and give our users and our customers the ability to use the platform in ways that they see fit or best meet their needs as we continue to evolve.

    Ashley: That certainly makes sense why you focused around the orb strategy and investing in CLI and APIs. Are you also focusing on onboarding?

    Zuber: Absolutely, yes. So, I think the key to this for everyone is time to value, right? Like, CI and CD can be a complex system—

    Ashley: Mm-hmm, very.

    Zuber: And it depends a little bit on the size of your org. But, as I said, when we talk about those small little companies starting out, I mean, they just want something that works that will get out of their way. And so, it’s that sort of gradual growth with you as a team to meet you where you are.

    So, if you have a simple application and you’re really focused on finding product market fit, then it should take as little effort as possible to get up and running and just make sure that you’re delivering with confidence so you can focus on those iterations of your early—I always talk about it in terms of companies like startups, but it might just be an early project, right, in a larger organization. Those small new projects are a great place to try out new capabilities, new tools, new processes.

    And so, supporting you to get up and going and realizing that value very quickly, but again, as you get to large organizations, you need to be able to roll in more and more capabilities. But getting up and going quickly and really getting those moments where you recognize, “Okay, this is actually changing how I’m working and this is really valuable,” that needs to be very simple, and so, we’re constantly investing in making that as simple for as many different kinds of teams, of projects, code bases, tech stacks, again, as they change, we want to cover as many of those as possible.

    Ashley: You’ve talked about startup companies and startup projects, but I know, also, you focus on enterprises. Those can be very, very different—drastically different in terms of customer requirements, issues, scale that you have to solve. What are some of the challenges that you’ve both run into, encountered, and also feel like you’ve addressed pretty well in those two different communities?

    Zuber: Yeah, that’s exactly right. I mean, I like to think of it as a continuum. I don’t know, maybe that just makes me happier than two really distinct communities, right? And I think that one of the things you see in enterprises that are succeeding is seeing the types of approaches that smaller companies take, right? But, of course, you have to take that and figure out how to make it work at your scale.

    Ashley: Mm-hmm.

    Zuber: To your point, we absolutely have a very large number of very large customers, about a third of the Forbes Cloud 100. So, really large, influential, but I would still say—that particular group, tech forward companies. Meaning, coming from a background where their software development was always central. You mentioned transformations previously, so we also play in a lot of those. But it’s a different space, right, of companies that are trying to reimagine how they build versus companies that have grown to scale, sort of always thinking about software development.

    But many of the challenges are similar, right? Just the pure scale. And so, that scale comes in multiple different forms. It might just be the total volume of jobs that you’re running, and the growth of our cloud platform over the years has been remarkable, and we’re constantly working to figure out what’s the next order of magnitude, the next order of magnitude, how do we continue to support that as we just continue to go through this growth, which is fantastic, but also exciting, I would say, from an engineering perspective.

    Ashley: Mm-hmm.

    Zuber: So, there’s kinda pure scale on just a job perspective, but the things that get more interesting and that we’ve really invested in are, for example, the complexity of workflows, right? So, if you have a lot of different systems that all need to be either validated together or have dependencies that need to be understood as they flow through the CI and CD process, or maybe a large set of validations that you do beyond just testing. So, that might be—again, I mentioned security scans earlier, linting. You know, all of the kinds of gates and processes that get put in place as companies get larger and being able to manage those independently against a very large code base with a large number of contributors.

    Again, that might not be total number of jobs, for example, but the complexity of those definitions scales itself, the number of developers contributing—that scales. And so, orienting the product around those kinds of scaling points has been something that we’ve had to do as our customers have grown, as we’ve brought on large customers where we’ve really invested a lot of time to make sure, particularly in a cloud environment, which is where—there’s an additional layer of value, for sure, for our customers, because they don’t have to think about any of the management, right? They come in with very, very large workflows, and the capacity is all available. And when they’re quiet, they don’t have to worry about additional machines being online or wastage or anything like that, because we’re managing all that for them.

    Ashley: Mm-hmm.

    Zuber: And so, doing that for this large blend of customers, some of whom are quite big and driving a lot of work, is something that we’ve really figured out.

    Ashley: Well, thinking about, you mentioned continuum, which is a great way to think about it, too—why don’t you share with us a couple lessons that you’ve seen customers learn, maybe you’ve learned yourself, running your own product development and software development process. As people go from that continuum of, “I’m just getting involved in CI/CD,” using a product like yours, obviously, there’s great features and stuff, we all know that, that you all have—but what are some of the lessons that they learn as someone goes from, “I’ve got a development team, we’ve just implemented CI/CD,” kinda getting up to this point? The next scale issue that we tend to run into is X and then kinda what happens after that.

    What’s that maturity lifecycle look like?

    Zuber: Yeah, I really like the word maturity that you used there. Because I think that a lot of times, when we think about this, we think about the growth of companies at scale, we spend a lot of time talking about tools. And of course, you know, it’s easy to look at CircleCI and what we do and think about it as a tool. But ultimately, the biggest challenges are gonna be shifts in culture, right? So, process how you think about getting work done, how people interact, definition of roles and responsibilities.

    I mean, everybody starts out in a—well, everybody—when you start a company in this space as a tiny little, maybe you’re like three people, five people, whatever, roles tend to be pretty loose, because everybody’s just trying to get done whatever needs to get done, right? And one day, you’re the DBA and the next day you’re the barista making sure everyone else has enough coffee to get work done, right?

    And as you grow, there’s parts of that that you really wanna keep—absolutely, right? Like, the focus on the mission and being really clear about where you’re trying to get to. But, it becomes more challenging for everybody to do everything, right? You actually need to have some clear boundaries and understanding.

    So, that shift in culture that is like—what are the parts that we keep? Or one of the ways that I often describe it, and we, you know, for our own part, as I said, have gone from about 20 when I joined to 250 and still growing. One of the things that I always look for is what was the intent, and then how do we implement that now at this next level of scale?

    Ashley: Mm-hmm.

    Zuber: And I think that applies to your tooling and your process and everything else as well, right? So, we have always been a very transparent company. And so, transparency when you’re five, 10, 20 people is usually about just kind of making sure everyone knows everything that’s happening. But when you get to 250 people, it’s about really being clear about what’s happening, but being able to define that message and convey it in a way that’s not just this firehose of information or an overload for everyone, right?

    And I’m trying to shift that back to sort of technology and where you were going with this—even though I believe it’s ultimately, it’s these underlying cultural pieces. When I look at people building software, I see, for example, people looking to large organizations—you know, Google, Facebook, Netflix—and saying, “Well, they build software like this, so that must be right.” And again, it’s important to look at the intent, right?

    So, yes, you probably wanna have a CI and CD pipeline, because it’s gonna get a lot of stuff out of your way, but I would guess that when you’re starting out, you probably wanna have a very simple application, because you don’t know yet what your business is, whether you have a business, what the fit is.

    Ashley: [Laughter]

    Zuber: So, this is like, this argues for the monolith, right? Everybody, ultimately—not everybody—many people ultimately say, “You know what? The monolith isn’t scaling with our organization. It doesn’t match our ability to follow our intent. Our intent might be autonomy or ability to work on disparate areas of a product separately, stuff like that.” That works, actually, really well in a monolith at a small size, because you have so much shared understanding.

    Ashley: Right, right.

    Zuber: And at some point, maybe you say, “Okay, this isn’t working any more, we’re gonna start breaking out services”—kind of a natural evolution that many companies go through. But, again, people look at that at the beginning and say, “Oh, well, that’s where we’re gonna end up. Let’s just do it out of the gate” and bring in a lot of overhead and complexity that’s unnecessary for their size, and ultimately end up, I would go so far as to say failing, because they create sort of a technical overhead or burden that’s not in line with where they’re at as a business.

    Ashley: Mm-hmm.

    Zuber: And so, if I were to pull out the underlying lesson in all of that, it’s like—find the intent in what you’re doing and then determine the implementation that’s right for your scale. And then, I guess the other big lesson if you’re going through scale at a high enough rate, recognize where you are on that curve and recognize that it’s changing, right? Because it’s easy to think that things are gonna stay the same and the system that you have is gonna be a great system for a long time.

    But if you’re growing quickly, this applies to your software, it applies to your team structure, to how you manage your organization. You need to be aware of that change.

    Ashley: Yeah, I believe that when we talked about developing software, what organizations are really doing is learning how to create software, and that’s what we—or the team, the organization is in the process of doing, and then there’s that evolution on the maturity curve.

    So, you, whether you’re the QA person, the DevOps person, the developer, the architect, et cetera—it’s about all that function so that you can think of it as running a football play or a soccer play or a baseball play. You’re learning to function and operate as a team to create software. Do you agree, disagree?

    Zuber: Yeah, I think it’s quite on point. And the reason that I think this is really fascinating, I know this is very—speaking of side tangents, my earliest days before I got really into software development, I actually spent in a factory. I was a process engineer. And the great thing about a factory is, we would build tens of thousands of the same thing, every day. And so, refining the process was about refining the process for building the same thing.

    But in software development, you basically never build the same thing twice, right? I mean, you might get hired into another company and someone’s like, “It’s great that you are here, because we need you to build basically the same thing that you already built.” But it’s this constant discovery, right? You’re constantly in a design phase of trying to figure out how do we go about building this thing that we’ve basically never done before? And of course, there’s prior art out there and all those things, but we have to map that then into our specific domain, our specific team and constraints.

    And so, a lot of that is figuring out—okay, we know that we need to do a thing and we have some basic sense of that, but how do we map that into our process? And you certainly described it as our model for building the software as opposed to just thinking about building a thing.

    Ashley: Well, we’ve run out of time. Rob, we should just grab a beer or a coffee and finish this conversation in about three hours.

    Zuber: I’d love to. Perfect.

    Ashley: [Laughter] Sounds great. Well, thank you for being a guest on the podcast. This is Rob Zuber, CTO of CircleCI. Appreciate you joining us.

    Zuber: Yeah, thanks so much for having me. It was great fun.

    Ashley: It’s been a pleasure. And also, thank you to you, our listeners, for joining us. This is Mitch Ashley with devopsy.kinsta.cloud, and you’ve listened to another DevOps Chat. Be careful out there.

    — Mitchell Ashley

  • Quality Engineering Has DevOps and Agile in the Driving Seat

    Quality Engineering Has DevOps and Agile in the Driving Seat

    As opposed to the traditional software development lifecycle (aka waterfall), today’s Agile and DevOps-based software development process is more outcome-oriented. The unrelenting pace of the changing market landscape has made the hybrid, Agile plus DevOps way of software development absolutely critical in addressing customer demands and staying competitive.

    The focus on Agile and DevOps is necessary due to the high failure rates of traditional software development methodologies. These failure rates are mainly attributed to the glitch-infested, low-quality applications churned out by following legacy methodologies.

    The failure rates had left many companies to bite the dust and brought the key role played by quality in ensuring customer satisfaction and ROI for the business into sharp focus. Also, the IT landscape is witnessing developments such as mergers and acquisitions, increased focus on risk and compliance, data and analytics, the fast rollout of apps and mobile commerce, among others. These have necessitated the software development process to become increasingly agile, streamlined, collaborative and flexible. The reshaping of customer expectations is letting organizations to go beyond shift-left testing or DevOps testing by transforming the QA process into one driven by quality engineering.

    What Is Quality Engineering?

    To meet the growing demand for quality software applications in double quick time, a mere tweaking of the software development process is not enough. What is needed is the adoption of software quality engineering process comprising optimal quality assurance, predictive analytics and monitoring of QA elements to reduce glitches to negligible levels. The process would involve a continuous cycle of feedback and quality improvement based on the same. The quality engineering process offers maximum test coverage in the shift-left scheme of things and ensures outcomes like functionality, security, accessibility, usability, performance and reliability of the software application. It complements Agile and DevOps methodologies and ensures their outcomes to remain consistent with the desired business objectives. Quality engineering, instead of identifying the inherent glitches in the SDLC, focuses more on preventing them altogether.

    Shift Left and Strengthen Right

    Quality engineering services cover the entire spectrum of the SDLC thereby yielding the maximum test coverage and delivering the best quality product. With DevOps testing shifting left, the quality determinants are incorporated right into the product build during the development phase. At the same time, DevOps-based QA focuses on the shift-right approach to ensure the last stage of the SDLC i.e., delivery goes on unhindered and customer feedback is taken in right way and worked upon. The ultimate aim of both shift-left and right is to create and deliver a glitch-free product that meets the requirements of the end-users. Here, since end-users are the ones who ultimately assess quality of a software product based on parameters such as usability, functionality and performance, among others, the feedback mechanism should be responsive enough to understand the issues faced by the end-users and remedy them at the earliest.

    Quality Engineering as an Aid

    Quality engineering (QE) helps to bridge the gap between development and deployment processes, which can arise due to the lack of agility. It harps on the successful strategy of “test early, test often,” to pre-empt challenges that businesses face when testing a software product. Quality engineering ensures the quality of a software application throughout the SDLC–right from the designing stage to its final delivery. QE can be incorporated into the development process by using methods such as Behavior-Driven Development (BDD), Test-Driven Development (TDD) and Acceptance Test-Driven Development (ATDD) respectively.

    Let’s find out what these methods are all about:

    • BDD: In this software development method, the behavior of both the software and business outcomes are taken into consideration. Here, the right sets of tests are automated, leading to an increased collaboration among developers, testers and other business stakeholders.
    • TDD: In this software development process, the QA team writes unit level tests before the development stage. This results in getting an early feedback and helps the development team to refactor its requisites.
    • ATDD: This software development process focuses on writing an acceptance test even before the development phase. This helps the software to meet the acceptance criteria beforehand.

    Quality Engineering and DevOps

    QE, being an end-to-end testing methodology, can offer optimum solutions to businesses struggling with their legacy IT infrastructure. The solutions in terms of continuous testing and integration as mandated by DevOps, can be arrived at by integrating the QA process with the DevOps pipeline. This results in executing processes such as build, test, deploy and deliver in a seamless manner. QE complements DevOps and Agile by detecting glitches right at the beginning of the development process.

    Moreover, QE’s focus on end-to-end testing helps the product to be developed and tested simultaneously. This approach adds teeth to the DevOps’s requirement for continuous integration (CI) and continuous delivery (CD). No wonder, the successful implementation of quality engineering is underpinned on fulfilling the requirements of DevOps and Agile. It further consolidates the benefits achieved from implementing DevOps testing services and Agile testing services.

    QE riding on DevOps and Agile can help businesses to scale up their operations without investing much resources and time. By implementing DevOps test automation and Agile test automation using a test automation software such as Selenium, Robitium etc., businesses can boost their SDLC. QE can help businesses to develop and deploy glitch-free software speedily and deliver enhanced customer experience.

    Conclusion

    The fast-changing competitive business landscape of today requires organizations to streamline their operations, increase productivity and fast forward the delivery of glitch-free software applications. To achieve these objectives, they need to make quality engineering as part of their development and testing cycles. However, QE ends up complementing the Agile and DevOps approach by achieving outcomes such as CI and CD. Furthermore, it leads businesses to get high ROI, better productivity, reduced cost of operations and enhanced customer experience.

    — Akshaya Choudhary