Tag: continuous integration

  • The Surprising Secret to DevOps ROI

    The Surprising Secret to DevOps ROI

    As a result of my many years of DevOps consulting, I have discovered a simple, but not well-understood, secret ingredient that drives ROI for all the Three Ways of DevOps.

    Measuring and optimizing return on investment (ROI) for DevOps is not well-understood. It is a proven fact that DevOps, when engineered well, delivers tremendous value to organizations by way of continuous delivery practices. Reduced lead time, more frequent releases, lower failure rates and faster time to restore services are well-accepted indicators of DevOps value. It is not a secret that the combination of engineering DevOps practices for people, processes, and technologies around the Three Ways of DevOps – continuous flow, continuous feedback and continuous improvement – gets results. As valuable as these things are, they are not a measure of ROI, and do not tell you what to do to improve the return on your DevOps investments.

    How Do You Calculate and Optimize DevOps ROI?

    First, it is important to understand that ROI for DevOps is best measured using a simple ratio of return (R) divided by investment (I). (OK – for the accounting purists out there; I know the real ROI formula is actually (((R-I)/I)*100%) but that is a technicality that we don’t need for this argument.)

    The “return” of DevOps value is the important factor in the numerator of the ROI ratio. While there are many values that can be attributed to DevOps, the most direct value that can be measured and justified for legitimate comparison purposes is the cost savings associated with accelerating software delivery value streams. Application developers, and others, can get more applications released faster because of DevOps, which has a dramatic effect on valuable cost reductions. The “investment” in DevOps projects is the denominator of the ROI ratio. To optimize ROI, simply increase return by getting more application releases out faster, while reducing the investment required for a DevOps project. Sounds easy enough. But wait! How do you do that?

    The primary factor in the return is derived from reducing bottlenecks. I have found, in more than half of the thousands of DevOps value streams I’ve studied, that the biggest bottleneck is testing! It is a myth that continuous testing is just the execution of automated tests. I am talking about the whole range of ‘testing things,’ including test strategy, test planning, test resource scheduling, test design, test implementation, test environment management, test execution, test results reporting, test result analysis, troubleshooting, fix, retest and test management. That is a lot! In fact, testing things are a source of bottlenecks for every stage of a DevOps pipeline, for all three ways of DevOps. The point is that ROI can be greatly improved by improving testing.

    As it turns out, the primary factor in reducing investment costs also has to do with testing! Putting ‘testing things’ in place is expensive in terms of labor and capital costs for both people and systems. The primary factor to reduce total investment cost is to standardize, share and use ‘testing things’ with as many application pipelines and stages as possible.

    What is the secret ingredient that I have discovered? After all, the importance of testing itself is not much of a secret. I have isolated the key ingredient that is the heart of all ‘testing things.’ The purpose of a test is to determine a verdict. A test verdict is the codified representation of a pass, fail or inconclusive result state of a test, assessed relative to the purpose of the test. Test verdicts are essential, no matter what kind of test it is; no matter the stage in the pipeline a test is used. Without a verdict, all the ‘testing things’ in the world are not valuable.

    So – the secret ingredient for optimizing DevOps ROI is to optimize test verdicts. Those that know how to optimize test verdicts hold the key to optimizing DevOps ROI.

    As I indicated in this eBook I authored for the DevOps Institute, verdicts from properly engineered testing at each stage in the pipeline are essential for assessing the artifacts produced in each stage.

    How Can You Optimize Test Verdicts?

    As I have pointed out in prior articles, well-engineered DevOps requires balancing the nine pillars of DevOps.
    Surprisingly, test verdicts play a crucial role in optimizing all nine pillars of DevOps, and are vital to accomplishing the best return for the least cost investment in DevOps. Here are some examples of how this works for each pillar:

    Leadership – Leaders tend to underestimate the importance that ‘testing things’ have on DevOps ROI, and that the central ingredient of test effectiveness is the optimization of test verdicts. By sponsoring DevOps projects and training programs that drive improved test verdicts, leaders will have a direct and lasting impact on ROI.

    Collaborative Culture – How often have you seen people wasting time arguing over the meaning and importance of a test? Collaboration between application developers and QA and Ops teams is more effective when test verdicts are clear and based on a common understanding of the purpose and importance of each test.

    Design – The creation of excellent tests, designed to efficiently resolve to clear verdicts during the design phase, makes for reusable test assets in all subsequent stages and releases, and can be reused with other applications.

    Continuous Integration – The validation of builds is faster when all integration tests are arranged to get clear verdicts quickly during the build process.

    Continuous Testing – Test verdicts associated with each test are the key information ingredient that test management systems can key off to optimize test selection and test execution for each stage in the continuous delivery pipeline.

    Elastic Infrastructure – Test environment management (TEM) systems can optimize the orchestration of test resources better when test verdicts are clearly understood. Knowing a history of verdicts for a group of tests indicate which resources and how much of each resource are needed to run each test. This knowledge is essential to drive test environment management systems that have scaling algorithms for optimizing the use of ephemeral test environments, and to ensure test resources are used optimally.

    Continuous Monitoring – Reporting and analysis of test results can be a major bottleneck in the pipeline, but can be dramatically accelerated when the test verdicts are clearly defined.

    Continuous Security – Security tests are not much use without a clear verdict. While there is no such thing as 100% security assurance, the aggregate set of security test verdicts helps to profile security for applications and releases.

    Continuous Delivery – Algorithms that govern the ‘doneness’ of an application release candidate, and decisions to promote a release to production, depend on analysis of service level objectives (SLOs) derived from service level indicators (SLIs), including test verdicts. The fidelity and quality of those verdicts is essential for operations and site reliability engineering (SRE) teams to be confident enough to not bottleneck an application release.

    What This Means

    Measuring and optimizing DevOps ROI requires strategies that deliver value by improving returns through reducing bottlenecks and reducing investment costs. ‘Testing things’ are a dominant factor contributing dramatically to both the return and investment components of the ROI equation. A comprehensive strategy for optimizing test verdicts is the secret ingredient for optimizing and leveraging investment in ‘testing things,’ which, in turn, has a dramatic effect on improving DevOps ROI.

  • CircleCI Previews Support for Arm Platforms

    CircleCI Previews Support for Arm Platforms

    CircleCI today previewed the ability to deploy applications on platforms based on Arm processors in a forthcoming release of its namesake continuous integration/continuous delivery (CI/CD) platform.

    Tom Trahan, vice president of business development for CircleCI, said that Arm processors are rapidly being embraced by DevOps teams seeking to take advantage of the price/performance advantages they currently have over conventional x86 processors. Amazon Web Services (AWS), for example, makes available an AWS Graviton2 service based on 64-bit Arm Neoverse processors that it claims provides a 40% advantage in overall price/performance.

    The Arm community, meanwhile, has adopted many of the libraries employed on x86 platforms, Trahan noted, which is making it simpler to automate the deployment of applications on Arm-based platforms using a CI/CD platform.

    It’s not clear how quickly developers are building applications for Arm processors. Historically, Arm processors can be found in a wide range of embedded systems typically deployed at the network edge. However, cloud services based on Arm processors are also becoming more widely available, and it’s only a matter of time before more Arm-based platforms are deployed in on-premises IT environments.

    Arm itself is also in the process of being acquired by Nvidia, which envisions running machine learning algorithms, and other classed of advanced workloads, on both Arm processors and graphics processing units (GPUs). Many of the early efforts to build processors optimized for running AI workloads at the network edge are based on Arm processors.

    The addition of Arm platforms to any IT environment will naturally create some management challenges for DevOps teams. In some cases, developers may even decide to build applications using, for example, the latest generation of machines from Apple, that are based on Arm processors, to streamline the application development and deployment process. In other cases, however, applications that are intended to be deployed on Arm processors might still be built on x86 systems.

    Regardless of approach, the arrival of more Arm-based platforms in the enterprise doesn’t mean other classes of processors are going to fade away. Rather, from a processor perspective, IT environments are about to become a lot more diverse as more workloads are deployed on a wider range of processors. It may be quite a while before Arm-based platforms usurp x86-based systems that still dominate the IT landscape. However, during any turbulent economic time, the number of organizations inclined to reduce the total cost of IT by embracing new platforms always increases.

    Fortunately, as more IT infrastructure is managed as code, the easier it becomes to switch platforms. There may even come a day when the decisions about which platform to employ and when is completely automated by machine learning algorithms trained to maximize IT infrastructure efficiency to the fullest extent possible.

    In the meantime, DevOps teams should expect, to one degree or another, to revisit their workflows processes in the months ahead. Not only are more workloads being pushed out to edge computing platforms where Arm processors are commonly found, those Arm processors will soon find their way into the rest of the extended enterprise.

  • Continuous Integration Overview

    Continuous Integration Overview

    To improve the efficiency of your software development workflow, you should use continuous integration. We’ll explain what continuous integration is, why it’s important and how it can help you.

    Continuous Integration in DevOps

    Continuous integration is the automation of building and testing code each time a change is made in the codebase, and then committing the code back to your central code repository. For each new code commit that is made, an automated build and test process — which is also called a “pipeline”— is triggered. This trigger then generates a report on any defects found during code compilation and/or testing.

    The Benefits of Continuous Integration

    The benefits of using continuous integration include the following:

    • Easier to fix software vulnerabilities, errors and bugs.
    • Minimizing the amount of potential risk to your software development project.
    • Increasing the quality of your software.
    • Increasing the productivity of your team members.

    While the above list is not comprehensive, it does represent the most common benefits for software development teams.

    The Difference Between Continuous Integration and Continuous Delivery

    While both continuous integration and continuous delivery are software development processes, there is quite a bit of differences between them. To put it simply, continuous integration is used during the build and test phase, while continuous delivery is used once changes have been committed. Essentially, the aim of continuous delivery is to always have validated and verified code in your code repository, also known as a version control system.

    Why Continuous Integration Is Important

    Continuous integration is important because it enables you and your team to avoid common development pitfalls. In addition, a continuous integration pipeline ensures that every change is integrated, tested and verified.

    How Static Code Analysis Complements Continuous Integration

    One of the most effective practices you can adopt to improve your continuous integration development process is to use a static code analysis tool. The tool provides you with fast, reliable feedback on submitted code changes — enabling you to identify vulnerabilities and errors earlier in your development process. In addition, you are able to use quality gates with  static analysis tool to prevent those issues from entering your main code stream.

    To read more, please visit: https://www.perforce.com/blog/kw/what-is-continuous-integration

  • Using Incident Response for Continuous Testing

    Using Incident Response for Continuous Testing

    Incident response tools offer the ability for organizations to not only implement continuous testing but to also shorten the feedback loop from continuous testing back into planning and development

    At this point, you should be able to say the word “continuous” to any technical team, drop the mic and leave. Yes, the idea that we want to do more delivery, more testing and more interactions isn’t always novel. The reason we use phrases such as continuous testing and continuous improvement is to have the conversation about the unique set of tools and practices required to run these processes in production, and not just as part of continuous integration (CI). Part of supporting continuous testing is having a highly effective incident response process—arguably, it’s required.

    Continuous testing is used in the context of functional testing, performance testing and vulnerability scanning. All three come from different disciplines, but all suffer from the same challenge that they’re processes designed to be run during pre-release, not in production.

    Functional testing is the process of running automated tests of the application as if the test were a user, from the outside in. Performance testing is the process of putting artificial loads on the application to simulate high transaction volume to see how the application responds. Vulnerability scanning is the process of scanning application code to make sure components don’t have known vulnerabilities.

    All of these application quality processes are generally run in continuous integration (CI) environments and pre-production. If an organization were to move them to production, they get several benefits:

    • Full parity with production infrastructure. When you run these tests in CI, the environment it’s run on isn’t a one-for-one comparison with the infrastructure used for production. By running tests in production, you get a true picture of what is going to happen.
    • Better relation to production data. By running these tests in production you are running aside real user activity, which gives a more accurate picture from the outcome of the tests.
    • Reduced reliance on CI. Continuous testing allows you to streamline and even reduce pre-release processes, allowing more code to get to production faster. It also reduces the reliance on synthetics, mocks and service virtualization.
    • Specifically for vulnerability scanning, the ability to build DevSecOps workflows into production for vulnerabilities that show up at a later date.

    The mechanisms for running the tests in production are the same as CI, just with a different target environment. The problem is, when something breaks in production, it’s much more serious. So, to support continuous testing, you need to know what to do if there’s a test case failure or a failure in the application as a result of running the test.

    This is where incident response comes in. Today, most incident response tools and processes are used by SREs and developers to be alerted when something breaks. But, the same tools and approaches can be used for running tests as well. The only difference is, not only will the application be a data source of an alert, but so are the testing tools. This way, quality engineering and DevSecOps teams can confidently run their test suites and get alerted if something goes wrong.

    In particular for vulnerability scanning, continuous testing allows SecOps folks to get alerted when a new vulnerability is detected, which can result in patching holes long before the application is exploited.

    If an organization embraces continuous testing, they need to know:

    1. If a test fails. The effort to run tests, both in terms of human and compute time can be high. To wait for a result can also impact downstream processes. Therefore, it’s important for application quality and security to know that the tests themselves are running successfully. And, if they break, the QE team or SecOps team needs to be alerted so they can re-run the tests.
    2. If the tests break something in production. Not only do the teams who own the testing process and tools need to be alerted but if you’re on-call, you need to know as part of the context of an alert, that the incident was directly or indirectly impacted by tests being run. This can save a lot of time by killing tests versus chasing down issues with the application that may not be there.

    Incident response tools offer the ability for organizations to not only implement continuous testing but to also shorten the feedback loop from continuous testing back into planning and development. This can be done simply by reducing the amount of time it takes to get details from an incident back to the appropriate teams, but also for non-critical incidents that indicate potential issues in the application. Issues can be made more visible to everyone and communicated to product owners faster and more effectively. This is the other continuous, continuous improvement.

  • DevSecOps vs. Agile Development: Putting Security at the Heart of Program Development

    DevSecOps vs. Agile Development: Putting Security at the Heart of Program Development

    Despite most developers and managers being well aware of the concept of DevSecOps, it is still often confused with a number of related processes and concepts. This is particularly true for the Department of Defense (DoD) contractors because they have long been encouraged to use a related process known as agile development. 

    Since agile development has been around for more than a decade, there is a tendency for organizations to regard DevSecOps as an extension, or even a synonym, for it. In reality, though, the two approaches are distinct. The objectives of both approaches are similar: balancing speed and agility, detecting risk early and both focus on cloud-native security and performance. 

    However, while DevSecOps does build on some agile development principles, such as the continuous integration and delivery of software systems in cycles, its key emphasis from the beginning of the process is to integrate security features, while Agile only focuses on delivering software.

    In this article, we’ll look at the key differences between agile development and genuine DevSecOps processes, and how each complements the other.


    DevSecOps vs. Agile Development


    The difference between DevSecOps and agile development methodologies can be understood in reference to one aspect of software development: security. When, where and who implements security in software development varies between the two approaches.

    Agile development methodologies focus on iterative development cycles, in which feedback is continuously reintegrated into ongoing software development. However, even in mature agile development processes, security is still often added to software as an afterthought. This should not be read as blaming software developers for often underestimating the potential harm from malware or overlooking the importance of cybersecurity. 

    Rather, in many firms, it is simply not the responsibility of developers to think about the security implications of their code, because software will be passed to the security team before release.

    DevSecOps takes security and puts it on the same level as continuous integration and delivery. DevSecOps methodologies emphasize security at the very earliest stages of development and make security an important part of overall software quality.

    In essence, these approaches shift the program manager’s perspective away from making sure that software is in compliance or meets a specification or audit, to ensuring that the code is written correctly and securely and that it’s deployed in a repeatable manner.


    The Changing Culture of the DoD


    The adoption of DevSecOps methodologies is critical for DoD contractors because these methodologies reflect DoD’s own modernization strategy. Following high-profile vulnerabilities being discovered in all types of systems, DoD seems to have released that cybersecurity weaknesses are not just a potential threat to critical defense data, but also impose a significant operational bottleneck on the continuous delivery of functionality.

    At the moment, even those firms who possess a mature agile development framework can find that the multiple security checks and compliance processes that must be performed on software, prior to shipping, can detrimentally impact on their ability to deliver iterative software improvements. This is the issue that the transition to DevSecOps seeks to overcome, by attempting to shift organizations’ approach to cybersecurity away from compliance, and toward genuine security consciousness.

    At the same time, analysts are aware that shifting responsibility for cybersecurity onto developers will be uncomfortable, and potentially dangerous, for many DoD contractors. Developers working on the base code for military software do not have – and are not expected to have – an exhaustive appreciation of all of the contexts in which this will be deployed, and exactly which systems their software will be required to interface with.


    Automation and New Models


    In response to these concerns, DoD contractors are reappraising the DevSecOps model and thinking seriously about how it can be deployed in contexts where continuous service delivery is key. There are three key ways in which this is happening.

    The first is the rise of automation. The types of large-scale, multicloud infrastructures that most contemporary DoD projects rely on can often necessitate repetitive, ongoing maintenance and security assessment across both development and security teams. DevSecOps replaces these human checks with automated systems: Instead of requiring a person to go through checklists of hundreds of controls, this is done automatically as part of the software development and supply process pipeline. 

    The second key element in the transition to DevSecOps is endpoint security. The types of monolithic development processes that DoD contractors traditionally worked with are not suited to the contemporary deployment environment of many DoD projects. In these traditional methods, systems were built as discrete holes, with no expectation that data would be exposed as it moved between components. 

    This is now an obsolete approach: In DevSecOps processes, virtual private networks are used to provide security and encrypt data as it moves within a network, and the principle of least privilege reduces staff access to small portions of It environments. 

    Thirdly, a new generation of younger military and civilian personnel in the DoD, many of them trained in the commercial sector rather than entering the military directly from college, are bringing corporate approaches to the development of military software. This is seen in the exponential increase in the utilization of cloud services in DoD applications, and more dynamic and distributed managerial frameworks that distribute security responsibility across entire organizations, rather than having this as the sole remit of a dedicated security team.


    Get Support


    Moving to a truly DevSecOps methodology is likely to be a challenge for many contractors. However, just as in the last decade many firms have had to redesign their development lifecycles in order to be agile, now they will need to achieve secure development lifecycles in order to stay competitive.

    If you are looking to make this shift, you should also recognize that you are not alone. DoD is working actively with its partners in order to facilitate the roll-out of DevSecOps processes and to make commercial tools and techniques available and useful for military contractors because the department recognizes the value of this methodology for the software they commission. 

    This is seen most clearly in the recent updates to Microsoft Azure Government, though you should also be aware that many of the resources recently released by the Defense Logistics Agency are also focused on the transition to DevSecOps.

    In short, whilst the transition to DevSecOps may be challenging, it will be no more so than the earlier shift to agile development. To make this shift, however, firms should draw on the resources available to them, recognize the value of integrating security into their development workflows and build on existing agile frameworks.

  • CircleCI Extends Core CI/CD Platform

    CircleCI Extends Core CI/CD Platform

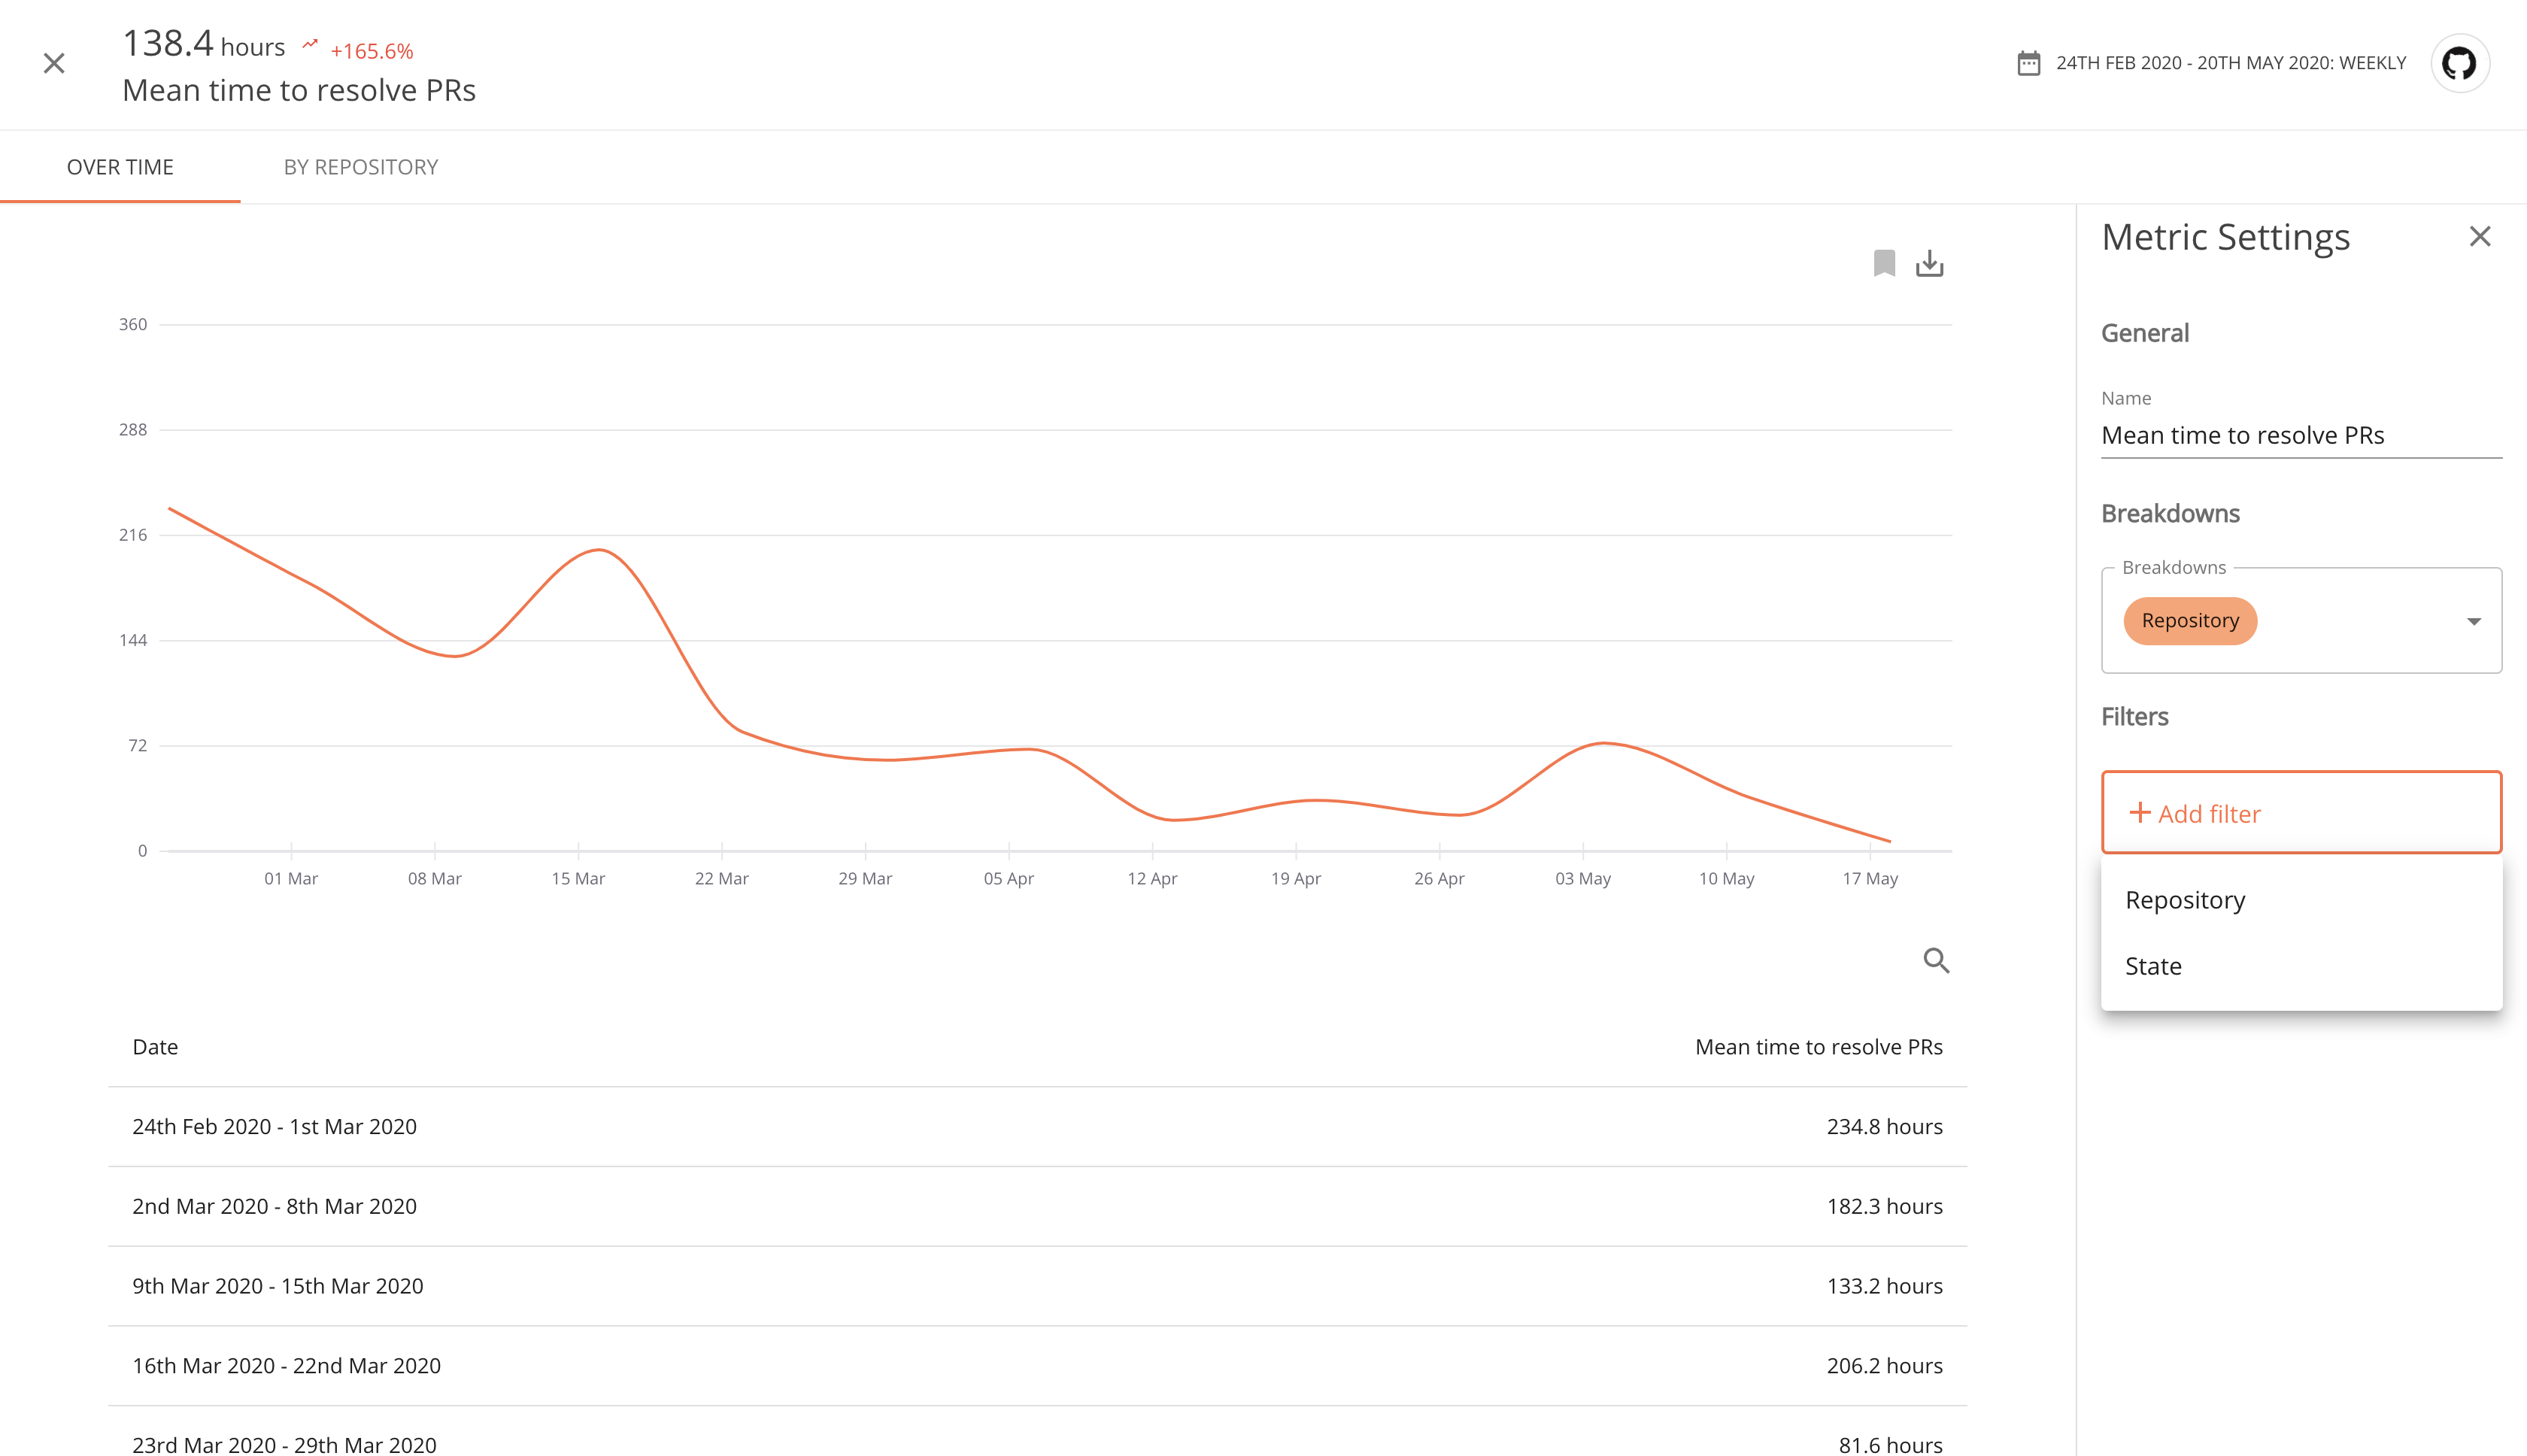
    CircleCI today in partnership with Plandek launched an analytics plugin dubbed Buildtrakr for its namesake continuous integration and continuous delivery (CI/CD) platform. Buildtrakr integrates with CircleCI and Git to synthesize commit and build performance data, with critical metrics being surfaced via a dashboard.

    In addition, CircleCI has revamped its user interface and reconfigured a new fleet of Docker images, also known as CircleCI convenience images, to optimize them for a continuous integration environment.

    CircleCI CEO Jim Rose said Docker images made available by CircleCI are faster, easier to download and provide a more efficient way to build custom images. CircleCI also released a new category of convenience images available for languages such as Python, Ruby, Rust, Go and several others, that come with improved documentation, more stability and more efficient infrastructure. Those convenience images are individual open source projects and can be used in IT environments other than the CI/CD platform from CircleCI.

    Finally, the company also announced that its insights endpoints now offer start and end date parameters for workflows and jobs. These parameters restrict the range of executions returned based on their start times in addition to providing a new filter to use for testing analysis.

    Rose said the new user interface is significant because it makes it possible to view the status of entire pipelines more easily while making it easier for more advanced DevOps teams to leverage workflows.

    The redesigned interface also adds a filterable view with nested workflow and job information, making it easier to scan the status of recent builds. Pages were also overhauled to deliver more digestible job details, full-screen step outputs for easier debugging and a cleaner configuration-as-code view. There’s also been a 65% reduction in page load times, noted Rose.

    In general, Rose said activity on the CircleCI platforms in cloud environments is on the rise in the wake of the COVID-19 pandemic. Organizations that are working remotely due to stay-at-home directives and can’t access a local data center have come to realize that having a build box located under someone’s desk is no longer a viable option.

    Of course, it remains to be seen how much of that initial burst of activity will result in new applications being deployed. However, with more organizations starting to build and deploy digital business applications to engage customers, it may be only a question of when IT operations teams will be able to catch up to a building backlog of applications. In fact, many of those applications are now likely to be deployed on the same cloud where they were constructed.

    Whatever the path forward, there most certainly will be a greater reliance on metrics. Naturally, the hope is that analytics will be used to coach DevOps teams to become more efficient versus simply riding roughshod over developers. After all, the goal isn’t to write more code faster but to deliver better code at the right time.

  • DevOps Practices: How to Make Valuable Changes to Your Teams

    DevOps Practices: How to Make Valuable Changes to Your Teams

    DevOps has become a buzzword within the software development industry, promising rapid turnaround times for requested changes. As for developers, DevOps promises to increase productivity while reducing the risk of production failures. The book “The Unicorn Project” by Gene Kim describes this process for developers as The Five Ideals.

    In this article, we’ll focus on only two of them:

    • The Third Ideal — Improvement of daily work
    • The Fourth Ideal — Psychological safety

    Psychological safety and improvement of daily work make it easier for developers to create changes for their teams, and the work to implement these ideals is not difficult. From automated testing to production monitoring, there are many great things that even junior developers can help bring to their teams that will help their entire team make safer changes to their code.

    So, what are these easy changes that can be made? Below is a list of tasks that can be done to improve the projects you are assigned to, with most taking less than four hours to complete.

    1. Set up a continuous integration server for your project, such as Jenkins or Team City. This will allow for automated jobs to be run for your code.
    2. Create jobs to run testing for pull requests as well as testing jobs to run overnight. This will show the current state of your project’s tests on a nightly basis and will allow for the number of failing tests to be monitored over time.
    3. Add a code coverage tool to your automated tests. This will show what is being tested in your code and what is not being tested, creating opportunities to help shore up your teams testing suite as well as confirm that your changes will be covered by existing tests.
    4. Create an automated deployment job on your CI server. This will convert the manual deployment process in a one click job, allowing the code to be deployed on command.
    5. Modify your project to extract metrics of the project, allowing your code to easily be monitored for faults in production.

    The tasks highlighted above will quickly add value to your team while helping protect you for making dangerous changes to your team’s code base. I recently changed teams and have moved to a new web project. The project runs fine on my local, but it is hard to track what is affected by my changes. The team already has a CI server to build their code, but there is no point in setting up any testing jobs as the project has fewer tests than I have fingers.

    Instead, I created a monitoring tool that captures all requests to the website and records their results. With the tooling in place, my team can now see how long it takes for each part of the website to load, as well as how many errors are being produced. Now, when I make any changes, I can check these metrics to see if my change is causing issues to the site, increasing my confidence in my code.

    If you are interested in learning more about DevOps and how to take advantage of it, here are a few good reading resources to look into:

    • “The Unicorn Project,” by Gene Kim.
    • “The Phoenix Project,” by Gene Kim, Kevin Behr and George Spafford.
    • “The DevOps Handbook: How to Create World-Class Agility, Reliability, and Security in Technology Organizations,” by Gene Kim, Patrick Debois, Jez Humble and John Willis.
  • Why DevOps are Keen on Open Source Logging

    Why DevOps are Keen on Open Source Logging

    With the advent of DevOps, we are now moving toward more collaborative workflow models, where the integration of development and operations teams make it easier to quickly move development projects into production, and with fewer roadblocks. However, within DevOps, many of our activities are not as clear-cut as they were in previous siloed methods. While previous methods made it easier to keep track of activities and processes, these systems were not particularly efficient.

    In the DevOps model, moving software from development to production is much faster. But, we need to be able to identify actions that occur in our increasingly complicated applications. We now have many chefs working at the same time, and visibility suffers.

    Logging helps us better understand applications throughout each stage in the process so that we can identify problems or larger issues that might arise already during the development process. This is particularly true within CI/CD environments where items are regularly pushed into production. We need methods for identifying not only if there are critical errors, but also the ability to attribute the errors to specific versions throughout the cycle.

    To deal with the increasing complexity and decreasing visibility, DevOps identifies complex issues using logs to keep track of services, APIs, containers, infrastructure issues, network activity and also security related logs.

    Log files provide a tremendous amount of useful information about what goes on beyond the CI/CD pipeline and also identify issues that directly impact customers. Good log analysis tools make it possible for DevOps teams to get much closer to the end user. And open source is the preferred starting point for many organizations.

    Why Open Source?

    Lack of Lock-in 

    Many DevOps teams make use of a wide-range of tools and find that they can work much better without vendor lock-in, which can be caused when using proprietary stacks exclusively. This makes it far easier to make any needed changes as the need arises, and not be reliant on individual vendors. This also helps avoid many risks, such as vendors disappearing, ending support, changing pricing models, etc.

    Widely Used

    Within CI/CD, there are many commonly used open source tools, which makes it easier for new members to be on-boarded. There is already a widely accepted suite of tools that almost all DevOps teams use. It’s hard to imagine working without Jenkins, Docker, Kubernetes, Git, etc.

    Regular Skill Development

    Open source work ensures that DevOps teams are actively learning and directly interacting with software and systems. It becomes a way of ensuring that skills and abilities of teams are continually staying updated. This can translate into better troubleshooting and problem solving skills. When working with closed systems, there’s considerably less opportunity for knowledge advancement, as closed systems tend to encourage rote work with existing software rather than skill development.

    Quality

    Fears about subpar open source software are largely unfounded, particularly if the projects are widely used and have a large community. There are far more developers working on a project in the open source community than in proprietary systems. Closed systems can lag behind, and there may actually be bad code but that is hidden due to its closed-source nature. The ability to make modifications to create functionality beyond that which already exists in closed source systems, makes open source extremely appealing for many DevOps personnel.

    Some Drawbacks

    It’s important to note there are a few drawbacks when attempting to work entirely within open source environments. Many resources used are not open by nature–for example leading clouds are decidedly not open source in nature. Individual users (outside these companies) have much less control over how they actually operate. However, if we look at the toolkits that we described above, we can think of open source tools as needed resources for working in and around these environments.

    Another drawback to consider is the actual costs of managing open source software versus a fully-managed service such as Coralogix, for example. Many times, teams will start with the self-managed approach and move to a managed service when faced with scaling and complexity issues as the organization grows. 

    Types of Features to Look for in Open Source Logging Models

    When setting up to work with open source logging tools, it’s important to understand there is a range of different types of models available, which can work better or worse depending upon needs and capacities.

    • OpenAPI: provides a useful interface into many different systems. It is language agnostic and can generate clear documentation of methods, parameters and models. In most cases it will work within RESTful interfaces, but will also work with other protocols such as SOAP.
    • Open Standards: Even if a tool is not open source, typically these should follow a set of standards to make sure that different pieces can talk to each other. OpenAPI is one example, but not the only one.
    • Federated Model: This is a broader type of open source model which is like many default open tools, but allows a much wider set of input and may allow individual users to provide input and maintain some control over local development areas. This means that aggregation, processing and control remain local. However there’s still a central organization which will be able to collect summarized or complete code. The advantage of a federated model is it increases flexibility for individual teams, while still contributing largely to the project as a whole. 

    Elasticsearch, Logstash, Kibana (ELK)

    One of the most popular open source logging stacks is known as ELK. It is particularly powerful and effective for the purposes of those wishing to create a clear aggregation and understanding of their log files, with the ability to find both problems and solutions quickly. 

    ELK is a combination of three tools.

    • Elasticsearch: a popular NoSQL Lucene search engine.
    • Logstash: a pipeline system which will take data from logs, ingest it and transform it into a data store (such as Elasticsearch), so that it can be searched and analyzed.
    • Kibana: a tool which makes it possible to create clear visualizations for Elasticsearch to appear in a human-readable format. 

    What ELK provides is a single place for all of your data, where it can be stored, searched and analyzed in a method. It is useful for DevOps teams wishing to make use of the vast amounts of data stored in log files. 

    Upfront expenses for open source tools like ELK are minimal; the software itself is free. However, this does come with a caveat. Professional management of ELK tools is required, otherwise costs can grow quickly out of control. 

    Generally, for low volumes of data, one can manage ELK for as little as a few hundred dollars a month on a platform such as AWS. However, without careful management, the cost can grow exponentially for large amounts of data.   

    Work required for ELK involves:

    • Setup, which may take some time but that’s typically not a problem for many ops teams—and is a project many will enjoy.
    • Maintenance of elastic search clusters can be quite a bit of work—several hours per week simply solving issues or resolving downtime. This can vary based on the size and growth of clusters. The more activity you have occurring, the more time you will need to spend maintaining your logs.

    FluentD

    FluentD is an open source alternative to Logstash which can collect, parse and transform data for further analysis. It has features which may be particularly helpful if you are running your logs in a Kubernetes environment.

    One of the drawbacks of Logstash is that it is written in JRuby, which means it requires a Java runtime for each implementation. If you are running many different microservices in Kubernetes, this can result in a large amount of your memory being taken up.

    Because FluentD is developed in CRuby, it doesn’t require as much memory to use with each new pod creation. This can help solve some memory allocation issues which could cause your logs to slow down your applications.

    FluentD also has a wide range of plugins, which can cover pretty much any use case that you come up with. Another advantage is that its tag-based routing makes it slightly easier for developers to work with than Logstash. 

    What to Log?

    With continuous integration, there are many things that merit monitoring. These can include everything from checking the frequency of merge conflicts in Git, or whether pulls are preceded by pushes prior to any other pulls.

    Are you receiving a high number of compiler warnings? You can identify code that has a strong likelihood of breaking builds, change your unit testing procedures and implement better automated checking in Jenkins.

    Much of this data is worth visualizing in Kibana for analysis. Deciding what specific activities to log can be a bit involved. Areas that are a good idea to log include:

    • Diagnostics: For example, understanding the causes of repeated errors.
    • Auditing: Track how well errors in code have been fixed, and whether they succeed or fail a second time.
    • Profiling: For example, get an idea of how long it takes for certain parts of code to execute, for the purpose of identifying whether this has any impact on customer experience, and identify areas for improvement.
    • Statistics: Code performance, such as execution time or memory consumption.

    Conclusion

    Gaining complete visibility or your infrastructure will go a long way to make sure that your operation runs smoothly and that your CI/CD pipelines function at optimum efficiency. Open source tools remain an attractive option for DevOps because of its advantages and knowing how to get around drawbacks.

    Finding the right tools is, of course, only the first step, but if you’ve picked good architectures and have implemented them properly, you are already moving in the right direction to a more streamlined operation.

  • CD Foundation Serves Up Tekton Pipelines Beta

    CD Foundation Serves Up Tekton Pipelines Beta

    The team overseeing the development of the open source Tekton Pipelines under the auspices of the Continuous Delivery (CD) Foundation announced today the project is now in beta.

    Christie Wilson, Tekton Project Lead and a software engineer at Google, said Tekton Pipelines are not necessarily a tool most DevOps teams will interact with directly. Rather they provide a foundation on which DevOps platforms can be built that will make it easier for DevOps teams to construct workflows spanning multiple continuous integration/continuous delivery (CI/CD) platforms.

    As such, Tekton Pipelines should play a critical role in not just fostering interoperability but also alleviating concerns about become locked into a specific CI/CD platform.

    The beta release of Tekton Pipelines is significant because it signals that the project is now stable enough to be incorporated in DevOps platforms and from here on will follow the same deprecation policies as Kubernetes in terms of supporting previous releases. However, Wilson noted that Tekton Triggers, Tekton Dashboard, Tekton Pipelines CLI and other components are still alpha and as such may evolve from release to release in a way that is not necessarily backward-compatible just yet.

    In the meantime, the Tekton Pipeline team is encouraging all Tekton projects and users to migrate their integrations to the latest version of Custom Resource Definition (CRD), which is the application programming interface (API) supplied. The Tekton Pipeline team is also making available a migration guide.

    The Tekton Pipelines project is one of several initiatives being advanced under the guidance of the CD Foundation, which is an arm of The Linux Foundation. Other projects include Jenkins and Jenkins X, a pair of open source CI/CD projects developed originally by CloudBees and Spinnaker, a CD platform originally created by Netflix. Tekton Pipelines are a framework that runs natively on Kubernetes that traces its lineage back to Google.

    Premier members for the CD Foundation include CloudBees, Google, Circle CI, JFrog, IBM, CapitalOne, Salesforce and Netflix. Other members of the CD Foundation include GitLab, Red Hat, Harness and Rancher Labs.

    Wilson said Jenkins X already supports Tekton Pipelines, while work involving Spinnaker is ongoing. It’s not expected that Jenkins, currently the most widely used CI/CD platform, will be able to employ Tekton Pipelines, said Wilson.

    It’s not clear when Tekton Pipelines might be pervasively employed across multiple CI/CD platforms. In theory, as more applications are built on top of Kubernetes, the use of CI/CD platforms that run natively on Kubernetes should increase. However, most organizations that have already adopted a CI/CD platform such as Jenkins are continuing to use the same platform to build and deploy both monolithic and microservices-based applications. At some point, however, it’s expected those organizations will eventually migrate to a CI/CD platform that runs natively on Kubernetes. In many cases, different teams within the same organization may opt to standardize on different CI/CD platforms while still be able to share workflows, said Wilson.

    Naturally, providers of DevOps platforms are already jockeying for position now that the race to support Tekton Pipelines as specified by the CD Foundation has formally started.

    — Mike Vizard

  • GitLab Shifts 18 Features Into Core Open Source Platform

    GitLab Shifts 18 Features Into Core Open Source Platform

    GitLab this week announced it has moved 18 features that previously organizations had to pay for into the core open source version of its namesake continuous integration/continuous delivery (CI/CD) platform.

    Scott Williamson, executive vice president of product management for GitLab, said as a general rule the company makes available DevOps tools for teams across the four tiers of services that organizations can employ. Features now being migrated to the Core offering include:

    Plan: Synchronize collaboration with “related issues,” “export issues,” “issues board focus mode” and “Service Desk”

    Create: Build better code and branch with the “web terminal for WebIDE,” “file syncing to web terminal” and “design management”

    Verify: Improve code quality with reports on merge requests

    Package: Build and share more efficiently with a set of package managers in one place

    Release: Continuous delivery simplified with “canary deployments,” “incremental rollout,” “feature flags” and “deploy boards”

    Configure: Support for multiple Kubernetes clusters to ease deployment of different environments

    Defend: Bolster application security with network policies for container network security

    As the global economy falters in the wake of the COVID-19 pandemic, it’s likely reliance on open source software will increase. Most organizations would rather throw IT labor at the ongoing management of an IT environment to manage open source software versus having to lay off IT employees that would be extremely difficult to find once the economy recovers. It remains to be seen to what degree that strategy will play out in DevOps environments, but Williamson said historically most of GitLab’s customers are organizations that first adopt the open source version of its platform.

    Less clear is the degree to which the downturn might also induce many of the organizations to employ a DevOps platform delivered as a set of software-as-a-service (SaaS) applications. GitLab has been for the past several years for an integrated approach to DevOps based on a single code base that is ultimately easier to deploy and manage. Many IT organizations may decide that rather than manage DevOps infrastructure, they now prefer to allocate what limited resources they have on hand to writing code.

    The number of application development projects being launched could also decline while others are suspended. At the same time, however, there are some vertical industry segments, such as digital entertainment and education services, that might see a spike in demand for additional services now that many people are staying home to help limit the scope of the COVID-19 pandemic.

    Of course, many DevOps teams are among the legions of workers that now need to remotely access platforms. Williamson said supporting remote DevOps teams has long been a strength of the GitLab platform. GitLab also makes available a playbook that provides DevOps teams with guidance on how best to work remotely.

    Clearly, it will be a few months before the full impact of the COVID-19 pandemic is fully appreciated. Regardless, many IT organizations are clearly preparing for the worst of times while continuing to hope for the best outcome possible.

    — Mike Vizard