Tag: continuous integration

  • IBM Adds Automated Testing Tool for Mainframe to DevOps Portfolio

    IBM Adds Automated Testing Tool for Mainframe to DevOps Portfolio

    IBM has added an automated testing tool to the portfolio of DevOps tools it has developed for mainframes.

    Sanjay Chandru, director of Z DevOps for IBM, said IBM Z Open Unit Test adds a continuous testing capability to the continuous integration/continuous development (CI/CD) platform based on an instance of an open source Git repository developed by Rocket Software that IBM launched last year. The automated unit testing tool automatically records and plays back test data for both batch-oriented applications written in COBOL or PL/I and CICS transaction processing applications.

    Chandru said IBM Z Open Unit Test is unique in that it eliminates the need to employ traditional debugging tools. Developers can generate test cases for COBOL CICS programs, as well as “stub out” CICS to achieving environment independence from CICS runtime during test case execution. A stub is an object that holds predetermined data, which is provided in response to calls made during tests. That approach eliminates the need to have objects that answer with real data. That means Z Open Unit Test operates without adding the overhead of a debugging tool, said Chandru.

    Any test case and the resulting program created then can be stored in any source code management (SCM) system.

    IBM is making a concerted effort to make mainframe a natural deployment target for any DevOps team, said Chandru. It increasingly has become apparent that millennials in particular aren’t biased toward one platform or another, as long as each platform is equally accessible, he noted, adding that as organizations embrace best DevOps practices to modernize their application portfolio, IBM wants to make sure the mainframe remains relevant.

    IBM launched the z14 mainframe in the fourth quarter of 2017. According to the company, 92 of the world’s 100 biggest banks use its mainframes, which handle most global credit card transactions alongside billions of ATM transactions and annual passenger flight bookings. While use of mainframes overall isn’t growing, the platform isn’t going away anytime soon.

    IBM has also enhanced the cryptographic capabilities of the z14 to make it one of the most secure platforms available and continues to invest in an instance of Linux for the mainframe. That latter capability makes the mainframe a more natural target for applications being developed and deployed using DevOps processes, said Chandru.

    Of course, the biggest challenge when it comes to DevOps and mainframes is not necessarily the technology. Most mainframe applications have been developed using waterfall processes for decades. Getting those teams to embrace DevOps processes represents a significant cultural hurdle for any IT organization.

    At the same time, however, DevOps teams who ignore mainframes are not taking advantage of an existing platform investment that has performance and security capabilities that are still unmatched after more than five decades. The real challenge is finding a way for old mainframe dogs to learn some new DevOps tricks while exposing proverbial whippersnappers to the capabilities of the most powerful mainstream platform ever built.

    — Mike Vizard

  • Semaphore 2.0 Brings Continuous Delivery to Teams of All Sizes

    Semaphore 2.0 Brings Continuous Delivery to Teams of All Sizes

    Since its inception in 2012, Semaphore has been focused on making code testing and deployment a quick and easy process. The cloud-based CI/CD platform from Rendered Text enables users to get up and running within a matter of minutes—which the company claims is at least twice as fast as other offerings.

    The company is releasing Semaphore 2.0 Nov. 6, which will expand the platform to enable continuous delivery, for a product that allows teams of any size to automate any continuous integration or continuous delivery workflow with custom pipelines so users can model their CI/CD however they prefer. The latest version also better supports CI/CD for containers, giving users the ability to use Docker or Kubernetes tools in building within container environments. Other features of Semaphore 2.0 include support for YAML files and command line interfaces, so teams can manage a large number projects more easily.

    Marko Anastasov, founding partner at Rendered Text, spoke with me about the latest version of Semaphore and his thoughts on the continuous integration and continuous delivery space at large. Read on for his insights:

    Can we start with some background about Semaphore? What was the catalyst for creating it?

    Our company was an early adopter of agile software development practices, including test-driven development and continuous deployment. We relied on cloud-based products like GitHub, which were simple to use and made software development easier.

    However, when it came to implementing continuous integration, we were out of luck. I remember spending days setting up Jenkins for just one of our projects. We saw how expensive and time-consuming it would be to make it fast and scalable. It felt as if by continuously verifying our code, we were doing something wrong. Developers need to set up a fast and functional CI process in minutes, and not worry about how it works.

    What’s new in Version 2.0 that’s worth mentioning?

    Semaphore 2.0 is made to enable continuous delivery in organizations of any size. Previously, like other hosted CI/CD services, Semaphore focused on solving the integration process: building code and running tests. Delivery features were limited and tailored for classic web development.

    This time we asked ourselves, What would a continuous delivery product focused on speed and simplicity look like in the age of cloud-native computing? I’d highlight three things that stood out.

    First, for DevOps transformation to succeed, we need to automate, visualize and accelerate all software development processes in our organizations. So at the heart of Semaphore 2.0 are infinitely customizable code pipelines, configured as code, run as a service.

    Second, infrastructure should be ephemeral and scale in real time. When CI/CD capacity is limited, developers are blocked in busy times of the day. Semaphore adopts the “pay only what you use” cloud model, in which CI/CD resources scale automatically to support the team’s actual needs.

    And third, we can’t manage what we don’t measure. It doesn’t make sense to prescribe the same metrics for every project and organization. So Semaphore lets users choose their own metrics and define their own dashboards.

    What feature or features do you believe will have the most impact with users?

    In building Semaphore 2.0 we were very careful not to add any unnecessary features. All parts are designed to support each other and provide a harmonious user experience.

    For example, Kubernetes wasn’t the first solution to run software in the cloud, but it made vendor-neutral cloud computing as easy as describing what you need to run. Similarly, developers can now describe any CI/CD process they need, and Semaphore will run it immediately at any scale.

    In day-to-day use, I expect users to like how much control they have via command line and autoscaling resources. It’s the overall boost in productivity that will make the most impact.

    How important is Semaphore’s increased support for container environments?

    Containers are the biggest change in the development stack in recent history. In the transition to container-based software delivery, many teams needed to maintain their own CI/CD infrastructure, since none of the existing solutions were flexible or easy enough to use. This takes valuable time away from delivering value to customers. Semaphore 2.0 is built to support the next-generation of cloud architectures based on containers.

    What are some of your thoughts on the current state of the CI/CD market, and where do you see it heading?

    For the continuous integration part of the equation, there are many options to choose from. There’s a wide spectrum from managed to DIY solutions, and from specialized vendors to those who provide basic tools for every aspect of software development. I think the shift that’s going to happen is from basic automation to optimization. For example, Semaphore provides bare-metal performance at convenience of cloud. When a customer tells us that they’ve combined that with our test optimization features to reduce build time from hours to minutes, that makes us so happy because we know what tremendous difference that makes in their workplace.

    On the continuous delivery front, I think there’s less maturity and that the market is still developing. So far, developers have needed to build their own solutions based on complex open source tools and self-managed infrastructure. Cloud vendors have entered the space, not with complete products but low-level tools that leave a lot of complexity for the end user to manage. The next phase will be about making the entire CI/CD process easier and more accessible. At Semaphore, we’re committed to making that happen.

    — Charlene O’Hanlon

  • DevOps Chat: CI/CD with the Semaphore Platform

    DevOps Chat: CI/CD with the Semaphore Platform

    As the old saying goes, “speed kills.” When it comes to development, a lack of speed can kill, too. Marko Anastasov and the Semaphore team have strived to make Semaphore the fastest continuous integration tool in the market. With version 2.0 of Semaphore, they believe it truly is.

    With his background in development, Marko brings a unique perspective in leading the Semaphore team. He knows what he and his colleagues like, and that is the road map for Semaphore. Have a listen to Marko tell us in his own words.

    As usual, the streaming audio is immediately below, followed by the transcript of our conversation.

    Transcript

    Alan Shimel: Hey, everyone, it’s Alan Shimel, devopsy.kinsta.cloud, and you’re listening to another DevOps Chat. In today’s DevOps Chat, we’re gonna talk about a company called Semaphore. Their website is semaphoreci.com. And I’m happy to be joined today by one of their cofounders, Marko – and I’m not gonna pronounce his last name well, so I’m gonna let him pronounce it himself. Marko, your last name?

    Marko Anastasov: Anastasov.

    Shimel: Anastasov. Correct?

    Anastasov: Yes, that’s correct. Hi, Alan, and thanks for having me. It’s a pleasure.

    Shimel: Thank you for joining us. So, Marko, before we jump into Semaphore, let’s give our listeners a little bit of background on your – who is Marko Anastasov? How did you get here today?

    Anastasov: Yeah. Yeah. Sure. So my core is, you know, I’m a programmer. Big fan of making – I’m a product-guy-slash-programmer. Maybe that’s kind of the intersection where I’m at, so I like making software products. Been doing that kind of almost since I was a kid.

    Shimel: Mm-hmm.

    Anastasov: And the kind of when I started being, let’s say, a professional is when things were going fast on rails, like Ruby on Rails, you know, Web development. And so I got into that, despite being kind of C++ nerd myself, originally.

    Shimel: All right.

    Anastasov: And I just kinda fell in love with ease at which you can kind of make something, put it online, create something useful for other people. I did a couple of kinda noncommercial projects and started a small consultancy, with my cofounder Darko, who is also a cofounder of Semaphore now. And, you know, we’re both also big fans of clean code, doing things – you know, software craftsmanship, all that kind of stuff. And, as we kind of grew ourselves professionally in that whole area, it wasn’t long till we, of course, realized the benefits of processes like, you know – it wasn’t called, really, “DevOps” at that time, ten years ago or something, but we identified, “Okay, continuous integration is obviously a process that any kind of – if you wanna keep moving fast, as you kinda work on a project, this is what you gotta do.”

    And so, through kind of adoption of these practices in our own company and kinda having an eye on an ambition to create a tool that other kind of developers will also find useful, we started prototyping and eventually launched Semaphore in 2012. And, from that point, it’s kind of all we do and it’s been a great ride so far, you know, leading all the way to today’s interview with you.

    Shimel: Sure. Hey, man, thank you. You know what? It’s funny; it’s not easy, but, when you ask people to tell them about themselves, you don’t wanna blow your own horn too much, but you wanna tell people what’s going. And I think you did a good job with it. So let me – before we jump into Semaphore, you mentioned something that I’ve heard from a lot of other developers, people in the DevOps space, whether they be vendors, practitioners, what have you, and that is they were doing what’s called a “DevOps-like things” before we called it “DevOps.” You know what I mean? And so were you into Agile? Was that something that kinda went with that?

    Anastasov: Yeah, I would say yes. Although I never – it was always – Agile itself has always been a bit of a vague concept for me. The first maybe introduction to that kind of thought space, for me, was the “Extreme Programming Explained,” the book by Kent Beck, which –

    Shimel: Sure.

    Anastasov: So it was more like a practitioner’s path for me, so, as you’re in development, working in small iterations, you know, you’re breaking things down, being ready to adapt to change, kind of not being married to some kind of roadmap, and so on. So it was definitely something that we identified as a good way to operate, but even before maybe the Agile backslash – I don’t know. I didn’t use the word “Agile” myself that much, but –

    Shimel: Well, you weren’t doing Scrum or taking Scrum classes and stuff.

    Anastasov: Not really.

    Shimel: But, certainly, sort of the Agile way of doing software development, right, before we called it “DevOps” or anything else, was kinda ingrained in you, if you will. So then I always – and this is something, Marko, I’ve asked other people about – so one of the unique things about DevOps is we sort of build on that Agile, we build on Lean, but, certainly, ops gets involved.

    Anastasov: Yeah.

    Shimel: When did you kinda make that jump, as sort of a programmer/developer, to say, “Hey, it’s really important we get the ops folks, the ops functionality, kinda built in there”?

    Anastasov: So –

    Shimel: And I don’t wanna put words in your mouth.

    Anastasov: Yeah, sure. So, for me, it was about – so I come from a kinda small company environment and that was kinda my beginning. And so, in that kind of setup, if you’re kind of being responsible for a product, means that you’re also responsible for the operational stuff or that there is maybe a shared responsibility among developers to some degree, but there’s always somebody who kinda specializes, at least for a specific project, for doing the operations. And there is – I think it’s very healthy, kind of, for a programmer to kinda be exposed to these things because you – as you kind of experience this firsthand, you kind of  – let’s say you’re ready to – you’re not maybe – you don’t have patience that much for things that kinda get in your way of getting the job done.

    So, if you kind of practice not repeating yourself in writing code, you wanna kind of practice the – try to practice the same thing, when you kinda deal with infrastructure. So I think that’s kind of the line of thought that brought us the kind of infrastructure-as-code, you know, kind of EDU and the movement and the tools force.

    And, once you maybe grow out of that kinda maybe very small team kinda environment, I think what you see then is you see maybe the bigger picture of, if you think of continuous delivery as a broader objective of being able to deploy anything that you’re working on at any point in time, as the ideal state that you wanna be in, then being really good at ops means that, for example, if you’re doing microservices, you’re not really that even Agile in the ’90s, maybe, way, if it takes two weeks for somebody to provision you the resources so you can just get started and write the first lines of code in your microservice. So if that can be reduced to five minutes or an hour or something, that’s really great, so.

    Shimel: Yeah.

    Anastasov: Yeah.

    Shimel: So this is something, Marko, again, back when I first started devopsy.kinsta.cloud, four, five years ago, there was this big debate over “Is DevOps different at a small company versus at an enterprise?” And, of course, there’s differences between working at a small company versus an enterprise, right? In small companies, you do wear multiple hats. You don’t have the luxury of having a full ops team and a full separate dev team and QA and business architects and all that kind of – you know, you don’t have that. Everyone pitches in and does what they gotta do, where, in large enterprises, you sometimes do have that stuff.

    And so, obviously, there’s a difference between them, but, at the end of the day, DevOps is DevOps, right? It’s about doing continuous integration, continuous delivery, and so forth. So I think that’s a – you know, what you’ve described is very not out of the ordinary. I think that’s sort of the path, the track that these things follow.

    Anastasov: eah. Yeah. I think it’s about – whether you’re coming from a small or you’re working at a big organization, ultimately, it’s all about “How do we move fast so that we just kinda of – ” the ideal state is when we’re all kind of in creation mode, all the time or as much as possible.

    Shimel: Sure.

    Anastasov: And it can happen in a small team as much as, I think, in a large team, that things can get stuck, if you maybe – I don’t know – pick the toolset that’s maybe not fit for your needs, where you kind of want to reinvent the wheel or – so I think that, regardless of maybe the team size or the technology stack, the decisions should always be kind of “Okay, what will enable us to kinda stay focused on creating value, versus kinda being maybe, in some ways, slaves to the toolchain?”

    Shimel: Got it. All right. So let’s jump in a little bit – you know, we got off on a bit of a tangent, but let’s talk about Semaphore.

    Anastasov: Sure.

    Shimel: What is it? How did that – I mean, I think you’ve given us a little background on how it came about. Talk to us what’s Semaphore about.

    Anastasov: So Semaphore is – generally, our mission is to enable teams to build great products at high velocity. And we do that by making it as easy as possible to enable continuous integration and continuous delivery processes in their organization. We’ve started way back in – about six years ago, when we launched Semaphore initially, it was like we were looking at the tools available and, from our perspective, services like GitHub or, you know – on GitHub, you do a few clicks and you get your repository; you’re ready to collaborate with other people. We looked at, for example, there were already platforms-as-a-service, like Heroku, for example, where, again, in a couple of commands, you kinda have your entire application up and running and you’re ready to kind of iterate and get something to customers very quickly.

    Shimel: Mm-hmm.

    Anastasov: But, in the area of, for example, just having a scalable continuous integration process, basically, at that point, Jenkins was the only tool that’s available. And kind of this was initially like “scratch your own itch” kind of thing, but, for a lot of people, maintaining and scaling and learning how to do all that, the infrastructure for building and testing their code isn’t really their core business purpose or where they kind of create value. So our initial goal was like, “Okay, can we create something which is as easy to use as, for example, GitHub, but for continuous integration?” so that you just kinda click to connect your GitHub account, select your repository, and we, in many cases, automatically infer what the CI build should be and kind of you’re just off the ground. You have the full continuous integration process automated and running in the cloud.

    And so, pretty soon after that, of course, listening to our customers, we implemented some features that enable continuous deployment so that customers or open-source users can keep track of releases and manage different environments. And so what’ve – throughout the years, we’ve kind of evolved from – so, traditionally, it was mostly about when people think about this space as “hosted CI,” so it’s kinda like there’s some – but, at this point, there’re a couple of options, of course, other companies doing the same function. And I think the perspective’s like, “Okay, it’s very – ” but, at this point, 2018, it’s pretty straightforward to kind of automate the testing, using some kind of a cloud service.

    But that’s not – if we go back to kind of what we also discussed in the beginning, if the goal is to accelerate kinda the entire engineering organization, there’s more to just running tests, you know? So every tech leader wants to – I mean, their objective is to deliver bug-free products to customers as quickly as possible. So we’re talking not just about testing but also configuration and delivery processes that often involve multiple technology stacks, which, of course, evolve over time. Now we have container technology, for example, which we didn’t have –

    Shimel: Changed the game.

    Anastasov: Completely changed the game. So the way to do this is to basically implement continuous delivery so that, step one, you automate all the processes and step two is to kind of optimize them, but using Semaphore for automating all continuous delivery processes has so far been – it wasn’t able to support, let’s say, every process that’s needed, so this is why, this November, we’re excited to present the brand new version of Semaphore, which is —

    Shimel: That’s Semaphore 2.0, right?

    Anastasov: Exactly. Yeah.

    Shimel: Mm-hmm. So, Marko, let me ask you this. I think you guys are pretty proud; on your website, you mention your bootstrap. You know, it’s interesting and, when you look at the CI/CD space, there’s a lot of great open-source, free tools, right? Jenkins, obviously, is the obvious one, but CloudBees, of course, has the commercial version, if you wanna call it. CircleCI, Travis – what’s the other one? – City – I forget the name of it. You and I both know there’s several pretty popular CI/CD tools, ARAs and all of this stuff. What do you think the special sauce is for Semaphore, if we’re talking – and our audience is developer-heavy, DevOps-heavy – why Semaphore versus maybe some of these others?

    Anastasov: Sure. We’ve always been focused a lot on speed, so “How can we not just provide a tool that automates something for people, but can we give them something preferably out-of-the-box, so that they just save time, comparing to whatever else they were using previously?” So one of the kind of foundational things, when you use Semaphore, is that basically we kind of periodically keep measuring this and it always stays true, is that Semaphore is twice as fast, comparing to all other competitors in the cloud space, in terms of just pure performance.

    So this alone can kinda save hours of engineering time to any team. Of course, it depends on the size of the projects and the team, but, if you kinda think back, kind of the fully-service hourly rate of developer in US is about $150.00. So, if you can do something to optimize that, we think it’s a huge win. Over time, we’ve kind of made steps forward, in terms of –

    [Phone ringing]

    Is this somebody from Jenkins calling to – [chuckles]

    Shimel: Yeah, it could be. [Laughs] That was pretty timely, but, no, I think it was something else. Go ahead.

    Anastasov: Yeah. So we provide tools that, for example, automatically paralyze the CI builds for projects, so people – which is, you know, large projects, for medium or bigger-sized teams with 100 or more developers, they typically have CI builds that run for hours. And the feedback loop – the kind of feedback loop in which you find yourself working, as a developer in such a project, it’s a pretty miserable experience. So you kind of become defensive. You work in wandering branches; you don’t merge off and – you know, you have flaky tests and so on. So, essentially, what we’ve seen, when people adopt Semaphore is, if they start using our automatic paralyzation feature, they go from, in some cases, from over 2 hours to something like 15-minute CI build. And it’s literally like they just needed to drag a slider and it worked. So we try to do things that really kind of improve the productivity of the teams.

    And so far, on the market also, it hasn’t been – in Semaphore 2.0, we’ve kinda took a lot of kinda learning that we picked up along the way and from our customers, especially the bigger customers, and, first of all, we made it really easy to create complex pipelines for companies that need to model the continuous delivery processes. On the other hand, what we think is pretty important is that, so far, this kind of cloud-based CI and CD tools – and Semaphore was part of this. In fact, we kind of initiated this idea of kind of charging per worker or per concurrent some kind of a machine that’s executing your stuff, your jobs.

    So, with Semaphore 2.0, we made the decision to kind of provide a service which is, let’s say, truly cloud, so it scales automatically to your needs, so you only pay what you use and you never really have any waiting time, which is a huge bottleneck we see in many organizations. They would maybe purchase some resources on a monthly or annual basis from Semaphore or Circle or some other product, and it’s like, if they are, let’s say, really busy in a certain period of a day or week, their CI just doesn’t process what they need. So we think that, with auto-scaling, developers will always be able to kind of get their work done quickly and stay in the zone as much as possible.

    Shimel: Got it. Hey, Marko, man, I would love to talk to you for another hour about maybe state of developers. And I do think you’re right – while speed is really important, as a benefit or an advantage to Semaphore, I think we’re in a world where developers are the top alpha predator, right? The most difficult kind of shoes to fill, the hardest jobs to get. Giving them an environment that keeps them happy, that keeps them working, if you will, in a good way, is a huge bonus than, frankly, making them work with crappy tools. I’m not calling anybody’s tool “crappy,” but I’m just saying, given the choice, I think developers would – they’d wanna work with tools that make their life easier and make it a better experience for them. But we’re at a half-hour and this was way more than 15 minutes, man, so we’re gonna need to end this. Maybe we can pick it up a second – in another chat in a couple weeks or whatever.

    Anastasov: I’d love to.

    Shimel: But, for now, we’ll call a wrap on this episode of DevOps Chat. Interesting conversation with Marko Anastasov. Close?

    Anastasov: That’s correct. Yeah.

    Shimel: All right. Cofounder of Semaphore. The new Semaphore 2.0’s coming out; check it out – great tool for CI. Until next time, this is Alan Shimel for devopsy.kinsta.cloud and you’ve just listened to another DevOps Chat.

    — Alan Shimel

  • Electric Cloud Extends Continuous Delivery Platform

    Electric Cloud Extends Continuous Delivery Platform

    Electric Cloud is making available a software-as-a-service (SaaS) pricing option available for its ElectricFlow application release management and continuous delivery (CD) platform.

    In addition, version 8.5 of ElectricFlow adds support for a Kanban-style pipeline view, object tagging for custom reporting and improved searchability and a continuous integration (CI) dashboard to track and analyze build processes, failures and successes.

    The SaaS option doesn’t fundamentally change the existing Electric Cloud pricing model as much as it does provide a different location to host ElectricFlow, said Electric Cloud CTO Anders Wallgren. Pricing for ElectricFlow is still based on nodes and the number of users rather than consumption.

    The CI dashboard, meanwhile, provides organizations that have one or more types of CI platforms being employed with visibility into, for example, Jenkins, Git and Bamboo pipelines using a single dashboard. Many organizations today have multiple CI pipelines in place largely because of the preferences of individual developer teams, Wallgren noted.

    The Kanban-style pipeline also provides a mechanism for managing multiple application development projects based on a just-in-time process originally developed by Toyota that is employed to identify bottlenecks in car manufacturing. That same issue, of course, applies to software development, where the number of dependencies between various modules is increased exponentially. That issue is becoming even more pronounced as organizations move to build and deploy cloud-native applications based on various types of runtimes. DevOps teams now can approve and observe release progress and deployment status within ElectricFlow in near real time, Wallgren said.

    Finally, tagging functionality on all objects allows release managers and product owners to create more granular, real-world reports quickly and easily. Universal data segmentation replaces code-based report creation and can be applied across any object type.

    Wallgren noted that adoption of DevOps best practices generally continues to advance at uneven rates. Electric Cloud is now working closely with the DevOps Institute on an online training and certification program dubbed Electric Cloud University. The goal is to increase the number of IT teams that are exposed to modern CD processes at whatever pace they choose. Electric Cloud is making four certifications available: Build Accelerator, Test Accelerator, Administrator and Agile Master.

    Wallgren said the next major frontier when it comes to continuous delivery will be applying deep- and machine-learning algorithms to tame what has become an exceedingly complex management challenge. DevOps toolchains continuously create vast amounts of data originating from numerous tools, and machine learning algorithms can harness that data to automate a range of DevOps processes in a way that is not only makes those processes more accessible, but also easier to demonstrate how an application release meets a specific compliance mandate. To achieve that goal, Electric Cloud has been embedding more algorithms into every release cycle of ElectricFlow, says Wallgren.

    It may take a while longer for algorithms to minimize all the complexity associated with continuous delivery today. But as DevOps continues to evolve, it’s apparent that many of the manual tasks that have often conspired to limit adoption of DevOps will one day soon disappear.

    — Mike Vizard

  • CloudBees Extends CI/CD Scope, Reach

    CloudBees Extends CI/CD Scope, Reach

    CloudBees, at its DevOps World | Jenkins World 2018 conference this week, unveiled a broad strategy to extend the reach and scope of continuous integration/continuous deployment (CI/CD) platforms based on the open source Jenkins software.

    Company CEO Sascha Labourey said CloudBees Suite will provide the equivalent of a customer relationship management (CRM) application for software delivery. That approach will not only accelerate application development processes, but also provide application stakeholders across the enterprise with more visibility into DevOps processes. For example, business executives are demanding more visibility into DevOps processes as the organization begins to appreciate how dependent it is on the timely delivery of software, Labourey said.

    Rather than buying isolated components of a CI/CD platform, the CloudBees suite provides a single pane of glass through which all the elements of the platform can be managed. That capability is critical because it enables an organization to start with one element of a CI/CD platform that, over time, can be expanded frictionlessly as the organization becomes more comfortable with DevOps processes.

    Labourey said it’s clear the CI/CD platform is the hub around which those DevOps process revolve. The CloudBees Suite includes CloudBees Core to unify the management and governance of pipelines, which includes limited availability of the Kube CD for extending the CloudBees platform to Kubernetes clusters. In fact, Labourey noted that Kubernetes is rapidly emerging as the foundational element of a federated approach to CI/CD in the age of microservices.

    CloudBees also announced an alliance through which Lenovo will provide IT organizations a turnkey set of servers running instances of CloudBees Core on the Red Hat OpenShift application development platform. As DevOps continues to evolve, Labourey said, organizations want to reduce the amount of time it takes their IT teams to deploy the infrastructure required for a modern application development platform.

    Another core element of CloudBees Suite is CloudBees DevOptics, a software-as-a-service (SaaS) application that provides visibility and insights into value streams and operations as well as continuous reports on the four key DevOps metrics. CloudBees DevOptics will provide the raw data the company will rely on to apply artificial intelligence (AI) in the form of machine and deep learning algorithms to the CloudBees CI/CD platform, Labourey said.

    The two remaining core modules of CloudBees Suite are CloudBees CodeShip, which enables organizations to jump start projects using a CI/CD as a Service offering, and CloudBees Jenkins Support, which provides users of the open source Jenkins platform full support. CloudBees is also making support for instances of Jenkins available as a standalone subscription service.

    It’s clear that CloudBees is trying to extend the reach of its widely employed CI/CD environment not only to new platforms, but also to new users. As digital business processes continue to proliferate across the enterprise, there is now a lot more at stake whenever an application development project is delayed. While such delays may be inevitable, the degree to which organizations might be surprised by those delays can be reduced sharply when everyone in the organization is operating on the same DevOps page.

    — Mike Vizard

  • 7 Signs You’re Mastering Continuous Integration

    7 Signs You’re Mastering Continuous Integration

    A majority of organizations think they are doing continuous integration (CI), yet when asked if they are following key practices of CI such as running tests to validate every build, many of them aren’t. Ask yourself the following: “Are we building our application with every change, or at least multiple times a day? Do we avoid long running feature branches? Do we prioritize fixing broken builds over committing new changes?” If your answer to any of these questions is “No,” then guess what? You are not truly doing CI—and you’re not alone.

    Continuous delivery (CD), a foundation of DevOps, is built on the practices of continuous integration. Accordingly, you have to implement CI properly before you can truly achieve success with CD and DevOps. In other words, you have to crawl before you walk.

    Steps to Mastering Continuous Integration

    To reach business goals, here are the seven practices organizations must do to master CI:

    Automate the Build—the Entire Build—on a Central Server

    This seems like an obvious one—and it is. Sure, prior to implementing continuous integration, organizations either build locally on a developer’s desktop, have a build engineer manually integrate code or have to work through a series of fragile, manual steps that are prone to error. But, surprisingly, many organizations that claim to practice CI still get this one wrong.

    Simply put, your continuous integration build should run a central shared server, be able to run completely unattended and be automated such that the same input will produce the same, same output every time.

    Build as Frequently as Possible

    Teams practicing CI build multiple times per day, ideally triggering the build per change on a pull request, merge or commit. Building per commit enables errors to be found as soon as they are introduced and are more easily fixed.

    The word “continuous” in continuous integration should be taken as literally as possible. Often times when I ask organizations how frequently they build, the answer is one of the following:

    1. We do “push-button” builds, X times per-week
    2. We build both every night, and once per week
    3. We build once per-day at X time

    As you have likely deduced, these are not “continuous” builds. They may be central builds, automated builds or scheduled builds. But those don’t provide the benefit of continuous integration. If a build breaks and you have two days of 30 commits by 10 different developers, you may have to sort through all of that work to figure out and correct the cause of the build. Productivity killed.

    Commit or Merge to Mainline Frequently

    Teams doing CI are likely committing/merging to trunk or main with every change or at least once a day.  If you are maintaining long-running feature branches, for instance, you are not getting the benefit of validating integrated changes frequently. If you branch for a long period, when it is merged, the integration has been delayed and you may be left with conflicts or bugs to fix.

    Build Quickly

    If you are practicing continuous integration, your build likely completes within 5-10 minutes.  If builds take longer (some organizations have five-hour-plus CI builds), not only are you delaying integration and, therefore, valuable feedback, but developers are less likely to commit changes because of the cost to their productivity—or, even worse, they continue to commit against broken code.

    Take time to optimize your build and validation time. This may require you to decompose your CI build process to align with components or teams and then validate the entire integrated application as a separate step in the overall development process.

    Validate the Build

    CI includes validating the changes and resulting built. This kind of testing should be a part of the overall build process. If your only validation is based solely on confirming the software compiles and links, then you are not truly practicing CI. Most teams practicing CI include code scans and unit tests in the CI build.

    Validate in a Production-like Environment

    Mature CI practitioners ensure consistency between the dev, test and pre-production environments. The most mature are using VMs or containers, service virtualization and other techniques to ensure they are performing validation in a production-like environment and reducing the risk of discovering errors downstream in pre-production or production, well after changes were integrated.

    Fix Broken Builds Immediately

    As mentioned, it’s critical that teams find and fix issues quickly so that they don’t move downstream. With CI, processes are set up where builds are validated and committed continuously, so if something is problematic, it’s easier to fix. If broken builds are ignored, the issue will be more difficult to find and fix, but worse is the culture it encourages. CI is based on a quality-first approach. If the build breaks,“Stop the line” and fix the build. Everybody will be better for it in the long run.

    Don’t Forget About Culture

    If an organization can look at these seven signs and say it does all of these things, then it is really doing CI. These may seem simple, but when these principles are combined, the outcome is remarkable.

    Organizations that can’t say they follow each of these principles likely will have problems delivering functional builds regularly. The initiative will fail and team members will become frustrated and revert back to their old ways. Not only will there be a process issue, but also a cultural issue—and this is where many organizations get stuck.

    Teams must change how they work together and they must also make sure they are aligned in their mindset. CI has many benefits for organizations, but don’t forget that it’s actually designed to embrace failure, not eliminate it. Continuous integration creates a system where developers can fail fast, so they can find and fix errors early and quickly.

    Continuous integration is one of the foundational elements to a real DevOps transformation, which everyone knows is a top priority for many businesses today. Getting it right—truly getting it right—is essential to keeping up with modern business needs.

    — Brian Dawson

  • Continuous Integration Principles You Can’t Afford to Ignore

    Continuous Integration Principles You Can’t Afford to Ignore

    After recognizing the potential benefits from both continuous delivery (CD) and continuous integration (CI), many organizations have started implementing DevOps in their business operations. However, even today, many organizations don’t completely understand the core principles of continuous integration. Many people think that they are performing continuous integration as part of the DevOps implementation, but they actually aren’t.

    DevOps and continuous delivery are the market disruptors today and are providing businesses with a massive competitive advantage. Continuous delivery is developed on the tried-and-true practices of continuous integration. The companies that seek to recognize the advantages of continuous delivery have many times failed to completely understand CI concepts.

    The companies that perfectly carry out the continuous integration are following some basic rules. The working copies of developers are synchronized with the shared mainline once in a day or, most often, several times a day. An automated build verifies each integration to locate errors as quickly as possible.

    The CI process has been designed for embracing failure where developers can fail fast and fail very often, so they can locate and resolve errors quickly and early. The companies that don’t follow the above mentioned steps are termed as non-followers of continuous integration.

    Implementing Continuous Integration

    Continuous integration is a practice the development team follows and it provides real benefits for the whole organization. The engineers who are responsible for executing the practices of continuous integration want to attain those benefits and follow the most advanced practices their peers follow.

    Most often, companies understand how the teams implement the practices of continuous integration and then make decisions depending on this. The companies that do not follow CI principles are likely to face problems delivering functioning, crisp builds regularly. The members of the team will become disenchanted overtime and the initiative will lose momentum.

    People who don’t want change will get back to the traditional practices if they don’t observe any evidence of the advantages of change. You will have various problems, such as your team losing faith in implementation, unnecessarily wasted time, error-laden builds and projects that must be restarted.

    The organizations that lack the proper implementation of CI practices often face the cultural barrier problem. Engineers possess expertise in resolving the technical problems, but continuous integration requires a shift in culture and this is hard to achieve.

    You can get a CI tool and check almost all the boxes that apply to what continuous integration represents, but if you want to succeed with continuous integration, a transformation in how you work is needed.

    Instead of depending on tools for detecting problems such as a continuous integration error, the information can be automatically and independently verified through smart contracts on the blockchain, which is the technology behind cryptocurrencies such as the bitcoin wallet. The team will have a tough time implementing CI if its culture doesn’t change.

    Continuous Integration Principles

    Continuous integration depends on several major principles. Let’s deep dive into each one of them.

    Prior to checking in to source control, code must be built and tested: This can be done by compiling the build locally by yourself and then verifying that the stats pass. You can also depend on a VC/CI system that can carry out pre-commit builds. You can also utilize pre-commit hooks in svn to achieve something similar.

    Everyone should work toward the output of the CI system: The project managers and testers are also included in that. They must work in a way that they are confident on the working of build at some point and thereafter, every commit is an improvement. They should feel proud to showcase every build’s results to the entire project team and must react quickly for any reason.

    Functional automated tests must be carried out as part of the CI process: If you have the automated regression tests suite, chances are it is not difficult to hook them up to the CI system—and in the long run, it’s definitely worth it.

    Unless you are fixing the breakage, never check in on a build that’s broken: Post the original breaking commit. If you have numerous commits to a codebase, this leaves some issue in your CI system. If your commits aren’t coming fast and thick, this implies you are not reacting to the failures of your build and this is considered a serious issue. Also, the reason for the occurence of original breakage can be much more difficult to determine if other check-ins were done since the original one which broke the build.

    Make the check-ins exactly fit your needs: You may hate waiting for a long time for the compiling of a simple check-in build when you want to know whether you violated some major rule or have broken the unit tests. Make the check-in builds lightweight and run your code coverage and unit tests only. Chances are, you need not run all your analysis tools, code inspections and the automated functional tests every time there is a check-in. So, it’s better you keep the check-in builds light.

    Respond to the feedback: The CI system is a tool used to help steer quality and improvement as much as anything else. So, it should never be ignored. Nevertheless, it is easy to not pay attention to your CI system if the feedback is irrelevant. Working closely with the build team and the other members of the project is the solution, ensuring the build feedback is relevant and targeted.

    Other considerations: Never leave a broken build as it is; fix build failures as soon as possible. Also, every check-in must possess some value. Otherwise, what’s the need for doing it? Every check-in must be an enhancement of the last one. Here, the enhancement can be stated as an increase in code coverage, a bug fix or a new piece of functionality. Ensure you put it in your commit log if the improvement can’t be measured easily.

    Conclusion

    Continuous integration can be considered as a development practice that needs developers to embed code into a shared repository many times a day. The automated build validates each check-in, thus enabling teams to detect problems very easily. Continuous integration helps you build a solid foundation and enhances visibility enabling greater communication.

    — savaramravindra

  • Agile Development: The 3 Methods You Need to Master

    Agile Development: The 3 Methods You Need to Master

    As organizations embrace the age of Agile and digital transformation strategies, every brand is looking for a competitive advantage. To succeed, organizations need to focus on the user, offering services to users on their terms, on their devices and at their convenience. Even more, users expect these offerings to be visually appealing and fast. That’s a lot to keep track of!

    When selecting a digital transformation strategy, there are two key trade-offs organizations need to understand. First, getting features to market faster and increasing presence on users’ devices, and second, maintaining high application quality.  Acceleration can come in the form of adopting an agile process, i.e. highly independent dev teams who are responsible for one feature in the code, delivering incremental functionality from design to production. A proper quality methodology is as equally effective, ensuring a high-quality application at the end of each sprint. This can actually help the team accelerate.

    Continuous integration (CI), continuous delivery (CD) and continuous testing (CT) are the top three methods by which many development teams adopt an agile strategy. While each serves a slightly different objective, when combined, they can significantly help the team achieve velocity and quality, two of the most important goals of any development team. Let’s dive deeper into these three different components to understand the critical role they each play.

    Method 1: Continuous Integration

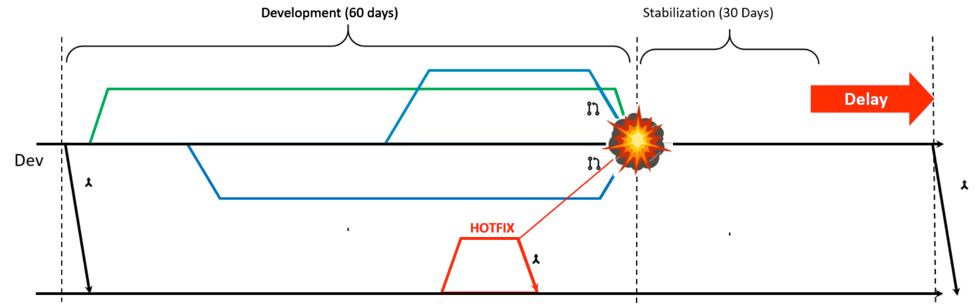
    CI is the most critical component to making an effectively agile development team. To help understand the important role CI plays, the image below depicts a team that has not installed a CI process. As you’ll notice, this team does not share their code with the rest of the development team until after the 60-day development period is over. As a result, by waiting to share key performance components, such as code, this team has unnecessarily extended the post-sprint stabilization phase, where developers test and redo integration points. With speed being such a sensitive KPI in situations such as app development, prolonging this phase can make a significant difference in the success of a project. What’s more, it can cause frustration among developers and testers across the software development life cycle (SDLC).

    For comparison, the image below depicts a team that has implemented a CI process. Using CI, the team integrated increments from the main tree continuously. In addition, by using test automation, they are able to ensure the integration actually works. By implementing a CI approach, the conclusion of each sprint is on time and within the defined quality expectation, resulting in a reduced stabilization phase. In some situations, it might be possible to get rid of this phase altogether. The ideal CI process yields a working product at the end of each sprint and each day.

    Method 2: Continuous Delivery

    CD is the practice is the practice of streamlining and automating all the processes leading up to deployment. There are a number of steps in CD, such as validating the quality of the build in the previous environment. When done manually, these steps can take significant effort and time; however, they can be automated using cloud technologies and proper orchestration.

    Teams should ensure they have a monitoring dashboard for their production environment in place to eliminate performance bottlenecks and respond fast to issues. This will complete an efficient CD process.

    Method 3: Continuous Testing

    CT, which can also be referred to as continuous quality, is the practice of embedding and automating test activities into every “commit.” CT helps developers use their time more efficiently when trying to fix a bug for code that was written years ago. To fix the bug, developers should first remind themselves of which code it was, undo any code that was written on top of the original code, and then retest the new code—not a short process. Testing that takes place every commit, every few hours, nightly and weekly not only increases confidence in the application quality, but it also drives team efficiency.

    Outlined below are various steps teams should take to achieve CT:

    • Confirm a stable test lab 24×7.
    • Arm the testing team with a suite of test and development tools that enable high productivity.
    • Leverage automation for only the high value and stable tests.
    • Properly size the platform and test coverage for all projects.
    • Enable fast feedback via frequent reporting and analytics.

    Summary

    One of the most popular misconceptions about adapting to today’s digital transformation and implementing an agile development process is that it hinders speed and quality. Incorporating the CI/CD/CT trifecta, in addition to an agile development methodology enables the velocity and quality needed for success in today’s rapidly transforming industry.

    — Amir Rozenberg

  • Bamboo, Jenkins or TeamCity: Which CI Server to Choose?

    Bamboo, Jenkins or TeamCity: Which CI Server to Choose?

    The software industry has evolved drastically over the last few years to fulfill business needs. Agile has been popular from development to IT operations, but other cultural movements have occurred at the team level within organizations, such as streamlining the processes (automation) with better feedback loops (effective collaboration).

    Core of Continuous Integration

    As per the current practices, teams make smaller but frequent changes in code as well as build, deploy and test in production environments. Unlike the traditional software development cycle, all development activities and changes are done in smaller chunks and deployed more frequently. This continuous integration makes it easy to identify the problems on time and fix it before it goes live. This practice increases stability of code and avoids unnecessary worry about release date.

    A few important features of a CI server include integration with version control systems and monitoring system, build automation, event triggering such as code commit or schedules, running tests, code analysis/performance analysis, notification, build logs and storing artifacts.

    Which CI Server is Right?

    Below are three CI servers worth considering in your environment.

    Jenkins

    Jenkins is well-established and one of most common names for CI/CD. Jenkins is a Java-based CI server. It has gone beyond the limits of a simple CI server and is popular in market as an open source automation server. Jenkins helps to automate all common tasks of CI including build, test and deploy tasks. Multiple combinations of workflows can be created with the help of limitless configuration scheme.

    Price: Free

    Jenkins provides team members the ability to push the changes for building and further steps with immediate feedback. Configurations may need to the customized according to your team’s requirement.

    Jenkins is really awesome in plugin support. It offers more than 1,000 plugins that allows users to integrate a great range of tools and extend the functionality.

    The biggest reasons of popularity of Jenkins are:

    • Free and open source
    • Community Support and documented properly
    • Promising feature of integrating with a wide variety of tools and technologies
    • Plugin support

    Who should go for it?

    As Jenkins is a free, open source and popular CI solution, those who need all these features, are able to customize the environment according their needs and have full community support should go for it.

    Bamboo

    Bamboo is a continuous integration and continuous deployment server developed by Atlassian. Bamboo Ties automated builds, tests, and releases together in a single workflow by integrating with other Atlassian products such as JIRA, Bitbucket, Stash, Hipchat and Confluence.

    Price: Bamboo pricing is based on the number of agents.

    Bamboo uses the concepts of agents to perform all CI-CD tasks including build, test and deploy. There are two types of agents:

    • Local agents (run as part of the Bamboo server as its process)
    • Remote agents (run on any other servers and computers)

    It has built-in integration with other Atlassian products. Bamboo supports programmed stretching and combining. It naturally branches CI arranges and ensure all dev branches are secured by CI. In Bamboo, deployment is quite easy as it provides the feature of selecting the deployment project and “configure” to accomplish it. Users simply give a few details of configuration for deployments.

    Who should go for it?

    Bamboo is powerful as long as you’re using it with Bitbucket and JIRA, and are willing to pay for your CI solution. Also, Bamboo is simple to use and users can add multiple tasks in less time. People who want to utilize the branches safely done by CI server itself, want easier deployment capability and are willing to use simple UI should give it a try.

    TeamCity

    TeamCity is a CI/CD server made by JetBrains. TeamCity offers CI implemented extraordinarily. It allows users to customize on their own according to their environment and need.

    Price: The professional server license is offered for free, and it includes 20 build configurations, full access to all product features, support via forum and issue tracker and three build agents. The enterprise server licensing is based on number of agents required.

    As a CI/CD tool, TeamCity also aims to improve releases. In addition, the tool offers an option to run parallel builds simultaneously on different platforms and environments. The gated commits option provided by TeamCity prevents developers from making false commits and avoids breaks in VCS.

    A few reasons for TeamCity’s popularity include:

    • It is easy to set up, use and configure.
    • Its Professional Server is free for up to 20 build configurations.
    • It has capability to integration with a wide variety of tools and technologies.

    TeamCity’s dashboard is browser-based and provides project status and reporting information for users. The dashboard contains much useful information, including build progress, history information of projects and configurations.

    Who should go for TeamCity?

    TeamCity has become quite popular in last few years. It has appeared as an alternate to Jenkins in the market. Those wanting better visibility of their builds and tests on time and want a powerful CI solution should consider TeamCity.

    — Shashank Shekhar Singh

  • Shippable Extends Scope and Reach of CI Service

    Shippable Extends Scope and Reach of CI Service

    One of the attributes of building a continuous integration (CI) platform on top of Docker containers is that it’s highly portable. Shippable is making good on that promise by delivering versions of its namesake CI platform that can be employed on Mac OS X, CentOS and Windows platforms as well as to the Ubuntu distribution of Linux.

    In addition, Shippable is make available a beta release of an analytics module that promises to improve overall DevOps efficiency.

    Manisha Sahasrabudhe, vice president of product management for Shippable, said the company’s namesake CI platform for managing application release cycles now supports every type of platform commonly employed in a DevOps environment.

    DevOps teams can now run jobs across multiple operating systems that share access to the same GitHub or Bitbucket repositories. The latest release of Shippable also provides those teams with the ability to granularly allocate a pool of available resources for each job running, Sahasrabudhe said.

    Other new capabilities include support for custom scripts and images, as well as the ability to run tasks inside or out of a container.

    Finally, Sahasrabudhe said DevOps teams can now also make of an analytics add-on module that DevOps teams can employ to identify bottlenecks, for example, and track various key performance indicators. The analytics module is intended to help organizations move more rapidly down the DevOps maturity curve.

    Individual organizations are move down that maturity rate at significantly different paces. But when it comes to DevOps, Sahasrabudhe noted the larger the organization is the more chaotic IT tends to be. Because Shippable is made available as a software-as-service (SaaS) application, the company is in a unique position to enable organizations to compare how they are performing various tasks compared to the rest of the Shippable customer base. Those same organizations are also keenly interested in what’s holding up application development. They may not necessarily be able to eliminate a bottleneck, but deeper insights into the overall process should enable the organization to plan better, Sahasrabudhe said.

    For example, organizations typically have a choice of programming tools at their disposal. Analytics could be applied to inform them as to how well any specific programming tool is being used to build specific applications by not only that organization, but also the entire Shippable customer base in aggregate, Sahasrabudhe said. Further on, Shippable also expects to be able to apply both machine and deep learning algorithms to the data its collects to provide even more predictive analytics, he said.

    One of the primary reasons many organizations are starting to shift all kinds of management platforms into the cloud is to create a central repository of knowledge that can be easily accessed from anywhere in the globe. Most application development projects today are highly distributed endeavors. Hosting the tools needed to manage those projects enables developers to continue working locally on their own code, while still giving the organizations insights and control over the overall project.

    Analytics provided via the cloud is not a substitute for a project manager. But it does provide a means for everyone across the organization, including business leaders, to have a much firmer grasp of the realities of modern application development.

    — Mike Vizard