Tag: continuous delivery

  • Role of DevOps in Mobile App Development

    Role of DevOps in Mobile App Development

    Emerged out of Agile methods in 2001, DevOps basically represents a fundamental departure from the traditional waterfall software development approach.

    DevOps is a modern software development method that focuses mainly on the effective collaboration between software developers, project managers and operations staff, while also aligning with business goals at the same time.

    DevOps came into being when developers and operations staff came together to more effectively overcome the challenges associated with continuous software delivery.

    DevOps in Mobile Applications

    Peerbits takes a holistic view of mobile DevOps, defining it as a capability for continuous mobile app delivery that enables our clients to reduce time-to-market new features and seize new market opportunities simultaneously.

    The key principle in DevOps is continuous delivery, which means deploying the software (in this case a mobile app) and the environment on which it runs, automatically and on-demand, during any stage of the mobile app development cycle.

    DevOps basically applies the same principles whether you want to build an app for either mobile or web. However, the challenges in mobile DevOps are bit different and specific.

    Mobile DevOps Challenges

    The challenges in mobile DevOps mainly include:

    Different OS Versions: Most mobile apps have multiple target environments and multiple devices, which require dealing with different specs, different OS versions and different form factors.

    Furthermore, not only is there a wide range of operating systems running in the market, but there are also different installed versions.

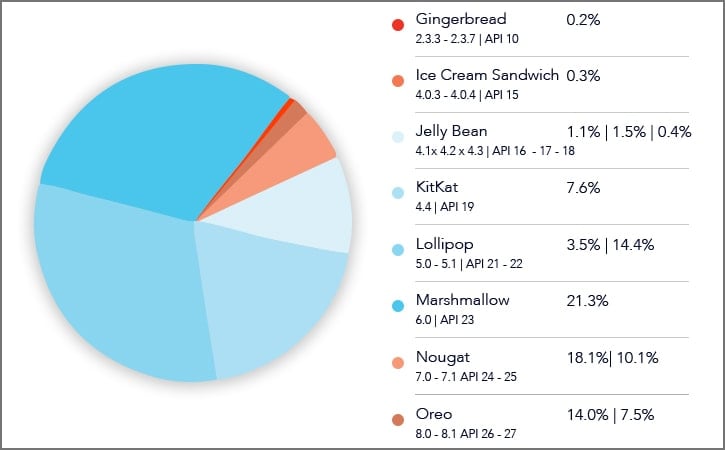
    Take Android, for instance: The Android market accounts for almost 85 percent of the smartphone market. The below mentioned chart shows the breakdown of installed Android Versions as of Oct. 26.

    Image source: www.developer.android.com


    As you can see from the chart, the Android version 6.0, which according to Wikipedia is now unsupported, is still being used by 21.3 percent of Android users.

    This clearly indicates that only a few users update as soon as the new version comes along, while others don’t, either because they don’t want to or because their smartphone manufacturers are not providing newer OS updates.

    In addition to this, most Android smartphone manufacturers also tweak newer Android OS slightly, resulting into an increase in the OS fragmentation and making the launch times slower.

    Hardware: Smartphone hardware presents two primary challenges. First, smartphone manufacturers offer a good range of chipset, memory, storage options and, most importantly, different screen sizes. This makes it difficult to support each of them.

    Second, the mobile device war no longer is being fought only between Apple and Samsung. There are new smartphone manufacturers entering market more often than before. Out of these new rivals, there are also many manufacturers that offer low-cost models.

    Though Apple and Samsung might be dominating the Western markets right now, in China both of these brands account for only 13.7 percent and 20.7 percent respectively.

    In 2015, at least 18 new smartphone manufacturers entered in the market in Asia.

    This localization and fragmentation of available devices and their different OS versions adds a considerable complexity to the mobile application development as a challenge.

    Balancing Mobile App Quality with Always Changing Consumer Demand: As the app economy grew in last recent years, the need for businesses to get their mobile apps released in the market quickly also grew along with it.

    However, since the consumer expectations are also increasing, the quality of a mobile app is the most essential factor in retaining existing customers as well as attracting the new ones.

    In 2018 especially, this is more and more difficult, due to the ease in which customers can delete apps and give poor ratings and review to low-quality mobile apps.

    As a result, businesses need to be extra careful in terms of their app quality, while consistently adding value to keep their existing customers happy.

    All of these factors are putting strain on mobile app development teams, as the waterfall model approach is not a sustainable practice for today’s consumers.

    3 Rules for Successfully Adopting Mobile DevOps

    Adopting DevOps in your business mobile app needs only three considerations, which are explained below.

    Continuous Planning and Integration

    Continuous planning refers to bringing your entire mobile app project team—developers, project managers, operations staff, and other stakeholders—on the same platform to finalize the scope of the mobile app in the preparation of a launch plan.

    Continuous integration, on the other hand, ensures that the code submitted by one developer works with the code submitted by the other developer(s). Simply put, continuous integration in mobile DevOps demands frequent builds, which must be integrated with the last developed code.

    Continuous Testing and Monitoring

    Most mobile application testing is executed on simulators instead of actual devices. Plus, the testing is also manual. And given the number of OS versions alone, it is impossible to do manual testing for all versions.

    A mobile app can perform well in test environment, but it is very common that it will fail in the live environment.

    The reasons of these failures can be many, such as memory, network conditions, power, etc. It is necessary, therefore, for developers as well as businesses to make sure that the continuous monitoring is done via third-party SDKs for log, crash report and so on to find the root of the problem.

    Continuous Delivery and Deployment

    Continuous delivery refers to the practice that makes sure the code is deployed to the production environment by submitting each change to the production-like environment.

    Continuous deployment is the next step of continuous delivery. In continuous deployment, each change that has been approved by continuous testing gets deployed to the production environment automatically.

    Takeaway

    In our perception, there is no such thing as a separate DevOps for mobile application development. DevOps is a general approach that works for all components as well different kinds of application development.

    While there are certain challenges involved in adopting DevOps for mobile apps, but there also measurable benefits that makes the entire journey worthwhile.

    All in all, despite the cost to build an app and its initial pains, the benefits of DevOps make the investment worthwhile.

    — nasrullahpatel

  • Semaphore 2.0 Brings Continuous Delivery to Teams of All Sizes

    Semaphore 2.0 Brings Continuous Delivery to Teams of All Sizes

    Since its inception in 2012, Semaphore has been focused on making code testing and deployment a quick and easy process. The cloud-based CI/CD platform from Rendered Text enables users to get up and running within a matter of minutes—which the company claims is at least twice as fast as other offerings.

    The company is releasing Semaphore 2.0 Nov. 6, which will expand the platform to enable continuous delivery, for a product that allows teams of any size to automate any continuous integration or continuous delivery workflow with custom pipelines so users can model their CI/CD however they prefer. The latest version also better supports CI/CD for containers, giving users the ability to use Docker or Kubernetes tools in building within container environments. Other features of Semaphore 2.0 include support for YAML files and command line interfaces, so teams can manage a large number projects more easily.

    Marko Anastasov, founding partner at Rendered Text, spoke with me about the latest version of Semaphore and his thoughts on the continuous integration and continuous delivery space at large. Read on for his insights:

    Can we start with some background about Semaphore? What was the catalyst for creating it?

    Our company was an early adopter of agile software development practices, including test-driven development and continuous deployment. We relied on cloud-based products like GitHub, which were simple to use and made software development easier.

    However, when it came to implementing continuous integration, we were out of luck. I remember spending days setting up Jenkins for just one of our projects. We saw how expensive and time-consuming it would be to make it fast and scalable. It felt as if by continuously verifying our code, we were doing something wrong. Developers need to set up a fast and functional CI process in minutes, and not worry about how it works.

    What’s new in Version 2.0 that’s worth mentioning?

    Semaphore 2.0 is made to enable continuous delivery in organizations of any size. Previously, like other hosted CI/CD services, Semaphore focused on solving the integration process: building code and running tests. Delivery features were limited and tailored for classic web development.

    This time we asked ourselves, What would a continuous delivery product focused on speed and simplicity look like in the age of cloud-native computing? I’d highlight three things that stood out.

    First, for DevOps transformation to succeed, we need to automate, visualize and accelerate all software development processes in our organizations. So at the heart of Semaphore 2.0 are infinitely customizable code pipelines, configured as code, run as a service.

    Second, infrastructure should be ephemeral and scale in real time. When CI/CD capacity is limited, developers are blocked in busy times of the day. Semaphore adopts the “pay only what you use” cloud model, in which CI/CD resources scale automatically to support the team’s actual needs.

    And third, we can’t manage what we don’t measure. It doesn’t make sense to prescribe the same metrics for every project and organization. So Semaphore lets users choose their own metrics and define their own dashboards.

    What feature or features do you believe will have the most impact with users?

    In building Semaphore 2.0 we were very careful not to add any unnecessary features. All parts are designed to support each other and provide a harmonious user experience.

    For example, Kubernetes wasn’t the first solution to run software in the cloud, but it made vendor-neutral cloud computing as easy as describing what you need to run. Similarly, developers can now describe any CI/CD process they need, and Semaphore will run it immediately at any scale.

    In day-to-day use, I expect users to like how much control they have via command line and autoscaling resources. It’s the overall boost in productivity that will make the most impact.

    How important is Semaphore’s increased support for container environments?

    Containers are the biggest change in the development stack in recent history. In the transition to container-based software delivery, many teams needed to maintain their own CI/CD infrastructure, since none of the existing solutions were flexible or easy enough to use. This takes valuable time away from delivering value to customers. Semaphore 2.0 is built to support the next-generation of cloud architectures based on containers.

    What are some of your thoughts on the current state of the CI/CD market, and where do you see it heading?

    For the continuous integration part of the equation, there are many options to choose from. There’s a wide spectrum from managed to DIY solutions, and from specialized vendors to those who provide basic tools for every aspect of software development. I think the shift that’s going to happen is from basic automation to optimization. For example, Semaphore provides bare-metal performance at convenience of cloud. When a customer tells us that they’ve combined that with our test optimization features to reduce build time from hours to minutes, that makes us so happy because we know what tremendous difference that makes in their workplace.

    On the continuous delivery front, I think there’s less maturity and that the market is still developing. So far, developers have needed to build their own solutions based on complex open source tools and self-managed infrastructure. Cloud vendors have entered the space, not with complete products but low-level tools that leave a lot of complexity for the end user to manage. The next phase will be about making the entire CI/CD process easier and more accessible. At Semaphore, we’re committed to making that happen.

    — Charlene O’Hanlon

  • DevOps Chat: CI/CD with the Semaphore Platform

    DevOps Chat: CI/CD with the Semaphore Platform

    As the old saying goes, “speed kills.” When it comes to development, a lack of speed can kill, too. Marko Anastasov and the Semaphore team have strived to make Semaphore the fastest continuous integration tool in the market. With version 2.0 of Semaphore, they believe it truly is.

    With his background in development, Marko brings a unique perspective in leading the Semaphore team. He knows what he and his colleagues like, and that is the road map for Semaphore. Have a listen to Marko tell us in his own words.

    As usual, the streaming audio is immediately below, followed by the transcript of our conversation.

    Transcript

    Alan Shimel: Hey, everyone, it’s Alan Shimel, devopsy.kinsta.cloud, and you’re listening to another DevOps Chat. In today’s DevOps Chat, we’re gonna talk about a company called Semaphore. Their website is semaphoreci.com. And I’m happy to be joined today by one of their cofounders, Marko – and I’m not gonna pronounce his last name well, so I’m gonna let him pronounce it himself. Marko, your last name?

    Marko Anastasov: Anastasov.

    Shimel: Anastasov. Correct?

    Anastasov: Yes, that’s correct. Hi, Alan, and thanks for having me. It’s a pleasure.

    Shimel: Thank you for joining us. So, Marko, before we jump into Semaphore, let’s give our listeners a little bit of background on your – who is Marko Anastasov? How did you get here today?

    Anastasov: Yeah. Yeah. Sure. So my core is, you know, I’m a programmer. Big fan of making – I’m a product-guy-slash-programmer. Maybe that’s kind of the intersection where I’m at, so I like making software products. Been doing that kind of almost since I was a kid.

    Shimel: Mm-hmm.

    Anastasov: And the kind of when I started being, let’s say, a professional is when things were going fast on rails, like Ruby on Rails, you know, Web development. And so I got into that, despite being kind of C++ nerd myself, originally.

    Shimel: All right.

    Anastasov: And I just kinda fell in love with ease at which you can kind of make something, put it online, create something useful for other people. I did a couple of kinda noncommercial projects and started a small consultancy, with my cofounder Darko, who is also a cofounder of Semaphore now. And, you know, we’re both also big fans of clean code, doing things – you know, software craftsmanship, all that kind of stuff. And, as we kind of grew ourselves professionally in that whole area, it wasn’t long till we, of course, realized the benefits of processes like, you know – it wasn’t called, really, “DevOps” at that time, ten years ago or something, but we identified, “Okay, continuous integration is obviously a process that any kind of – if you wanna keep moving fast, as you kinda work on a project, this is what you gotta do.”

    And so, through kind of adoption of these practices in our own company and kinda having an eye on an ambition to create a tool that other kind of developers will also find useful, we started prototyping and eventually launched Semaphore in 2012. And, from that point, it’s kind of all we do and it’s been a great ride so far, you know, leading all the way to today’s interview with you.

    Shimel: Sure. Hey, man, thank you. You know what? It’s funny; it’s not easy, but, when you ask people to tell them about themselves, you don’t wanna blow your own horn too much, but you wanna tell people what’s going. And I think you did a good job with it. So let me – before we jump into Semaphore, you mentioned something that I’ve heard from a lot of other developers, people in the DevOps space, whether they be vendors, practitioners, what have you, and that is they were doing what’s called a “DevOps-like things” before we called it “DevOps.” You know what I mean? And so were you into Agile? Was that something that kinda went with that?

    Anastasov: Yeah, I would say yes. Although I never – it was always – Agile itself has always been a bit of a vague concept for me. The first maybe introduction to that kind of thought space, for me, was the “Extreme Programming Explained,” the book by Kent Beck, which –

    Shimel: Sure.

    Anastasov: So it was more like a practitioner’s path for me, so, as you’re in development, working in small iterations, you know, you’re breaking things down, being ready to adapt to change, kind of not being married to some kind of roadmap, and so on. So it was definitely something that we identified as a good way to operate, but even before maybe the Agile backslash – I don’t know. I didn’t use the word “Agile” myself that much, but –

    Shimel: Well, you weren’t doing Scrum or taking Scrum classes and stuff.

    Anastasov: Not really.

    Shimel: But, certainly, sort of the Agile way of doing software development, right, before we called it “DevOps” or anything else, was kinda ingrained in you, if you will. So then I always – and this is something, Marko, I’ve asked other people about – so one of the unique things about DevOps is we sort of build on that Agile, we build on Lean, but, certainly, ops gets involved.

    Anastasov: Yeah.

    Shimel: When did you kinda make that jump, as sort of a programmer/developer, to say, “Hey, it’s really important we get the ops folks, the ops functionality, kinda built in there”?

    Anastasov: So –

    Shimel: And I don’t wanna put words in your mouth.

    Anastasov: Yeah, sure. So, for me, it was about – so I come from a kinda small company environment and that was kinda my beginning. And so, in that kind of setup, if you’re kind of being responsible for a product, means that you’re also responsible for the operational stuff or that there is maybe a shared responsibility among developers to some degree, but there’s always somebody who kinda specializes, at least for a specific project, for doing the operations. And there is – I think it’s very healthy, kind of, for a programmer to kinda be exposed to these things because you – as you kind of experience this firsthand, you kind of  – let’s say you’re ready to – you’re not maybe – you don’t have patience that much for things that kinda get in your way of getting the job done.

    So, if you kind of practice not repeating yourself in writing code, you wanna kind of practice the – try to practice the same thing, when you kinda deal with infrastructure. So I think that’s kind of the line of thought that brought us the kind of infrastructure-as-code, you know, kind of EDU and the movement and the tools force.

    And, once you maybe grow out of that kinda maybe very small team kinda environment, I think what you see then is you see maybe the bigger picture of, if you think of continuous delivery as a broader objective of being able to deploy anything that you’re working on at any point in time, as the ideal state that you wanna be in, then being really good at ops means that, for example, if you’re doing microservices, you’re not really that even Agile in the ’90s, maybe, way, if it takes two weeks for somebody to provision you the resources so you can just get started and write the first lines of code in your microservice. So if that can be reduced to five minutes or an hour or something, that’s really great, so.

    Shimel: Yeah.

    Anastasov: Yeah.

    Shimel: So this is something, Marko, again, back when I first started devopsy.kinsta.cloud, four, five years ago, there was this big debate over “Is DevOps different at a small company versus at an enterprise?” And, of course, there’s differences between working at a small company versus an enterprise, right? In small companies, you do wear multiple hats. You don’t have the luxury of having a full ops team and a full separate dev team and QA and business architects and all that kind of – you know, you don’t have that. Everyone pitches in and does what they gotta do, where, in large enterprises, you sometimes do have that stuff.

    And so, obviously, there’s a difference between them, but, at the end of the day, DevOps is DevOps, right? It’s about doing continuous integration, continuous delivery, and so forth. So I think that’s a – you know, what you’ve described is very not out of the ordinary. I think that’s sort of the path, the track that these things follow.

    Anastasov: eah. Yeah. I think it’s about – whether you’re coming from a small or you’re working at a big organization, ultimately, it’s all about “How do we move fast so that we just kinda of – ” the ideal state is when we’re all kind of in creation mode, all the time or as much as possible.

    Shimel: Sure.

    Anastasov: And it can happen in a small team as much as, I think, in a large team, that things can get stuck, if you maybe – I don’t know – pick the toolset that’s maybe not fit for your needs, where you kind of want to reinvent the wheel or – so I think that, regardless of maybe the team size or the technology stack, the decisions should always be kind of “Okay, what will enable us to kinda stay focused on creating value, versus kinda being maybe, in some ways, slaves to the toolchain?”

    Shimel: Got it. All right. So let’s jump in a little bit – you know, we got off on a bit of a tangent, but let’s talk about Semaphore.

    Anastasov: Sure.

    Shimel: What is it? How did that – I mean, I think you’ve given us a little background on how it came about. Talk to us what’s Semaphore about.

    Anastasov: So Semaphore is – generally, our mission is to enable teams to build great products at high velocity. And we do that by making it as easy as possible to enable continuous integration and continuous delivery processes in their organization. We’ve started way back in – about six years ago, when we launched Semaphore initially, it was like we were looking at the tools available and, from our perspective, services like GitHub or, you know – on GitHub, you do a few clicks and you get your repository; you’re ready to collaborate with other people. We looked at, for example, there were already platforms-as-a-service, like Heroku, for example, where, again, in a couple of commands, you kinda have your entire application up and running and you’re ready to kind of iterate and get something to customers very quickly.

    Shimel: Mm-hmm.

    Anastasov: But, in the area of, for example, just having a scalable continuous integration process, basically, at that point, Jenkins was the only tool that’s available. And kind of this was initially like “scratch your own itch” kind of thing, but, for a lot of people, maintaining and scaling and learning how to do all that, the infrastructure for building and testing their code isn’t really their core business purpose or where they kind of create value. So our initial goal was like, “Okay, can we create something which is as easy to use as, for example, GitHub, but for continuous integration?” so that you just kinda click to connect your GitHub account, select your repository, and we, in many cases, automatically infer what the CI build should be and kind of you’re just off the ground. You have the full continuous integration process automated and running in the cloud.

    And so, pretty soon after that, of course, listening to our customers, we implemented some features that enable continuous deployment so that customers or open-source users can keep track of releases and manage different environments. And so what’ve – throughout the years, we’ve kind of evolved from – so, traditionally, it was mostly about when people think about this space as “hosted CI,” so it’s kinda like there’s some – but, at this point, there’re a couple of options, of course, other companies doing the same function. And I think the perspective’s like, “Okay, it’s very – ” but, at this point, 2018, it’s pretty straightforward to kind of automate the testing, using some kind of a cloud service.

    But that’s not – if we go back to kind of what we also discussed in the beginning, if the goal is to accelerate kinda the entire engineering organization, there’s more to just running tests, you know? So every tech leader wants to – I mean, their objective is to deliver bug-free products to customers as quickly as possible. So we’re talking not just about testing but also configuration and delivery processes that often involve multiple technology stacks, which, of course, evolve over time. Now we have container technology, for example, which we didn’t have –

    Shimel: Changed the game.

    Anastasov: Completely changed the game. So the way to do this is to basically implement continuous delivery so that, step one, you automate all the processes and step two is to kind of optimize them, but using Semaphore for automating all continuous delivery processes has so far been – it wasn’t able to support, let’s say, every process that’s needed, so this is why, this November, we’re excited to present the brand new version of Semaphore, which is —

    Shimel: That’s Semaphore 2.0, right?

    Anastasov: Exactly. Yeah.

    Shimel: Mm-hmm. So, Marko, let me ask you this. I think you guys are pretty proud; on your website, you mention your bootstrap. You know, it’s interesting and, when you look at the CI/CD space, there’s a lot of great open-source, free tools, right? Jenkins, obviously, is the obvious one, but CloudBees, of course, has the commercial version, if you wanna call it. CircleCI, Travis – what’s the other one? – City – I forget the name of it. You and I both know there’s several pretty popular CI/CD tools, ARAs and all of this stuff. What do you think the special sauce is for Semaphore, if we’re talking – and our audience is developer-heavy, DevOps-heavy – why Semaphore versus maybe some of these others?

    Anastasov: Sure. We’ve always been focused a lot on speed, so “How can we not just provide a tool that automates something for people, but can we give them something preferably out-of-the-box, so that they just save time, comparing to whatever else they were using previously?” So one of the kind of foundational things, when you use Semaphore, is that basically we kind of periodically keep measuring this and it always stays true, is that Semaphore is twice as fast, comparing to all other competitors in the cloud space, in terms of just pure performance.

    So this alone can kinda save hours of engineering time to any team. Of course, it depends on the size of the projects and the team, but, if you kinda think back, kind of the fully-service hourly rate of developer in US is about $150.00. So, if you can do something to optimize that, we think it’s a huge win. Over time, we’ve kind of made steps forward, in terms of –

    [Phone ringing]

    Is this somebody from Jenkins calling to – [chuckles]

    Shimel: Yeah, it could be. [Laughs] That was pretty timely, but, no, I think it was something else. Go ahead.

    Anastasov: Yeah. So we provide tools that, for example, automatically paralyze the CI builds for projects, so people – which is, you know, large projects, for medium or bigger-sized teams with 100 or more developers, they typically have CI builds that run for hours. And the feedback loop – the kind of feedback loop in which you find yourself working, as a developer in such a project, it’s a pretty miserable experience. So you kind of become defensive. You work in wandering branches; you don’t merge off and – you know, you have flaky tests and so on. So, essentially, what we’ve seen, when people adopt Semaphore is, if they start using our automatic paralyzation feature, they go from, in some cases, from over 2 hours to something like 15-minute CI build. And it’s literally like they just needed to drag a slider and it worked. So we try to do things that really kind of improve the productivity of the teams.

    And so far, on the market also, it hasn’t been – in Semaphore 2.0, we’ve kinda took a lot of kinda learning that we picked up along the way and from our customers, especially the bigger customers, and, first of all, we made it really easy to create complex pipelines for companies that need to model the continuous delivery processes. On the other hand, what we think is pretty important is that, so far, this kind of cloud-based CI and CD tools – and Semaphore was part of this. In fact, we kind of initiated this idea of kind of charging per worker or per concurrent some kind of a machine that’s executing your stuff, your jobs.

    So, with Semaphore 2.0, we made the decision to kind of provide a service which is, let’s say, truly cloud, so it scales automatically to your needs, so you only pay what you use and you never really have any waiting time, which is a huge bottleneck we see in many organizations. They would maybe purchase some resources on a monthly or annual basis from Semaphore or Circle or some other product, and it’s like, if they are, let’s say, really busy in a certain period of a day or week, their CI just doesn’t process what they need. So we think that, with auto-scaling, developers will always be able to kind of get their work done quickly and stay in the zone as much as possible.

    Shimel: Got it. Hey, Marko, man, I would love to talk to you for another hour about maybe state of developers. And I do think you’re right – while speed is really important, as a benefit or an advantage to Semaphore, I think we’re in a world where developers are the top alpha predator, right? The most difficult kind of shoes to fill, the hardest jobs to get. Giving them an environment that keeps them happy, that keeps them working, if you will, in a good way, is a huge bonus than, frankly, making them work with crappy tools. I’m not calling anybody’s tool “crappy,” but I’m just saying, given the choice, I think developers would – they’d wanna work with tools that make their life easier and make it a better experience for them. But we’re at a half-hour and this was way more than 15 minutes, man, so we’re gonna need to end this. Maybe we can pick it up a second – in another chat in a couple weeks or whatever.

    Anastasov: I’d love to.

    Shimel: But, for now, we’ll call a wrap on this episode of DevOps Chat. Interesting conversation with Marko Anastasov. Close?

    Anastasov: That’s correct. Yeah.

    Shimel: All right. Cofounder of Semaphore. The new Semaphore 2.0’s coming out; check it out – great tool for CI. Until next time, this is Alan Shimel for devopsy.kinsta.cloud and you’ve just listened to another DevOps Chat.

    — Alan Shimel
  • Defining DevOps: How Do You Know When You Have Achieved DevOps?

    Defining DevOps: How Do You Know When You Have Achieved DevOps?

    Key to understanding where you are in your organization’s journey is by defining DevOps

    Much has been written about the compelling benefits of DevOps. However, the lack of a commonly agreed definition and clear prescription for implementing DevOps have left many people puzzled. Ask a group of experts, “How do you know when you have achieved DevOps?” and you are likely to get different answers.

    It is tempting to dismiss definitions as academic. However, there are many incomplete, floundering and costly DevOps implementations that fall short of expected business benefits. This article explains some of the key challenges of defining DevOps, and the importance for having a definition at least within the scope of an enterprise. This article includes suggestions to help enterprises navigate their DevOps journey toward successful business outcomes.

    Defining DevOps

    An enterprise needs to know when it has accomplished DevOps to justify investments that support business goals. Pinning down a universal definition that satisfies the diverse community of stakeholders and survives the test of time has proven elusive. DevOps spans an evolving body of knowledge covering multiple humans, process engineering and technology disciplines. DevOps is never really “done” because the highest level of maturity, “The Third Way,” continuous improvement, defies setting boundary conditions.

    To reconcile this dilemma, some have defined DevOps using vague or transient terms such as a “cultural movement.” Others have skirted the problem of definition with rambling statements describing what is involved to do DevOps, rather than state what it is in concise and concrete terms. Despite these challenges, acceptance of a definition by enterprise stakeholders is a key first step in any successful DevOps transformation. Any meaningful project progress measurements hinge on clear definitions.

    I have found the following DevOps definition useful, relatively concise, and stable: “DevOps is the application of continuous flow, feedback and improvement to people, processes and technology for the benefit of agility, stability, efficiency, quality, security, availability and satisfaction.” Defining DevOps in this way is broad enough to stand the test of time, yet specific enough to answer key questions addressed by a good definition including “What is it?” “How it is done?” and “Why do it?” without too much rambling.

    Whether you create of choose another definition, or decide to use mine, it is important that your cross-functional teams agree on one to align their goals and implementations and to have a basis to measure your DevOps progress and business outcomes.

    DevOps and Continuous Delivery Partnership

    DevOps is often said to refer to cultural aspects of high-performance software development and operations including leadership, teams and collaborative practices. Nevertheless, technical mechanisms involved in architecting applications and toolchains are essential for continuous delivery pipelines. Culture, without the technology associated with continuous delivery pipelines, will not achieve the expected benefits of DevOps and vice versa. Therefore, a practical measure of DevOps maturity really must include the technology and not only the culture.

    Continuous Flow is a Practical Baseline

    DevOps benefits are derived primarily from applying lean manufacturing methods to software development and operations. The “First Way of DevOps,” continuous flow, is first because it is a prerequisite to the Second and Third Ways. Therefore, the realization of continuous flow for at least one application in an enterprise can be considered a baseline for “having DevOps.” If you accept this point of view, then the answer to the question, “How do I know when I have DevOps” can be equivalent to the question, “What is the minimum requirement for continuous flow for an application?” In the context of continuous delivery toolchains, a continuous flow pipeline is achieved when it allows code submissions from development to successfully transit all pipeline stages to deliverable packages acceptable for production deployment.

    A DevOps Model Application

    Enterprises typically have many applications moving toward DevOps at different paces. Identifying one application as a model for DevOps is useful. The model provides a focal point for DevOps investments, and experiments. Other application product teams learn from the model application as it matures from discontinuous flow to continuous flow and higher levels of DevOps maturity.

    Summing Up

    A practical answer to, “How do you know when you have DevOps” depends on having a definition. While defining DevOps itself has been elusive, an enterprise definition is needed for alignment and progress measurement. Considering that DevOps needs continuous flow to accomplish business goals, it can be said you have DevOps when you have implemented continuous flow for at least one model application.

    — Marc Hornbeek

  • Electric Cloud Extends Continuous Delivery Platform

    Electric Cloud Extends Continuous Delivery Platform

    Electric Cloud is making available a software-as-a-service (SaaS) pricing option available for its ElectricFlow application release management and continuous delivery (CD) platform.

    In addition, version 8.5 of ElectricFlow adds support for a Kanban-style pipeline view, object tagging for custom reporting and improved searchability and a continuous integration (CI) dashboard to track and analyze build processes, failures and successes.

    The SaaS option doesn’t fundamentally change the existing Electric Cloud pricing model as much as it does provide a different location to host ElectricFlow, said Electric Cloud CTO Anders Wallgren. Pricing for ElectricFlow is still based on nodes and the number of users rather than consumption.

    The CI dashboard, meanwhile, provides organizations that have one or more types of CI platforms being employed with visibility into, for example, Jenkins, Git and Bamboo pipelines using a single dashboard. Many organizations today have multiple CI pipelines in place largely because of the preferences of individual developer teams, Wallgren noted.

    The Kanban-style pipeline also provides a mechanism for managing multiple application development projects based on a just-in-time process originally developed by Toyota that is employed to identify bottlenecks in car manufacturing. That same issue, of course, applies to software development, where the number of dependencies between various modules is increased exponentially. That issue is becoming even more pronounced as organizations move to build and deploy cloud-native applications based on various types of runtimes. DevOps teams now can approve and observe release progress and deployment status within ElectricFlow in near real time, Wallgren said.

    Finally, tagging functionality on all objects allows release managers and product owners to create more granular, real-world reports quickly and easily. Universal data segmentation replaces code-based report creation and can be applied across any object type.

    Wallgren noted that adoption of DevOps best practices generally continues to advance at uneven rates. Electric Cloud is now working closely with the DevOps Institute on an online training and certification program dubbed Electric Cloud University. The goal is to increase the number of IT teams that are exposed to modern CD processes at whatever pace they choose. Electric Cloud is making four certifications available: Build Accelerator, Test Accelerator, Administrator and Agile Master.

    Wallgren said the next major frontier when it comes to continuous delivery will be applying deep- and machine-learning algorithms to tame what has become an exceedingly complex management challenge. DevOps toolchains continuously create vast amounts of data originating from numerous tools, and machine learning algorithms can harness that data to automate a range of DevOps processes in a way that is not only makes those processes more accessible, but also easier to demonstrate how an application release meets a specific compliance mandate. To achieve that goal, Electric Cloud has been embedding more algorithms into every release cycle of ElectricFlow, says Wallgren.

    It may take a while longer for algorithms to minimize all the complexity associated with continuous delivery today. But as DevOps continues to evolve, it’s apparent that many of the manual tasks that have often conspired to limit adoption of DevOps will one day soon disappear.

    — Mike Vizard

  • HSBC Speeds Software Delivery with CloudBees Core

    HSBC Speeds Software Delivery with CloudBees Core

    HSBC Speeds Software Delivery with CloudBees Core

    HSBC’s Global Head of Digital Platform Operations, Cheryl Razzell discusses how CloudBees Core helps developers to build new products for customers and push to production more frequently.

     I see total evolution of the HSBC environment to encompass CloudBees Core and aligning the roadmaps of CloudBees and HSBC to create a platform that we can use for the future within the bank that not just sits within HSBC digital, but is used by and encompassed by the entire bank. 
    Cheryl Razzell
    Global Head of Digital Platform Operations
    [su_youtube url=”https://www.youtube.com/watch?v=eHgwJAuTIgI”]
  • CloudBees Extends CI/CD Scope, Reach

    CloudBees Extends CI/CD Scope, Reach

    CloudBees, at its DevOps World | Jenkins World 2018 conference this week, unveiled a broad strategy to extend the reach and scope of continuous integration/continuous deployment (CI/CD) platforms based on the open source Jenkins software.

    Company CEO Sascha Labourey said CloudBees Suite will provide the equivalent of a customer relationship management (CRM) application for software delivery. That approach will not only accelerate application development processes, but also provide application stakeholders across the enterprise with more visibility into DevOps processes. For example, business executives are demanding more visibility into DevOps processes as the organization begins to appreciate how dependent it is on the timely delivery of software, Labourey said.

    Rather than buying isolated components of a CI/CD platform, the CloudBees suite provides a single pane of glass through which all the elements of the platform can be managed. That capability is critical because it enables an organization to start with one element of a CI/CD platform that, over time, can be expanded frictionlessly as the organization becomes more comfortable with DevOps processes.

    Labourey said it’s clear the CI/CD platform is the hub around which those DevOps process revolve. The CloudBees Suite includes CloudBees Core to unify the management and governance of pipelines, which includes limited availability of the Kube CD for extending the CloudBees platform to Kubernetes clusters. In fact, Labourey noted that Kubernetes is rapidly emerging as the foundational element of a federated approach to CI/CD in the age of microservices.

    CloudBees also announced an alliance through which Lenovo will provide IT organizations a turnkey set of servers running instances of CloudBees Core on the Red Hat OpenShift application development platform. As DevOps continues to evolve, Labourey said, organizations want to reduce the amount of time it takes their IT teams to deploy the infrastructure required for a modern application development platform.

    Another core element of CloudBees Suite is CloudBees DevOptics, a software-as-a-service (SaaS) application that provides visibility and insights into value streams and operations as well as continuous reports on the four key DevOps metrics. CloudBees DevOptics will provide the raw data the company will rely on to apply artificial intelligence (AI) in the form of machine and deep learning algorithms to the CloudBees CI/CD platform, Labourey said.

    The two remaining core modules of CloudBees Suite are CloudBees CodeShip, which enables organizations to jump start projects using a CI/CD as a Service offering, and CloudBees Jenkins Support, which provides users of the open source Jenkins platform full support. CloudBees is also making support for instances of Jenkins available as a standalone subscription service.

    It’s clear that CloudBees is trying to extend the reach of its widely employed CI/CD environment not only to new platforms, but also to new users. As digital business processes continue to proliferate across the enterprise, there is now a lot more at stake whenever an application development project is delayed. While such delays may be inevitable, the degree to which organizations might be surprised by those delays can be reduced sharply when everyone in the organization is operating on the same DevOps page.

    — Mike Vizard

  • Continuous Discussions, Episode 90: Gene Kim and DOES18 Speakers

    Continuous Discussions, Episode 90: Gene Kim and DOES18 Speakers

    In a recent episode of the Continuous Discussions (#c9d9) podcast, we hosted Gene Kim and several speakers from the upcoming DevOps Enterprise Summit Las Vegas (DOES18) conference. We’re proud Founding Partners of the event and always enjoy having IT thought leaders join us ahead of the show to talk about DevOps, the conference program and more. In this episode, we discussed an emerging conference theme of next-gen operations and infrastructure.

    The panel of DOES18 speakers included: Cornelia Davis, senior director of technology at Pivotal; Damon Edwards, co-founder and Chief Product Officer of Rundeck; Mik Kersten, CEO of Tasktop; Tom Limoncelli, SRE at StackOverflow.com; Gene Kim, founder of IT Revolution and co-author of “The DevOps Handbook,” “The Phoenix Project” and “Accelerate”; and Electric Cloud’s Sam Fell and Anders Wallgren.

    Continue reading for some of the top takeaways from the discussion!

    Next-Generation Operations: Programming and Insights

    As we continue to evolve, the best is yet to come for operations teams, per Kim: “If we follow the course of what the development languages and development frameworks have done for development productivity, and extend that to operations, I think the best time for operations and infrastructure and platforms are to come.”

    Davis encouraged operations teams to treat their platform like a product instead of infrastructure: “When I speak with the IT operations folks, they’re still largely short order cooks. They’re very reactive, doing things that people need them to do. It’s about being able to apply some of the same principles of continuous delivery to the way that you do ops. At the core of that is this philosophical notion, which is to treat platform just like you treat any other product.”

    The way enterprise operations teams do work is unique, per Edwards: “For enterprise operations, you have to fundamentally rethink the conventional wisdom of how you think about, approach and do operations work. DevOps Enterprise Summit started in the early days of the DevOps explosion. This is distinctly an enterprise discussion because it’s all about that history of success that we have to account for.”

    Kersten on the different ways development and operations teams measure outcomes: “I so often see the development side of the organization and the infrastructure operations side collecting completely different metrics and telemetry. The development side uses the more familiar telemetry that comes from DevOps. And the operations side is still in a burnup, burndown world. There are no common metrics or languages for what really should be an internal value stream.”

    Great operations management advice from Limoncelli: “Get one team to do it well, and let people copy that success. And do it in a way that creates cultural minimums or cultural ways of doing things, so that people are competing to make things better instead of being told you have to make this change.”

    Moving away from legacy operations is a dauting challenge especially for the enterprise, explained Wallgren: “The things that we refer to as legacy are the things that keep the lights on and bring the money in. It’s a big leap to move away from that and it’s going to take a lot of work and quite a lot of time. It’s like changing the engine and tires on a car while you’re driving down the highway at speed.”

    Functional Programming, SREs and More Musings

    Davis on functional programming, something she will be talking in-depth about at DOES18: “Treating function as a first-class citizen is absolutely essential because you start to create these functions very dynamically, and the functions now encapsulate the state. So instead of having state and then having side effects against a state, what we have are these functions encapsulating a sequence of changes that are going to generate a state.”

    Kim described an “aha” moment he had during Davis’ talk at DOES18 London about sidecars in Kubernetes: “The ability to liberate developers and address cross-cutting concerns like logging was one of the primary impetuses why people flocked to Spring from orthodox frameworks that were so unsatisfying. And that was, for me, that was one of the biggest aha moments of the conference.”

    Edwards discussed the implications of toil work and how to spend more time doing things of value: “Toil work is work that we should have automated, it’s repeatable, and not adding enduring value to what we’re doing. Versus work that requires human ingenuity, the engineering work that adds enduring value to our organization. Set a limit as an organization to not accept more than 50 percent of time being consumed by toil and figure out how to help those organizations where they have too much toil and not enough engineering work.”

    Most organizations don’t have $2.5 billion in their back pocket to build a product-oriented value stream, but Kersten said we should take a page from their book: “This is a testament to how invested the tech giants are in their own platform as products. If we don’t at least adopt their thinking around having this connected end to end platform that supports all your products and value streams, you’re just not on the right path.”

    Limoncelli on the ability of SRE’s to reach across silos: “In the SRE model, you can reach across silos. I like to think of it as you have the CICD pipeline and the SRE’s stand at the end of the pipeline asking, ‘What are the operational problems that we’re having? What’s the constraint? What’s the bottleneck?’ They fix that by asking how they can collaborate with the other team within our organization. And either sit with them for a week and fix it or collaborate with them to fix the problem.”

    Wallgren elaborated on treating pipelines as code: “Treating your pipeline as code is something we’ve been evangelizing. And really, that should be the first thing that you really worry about in some sense, because you’re not going to ship anything unless you have a pipeline.”

    The DOES18 Las Vegas agenda is now live! Check out the sessions from Davis, Edwards, Kersten, Limoncelli, Wallgren and dozens more. Tickets to DOES18 are running low, so be sure to register before it’s too late.

    Watch the full episode:

    — Anders Wallgren

  • VMware Extends DevOps Reach via SaaS Apps

    VMware Extends DevOps Reach via SaaS Apps

    VMware, at the VMworld 2018 conference today, announced it will be delving deeper in the realm of DevOps with the launch of a continuous delivery pipeline dubbed Code Stream.

    In addition, VMware announced Cloud Assembly, a set of declarative tools that enable IT organizations to spin up a cloud in as little as 10 minutes by managing infrastructure as code, and Service Broker, a catalog through which services residing on multiple clouds can be published, governed and secured.

    Milin Desai, vice president and general manager for the Cloud Services Business Unit of VMware, said these offerings extend the reach of VMware’s Cloud Automation Services that are all invoked as software-as-a-service (SaaS) applications.

    VMware also today announced a beta release of Secure State, a set of tools for tracking security alerts across Amazon Web Services (AWS) and Microsoft Azure that also can be used to investigate when changes to those environments were made. Secure Slate is based on the technology the company gained by acquiring CloudCoreo earlier this year. What’s more, VMware is updating the Wavefront by VMware monitoring service to add support for deeper support for containerized workloads running on Pivotal Kubernetes Service (PKS). Wavefront also now supports the Amazon Lambda serverless computing framework made available by Amazon Web Services (AWS).

    Code Stream is designed to track code across multiple platforms and comes with pre-built plug-ins for Wavefront, Harbor, Nexus, Pivotal Kubernetes Service (PKS), Ansible and Slack. VMware is also committed to providing integrations with continuous integration/continuous deployment (CI/CD) platforms such as Jenkins, Desai said.

    VMware has previously made extensive investments in software-defined data centers (SDDCs) based on a layer of management software deployed on top of VMware vSphere. As part of that effort, VMware today announced version 6.7 of VMware vSphere, which adds tools for verifying the state of a virtual machine, and a new Platinum edition of the platform that includes VMware AppDefense, to secure application workloads running on VMware vSphere.

    Beyond the virtual machine level, the scope of VMware’s DevOps portfolio has been limited. By adding a range of DevOps tools that are made available as SaaS applications, VMware now can provide tools spanning just about everything, from cloud orchestration to code delivery, Desai said.

    The expanded push into DevOps comes at a time when VMware is also extending the scope of its alliance with AWS. The company earlier this week announced it has lowered the cost of entry of VMware for AWS by 50 percent for a limited time and is making available a three-node configuration option. Previously, VMware required customers to set up a minimum four-node configuration. VMware will enable IT organizations to configure a three-host software-defined data center (SDDC) for the cost of two hosts.

    The company is further helping to reduce costs by make it possible for IT organizations to also specify the number of processor core counts for Oracle and Microsoft applications running on AWS, along with new options for deploying NSX network virtualization software.

    It’s unclear to what degree VMware will be able to leverage its historic strengths in server virtualization to become a significant force in the realm of DevOps. The acquisition of Wavefront in last year was clearly a significant step in that direction. But the individuals with an IT organization who decide what virtual machines to employ are not necessarily the same individuals selecting DevOps tools. VMware is clearly hoping that as more IT organizations embrace DevOps processes spanning multiple clouds, many more of them will view the company’s growing portfolio of SaaS applications as a natural extension.

    — Mike Vizard

  • Choose Your Toolstack — and Manage It — Wisely

    Choose Your Toolstack — and Manage It — Wisely

    Every DevOps toolstack has a control point, be it a bus, an app, a management app or whatever. Something always is in control and driving the other pieces of the architecture to do their part. It is a basic tenet of automation that jobs are mostly kicked off by something in the software hierarchy.

    In DevOps, most of us have defaulted to Jenkins for a large chunk of that automation. It was the center of the continuous integration/continuous delivery (CI/CD) side, and increasingly it is used to run both sides of DevOps (as I have called it previously, both DEVops and devOPS). CloudBees and recognized this trend, and an increasing amount of control and process functionality has been turning up in Jenkins.

    On the other side, there are organizations running all of devOPS from deployment tools such as Ansible or Puppet. Again, that’s not a terrible solution, since they can configure the software on the server and make sure all is ready to run.

    But neither of these toolsets was originally envisioned with the idea it would control as much of the DevOps stack as they currently do.

    If you read me regularly, you know I’m not a huge fan of this type of default control structure. There is a lot of functionality that can be laid over the CI/CD and environment automation tool. But to do some of it, the tool needs to be above the day-to-day functionality these tools specialize in.

    ARA can do it—and honestly, for a first brush at connecting the worlds represented by CI/CD and configuration management tools, is pretty impressive. Other vendors have come at it from a service bus perspective, allowing everyone to communicate through their tools and doing roll-up reports based upon what has been integrated. That’s not a terrible solution either, if it works with or can be made to work with your tools.

    ARA as a market is short on the monitoring and management end of the process when the app is deployed and clipping along. It’s getting better, and hopefully ARA that is fully integrated with monitoring tools will be the next step in this evolution, but for now most companies are handling tooling, monitoring and response to that monitoring outside of the ARA system.

    The queue systems tend to lag behind ARA in their ability to correlate and coordinate, but again this is getting better. They know only what is reported through them, so as they gain add-ons, expect they’ll handle the overall stack better.

    The long-term goal is, after all, to run from commit to release with only designed “go/no-go” checkpoints involving humans, and then to monitor, with humans getting notifications only as needed. How we get there may not be so important—or it might.

    In the market, the sand is still shifting too fast for vendors to keep up. In any given implementation, how fast you adopt all the new products is a function of choice. Use controlled chaos, changing things out for the better only when you have a quantifiable benefit and they fit into your overall architecture. Most importantly, no matter which toolset you choose to use to control the check-in-to-release cycle, new tools you introduce should integrate with it.

    So what am I recommending? That you choose a control tool that fits your specific environment and needs, and that you make certain when choosing new tools you have a path to get them integrated with that control tool. Nothing more. Don’t put a tool in charge of half or all of your DevOps toolstack just because it was there. Have a real reason, then use that reason as a gauge when adopting new tools.

    — Don Macvittie