Category: Blogs

  • A New DevOps Test Environment Platform is Needed

    A New DevOps Test Environment Platform is Needed

    Test environment management is bottlenecking DevOps transformations and is driving the need for a new test environment management platform solution. On-demand test environments in which developers and testers do not have to wait for a shared environment are sorely needed.

    The evidence is clear. In my book Engineering DevOps I indicated that finding and setting up test environments is a primary source of bottlenecks in DevOps value streams.

    In my February 2021 webinar with Plutora, I presented Best Practices for Developing Test Management Environments. I indicated that orchestrating and managing test environments is often a primary source of delays and waste within value streams.

    The State of Testing Report 2020 by PractiTest indicates that DevOps practices increased 57%; from 26% in 2017 to 41% in 2020. The report revealed that 46% of testing has shifted to using CI/CD processes, 55% are actively involved in shifting testing left and 36% are testing in production. This is clear evidence that DevOps testing is on the rise.

    Wolfgang Platz’s December 2019 article Why Software Testing Remains a Bottleneck indicates that testing is responsible for more delays than any other part of the development process – accounting for 52% of the bottlenecks in the development process. And  53% of respondents to the World Quality Report 2020-21 indicated that test environments are not available when needed, 67% lack the capability to book and manage test environments and 71% lack visibility of available test environments.

    An article by Velocity echoes the problems with pre-production environments. “With the rise of microservices and cloud-native applications, environments are becoming more complex. Often you need to wait or compete to get access to develop on a specific microservice, or can spend time waiting to deploy to a shared staging environment only to realize something already changed, and you’re back to square one.”

    The Continuous Testing Report – 2020 by Capgemini defines test environment management (TEM) as managing infrastructures, test data and applications to support testing on demand. These environments are one of the greatest impediments to continuous testing. In this report, 36% of respondents said they are spending more than half their time building and managing test environments; 44% of respondents indicate they spend weeks of their time searching, managing and generating test data.

    Test environments should be regarded as functions to be spun up or destroyed at will, with virtualization, infrastructure-as-code (IaC)  practices, service virtualization, containerization and improved test data management.

    Given all the above evidence, it is clear that a new approach to DevOps test environment management is needed.

    The following are examples of benefits that DevOps test environment management platforms need to offer:

    • Compatible with current tools:
      • Automatically map and configure application infrastructure to develop and test multiple services in an environment that runs just like it would in production. This needs to be fully agnostic to cloud and tech stacks, such as Kubernetes and other environments.
      • The platform needs to work on applications in parallel without disrupting others, with full access to data and third-party dependencies.
    • Automatic configuration and maintenance:
      • The platform needs to automatically configure and update any changes within the production infrastructure’s mapping in real-time so ephemeral environments will always be synced with what is in production. Instead of having to spend time making sure any changes are configured, the platform will ensure the right environment that replicates production, without having to wait.
    • Data and third-party dependencies:
      • The platform needs to load the relevant data and third-party resources that are vital parts of the environment to test, work and debug against, so test environments will, as closely as possible, mimic working in production.
    • Team collaboration:
      • The platform needs the capability to share ephemeral test environments with other stakeholders so they get visibility and can collaborate for faster feedback cycles. This is also important for collaborating for debugging.

    What This Means

    DevOps testing is on the rise, and test environments are a major bottleneck for DevOps testing. A new DevOps test environment management platform is needed to reduce the bottlenecks. On-demand test environments in which developers and testers do not have to wait for a shared test environment are needed. Such a solution would improve agility and reduce wasteful orchestration bottlenecks in test, improve quality and risk management through comprehensive and automated testing and enable continuous improvement by providing more intelligent insights and feedback.

  • Dependencies in Cloud-Native Apps can Amplify Risks

    Dependencies in Cloud-Native Apps can Amplify Risks

    Hidden Dependencies in Cloud-Native Apps can Amplify Security Risks

    Cloud-native applications and modern development practices result in applications that are highly distributed and loosely coupled. In many cases, organizations have no control over or little insight into the different elements and software entities they use in their applications. The result often is hidden dependencies that can impact performance and add to security risks.

    The New York Times noted an example of the consequences of hidden dependencies. The article cited the work of researchers who observed that the quality of weather forecasting models declined as air travel dropped off during the pandemic. One might easily conjecture there was a physical cause and effect. Jet engine exhaust includes water vapor, soot, carbon dioxide, unburned fuel, and several oxides. Perhaps the diminished amounts of these particulates due to fewer commercial flights had some impact on lower stratospheric dynamics.

    It turns out that was not the case. The article reported that researchers found “that when a short-term forecasting model received less data on temperature, wind, and humidity from aircraft, the forecast skill (the difference between predicted meteorological conditions and what actually occurred) was worse.”

    Atmospheric observations made by instruments on commercial and cargo planes are “among the most important data used in forecasting models,” according to the article. The measurements are transmitted in real-time to forecasting organizations around the world, including the National Weather Service.

    The pandemic resulted in fewer flights. So, there was less or no data. A prediction’s degradation due to this data disruption not only impacted the primary forecasting application but had many downstream implications. For example, these short-term forecasts are used by many industries (logistics, agriculture, entertainment, public safety, and more) to make business decisions. Hence, the degradation of performance in that one application due to previously unknown dependencies could propagate to third-party apps that simply relied on the output of this one app as input for theirs. In a sense, this particular dependency (fewer observations leading to poorer quality forecasts) becomes yet a different hidden dependency in many other applications.

    Security implications

    As this example illustrates, small changes in complex systems can have unexpected application performance impacts. They also can impart unintended security problems.

    At the heart of the issue is the fact that today’s cloud-native applications are complex systems. And security in cloud-native systems can be impacted by small changes.

    It might be something as simple as reusing a component whose original permission setting gave a development team broad access to certain data for testing purposes only. With software component reuse being quite common, that point may be forgotten at some point, and the code might be made available to other groups. Those groups may just want anonymized records in that database or a subset of data that did not include records that should remain private. Use of that code in a larger cloud-native app for such purposes would not necessarily expose the data. But someone might discover the mistake later and exploit it.

    Another aspect of cloud-native application security is that many modular elements are linked together via APIs and microservice calls to form a larger application. Those software elements (be they open-source or commercial) often have security flaws.

    A report last year by the Laboratory for Innovation Science at Harvard and The Linux Foundation highlighted this issue, noting the need for an “understanding and addressing of the security complexities in the modern-day software supply chain.” With frequent reuse of components, even if a known vulnerability is taken care of with a patch, the problem may not be eliminated. Someone needs to know that piece of code is in a distributed cloud-native app, that there is a patch for the vulnerability, and that the patch was applied.

    Any small flaws like this can have a larger negative effect on the security of the entire cloud-native system.

    What’s needed

    The reliance on open source and third-party code in cloud-native applications requires that security be entrenched throughout an application’s lifecycle. It is no longer enough to test for vulnerabilities after the fact. Third-party or open-source code used in any one element of a larger application might be changed at any time. If a vulnerability is introduced, a developer might not know of it.

    The inter-dependent nature of discrete code working together in a vast cloud-native app thus requires a new take on security. The constant refreshing, updating, and replacement of applications dictate that security must be an integral part of the entire lifecycle of an application. As such, companies must bring security into the application lifecycle just as DevOps does for development and deployment.

    To find these impacts, stay ahead of them, and react effectively and efficiently when they show up, developers and companies need a deep understanding of the context of their systems and how all the parts work together. Just as the pandemic-related downturn in commercial flights impacted the accuracy of forecasting models, so to can a seemingly unrelated (or unknows) security flaw in one part of a cloud-native application impact the entire application.

    To avoid such problems, a DevSecOps approach is increasingly needed to find weaknesses and vulnerabilities due to hidden dependencies in today’s applications comprised of many interconnected parts.

  • Establishing Trust in Multi-Cloud Environments

    Establishing Trust in Multi-Cloud Environments

    Modern applications are transforming enterprises into digital innovation factories. However, the distributed nature and complexity of modern apps have made it extremely difficult for organizations to maintain trust and compliance across multi-platform, multi-cloud environments. 

    Although Kubernetes is the standard for application platforms today, each cloud service provider (CSP) has a different offering for infrastructure-as-a-service (IaaS) or their own platform-as-a-service (PaaS) with varying capabilities and APIs. Not only are these APIs incompatible (with the exception of Kubernetes if no vendor extensions are used), each infrastructure and platform are treated and managed in silos. These silos act as an isolated and non-overlapping administrative boundary,  preventing cross-boundary visibility and trust between microservices.  This makes it much harder for enterprises to know and consistently remediate their security posture across clouds and platforms, opening them up to attacks.

    To solve this problem, organizations are extending enterprise security controls to cloud environments. The problem is that application teams and security teams have traditionally had competing goals—agility versus risk and control—and security operations have not evolved at the same pace as application operations. This creates friction between the teams and forces application operation teams to make a choice: 

    1) Slow down application delivery and operations to reduce risk and miss out on the transformative benefits of multi-cloud or 

    2) Continue to develop and ship applications as quickly as possible without considering security and compliance. 

    Neither is a good option. To unlock the power of modern applications running in multi-platform and multi-cloud environments, organizations need to find a way to integrate security seamlessly throughout the software delivery life cycle at the speed users expect.

    Integrating Zero-Trust into the Application Delivery Cycle

    The key to securing applications in a multi-cloud world is zero-trust. Building zero-trust principles directly into modern applications allows organizations to identify threats early, reduce attack surfaces and ship security functions alongside the rest of the application stack—regardless of the underlying application platforms and cloud stacks underneath.

    In this use case, one of the key components of zero-trust is application segmentation; in other words, how to make access decisions between different applications or components of applications. Zero-trust must provide identity-aware, adaptative and on-demand access to any app from any user or app in a way that improves the flexibility and the agility of application access through a scalable model.

    Application segmentation must be provided to application operation teams so that they can embed it into their application quality processes as another gate. Application operation teams can do this by implementing application segmentation policies that identify workloads as they are created through rich, dynamic attributes. The more intrinsic/static attributes (IPs, digital certificates, namespaces, labels, etc.) and extrinsic/dynamic attributes (user behavior, workload behavior, network behavior, etc.) that are identified, the more fine-grained your access decisions can be. 

    Incredibly, application segmentation today continues to be done manually. But with millions of transactions happening across multiple cloud environments, there’s no way a person—or even a team of people—can manually assign policies to each workload. Organizations need a way to deliver zero-trust application segmentation in a scalable, transparent and automatic fashion. 

    A Connectivity and Security Platform 

    The way to do this is through the use of a modern application connectivity and security platform. Through a service mesh, an attribute-based access control (ABAC) model consolidates multiple third-party tools that provide visibility and security across application platforms and multi-cloud environments. This single view operational model gives application teams the ability to seamlessly and simply orchestrate security services across multi-cloud environments, automatically and at scale. 

    Unfortunately, granular policy management through microsegmentation increases complexity, which is the enemy of security. Suddenly, an organization may find itself with thousands of policies that dictate how different workloads access and interact with entities inside the network. These policies need to be continually updated and maintained, creating massive headaches for both application and security teams.

    When a workload is deployed, the associated policies are created along with it and move through the environment with the workload until the workload reaches the end of its life and is decommissioned. As applications run over time, they are being characterized by their unique behavior. This runtime security characterization allows policies to be automatically selected and applied directly to the workload.

     However, for a service mesh to work and enable secure applications in a multi-cloud environment, it needs to follow zero-trust principles without adding complexity and without slowing down the agile delivery cycle. Here’s how you do that:

    1. Baselining trust: A modern app connectivity and security platform should have native observability and self-discovery capabilities, such as being able to automatically discover APIs, catalog APIs and generate API documentation based on the OpenAPI standard. The modern app connectivity and security platform should be able to continuously baseline application behavior and detect anomalous application behaviors. This needs to alert on unknown and zero-day attacks, especially exfiltration of sensitive data.
    2. Establishing trust: It is critical to define the interconnectivity needs of different pieces of the application right off the bat. This explicit declaration of intent is typically done manually by application teams during the deployment of the application as part of a CI/CD pipeline. Another option is to automatically discover the connectivity intent during the testing phase of the application and allowing the service mesh to identify and record the resulting communication flows between microservices’ APIs. These are the basis of the application’s segmentation policies.
    3. Enforcing trust: There also must be a mechanism to automatically apply the appropriate application segmentation policies to enable the necessary communication for the application to run as intended. In the microservices model, different pieces of the application are spun up and down dynamically to enable the application to run as intended. It’s critical that the application segmentation policies that govern accessibility also adapt to these changes. This is done through the service mesh control plane that interacts with the application platform to gather the inventory of workloads.
    4. Dynamically adjust trust: As the applications run over time and clients interact with them, they are being characterized by a behavior. In this case, a security behavior. Observing this behavior can be accomplished through various runtime analysis tools that organizations already have in place that detect process, container, network and user behavior to provide security context. However, to maintain trust, there needs to be a way to integrate these tools through the service mesh to create a single source of truth. 
    5. Extending the trust model to the edge: Applications also interact with software-as-a-service (SaaS) platforms such as Salesforce or SAP, and other apps outside the data center. Ideally, the service mesh/zero-trust application segmentation model can integrate with other security solutions in the cloud such as secure access service edge (SASE), secure web gateway (SWG), cloud access security broker (CASB) and other zero-trust security components. This standardizes the processes for establishing trust across the data center, multiple cloud service providers, SaaS platforms and web apps—ensuring consistent security and compliance posture across the entire organization.

    Modern applications are transforming how business works by enabling agility and real-time decision making, but they will never reach their full potential unless application teams work with security teams to protect users, data and applications in multi-cloud environments. It’s clear that organizations need an evolved security model that application teams can use to seamlessly establish trust and orchestrate application segmentation across multi-cloud, multi-platform environments. Service meshes can provide the visibility and control needed to establish and continually evaluate trust.

  • 5 Steps to a Seamless Multi-Cloud Migration

    5 Steps to a Seamless Multi-Cloud Migration

    With digitization the topic of discussion in almost every boardroom since the onset of COVID-19, it’s no coincidence that migration to the cloud has skyrocketed in tandem. In fact, at the onset of the pandemic, 87% of IT decision-makers noted that the remote restructuring of the workplace would push their organizations to accelerate cloud migrations.

    That trend shows no signs of slowing down. In fact, Gartner predicts that cloud spending will increase by 23% in 2021 to reach $332B. Driving this historic shift is the adoption of multi-cloud infrastructures. Businesses are increasingly separating and distributing their data flows and critical functions across multiple clouds from different service providers. According to Flexera’s 2021 State of the Cloud Report, an overwhelming 92% of enterprises say they now have a multi-cloud strategy, and 82% say they have a hybrid cloud strategy.

    There are many reasons for this increase in adoption. Developers that use containers, for example, can test their applications across multiple systems in the multi-cloud environment to speed up innovation, due to containers’ agility and portability. This use of multiple clouds also allows businesses to tackle cloud migrations in a more measured and deliberate manner rather than a ‘big bang’ approach.

    What this also means, however, is that it multiplies IT’s stress as they deliberate the benefits, costs and risks of moving their business to a multi-cloud strategy. For example, they must consider whether or not to keep their data on-premises, migrate it to a public cloud or some combination of both. They must also ensure their application’s ironclad security, which has become a mission-critical consideration during the unrelenting cybersecurity emergency that is the pandemic. Meanwhile, they may worry that such a large-scale cloud migration will result in lost revenue and increased downtime.

    With these key considerations and challenges in mind, here are five tips to help enterprises seamlessly migrate their resources to a multi-cloud environment.

    Assess Your Application’s Ripeness

    Before any application is migrated, it’s necessary to do a complete audit of current applications to assess their readiness for the migration. Businesses should look at the application’s dependencies and the ecosystem it lives in. This ecosystem could be its physical and virtual network infrastructure, including configurations, policies, load balancers, security and compliance requirements.

    Plan and Prepare

    This is a particularly challenging phase, as IT teams often linger here; wasting valuable hours and productivity. Therefore, the entire organization must outline what their migration journey will look like, discuss which departments will be affected during the process, and delegate responsibilities to facilitate a smooth transition to the cloud. The IT operations team, the development and quality assurance teams, key stakeholders and leadership should all be involved in these discussions—and should share the goal of ensuring a predictable migration process.

    Carefully Weigh Your Cloud Options

    Choosing the right cloud depends entirely on the unique needs, challenges and opportunities for the organization. While there are a number of different providers available to every enterprise, the best option will be influenced by financial constraints, goals for cloud adoption and even the systems already in place.

    Of course, when a business is taking a multi-cloud approach, these decisions become that much more difficult—especially in light of the fact that the average cloud company uses 2.6 public clouds and 2.7 private clouds, according to the Flexera report. Connectivity between these providers is crucial, with 88% of businesses enabling their multi-cloud strategy with a private connection.

    With this in mind, it’s also absolutely vital that decision-makers consider the security risks associated with each provider, as well. The number of cyberattacks on enterprises’ cloud infrastructures has increased significantly since the onset of COVID-19. With the stakes so high, a migration partner can help businesses assess which cloud providers are the right fit for them; accounting for their cost-effectiveness as well as which options will pose the least friction for the migration.

    Construct Your Migration Checklist

    The migration of an enterprise’s workloads is the most critical step of its cloud journey, and every company’s objective is to make a move swiftly and seamlessly. Creating a checklist can help businesses achieve this goal, as it helps them to prioritize the most critical components of their journey and understand the repercussions of a stagnant or inefficient migration.

    For example, every business should aim to achieve minimum downtime during their migration process and little to no disruption of service. Both the loss of network access and system downtime can cause immediate pain in the form of lost productivity and opportunities and even more harmful damage to a company’s brand. In fact, according to Gartner, the average cost of IT downtime is $5,600 per minute, meaning a well-practiced and efficient migration strategy has a significant impact on a company’s financial health.

    Since each migration is unique to the business and, often, unforeseen challenges arise that are native to the environment, it’s beneficial for organizations to have an expert migration team or partner to help them develop their checklist and ensure their migrations are streamlined and airtight.

    Validate Your Cloud Journey

    As the final step in a business’ migration journey, companies must validate that all their resources from their previous environment are fully migrated and operational in their target cloud environments. This step is crucial, as it marks the completion of a successful multi-cloud migration journey! This is primarily a manual process ensuring that nothing is neglected or forgotten and is often followed by an entire testing lifecycle.

    Post-Migration Pointers

    Cloud migrations can be complex, especially for companies relying on a years-old traditional and highly manual approach. Thankfully, in the age of automation, enterprises today are experiencing substantial time and cost savings and deploying migration strategies that move their workloads across multiple clouds in seconds instead of days.

    But even when an organization’s migration journey is complete, the management of several clouds at once creates its own set of challenges and risks—especially true in today’s landscape of skyrocketing climate and cybersecurity risks. It’s therefore vital that business leaders heighten their focus on organizational resiliency and minimizing downtime through things like tightened security and effective disaster recovery strategies.

    After all, with hybrid work forcing C-suites to scale their digital transformation plans even further, it’s becoming increasingly clear that the future of work is in the cloud. It’s therefore imperative that as cloud spending soars, enterprises allocate substantial resources not only to migration and management but protection, too.

  • EP 16: How DevOps has Changed Testing Forever

    EP 16: How DevOps has Changed Testing Forever

    DevOps has changed the game in almost every aspect of testing: who, what, when, where and even why. What’s working, what needs to change immediately, and what challenges—and opportunities—lie ahead?

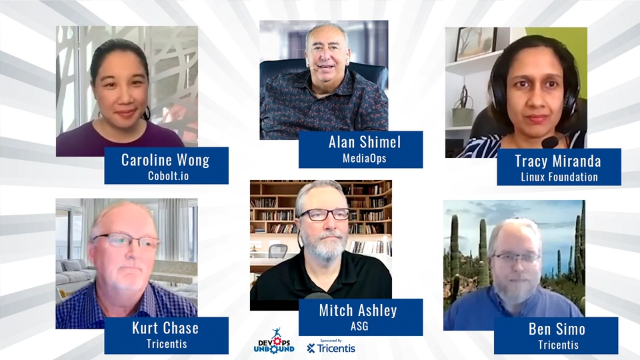
    In this DevOps Unbound episode, hosts Alan Shimel and Mitch Ashley are joined by Abel Wang from Microsoft, Tracy Miranda from CDF, Caroline Wong from Cobalt, Kurt Chase and Ben Simo from Tricentis to share a variety of perspectives on how testing fits into the ever-evolving world of DevOps. The video is below, followed by a transcript.

    DevOps Unbound is sponsored by Tricentis, the world wide leader in automated testing. DevOps Unbound airs biweekly on TechStrong TV, with all episodes available on Digital Anarchist. There is also a live monthly roundtable open to audience participation.

    Alan Shimel: Hey, everyone. Thanks for joining us on this special edition of DevOps Unbound. You’re watching this, probably, at the Tricentis Virtual Event and we are happy to have you join us, happy that you’re attending the event, and we’ve got what we think is gonna be a great discussion on testing and all of its various facets and what does the future – or near future – hold. We’ve got a great lineup of speakers that I’d like to introduce you to who are on our panel today. Let me first start with – she’s on the top of my screen – is Caroline Wong. Caroline, why don’t you say, “Hello” and introduce yourself?

    Caroline Wong: Hello. My name is Caroline Wong. I’m the Chief Strategy Officer at Cobalt. So, at Cobalt, what we do is pen testing as a service. We build a security software platform – like a lot of DevOps companies.

    We have data-driven product-based teams. We have – we really value automation and failing fast. I’ve spent 15 years in the information security industry. I wrote a book called Security Metrics. I host a podcast called Humans of InfoSec, and I teach the OWASP Top 10 Learning Path on LinkedIn Learning, and super excited to be here with this group today. Thanks for having me.

    Shimel: Thank you, Caroline. Next up, we have Kurt Chase.

    Kurt Chase: Hey, everyone. I’m Kurt Chase. I’m currently Head of Release Management and Engineering Services at Tricentis. Engineering Services is a group that supports the engineering function so, we do our own type of testing – testing all the processes and everything we use – to deliver our software at Tricentis. So, prior to Tricentis, I spent some years at Splunk and at AutoDesk. It’s great to be here with all of you today.

    Shimel: Fantastic.

    Chase: Be here today with all of you.

    Shimel: We got what you meant, Kurt. It’s okay. Next up, we have Ben Simo. Ben, why don’t you introduce yourself?

    Ben Simo: Hi. I’m Ben Simo. I’m a software tester of 30 years and past president of the Association for Software Testing who has recently stepped into a product management and product research role at Tricentis trying to discover and develop our testing platform of the future and bring new things to Tricentis customers and hopefully introduce new people to Tricentis with new products that enable new ways of testing.

    Shimel: Okay. Happy to have you here. Next up, Tracy Miranda. Tracy – well, I’m gonna let you introduce yourself. Go ahead.

    Tracy Miranda: Hi, everybody. I’m Tracy Miranda. I’m the executive director at the Continuous Delivery Foundation. It’s an open source organization that’s part of the Linux Foundation, and also home to projects to like Jenkins and Spinnaker, and our members include companies like Netflix and Google. And I have over 20 years of experience in open source so, I love open source and I’ve worked in it as a developer – also in QA and all different facets. So, yeah. Big fan.

    Shimel: Thank you, Tracy. Last, but not least, is my co-host on DevOps Unbound – my partner in crime here, Mitchell Ashley. Mitchell, why don’t you introduce yourself?

    Mitch Ashley: Thanks, Alan. Yes. I’m CEO of Accelerated Strategies Group, which is an analyst firm that focuses on, in addition to cyber security, digitial transformation, DevOps, and cloud-native kinds of applications, which really matches my background very well. I’ve been both a product creator CEO/CTO as well as running IT, CIO, CSO – that kind of thing. So, currently, I’m also CTO with MediaOps – I guess CSO at MediaOps, too, so, I’m trying to collect as many three or four-letter titles as I can. So far so good.

    Shimel: Alrighty. So, first of all, thank you all for coming on today. Secondly, testing – what a wild, mixed-up world we have in testing, right? Just from looking at the folks on our panel today, we have security testing – pen testing, in particular. We have the world of open source and what a factor that is in testing.

    We have product testing, right? We have sort of new product testing – taking testing to new heights. And you know, that variety is sort of a double-edged sword, right? Because it’s like jack of all trades, master of none type of thing. There’s so many aspects of testing, right?

    Even in our audience here at this virtual event, we have testers who come from, you know, what’s called old line QA testing, right, to DevOps enabled testing to visual testing – testers who, if it’s not an open source testing platform, they won’t use it, to proprietary systems. Through it all, though, a lot of times, all of this testing becomes sort of a red-headed stepchild or a whipping boy, if you will, right, to the whole application development system operations teams. It’s like, at the same time, their best friend and their worst enemy, right? They want everything tested, but they don’t want to give you the time, the budget, or the resources to do it, and then, when something doesn’t work, they said, “Well, we should have tested more, right?” So, how – first of all, do we agree that testing has been sort of the whipping boy of a lot of what we’ve seen go down in app dev and operations? Anybody want to jump on that?

    Chase: Well, I think it’s certainly gotten a bad name. I think some of that comes from prior to the digital transformation. A lot of the engineering was waterfall, and testing was always that last stop before the software went out live, you know? Nowadays, I think everyone’s come to realize the speed and scale at which we develop things, you have to do the testing up front at the very beginning. You can’t wait till the end, you know?

    You’re gonna be too slow. So, I think, from that perspective, absolutely. I think that’s why testing has really, I think, gotten a bad name, because they’re kind of the blockers to getting anything out into the public domain, whereas nowadays, you have to enable that up front because you want to get it into the public domain yesterday.

    Shimel: Yeah. And so, in many ways, to me, that sounds like, well, DevOps has been the best thing that ever happened to testing, right? In many ways, DevOps has been the best thing that’s happened to security testing, right? We’ve certainly seen that shift left, if you will. But has that shift left helped – has that rising tide lifted all boats?

    Miranda: I still see –

    Shimel: Oh, okay, Tracy. Go ahead.

    Miranda: I’m gonna jump in and say one thing that strikes me as funny. Like, we have, in our industry, everybody has embraced the DevOps terms, and then, you start to see all these spinoffs to put emphasis on things like, for security, we have DevSecOps, and you’ve got every variant of something with ops. But when it comes to testing, you know, there’s no TestOps. There’s no new buzzwords and it kind of speaks to how much it’s being neglected. Like, we had a conference on continuous delivery, and we asked for talks of everything in the life cycle, and we got lots and lots of submissions except for testing.

    So, again, I think it still is really under-appreciated and just not given the due credit for what it stands for.

    Shimel: Very –

    Simo: Yeah. And I think some of this comes from, as Alan mentioned, that testing is a very broad and diverse subject, and I’ve often watched people argue about testing that each interpret it to their piece of what they do with testing. And things like CI and some of the DevOps practices have helped us improve with the checking that our software can work – you know, demonstrating that it can work – and there’s a lot of people – if you primarily wear a developer hat, you’d look at that’s what testing is. And we’ve automated that.

    There’s been huge improvements in tooling and technology to do that, but sometimes, along with that is we throw out that we need someone involved that’s looking at things from a critical perspective that’s concerned about the safety and efficacy of what we’re delivering that is the, I guess, the one questioning and searching for information that they raise issues that we need to deal with that are reasons to not push things out to production now – so that we can make informed decisions. So, often, I think just that critical side gets thrown out as we improve the other side of testing, which is being able to demonstrate that things can work.

    Shimel: Anyone else?

    Ashley: You know, Alan, one of the ways you can tell who drew a diagram is to look at what’s in the center. And so, if we think about CICD, we kind of surround testing, but we don’t talk about testing. So, in some ways, it’s elevated, and some ways, it still sort of abstracts it out of DevOps. But my experience has been not really, because most teams know that testing has to get automated as part of that process, ’cause you can’t have this automated checking and automated deployment, then let’s kind of let a bunch of manual things happen. And not that testing hasn’t been automated – it has been – but I think it has elevated, at least in part, I think a good deal.

    My experience has been. I haven’t worked in every environment, maybe, where test still isn’t thought of very highly. By the way, the thing that the – it isn’t the last thing in the chain. Documentation is the last thing.

    Chase: That’s true. That’s true.

    Ashley: Let’s give documentation –

    Chase: And release notes. It’s true. I have tech doc’s team, too. You’re right. [Laughs]

    Shimel: And that hasn’t really changed much either, though testing has. No. No. But you know what? Caroline, I’d like you to focus in specifically.

    I mean, I think about – you know, Mitchell and I co-founded a security company, and we came out with a product in 2003 of just a vulnerability assessment and manager – “VAM”, we called it – and at that point, look, we used to beg people to scan their infrastructure at least once a year, right, if not quarterly. We were really pushing for quarterly. And you know, the idea of scanning and testing applications before you deployed them – unheard of. It was unheard of, right? We didn’t have the security tools or people.

    We did that after the fact. Now, that’s not normal anymore, right? Today, at least 85 percent of applications are tested prior to deployment. I don’t know who those other 15 percent are, but that’s a whole nother story. But talk to us.

    You’ve lived through this, Caroline. What do you think?

    Wong: Sure. So, you know, I think there needs to be an acknowledgment. There’s sort of these like, first order priorities and these second order priorities. When I think about security – and I think some of these concepts apply to testing more broadly – there’s a saying that, “You don’t take a $200.00 fence to protect a $5.00 asset.” I think security is about you have something of value and so, you want to test it – rather, so, you want to secure it.

    Testing, I think, is like you made something new and so, you want to test it. You’re not gonna test something unless you have something new. You’re not gonna secure something unless you have something of value. So, it’s okay that security and testing are not sort of the number one thing, you know? Inherently, by their definition, it’s sort of a second order attribute, if you will.

    Now, I think, you know, each of us has been through a version of annual organizational budgeting. You know, each organization says, “Okay. Here are the goals for the years. We’ve got limited resources and budget to accomplish those goals. How are we gonna allocated those resources?”

    And there are some things that, for a lot of organizations, are very clear. You know, even if I take a step way back and I say, “Okay. Most organizations might think about budget allocations in three buckets. Number one – general and accounting; number two – sales and marketing; number three – research and development.” You know, nowhere in those words is either security or testing.

    And that’s okay, you know? I think, Alan, when you share your story about VAM, you know, Vulnerability Assessment and Management, I agree that over the last, I would say, decade-two decades – so, when I started my security career 15 years ago, we were almost trying to convince folks that breaches really happened – that this was really a thing to be worried about. You know, today, everyone knows because it’s on the media headlines every day. This is real. And so, that has been a shift in the perception, I think, in our industry.

    There’s also been a big compliance driver. So, the – in the area that I’m very familiar with, security pen testing, a lot of that pen testing is actually driven by external compliance requirements – things that say, “Because of compliance framework A, B, C, you must actually conduct manual pentest on your application, for example, once a year.” You know, doing it more often than that is often because of perhaps what a lot of this group might think of as a really good thing – trying to actually secure your software, trying to actually test your software to ensure it does what you think and what you intend for it to do, but that’s not necessarily the first thing that comes to an executive’s mind when they’re thinking about budgeting, and there’s a variety of reasons for that, right? There’s an external perception thing. I think there’s also a lot of learning, certainly, that the security industry can do to be more approachable and to really understand better what is the software development methodology that we’re engaging with.

    What is the specific methodology and behaviors of these individuals? And how can we actually collaborate with them most effectively?

    Shimel: Fair enough. I mean, look, I don’t want to be the pessimist in the group or the bluebird of happiness here, but we have had success over the last 5-10 years, Caroline. You’re right. Especially in security, but not just security. We’ve had success in testing across the board.

    Tracy, to your point, the fact that we don’t have DevTestOps, I think, is, you know, testament to the fact that we’ve recognized that testing is so critical to the CICD process that it’s part of it. I mean, you can’t have DevOps, you can’t have CICD without a level of continuous automated testing in there – in my mind, anyway. I mean, prove me wrong. But, you know, I think that has been probably one of the biggest successes that the DevOps movement has brought – has been responsible for.

    Miranda: Yeah. And I really like Caroline’s analogy with security because, you know, that’s something else we think of as fundamental to DevOps, but it’s sort of elevated itself and, in a relatively short space of time, went from being ignored to being, you know, headline news. And I think there’s a lot of lessons there. And I – like, I will say, I do think testing is going through that journey and we’re probably on the cusp of it kind of really exploding and watching a few players in the industry and companies starting to do really interesting work in testing. I think that’s gonna turn around very shortly.

    So, yeah, there’s an exciting space that I think its moment is coming – just like securities has.

    Chase: Yeah. I think it’s all about the testing now, quite honestly. I mean, when you look at the future with low-code/no-code, it all becomes question-question mark ops, you know? Any function in a company could actually put something together and run it, and they’re gonna have to test it, you know, and it becomes less about all the engineering and more about the test patterns and things like that that are needed as you get to these future states. So – and speed and scale is gonna continue, I think.

    That’s driven everything with the digital transformation. It’s speed and scale. Everything needs to come faster, and we want more of it, you know? And so, I think that really pushes the envelope, and that’s what DevOps has responded to and, I think, addressed very, very well, but it’s not over. We’re gonna continue to scale up and go even faster.

    So, we have to be prepared for that, and I think it becomes more about testing in the future, and less about, you know, we’re gonna have these pre-built components – APIs you can piece together however you want – then, testing becomes, I think, almost first order, to Caroline’s point. And security, especially. I think security, we’re seeing that change now. If you’re a SAS company especially, security has to be top in line, ’cause you just can’t put something out there and not have it tested from a security perspective. And, furthermore, with compliance, it’s not just ISO and GovCloud and those programs, but large corporations now are saying, “Hey, if you want software in my ecosystem, these are my rules and I want to see your pentest reports and I want to see this.”

    So, I think more and more people are realizing that if the software’s not tested, it’s not worth it. And so…

    Simo: And, in my experience, part of adopting a DevOps culture and not just tool set is putting testing at the forefront. Some of the most productive teams that I’ve worked with that deliver some of the highest quality software I’ve seen – testing was center to absolutely everything that everyone on those development teams did.

    Ashley: Hm-hmm.

    Chase: Yep.

    Shimel: Yeah.

    Miranda: Yeah. We think – go ahead.

    Ashley: I’m just gonna jump in and say – there’s another factor that actually works to our benefit and that is not only to speed through automation and DevOps process, but contemporary software architectures, containerized micro-services, service mesh – we’re releasing smaller bits of code in encapsulated forms, which means, you know, we’re not testing monolithic applications all the time anymore so, we’re not having to run two weeks’ worth of tests just to get one pass through.

    Chase: Yeah.

    Simo: Right. _____ container solved the “It works on my machine” problem because we can ship the developer’s machine.

    Chase: Yep.

    Shimel: Yeah. That was always a big problem, right? Tracy, you were gonna say something though.

    Miranda: Yeah. No. I think the direction we see it heading is we’ll start breaking the testing monolith to talk about what is unit test, what is system test, and appreciate that is a specialization in itself. And the other things I’m starting to see from some of the end user teams we talk to is this real focus on culture – you know, a continuous quality culture – and seeing that hand in hand as part of the testing movement and again, _____ back to security – you know, the security first culture went hand in hand with that whole emphasis on security so, similarly, the continuous quality culture is starting to be something that – like, the really high performing teas we see pay a lot of attention to.

    Shimel: Absolutely. You know, Kurt, you said something there about low-code/no-code and how that could be a game changer. You know, some people refer to that as the rise of the citizen developer, and I’m wondering if maybe what we need is the rise of the citizen tester, right? Is testing too hard?

    Chase: Yes. I waste gonna say – the one thing we haven’t touched upon – I think Caroline did – is testing is hard. Security testing is super hard. And when you look at today’s modern environment and a lot of the ISVs – at least the ones I’ve seen and been associated with – you have a legacy of monolithic applications that you have to support that are bringing in a ton of revenue, and, at the same time, you’re transitioning – you know, going through your own digital transformation. So, that adds complexity after complexity in testing, and I do think, in the future, testing – you know, a lot of us, like Ben said, to his point, we have to push testing up – you know, shift left, move it far left as we can.

    And that’s gonna continue. I think that has to be the norm. To Caroline’s point, it has to become first order. And I think it’s starting to right now. I really do. Especially the – all the SAS solutions that are out there – you know, shipping code daily, hourly. You need excellent testing to do that and do it with competence.

    Shimel: Yeah. I think you do. But we do have to – and it’s funny that we’re talking about making testing easier because – not security testing, right? Security testing, pentesters – they were always sort of the hired guns of the security space, right? There were SAS or – there weren’t companies like Cobalt, right?

    The pentesters that I knew growing up – growing up – you know, that I knew coming up in the security space were gun slingers. These were, you know, white hat/gray hat folks who would come in and they’d do a little social engineering and pen testing using some open source tools, and you know, they give you a report. But you know, these were folks who traveled around the world doing that kind of thing. You know, we didn’t have a company like Cobalt that did this as a service, so to speak. So, it’s very different.

    But here’s the underlying thing with like, QA kind of testing – and, you know, I don’t mean any disrespect to anyone in our audience today, but for too long, a lot of folks in testing were viewed as failed developers or people who couldn’t be really good developers did testing or maybe testing was a weigh station on the way to becoming a real developer – like a Pinocchio stop or something, right, where you’re not a real boy yet. But that’s not true. There’s also – there’s a whole cadre of professional testers. And you know, in their capable hands, you could do great things. But I guess the question is – does testing have to be so hard that we need professional testing – professional testers to do testing?

    Or can we make testing automated enough that you – I’m not saying it has to be the dunces who don’t become developers. That’s ridiculous. But can we broaden the base of people who do testing? And that includes security testing? I’ll throw it out. Ben, you were a big-time guy in the testing industry. Tell us – what do you think?

    Simo: So, I think we can expand who’s involved in testing and that more people than those currently doing testing can learn to do testing. I don’t know _____ developers learning to become better testers and test their stuff. But I will say that ultimately, the part of the work that is the testing cannot be automated. Tasks that we do in testing can be automated. So, whether – not matter what hat someone primarily wears, if it’s a developer, you know, writing tests to demonstrate their code works or someone’s using TDD and they’re building some tests and then, building some code that matches it, the testing is the critical evaluation that’s going on in their mind of solving the problem and demonstrating that it’s solved – or evaluating how something might go wrong and coming up with some approach to demonstrate that it may go wrong and check for that.

    So, those things, whether you’re doing it automated or the execution is automated or done manually, the actually testing work, I’d argue, is the cognitive work that people are doing. And there is some – that we can never automate away. There are some ways that I think AI can help us. There’s also some ways that may lead us astray. But ultimately, I think we need people to learn to be critical thinkers to understand the technology, to understand the domain of the users and the problems that are being solved, and applying that critical thinking is the testing.

    Of course, then, we want to use tools to help us with some of our tests so, when we come into DevOps and CI, executing those demonstrations of the software working is a key part of that. Now, whether we do it as part of our, you know, building to those tests or we create them afterwards, then they can, at the very minimum, act as changed detectors going forward. But there was some testing in people’s minds that was going on that created those.

    Shimel: Caroline, what about – okay.

    Wong: I agree with quite a lot that Ben is saying. You know, I can’t help but think to myself that – I actually have this sort of visual in my mind, and it’s actually at a circus of a trapeze artists, you know? I think about these people, and they’re sort of like, whirling in the air and they’re doing these like, really incredible feats, you know, and they just do whatever they do, you know? But there’s like, a safety net to catch them if something goes wrong. It also reminds me of a metaphor that is often used in security that says, “We put brakes on a car so that you can go fast.”

    You know, when Mitch said earlier, you know, “These days, we’re releasing smaller pieces of code, modules of code” and there’s a way in which, yes, each small piece of code – each module – can be tested and some of that can be automated. We should automate performance testing. We should automate unit testing. But, to Ben’s point, there’s a lot that can’t be automated. There’s a lot of testing that actually depends on things like human judgment and opinion and it actually requires a person’s decision, you know?

    So, I think there’s – I think there’s a couple of frameworks for us to consider, right? If the first order is about creating value and making something new and the second order is about testing to make sure it does what you wanted it to do and protecting the value created, there’s also this spectrum that says there’s smaller bite-size stuff that may be a good candidate for automated testing, but, I think it’s super important to recognize that these small pieces of code – these modules that Mitch was talking about – it’s also super important to test what happens when they come together. So, to the extent that security folks need to be able to test chained exploits and business logic flaws, you know, those are exactly the types of things that will never be automated – is what I think, anyway.

    Shimel: I don’t disagree. I think security in particular is just there’s some things you’re just not gonna automate. I don’t care what you say. But that’s okay. Anyone else?

    Chase: I do want to make a comment on something you said. This was a long time ago now, when I was a dev manager, that I used to sense that when my developers – you know, if you were on my team, if you wanted to really get me mad, treat your tester badly. Treat them, you know, a bit, like you said, like they’re not quite at the level you are. I would be incensed as a manager. You know, that was a long time ago.

    Fortunately, I don’t see that as much nowadays. I think that role has been elevated where I don’t feel that at all on my teams, and if I do, that is, again, to this day, I’ll get super mad about that because I think it takes all kinds to develop software today and ship software. Testing role is just as critical as an engineering role, just as critical as the ops’ role, the security role. So, yeah, that was one thing that would drive me nuts ’cause I did sense that and go through that, and this back in, you know, the late ’80s-’90s, if you will, before the year 2000 – I’m dating myself – but it definitely was palpable in some of the large ISVs, you know? And as a manager, that was something that would drive me nuts.

    Shimel: Agreed. Agreed. Tracy, open source – look, testing has been inexplicably wound up with open source for as long as I’ve been around, right? Whether it’s security – open source security testing and you know, things like Metasploit and Nessus and Nmap or you know, in QA testing kind of stuff, it’s a rich history of open source testing tools. How do – and part of your mission at CICD is – at the CICD Foundation – is to nurture that, I’m going to assume, correct?

    So, how do you guys nurture that? What are you – what do we do to maintain that rich, open source tradition here?

    Miranda: Yeah. No. Absolutely. And, as I say, we at the Continuous Delivery Foundation, we want to look across the entire software delivery life cycle, and I think it is safe to say, you know, that testing hasn’t risen to the top. We’re actively – like the board wants it to be a more focused-on topic, the technical committee wants to encourage folks to bring us more projects in open source and with testing, but we’re still having to kind of fight through all the noise around other projects.

    And one of the ways we’re approaching it is, for example, our technical oversight committee wants to set out a landscape of the types of projects in each kind of bucket and say, “Okay, look. We need to have something in security. We need to have something in testing that covers these different aspects.” Almost like a call to action to say, “Bring us your testing projects and –” like my favorite saying about testing is, “There’s two key problems in testing – not enough tests and too many tests.” And yeah, I think we’re starting to see some really good frameworks around test generation.

    I’d love to see more open source options for that. And Kohsuke Kawaguchi, the famous creator of Jenkins, move on to focus on testing so, that says a lot about the importance of this area getting more open source focused. So, yeah, I’m excited to see what could come out, but we do have to actively encourage folks to come join us and have those conversations and not to, you know, have it assumed it’s all focused on delivery of pipelines for delivering software.

    Chase: I think another thing you’re seeing today is a lot of people, when they start developing an app, when they start creating something new, that’s the question they ask up front. “How are we gonna test this? How are we gonna automate it? How are we gonna pentest it?” I think those things, at least, are starting to bubble up a lot stronger in the cycle – you know, early on. ‘Cause I know that’s something we recommend highly – is that if you’re developing something new or need to head down a digital transformation, think about the testing. How are you gonna test that up front, you know? And products are actually being developed with that mindset now.

    Simo: And with short iterations, it’s how are we going to test this tomorrow, next week? It can’t be left off for months later to be someone else’s problem. So, people, I think, are learning to deal with those questions about testing from the start of their discussions about what the requirements are.

    Chase: The other thing I love – and in Caroline’s world, has been very successful – I know it is specialized skill set, but trying to teach that throughout your troops – you know, throughout the engineering team. Show them what, you know, across _____ scripting errors. What does it look like in code? That’s super successful. That really, really helps make – ’cause security is difficult, you know, no matter how you slice it.

    Even when you’re looking at product development – if you want to invest in fixing security defects or add a cool new thing for your users, you know, a lot of times, the cool new thing is gonna win out. But that’s starting to change as well, too. I think people are starting to value security – especially in today’s modern world, you know? It has to be up front, really.

    Ashley: Yeah. It’s all about AppSec at the moment. That’s one of the hot topics as well. You know, someone mentioned AI earlier. I just want to offer a perspective about that because we always seem to focus on the shiny new object.

    I know I have. I often do. But I think what we’ll see with AI is select applications when it comes to testing. The sort of vertical place is where it’s really well suited. When we say, “Yeah, AI”, we really mean machine learning in most cases, which is machine learning algorithms, and there’s two types – there’s supervised/unsupervised.

    Supervised is, “That’s a car. That’s a car. That’s not a car, right? That’s a bug. That’s a bug.”

    And unsupervised takes massive amounts of data and intellectual patterns and learnings from that. So, I think that as we’re taking our test automation and our test tools, there may be some of that, and it might be really useful for AI. I wouldn’t get worried about people being replaced as testers. Not in my lifetime, that’s for sure. It is still a – there’s very much a craft to it, just like there is software design.

    There is a craft to testing and a skill and a mentality about it that’s unique, just like with security.

    Shimel: No doubt. Caroline – oh, go ahead, Ben. I’m sorry. No, no, Ben. Go.

    Simo: Yeah. I was gonna say – and with any other sorts of automation – even you know, not learning automation that’s come before AI and machine learning based things, is that it not only has potential, in some cases, to replace some of the mundane work we do, but to enable to the skilled people to focus their work and apply their brain power to the things that really matter. So, I think there’s great potential for AI to help direct people’s attention to the things that maybe should be of concern and help deal with that big question of testing out of infinite possibilities of PaaS and data variations. Which one’s gonna show me the problem? And I think there’s huge potential for AI to help us find that if we’re also aware it may guide our eyes away from something that we do want to see.

    Shimel: Caroline, how does that relate to security, though? I mean, is AI helping Cobalt with pen testing? Be honest.

    Caroline Wong: So, the type of software that we’re building today is actually workflow and collaboration software. So, what we’re trying to do, is we’re trying to bring security folks and developers and penetration testers all together sort of in one place where they can collaborate. The technology piece, for us, is not about automating defect discovery. It’s not – I mean, if we’re gonna us ML or AI in the future, honestly, what we’re gonna do is we’re gonna use it to say, “What are the characteristics of this organization that wants us to do a test on this particular type of asset? What are the attributes of that asset and how might we match that to our talent pool – something that we do totally manually today?”

    I think that’s the opportunity. I don’t think that we’re gonna get to a point where we’re using the AI and the ML for automating the defect discovery itself. Frankly, I think that even if I take a step away from pen testing and I look at the security scans that are in existence today, I think, you know, whether or not they’re referred to as using AI or ML techniques, they’re just simply imperfect, you know? And there’s a super important place for them, but there’s a lot of false positives. There’s a lot of interpretation of data.

    And I think that’s always gonna be the case. I think that no matter what, when it comes to humans and machines, the machines can add a lot of value, but I don’t know that when it comes to software development testing and security in particular that there’s every gonna be a complete substitution. I don’t think that – I don’t think that makes sense.

    Shimel: Absolutely. So, guys, we’re coming up on the end of our time. I need to wrap up. Tracy, let me say this for you, if you don’t mind – and if I’m wrong, correct me. For you testers out there, the CICD Foundation – or CD Foundation, actually; I keep – we always say “CI” like it’s attached at the hip – but the CD Foundation is looking to hear from the testing community.

    Probably some companies – including Tricentis – may want to look into becoming involved with CD Foundation because if you don’t have a seat at the table, you don’t have a right to complain about not being heard. And so, you know, when we look at foundations like Linux Foundation and the CD Foundation, CNCF, we need the testing community – vendors, professionals, folks in it, you know – to be involved and get involved. Be heard and be part of it. So, I’m gonna extend that out there to everyone. But, short of that, though, Caroline, Tracy, Kurt, Ben, and, of course, Mitch, thank you so much for joining us on this special edition of DevOps Unbound.

    We hope everyone enjoys the rest of their Tricentis Virtual Summit. This is Alan Shimel for MediaOps, DevOps.com, Security Boulevard, Container Journal, Tech Strong TV. Have a great day, everyone, and thanks for joining us.

    [Musical outro]

    [End of Audio]
  • 4 Steps to More Agile Operations

    4 Steps to More Agile Operations

    After over a year of business disruptions, modern enterprises have realized that speed and agility are the only way forward. In fact, according to Gartner’s Top Strategic Technology Trends for 2021 eBook, “Organizations that don’t focus on efficiency, efficacy, and business agility will be left behind.”

    In order to stay future-ready, organizations across all industries are moving to adopt an operating model that is agile and competitive.

    Roadblocks on the Path to Agility

    Driving operational agility is easier said than done. Enterprises face a variety of challenges when it comes to streamlining their end-to-end processes, including a lack of visibility into business gaps, monolithic legacy systems, siloed departments and evolving regulatory requirements.

    Enterprises have no choice but to overcome these hurdles and streamline their operations or else they will fall behind their competition.

    Now more than ever, business and IT leaders must recognize the importance of investing in business agility when it comes to their bottom line. Especially since, as the Gartner report said, “agile software development practices are fueling software innovations globally. Agile techniques create more value for the business, and faster, than do traditional methods.”

    The real question is: how can enterprises seamlessly shift to a more agile operating model?

    Agile Operating Model: The Four-Step Approach

    Understand Business Needs

    An effective agile operating model is rooted in a comprehensive and deep understanding of an enterprise’s needs and gaps. This goes beyond identifying business goals, requiring organizations to analyze the nuances of their operations, the challenges impacting day-to-day functions and all their expected outcomes.

    Based on this holistic picture, business leaders can begin to recognize which technologies and strategies to implement and where to generate the most return on investment (ROI).

    Connect, Collaborate, Contextualize!

    The bedrock of agility is a connected enterprise, and so bridging operational and departmental silos is of the utmost importance. Every relevant stakeholder across the organization must have complete visibility as well as access to collaborative tools such as live dashboards, remote and mobile functionalities and personalized user interfaces.

    By leveraging modern technologies to enable anytime, anywhere collaboration, enterprises can make intelligent decisions and changes without compromising on speed or quality.

    Focus on Generating Value

    Of course, the overarching goal of implementing an agile operating model is to generate business value; however, to ensure that expected outcomes are met, enterprises must clearly define—and periodically redefine—how value and ROI are assessed.

    By leveraging process analytics and monitoring tools, business leaders can maintain complete visibility into their operations, quickly readjusting their approach whenever necessary.

    Empower Employees with Modern IT Infrastructure

    Organizations can drive continuous improvement and increase productivity by embracing modern technologies and low-code development capability.

    To respond to the evolving business needs, enterprises can leverage new-age technologies, including cloud, robotic process automation, artificial intelligence and machine learning while maintaining a well-integrated IT infrastructure.

    Furthermore, with low-code, enterprises can empower their employees by helping them easily develop applications per business requirements, with less dependence on IT.

    Agility: The Need of the Hour

    There is no slowing down for modern enterprises. To successfully navigate growing competition, heightened customer expectations, and a continuously evolving market, organizations must prioritize business agility.  In fact, “with the speed of change expected to continue, the need has never been greater for an operating model that can keep up.”

    And so, for business and IT leaders with their eyes on the future, the time is now to take steps toward establishing a more agile enterprise.

  • Improving Resiliency by Creating Chaos

    Improving Resiliency by Creating Chaos

    In the digital economy, preventing downtime is paramount. When digital systems fail, the consequences for business can be huge. The cost of downtime can run to thousands of dollars per minute for large businesses. That’s without taking into account the impact of customer dissatisfaction and reputational damage for the company and the IT careers involved.

    No matter how you measure it, IT failure is costly. It’s also largely unavoidable due to the increasing complexity and interdependence of today’s distributed IT systems. The combination of cloud computing, microservices architectures and bare-metal infrastructure create many moving parts and potential points of failure, making those systems anything but predictable.

    That IT faults will occur is easy to acknowledge. Understanding how to fix them is harder, especially when interdependencies are not always obvious. Until recently, build testing has been the go-to method for assuring quality and resilience, but this kind of testing does not take into account environmental factors that cause unpredictable events or how cascading failures that lie dormant and unnoticed can trigger larger failures.

    How Chaos Engineering can Help

    Chaos engineering is a relatively new approach to enterprise software development and testing designed to eliminate that unpredictability.

    Introducing chaos into a system may sound counterintuitive if your end goal is to get clarity and improve resilience. Indeed, if you have heard anything about chaos engineering, you may have been alarmed at some of the terminologies: “blast radius,” “random terminations,” “fault injection” and “storms,” to name a few.

    In practice, chaos engineering is about performing controlled experiments in a distributed environment so that digital engineering teams can build confidence in the system’s ability to tolerate inevitable future failures.

    How it Works

    The process of chaos engineering involves stressing applications in testing or production environments by creating disruptive events in a controlled manner, such as server outages or API throttling. By observing how the system responds, improvements can be made before those weaknesses affect real customers.

    Experiments are meticulously planned from initial scoping to execution and the insights they deliver are far-reaching.

    Chaos planning starts with identifying the target deployment for the experiment. This process requires a comprehensive review of the application architecture and infrastructure components to first define what we call steady-state behavior. In other words, you need to understand what “normal” looks like before you start experimenting.

    You can then form a hypothesis about how the system will behave during the disruptive event. You’ll need buy-in from the business areas you are potentially disrupting and you’ll need to plan the parameters of the test carefully, reducing the scope if necessary.
    It’s a good idea to start small with chaos experiments. You’ll need to replicate them many times over in any given system to properly test its resiliency.

    Tooling for Experiments

    Luckily, many different tools already exist to help organizations implement and manage planned disruptions. Chaos engineering as we know it today originated back in 2010 from experiments conducted at Netflix using the tool Chaos Monkey, which still exists and is used today.

    Nowadays, there are many more chaos offerings available, including services from Microsoft Azure and AWS as well as Gremlin, ToxiProxy, Litmus and many more. Organizations can choose tools tailored to the size of their environment and decide just how automated they want the process to be. Tool selection will also depend on whether experiments are designed to test the system at an infrastructure, network or application level.

    Chaos Culture

    Chaos engineering is much more than a set of tools and rules. It involves adopting a culture in which teams trust each other and collaborate to build resiliency and advance innovation.

    When it comes to thinking about this culture shift, it can be helpful to think back to when DevOps was new. Sure, people would say they were using DevOps tools, but that did not necessarily mean they were actually practicing DevOps. DevOps involves breaking down siloes between different groups in an organization, creating an atmosphere of trust and enabling collaboration–some of the same attributes a chaos engineering culture needs to have.

    Why you Need Chaos Engineering

    Although chaos engineering sounds like a disruptive or uncontrolled exercise, it is actually the opposite.

    Chaos experiments require meticulous planning with an emphasis firmly on rooting out failures before they become outages. Far from lacking in control, chaos testing is a closely coordinated process and the organization retains a firm grip on everything from the speed at which testing happens to what components are tested. Chaos engineering doesn’t create problems, it reveals them.

  • What is Continuous Delivery?

    What is Continuous Delivery?

    [pdf-embedder url=”https://devopsy.kinsta.cloud/wp-content/uploads/2022/02/what-is-continuous-delivery.pdf”]