Category: IT as Code

  • WhiteSource Tool Automatically Fixes Code Vulnerabilities

    WhiteSource Tool Automatically Fixes Code Vulnerabilities

    WhiteSource today announced that it has developed the first-ever tool that automatically remediates vulnerabilities discovered in custom code.

    Rami Sass, WhiteSource CEO, said WhiteSource Cure surfaces recommendations for fixing security vulnerabilities in code that developers can then apply with a click of a button. WhiteSource has a long history of providing tools that discover vulnerabilities in open source software that it tracks via a database it manages, but Sass said customers are making it clear they need a way to automatically remediate those issues in a way that doesn’t adversely impact developer productivity.

    The average developer spends, on average, half a day fixing a single vulnerability, so the impact security issues are having on the rate applications are being developed is significant, added Sass. WhiteSource Cure gives each developer the equivalent of their own personal security expert, noted Sass.

    Developers can either apply the remediation suggested by WhiteSource Cure—that manifests itself as a pull request in a DevOps pipeline—or they can fine-tune it as they see fit, said Sass.

    WhiteSource

    WhiteSource Cure arrived as friction and tensions between developers and cybersecurity teams rise in the wake of a series of high-profile attacks against software supply chains. As a result, organizations are instituting more thorough security reviews of application development projects. The concern is those reviews will dramatically reduce the rate at which applications are being delivered.

    Of course, many organizations are looking to shift responsibility for application security further left toward developers to minimize the number of vulnerabilities that might need to be remediated either just before an application is deployed in an on-premises IT environment or, worse yet, after it is deployed. Trying to achieve that goal within the context of DevSecOps best practices, however, is challenging. Organizations first have to acquire vulnerability scanning tools that developers will actually use, and then provide developers with the training required to identify various classes of vulnerabilities.

    The other big challenge is the time it takes to train developers to recognize vulnerabilities. WhiteSource Cure eliminates the need for developers to become security experts, said Sass. In addition to a commercial offering, WhiteSource is also making available a Community Edition of WhiteSource Cure for open source projects that will forever be available for free to developers working on those projects.

    Sass said that rather than relying on machine learning algorithms and other forms of artificial intelligence (AI) to build WhiteSource Cure, the team that developed the tool found that more traditional approaches to software composition analysis (SCA) provided more reliable results.

    It’s unclear whether the ability to automatically remediate known vulnerabilities in code will render much of the DevSecOps debate moot. However, it’s clear that the simplest path forward toward achieving DevSecOps is, as always, to automate as much of the remediation process as possible. The challenge will be waiting to see how much confidence developers and cybersecurity teams will have in the recommendations generated.

  • Shoreline Platform Automates Repetitive IT Tasks

    Shoreline Platform Automates Repetitive IT Tasks

    Shoreline emerged from stealth today to make available a namesake incident automation platform that eliminates the need to manually perform the same repetitive tasks.

    Anurag Gupta, Shoreline CEO, said the platform is based on domain-specific language, dubbed Op, that provides a simple pipe delimited syntax to integrate real-time resources and metrics in a way that allows DevOps teams to invoke an orchestration engine to automate the execution of a task from the Linux command prompt. Op employs a syntax that is familiar to any IT professionals that currently use shell commands and scripting tools to resolve IT issues, said Gupta.

    That same Shoreline tool, however, can also be employed to create remediation loops that check for issues, collect diagnostics and apply repairs automatically in the background, he added.

    Shoreline

    Shoreline achieves that goal by first collecting metrics on a per-second basis via data collected from open source Prometheus monitoring software. Armed with that data, it then becomes possible to distribute queries to both collect data in real-time and run local loops in parallel to automate repairs, Gupta said.

    The platform employs the JAX and XLA frameworks for machine learning algorithms to reduce the amount of CPU resources required to compute metrics and create alarms. Wavelets are also employed to compress the input metric stream. Finally, queries are portioned across historical data stored in the S3 cloud storage service from Amazon Web Services (AWS) and real-time data collected from each node.

    All Shoreline components are designed to be fault-tolerant, added Gupta. Automation can still run locally to Shoreline backends, even when connectivity is lost. All processes have supervisors to restart when failing and reestablish connectivity.

    Finally, Shoreline provides controls to limit the scope of a manual operator action and automate executions in a given time period to help prevent any errors from cascading through an entire IT environment. That approach makes it possible to safely automate tasks in a way that makes it less likely outages will occur because, for example, a misconfiguration winds up being propagated across every system, noted Gupta.

    While IT environments are arguably more complex than ever, Gupta said it’s the repetitive tasks that take up so much of developers’ time. In the absence of any way to automate those tasks, an IT team will, over time, become increasingly burned out, which Gupta noted inevitably leads to mistakes being made.

    At the same time, Gupta noted the Shoreline platform makes it simpler to onboard new members of an IT team because much of the tribal knowledge that once had to be learned on the job has been captured within an automation platform.

    The arguments for automating IT have, of course, been growing louder and more frequent for nearly two decades. Most platforms that promise to automate IT have required a fair amount of expertise to implement and maintain. The Shoreline approach, in contrast, starts with a Linux prompt that many IT teams already routinely use to execute a range of tasks. The difference now is simply the level of scale at which those tasks can be performed with a minimum of programming skills.

  • Programmability is Key to Agile Transformation

    Programmability is Key to Agile Transformation

    Enterprise agility has rapidly become one of the most crucial variables for a business’s long-term resiliency. With the COVID-19 pandemic, never-ending disruptions to the global supply chain and nearly every industry’s typical processes flipped upside down, there has never been a more important time to prioritize agility than now.

    While the rewards of agility are high, organizations are struggling to implement key technologies and adhere to the methodologies that can get them there. In fact, the 14th Annual State of Agile Report notes that 59% of organizations are following agile principles, but only 4% of these organizations are getting the full benefit. But the ability to adapt quickly, seize new opportunities, and reduce costs is critical for survival in the ever-evolving and hypercompetitive digital age.

    Agility is about adapting quickly to changes and increasing productivity. Importantly, agile methodologies are not agile themselves and therefore will not magically transform enterprises into agile organizations. Instead, the focus needs to be on practicing the correct principles to become truly agile. With this in mind, let’s look at how two of these critical principles—programmability and observability—can increase productivity and allow for innovation across the business.

    Programmability

    Programmability describes the capability of hardware and software to change and accept a new set of instructions that alter its behavior. Let’s look at each of these two forms.

    One way programmability is used is to connect analog devices with software, for example, software-supported network routers. More recently, programmability has been extended to use networking to control the hardware involved and bridge with software systems. The rising popularity of infrastructure-as-a-service (IaaS) has increased the demand for programmability and brought concepts, such as infrastructure-as-code (IaC), into the realm of reality.

    The other use of programmability is to extend existing software capabilities. The two most widely known examples of this are application programming interfaces (APIs) and software development kits (SDKs). Using both approaches, a developer can extend the default capabilities of an existing program. The rebirth of APIs as business APIs has significantly extended the introduction of programmability into application software systems. The approach is particularly popular with application service providers since it enables end users to extend and customize the core capabilities provided by a product or service.

    Connecting Agility and Programmability

    So how are these two concepts connected? Agility requires a foundation and the right kind of environment to provide optimal results. Programmability is an enabler for creating an adequate path for agility. An organization with highly programmable components increases the ability to automate repeatable tasks. Let’s look at two scenarios: a business use case and a technical use case.

    Programmability in Business

    When a purchase order (PO) arrives, the customer care representative must verify the organization’s ability to fulfill the request and then create an order in the back-end customer relationship management (CRM) system. Traditionally, this process has required a good deal of manual effort: first, extract the PO data; then verify the details using other systems or spreadsheets and, finally, type the data into the CRM system.

    By contrast, consider a person working in a modern environment with high programmability. The PO can be received in an electronic format, such as JavaScript object notation (JSON), extensible markup language (XML) or electronic data interchange (EDI). Then it can be validated by connecting to other systems and reference data repositories, prompting the user to verify it and feed the data into the CRM system.

    Programmability in a Technical Environment

    In a typical technical use case, software developers will finish writing code; quality assurance (QA) engineers have to test the release; release engineers have to verify it and the DevSecOps team has to deploy the released artifacts. Similar to the business use case, this technical workflow has traditionally required extensive, tedious, manual work.

    However, the process becomes significantly more streamlined when the development organization makes the environment programmable. In this case, once developers commit the code, the automation flow will kick in, exert the committed code, run through the life cycle stages and deploy it into production.

    Through automation, which is enabled and extended by programmability, organizations can streamline their repeatable tasks and provide more time and space for users to work on essential or innovative tasks.

    Now, let’s look at the implementation details of the two use cases.

    Programmability in the Digital Supply Chain

    In the business use case, the automation of a workflow, such as PO processing, is treated as part of a modern digital supply chain initiative. The systems, messaging and data involved in such a flow are linked together using integration technologies.

    Integration approaches first involved point-to-point connections and then evolved to the use of centralized enterprise service buses (ESBs). More recent, modern approaches have centered around API-centric, integration microservices and integration platform-as-a-service (iPaaS) solutions that use decentralized models and cloud-native technologies.

    Now, organizations build or acquire digital platforms by combining APIs, integration and security technologies to create digital supply chain flows. Critical to the success of any digital supply chain is the ability to select systems with built-in API capabilities and enable existing systems to expose applications and services as APIs and make the entire enterprise programmable.

    Programmability in a Secured Software Supply Chain

    In the technical use case discussed earlier, DevSecOps automation provides the foundation for automating various aspects of the software life cycle. Here, development tools, testing tools and governance-related tools are all connected using a pipeline.

    IaC and automated build servers are two popular technologies used in automating such flow, which we call a secured software supply chain. Puppet, Chef and Ansible are widely adopted IaC scripting languages while Bamboo and Jenkins are popular build servers. However, as the DevOps space has evolved with cloud-native and decentralized technologies, GitHub and GitOps are also playing a vital role in building effective pipelines.

    Similar to the business use case, the components involved here need to connect to the build pipeline, and therefore the programmability of each element involved plays a significant role in automating the workflow. Furthermore, in order to build a comprehensive pipeline, the code quality, unit test, automated test, infrastructure provisioning, artifact building, dependency management and deployment tools involved have to connect using APIs and extend the required capabilities using IaC.

    Observability

    By analyzing both the business and technical use cases, we have a clear idea about the impact of automation and how it is enabled by programmability. However, we have missed one important element: observability. Let’s examine this here.

    The environment created by automation and programmability provides a good playground for teams to be practice being more agile, experiment with new ideas and take them to production rapidly. While agility increases, the responsibility of running healthy systems that provide a continuous digital experience is vital.

    Observability helps detect and predict issues using analytics, machine learning (ML) and artificial intelligence (AI). Modern cloud infrastructure provides a certain level of observability at the operational level. Meanwhile, some modern programming languages, such as BallerinaLang, have built-in support for application-level observability associated with the specific language. When working with languages that lack this functionality, developers will have to either use a third-party tracing library that is compatible with the programming model or directly insert observability instructions along with tracing and debugging instructions.

    Enterprises today are on a journey towards agility as they seek to optimize their digital strategies. However, organizational agility needs to catch up with project agility—and then, with each individual’s agility—to be more effective. This is the concept of “structured agility,” which is being fueled by “two-pizza teams” or self-organized teams.

    APIs are the foundation of programmability, which makes it possible to connect analog and digital systems, as well as extend software systems. Programmability increases the speed of delivery, enables an enterprise to become “composable” with high reusability and allows a flexible environment by opening it up for innovation—the core principles of agility.

  • How ESM Enables Digital Transformation

    How ESM Enables Digital Transformation

    The pandemic has forced organizations of all sizes to overcome colossal challenges and embrace flux. We’ve all heard stories about businesses having to adopt a new communication tool and train staff overnight, but that’s just the tip of the iceberg.

    Many companies are in the middle of fundamental transformation, enabling enterprises to create more business value quickly. Still, digital shifts can also highlight stumbling blocks—such as inefficient management of people, tools and processes.

    As modern business needs grow increasingly complex and require teams to do more with less, C-suite executives have learned that real value lies in customizable systems built for scalability, automation and collaboration. In the same way, companies have embraced DevOps to break down silos between development and operations teams, modern businesses are adopting enterprise service management (ESM) principles to create shared responsibility and opportunity across departments.

    This approach has helped businesses view their digital transformation plans in a new light. Forward-thinking leaders are using ESM to enable a DevOps mindset, to centralize knowledge and ensure efficient digital service delivery within their organizations over the last twelve months.

    The Business Benefits of ESM

    ESM includes the tools and processes that enable an organization to manage the entire life cycle of IT (or other business units’) services. At an organizational level, it can be considered analogous to service-oriented architecture rather than an application architecture level.

    Within larger organizations, multiple teams are often doing similar things to support different parts of the business. Keeping track of requests, prioritizing them and ensuring the right resources are available can be challenging. With ESM, companies can consolidate their resources and provide a consistent way for the organization to consume them. Akin to microservices, employees can easily access shared company services through a uniform interface, streamlining resources management.

    The approach encourages enterprise leaders to see everything the company does as an integral service to the entire business. So, rather than an accounting team merely existing to process purchase orders and take care of payroll, it becomes a service provider. For example, they might create a portal that provides templated service requests for everyday tasks, such as raising a purchase order or understanding if a payment has been received, and a mechanism for capturing ad-hoc work that isn’t otherwise defined.

    The real benefit of this approach is work management. A ticket is raised, and the department dealing with it can have a rotation of people, with whoever is least busy picking up the service request, assessing and resolving it or assigning it to someone else. That’s one reason it’s hardly a surprise that 87% of companies surveyed in 2019 said that they had already incorporated ESM in some way.

    Practices, Not Processes, to Optimize Digitization

    However, with businesses forced to undergo historic digital transformations over the last year, ESM has become even more valuable for organizations. The pandemic has shifted work management to a 100% digital initiative as teams were distributed remotely. A well-executed ESM strategy has enabled enterprises to take their digital-first workflows to a higher level, driving more value from employees and enabling organizations to scale service delivery and create unrivaled customer experiences.

    ESM requires businesses to understand that there is no one-size-fits-all approach to service delivery and encourages them to replace their process-orientated mindset with an approach that focuses on value delivered through practices. These practices, which are built on user interaction and feedback, support agile organizations by helping them accelerate change and make services more available and reliable for customers.

    Furthermore, these practices put users’ pain points and needs front and center to ensure continuous improvement. Through frequent evaluation, enterprises can address the things that matter the most to staff and customers. While this might seem like a basic practice for any company’s digital transformation plans, the truth is in many cases, we’ve found the practice to be widely neglected. A recent report from Eagle Hill Consulting found that one-third of U.S. employees say their company’s technology either doesn’t help or makes it more challenging to serve internal and external customers.

    Digitization driven by these ESM principles can enable businesses to improve operational efficiency, reduce cost and risk, and plan strategically to support their evolving needs. All of these are, of course, what every organization had in mind as goals when the COVID-19 pandemic forced them to rethink how they do business.

    ESM Automation and Cross-Departmental Visibility

    At a high level, ESM sets out to bring all internal services into one place where every employee can easily find what they’re looking for in an instant. Accessing everything in one place also opens the door to leveraging automation. The option for automation means that some previously manual tasks – like providing access to systems – can be automated, speeding up wait times for staff or external customers and ensuring scarce resources, like your best people, are used more efficiently.

    Moreover, common, consistent and shared platforms for all with a single access method gives individual departments enhanced visibility and control throughout the entire organization. Historical silos hampered individual business units’ visibility and understanding of the functions their business provides or how they’re processed. A unified portal where all departments can access resources and receive requests, in the same way, solves that.

    Of course, this isn’t to take away from the inevitable learning curve that comes with digital transformations, especially at the size, scope and scale currently being undertaken. But the turnaround time from disconnected, slow, siloed teams to visible, open, speedy services far outweighs the effort required. In fact, recent research from Digital.ai uncovered just how badly visibility problems and poor internal alignment plagued businesses, with 56% admitting they’re worried that they’ll fail to achieve any return on investment from their stagnant digital transformation initiatives.

    On the other hand, industries like finance, which have upscaled self-service and automation significantly in recent years, have built entirely new business models with collaborative technologies, accelerated innovation cycles, and have learned to make better, faster decisions.

    These companies all embraced technology to empower their employees to help customers get the most from their service. In doing so, they are better able to deliver the best business value, which is core to a DevOps mindset and is achievable with successful ESM strategies.

  • Why You Should Embrace Incidents and Ditch MTTR

    Why You Should Embrace Incidents and Ditch MTTR

    The cliché is that everyone in IT hates incidents, and the natural reaction when assembling incident response metrics is to look for numbers that you can lower over time. Fewer incidents and shorter incident response times must be better, we think. You might already be familiar with the common metrics associated with these goals, including mean time-to-resolution (MTTR) and total incident count.

    As it turns out, however, these metrics actually work against your company’s resilience goals. To understand why, let’s look at the industry that birthed most of our modern incident management practices and has learned the most about how to properly apply them: the airline industry.

    What the Airlines Can Teach Us

    From the 1950s to the 1990s, the airline industry built and refined best practices for incident management that we have since simplified and that have been widely adopted across the tech industry. What’s often termed “modern incident management” simply means the predictable and repeatable approach to handling unexpected disasters and the learnings-driven remediation steps that are prized when building a DevOps or SRE practice.

    One of the most important findings to come out of this research is the somewhat surprising fact that incidents weren’t being declared often enough. Instead, incident reports were created and the carefully assembled response and cataloging process was only followed after catastrophic events, which meant earlier opportunities to catch the underlying problem during a less severe incident were being missed.

    So why did an industry with such incredibly high stakes take so long to realize that more incidents were actually a good thing? You guessed it: a misguided desire to decrease the incident count. In chasing this goal of “lowering the number,” pilots and mechanics were often reluctant to file incident reports for anything less than the most critical situations, which meant the powerful, learnings-focused response and remediation process was only triggered in response to relatively rare and critical situations.

    This is a textbook example of Goodhart’s Law in action. To paraphrase, Charles Goodhart posited that any metric created will ultimately become the goal. In other words, if the incentives are aligned to reduce incidents, no matter how good your response and learning process is, it will only be executed in the most dire and unavoidable circumstances. After discovering this, the industry rapidly moved their focus towards expanding the use of the incident process by working to expand the spectrum of situations that could be classified as incidents with the goal of triggering the formal incident response process more often, distributing learnings for more incidents of lower relative severity and, yes, ultimately resetting the goal to increase the number of incidents.

    This approach effectively turned Goodhart’s Law to the airlines’ advantage—any effort to game the metric(s) meant more learning, not less. Filing incidents became directly and heavily incentivized and these metrics were never used as a justification for punitive action. This resulted in the safest decade of commercial aviation on record, with over 12 billion passengers traveling and no fatal accidents.

    What IT Can Learn About Successful Incident Response

    As technology companies, there is much for us to learn from this exercise in achieving resilience versus chasing “lower numbers.” The primary learning is this: increasing your incident count by incentivizing the use of your incident management process for more non-critical incidents—likely your SEV2s and below—and focusing your metrics and incentives on that goal, is likely the best way to reduce your overall count of catastrophic failures.

    For most companies, this means putting MTTR on the back burner and instead focusing on making the incident process itself more accessible throughout your company and across your organizations. It means leaders should talk about impactful and recent postmortems publicly and that postmortem distribution should be a priority; it should also be something that’s measured. Most importantly, it means opening up the incident management process more widely. Ideally, everyone at your company should have access to systems that allow them to file incidents, read incidents in progress and review postmortems from previous incidents.

    I like to reference the “big red button” philosophy of factory floors, where the decision-making power to declare an incident is in the hands of every employee. An unsafe situation shouldn’t be up for discussion, debate or approval before being acted on, even if the situation is later determined to be less severe than originally thought. The context of why that incident was filed—why that big red button was pressed—may prevent larger, more catastrophic failures in the future.

    So if you’re just getting started building out an incident management practice at your company, or you’ve been chasing MTTR metrics and focusing on pushing your incident count down as a primary goal, consider taking these learnings to heart and creating a positive incident culture with positive metrics meant to encourage and reward incident responders and reporters. Your company’s future depends on it.

  • Visualize Logs to Get More Value from Data

    Visualize Logs to Get More Value from Data

    Why do you keep logs? Regardless of the type of logs we’re talking about, you keep them because you expect them to provide some value for the organization. Maybe the logs will help you improve profitability; perhaps they will help you recover from downtime or perhaps they are expected to alert you to a security incident in progress. If you’re a system administrator or someone tasked with infrastructure reliability and maintenance, you’d agree that logs are critical. They represent the source of truth you go to for information about your server status and activity, website traffic, application performance and much more.

    No matter the intended purpose of logs or how you use them, the information in these logs should be easy to access and interpret. Today’s complex systems generate enormous amounts of log data, making it almost impossible to dig through tons of data in raw text files to find important information. Finding valuable information is immensely difficult in text logs but not in the visual world. This is precisely where log visualization comes into play. What if the data in your logs could transform into graphic shapes and patterns? Wouldn’t it be much easier and faster to decipher information from log data and understand it better?

    What are Logs, and What are They Used For?

    Before going any further, let’s make sure everyone is on the same page about the meaning of logs. A log is a textual, timestamped record that tells us what happened and when. DevOps engineers have to rely on a combination of logs from various system components and data sources to understand why an event occurred, and perhaps even predict future events.

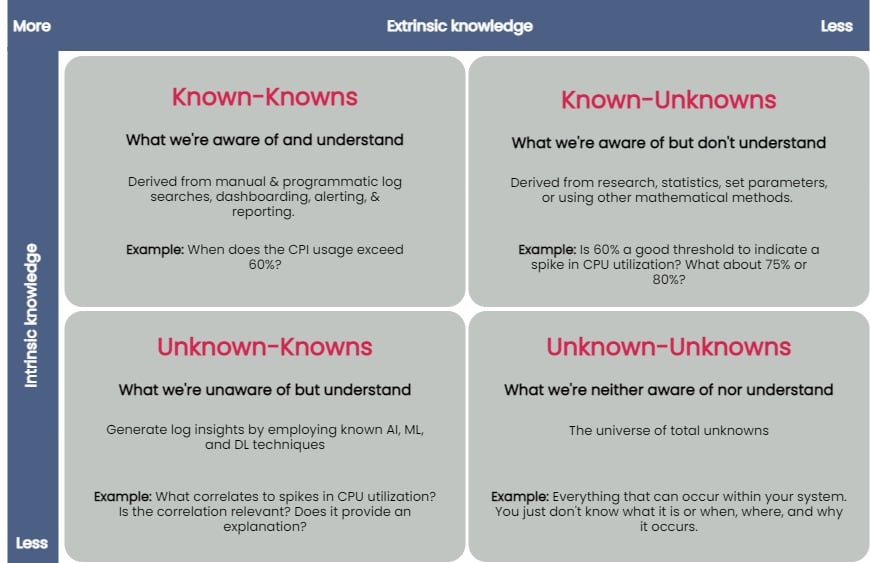
    logs value unknown


    You can taxonomize knowledge extracted from log data into four key groups: known-knowns, known-unknowns, unknown-knowns and unknown-unknowns. Manual and programmatic log searches, dashboarding, alerting and reporting manually extracted log fields are common ways to extract and analyze known-knowns. These methods assume that the engineer is already familiar with the data and knows where to look for answers. You can use statistics or other mathematical means to algorithmically resolve the known-unknowns, such as search terms and thresholds. The unknown-knowns are taken care of using AI/ML/DL techniques that generate log insights such as event correlations, log pattern clustering and known anomaly detection. But what about the unknown-unknowns?

    Uncovering Unknown-Unknowns

    With raw text logs, it’s relatively simple for engineers to conduct machine searches or set alerts upon encountering certain specific errors or specific types of behavior. However, to search through logs or even set up alerting parameters requires you to know what you’re looking for. If you have no idea what kind of errors or threshold limits for which you need to be alerted, it’s impossible to set these up.

    Modern applications are incredibly complicated, and one can not honestly understand everything about how they work or even always ask the right questions when things go wrong. But if an engineer reviewing logs doesn’t even know what to search for, it becomes impossible to figure out without an assistance tool like a purpose-built log visualization solution.

    For the most part, none of the techniques used to uncover the known-knowns, known-unknowns, and unknown-knowns of log data can help reveal the unknown-unknowns. An effective way of unraveling them is to rely on human intelligence to explore the unknown-unknowns space. Supplementing human intellect with a purpose-built log visualization tool can significantly help analyze the unknown-unknowns. Once you’ve recognized the unknown-unknowns, you can quickly feed this knowledge back into the appropriate, less esoteric groups (known-knowns, known-unknowns and unknown-knowns) and get more value from your log data.

    A good log visualization tool can aid in gathering knowledge from unknown-unknowns and can inform proactive log analysis or fast reactive log analysis use cases. Current log analysis practices center around reactiveness; the focus is to minimize and resolve issues after a problem has occurred. Using a log visualization tool, you can quickly isolate subtle and anomalous changes within a system by visualizing patterns generated from log data and exploring unknown-unknowns before an incident occurs.

    Current log visualizations are limited in display log count distribution and its variations. They do not visualize other log attributes or log combination attributes.

    All the UIs shown have similar function usage and displays. Drilling into an example of UI windows gives one the feeling of a typical log analytics practice. The figure below annotates different log analysis functions in the labeled, boxed area. None-visual log analytics functions such as search, tag, and log display are all required time-range input.

    log metrics annotate UI

    An ideal log visualization tool should not rely on just one information type. Log data is multifaceted. A log visualization tool can only begin to be valuable when it lets you focus on as many facets of log data as you can derive.

    Log Visual Pattern Discrimination

    The power of log visualizations comes from humans’ ability to recognize visual patterns. It’s hard to spot a pattern among raw log data, but it becomes easier once you can visualize that data.

    When an experienced DevOps operator looks at a log visualization, they can easily see where the anomaly is, even with no previous understanding of how the system works or where the anomaly might be coming from.

    Visualizations allow engineers to identify visual patterns and quickly understand what is going on in the system—whether it’s a hack in progress or an error causing a poor user experience. Visualizations are compelling, as they help shed light on important events, even if the engineer has no idea where to look or had no idea there was a hack going on in the first place.

    For instance, consider a scenario where a complex system generates millions of logs daily. Suppose we were to establish a baseline of the number of logs the system would generate when functioning normally. In that case, we’d have to take a daily count over a couple of weeks, or at least a month, to deduce a good-enough baseline.

    Even if we derive an acceptable baseline, we’d have to keep recording daily counts and compare it with this baseline to detect an anomaly. Doing this can be time-consuming and counterproductive as you might end up discovering an anomaly when it’s already too late to take any action.

    Once we plot logs daily on a graph, we can immediately figure out the baseline by observing it visually. Once we’ve visually established a baseline, we can instantly identify anomalies when we see values plotted above or below that established baseline. The following image visualizes logs ingested over ten days, illustrating how simple it is to establish baselines and identify when a system is doing something outside its usual behavior. This graph can deduce the baseline to be around 38,000 log records, with anything above denoting abnormal behavior within the system.

    log visualization

    Better Log Visualizations

    There are a few essential criteria for creating good log visualization analytics. They are:

    Use original log data. Data strategy is important. Most log data is unstructured by default, and many organizations tend to convert it to structured data before doing anything else with it. Doing so is a mistake, as you can lose vital pieces of information in the process. Good visualizations should be based directly on the logs exactly as the system produces them.

    Log data consistency. The format for the visualization should be consistent because if there are constantly changing variables, it becomes harder for humans involved to spot patterns.

    Choose robust log attributes and use them wisely. Instead of using just one log attribute for visualization (such as time distributed log density), you should look at visualizing more facets. Doing so gives analysts a better grasp of—and an intuitive understanding of—the log data set. For example, multiple pictures of an elephant taken from different angles help people understand elephants better than showing them only a single photo of an elephant taken from one angle. Similarly, if we break down logs by each of their attributes and then plot their frequency, we can better visualize how a system is performing. However, the attributes you pick are critical to providing valuable visualizations.

    With modern systems becoming even more complex, deciphering logs and uncovering unknown-unknowns will never be easy. The time is right to introduce new log visualization techniques to handle these unknown-unknowns. With log visualization becoming more user-friendly, you no longer need to count on people to be familiar with log interpretation or be aware of statistical, mathematical or AI techniques to analyze log data. Visualizing log data is not just a decision-making aid to human intelligence, discriminating between what is and isn’t acceptable and quickly identifying and remediating issues—the knowledge gained from unraveling the unknown-unknowns also helps advance AI/ML and automation techniques used to ascertain the knowns of your log data.

  • Using ML/AI to Support Infrastructure Monitoring

    Using ML/AI to Support Infrastructure Monitoring

    Successful infrastructure monitoring enables IT teams to ensure constant uptime and performance of their company’s systems. Technologies like machine learning (ML) and artificial intelligence (AI) benefit infrastructure monitoring by more quickly collecting and analyzing data from all of the hardware and software components that comprise the IT stack. Infrastructure changes are occurring faster than ever before, but complex systems, the unique nature of applications and lack of IT skillsets can cause challenges when integrating with these newer technologies. However, it’s more important than ever that sysadmins and DevOps teams understand how ML and AI can mitigate these roadblocks, support them in staying on top of infrastructure performance and rapidly address issues that arise.

    Intelligent Monitoring Support for Complex Systems

    The most tangible result of intelligent infrastructure monitoring tools and processes is near-immediate alerting of performance and uptime issues, which can then be addressed in an efficient and effective manner so no business interruptions occur. However, complex systems can stunt these benefits if ML and AI are not being used and manual monitoring protocols are still in place.

    Tools that use ML or AI lessen the work of IT staff immensely, freeing up critical business resources and aiding in overall productivity. Both technologies can automatically identify and update all IT stacks that comprise an enterprise’s infrastructure to keep systems up-to-date and aligned with established key performance indicators (KPIs). In addition, intelligent offerings can detect and factor those metrics against set standards so that early alerts to an “unhealthy” section of infrastructure can be identified, even as the IT stack is constantly changing. This drastically speeds up troubleshooting efforts.

    Differentiation in Applications

    The different applications supported by the various IT stacks will most often have unique service-level agreements (SLAs) for their performance and uptime, as well as remedies or penalties should those service levels not be achieved. Plus, system loads that stress the underlying infrastructure are frequently changed. For these reasons, it is important to identify what constitutes a “healthy” IT stack so that these minute parts of the infrastructure are not overlooked due to the variation involved.

    ML and AI can be programmed to track system baselines that support a “healthy” IT stack. These technologies are particularly great at finding novel and unusual patterns in data. As the monitoring and observability landscape becomes more complex over time, driven by real changes in how developers build applications and systems, the ability to spot and detect such patterns in data can be crucial in helping make sense of it, further cutting down efforts on manual searching, detective work and “death by dashboards,” which we’ve all experienced at one time or another.

    Supporting IT Team Skills with Intelligence Technology

    The role of sysadmins—and to a greater extent, developers—has shifted over the past few years to become nearly as complex as the infrastructure they oversee. Nowadays, it seems as though developers are required to have expertise in all aspects of infrastructure, from monitoring to Kubernetes to machine learning. This can take quite the toll on developers who possess such skills, but in a more realistic sense, developers that can do all these things are very hard to come by. The lack of these skillsets is pervasive in the industry, which is why ML and AI can be seen as supporting technologies—they can fill in these gaps, to an extent.

    With built-in intelligence and automation, ML/AI can enable even the most inexperienced sysadmin or DevOps professional to monitor complicated infrastructure like a pro, taking on most of the time-intensive work around collecting and analyzing the data and identifying where to troubleshoot. The main goal is to put humans in the driver’s seat, utilizing ML and AI for granular discovery of system issues, providing the metrics or charts that might be most relevant to IT staff as they troubleshoot their system and reducing the cognitive load of developers.

    With the vast benefits that intelligent technologies possess, integrating them into your IT stack can help mitigate challenges experienced with complex systems, application differentiation and the skills deficit experienced in the IT team. The important ingredient in making ML and AI effective in infrastructure monitoring is using tools that incorporate the right formulas, algorithms and automation that can best help determine success when it comes to your desired outcome.

  • Decentralized Autonomous Organizations (DAOs): Org-as-Code

    Decentralized Autonomous Organizations (DAOs): Org-as-Code

    We are all familiar with ‘everything-as-code’—a pattern that started with infrastructure-as-code and has now extended to other areas such as architecture-as-code,  security-as-code and more. However, all the incarnations we have seen so far have been less than ambitious! The dawn of cryptocurrencies and the underlying blockchain technology is moving us firmly toward organization-as-code. Org-as-code is the most disruptive evolution we have seen so far. The crypto world uses a different term for it: decentralized autonomous organization (DAO).

    Before you freak out because, “OMG crypto!” let me assure you that I am not trying to sell you any of the 9,000 (at last count) cryptocurrencies. Undoubtedly, crypto has polarized public opinion. There are crypto maximalists who believe that crypto is the solution to everything. You often hear, “Bitcoin solves it!” Then, there are the crypto skeptics who dismiss the movement as simply digital tulips—a Ponzi scheme at scale for the internet age. Only time will tell if they are right.

    Now, my opinion falls in the gray area in between, where some groundbreaking new ways of working are evolving. People across the globe are collaborating in decentralized, efficient, democratic and non-hierarchical ways in the world of crypto. Radical new constructs for the internet age are being piloted—DAOs, smart contracts, pseudonymous identities, tokenomics, etc. just to name a few.

    This post is firmly focused on DAOs.

    So, What is a DAO?

    A DAO is a way to work with like-minded folks around the globe where the business (the org) is owned and managed by its members in a democratic way.

    “In traditional organisations, people are at the core and automation is at the edge; whereas in DAOs, automation is the core and people are at the edge.” – Vitalik Buterin

    As opposed to traditional organizations that are structured in a top-down hierarchy, with many layers of management and bureaucratic coordination, DAOs provide an operating model for people and institutions that do not know nor trust each other, who might live in different geographical areas, speak different languages and, therefore, are subject to different jurisdictions. Instead of legal contracts managing the relationships between people, computer code enforces the rules.

    Some of the key features of a DAO are:

    1. An organizational setup based on rules and policies that are encoded as computer code.
    2. The rules are transparent and controlled by members, not a central authority; usually, on a public blockchain.
    3. Rules are executed by a set of smart contracts independent of human (not even the creators!) involvement.
    4. Built-in treasury that no one has the authority to access without the approval of the group/community.
    5. Decisions and ideas are governed and funded by proposals that are voted on and managed through voting by token holders.

    Colony.io is one startup that helps set up DAOs. A screenshot below from their site gives you an idea of the elements of organizational design that can be (re)defined in the radical new DAO world.

    DAOs features

    Do We Really Need DAOs ?

    Here are a few challenges that DAO attempts to resolve that you often see in conventional centralized organizations:

    • Good ideas struggle to reach the top.
    • The system incentivizes authoritarian leadership.
    • Failure to tap into the wisdom of the crowd.
    • There is a higher probability of spectacular failures driven by the greed of a few, as evident from examples such as Enron or the 2008 financial crisis.
    • There is usually a lack of transparency in decision-making.
    • Good policies exist—usually on paper or hidden away in by-laws—but are not executable.
    • Single points of failure are natural due to the asymmetry in organizational structure.

    Examples of DAOs

    Before you dismiss this as utopian and unrealistic, here are a few real-world of examples of DAOs in play

    1. Nexus Mutual—A decentralized ‘people-powered’ alternative to insurance which operates as a DAO. It is run entirely by its members. Only members can decide which claims are valid. All member decisions are recorded and enforced by smart contracts on the Ethereum public blockchain.
    2. DAI and MKR—A stable decentralized currency (DAI) and platform for decentralized finance apps (with a market cap of about $5 billion).
    3. The DAO ( Đ)—A form of venture capital that started as a crowd-funded token sale. There was no conventional management structure or board of directors. But it got hacked in 2016, and a third of funds were siphoned off. (This is a key example to remind ourselves that if the org is code, then security issues can be near-fatal.)
    4. DASH —A digital cryptocurrency. A DAO run by a subset of users called masternodes, which perform standard node functions like hosting a copy of the blockchain, relaying messages and validating transactions on the network, and which, in addition, act as shareholders, voting on proposals for improving DASH’s ecosystem.
    5. Flamingo DAO—A DAO that deals in digital art via NFTs. NFTs are non-fungible tokens, not non-functional testing!
    6. Gitcoin —Uses DAO to fund digital public good projects ( $24 million funded so far using a quadratic funding model)

    These are just a few examples. Adoption is exploding, and stretching into areas like charities, freelancer networks, venture funds, investment clubs and more.

    DAOs are still emerging, and there are many aspects that are yet to be fully explored, especially around legal status, regulatory frameworks and compliance. It is, however, only a matter of time before the DAO way of working becomes mainstream.

    In my view, it is not a binary question between DAOs and conventional organizations. Adopting many of the practices of DAOs will strengthen traditional organizations and reduce some of the weaknesses we touched on earlier.


  • Best Practices for AWS Tagging With Yor

    Best Practices for AWS Tagging With Yor

    On the surface, AWS resource tags are simple, informational key:value metadata that you can assign to most AWS resources. They also have many hidden benefits, as outlined in this AWS Tagging Best Practices guide for improving cloud operations. There are six use cases author Brian Yost calls out in particular:

    1. AWS console organization and resource groups
    2. Operations support
    3. Cost allocation
    4. Access control
    5. Automation
    6. Security risk management

    In summary, tags can simplify operational processes, improve security posture, speed up mean time to resolution (MTTR) and even save money if implemented consistently and persistently. But, unfortunately, in large organizations, that’s a tedious and often faulty process.

    To help teams overcome that challenge and make the most of cloud resource tags, Bridgecrew (recently acquired by Palo Alto Networks) recently launched a new open source tool, Yor. Yor is designed to automatically add consistent, helpful tags to infrastructure-as-code (IaC) templates starting with Terraform, CloudFormation and Serverless Framework. If run locally or added to a continuous integration (CI) pipeline, Yor will add tags like git organization and repository, unique trace ID and commit modifier details to IaC resources that carry through to cloud resources. For example, with Yor, you can tag your aws_instance code block in Terraform, and those tags will show up in your running EC2 instances.

    This post will explore how to leverage Yor to achieve the six tagging use cases outlined in the AWS Tagging Best Practices guide.

    AWS Console Organization and Resource Groups

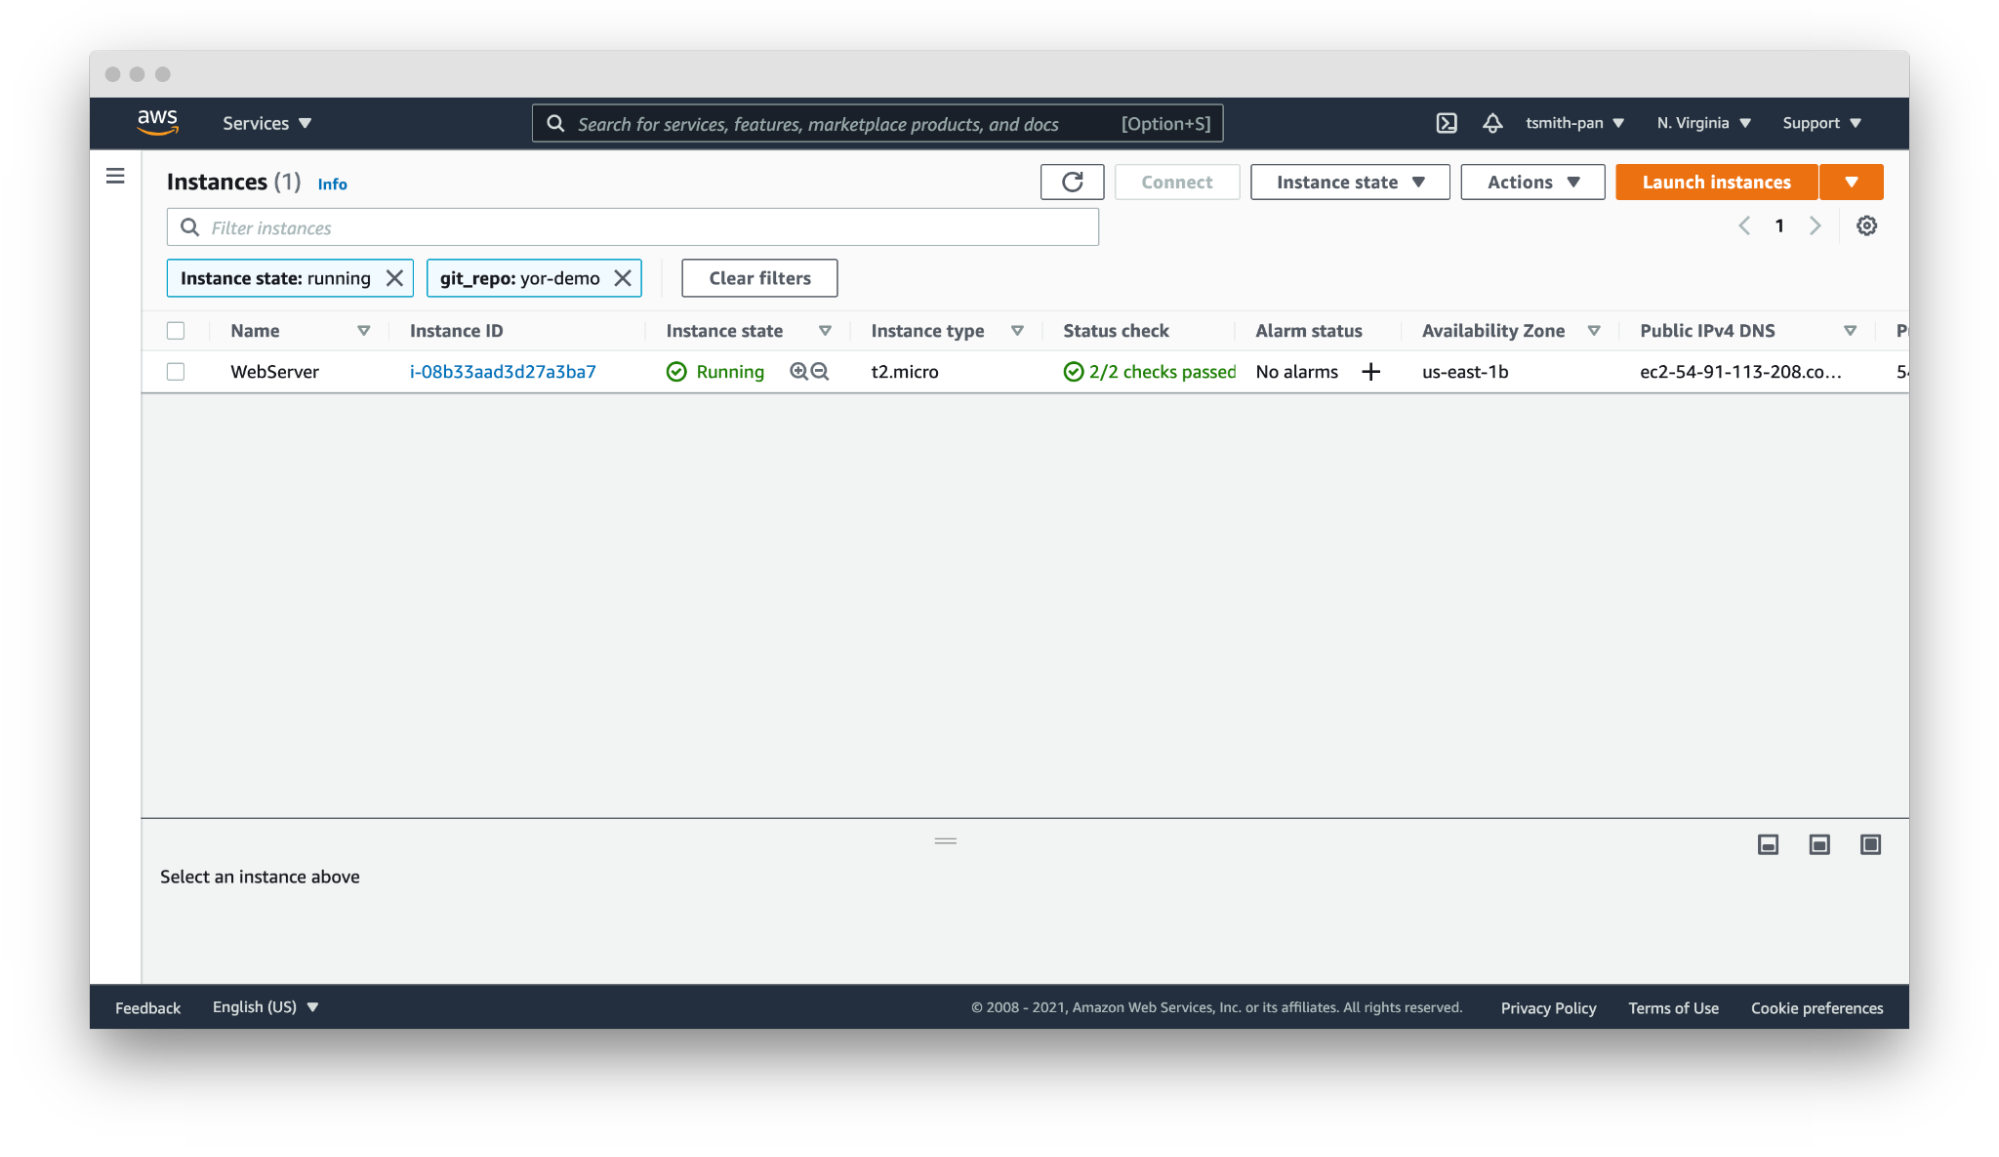
    Using tags to organize and filter resources is the simplest and most common use case for tags. If you add tags to resources, such as EC2 instances or database resources, you can filter based on those tags. 

    If your AWS account has thousands or tens of thousands of resources in a region, filtering is necessary to manage those resources. For example, if you have hundreds of web servers, filter by the git_repo tag Yor added to quickly filter down to the web server(s) for your application.
    Yor

    In that same vein, you can set up resource groups to organize multiple resources across AWS services based on tags. For example, if you want to hunt down the VPC, EC2, internet gateway or database created by your Terraform repository, use Yor’s git_repo tag to group together multiple resources into a single resource group.


    Yor 

    Operations Support

    Yor excels at simplifying and speeding up operations support. In the words of Brian Yost, “For example, Level 1 support teams could use tags to direct workflow and perform business service mapping as part of the triage process when a monitoring system triggers an alarm.” Yor automatically tags resources with the git organization and modifiers of the cloud resource. This makes it easier to identify the right team and user to patch issues. 

    If you work in a GitOps organization, this is even more critical. Following GitOps best practices means all changes should be performed in the IaC template, not directly on the cloud resource. So if your security team identifies an open port 22 in runtime using policy-as-code or CSPM tools, such as Bridgecrew, Yor’s tags will make finding the owner of the IaC template easier and faster, lowering MTTR.

    Yor takes this a step further. By adding the repository, file and trace tags, Yor helps teams identify not only the code owner but also the exact file and resource block that created that resource misconfiguration.
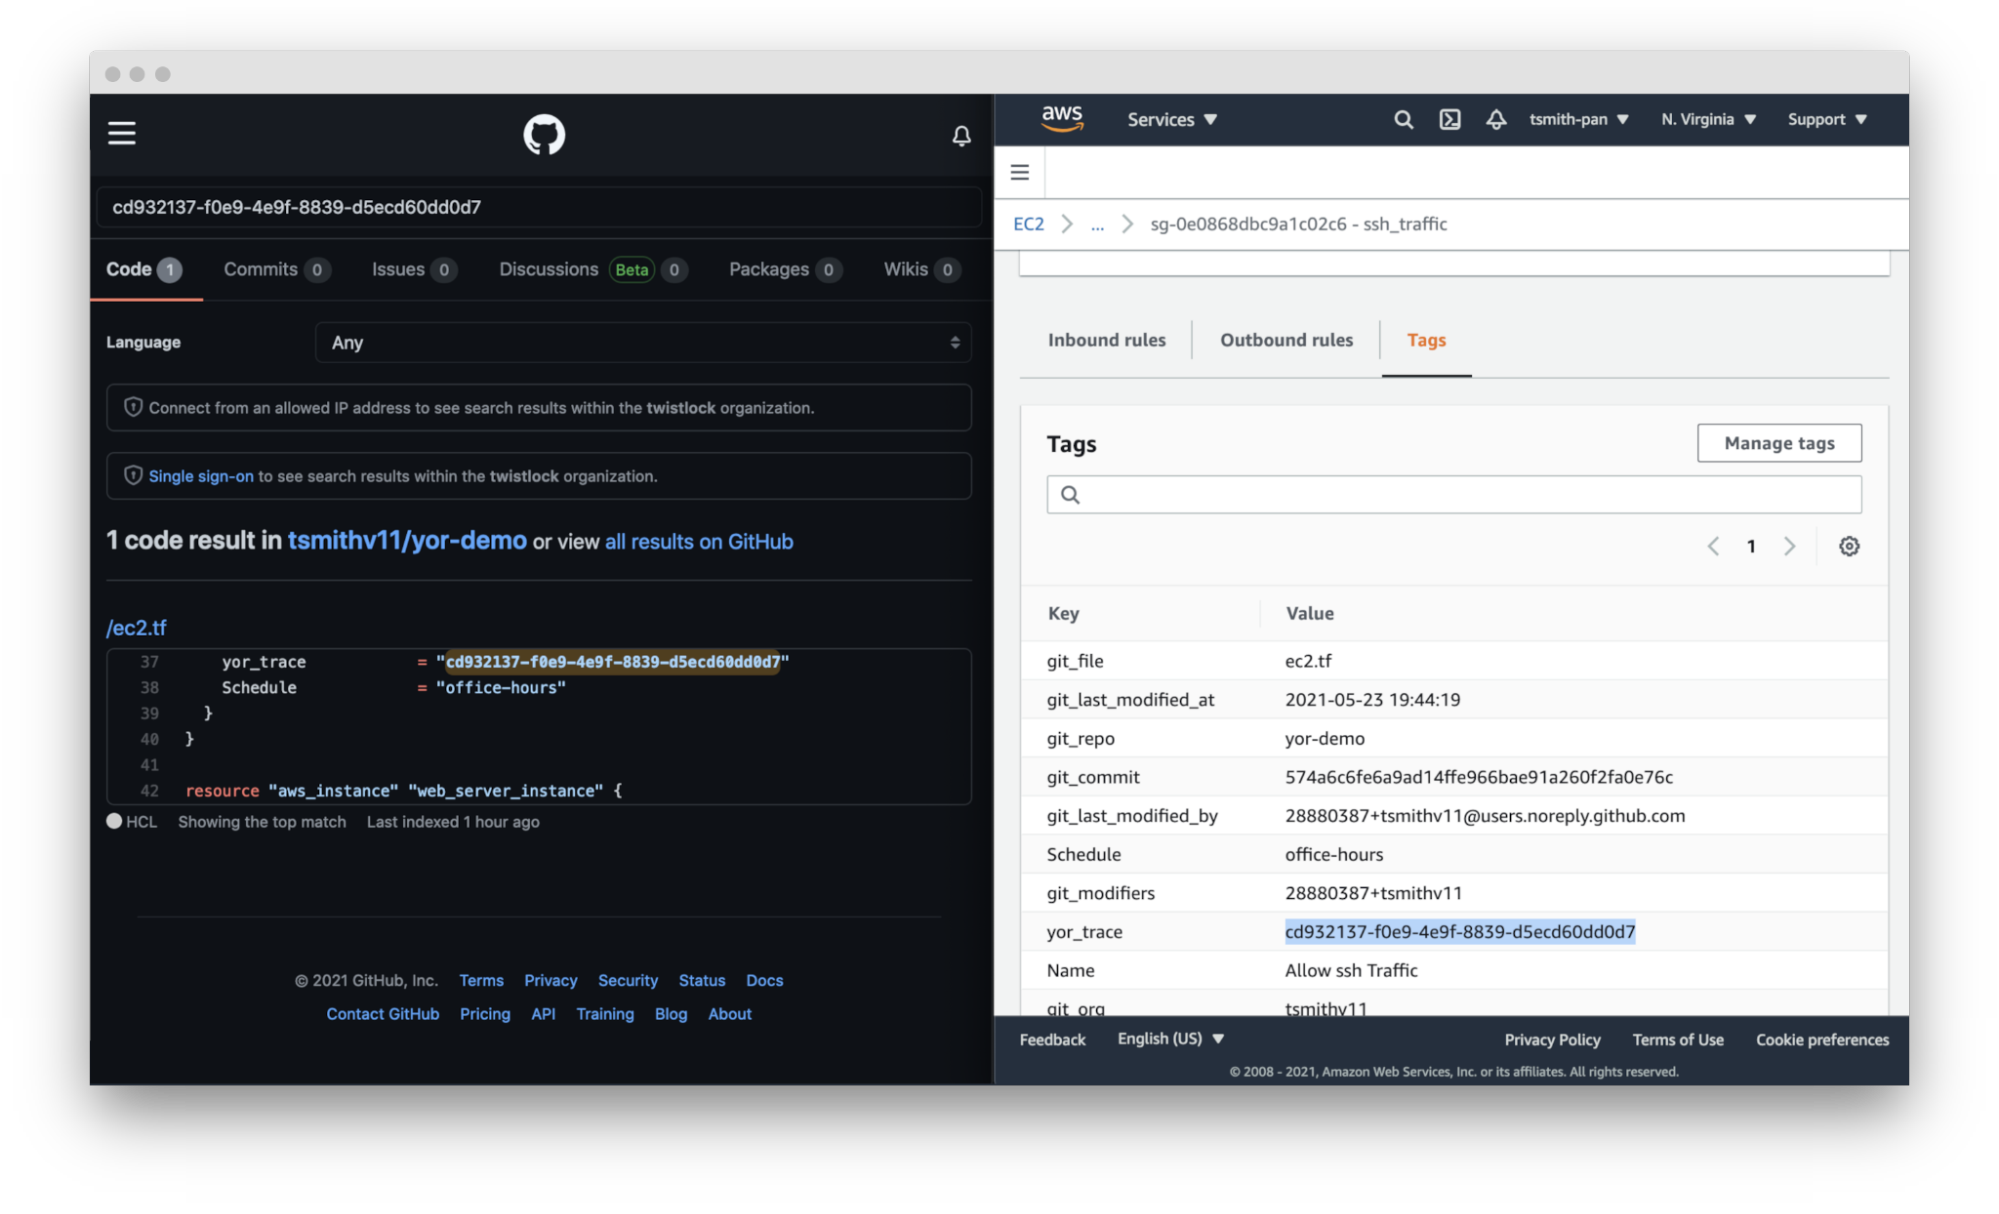
    Yor

    Cost Allocation

    Large companies often have different profit and loss (P&L) statements for each of their business units. At the end of a reporting period, such as a fiscal quarter, finance teams allocate the expenditures made across the company to the various cost centers.

    For traditional IT teams, this usually involves very broad, general estimates. For example, if two organizations share a server rack, you could allocate costs based on virtual CPU time or disk space. Once that scales into dozens of organizations and ephemeral workloads, that allocation is much more difficult. Cloud costs can be just as difficult to allocate. If you have thousands of resources across types (virtual machines, serverless, managed Kubernetes workloads, managed databases, streams, CDNs, etc.) with differing life cycles and life spans, tying those resource costs back to a cost center is difficult.

    Cloud tagging simplifies that process. Assuming each team has a git organization, Yor will automatically tag resources with the git_org or custom tags can group git_modifiers into cost center tags, and AWS Cost Explorer will let you filter by those tags to easily allocate costs. You can also export those costs by tag(s) to a CSV file for import into other tools for analysis.

    Yor applies those tags reliably and consistently so that finance teams don’t need to dig through different organization name versions, such as combining dev_team_one and devTeam1, or manually categorizing untagged resources.
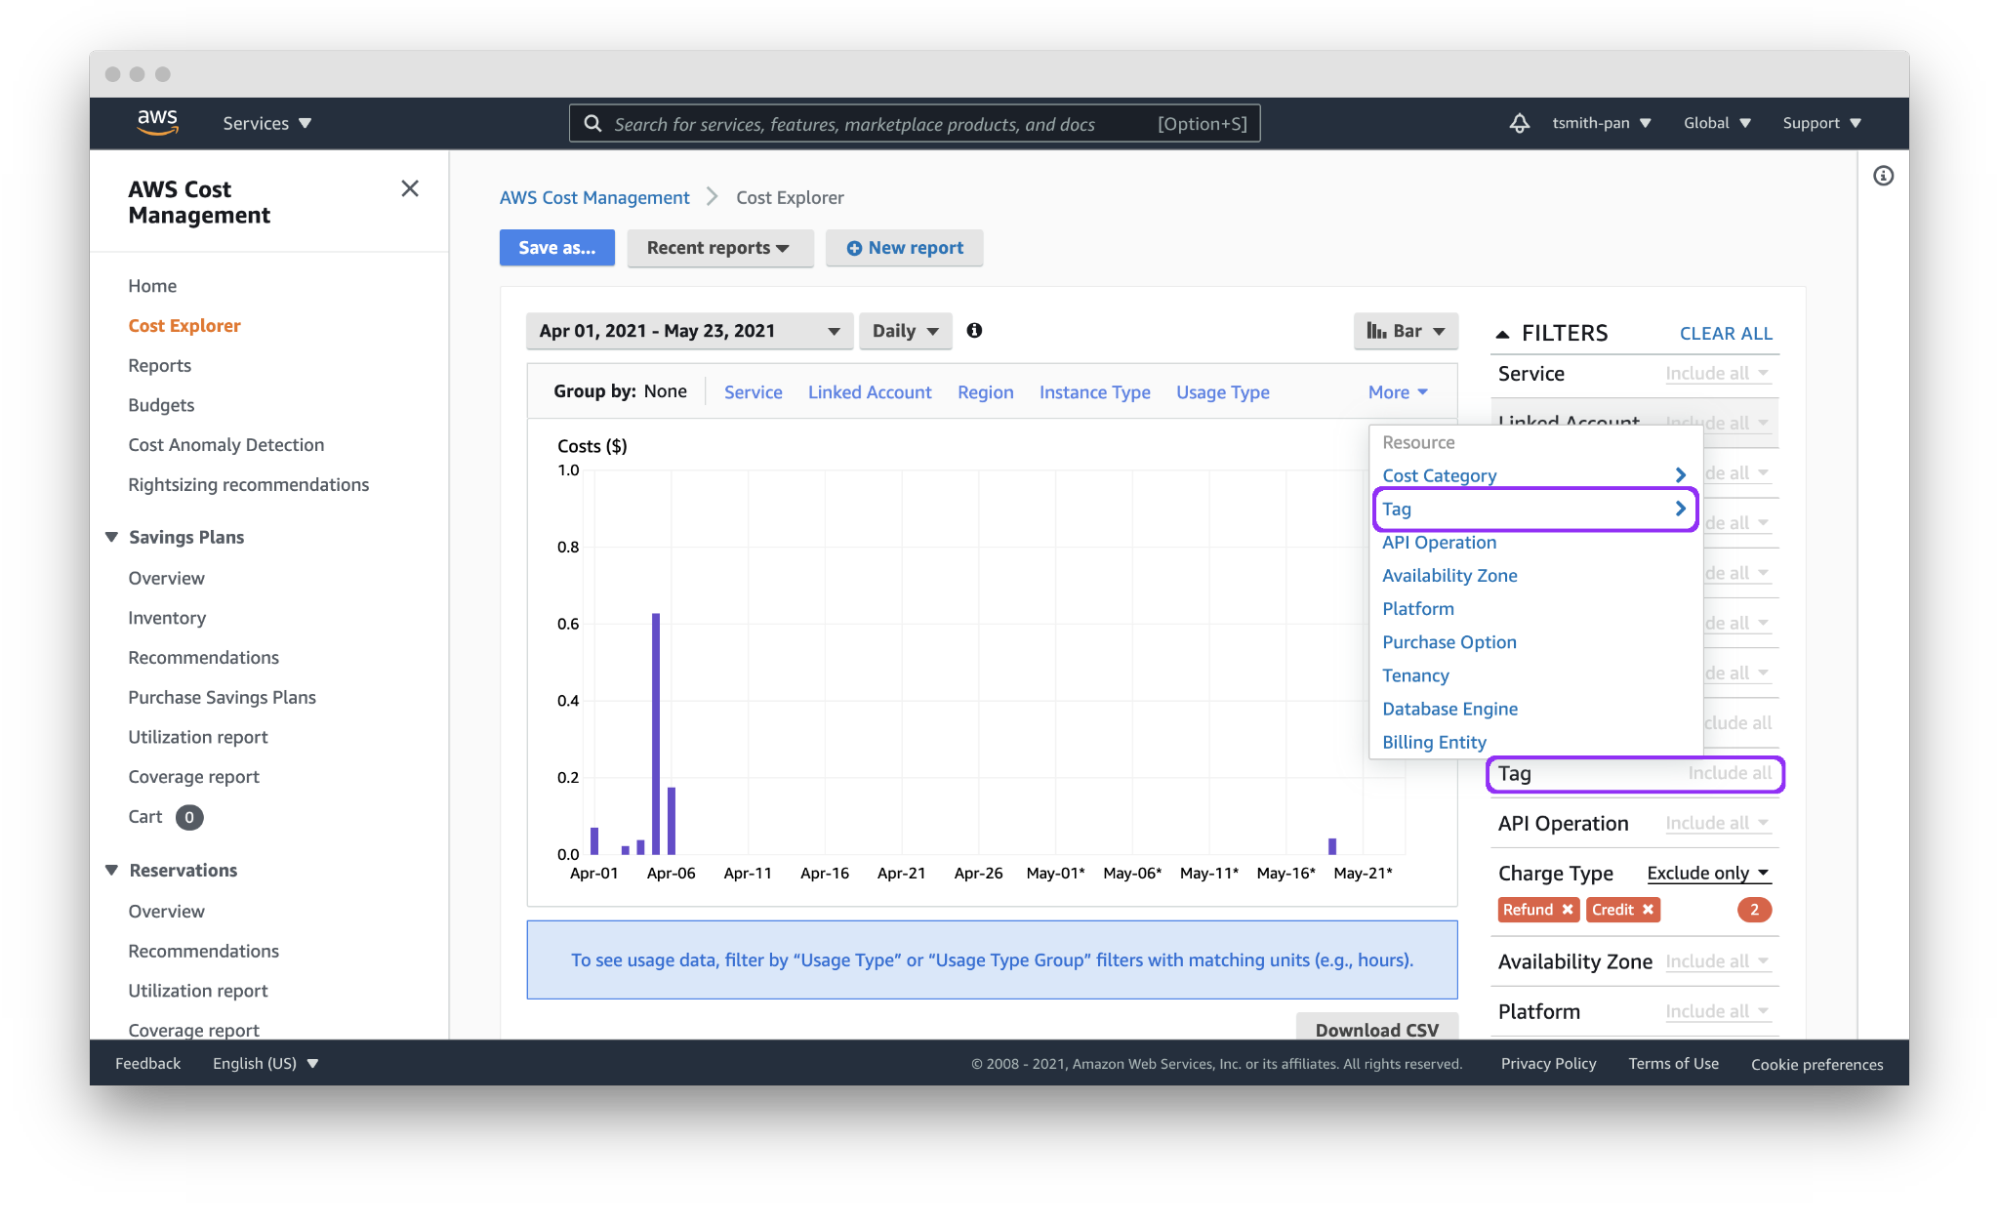
    Yor

     Access Control

    AWS identity and access management (IAM) policies support the ability to limit control of resources using tags. This simplifies dividing up resources by teams using complex IAM rules.

    For example, if you want developers to access only the EC2 instances they provisioned, you can use the git_modifiers tag added by Yor. Yor will automatically tag resources with the git users who edited the IaC code. Then, Yor will add an AWS IAM policy to limit access based on that tag.  You’ll also want to add a policy to deny actions such as ec2:CreateTags and ec2:DeleteTags so users can’t just add themselves to other resources.

    This is where Checkov, an open source policy-as-code tool, can be leveraged for additional control. Yor can enrich the context for Checkov’s checks, enabling finer-grained policy control. For example, Yor will populate the user identification of whoever modified an IaC template, and Checkov can make sure that only approved team members modified the code. The following is an example of a custom check to determine that only security personnel modified CloudTrail settings.

    If the git_modifier tag added by Yor is anything other than “Nimrod,” “Rotem,” or “Naor,” Checkov will show a failed policy check for that custom check for that resource.

    Automation

    By leveraging tags in combination with other tools, such as Lambda functions and backup plans, you can apply automation to specific resources, such as targeting resources for archive, update or deletion.

    The AWS Tagging Best Practices guide uses as an example a situation where development resources are turned off during non-business hours. AWS recently released a tool called Instance Scheduler for just such a use case. It is a CloudFormation stack with a Lambda function and DynamoDB instance that automatically starts and stops EC2 and RDS instances based on a pre-defined schedule. 

    Instance Scheduler takes a tag with a key:value pair; for example, “Schedule” (or a custom key) as the key and the schedule as the value. The schedules can be either one of the preconfigured schedules in the DynamoDB table, like office-hours, or a custom one.

    Using simple custom tags in Yor, you can tag every resource in a repository with a schedule by using environment variables such as adding the following to the Yor GitHub Action YAML file:
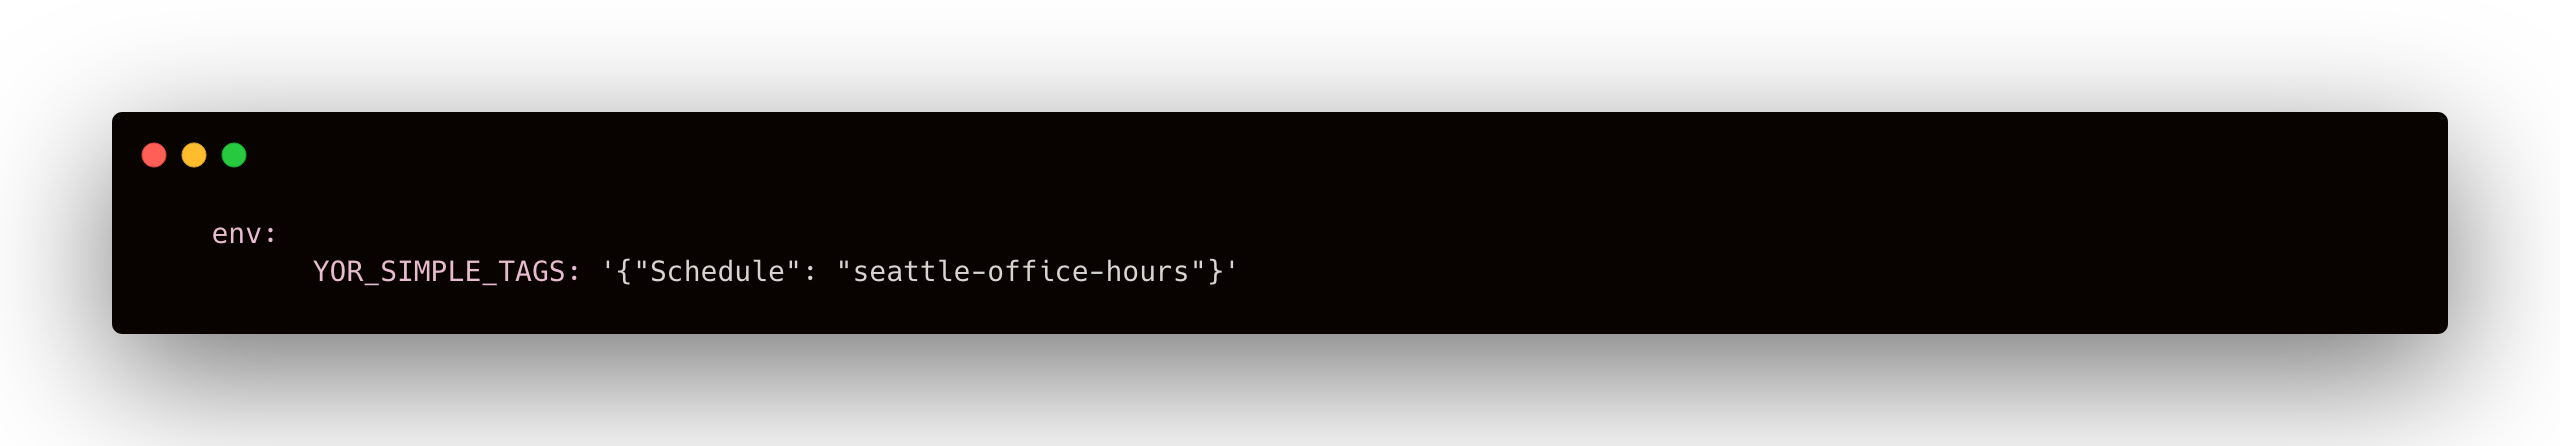
    This results in tags being added to every resource in that IaC directory. With the seattle-office-hours tag, Instance Scheduler will turn off EC2 instances at 5:00 pm Pacific Time and on again at 9:00 am Pacific Time Monday through Friday. This saves money by stopping instances automatically during downtime.
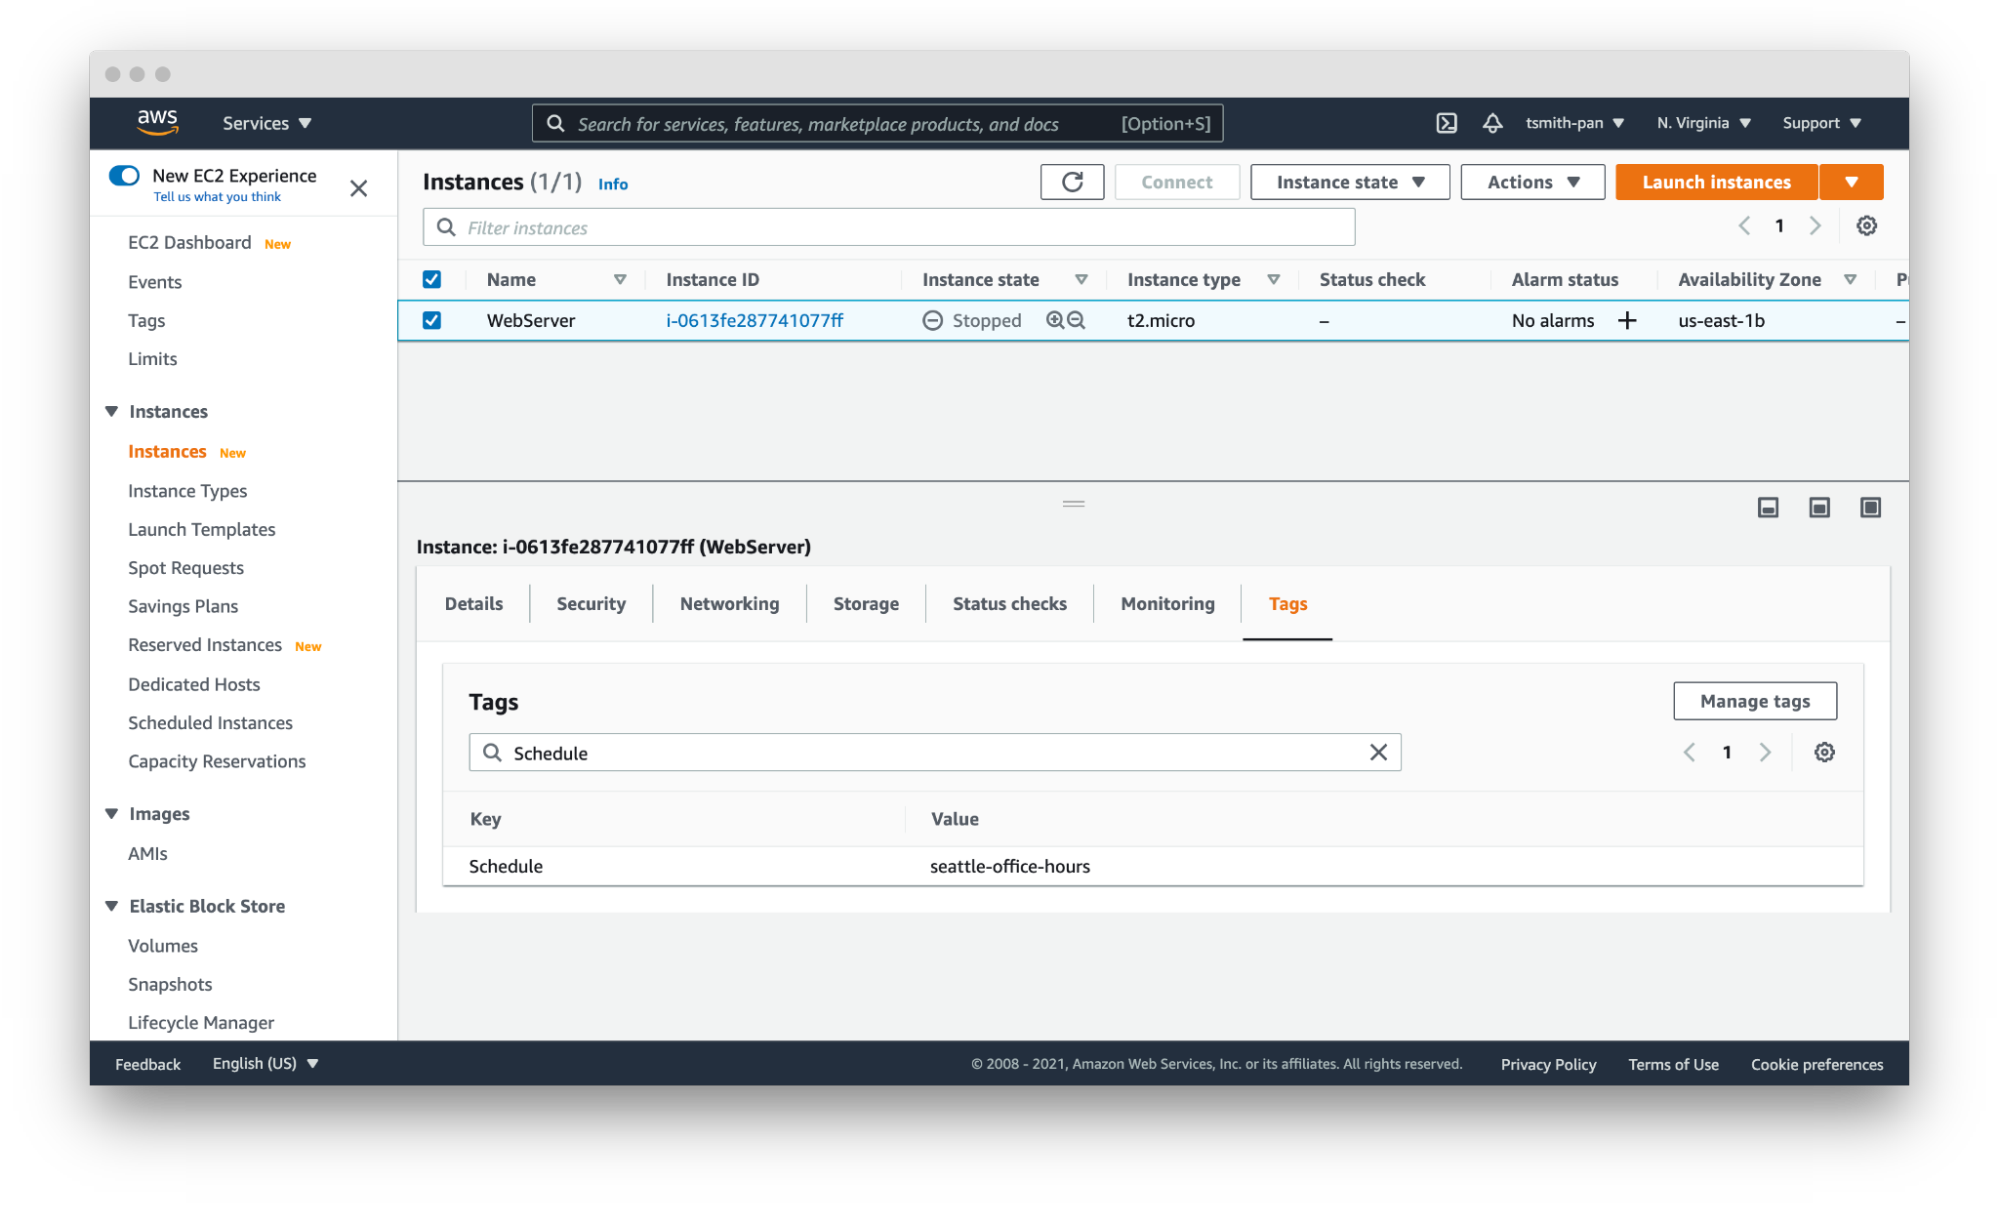
    Yor

    Another popular automation use case is for backups and archival plans. AWS can automatically apply different backup plans based on the tags applied to resources, such as storage and database resources. For example, if certain organizations, such as those that process financial data, need things archived forever, but others only need one year of backup, applying backup plans can move the short-term storage to cheaper options, such as Glacier, and eventually delete them on a schedule.

    Security Risk Management

    The final use case is risk management. The risk level of cloud resources differs based on whether they are in test or production environments and the sensitivity of the data those resources process and hold. This is another area where you can use simple tags like git_repo to filter down to repositories for applications that deal with sensitive data. You can also leverage complex custom tags. For example, EC2 instances attached to databases with “customer” in the name will get a data_level:sensitive tag.

    IT service management tools can apply higher priority to patching and updating resources with tags denoting sensitive data. This is another area where you can leverage Checkov’s graph-based checks in combination with Yor tags to assign higher severity levels to policy violations for resources with sensitive data tags or production environment tags. Assigning priority helps to focus developer attention and mitigate risk faster.

    These six tagging use cases are just a few examples of how you can leverage tags to be more efficient and improve your cloud security posture in AWS. The power of Yor’s tracing capabilities enables development and operations teams to work together without requiring complex triage to find the right person and IaC templates. With Yor’s extensibility and custom tagging capabilities, we can’t wait to see what other use cases the community comes up with!

  • Leveraging the Cloud for Mainframe Access

    Leveraging the Cloud for Mainframe Access

    Now more than ever, organizations around the world are looking to extend their existing mainframe investments as part of larger digital transformation initiatives. As core systems of record and reliability, mainframes continue to run many organizations’ most important applications and the idea of replacing these systems comes with greater risk than reward. While organizations are considering modernization of their mainframe investments, it’s important to remember that maintaining mainframe access and offering new ways for their users to work with the data and systems is a vital part of the larger project.

    Leveraging the Cloud for Mainframe Access

    With the recent increase in remote work, it’s no surprise that more companies are looking to leverage the cloud for mainframe access. This has many benefits from increasing scalability, availability and performance, to reducing application costs and improving security. Implementing modern mainframe access as part of a larger cloud project ensures that an organization’s modernization journey is not only transformational but also secure.

    If making the decision to leverage the private or public cloud for mainframe access, the integration of a secure host access solution ensures teams have access to the systems and applications needed to do their jobs, wherever they may be located. Deploying this secure access in a cloud environment is made easier by host access administration being integrated and centralized with the corporate user directory. Along with simplifying provisioning and management, centrally managed host access is, most importantly, more secure than other forms of access.

    The extension of enterprise security to the mainframe is sometimes overlooked in a transformation, but it is an integral part of the larger process of strengthening data and system security. In a perfect world, this can best be done through the integration of a host access solution with the existing identity and access management (IAM) system. If this is possible, the authentication credentials that are already in use for authorizing or denying access to the mainframe can be leveraged successfully.

    There are numerous benefits to an IAM integration with regard to access, data, stronger passwords, application security settings and system configurations. With IAM, the benefit of least privilege access means that users can access only the mainframe systems and data that are needed to do their jobs. Additionally, application security settings and session configurations can be changed from a central point by using the user directory. Finally, the stronger credential requirements of the IAM integration get rid of weaker eight-character passwords, strengthening security as a whole.

    Host Access Improves User Experience

    When it comes to host access, having a secure and centralized solution not only improves the mainframe access experience for the user, but also for the administrator. With zero-footprint secure access, users can be moved to a more secure web with higher security standards if needed. Security is also stronger with enterprise credentials that leverage mainframe session authorization to automatically sign them in. The integration of a host access solution gives administrators the ability to quickly deploy secure browser-based sessions, as well as providing web interfaces with no Java required, eliminating workstation dependencies as a result. This is also paired with the use of containers to enable deployment to countless users and support for mobile devices. For these reasons, a host access solution should be a common component in any cloud journey.

    The mainframe and its data, applications and user access remain vital for organizations and it is important that they remain protected and connected. With security being an ever-evolving issue, keeping these core systems secure while ensuring employees are able to access the systems and data they need should always be a priority. In conclusion, organizations looking to leverage the public or private cloud for their mainframe will have more success if they also strengthen their data and system security as part of the process.