Category: IT as Code

  • Datadog Cloud Security Platform Advances DevSecOps

    Datadog Cloud Security Platform Advances DevSecOps

    Datadog has launched a Datadog Cloud Security Platform that promises to advance DevSecOps by identifying potential threats using the same agent software many DevOps teams already rely on to instrument applications.

    Renaud Boutet, senior vice president of product for Datadog, said organizations that rely on the Datadog software-as-a-service (SaaS) platform can now more easily invoke security services based on the same data model used to observe applications.

    The security services provided by Datadog include a cloud security posture management (CSPM) offering that identifies misconfigurations and applications that are not compliant with industry standards such as the Payment Card Industry Data Security Standard (PCI DSS).

    A cloud workload security (CWS) offering, meanwhile, detects threats to production workloads by monitoring file and process activity, while a monitoring tool identifies threats to cloud environments by analyzing operational and security logs. It also provides integrations and threat detection rules that are easy to extend and customize.

    Finally, there is an application security tool, currently in beta, that identifies and blocks attacks that target code-level vulnerabilities, such as SQL injections and cross-site scripting (XSS) exploits.

    Boutet noted that many DevOps teams are reluctant to roll out security platforms that require them to deploy, manage and update an additional set of agents across their application environment. Datadog is now effectively unifying application observability and security in a way that makes it simpler for those DevOps teams to embrace DevSecOps best practices, added Boutet.

    In some cases, the dashboards surfaced by Datadog will be employed by DevOps teams that have assumed responsibility for cybersecurity as part of an effort to shift more responsibility for application security further left, noted Boutet. In other instances, cybersecurity teams will be able to view the same alerts shared with their DevOps colleagues, he added.

    Pressure to address DevSecOps is mounting in the wake of a spate of high-profile software supply chain breaches. While the majority of organizations have not been breached, questions are now being asked at the boardroom level as concerns over application security increase. Many organizations are wondering if they should slow down the pace of application development to ensure better security and to what degree.

    Regardless of the path forward, awareness of application security has never been higher. An executive order issued by President Biden calling for improvements to security will likely have a cascading effect across not just government agencies but also on organizations that do business with those agencies. One way or another, DevOps teams and cybersecurity professionals will be required to work more closely together. The challenge is striking the right balance between security and productivity. Most developers are never going to become world-class security experts. Conversely, most security professionals know next to nothing about coding. That doesn’t mean, however, that efforts shouldn’t be made to educate both camps as much as possible. After all, even a small amount of education can have a profound impact when most of the attacks being made against applications are not especially sophisticated.

  • The SolarWinds Query Report 2021: Database Priorities and Pitfalls

    The SolarWinds Query Report 2021: Database Priorities and Pitfalls

    The rise of hybrid IT and the accelerated adoption of cloud-native apps have evolved traditional database design, management and monitoring. Workloads are rapidly shifting to the cloud and application performance is heavily dependent on the performance of the underlying database. Meanwhile, the global COVID-19 pandemic has forced companies to make significant changes in the last year. Although it was and is a necessity, the transition to remote work and many organizations’ rapid pivots in strategy posed significant challenges for the technology professionals tasked with supporting new employee demands and shifting business priorities.

    As a result, organizations are increasingly acknowledging the importance of database performance management and strategy to ensure their most valuable asset: Data. SolarWinds recently revealed the findings of The SolarWinds Query Report 2021: Database Priorities and Pitfalls, which examines the current state of database management, evaluates the primary challenges database professionals face today and outlines how database professionals can best overcome these challenges.

    The North American results are based on responses to an online survey fielded in February 2021, which included participation from 331 technology professionals responsible for database performance management in the U.S. and Canada from public and private sector small, mid-size and enterprise organizations.

    Among many other key findings, this year’s report revealed the following:

    Increasing Complexity

    Database design and management are evolving in tandem with increased complexity, and IT professionals are on the verge of a significant shift in strategy that embraces cloud database-as-a-service (DBaaS) platforms as critical database performance success factors.

    • Though nearly 80% of the respondents said Microsoft SQL Server is the most critical platform in use today, there’s a relatively even split between the second, third, and fourth most-used platforms: cloud DBaaS (54%), Oracle (47%) and MySQL (43%).
    • As tech pros keep pace with advances in database platforms and indicate an intended shift toward cloud DBaaS adoption (33% of the respondents ranked cloud DBaaS as the number-one priority database platform to adopt over the next three years), the new mix of traditional/cloud DBaaS platforms will also require new skills.
    • Complexity increased in response to COVID-19 and the transition to remote work over the past year, according to 31% of respondents, who cited increased data demands from users, increased volume of data and security/compliance issues (such as GDPR) as the top three drivers of added complexity.

    The industry’s acknowledgment of cloud DBaaS platforms as critical success factors for database performance is now underway. When it comes to cloud migration (especially amidst a pandemic dramatically accelerating planning and execution of cloud computing and digital transformation), database professionals should start with a basic data and code cleanse and ensure only what’s truly needed is being migrated to reduce complexity and overall cost (we know cloud computing costs can add up). A comprehensive, successful migration strategy should also include a detailed assessment of the data estate—what dependencies or complex coding features exist? Remember, everything interconnected with a database has to go with it to the cloud, so taking these preliminary steps will help organizations avoid surprises down the road.

    Database Security/Compliance Influence Priorities

    The cloud and security/compliance are key factors influencing priorities and resource allocation in 2021 and beyond.

    • Nearly 60% of tech pros surveyed stated that of the data/systems currently managed within their organization, less than 25% are in the cloud. But this is expected to change, as 36% of respondents reported integrating cloud DBaaS is one of their organization’s top priorities in 2021.
    • Two-fifths of the respondents anticipated bigger budget allocations in 2021 (compared to 2020) for cloud services and security/compliance (42% and 39%, respectively).

    Managing database platforms is a big undertaking—a balancing act between proactive and reactive responses. But tech pros must make sure they’re covering all their bases, especially when it comes to security and compliance (and, on occasion, cost and licensing). Time and time again, we see these four big-ticket items pushed to the bottom of the priority list, and falling at one of these hurdles can do a great deal of damage. The new generation of legal compliance has real teeth if you fail to comply with the law. A simple cost-benefit analysis can be the proof point you need to highlight the potential impact of not upskilling in one of these areas and can give you a reason to move it back to the top of the priority list.

    Maintenance Constraints

    Database professionals devote more than a third of their day to database maintenance. This constrains both time and opportunity for activities such as innovation and upskilling in response to increased complexity and data-driven initiatives.

    • Maintenance work accounts for a greater portion of database professionals’ time when compared to other tasks. One-third of the tech pros surveyed stated one of the top areas where they spend the most time as a database/data/tech pro is maintenance (33%) and database development (22%).

    Daily database maintenance consumes time tech pros could otherwise be spending on things like upskilling or innovating new ways of working. For example, nearly half of those polled stated performance/query tuning was one of the top three skills/tools they believed they could develop/improve to better manage increasing database complexities, followed by security management and data engineering (45% and 41%, respectively). One of the best ways to work smarter, not harder: Mitigate downtime spent on maintenance and enable efficiency is to implement appropriate automation and monitoring tools. When implemented properly, automation and monitoring solutions can improve overall performance and eventually lead to reduced costs. Additionally, they can free up tech pros’ time, allowing them to focus on more proactive database performance management.

    The report reveals just how quickly the database architecture and operations tech pros are managing in today’s organizations are changing—and the web of management complexity accompanying this change. With application availability and performance as critical business drivers, the database has long been the linchpin of today’s IT environments. However, against the headwinds of increasingly diversified platforms and reduced resources, tech pros must be equipped to do more than reactive maintenance in environments that keep adding more databases with each passing day.

    Tech pros must capitalize on the opportunity ahead to maximize the performance potential of cloud-hosted databases and ensure the successful optimization of their organizations’ data.

  • Establishing Trust in Multi-Cloud Environments

    Establishing Trust in Multi-Cloud Environments

    Modern applications are transforming enterprises into digital innovation factories. However, the distributed nature and complexity of modern apps have made it extremely difficult for organizations to maintain trust and compliance across multi-platform, multi-cloud environments. 

    Although Kubernetes is the standard for application platforms today, each cloud service provider (CSP) has a different offering for infrastructure-as-a-service (IaaS) or their own platform-as-a-service (PaaS) with varying capabilities and APIs. Not only are these APIs incompatible (with the exception of Kubernetes if no vendor extensions are used), each infrastructure and platform are treated and managed in silos. These silos act as an isolated and non-overlapping administrative boundary,  preventing cross-boundary visibility and trust between microservices.  This makes it much harder for enterprises to know and consistently remediate their security posture across clouds and platforms, opening them up to attacks.

    To solve this problem, organizations are extending enterprise security controls to cloud environments. The problem is that application teams and security teams have traditionally had competing goals—agility versus risk and control—and security operations have not evolved at the same pace as application operations. This creates friction between the teams and forces application operation teams to make a choice: 

    1) Slow down application delivery and operations to reduce risk and miss out on the transformative benefits of multi-cloud or 

    2) Continue to develop and ship applications as quickly as possible without considering security and compliance. 

    Neither is a good option. To unlock the power of modern applications running in multi-platform and multi-cloud environments, organizations need to find a way to integrate security seamlessly throughout the software delivery life cycle at the speed users expect.

    Integrating Zero-Trust into the Application Delivery Cycle

    The key to securing applications in a multi-cloud world is zero-trust. Building zero-trust principles directly into modern applications allows organizations to identify threats early, reduce attack surfaces and ship security functions alongside the rest of the application stack—regardless of the underlying application platforms and cloud stacks underneath.

    In this use case, one of the key components of zero-trust is application segmentation; in other words, how to make access decisions between different applications or components of applications. Zero-trust must provide identity-aware, adaptative and on-demand access to any app from any user or app in a way that improves the flexibility and the agility of application access through a scalable model.

    Application segmentation must be provided to application operation teams so that they can embed it into their application quality processes as another gate. Application operation teams can do this by implementing application segmentation policies that identify workloads as they are created through rich, dynamic attributes. The more intrinsic/static attributes (IPs, digital certificates, namespaces, labels, etc.) and extrinsic/dynamic attributes (user behavior, workload behavior, network behavior, etc.) that are identified, the more fine-grained your access decisions can be. 

    Incredibly, application segmentation today continues to be done manually. But with millions of transactions happening across multiple cloud environments, there’s no way a person—or even a team of people—can manually assign policies to each workload. Organizations need a way to deliver zero-trust application segmentation in a scalable, transparent and automatic fashion. 

    A Connectivity and Security Platform 

    The way to do this is through the use of a modern application connectivity and security platform. Through a service mesh, an attribute-based access control (ABAC) model consolidates multiple third-party tools that provide visibility and security across application platforms and multi-cloud environments. This single view operational model gives application teams the ability to seamlessly and simply orchestrate security services across multi-cloud environments, automatically and at scale. 

    Unfortunately, granular policy management through microsegmentation increases complexity, which is the enemy of security. Suddenly, an organization may find itself with thousands of policies that dictate how different workloads access and interact with entities inside the network. These policies need to be continually updated and maintained, creating massive headaches for both application and security teams.

    When a workload is deployed, the associated policies are created along with it and move through the environment with the workload until the workload reaches the end of its life and is decommissioned. As applications run over time, they are being characterized by their unique behavior. This runtime security characterization allows policies to be automatically selected and applied directly to the workload.

     However, for a service mesh to work and enable secure applications in a multi-cloud environment, it needs to follow zero-trust principles without adding complexity and without slowing down the agile delivery cycle. Here’s how you do that:

    1. Baselining trust: A modern app connectivity and security platform should have native observability and self-discovery capabilities, such as being able to automatically discover APIs, catalog APIs and generate API documentation based on the OpenAPI standard. The modern app connectivity and security platform should be able to continuously baseline application behavior and detect anomalous application behaviors. This needs to alert on unknown and zero-day attacks, especially exfiltration of sensitive data.
    2. Establishing trust: It is critical to define the interconnectivity needs of different pieces of the application right off the bat. This explicit declaration of intent is typically done manually by application teams during the deployment of the application as part of a CI/CD pipeline. Another option is to automatically discover the connectivity intent during the testing phase of the application and allowing the service mesh to identify and record the resulting communication flows between microservices’ APIs. These are the basis of the application’s segmentation policies.
    3. Enforcing trust: There also must be a mechanism to automatically apply the appropriate application segmentation policies to enable the necessary communication for the application to run as intended. In the microservices model, different pieces of the application are spun up and down dynamically to enable the application to run as intended. It’s critical that the application segmentation policies that govern accessibility also adapt to these changes. This is done through the service mesh control plane that interacts with the application platform to gather the inventory of workloads.
    4. Dynamically adjust trust: As the applications run over time and clients interact with them, they are being characterized by a behavior. In this case, a security behavior. Observing this behavior can be accomplished through various runtime analysis tools that organizations already have in place that detect process, container, network and user behavior to provide security context. However, to maintain trust, there needs to be a way to integrate these tools through the service mesh to create a single source of truth. 
    5. Extending the trust model to the edge: Applications also interact with software-as-a-service (SaaS) platforms such as Salesforce or SAP, and other apps outside the data center. Ideally, the service mesh/zero-trust application segmentation model can integrate with other security solutions in the cloud such as secure access service edge (SASE), secure web gateway (SWG), cloud access security broker (CASB) and other zero-trust security components. This standardizes the processes for establishing trust across the data center, multiple cloud service providers, SaaS platforms and web apps—ensuring consistent security and compliance posture across the entire organization.

    Modern applications are transforming how business works by enabling agility and real-time decision making, but they will never reach their full potential unless application teams work with security teams to protect users, data and applications in multi-cloud environments. It’s clear that organizations need an evolved security model that application teams can use to seamlessly establish trust and orchestrate application segmentation across multi-cloud, multi-platform environments. Service meshes can provide the visibility and control needed to establish and continually evaluate trust.

  • 5 Steps to a Seamless Multi-Cloud Migration

    5 Steps to a Seamless Multi-Cloud Migration

    With digitization the topic of discussion in almost every boardroom since the onset of COVID-19, it’s no coincidence that migration to the cloud has skyrocketed in tandem. In fact, at the onset of the pandemic, 87% of IT decision-makers noted that the remote restructuring of the workplace would push their organizations to accelerate cloud migrations.

    That trend shows no signs of slowing down. In fact, Gartner predicts that cloud spending will increase by 23% in 2021 to reach $332B. Driving this historic shift is the adoption of multi-cloud infrastructures. Businesses are increasingly separating and distributing their data flows and critical functions across multiple clouds from different service providers. According to Flexera’s 2021 State of the Cloud Report, an overwhelming 92% of enterprises say they now have a multi-cloud strategy, and 82% say they have a hybrid cloud strategy.

    There are many reasons for this increase in adoption. Developers that use containers, for example, can test their applications across multiple systems in the multi-cloud environment to speed up innovation, due to containers’ agility and portability. This use of multiple clouds also allows businesses to tackle cloud migrations in a more measured and deliberate manner rather than a ‘big bang’ approach.

    What this also means, however, is that it multiplies IT’s stress as they deliberate the benefits, costs and risks of moving their business to a multi-cloud strategy. For example, they must consider whether or not to keep their data on-premises, migrate it to a public cloud or some combination of both. They must also ensure their application’s ironclad security, which has become a mission-critical consideration during the unrelenting cybersecurity emergency that is the pandemic. Meanwhile, they may worry that such a large-scale cloud migration will result in lost revenue and increased downtime.

    With these key considerations and challenges in mind, here are five tips to help enterprises seamlessly migrate their resources to a multi-cloud environment.

    Assess Your Application’s Ripeness

    Before any application is migrated, it’s necessary to do a complete audit of current applications to assess their readiness for the migration. Businesses should look at the application’s dependencies and the ecosystem it lives in. This ecosystem could be its physical and virtual network infrastructure, including configurations, policies, load balancers, security and compliance requirements.

    Plan and Prepare

    This is a particularly challenging phase, as IT teams often linger here; wasting valuable hours and productivity. Therefore, the entire organization must outline what their migration journey will look like, discuss which departments will be affected during the process, and delegate responsibilities to facilitate a smooth transition to the cloud. The IT operations team, the development and quality assurance teams, key stakeholders and leadership should all be involved in these discussions—and should share the goal of ensuring a predictable migration process.

    Carefully Weigh Your Cloud Options

    Choosing the right cloud depends entirely on the unique needs, challenges and opportunities for the organization. While there are a number of different providers available to every enterprise, the best option will be influenced by financial constraints, goals for cloud adoption and even the systems already in place.

    Of course, when a business is taking a multi-cloud approach, these decisions become that much more difficult—especially in light of the fact that the average cloud company uses 2.6 public clouds and 2.7 private clouds, according to the Flexera report. Connectivity between these providers is crucial, with 88% of businesses enabling their multi-cloud strategy with a private connection.

    With this in mind, it’s also absolutely vital that decision-makers consider the security risks associated with each provider, as well. The number of cyberattacks on enterprises’ cloud infrastructures has increased significantly since the onset of COVID-19. With the stakes so high, a migration partner can help businesses assess which cloud providers are the right fit for them; accounting for their cost-effectiveness as well as which options will pose the least friction for the migration.

    Construct Your Migration Checklist

    The migration of an enterprise’s workloads is the most critical step of its cloud journey, and every company’s objective is to make a move swiftly and seamlessly. Creating a checklist can help businesses achieve this goal, as it helps them to prioritize the most critical components of their journey and understand the repercussions of a stagnant or inefficient migration.

    For example, every business should aim to achieve minimum downtime during their migration process and little to no disruption of service. Both the loss of network access and system downtime can cause immediate pain in the form of lost productivity and opportunities and even more harmful damage to a company’s brand. In fact, according to Gartner, the average cost of IT downtime is $5,600 per minute, meaning a well-practiced and efficient migration strategy has a significant impact on a company’s financial health.

    Since each migration is unique to the business and, often, unforeseen challenges arise that are native to the environment, it’s beneficial for organizations to have an expert migration team or partner to help them develop their checklist and ensure their migrations are streamlined and airtight.

    Validate Your Cloud Journey

    As the final step in a business’ migration journey, companies must validate that all their resources from their previous environment are fully migrated and operational in their target cloud environments. This step is crucial, as it marks the completion of a successful multi-cloud migration journey! This is primarily a manual process ensuring that nothing is neglected or forgotten and is often followed by an entire testing lifecycle.

    Post-Migration Pointers

    Cloud migrations can be complex, especially for companies relying on a years-old traditional and highly manual approach. Thankfully, in the age of automation, enterprises today are experiencing substantial time and cost savings and deploying migration strategies that move their workloads across multiple clouds in seconds instead of days.

    But even when an organization’s migration journey is complete, the management of several clouds at once creates its own set of challenges and risks—especially true in today’s landscape of skyrocketing climate and cybersecurity risks. It’s therefore vital that business leaders heighten their focus on organizational resiliency and minimizing downtime through things like tightened security and effective disaster recovery strategies.

    After all, with hybrid work forcing C-suites to scale their digital transformation plans even further, it’s becoming increasingly clear that the future of work is in the cloud. It’s therefore imperative that as cloud spending soars, enterprises allocate substantial resources not only to migration and management but protection, too.

  • Where Do SREs Go From Here?

    Where Do SREs Go From Here?

    Charlene O’Hanlon talks with Leo Vasiliou, director of product marketing at Catchpoint, about the results of a study the company fielded with VMWare Tanzu and DevOps Institute of nearly 300 site reliability engineers (SREs). This year’s report underscores the challenges of multi-cloud, calls out the underutilization of AIOps and shows a systemic shift in core baselining data. The video is below, followed by a transcript of the conversation.

    Announcer: This is Digital Anarchist.

    Charlene O’Hanlon: Hey, everybody. Welcome back to TechStrong TV. I’m Charlene O’Hanlon, and I’m here now with Leo Vasiliou who is the Director of Product Marketing over at Catchpoint. Leo, thanks so much for joining me today. Really appreciate it.

    Leo Vasiliou: Oh, of course, Charlene. Thank you very much for allowing us to have the conversation today.

    O’Hanlon: Absolutely, absolutely. I want to talk to you about a recent survey study that you guys put out in conjunction with VMware Tanzu and DevOps Institute. What were you guys looking at?

    Vasiliou: Well, from an existential perspective, we hope that the survey that we do leads into the annual report and we’d like for it to be the most data-backed set of insights in its community. There are sort of three underlying constructional essences of the report. One is to provide a core baselining data for the key SRE tenants. So DevOps, who had an amount of time, would call in reported levels of toil. The other essence is to look at what’s trending. And then the third one will generally be around the IT to business relationship. And then with each one of those constructional essences, the context and line items within each section will change from year to year.

    O’Hanlon: Gotcha. Alright. So this one focuses on site reliability engineering and what they’re seeing and what they’re dealing with on kind of a daily basis. Is that right?

    Vasiliou: Yes, yes.

    O’Hanlon: Okay. Alright, great. So tell me a little bit about some of the findings in the study. I know you guys do these, as you just said, reports yearly. So I’m interested in knowing what’s changed from year to year and what really surprised you in this year’s report.

    Vasiliou: Well, I like to say SREs are double struck with challenges because the SRE is essentially two jobs in one, right? They have to increase the efficiency of their operational activities while mitigating the risk of their transformational activities. So one of the key findings this year, which by the way this may be the most provocative dataset we’ve published just because some of the findings conflict with some popular theories in the market, but take the first one just as an example of that, is as part of the baselining set of data there was a self-reported drop in toil, which is the word they use to define repeated, mundane, busywork that doesn’t have any inherent value, of 15 percent. And one of the reasons this is such an insightful nugget to lead us into our various conspiracy theories is it was across the entire distribution of data, across all of their percentiles, as well as across all of the geographies that we looked at.

    O’Hanlon: Wow.

    Vasiliou: And so for me, when I had the blessed opportunity to do the research and sit down and co-write the report, having been stuck in the house for, let’s just call it a year and a half at this point, there was just something different about working on a piece like this and it just felt a bit more meaningful. And the conspiracy theory there or the hypothesis is that if people return to work, or return to the office I should say or some type of hybrid environment, will those reported levels of toil increase again next year as people adjust to the hustle and bustle of commutes just adding to frustration in how they think about things?

    O’Hanlon: That is a really, really fascinating thought process there. We could do an entire conversation about just that and whether what happens this year is going to be indicative of what happens in the future or if this year is going to be like a reset year. So from an SRE perspective though, the fact that the level of toil decreased 15 percent, that seems pretty significant. If you look at the entire spectrum of what they have to deal with on a daily basis, 15 percent, good lord, that’s huge in the SRE space.

    Vasiliou: Yeah. It is huge. I agree. It’s also based on the response of hundreds of survey participants year over year. And what’s interesting, Charlene, is one of the unique tactics we took in this year’s report is before we publish the reports and post survey pre report, we actually showed the results to various industry, let’s just call them, leaders. One of them we shared this particular section to had an alternative theory on why levels of toil dropped, and it had to do essentially with the fact that if people are not in the office, maybe does the very act of them not being observed compel them to do less busywork.

    So there was an alternative theory. But bringing us back to and leading into one of the other essences of the report, which is kind of the trends piece, it had to do with the amount of monitoring data sources, like the volume, variety, velocity of data, and the number of multi same-service platforms, e.g. multi CDN, multi DNS, et cetera, in use. And so will the return to work and the promise of AI ops help them keep toil levels low? Which leads us into the next sort of surprising finding, which is that SREs and their implementation or shift to AI ops is quite slow to maybe what we might be reading about in the industry, which was probably the second most provocative finding in the report.

    O’Hanlon: Yeah. So why do you think it is so slow then? Were there any trends that kind of came out of that? Any reasons why organizations are kind of slow to adopt AI ops?

    Vasiliou: Well, there is obviously a deluge of information and rhetoric in the market on the internet today. We need to seriously consider this idea of an information diet, which is a concept I first heard about a couple years ago. When we think about the idea of the hype cycle versus the challenges SREs face on a day-to-day basis, sometimes the market and the promise of what these types of solutions will offer might outpace actual implementation capabilities from, hey, we’re an SRE, let’s go implement this. I think part of the challenge here is probably the concept of AI ops is too broad and too large for consumption. It’s the idea of just saying, “Hey, let’s go solve world hunger or, hey, let’s go solve or implement AI ops,” right?

    O’Hanlon: Right, right.

    Vasiliou: You’ve got to break it down into smaller components and incrementally develop capabilities from there. Otherwise, how the heck are you going to baseline your progress for when you’re done? I think it’s too big, too broad, and some of the vendor promises may be of self-healing, auto remediation, maybe they were a little more on the hype side, where some of the other AI ops of components like root cause analysis or even correlation, maybe those are truthfully more on the hope and promise side.

    O’Hanlon: Okay. Do you think that AI ops – to your point, it is broad – do you think it just means different things to different people and so somebody actually may be implementing some type of AI ops and actually not realizing it?

    Vasiliou: The short answer is yes. So when we asked the question what monitoring tools or practices are used today, they were presented with seven options, ranging from application, infrastructure, experience monitoring, AI ops, and it was the fifth lowest, meaning that almost 40 percent of respondents said they’d never used it in the first place. The second question we asked is very simply what is the received value from AI ops, where one was the low value, nine was the high, and the range evenly spanned the value scale that was presented in the survey. What was interesting is there were a subset of people who said they never used AI ops but that they still received value, which was an additional dimension we didn’t think about when writing the survey.

    But it kind of brings me back to the essence of your question, which is are you user versus a consumer? And then go back to the previous comments about how big and broad this quote/unquote AI ops idea is, and there’s absolutely a propensity that people hear and think completely different things, unfortunately.

    O’Hanlon: Interesting. Interesting. So one of the things that we’ve been talking about in the SRE space over the last couple years is really how the role is kind of morphing and changing along with the market in general and to address a lot of organizational needs as well. Are there any findings from this year’s study that kind of bear out how an SRE role is changing and even if it is changing?

    Vasiliou: That will go back to what we were saying just a moment ago about mitigating the risk of their transformational activities. When you were asking the question, I’ll just cite the stat from our very first SRE report. We said that 85 percent of respondents said that in order to be successful in this role you have to commute into an office. So that got topsy-turvy turned upside down on its head.

    O’Hanlon: Right. Yeah. [Laughs]

    Vasiliou: But to get back to the essence of the question here, when we looked at the quantity of data sources and the prolific rise of the use of multiplatform providers, we sort of looked at this correlation between how SRE orgs are structured. Are you decentralized, are you centralized, or is there some type of hybrid in between? And then the decentralized piece was broken down even further by stack component, by platform component, or by business product or service. The vast majority of SREs said they are currently decentralized by business product or service, but I think the transformational piece here, which is something we’ll look at next year when we write the report, is because of the prolific rise of multiple third party and multiple same-service third party providers, there is a huge, gigantic spotlight to shift the primary dimension of org structure from product and service to a platform basis.

    And we talk about it like this. If you’ve got 10 different teams assigned to 10 different products or services and one member from each of those SRE teams developing capabilities that happen to be the exact same capabilities in development by those other nine teams, that’s the scalability and efficiency _____ that we start to lead in and talk about in this year’s report. So I think the transformational piece will be the assignment of SRE development engineering resources from product and service as a primary dimension to a platform – for example, cloud, CDN, DNS, API – as the primary dimension where those capabilities will be normalized and developed. Even though underlying platform structures will be different, those capabilities will then be offered as part of, let’s call it, an internal marketplace for use by multiple teams to kind of get away from that concept of silos and being segmented by product or service. So a bit of a long answer but all contextual to the key part there, which is the trend and the transformational piece that we wrote about this year.

     O’Hanlon: Right. Yeah, well it really is food for thought there if you consider how the SRE role was established and how it’s kind of – if you go down that path, how it seems to be changing and evolving as the more technology is adopted and more things are moved out to the edge and the need for SREs at basically all points on the network if you think about it. So great stuff there. Well, Leo, I know we could talk about all of the findings and have a much larger conversation, but unfortunately that’s all the time that we have for this one. But I do want to thank you very much for going through some of the survey findings. If folks are interested in taking a look at the study itself, is it readily available?

    Vasiliou: It is, it is. So it’s available at Catchpoint.com. Just head over to our learning and research section and enjoy the read. Charlene, one of the sentiments we wanted to leave readers with this year was this concept of baselining against Google’s definition of SRE, but we hereby declare by the power vested in us by absolutely nobody at all that you are hereby free to be an SRE.

    O’Hanlon: Oh, wow. Just one more thing to add to my plate. [Laughs] Well Leo, thanks again. I really do appreciate your time, and it’s a pleasure talking to you. I’m sure that we’ll talk again in the future about future studies that you guys have going on. So, thanks again. Really appreciate it.

    Vasiliou: You are quite welcome. Thank you for your time, Charlene.

    O’Hanlon: Alright, everybody. Please stick around. We’ve got lost more TechStrong TV coming up, so stay tuned.

    [End of Audio]

  • Improving Security with Mapping, Automation and DevOps

    Improving Security with Mapping, Automation and DevOps

    Strong cybersecurity is paramount for every organization. But all too often, security teams are disconnected from ongoing development processes and viewed either as an impediment to bringing products to market or as an afterthought. This leads to increased costs and possible gaps in the attack surfaces of new platforms.

    While many organizations are turning to security automation to help them manage and mitigate their expanding threat landscape, quick fixes rarely work. Planning is required to help organizations determine their pain points, add security early in the software development process, and determine where automation can deliver the best ROI.

    What Should Be Automated?

    Security automation can programmatically test, institute guardrails, provide feedback and remediate cyberthreats by executing tasks as part of the continuous improvement pipeline. This, in turn, can help understaffed security teams by streamlining complicated and time-consuming testing processes, enabling teams to maximize their time, be more productive and focus on risk priorities. Once the manual process is removed, the automated workflows can then carry out a variety of more minute actions using intelligence and logical decision-making.

    Security-focused areas that may benefit from automation technology include but are not limited to:

    • Static and dynamic code analysis used to discover security vulnerabilities
    • Test harnesses for software configured to run a program unit under varying conditions to discover and monitor its behavior and outputs
    • Upstream code analysis that examines code such as complete code blocks or patches
    • Vulnerability testing, management and remediation to discover and fix weaknesses that may be susceptible to attacks
    • Penetration testing used to simulate cyberattacks on an organization’s computer systems and evaluate security posture
    • Automated enforcement based on data classification and tagging strategy
    • Deployment and management of infrastructure components

    Focus on ROI

    Despite the benefits, many organizations face substantial hurdles in developing, implementing, testing and optimizing the comprehensive, integrative, long-term approach needed to use security automation to cope with the evolving threat landscape. It’s all too common for organizations to begin projects that start with automation as the outcome rather than rigorously mapping the processes and determining where value from automation can be gained.

    Consider an organization that decides to automate the process of deploying a firewall to an AWS cloud. A team spends several weeks developing and testing an automation playbook that can spin up virtual firewalls, license them, connect them to a central manager, deploy configurations and apply them and send logs to the appropriate places. Testing proves the automation works.

    But when asked how many firewalls they expect to spin up this year, the answer is two–maybe. How many next year? None. The team, therefore, spent more time automating this function than it would have taken to just deploy the systems and the organization won’t likely realize any direct return on this work for at least two years.

    Value Stream Mapping

    The first step in achieving real value is to understand that automation is a second-order operation that relies on a thorough assessment and plan of all the steps required to achieve real technical and business outcomes. That means conducting value stream mapping to analyze, design and manage workflows that best suit your environment.

    Mapping will help you analyze and define security processes. Without analyzing your processes, you’ll have no idea of where the bottlenecks are or how they can be removed. Better understanding the processes will also allow you to refine them as needed. Without doing all this, you’ll have no way to prove the value of the automation you’re implementing, and no compelling business justification for it.

    The Role of DevOps

    Few organizations are able to effectively realize the benefits of automation right out of the gate. Value stream mapping enables organizations to determine their pain points, pinpoint exactly where they want to use automation and identify processes that cannot or should not be automated. Clear-eyed planning and assessment will help teams define a process and determine the value of return on automating certain processes.

    In addition, for security to be effective, we have to shift security left in the software development life cycle (SDLC). Security practitioners should be engaged in the development pipeline, including collaborating on automation initiatives and building harness and test cases as the work progresses. This will save time, improve quality and ultimately add value, ensuring the success of security automation projects.

  • What It Will Take To Bring Cloud Gaming to Fruition?

    What It Will Take To Bring Cloud Gaming to Fruition?

    The gaming industry is booming. There are 211 million people gaming in the U.S., and it’s one of the fastest-growing forms of entertainment on the planet. In the age of Twitch streaming, gaming has even upstaged traditional sports viewership. On average, young gamers between the ages of 18 and 25 spend a full hour more watching online gaming than watching traditional sports.

    Gaming has also become a way of connecting with others—65% of players say they play with others online or in person. Some software development teams even encourage gaming in the workplace to increase productivity. For this reason, there has been a massive shift toward online cooperative games, RPGs and sandboxes like Minecraft. Also, games are becoming more cloud-based, with purchases, downloads and game saves occurring in the cloud. Still, many people lack the hardware necessary to run complex games locally. All these factors are harbingers of a coming shift away from PC and console-based processing.

    I recently met with Noam Salinger, product manager, Granulate, to learn about the future of gaming and how software teams in the gaming industry can prepare. To Salinger, “cloud gaming is the next step.” The move away from consoles and toward cloud-based, remote processing will have huge ripple effects. Lowering the barrier to gaming could introduce millions of more players into the ecosystem and further balloon the industry. However, cloud gaming presents significant hurdles. The transition will require a substantial reduction in latency, 5G networking and highly efficient computing optimizations.

    Roadblocks to Cloud Gaming

    “Cloud is an integral part of any gaming company,” says Salinger. More and more functionality associated with gaming is being pushed online. There are already online game marketplaces, cloud-based account management and remote game saves. This is especially prevalent with mobile gaming. But, what about the actual processing for computationally-intensive games—could these workloads also move to the cloud soon?

    This kind of cloud-based gaming could soon come to fruition. Yet, Salinger foresees some major roadblocks to cloud gaming:

    1. The Software Components

    A complete jump to cloud gaming will require having the proper software infrastructure in place and getting vendors on board to support it. This is perhaps the biggest obstacle to cloud gaming in the software industry, said Salinger, “It’s still not mature enough.”

    2. The Business Components

    Furthermore, gaming platform companies might refrain from cloud gaming due to fears of it cannibalizing their existing hardware sales channels. On the other hand, cloud gaming presents a big opportunity to take on more of a subscription-based model, such as allowing a user to play any game they want from an extensive suite of games. Akin to streaming services like Netflix, Hulu or Peacock, we could see similar platform styles emerging in gaming. “They will have no choice but to participate at some point,” said Salinger.

    3. The Network Components

    As most gamers can attest, online games can easily suffer from network issues that negatively affect gameplay. Salinger predicts that the ubiquity of 5G networks will be necessary to propel the cloud gaming market forward. 5G could be a universal method to enable real-time connections for a broader base of end-user gamers.

    Even if software developers optimize game processing speeds, a poor network could add enough latency to data throughput to cancel out those gains. 5G could expedite this process, but it’s taking a lot longer than expected. Some estimates place 5G finally arriving at full throttle sometime in 2023, after more antennas are constructed and pre-existing physical infrastructure is upgraded.

    4. The Latency Components

    Another significant roadblock to cloud gaming is figuring out real-time remote computing on the game vendor side. “This is where the latency aspect of things really comes into play,” said Salinger. Since game clients will be making many remote calls, optimizing cloud CPU utilization will be vital to reducing the response time to requests.

    Cloud gaming will require parallel running processes that anticipate user action. Similar to the way modern web applications simultaneously trigger multiple backend requests for authentication, geolocation, user databases and so on, real-time cloud games will require many different processes running in parallel. Servers could allocate resources before requests come in, using predictive analysis of usage patterns to trigger components in advance of user behaviors.

    To enable intelligent resource allocation, Salinger describes how an OS-agnostic kernel module could be in charge of resource allocation, continuously adapting to changes in the application workload. Low-level resource allocation at the CPU level, the allocation memory, I/O, and the sequence of execution must be optimal for each specific application, he described.

    This sort of process is already being applied in production by some ad tech companies to enable real-time ad bidding. For example, by optimizing cloud CPU utilization, Perion is able to perform faster, process more responses and use fewer machines to perform the same task—thereby reducing the roundtrip time for each request. Similar principles could be used to advance cloud gaming.

    Rendering sophisticated virtual environments is highly resource-intensive, and high-performance graphics cards are expensive. Video games are set to only increase in complexity with new AR/VR modes. Cloud gaming could help respond to rising computational needs and replace the need for local computing hardware. In the process, this move could bring in more gamers, disrupt the console wars, and nullify age-old PC-versus-Mac compatibility issues.

    Moving to a cloud-based approach is also arguably more aligned with today’s fast-paced software release cadences. Pushing more frequent patches can help resolve bugs faster. But it also could aid in retaining engagement by introducing new levels and objectives continually.

    The rise of the gaming ecosystem can’t be ignored. But as it stands now, there are still significant challenges to wider penetration of cloud gaming. Cloud computing optimizations to reduce latency, mainstream adoption of 5G and significant re-platforming of software infrastructure are just some of the many issues that will need to be tackled before truly cloud-based gaming experiences advance to the next level.

  • How to Build an Options-Based Observability Strategy

    How to Build an Options-Based Observability Strategy

    The global pandemic forced companies to accelerate their digital transformations, pushing them toward new technologies and architectures as they struggled to adapt to a changing world. Companies wanted fast development and deployment and were happy to trade off efficiency, reliability and sometimes, security, to pursue their goals. Now that the pandemic is receding in many parts of the world, the priorities are rebalancing as companies grapple with choices they made under fire.

    Observability has emerged as a way for enterprises to better understand sprawling infrastructure and application environments. According to Gartner, “Observability enables organizations to reduce the time it takes to identify the root cause of performance-impacting problems. In particular, and in contrast to traditional monitoring, operators can freely interrogate data post-hoc without the need to pre-program dashboards.”

    This sounds promising and the market responded quickly, but predictably. Large and monolithic monitoring platforms embraced the term and added new features, making them even larger and more monolithic. These monolithic platforms represent a failed choice-based strategy. They assume that all observability data is collected, centralized, integrated and only analyzed by a single tool. Enterprises following a choice-based observability strategy find themselves locked-in to multi-year investments without the flexibility to react to evolving technologies.

    While this has been good for vendors in the incumbent monitoring space, end users haven’t benefited from these enormous platform deployments because the choice-based strategy is built on the faulty assumption that a single pane of glass serves all of your monitoring and observability audiences, from SREs to DevOps and SecOps.

    A choice-based strategy also forces customers into limited options in the future as technology continues to evolve and requirements change. Defaulting to choice-based strategies also leaves little leverage for contract negotiations, data integrations and data access.

    Infrastructure and operations teams need to take a different approach to their observability strategy. Instead of focusing on buying products and making choices, teams need to shift their thinking to creating options. The choices you make today limit your options tomorrow. Tomorrow is unpredictable and uncertain. Taking an options-based approach allows you to be flexible and adaptable today and into the future.

    An options-based observability strategy is built on three pillars:

    • Establishing your observability strategy principles
    • Building composable environments
    • Staging your commitments

    Let’s look at each of these.

    Establish the Principles of Your Observability Strategy

    When asked about their observability strategy, many often leap into detailed plans covering every imaginable use case. They talk about the current state of their infrastructure and how things will be at the end of three or five years, including the skills and functions they’ll need in that time. If you’ve read the above, you’ll recognize this as a choice-based strategy: All the choices they need to make over the next several years are already laid out. This leaves little room for adaptation and options as the world evolves around you.

    Instead, think of your observability strategy as a single principle, or a collection of principles, guiding your observability strategy. Let’s say your core principle is that observability is a key enabler of operational efficiency across SREs and DevOps. We can build on that operational efficiency principle to define what key elements of our strategy has to include:

    • Data sources have utility-like accessibility; always on and available across tools.
    • Metrics are primarily driven by total cost of ownership and optimization.
    • Governance is centralized to the team distributing data to downstream systems.

    These elements are different if your core principle is something like customer intimacy or risk management.

    With principles and strategy in hand, we can focus on the next phase: Composing the observability environment.

    Compose your observability environment

    In an options-based strategy, the key success factor is avoiding large ecosystems that limit flexibility. Many vendors take a “give us everything” approach to observability. These approaches appear to start and end at the destination platform, but they begin even earlier, at data origination. It’s common to see agents only sending data to one destination, limiting the usefulness of the data by locking it into a silo.

    Staying modular means selecting tooling that abstracts the data sources from destinations and puts the power back into your hands. By using an abstraction like an observability pipeline, you can send data from one source to multiple destinations, while managing that data in any way you see fit. For example, this is where your centralized governance can occur.

    When new tools are introduced, upgraded or deprecated, an observability pipeline insulates the rest of your environment and users from those changes. A modular approach also gives you more power in contract negotiations with your other vendors because you’re less reliant on one vendor for all of your observability needs.

    Stage Your Commitments

    A choice-based observability strategy is a large commitment, often taking years. Once you start, stopping becomes impossible. That’s simply unacceptable in today’s environment of uncertainty. Choice-based strategies limit your ability to test, experiment, and learn. At the same time, our infrastructure is critical and it must be reliable.

    An options-preserving approach may involve experimenting with freemium products; only paying once the product’s value has been proven. Cloud-based options are another consideration since they are commonly subscription-based and offer easy try-before-you-buy purchasing styles. Even better, cloud-based options don’t require using your own infrastructure to test new options.

    Every IT team feels the need to react and respond to demands from the business. That urgency to make choices, to solve the immediate problem, can have long-term implications for future flexibility and agility. By structuring your observability strategy around a long-term vision based on preserving options, your team can remain adaptable as technologies and business requirements evolve.

  • Multi-Cloud Is Not About Lift and Shift

    Multi-Cloud Is Not About Lift and Shift

    Multi-cloud is often framed from the perspective of “lift and shift.” In other words, an organization takes a computing environment previously running on one cloud and transfers it over to a different service provider. Cloud migration may make sense for cost savings or performance benefits and such a shift may be necessary when migrating on-premises data centers to a public cloud.

    In theory, lift and shift sounds like it would empower cloud consumers with more choice in the marketplace. However, according to John Gentry, CTO of Virtana, lift and shift is quite rare in practice; it may not be the true driver behind multi-cloud strategies. Moving resources between clouds can result in costly egress fees. Plus, culturally-ingrained cloud preferences become challenging to shake. Unique configurations and add-on software-as-a-service (SaaS) make each cloud more nuanced, requiring new skills and procedures with every migration.

    Instead, Gentry advocates for a “fit-for-purpose cloud” strategy. This attitude is less about moving similar workloads between clouds but, instead, pairing particular types of workloads with the appropriate cloud types. According to Gentry, using multiple clouds simultaneously could still help organizations strategically align their digital resources and reduce dependency on a single cloud service provider (CSP). But, the real value of a hybrid multi-cloud setup lies in matching computing environments to different business layers.

    Fit-For-Purpose Cloud

    At first glance, the ability to move between clouds appears to be driving a new multi-cloud economy where cloud strategists can swiftly migrate resources and optimize intercloud utilization. However, when organizations attempt to shift, they usually experience many hidden costs, Gentry warned. These often pop up around data egress. Or, new data storage costs may take a surprising toll, Gentry added. “A lot of companies look at it from a computing perspective and they don’t account for the storage footprint.”

    DevOps in the cloud also introduces new responsibilities and processes that may differ between clouds, continued Gentry. From unique storage operations to managing the life cycle of a virtual machine, each cloud carries unique configuration methods. This makes it more difficult to abandon established procedures in favor of a different computing arrangement.

    Nevertheless, Gentry recognizes that we’re starting to see a maturing effect of the multi-cloud concept, especially among large enterprises. “Companies have a multi-cloud strategy—it’s less about moving between clouds than about picking a cloud that has specific advantages for a given workload,” he said. In a fit-for-purpose cloud approach, different workloads correspond to different layers of the business. For example, an organization may require a local data center or private cloud for high-security data. Certain applications may benefit from a distributed global public cloud, whereas other workloads could reap performance benefits and cost savings from a cloud-adjacent edge model. “These specific areas may not have anything to do with one another other than supporting the overall business,” explained Gentry.

    Matching Cloud Types to Business Units

    So how do we match the workload at hand to the ideal computing arrangement? Gentry identified three emerging cloud types:

    • Private cloud: A private core for particular functions that can’t be replatformed or rearchitected. Business areas such as financial records or patient care hold sensitive data that must be stored properly to meet regulations and SLAs.
    • Public cloud: End customer-facing, where sensitive data is not an issue. Public distributed cloud is ideal for delivering a highly available front end for customer-facing digital experiences.
    • Cloud adjacent/edge: When an environment is kept in a cloud adjacent facility with relatively local geographies. This may sit alongside the public cloud or connect to a front end in a cloud.

    For example, Gentry described how a large health care company uses a hybrid multi-cloud setup to support various business divisions. The organization is keeping traditional patient care workloads exclusively on-premises; due to regulatory reasons, it will never see the inside of a cloud. Yet, they are simultaneously building the next generation of applications in a public cloud, using Google Cloud to scale a clinical trial division. Simultaneously they began using Microsoft Azure for their back office. This scenario highlights one peculiar advantage of late-stage cloud adoption, noted Gentry: “They had the advantage of being able to take a more thoughtful approach.”

    Gentry described another case of an organization performing genomic sequencing. For data-heavy applications like this, where there is a high dependency on input and output, syncing with a public cloud could be extremely costly and introduce latency. For them, the most cost-effective method was to use a cloud-adjacent or edge model alongside a public cloud.

    How to Leverage Fit-For-Purpose Cloud

    One situation that may warrant cloud migration is a complete replatforming, noted Gentry. He described one early cloud adopter that rushed into AWS, only to find it wasn’t cost-effective for their needs. Architects then had to make tough decisions to determine what would be repatriated back to local data centers and what should remain in the cloud. “Their only motive going from cloud to cloud was, ‘We made a bad choice and we want to move.’”

    Clearly, to match cloud use with business requirements, you must choose the appropriate cloud. AWS is widely adopted for elastic computing and offers a wide product catalog. GCP is offering feature innovation and cost reduction to compete and is going after un- and under-penetrated regions. Azure, on the other hand, will offer licensing advantages if you are a Microsoft shop.

    Secondly, to unite IT around a hybrid multi-cloud strategy, you must remove the adversarial state between traditional ops and cloud ops. Classic ops is typically very safety-oriented, using a slow approach with endless tests in pre-production. Traditional ops may produce yearly updates. This is directly opposed to the new cloud ops approach, which emphasizes agility, speed and constant deployment. “They sit in different silos,” Gentry explained.

    To solve this dilemma, companies must share technical skillsets between the three main cloud types. “DevOps must become a continuum for all types,” Gentry said. In addition to cultural change, DevOps tools must evolve to monitor workloads across a hybrid multi-cloud estate. This will require integration to tie together tools and deeper observability.

  • Cycloid Tool Can Reverse Engineer Provisioned IaC

    Cycloid Tool Can Reverse Engineer Provisioned IaC

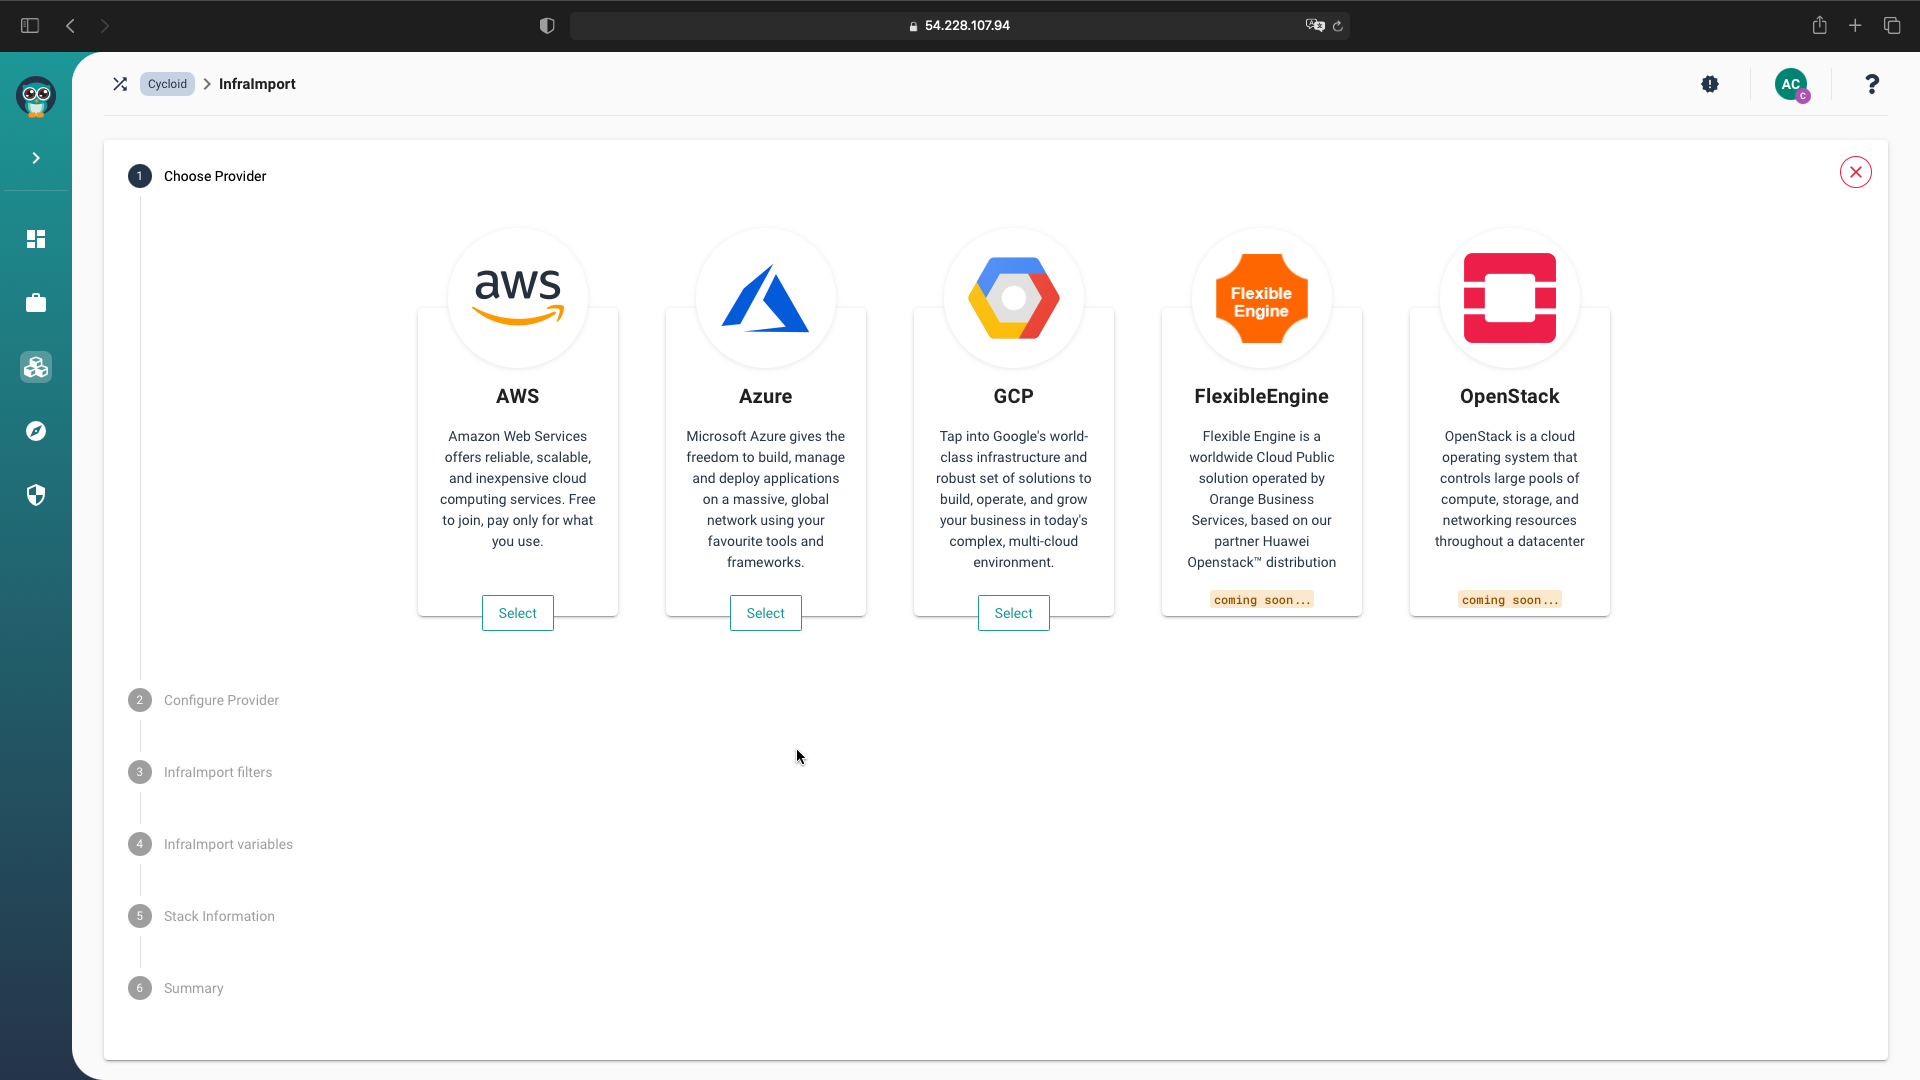
    Cycloid this week unveiled a tool that makes it possible to reverse engineer code used to manually provision cloud infrastructure. The Infra Import tool is part of an effort to create a more consistent and reliable version of that code using open source Terraform software.

    Benjamin Brial, Cycloid CEO, said Infra Import is based on Cycloid’s open source TerraCognita software, which enables IT teams to reverse engineer infrastructure-as-code (IaC) created using open source Terraform tools.

    Infra Import extends that capability to cloud platforms such as Amazon Web Services (AWS), Microsoft Azure, Google Cloud Platform or an IT environment employing the open source OpenStack cloud platform that may have been manually provisioned. IT teams can then create a configuration based on that Terraform code that could be employed across multiple clouds.

    Infra Import is designed to connect to a cloud provider and then automatically reverse engineer Terraform files and IaC stacks based on the existing deployment. It also ensures that the latest edition of Terraform is being used to create that configuration code, noted Brial. That capability eliminates the need for DevOps teams to keep track of what version of Terraform might need to be updated as new versions of the IaC tool become available.

    Just as significantly, Infra Import also makes it a lot easier to onboard new members to a DevOps teams because the tools uses valid secure configurations they know can be relied on. Misconfiguration of cloud services is one of the biggest security issues that IT teams today are wrestling with, simply because most developers lack the security expertise required to configure cloud services properly.

    Cycloid is in the process of rolling out a comprehensive suite of management tools that complement a lightweight framework it created to make DevOps best practices more accessible. The challenge is many IT organizations have already manually provisioned cloud infrastructure in a way that is, at the very least, often suboptimal if not downright insecure.

    Misconfigurations are rife across cloud computing environments, but most organizations are not prepared to manually address the issue. Automating the reverse engineering of those configurations is the first step toward enabling IT teams to address the problem at scale.

    It’s not clear to what degree configuration concerns have impacted the number of applications that would otherwise have been deployed in the cloud. Security is always listed as the top concern IT leaders have when employing cloud platforms. The issue, however, is not the security of the platforms themselves but rather the processes employed to deploy applications on the platforms. Cloud service providers have promoted a shared responsibility model for security under which developers are accountable for both securely configuring services and ensuring the overall security of the software environment. The trouble is, not every developer understands the implications of that shared responsibility model much less how to actually secure an application workload.

    It’s not likely security concerns will slow down the rate at which applications are deployed in the cloud. However, as more cloud security issues are encountered, more scrutiny will be applied.