Category: DevOps Toolbox

  • Atomist Advances Developer Productivity

    Atomist Advances Developer Productivity

    Atomist is extending the reach of an automated approach to managing software delivery out to the local machines developers work on every day.

    Company founder and CEO Rod Johnson said with its Software Delivery Machine (SDM) project, Atomist seeks to eliminate much of the complexity developers currently must navigate as they build code, including making changes that require updates to dependencies across projects.

    That capability makes it easier to keep multiple development projects consistent and up to date automatically, Johnson said.

    Atomist is applying many of the concepts Johnson used to create the widely employed Spring framework as an alternative to Java Enterprise Edition (J2EE), which is now being developed under the auspices of Pivotal Software, a unit of Dell Technologies. Atomist created a domain model for software delivery based on an API server and GraphQL, an open source data query and manipulation language.

    This approach eliminates the need to work within the construct of more cumbersome framework based on, for example, YAML files, Johnson said. Rather, Atomist is making use of code to develop an alternative framework that is optimized around a more familiar API construct, which frees developers to extend the SDM in any direction that best reflects how they want to work.

    Atomist currently provides a service based on SDM to large enterprises that have aggressively embraced DevOps. Johnson said that service enables organizations to allow developers a maximum amount of flexibility within the context of policies that can be defined by an IT operations team. The local instance of SDM is intended as an open source tool for increasing individual developer productivity.

    Most organizations are becoming increasingly obsessesed with developer productivity at a time when companies recognize how dependent they are on software to differentiate themselves. The rate at which new and existing applications are being rolled out and updated has expanded considerably. For developers face to rise to that challenge, many of them embraced microservices that make it easier to add and replace new functionality using Docker containers. Those microservices, however, create a massive number of dependencies across different code bases that must be tracked. SDM can be employed to not only spin up containers images and Kubernetes clusters, but also update all the interdependent microservices spanning multiple clusters.

    Asking developers to keep track of and manually update all those dependencies involving multiple projects is not the best use of their time, Johnson said. Real DevOps progress will be achieved only when organizations provide tools that make it easier for developers to do the right thing in a way that doesn’t try to impose an inflexible framework.

    Most of the processes that organizations rely on to build code today are not nearly as automated as they should be. In fact, DevOps adoption arguably would be much further along than it is today if it didn’t require so much manual effort.

    — Mike Vizard

  • Atlassian Acquires OpsGenie to Automate Incident Management

    Atlassian Acquires OpsGenie to Automate Incident Management

    Atlassian this week announced its plans to acquire OpsGenie as part of an effort to apply DevOps principles to incident management. The announcement was made at the Altassian Summit Europe 2018 conference.

    Atlassian plans to integrate OpsGenie, which provides incident alerting and communications software, with its Jira service desk software to enable organizations to automate responses to a major incident such as a site outage using a Jira Ops incident management command center unveiled this week.

    Jens Schumacher, head of software teams for Atlassian, said that while most organizations today have processes in place to respond to minor incidents, very few have incident management processes in place to deal with significant catastrophic events. OpsGenie already has been adopted by more than 3,000 customers to enable organizations to put together a set of structure processes to recover as quickly as possible.

    Schumacher said a more structured approach to recovery is now required because so much more of a modern organization’s ability to drive revenue is tied to the availability of IT. Whenever there is a significant amount of downtime, the urgency attached to recovery process is now much greater. The combination of OpsGenie and Jira, available now via an early access program, makes it possible to predefine a structured set of workflow processes to be followed in the event of an emergency, he said, adding that by defining those processes within a common framework, IT organizations also will be able to significantly reduce the number of point products they need to navigate during a crisis.

    The combination of the two products will also aid in applying forensics to discover the root cause of any outage, Schumacher said.

    Incident management within IT environments over the last few years has been evolving into a science. There are several dedicated incident management platforms that mange everything from who needs to be alerted in what order to providing detailed instructions bringing applications back online. The challenge many organizations wrestle with today is that all the silos of IT make it difficult to approach incident management comprehensively.

    But as it becomes easier for finance officers to draw a straight line between IT downtime and lost revenues, interest in more structured approaches to recovery is on the rise. In fact, regardless of whether the root cause of an issue is a cybersecurity breach or a geological event, the recovery process is usually consistent. Incident management platforms provide the means to capture those processes in a way that creates institutional memory. Access to those best practices is often critical, because organizations can never be sure which members of the IT staff will be available during a crisis. If the one person who knows how to provision a storage system is unavailable, there should be enough information in an incident management system to enable another member of the IT team to accomplish that task.

    As is often the case when it comes to IT, the tools at hand only enables the battle to be joined. It’s the quality of the processes attached to those tools that decides whether the battle will be won or lost.

    — Mike Vizard

  • DevOps Dozen 2018 – Nominations Are Now Open

    DevOps Dozen 2018 – Nominations Are Now Open

    The DevOps Dozen awards are back and now open for nominations. This fourth annual DevOps Dozen honors the best of the best—the leaders and innovators in the DevOps community. This year’s awards will include 12 categories, with a winner chosen from each. The top four to six nominees in each category will become finalists, who will be selected based upon the number of nominations they received. You can nominate up to two entrants in each category; however, you can make only one nomination per person. In addition, everyone nominating will be required to provide their name and email address; while that won’t thwart any ballot-stuffing, we hope people will be trustworthy during the nomination process. The winners will be selected by our panel of judges.

    Last day to submit your nominations for the DevOps Dozen 2018 awards is Oct 10, 2018. Here’s where to vote: https://www.surveymonkey.com/r/devopsdozen

    Who are the judges? This was tough. We couldn’t have anyone who might be eligible for an award. That disqualifies vendors, practitioners and many others. However, I think we have four great judges:

    1. Alan Shimel, founder and editor in chief, devopsy.kinsta.cloud
    2. George Hulme, longtime tech journalist and editor at devopsy.kinsta.cloud and Security Boulevard
    3. Jayne Groll, CEO and co-founder of the DevOps Institute
    4. Helen Beal, DevOpsologist at Ranger4.

    So what are the dozen categories for the DevOps Dozen this year? That you can get on the site itself, but here they are as well:

    [su_custom_gallery source=”media: 125437,125438,125439,125440,125441,125442,125443,125444,125445,125446,125447,125448,” link=”custom” target=”blank” width=”400″ height=”200″]

    Thank you again for your enthusiastic response to last year’s awards. The full list of 2017 finalists and winners are available to view here.

    There are so many great companies and people involved in DevOps that it’s always difficult to pick the winners. We know some worthy choices will not be voted tops in their category; however, acknowledging them in our awards process helps show how important they are in the DevOps space.

    As stated earlier, the top four to six nominees in each category will be designated as finalists, who then can submit a presentation on why they deserve the award to judges@devops.com. Finalists will be announced the second week of November and the winners, who will be chosen by our panel of judges, will be announced in December.

    If you have questions, send them to DD@devops.com. Voting for finalist nominees is open for three weeks, so don’t waste any time—nominate your favorites today. Good luck to everyone vying to be one of the DevOps Dozen 2018!

    — Alan Shimel

  • VMware Looks to ‘Ruthlessly’ Automate IT

    VMware Looks to ‘Ruthlessly’ Automate IT

    VMware, at VMworld 2018 this week, advanced an ambitious campaign to automate IT management by announcing a deal to acquire CloudHealth Technologies and then previewing a Project Magna initiative that employs machine learning algorithms and other forms of artificial intelligence (AI) to create what VMware describes as self-driven data centers.

    VMware CEO Pat Gelsinger told conference attendees that, as part of achieving that goal in the era of the cloud, every aspect of IT now needs to be automated.

    “The rule of the cloud is to ruthlessly automate everything,” he said.

    Project Magna represents an effort to centralize AI research and development to enable IT organizations to reallocate resources to building applications by eliminating many of the manual tasks that conspire to make IT inflexible.

    At the same time, increased levels of automation will serve to reduce the cost of labor associated with managing IT, which remains the single highest cost within most IT budgets. Without increased levels of automation, those costs inevitably will rise as IT organizations embrace not only public clouds but also emerging new platforms such as Kubernetes.

    Gelsinger this week made it clear VMware views being able to automate the management of Kubernetes as an opportunity to expand the reach and scope of its management offerings.

    The addition of CloudHealth Technologies to the VMware portfolio adds a cloud operations platform that spans Amazon Web Services (AWS), Microsoft Azure and Google Cloud Platform (GCP). Once the acquisition is formally closed, VMware has pledged to integrate its cloud automation services, Secure State and Wavefront cloud services with the CloudHealth platform. The CloudHealth platform will be rebranded VMware Cloud Operations. Those moves come on the heels of a significant expansion of the portfolio of DevOps tools the company also announced this week.

    VMware also revealed its is working on the Dimension project with Dell EMC and Lenovo, which will create a hyperconverged architecture optimized for deployment at the network edge. Project Dimension will make use of VMware NSX network virtualization software and the software-defined wide area networking (SD-WAN) platform gained by the company’s acquisition of VeloCloud to connect servers running at the network edge. That initiative complements the existing Pulse project for managing internet of things (IoT) devices, for which VMware announced REST application programming interface (API) support and which will be available as an on-premises or a software-as-a-service (SaaS) application.

    VMware this week also unveiled updates to updates to its vRealize automation portfolio that enable organizations to rightsize workflows and automate host-based placement of those workloads. The core vRealize Automation platform also sports a new user interface and integration with open source Ansible Tower automation software and integration with Pivotal Container Service (PKS), an instance of Kubernetes. Version 7.5 of vRealize Automation 7.5 also features enhanced AWS and Azure support.

    It’s unclear to what degree increased automation will transform how IT is managed within the context of modern DevOps processes. But the one thing that is clear is the economics of IT are being altered. Via automation VMware is sharply reducing the need for IT specialists in favor of “super” administrators capable of managing compute, storage, networking and security at unprecedented levels of scale in a much more integrated fashion. How much of that will be accomplished by AI is still anyone’s guess. But it’s already clear the job of the average IT administrator will soon be transformed utterly.

    — Mike Vizard

  • Mirantis Modeling Tool Extends SDI Scope and Reach

    Mirantis Modeling Tool Extends SDI Scope and Reach

    Mirantis has added a modeling tool to its portfolio that enables users to allocate IT infrastructure that has been distributed across multiple data centers to a common set of workloads.

    Company CEO Adrian Ionel said the latest edition of the Mirantis Cloud Platform (MCP) for building provide clouds on OpenStack or Kubernetes platforms now includes a Mirantis Infrastructure Model Designer tool that makes it possible to manage IT infrastructure residing in multiple data centers as though they were one logical resource. In effect, slices of distributed data centers can be allocated to run specific classes of application workloads, he said.

    The Mirantis tool is based on open source software spanning Cookiecutter, Reclass and Salt projects that Mirantis is employing to enable users to apply management templates across multiple distributed data centers. The goal is to make it possible for IT organizations to employ a software-defined framework that makes it easier to not only manage distributed IT environments, but also change the configuration of those environments as the nature of application workloads change over time, Ionel said.

    The Mirantis modeling tool provides a declarative approach to managing software-defined infrastructure that doesn’t require IT operations teams to learn how to program, he added.

    Ionel said that as IT organizations invest in IT infrastructure, they need to deploy multiple classes of application workloads on the same systems. Each of those application workloads has distinctly different attributes and requirements. For example, a big data application running on Hadoop today has different infrastructure requirements than an analytics application infused with machine learning data that might be deployed tomorrow. That said, most IT organizations won’t be able to replace IT infrastructure as application workloads evolve, he said, noting the Mirantis tool provides a means to easily reconfigure IT infrastructure from a central location without requiring IT personnel to be present in each local data center.

    Virtualization of servers and now storage and networks is a concept that has now permeated data centers for decades. Mirantis is effectively taking that concept to its next logical conclusion by making it possible to maximize utilization of data centers. In fact, Ionel noted, templates can be configured to prioritize the running of different workloads on the same infrastructure.

    As software-defined infrastructure (SDI) continues to mature, it’s becoming apparent that data centers soon will be managed at much higher levels of abstractions than they typically are today. Instead of trying to navigate individual compute, storage and networking silos, IT organizations will be able to manage data center resources on demand. The implications of the level of automation go well beyond simply enabling IT organizations to be more agile—the entire organizational structure of IT organizations will need to evolve.

    Obviously, organizations that have embraced DevOps are further down than the SDI path than most. But as SDI continues to be able to automate IT infrastructure at levels of unprecedented scale, it’s clear there’s still a long road ahead in terms of how just how extended those DevOps processes can become.

    — Mike Vizard

  • SnapLogic Extends DevOps Reach via GitHub

    SnapLogic Extends DevOps Reach via GitHub

    SnapLogic has extended the reach of its SnapLogic Enterprise Integration Cloud into the realm of DevOps by making it possible to store integrations creating using Snap connectors in GitHub.

    The company also announced integration with the DC/OS platform from Mesosphere along with a new service catalog and several updates to the Iris artificial intelligence (AI) software it uses make recommendations concerning the construction of integration pipelines. At the same time, SnapLogic has enhanced both its monitoring tools for application programming interfaces (APIs) and search tools for discovering broken integration pipelines.

    Craig Stewart, vice president of product management for SnapLogic, said support for GitHub makes it easier for developers at all skill levels to share preconfigured integrations via GitHub alongside all the other code they already share via the widely employed repository. That capability also makes it easier for DevOps teams to include preconfigured Snap connectors within a continuous integration/continuous development (CI/CD) pipeline, he noted, adding those integrations now can be more easily discovered within a Patterns Catalog to help developers discover and reuse integration patterns.

    Support for Mesosphere, Stewart said, is being provided by customer request. That effort will then be extended to include support for Kubernetes, which SnapLogic expects will become the de facto standard for container orchestration engine.

    Finally, SnapLogic updated its Iris AI software to provide an additional option for users to build their integration workflows starting with the last Snap of the integration pipeline. Previously, the Iris recommendation engine started with the first Snap connector. Now, when a user first places the last Snap on the canvas, the Integration Assistant will display suggested previous Snaps until the pipeline is complete. Users also have the option to start with the first and last Snaps of the pipeline and the Integration Assistant will work from the outside-in to recommend Snaps to build out the entire pipeline.

    SnapLogic is making investments designed to facilitate self-service capabilities that promote reuse of integrations, Stewart said. A recent survey of 500 IT decision-makers conducted by Vanson Bourne on behalf of SnapLogic finds on average organizations expect to generate a 547 percent return on their data investments, increasing revenue by an average $5.2 million by using data more effectively. But the survey also finds that on average organizations are using only half (51 percent) the data they collect or generate, and data drives less than half (48 percent) of the decisions being made. Organizations will spend $1.7 million on an average to operationalize data over the next five years to rectify that problem, according to the survey results, which is more than double what they currently spend.

    Much of that effort will be driven by so-called citizen integrators that reside within various lines of business outside the traditional IT department. In many cases those citizen integrators will be leveraging prebuilt integration patterns created by developer working within the internal IT department. The challenge now is finding a way to make sure all those integration patterns can be slipstreamed into a larger set of DevOps processes that are increasingly spanning the entire enterprise.

    — Mike Vizard

  • OverOps Brings Machine Learning to DevOps

    OverOps Brings Machine Learning to DevOps

    OverOps has launched a namesake platform employing machine learning algorithms to capture data from an IT environment that identify potential issues before a DevOps team decides to promote an application into production.

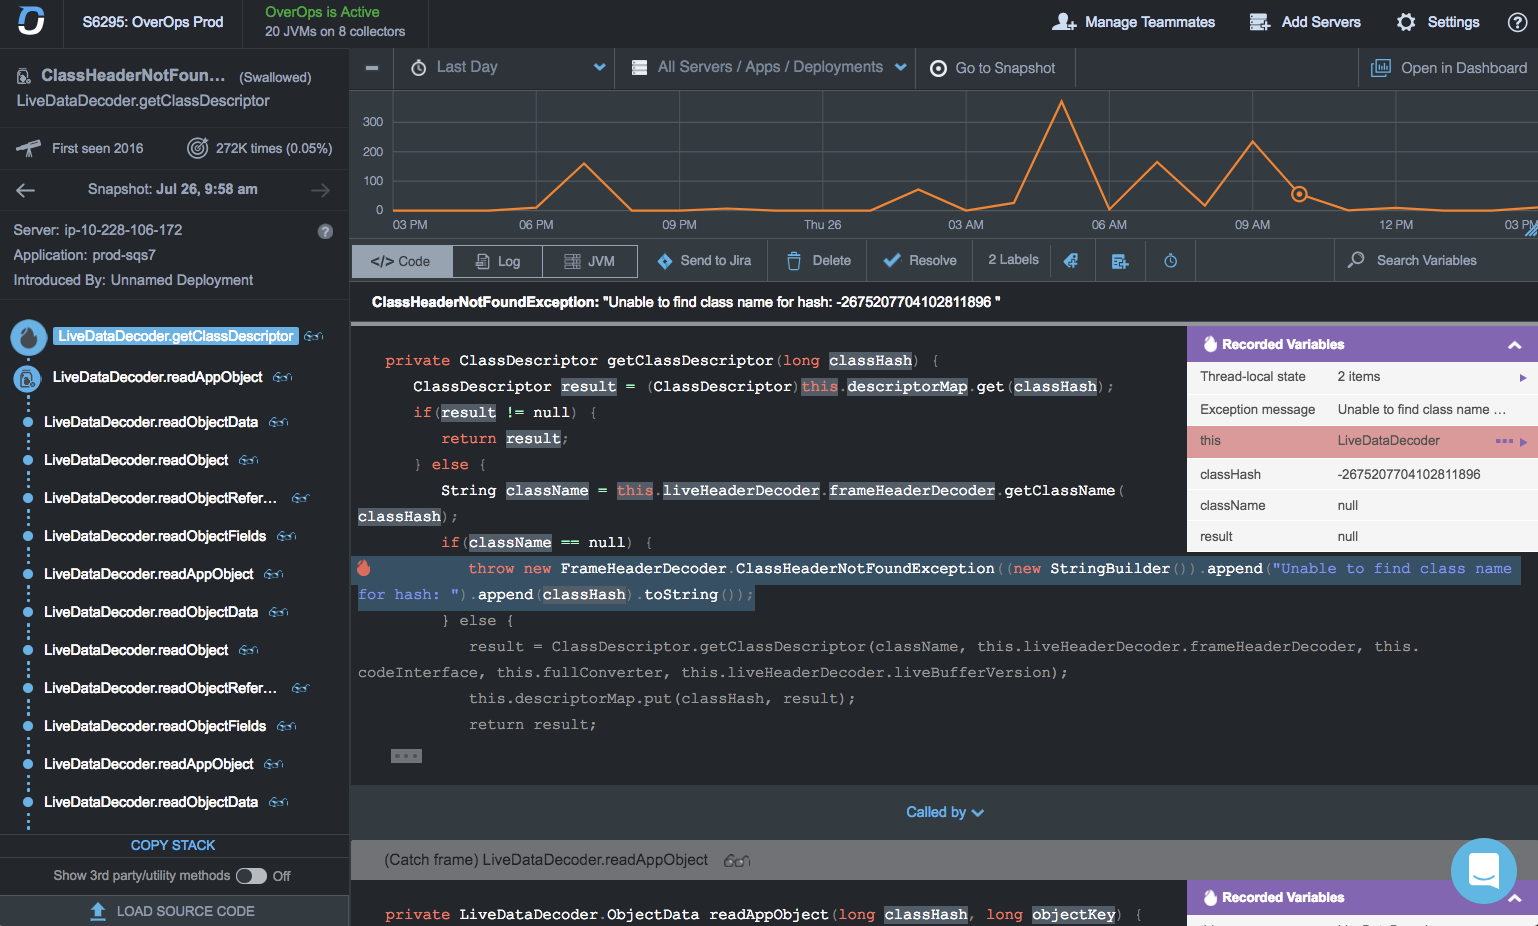
    Company CTO Tal Weiss said the OverOps Platform is unique in that, rather than relying on log data, it combines static and dynamic analysis of code as it executes to detect issue. That data then can be accessed either via dashboards or shared with other tools via an open application programming interface (API). The dashboards included with the OverOps Platform are based on open source project Grafana software.

    That approach makes it possible to advance usage of artificial intelligence (AI) within IT operations without necessarily requiring that every tool in a DevOps pipeline be upgraded to include support for machine learning algorithms, Weiss said.

    OverOps also includes in the platform access to an AWS Lambda-based framework or separate on-premises serverless computing framework to enable DevOps teams to also create their own custom functions and workflows.

    Weiss said OverOps is designed to capture machine data about every error and exception at the moment they occur, including details such as the value of all variables across the execution stack, the frequency and failure rate of each error, the classification of new and reintroduced errors and the associated release numbers for each event. Log data is, by comparison, relatively shallow in that it is challenging to determine precise root cause analysis when trying to troubleshoot an issue, he said, noting the OverOps Platform offers visibility into the uncaught and swallowed exceptions that would otherwise be unavailable in log files.

    DevOps teams spend an inordinate amount of time analyzing log files in the hopes of discovering an anomaly. But as IT environments continue to scale out, the practicality of analyzing millions, possibly even billions, of log files becomes impractical. OverOps is making the case for employing machine learning algorithms to analyze events before the log file is even created, which eliminates the need to find some way to store log files before they can be analyzed.

    There’s naturally a lot of trepidation when it comes to anything to do with machine learning algorithms and other form of AI to manage IT. But as the complexity of IT environments continues to increase, it’s clear DevOps teams will need to rely more on AI to mange IT at levels of scale that were once considered unimaginable. For example, while microservices based on containers may accelerate the rate at which applications can be developed and updated, they also can introduce a phenomenal amount of operational complexity. Most DevOps professionals would rather automate as much as possible the manual labor associated with operations, especially if that leads to more certainty about the quality of the software being promoted into a production environment.

    Of course, while making use of machine learning algorithms to analyze code represents a step forward in terms of automation, it’s still a very long way from eliminating the need for DevOps teams altogether.

    — Mike Vizard

  • When AI Met DevOps: Machine Teaching

    When AI Met DevOps: Machine Teaching

    One of my favorite quotes about artificial intelligence (AI) isn’t from a data scientist or tech industry analyst. It’s from a doctor.

    When asked if AI would eventually replace radiologists, Dr. Curtis Langoltz of Stanford University pithily replied “No, but radiologists who use AI will replace those who do not use it.”

    This great insight is highly applicable to IT. Yes, there are many ways we can use AI methods to fully automate a broad range of DevOps tasks. Companies, including CA Technologies, are actively involved in the development of solutions that enable our customers to do exactly that.

    Algorithmic machine learning, however, doesn’t just empower systems to perform tasks and solve problems autonomously. It also makes them great active partners with human beings. In fact, much of what machines learn they also wind up teaching.

    The synergy between AI and human radiologists, for example, stems in part from the fact that digital systems can differentiate about 200 levels of gray in a diagnostic image—compared to only about 16-20 that are discernable by the human eye. Train an AI system with enough images, and that precise cognitive power can more effectively detect that something is going on.

    But for the most effective diagnostic process, you don’t just depend on that detection alone. You use that detection to empower a human diagnostician who can apply a broad understanding of pathologies and deep experience with the complexities of individual patients to deliver the highest quality care.

    In DevOps, we can do the same. We can use AI to capture insights that teach us how to continuously optimize our workflows and processes. We can also use our AI learnings to push our work up higher on the value chain.

    More specifically, the synergy between AI and human intellect can:

    Make development smarter. The speed, quality, and efficiency of development pipelines can be affected by all kinds of subtle factors. A less-than-optimally designed API, for example, can be a small but chronic stumbling block to everyone who has to use it. Scrum outcomes can be undermined by anything from a particular type of technical challenge to a nascent personality conflict.

    By capturing a rich set of DevOps metrics and applying machine learning to those metrics, development leaders can discover process bottlenecks and skilling shortfalls. They can better coach individuals and promote team collaboration. The result: a better working environment that facilitates digital agility for the enterprise and higher satisfaction/retention for valuable employees.

    Make ops smarter. Enterprises are running increasingly volatile and complex workloads on increasingly hybridized infrastructure. At the same time, the tolerance of internal and external users for latency and outages continues to approach zero. There are also real costs associated with performance problems.

    The elastic capacity of public and private cloud does much to help with workload volatility. But adding cloud capacity also has its costs—and end-to-end application performance often depends on back-end systems that are not cloud-based. So not every performance issue can be solved by simply throwing more capacity at it. Nor should it be, if a rearchitecting can fix a bottleneck less expensively.

    Here again, AI can teach us a lot. We can uncover opaque interdependencies in processing load and data throughput. We can spot conditions when it may make business sense to throttle cloud costs that aren’t cost-justified. We can even better understand the real-world conditions—whether patterns in customer behaviors or our own marketing programs—that are driving our demand spikes and troughs. All of this helps us deliver consistently responsive digital experiences at a cost that makes good business sense.

    Make security smarter. AI is already being broadly implemented in security solutions such as endpoint protection and threat response to automate the detection and neutralization of anomalous activities in the enterprise environment. But effective multi-layer security isn’t just about finding and stopping exploits. It’s also about building applications that are themselves inherently less vulnerable to hacking. This is the essence of DevSecOps.

    AI has huge potential value here. We are writing a rapidly growing volume of increasingly sophisticated code. It is very easy for subtle vulnerabilities to hide in that code. As our development practices become more complex—often including multiple contractors—it becomes more difficult to understand exactly where and why these vulnerabilities were introduced into our code. Machine learning can teach us the answers to these questions, so we can more proactively secure our data and our businesses.

    It’s especially interesting to consider what may happen as we start to apply AI to DevSecOps across our organizations, as well as within them. More diverse inputs enable machine learning to discover more factors that impact code pipeline performance. By aggregating our knowledge about how we build, deliver and secure our code, we are all likely to benefit with better practices and stronger guardrails.

    — Cameron Van Orman

  • 6 Ways AI and ML Will Change DevOps for the Better

    6 Ways AI and ML Will Change DevOps for the Better

    There’s been a lot of media attention in recent years about how artificial intelligence (AI) and machine learning (ML) are going to change the world—how they’re going to create new and interesting applications in fields as diverse as education, law, health care and transportation. This may happen. But if I had to bet on a use case where AI and ML will create a tangible, lasting impact, I’m putting my chips on DevOps.

    DevOps is all about automation of tasks. Its focus is on automating and monitoring every step of the software delivery process, ensuring that work gets done quickly and frequently. While it doesn’t eliminate human tasks—far from it—it does encourage enterprises to set up repeatable processes that promote efficiency and reduce variability.

    AI and ML are perfect fits for a DevOps culture. They can process vast amounts of information and help perform menial tasks, freeing the IT staff to do more targeted work. They can learn patterns, anticipate problems and suggest solutions. If DevOps’ goal is to unify development and operations, AI and ML can smooth out some of the tensions that have divided the two disciplines in the past.

    Here are six ways AI and ML can and will change DevOps for the better.

    Promoting Feedback on Performance

    One of the key tenets of DevOps is the use of continuous feedback loops at every stage of the process. This includes using monitoring tools to provide feedback on the operational performance of running applications. This is one area today where ML is impacting DevOps already. Monitoring platforms gather massive amounts of data in the form of performance metrics, log files and other types. Advanced monitoring platforms are applying machine learning to these datasets to proactively identify problems very early and make recommendations. These recommendations go to the DevOps team members so that they can ensure that the application service remains viable. Machine learning is enhancing the continuous feedback loops that are critical to DevOps.

    Enabling Communication

    Communication and feedback is always one of the biggest challenges when organizations move to a DevOps methodology. Human interaction is vital, but with so much information flowing through the system, teams need to set up a wider variety of channels to set and revise workflows on the fly. Using automation technology, chatbots and other systems initiated by AI, these communications channels can become more streamlined and more proactive.

    Correlate Data Across Platforms and Tools

    To operate efficiently, DevOps teams need to simplify tasks. This is getting more difficult as environments get more complex. Start with monitoring tools: Teams tend to use multiple tools that monitor an application’s health and performance in different ways. Machine learning applications can absorb these data streams and find correlations, giving the team a more holistic view of the application’s overall health.

    Manage a Flurry of Alerts

    Since DevOps encourages teams to “fail but fail fast,” it’s critical to have an alert system that spots a flaw quickly. This tends to create scenarios where alerts are coming fast and furious, all labeled with the same severity, making it difficult for teams to react. Machine learning applications can help teams prioritize their responses based on factors such as past behavior, the magnitude of the current alert and the source that specific alerts are coming from. Humans can set up rules, but machines can help manage these types of situations when too much data overwhelms the system.

    Evaluating Past Performance

    AI/ML also has the potential to help developers during the application creation process. By examining the success of past applications in terms of build/compile success, successful testing completion and operational performance, machine learning algorithms could make recommendations to developers proactively based on the code they are writing or the application that they are building. The AI engine could direct the developer in how to build the most efficient and highest-quality application.

    Software Testing

    In the future, we could see AI/ML applied to other stages of the software development life cycle to provide enhancements to a DevOps methodology or approach. One area where this may happen could be in the area of software testing. Unit tests, regression tests, functional tests and user acceptance tests all produce large amounts of data in the form of test results. Applying AI or machine  learning algorithms to these test results could identify patterns of poor coding practices that result in too many errors caught by the tests. This information could then inform the development teams so that they can become more efficient in the future.

    Similarly, leveraging historical data, AI/ML could be used to fine-tune deployment strategies as applications are moved from Dev to Test to Production environments.

    — Mike Hughes

  • Choose Your Toolstack — and Manage It — Wisely

    Choose Your Toolstack — and Manage It — Wisely

    Every DevOps toolstack has a control point, be it a bus, an app, a management app or whatever. Something always is in control and driving the other pieces of the architecture to do their part. It is a basic tenet of automation that jobs are mostly kicked off by something in the software hierarchy.

    In DevOps, most of us have defaulted to Jenkins for a large chunk of that automation. It was the center of the continuous integration/continuous delivery (CI/CD) side, and increasingly it is used to run both sides of DevOps (as I have called it previously, both DEVops and devOPS). CloudBees and recognized this trend, and an increasing amount of control and process functionality has been turning up in Jenkins.

    On the other side, there are organizations running all of devOPS from deployment tools such as Ansible or Puppet. Again, that’s not a terrible solution, since they can configure the software on the server and make sure all is ready to run.

    But neither of these toolsets was originally envisioned with the idea it would control as much of the DevOps stack as they currently do.

    If you read me regularly, you know I’m not a huge fan of this type of default control structure. There is a lot of functionality that can be laid over the CI/CD and environment automation tool. But to do some of it, the tool needs to be above the day-to-day functionality these tools specialize in.

    ARA can do it—and honestly, for a first brush at connecting the worlds represented by CI/CD and configuration management tools, is pretty impressive. Other vendors have come at it from a service bus perspective, allowing everyone to communicate through their tools and doing roll-up reports based upon what has been integrated. That’s not a terrible solution either, if it works with or can be made to work with your tools.

    ARA as a market is short on the monitoring and management end of the process when the app is deployed and clipping along. It’s getting better, and hopefully ARA that is fully integrated with monitoring tools will be the next step in this evolution, but for now most companies are handling tooling, monitoring and response to that monitoring outside of the ARA system.

    The queue systems tend to lag behind ARA in their ability to correlate and coordinate, but again this is getting better. They know only what is reported through them, so as they gain add-ons, expect they’ll handle the overall stack better.

    The long-term goal is, after all, to run from commit to release with only designed “go/no-go” checkpoints involving humans, and then to monitor, with humans getting notifications only as needed. How we get there may not be so important—or it might.

    In the market, the sand is still shifting too fast for vendors to keep up. In any given implementation, how fast you adopt all the new products is a function of choice. Use controlled chaos, changing things out for the better only when you have a quantifiable benefit and they fit into your overall architecture. Most importantly, no matter which toolset you choose to use to control the check-in-to-release cycle, new tools you introduce should integrate with it.

    So what am I recommending? That you choose a control tool that fits your specific environment and needs, and that you make certain when choosing new tools you have a path to get them integrated with that control tool. Nothing more. Don’t put a tool in charge of half or all of your DevOps toolstack just because it was there. Have a real reason, then use that reason as a gauge when adopting new tools.

    — Don Macvittie