Category: DevOps Practice

  • Cycode Discloses GitHub Actions Vulnerability in Google Bazel Project

    Cycode Discloses GitHub Actions Vulnerability in Google Bazel Project

    Cycode today revealed it discovered a command injection vulnerability in the way the GitHub Actions continuous integration/continuous delivery (CI/CD) platform was used to update the open source Bazel project that many organizations employ to build and test software.

    The vulnerability, now remediated, could have been used to create a backdoor through which malicious code could have been inserted into a codebase that is managed by Google.

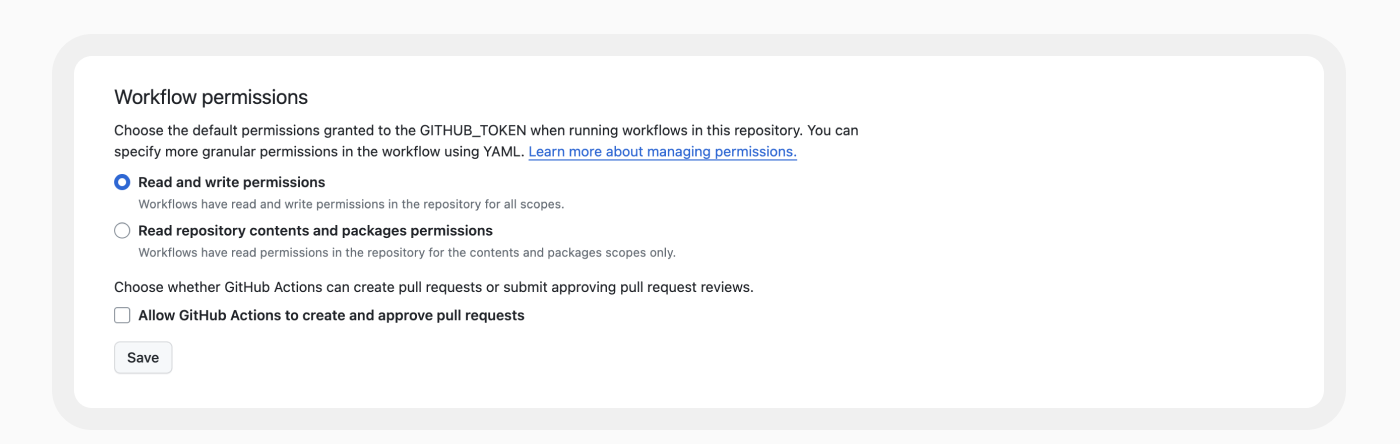
    Cycode researchers shared their discovery with Google, which has since updated the way it employs GitHub Actions to manage the Bazel codebase. Specifically, Google updated the base permissions to embrace least privilege principles to resolve the vulnerability discovered by Cycode.

    The vulnerability was discovered using RAVEN, an open source tool for scanning CI/CD platforms for vulnerabilities that Cycode makes available.

    Elad Pticha, senior security researcher for Cycode, said the vulnerability is the latest example of an instance of an open repository for building software that has been shown to be potentially vulnerable to an attack on a software supply chain that could theoretically impact any number of downstream applications and projects, including Kubernetes, Angular and platforms and services provided by Uber and LinkedIn.

    A Custom Actions capability that enables application development teams to create their own workflows presents any cybercriminal attempting to compromise of software supply chain with a tempting target, noted Pticha. A few changes to lines of code in a workflow can translate into thousands or even millions of lines of code, many of which an organization may never detect. Out of 3.4 million workflows examined by Cycode, nearly all (99%) make use of one or more Custom Action.

    Cycode has previously identified dozens of vulnerabilities in open source projects by mainly focusing on vulnerabilities within workflows. This latest research shows those vulnerabilities extend to indirect dependencies, such as Custom Actions, noted Pticha.

    Each DevOps team should review its own workflows for similar vulnerabilities at a time when more cybercriminals than ever are intent on compromising software supply chains. While many organizations have embraced DevSecOps workflows to improve application security, there is a natural tendency to overlook vulnerabilities that might exist in the workflows used to build and deploy software. The challenge is that DevSecOps workflows are still immature. A recent survey of 500 U.S. CISOs, AppSec directors and DevSecOps team members conducted by Cycode found 78% admitted application security attack surfaces are unmanageable, with 90% acknowledging relationships between their security and development teams need to improve.

    It’s not apparent if the vulnerability discovered by Cycode was actually ever exploited, but as most cybersecurity professionals know, if it can be imagined, someone has tried it. As such, any organization that uses Bazel might be well-advised to conduct a code review.

    In the meantime, it’s already apparent that regulations pertaining to securing software supply chains are only going to become more stringent in the months ahead. In the wake of the executive order from the Biden administration requiring federal agencies to lock down their software supply chains, it’s now only a matter of time before similar requirements are baked into legislation and various other regulations are implemented. The challenge and the opportunity now is to get ahead of this issue before a mandate with a hard deadline that can’t be ignored winds up disrupting the entire software development life cycle.

  • How to Manage Multi-Cloud Infrastructure and Reduce Costs

    How to Manage Multi-Cloud Infrastructure and Reduce Costs

    It’s no secret that the public cloud has been a game changer for businesses. In today’s world, every organization is looking for ways to store data more efficiently, support agile application development and reduce the burdens associated with on-premises data centers.

    The public cloud is essential for meeting those objectives and achieving the higher degree of innovation and digital transformation that many organizations seek. While the shift to the cloud has unlocked unprecedented innovation, it has also created a new layer of complexity and sometimes unexpected costs.

    The Nutanix Enterprise Cloud Index found that nearly every organization (99%) has moved one or more applications to a different IT infrastructure in the past year, and the vast majority (86%) agree that moving applications is both complex and costly. Accordingly, 56% plan to focus on gaining more visibility into their cloud consumption and costs this year, while 52% plan to leverage solutions that minimize cloud waste.

    As Scott Sinclair, senior analyst for TechTarget’s Enterprise Strategy Group explains, “The typical enterprise now has multiple data centers and public cloud providers, and many are also using lots of different colocation facilities and multiple edge locations.” As such, “It presents a new paradigm with companies having to look at different factors and considerations like cost, portability and security because their data is no longer all locked in one room.”

    Organizations must carefully plan their cloud strategy to avoid getting bogged down by complexity and sticker shock. But in most cases, this is easier said than done. The majority of companies are not using a single environment — their infrastructure includes some combination of on-premises and public cloud resources. One of the challenges this creates is additional expenses and complexity associated with data mobility and data protection: Moving data around so that it’s available where and when it’s needed while simultaneously keeping it safeguarded requires careful planning and budgeting. In other words, data has gravity, and unless data movement and orchestration are planned, one can end up stranded when the primary location for a dataset is unavailable.

    Even companies that were born in the cloud have their work cut out for them. Managing different cloud environments might be relatively straightforward for a cloud-native organization initially, but if at some point their data needs to be relocated on-premises to address compliance, data sovereignty issues or budget, it can result in soaring costs if not properly executed.

    With this being said, here are four considerations CIOs should take into account to keep cloud complexity and costs in check from the start.

    1. Have Your Head in the Cloud but Your Feet on the Ground

    To reap the benefits of the cloud, organizations need to adjust their expectations and plan realistically. There’s a false perception that companies can run an application on AWS in the morning, Azure in the afternoon, and Google Cloud Platform at night. In actuality, multi-cloud is a medium-to-long-term strategy that occurs over months or years. Building a cloud operating model with this in mind lets organizations benefit from the flexibility of leveraging multiple clouds while avoiding the cost and complexity associated with trying to do too much too fast with the cloud. When appropriate expectations are in place, hybrid multi-cloud is achievable, affordable, and undoubtedly beneficial.

    2. Learn on Others’ Dime as Much as Possible

    There are several best practices organizations should follow as they begin their hybrid multi-cloud journey. These include things like ensuring key application capabilities have API wrappers, containerizing modern applications as much as possible so they are portable, and automating application deployments through CI/CD pipelines to avoid manual errors and reduce costs. Public clouds have been around for almost 15 years, and designing for the public cloud is now quite well understood across the industry. Still, companies need to be mindful of how they leverage public cloud for certain applications or workloads. For example, modernizing a legacy application portfolio might sound like a good idea in theory, but in reality, it is cost-prohibitive and it will not provide ROI —lift and shift is a much better option for legacy applications.

    3. Standardize, Automate and be Paranoid

    Public cloud environments are fundamentally different from traditional on-premises infrastructure, so organizations need to think about them differently—especially where security is concerned. While a fortified exterior with unfettered internal freedom might be a workable model for on-premises, the same model could spell disaster in the cloud. Host-based security approaches have become more critical in the public cloud. Automation and standardization ensure that security measures are applied consistently across all cloud resources and services within an organization and shorten the window to detect unauthorized behaviors. Organizations must also consider the non-technology aspect of this: training and education for their teams. All teams and departments must be on the same page when it comes to security so they can collaborate effectively on security-related initiatives.

    4. Build in Optionality From Day One

    The public cloud is by far the best place to begin innovation. However, as companies experiment in the public cloud and a smaller portfolio of applications gain traction, enterprises need to adjust to the reality that — for the vast majority of applications — the public cloud will always be more expensive than running them on-premises (or perhaps even another cloud). To avoid lock-in, enterprises must build in optionality for migrating their compute when needed, as well as the mechanism to move their data out of public clouds when needed. Organizations that are flush with cloud engineering talent can do this on their own, but the vast majority will require an underlying platform that’s explicitly designed for data and computation mobility.

    The perks of one platform to run all workloads across clouds, on-premises, and the edge are undeniable: From increased flexibility to optimized performance, compliance, agility and more. By heeding the advice above, companies can keep multi-cloud challenges like complexity and unexpected costs at a minimum and fuel innovation.

  • Azure Cost Optimization: A Complete Guide

    Azure Cost Optimization: A Complete Guide

    Microsoft Azure is one of the “big three” cloud providers, and is a primary part of IT expenditure for many companies. Azure cost optimization is a strategy that involves managing and controlling Azure costs to ensure efficient usage and spending. It requires a thorough understanding of where and how your resources are being used, as well as insight into the various pricing options available.

    Azure cost optimization involves implementing best practices related to managing cloud costs, such as turning off resources when not in use, choosing the right-sized resources, taking advantage of Azure discounts and more. By optimizing these aspects, you can ensure that you are only paying for the resources you need and are using them efficiently.

    Azure cost optimization is an ongoing strategy that involves constant monitoring and adjustments as your usage and needs evolve. This means that you need to be proactive and vigilant in your cost management efforts, regularly reviewing your usage patterns and making adjustments as necessary.

    Why is Azure Cost Optimization Important?

    As organizations migrate more and more of their workloads to the cloud, the costs associated with Azure usage can quickly escalate if not properly managed. This can lead to budget overruns and decreased profitability.

    By leveraging Azure cost optimization strategies, businesses can gain greater control over their Azure spending. This not only helps in reducing costs but also enables businesses to more accurately predict their future cloud spending. This can be a major advantage when it comes to financial planning and budgeting.

    Moreover, Azure cost optimization can also lead to improved operational efficiency. By ensuring that resources are used efficiently, businesses can avoid wasted spend and focus their resources on the tasks that truly add value to their operations. This can lead to increased productivity and better overall performance.

    Azure Cost Optimization Tools

    Azure provides several free tools designed to help customers optimize their cloud spending. These tools provide insights into your usage patterns, help you identify potential cost savings, and guide you in implementing best practices for cost management.

    Azure Cost Management and Billing

    Azure Cost Management and Billing provides detailed insights into your Azure spending. It allows you to track your spending by resource, location, service, and more, enabling you to identify where your money is going.

    With Azure Cost Management and Billing, you can set up budgets to control your spending and set up alerts to notify you when you’re nearing your budget limits. You can also analyze your spending trends over time, which can be useful for forecasting future costs.

    Azure Advisor

    Azure Advisor provides personalized recommendations based on your usage and configurations, helping you optimize your resources for cost, performance, security and reliability.

    Azure Advisor can identify unused or underutilized resources you can shut down or resize to save money. It also provides recommendations for purchasing reserved instances or using Azure Hybrid Benefit, which can lead to significant cost savings.

    Azure Pricing Calculator

    The Azure Pricing Calculator is a tool for estimating the cost of Azure services before you use them. You can input your expected resource usage, and the calculator will provide an estimate of the costs.

    This tool can be especially useful when you’re planning a new workload or considering a migration to Azure. By understanding the potential costs upfront, you can make more informed decisions and avoid surprises.

    Azure Monitor

    Azure Monitor is a comprehensive service that provides insights into your application performance, infrastructure, and network. While primarily used for performance monitoring, it can also provide valuable insights for cost optimization.

    For example, Azure Monitor can help you identify overutilized or underutilized resources, enabling you to make adjustments to optimize your costs. It can also help you track your resource usage over time, providing insights into your spending patterns.

    Azure Resource Graph

    Lastly, Azure Resource Graph is a service that enables you to explore your Azure resources at scale. It provides a unified view of your resources across all your subscriptions, making it easier to manage and optimize your resources.

    With Azure Resource Graph, you can quickly identify resources that are not in use or are underutilized, allowing you to reduce unnecessary spending. It also enables you to visualize your resource usage, helping you understand your spending patterns better.

    6 Strategies for Azure Cost Optimization

    Now that we are familiar with the basics of cost optimization on Azure and the tools the platform provides, let’s review some strategies that can help you optimize and reduce costs in Azure.

    1. Right-Sizing Azure Resources

    One of the simplest yet most impactful strategies for Azure cost optimization is to right-size your Azure resources. This involves matching your business requirements with the appropriate Azure resources in terms of type, size and quantity.

    Too often, organizations over-provision their Azure resources, which leads to unnecessary expenditures. By right-sizing, you ensure that you’re only paying for what you need. This can be achieved by closely monitoring your Azure resources usage, identifying any underutilized resources, and scaling them back accordingly.

    Remember, Azure provides a range of resource types, each with its own set of capabilities and costs. Always cross-verify whether the selected resource is the most cost-effective one for your specific use case. For instance, if your application doesn’t require high compute power, choosing a lower-tier virtual machine could significantly reduce your costs.

    2. Utilizing Azure Budgets and Alerts

    Azure Budgets and Alerts are powerful tools for cost management. They provide you with the ability to set a budget for your Azure spending and receive alerts when your spending approaches or exceeds your budget.

    Setting up an Azure budget is a proactive approach to cost management. It allows you to allocate your finances effectively and avoid any unexpected charges. Furthermore, with Azure alerts, you can instantly get notified when your consumption is nearing your budget. This gives you ample time to adjust your usage or increase your budget, preventing any service disruptions due to overspending.

    Moreover, Azure Budgets and Alerts are highly customizable. You can create multiple budgets for different scopes (like management groups, subscriptions, or resource groups), set your alert conditions, and even automate actions based on these alerts using Azure Logic Apps.

    3. Tagging and Resource Organization

    Azure tagging and resource organization is another crucial strategy for Azure cost optimization. Tags are user-defined key-value pairs that you can assign to your Azure resources. They help you categorize and manage your resources based on your business needs.

    By effectively tagging your Azure resources, you can gain visibility into your resource consumption at a granular level. This can help you identify any high-cost resources, track your spending by project, department or environment, and make informed decisions about cost optimization.

    Organizing your resources into logical groups can also simplify management and governance. For instance, you can group your resources based on their life cycle or purpose and apply consistent policies and access controls across the group. This not only improves security and compliance but also helps in identifying any redundant resources that can be eliminated to save costs.

    4. Utilizing Storage Tiers Based on Usage Requirements

    Another effective strategy for Azure cost optimization is to utilize different storage tiers based on your usage requirements. Azure Storage provides three access tiers – hot, cool and archive, each designed for different types of data.

    The Hot tier is for data that is frequently accessed and requires low latency. It has higher storage costs but lower access costs. The Cool tier is for infrequently accessed data, offering lower storage costs but higher access costs. Finally, the Archive tier is the most cost-effective solution for long-term retention of rarely accessed data.

    By carefully analyzing your data usage patterns and selecting the right storage tier, you can significantly reduce your Azure storage costs. Moreover, Azure offers automatic tiering options like blob-level tiering and life cycle management policies, which can further optimize your storage costs based on your data lif ecycle.

    5. Leveraging Azure Hybrid Benefit

    If you’re an existing Microsoft customer, leveraging Azure Hybrid Benefit can be a game-changer for your Azure cost optimization. Azure Hybrid Benefit allows you to bring your on-premises Windows Server and SQL Server licenses with software assurance to Azure, offering significant cost savings.

    With Azure Hybrid Benefit, you can run Windows Server and SQL Server workloads on Azure at a reduced rate, providing substantial savings as compared to pay-as-you-go prices. Furthermore, Azure is the only cloud provider that offers such benefits, making it an ideal choice for businesses looking to optimize their cloud costs while leveraging their existing Microsoft investments. Azure Hybrid Benefit is starting to support software from other companies, including Oracle and Red Hat.

    6. Regularly Reviewing and Optimizing Subscriptions

    Lastly, regularly reviewing and optimizing your Azure subscriptions is a must for Azure cost optimization. This involves keeping track of your Azure usage and costs, identifying any inefficiencies and making necessary adjustments.

    Azure provides several tools like Azure Cost Management and Azure Advisor that can help you gain insights into your Azure spending and offer personalized recommendations for cost optimization. For instance, Azure Advisor can identify idle resources that can be shut down to save costs or suggest reserved instances for predictable workloads to avail discounts.

    Moreover, consider exploring Azure Cost Management Power BI App for advanced reporting and analysis of your Azure spend. It offers a rich set of visuals and filters that can help you uncover deep insights into your cost data and drive cost efficiency.

    In conclusion, while Azure offers a plethora of services and capabilities, managing costs effectively requires strategic planning and continuous monitoring. By implementing the above strategies, you can ensure that you’re making the most out of your Azure investments while keeping your costs under control.

  • Dynatrace Extends Data Reach and Scope of Observability Platform

    Dynatrace Extends Data Reach and Scope of Observability Platform

    At its Perform 2024 event today, Dynatrace unfurled a Dynatrace OpenPipeline that makes it possible to apply analytics to multiple types of data sources in real time.

    The company also unveiled a Data Observability offering that can be used to vet the quality and lineage of data being exposed to the Davis artificial intelligence (AI) engine at the core of the Dynatrace observability platform to reduce false positives that otherwise might generate an alert in addition to helping reduce the volume of data that might need to be stored.

    Finally, Dynatrace announced it is starting today extending the reach of its observability platform to the large language models (LLMs) that are used to create generative AI platforms. That capability will, for example, make it simpler to monitor the consumption of tokens that are used to provide access to these models.

    Steve Tack, senior vice president for product for Dynatrace, said Dynatrace OpenPipeline will enable organizations to streamline the collection of data in a way that will enable them to apply observability more broadly by applying stream processing algorithms to petabytes of data.

    Scheduled to be available in 90 days, the Dynatrace OpenPipeline capability enables IT teams to ingest and route observability, security, and business events data from any source and in any format at the point of ingestion, including unstructured data that is automatically converted into a usable format. That data can then be enriched to enable deeper analytics.

    It also provides IT teams with more control over which data they analyze, store or exclude from analytics, which in turn helps reduce the total cost of observability, noted Tack.

    Finally, it presents IT teams with the ability to apply more customizable security and privacy controls to how that data is employed, he added.

    Dynatrace is pursuing a multimodal approach to AI that spans predictive, causal and generative models. Collectively, that approach makes it simpler to identify the root cause of issues, identify anomalies that might disrupt services and streamline incident management by, for example, providing summarizations of events in a natural language format.

    It’s not clear how broadly observability will be applied beyond the data collected to manage DevOps workflows and other IT processes, but it’s clear there is a high correlation between IT events and business outcomes as organizations become more dependent on software. As AI becomes more pervasively employed, it should become simpler to apply analytics to a much wider range of types of data to surface the relationship between IT events and business processes. In effect, Dynatrace is making it simpler to apply best data engineering practices to collect, manage and analyze that data, noted Tack.

    In the meantime, DevOps teams should revisit how their pipelines are currently constructed to make it simpler to capture all relevant data. As critical as telemetry data collected from the DevOps platform is to ensure application development and delivery occurs as fast as possible, that data is only one factor in a larger equation. The challenge and the opportunity now is determining how best to apply AI to correlate it all.

  • Security Across the SDLC

    Security Across the SDLC

    We’ve seen some interesting movements in the security space over the last couple of years. My focus is on application security, but one of the movements we’ve seen is the blurring of what is application and what is infrastructure security, so I do a fair amount of that also. And then, with the advent of WAAP, we have network security playing a role in AppSec… It’s a growing snowball.

    I will start with the mandatory happy declaration that DevOps no longer treats security as an annoyance. While we’re well past that, I think the shock of the whole “security is a problem, not protection” mentality that DevOps started with is still hanging with us, and some still actively believe that. But at this point, we’re well on the “Security is part of the process” trail we should be on.

    If you look at the top-level changes, static application security testing (SAST) vendors have grown to be development security, covering SAST, DAST, IAST, RASP and even a bit of data security. Meanwhile, load balancers and WAF slowly evolved into full-on web applications and API security that covers the production side with active protections for things like DDoS and DLP.

    Likewise, we’ve seen this with the growth of cloud workload protection and how the entire digital architecture is being pulled into CSPM.

    I’ve said it before – we’re in a consolidation phase. It looks like it will go even further than I thought, though. Now, we are starting to see an interesting development: WAAP vendors are starting to include some or all of DAST, SAST and RASP. Arguably, they always did some IAST because their focus was on runtime protection, but their emphasis is more on protection than test, so it will be interesting to see that bit expand also.

    And all of this includes an inconvenient fact. We don’t have any more people to do security than we ever did; in fact, we have less. That’s part of the reason that we haven’t shoved security everywhere – there aren’t people to do it. In true DevOps fashion, we have distributed the work across other teams – Dev is right there where code security and API security start, so we’ve implemented SAST and DAST bits right into the IDE, for example. Or Ops has always done some amount of security, and we’ve just upped the amount. But they don’t magically have more time, either. I’m sure you are feeling it if you are a practitioner; almost all of us are. AI promises to help with that, and in security, it will likely deliver. Another thing I’ve pointed out before is that security is one space that really does stand to gain from generative AI – in helping make more secure code, in helping make all the permutations of tests, in making rules based upon observed data and more. The time-saving benefits will deliver, in my opinion. But it’s still a lot of work, and some of it is straight-up additional work because we weren’t doing things like container security a few years ago.

    In the short term, if full SDLC security is applied, there will be more work. In the long term, the mega platform for security may well reduce this work as it limits notifications across tools. Maybe we should name the coming mega platform SecArch. Also in the long term, AI will help alleviate some of the load. Until then, buckle in. You’re not likely to get staff to cover new work. But it will be worth it. Just keep plugging along, and know when to say you just can’t add one more thing to the pile.

  • Anima Adds Ability to Personalize Generative AI Code

    Anima Adds Ability to Personalize Generative AI Code

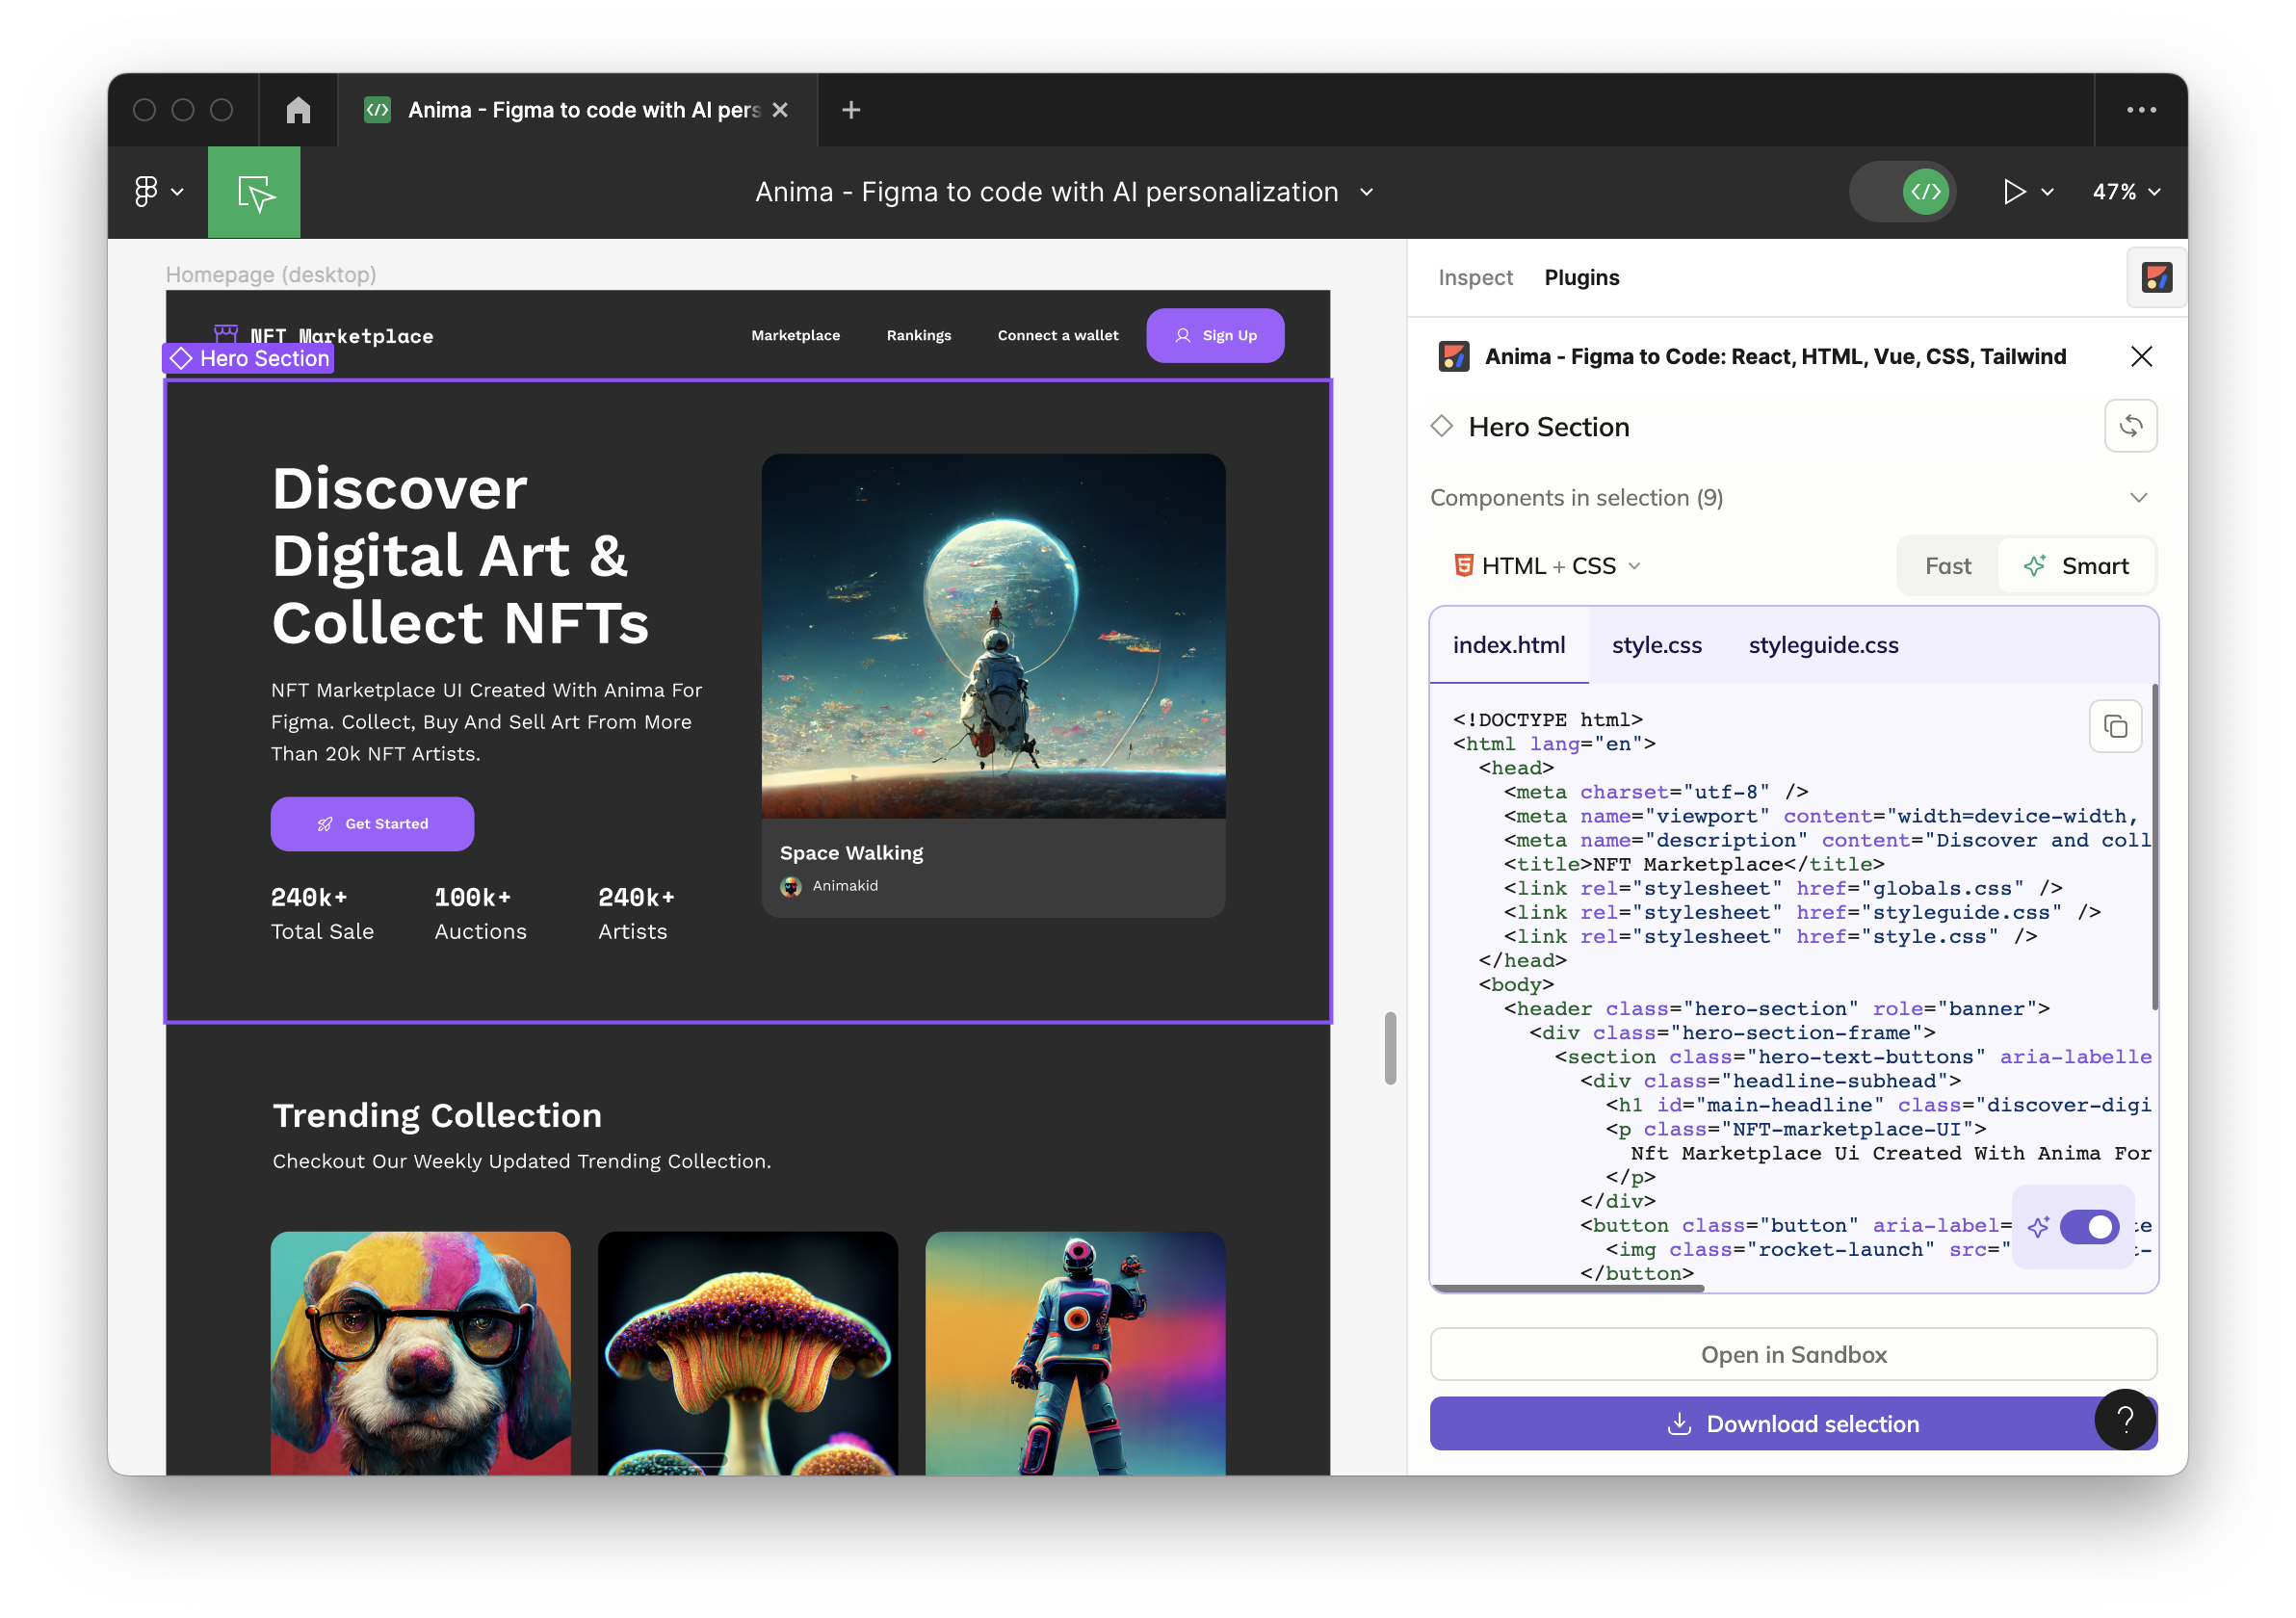
    Anima today revealed is has added an ability to personalize the code its generative artificial intelligence (AI) platform creates based on how an application is described using tools from Figma and Adobe.

    That capability makes it possible for the code being generated to resemble the coding style of an organization or specific developer more closely.

    Anima CEO Avishay Cohen said the company developed this capability to reduce the editing time that is otherwise required when trying to embed code generated by a large language model (LLM) within an application that has a well-defined coding methodology.

    The platform that Anima provides is based on a mix of LLMs and heuristics that the company developed to generate code. In this case, the code being generated is written in React or HTML to make it simpler to build an application’s front end. In contrast, a general-purpose LLM such as ChatGPT is not optimized for creating these types of graphical applications.

    Developers no longer need to worry about, for example, making sure each pixel is perfectly placed because the Anima platform automates that part of the application development process, including adding responsive behavior, animations and logic, noted Cohen. In addition, customized instructions may be applied to an entire project or even a specific component.

    In effect, the platform enables backend developers to automatically create a front-end for their application from a description in tools provided by Figma or Adobe. As a result, developers can allocate more time to writing business logic and optimizing application performance, said Cohen.

    Later this year, Anima will integrate its platform with GitHub and other continuous integration/continuous delivery (CI/CD) platforms as part of an effort to extend the reach of the platform across an entire codebase, he added.

    There is, of course, already no shortage of generative AI tools for writing code, but the degree to which they have been incorporated into DevOps workflows varies from one organization to the next. Much of the code created using platforms such as ChatGPT can vary widely in terms of quality. These platforms were trained using code collected from across the web so it’s not uncommon for the code generated to include known vulnerabilities that DevOps teams need to scan before incorporating into a build. In other cases, the code generated might simply break when installed.

    Regardless of these issues, however, the amount of code being generated by machines is only going to increase, especially as more LLMs that are specifically trained to create code based on examples that have been closely vetted become more widely available.
    In the meantime, developers who never especially enjoyed building the visual front ends of applications can now focus more of their time on tasks they prefer. Alternatively, developers who specialize in the front ends of applications will find that much of the toil involved will soon be automated in a way that should provide more time for them to create customized experiences.

    One way or another, the overall pace at which applications are built is about to exponentially increase. The challenge now will be finding ways to take advantage of AI to enable DevOps teams to keep pace.

  • CloudBolt Commits to Applying AI to FinOps

    CloudBolt Commits to Applying AI to FinOps

    CloudBolt Software today revealed it plans to infuse artificial intelligence (AI) into the financial operations (FinOps) capabilities it provides via its IT management platform over the coming year.

    Kyle Campos, chief product and technology officer for CloudBolt, said given the inherent complexity of modern IT environments, there is a need to apply machine learning algorithms and other forms of AI to enable IT organizations to apply policies in real-time to reduce costs. That capability is especially critical in cloud computing environments where services are often invoked by developers with little to no oversight, he noted.

    FinOps is a discipline that promotes a shared responsibility for an organization’s cloud computing infrastructure and costs. Rather than having disparate procurement teams working in silos to identify and approve costs, business, financial and IT leaders establish policies and best practices for usage that are programmatically enforced. The FinOps Foundation, an arm of the Linux Foundation, has been defining a set of FinOps best practices, but many organizations still lack the discipline required to implement them. One of the major reasons organizations lack this discipline is that many of them have been allowing application developers to provision cloud resources themselves. It’s not until the bill comes due at the end of the month that finance teams realize there is an issue when there is a sudden spike in costs.

    Rather than deploying a separate platform to manage FinOps, CloudBolt is making a case for integrating a framework for managing FinOps within the same platform IT teams use to manage those IT environments. That approach makes it possible to apply FinOps policies in a way that ensures best practices for controlling costs are implemented without creating yet another silo within an IT organization, said Campos.

    Running application workloads in the cloud is fundamentally different than running them in an on-premises IT environment where costs are largely fixed. Not many developers have much of an appreciation for the additional storage and cybersecurity expenses that are generated every time a new workload is added. As a result, many organizations lack visibility into the total cost of cloud computing until the monthly bill arrives. By then, it’s too late for IT teams to have any impact on the outcome.

    In the face of ongoing economic uncertainty, more organizations are clearly moving to reduce cloud computing costs more aggressively. In an ideal world, IT teams would be able to instantly see what impact any change to an IT environment will have on costs as part of any scenario planning exercise, said Campos.

    While most organizations would like to reduce their cloud costs, it’s just as important to ensure that the bills being incurred are predictable. Finance teams don’t appreciate surprises, no matter how important an application may be. IT leaders are now being held more accountable than ever to make sure cloud computing costs meet expectations from one month to the next. The challenge now is finding a way to inject controls in IT environments long after applications have already been deployed.

  • Snyk Acquires Helios to Extend Reach of ASPM Platform

    Snyk Acquires Helios to Extend Reach of ASPM Platform

    With its acquisition of Helios, Snyk plans to add an ability to capture application runtime data to extend the capabilities of its application security posture management (ASPM) platform.

    Manoj Nair, chief product officer for Snyk, said Snyk AppRisk will soon provide real-time insights into runtime environments using a Helios observability platform that provides them with deeper insights into issues that need to be resolved. That capability will provide developers with additional context as more responsibility for application security continues to shift left toward application development teams, he added.

    Armed with that insight, it then becomes simpler to prioritize remediation efforts based on the level of risk a vulnerability actually represents to the organization, said Nair. That’s critical to close a longstanding divide between cybersecurity and application development teams that, in the absence of any real ability to determine the severity of a vulnerability, results in developers wasting what limited time they have to allocate to remediation, he noted.

    Nair said the overall goal is to enable organizations to deploy more secure applications while minimizing adverse impacts on developer productivity.

    Snyk last year acquired Enso Security to add an ASPM platform to its portfolio that serves as the foundation upon which Snyk AppRisk was built. It also includes Insights, a Snyk tool that makes use of multiple types of artificial intelligence (AI) models to identify, prioritize and fix vulnerabilities.

    There’s often not a lot of love lost between cybersecurity teams and application developers who typically don’t have a lot of cybersecurity expertise. Most of the issues that cybersecurity teams are tasked to address start with mistakes made by developers that cybersecurity teams then need to convince developers to allocate time to fix.

    Thanks to the rise of DevSecOps best practices, the overall security of software supply chains is improving, but there is still a long way to go before application security truly improves. The one thing that is certain is the level of accountability for vulnerabilities is only going to rise as more stringent regulations go into effect in the months and years ahead.

    In the meantime, DevSecOps teams should assume there will be many more vulnerabilities to remediate. Developers are increasingly using generative AI tools to write code. The challenge is general-purpose large language models (LLMs), such as the one used to drive ChatGPT, were trained using examples of code of varying quality collected from across the web. A lot of the code these platforms generate, not surprisingly, contains vulnerabilities that many developers will not immediately recognize without the aid of some type of scanning tool.

    At the same time, cybercriminals are becoming more efficient at discovering and exploiting vulnerabilities that exist in applications that have already been deployed in production environments. DevSecOps teams should expect that, as a result, more zero-day vulnerabilities requiring immediate attention will soon be discovered.

    One way or another, the percentage of time allocated to application security issues is only going to increase. The only thing left to determine is how best to go about reducing the time and effort needed to make applications as secure as possible.