Category: DevOps Practice

  • 7 Principles for Using Microservices to Build an API That Lasts

    7 Principles for Using Microservices to Build an API That Lasts


    SparkPost launched the first beta version of our cloud-based email delivery service three years ago. At its introduction, a handful of customers sent a few million emails a month. Now, our API is used by tens of thousands of customers—including Pinterest, Zillow, and Intercom—to send more than 15 billion emails a month. That dramatic growth demonstrates how rapidly our business pivoted from providing on-premises email infrastructure to operating as a fully cloud-based email delivery service.

    It’s a great business story. But how did we manage change at that scale with regard to technology and development management? In this article, I’ll review several of the choices and best practices that have helped us to not simply manage this pace of change, but actually to thrive from it.

    REST Is Best: Be Practical, Not Pedantic

    From the start, we took an “API first” approach. Our email API is our core application, not an afterthought.

    The first, and most important, step we took was deciding to use REST for our API. Our philosophy was to choose the following three elements as our API’s foundation:

    1. HTTP: This covers response codes as well as operators. The operators include POST, GET, PUT and DELETE, and they can be mapped to the basic CRUD (create, read, update, delete) operations.
    2. Resources: These are the entities that the HTTP operators act on.
    3. JSON (JavaScript Object Notation): This is a data-interchange format.

    Those three elements provide everything needed for a practical REST API, including simplicity, portability, interoperability and modifiability. After the API is built, users can easily integrate against it regardless of their programming language, including C#, PHP, Node.js, Java or even cURL in a shell. They can do so without worrying about the underlying technology, including its use of multiple microservices.

    When we created the SparkPost API, we tried not to be too pedantic about following a pure REST model, opting for ease of use instead. Here are two examples that may not follow RESTful best practices:

    1. GET /api/v1/account?include=usage
    2. POST/api/v1/sending-domains/example.domain.com/verify

    The first example uses a query string parameters for GET to filter what comes back in an entity. In the second example, we use the action word “verify” in the endpoint name, which may not be RESTful. We discuss each new use case and do our best to ensure it’s consistent and easy to use.


    Related Content:

    APIs: Automation is Great. So is Usability

    Tips to Optimize the Cloud for Scaling


    Evolving and Managing Change

    We have many developers and teams working on our API’s microservices, with changes delivered on a continuous basis. We automate deployment of a change to production when an engineer (and a second) concludes it has passed our tests. It’s “released” when the product team decides we’re ready to tell customers about the change.

    We decided early on to keep our API consistent in its use of conventions and how changes are managed. We established a governance group that includes engineers representing each team, a member of the product management group, and our CTO. This group establishes and enforces our API conventions, which are thoroughly documented.

    Documenting our conventions reduces inconsistencies and makes it easier to define each new endpoint. Here are a few conventions we’ve established:

    • URL paths are lowercase with hyphens when separating words, and are case sensitive.
    • URL query parameters and JSON fields are also lowercase with underscores, and are case sensitive.
    • Unexpected query parameters and JSON fields in the request body should be ignored.

    Our governance group also sets the ground rules for how changes can be made and what types of changes are allowed. There are a number of good API changes that are beneficial to users and don’t break their integrations, including:

    • A new API resource, endpoint, or operation on an existing resource
    • A new optional parameter or JSON key
    • A new key returned in the JSON response body

    Conversely, a breaking change includes anything that could break a user’s integration, such as:

    • Changing a field’s data type
    • A new required parameter or JSON Key
    • Removal of an existing endpoint or request method
    • A materially different behavior of an existing resource method, such as changing the default for an option from “false” to “true”

    Those kinds of changes will either break users’ integrations or require the addition of a new version, which introduces more overhead.

    Don’t Break Bad When Making Changes – Nearly All the Time

    Breaking changes should be avoided, even if they’re the result of fixing bugs or inconsistencies. It’s usually better to work around such idiosyncrasies rather than risk breaking customers’ integrations. If a change is of the breaking variety, we proceed with extreme caution and seek out alternative ways to achieve our goal. Sometimes that can be accomplished by simply allowing the user to change their behavior through an account setting or an API parameter.

    However, there are times when the benefits to our users outweigh any potential negatives that would be introduced by a change. In those cases, though, we followed these best practices:

    • We received buy-in from our product, support and developer relations teams.
    • We analyzed API logs to see how many users the change might affect.
    • We gave users at least 30 to 60 days of advance warning about the change.
    • We sent an email or published a blog post containing explicit details of the change and why we were making it.
    • We provided guidance in the API documentation.

    One Version to Rule Them All

    After making thousands of changes to our API during the past three years, we’re still on the first version. We decided early on not to version our API beyond the first one because doing so adds a level of unnecessary complexity that can slow down user adoption of our latest and greatest functionality. Versioning an API can also slow down development and testing, complicate monitoring and confuse user documentation.

    In addition, not versioning our API means we can avoid the controversy that tends to swirl around the subject. There are three ways to version an API, and all of them come with potential pitfalls:

    • Put the version in the URL: Easy to do but a bad choice from a semantic perspective because the entity doesn’t change between v1 and v2.
    • Add a custom header: Also easy to do but not semantically correct.
    • Put the version in the accept header: More semantically correct but the most complicated approach.

    Use Client Libraries to Help Non-JavaScript Users

    Some of our users prefer Python, C#, Java or PHP over JavaScript. We make it quick and easy for them to integrate our API into their applications by maintaining client libraries that offer an easy-to-use set of functions for their code.

    Our client libraries have changed over time, and we do version them. We’ve learned that abstraction is hard when wrapping a living, growing API, so we focus on providing a thin layer of abstraction with some syntactic shortcuts that simplify the more complex areas of our API. Doing so lets our users quickly hit any of our API endpoints quickly and with a lot of flexibility—it also lets us “future proof” our API to some extent.

    A ‘Documentation First’ Strategy, Too

    We treat our documentation as code and use it to document our API changes before we write or change a single line of API code. Doing so helps us enforce our conventions, keeps everything consistent and maintains a good customer experience. It also cuts down on support costs.

    We maintain our documentation in GitHub, which makes it easy for technical and non-technical users to contribute changes. We’ve also found that it’s easier to review changes that way. We use API Blueprint Markdown format and Jekyll to generate the HTML docs, along with a nice search service called Algolia. Doing so lets us have full control over the customer experience, including mobile.

    For those who don’t want to “roll their own” documentation, we recommend OpenAPI (previously known as Swagger), Apiary and API Blueprint. It’s important to avoid a tool that isn’t well-suited for REST API documentation. We suggest including a bright orange “Run in Postman” button in the documentation so it’s easy to try an API, along with good examples of success and failure scenarios.

    Listen to Users

    Finally, we recommend that all developers pay attention to what their users have to say. SparkPost has a community Slack channel where thousands of users can easily access members of our product, support, engineering and executive management teams. We also have a dedicated Developer Relations team that’s squarely focused on engaging with the developer community. All of that allows us to listen to our users and incorporate their feedback into our API.

    — Chris McFadden

  • CloudBees Acquires Codeship to Extend CI/CD Reach

    CloudBees Acquires Codeship to Extend CI/CD Reach

    CloudBees today signaled its DevOps ambitions to extend well beyond the Jenkins continuous integration/continuous deployment (CI/CD) platform by acquiring Codeship, a provider of a CI/CD platform that is delivered as a software-as-a-service (SaaS) application.

    The decision to acquire Codeship is being driven by the need to engage smaller DevOps teams that don’t have the time or expertise required to set up on-premises instances of Jenkins, said CloudBees CEO Sacha Labourey.

    Codeship today is being used by more than 100,000 developers spanning 2,400 customers. Many of those developers are working at smaller companies. But Labourey noted that small teams of developers inside larger companies also prefer to invoke a CI/CD platform as a service.

    “Different teams will decide to do different things in the same organization,” said Labourey.

    The Codeship platform is not based on Jenkins and there is no plan to rehost the Codeship service on Jenkins, says Laborey. Jenkins is designed to be highly customizable by the organization that employs it. The Codeship service is a highly opinionated instance of multitenant CI/CD platform that is designed to provide a turnkey experience capable of support lots of developers at once, explained Labourey.

    CloudBees will explore ways to bundle its core platform with the Codeship service for organizations that find themselves needing to deploy both a CI/CD platform on-premises in addition to a cloud service, he added.

    The acquisition of Codeship signals a wave of coming consolidation across the DevOps sector, Labourey said, predicting that over time, a much smaller number of companies will account for most of the DevOps software and services sold. Some will rise from the ranks of the pioneers of DevOps. Others will be the same companies that today dominate application lifecycle management (ALM) and software development lifecycle (SDLC) software in the enterprise. As DevOps continues to gain momentum in the enterprise, it’s now only a matter of time before legacy ALM and SDLC vendors are forced to modernize their portfolios by making acquisitions or partnering with companies such as CloudBees, he said.

    It’s too early to speculate how that consolidation might play out. But it’s clear the rise of microservices is about to force the DevOps issue in many enterprises. The rate at which DevOps processes have been adopted across enterprise has been uneven, but as organizations embrace microservices to build better applications faster, many will need to re-engineer their application development processes. There always will be monolithic enterprise applications that may be better-served by waterfall approaches to application development, but in time, the bulk of applications will be built employing microservices architectures that make it easier to update and manage applications employing modern DevOps best practices.

    How much those DevOps processes will be based on CI/CD platforms running in the cloud or on-premises is anybody’s guess. More than likely, most organizations will rely on a combination of both, depending on the size and scope of their efforts. Regardless of the approach, however, at a time when every company is becoming more aware of their dependency on software to compete, it will be those organizations that embrace DevOps processes best that will prosper at the expense of rivals.

    — Mike Vizard

  • IBM CTO Sees Bright Future for Java in 2018

    IBM CTO Sees Bright Future for Java in 2018

    Significant advances in microservices written in Java, as well as tighter coupling between Java applications and containers, are set to transform the way most organizations build and deploy Java applications by the end of the year.

    IBM Java CTO John Duimovich, as part of five Java predictions for 2018, noted that The Eclipse Foundation has taken over the development of MicroProfiles, a baseline platform definition that optimizes Enterprise Java for a microservices architectures, and the EE4J project, an effort to create standard application programming interfaces (API) for Java runtime. This, he said, will make it much easier to build next-generation Java applications using programming tools based on the Eclipse integrated development environment (IDE).

    In some instances, those applications will take the form of a microservice that gets deployed using a Java runtime. In other instances, those applications will be deployed using containers such as Docker. Duimovich said it’s not only a matter of time before containers and runtimes including Java will become more tightly coupled. That will result in more consistent memory management and easier wiring between Java constructs and containers. For example, Java applications will be able to determine automatically how much memory is available to any given container. That’s critical because the reason most containers fail is they exceed available memory limits, he said.

    Duimovich also predicted that Kotlin will be the next big variant of Java to be adopted in the enterprise. Concise coding syntax plus interoperability with other instances of Java have already made it popular for many developers. Now that Kotlin can be used to build applications for devices running Android, this year will see much broader usage of Kotlin to build greenfield applications, Duimovich said. However, he added, it won’t be too long before other variants of Java start employing similar concepts.


    Related Content:

    Hopes and Fails in DevOps 2017

    DevOps Chat: Microservices & Containers – Mastering the Replatforming of the IT Infrastructure


    Other major Java predictions for 2018, Duimovich noted, will be optimization of Java runtimes for serverless computing frameworks and a more regular six-month release cycle for incorporating new functions in Java. The rise of serverless computing frameworks will also result in more Java applications being deployed on public and private cloud services, he said.

    Duimovich noted that, from a practical perspective, a Java runtime is simply another type of container. The challenge facing DevOps teams will be determining when and where to use Docker containers instead of traditional Java runtime to deliver an application. Whatever the outcome, it’s unlikely any IT organization will standardize on one approach to the exclusion of all others.

    The increased rate of Java innovation can be attributed to an Oracle decision made last fall to place Java Enterprise Edition under the auspices of the Eclipse Foundation, said Duimovich. At the same time, IBM moved to open-source its implementation of a Java virtual machine. This has resulted in something of a Java Renaissance, as more developers and organizations are contributing expertise via the Eclipse Foundation.

    There’s no shortage of programming language options available these days. But in many cases, if Java is able to build modern applications, then it’s probable many developers will continue to use Java rather than take the time to learn something new.

    — Mike Vizard

  • The Developer Playbook: 5 Ways We’re Just Like Football Players

    The Developer Playbook: 5 Ways We’re Just Like Football Players

    — Jeff Veis

  • Dev vs. Ops Needs for Large-Scale Version Control Systems

    Dev vs. Ops Needs for Large-Scale Version Control Systems

    Distributed version control systems (DVCS) such as Git (introduced in 2005 by Linus Torvalds, the creator of Linux) rapidly gained worldwide acceptance by the global software development community. DVCS offer very fast, lightweight and local software change control capabilities that support many parallel code branches across large project code bases. These are compelling benefits for individual developers and development teams. At their heart, DVCS accomplish this by tracking software changes as a series of file system snapshots in local repositories instead of via management of individual file changes in a central database. “A Short History of Git” explains this in more detail.

    The DVCS approach is ideal for individuals and small agile teams because it puts control directly in their hands without the need to transact all file changes with burdensome systems that were designed using a central management paradigm.
    However, the distributed approach taken by DVCS has historically presented challenges for operations, especially when large-scale enterprise software systems consisting of components from many separate repositories need to be managed and controlled. Enterprises with many developers, large source or binary files (e.g. graphics, audio or video), many artifacts or many large containers need granular end-to-end version traceability. Enterprise-class support requirements exceed the original design intentions of DVCS.

    End-to-end software version management offerings that on one hand leverage efficiencies of distributed systems for developers yet still support scalable operations are required to address the needs of Dev and Ops communities in enterprises with large software version management needs. These complementary requirements have driven the evolution and best practices of large-scale hybrid version control systems:

    • Simplify builds and manage complex projects by organizing multiple repositories
    • Move code and build assets into the DevOps pipeline quickly
    • Improve performance for remote sites by using a central system as a proxy/cache
    • Speed up many activities at the system level, such as cloning and copying code
    • Implement a seamless workflow that incorporates assets such as large graphics and binaries, in addition to source code

    Related Content:

    35+ Tools Every DevOps Expert Must Know

    Automation: Achieving Faster Rollouts with Better Accuracy


    As stated, historically, these were problems that could only be addressed by a centralized version control offering. DVCS alone simply couldn’t handle the large-scale continuous integration (CI) and operations requirements of large-scale software development communities. While there are still inherent issues in the way DVCS manages large binary assets, select vendors have begun to tackle the problem by mirroring DVCS repos in real time, which marries the developers’ need for easy branching and local control with the operations team’s needs for faster and more efficient builds.

    For enterprises developing complex software incorporating both binary and text-based assets, large-scale enterprise hybrid version control systems with supporting both distributed and centralized structures offer a best practice solution. They provide capabilities for a global single source of truth, replication of all types of artifacts and manage versions of everything from planning to release. By resolving operational management problems resulting from sprawl of individual Git repositories, while at the same time preserving benefits of distributed systems, today’s enterprise-class centralized and/or hybrid version control systems can meet the needs of both Dev and Ops without sacrificing efficiency or operations control.

    Summary

    What do you think? Do you agree that the benefits of hybrid versions control systems listed above are important to achieving large-scale version control? Are there other solutions you recommend?

    — Marc Hornbeek

  • Red Hat Rises to Data Management Challenges

    Red Hat Rises to Data Management Challenges

    Red Hat is moving to reduce or eliminate many of the manual tasks DevOps teams routinely encounter via a beta release of an update to Red Hat Enterprise Linux (RHEL) that addresses multiple data management issues related to DevSecOps and DataOps.

    Steve Almy, principal product manager for RHEL, said version 7.5 of RHEL adds support for integration between the Ansible IT automation framework that Red Hat now bundles in the RHEL operating system and OpenSCAP, a security auditing tool originally developed by the National Institute of Standards and Technology (NIST). OpenSCAP provides IT administrators with a baseline of security settings to compare with the current state of their Linux deployment. They then can invoke the declarative Ansible framework to automatically resolve any of those issues raised by the OpenSCAP audit, said Almy.

    In a similar vein, Red Hat is also making it easier to securely unlock Network Bound Disk Encrypted devices at boot-time while adding time-stamping and synchronization needs with the addition of failover with bonding interfaces for Precision Time Protocol (PTP) and Network Time Protocol (NTP).

    Additionally, to reduce data management headaches, Red Hat is now embedding support for data deduplication and compression software based on technology it gained by acquiring Permabit last year. The goal is to enable IT organizations to perform those tasks on data running on the server before it is ever stored on a disk, said Alby. In many cases, that may eliminate the need to acquire, deploy and manage separate data deduplication and compression software for the storage system. That approach also serves to indirectly benefit DataOps, an emerging discipline through which many organizations are trying to modernize the management of data and the pipelines employed to feed that data into applications.

    Other additional management capabilities being added to RHEL 7.5 include an easier-to-use cockpit administrator console for managing storage, networking, containers and other services, and a “known-good” bootable snapshot to help speed recovery and rollback after patching software.

    Almy said Red Hat is focusing more on eliminating much of the friction that gets in the way of enabling IT administrators to accomplish more tasks in a specific amount of time. The goal is not to eliminate the need for IT administrators, but rather to eliminate tasks that conspire to make managing IT more time-consuming than it need be. Much of that Red Hat strategy is anchored around an Ansible automation framework that doesn’t require IT administrators to know how to program to automate the management of underlying IT environment.

    It’s not clear just how much ease of data management impacts IT decisions. All things being relatively equal, however, IT administrators in the agile programming age are trying to manage more workloads than ever. Most organizations are not adding additional IT operations staff mainly because it’s hard to find and retain them. That means make sure existing IT administrators are more efficient than ever by embracing IT automation whenever and wherever possible to streamline DevOps processes.

    — Mike Vizard

  • Focusing on the Real Value of AI for IT Ops

    Focusing on the Real Value of AI for IT Ops

    In all the hype over AI, let’s concentrate on the real value it can provide, especially for busy IT Ops teams.

    2018 is already shaping up to be the year when AI and machine learning (ML) go mainstream—at least in terms of public awareness, if not yet of actual usable products. As I write this, the annual CES event—the show that is, Prince-style, “formerly known as “The International Consumer Electronics Show—is in full swing. The usual suspects are out in force, with Amazon’s Alexa getting embedded in more and more products and Google also showcasing its own consumer AI capabilities.

    More unexpected AI adopters included Ferrari, but there were also some notable failed demos, with an AI-enabled suitcase repeatedly running away from its owner or AI refusing to answer questions during an on-stage demo. All of this led the BBC to question, “When will AI deliver for humans?”

    What Happens in Vegas, Stays in Vegas

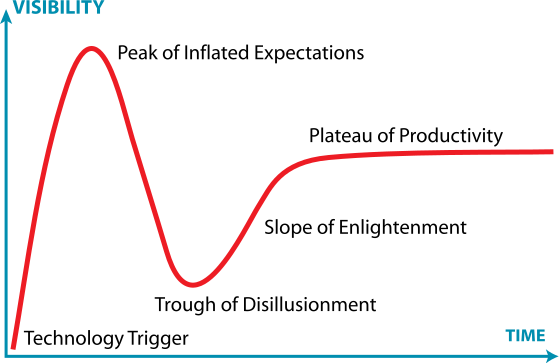
    Of course, much of what comes out of CES is frivolous, but there are all sorts of other applications of AI and ML. The problem is that whenever there is this much hype, disappointment and disillusionment are not far behind. Gartner’s famous Hype Cycle model can help here.

    Gartner Hype Cycle - from Technology Trigger, via Peak of Inflated Expectations, through Trough of Disillusionment, up Slope of Enlightenment, to Plateau of Productivity.
    By Jeremykemp at Wikipedia, CC BY-SA 3.0

    The conventional concern is that overly optimistic projects initiated at the Peak of Inflated Expectations risk failing, leading to excessive caution and fewer projects starting during the Trough of Disillusionment, before a more realistic understanding sets in and the technology achieves true mainstream adoption. Due to the nature of AI and ML, though, there is a second failure mode that is far more insidious.

    AI and ML generally operates as a black box. Results are provided, very quickly and without the need to develop deterministic rules, but it is generally not possible to determine why a specific result was generated or troubleshoot failures in detail. As these techniques are used in the real world, potential problems that might not have been obvious in the lab begin to appear. If your smart fridge misreads the expiry date on that chicken (and you don’t think to check yourself), you might be in for an uncomfortable few hours. If your smart thermostat decides for some reason that your house should be as hot as physically possible, you’re still on the hook for the heating bill.

    Those are the “nice” failure modes. If a facial recognition algorithm was trained on a data set that didn’t have the right racial balance, you might wind up with some of your employees not being able to get in the door, or some of your customers not being able to unlock your device, or whatever.

    It gets worse. Law enforcement has an obvious interest in facial recognition—but what if a faulty system places you at the scene of a riot? https://www.liberty-human-rights.org.uk/news/blog/misidentification-and-improvised-rules-we-lift-lid-mets-notting-hill-facial-recognition Even if you can prove your innocence, you might still have to deal with some difficult conversations with your family and your employer, and your neighbours may never forget the time you were hauled off in handcuffs.

    Don’t Throw The AI Baby Out With The Hype Bathwater

    So should we just forget about this AI nonsense? Far from it. In fact, I am personally convinced that AI is very much a key part of our future. It just needs to be used in the right way.

    I mentioned training data above, and that is the key. AI systems need a lot of good data, and they need to be trained to make good assessments. Out there in the real world, both sides of that problem are actually very hard. Gathering enough data, making sure that the data gathered are actually representative of the problem space, dealing with privacy issues around personally-identifiable information, and formatting the data correctly for ingestion by your machine learning system are already not trivial issues. However, even assuming that you have successfully dealt with that hurdle, the initial results will not be very good or reliable. Intelligent assessment by humans who understand the domain that you are training for is key if your deep learning model is not to go off the rails.


    Come Up to the IT Ops Lab

    Seen in these terms, IT Ops is an ideal domain to which to apply these techniques. First of all, IT infrastructure already generates huge amounts of event data – Big Data, if you insist – and all of those events are already, by definition, formatted to be easily machine-readable. Sure, there are many different formats out there, from SNMP, via various proprietary product-specific formats, to modern REST APIs, but it turns out that computers are pretty good at translating information from one representation to another.

    Once the event data are in the AI system, it can apply whatever algorithms to try to make sense of them: which events are even significant, which ones are related to each other, what other relationships might exist, and so on. When it comes to evaluating the results, again, IT Ops already has people, tools and processes working on precisely that question: is this a real issue, and if so, what to do about it — or if not, why not. This evaluation can be fed back to the learning system to improve its results for next time, iterating over time to provide ever more valuable and reliable results.

    This learning can even be applied to the evaluation process itself, watching what users find most interesting and valuable, and extrapolating from that to present the most significant data first, or looking for patterns in human interaction to assemble the most effective teams to work on particular types of incident.

    This is what AIOps is all about. Don’t assume that the sort of consumer-grade AI that you see at CES is all that is going on in this field. AI has huge potential to help streamline enterprise IT Ops, by presenting human specialists with actionable events, helping them collaborate more effectively, and learning and improving over time.

    Once the CES hype has died down, take a good look at AIOps and start to think how it can fit into your plans for 2018.

    — Dominic Wellington

  • The Origins of DevOps: What’s in a Name?

    The Origins of DevOps: What’s in a Name?

    Depending on your frame of reference, DevOps will celebrate it’s ninth or 10th anniversary this year. In 2016, RightScale’s “State of the Cloud Report” estimated that 70 percent of SMBs were adopting DevOps methods. Every indication is that percentage has increased since then. As DevOps prepares for its second decade of existence, it might be worth a stroll down memory lane to revisit the origins of DevOps methods—and even the term itself.

    Pre-2007: A Perfect Storm of Events

    Prior to 2007, a series of circumstances came together that would eventually give birth to what we know today as DevOps.

    “Lean manufacturing” was already well-established as a set of best practices for manufacturing. Often branded as the “Toyota Manufacturing Method,” lean manufacturing strives for process optimization across the manufacturing floor. (Sidebar: Toyota leaders were originally inspired by the ingenious assembly line methods introduced by Ford Motor Company.) “Continuous improvement” is the mantra for lean manufacturing and practitioners continually evaluate ways to:

    • Keep inventory at a minimum. Lean manufacturing means minimal inventory on hand: raw materials (materials used to produce goods) and finished inventory (completed products waiting to be assigned to an order and/or shipped).
    • Minimize the queue of orders. Ideally, orders received should move immediately into fulfillment mode. A key metric of lean manufacturing will always be “order to ship” time.
    • Maximize efficiency in the manufacturing process. Process re-engineering and improved automation will marry into a goal to produce goods as quickly as possible. Each station of operation along the way (cut, weld, assemble, test, etc.) is evaluated for inefficiencies.

    In IT, traditional waterfall methods of application development were already giving way to rapid, iterative methods such as agile. “Speed” was the battle cry, even if quality output was occasionally compromised in the pursuit of rapid development and deployment. Similarly, on the operations and infrastructure side of IT, Cloud Computing and, in particular, infrastructure as a service (IaaS) and platform as a service (PaaS) were coming into their own as mature service offerings.

    Finally, a fledgling set of tools classified as “continuous integration (CI)” tools began to emerge. The notion of CI tools was birthed and branded by Grady Brooch back in 1991 in his Brooch Method.


    Related Content:

    DevOps: The Innovation Power Couple

    A Definition of DevOps for the Masses


    2007-2008: A Frustrated Belgian

    Belgian consultant, project manager and agile practitioner Patrick Debois took on an assignment with a Belgian government ministry to help with data center migrations. In particular, his role was in certification/readiness testing. His duties required him to straddle activities and relationships between the application development teams and the operations teams (server, database network). His experiences—and frustrations over the walls of separation and lack of cohesion between application methods and infrastructure methods—planted seeds of discontent for Debois. His desire for a better way would soon lead him to action.

    In 2008, at the Agile Conference in Toronto, Andrew Schafer posted an offer to moderate an ad hoc “Birds of a Feather” meeting to discuss the topic of “Agile Infrastructure.” Only one person showed up to discuss the topic: Patrick Debois. Their discussions and sharing of ideas with others advanced the concept of “agile systems administration.” In that same year, Debois and Shafer formed an Agile Systems Administrator group on Google, with limited success.

    2009: The Case for Dev and Ops Cooperation

    At the O’Reilly Velocity Conference, two Flickr employees—John Allspaw, senior vice president of technical operations, and Paul Hammond, director of engineering—gave a now-famous presentation titled, “10+ Deploys per Day: Dev and Ops Cooperation at Flickr.” The presentation had a dramatic flair to it, as Allspaw and Hammond would role-play the contentious interplay between representatives of  Development and Operations during a typical software deployment, along with all the finger-pointing/blame that goes on, such as, “It’s not my code, it’s your machines!” Their presentation made the case that the only rational way forward is for application development and operations activities to be seamless, transparent and fully integrated. Over time, this presentation has reached legendary status, and is historically viewed as the seminal moment in time for that called out to the IT industry for methods that we now know as DevOps.

    Unable to attend in person, Debois watched the Allspaw/Hammond presentation by video stream. He was inspired, and—at the prompting of others through social media—formed his own conference called Devopsdays in Ghent, Belgium. By this point in time, the term “DevOps” had officially landed in the history books.

    2010: DevOps in the United States

    With a growing constituency, a Devopsdays conference is held for the first time in the United States in Mountain View, California, on the heels of the Velocity annual conference. Fast forward to 2018: There are more than 30 Devopsdays conferences already scheduled for 2018, including dozens across the United States.

    2013: ‘The Phoenix Project’

    For many of us, another noteworthy moment in the history of DevOps was the publishing of the book, “The Phoenix Project,” written by Gene Kim, Kevin Behr and George Spafford. This fictional novel tells the story of an IT manager thrust into a seemingly hopeless situation, as he’s charged with salvaging a mission-critical ecommerce development project that’s gone off the rails. His mysterious mentor, a board member steeped in the disciplines of lean manufacturing, guides the main character into new ways of thinking about IT and application development, introducing the concept of DevOps along the way.

    (Sidebar: The Phoenix Project helped inspire us to write “Outsource or Else!” a similar business fable in which a VP of Software uses DevOps when outsourcing development of a major new product.)

    DevOps for the Future

    It’s reasonable to describe DevOps as a journey, or perhaps an aspiration, rather than defined destination. DevOps, like lean manufacturing, seeks continuous improvement, seeking higher output, greater efficiencies and even continuous deployment. Automated tools that support DevOps continue to evolve.

    Much has been accomplished since the inception of DevOps in the last decade and we expect to see even more in 2018 and beyond.

    — Steve Mezak

  • CA Technologies Survey Uncovers DevSecOps Challenges

    CA Technologies Survey Uncovers DevSecOps Challenges

    When it comes to infusing security concerns into a DevOps culture, most organization still have a very long way to go. A global survey of 1,279 IT leaders conducted by the market research firm Freedom Dynamics on behalf of CA Technologies finds more than half of respondents (58 percent) cited existing culture and lack of skills as hurdles to being able to embed security testing and evaluation within software development processes. Only 24 percent strongly agreed that their organization’s culture and practices supported collaboration across development, operations and security.

    More challenging still, less than a quarter of respondents strongly agreed that senior management would sacrifice time to market to make sure there is sufficient time to assess and repair software security vulnerabilities.

    Chris Wysopal, CTO for the Veracode portfolio of security testing tools CA Technologies acquired last year, said the survey results make it clear many organizations are still wrestling with the concept of DevSecOps. Many of them may be far along the path to building a culture around DevOps, but more often than not, security teams haven’t been included in those processes, says Wysopal.

    Because security teams are not included, many organizations wind up incurring substantial costs by having to address a much broader number of security updates to applications running in production environments. Organizations that have shifted security to the left as part of more comprehensive approach to DevSecOps discover and eliminate many more security issues during the development process.

    Wysopal said the survey bears out those conclusions. The survey finds the top 34 percent of respondents who report their organizations have been able to fully integrate security into their software development life cycles view security as an enabler of new business opportunities. These organizations typically exhibited 50 percent higher profit growth and 40 percent higher revenue growth. They are also 2.6 times more likely to have security testing keep up with frequent application updates. Wysopal conceded there’s no direct correlation between better security and better overall corporate performance. But at the very least, the results indicate that organizations that invest more time in DevSecOps are not adversely impacting financial performance.

    Organizations that embrace DevSecOps not only ship higher-quality software that reduces total cost of application ownership, they also typically are in a much better position to absorb the application update impact of unexpected security events such as Spectre and Meltdown flaws being discovered in processors. Because of the need to patch these flaws, most application update processes are now being stressed across the entire IT industry.

    It remains to be seen what impact the need to quickly address these flaws will have on adoption of DevSecOps. Wysopal noted the old way of addressing security issues during a waterfall-based approach to application development simply don’t work in the age of agile development. IT security teams now need to work hand in glove with application developers. The challenge now, Wysopal said, is getting the leaders of those organizations to come to terms with the impact that change may have on the pace at which software is developed. But given the critical role software now plays in critical business processes, organizations soon will come to appreciate the need to better balance the speed of application development speed against all the potential risks involved.

    — Mike Vizard

  • How to Isolate Development Environments: Vagrant vs. Docker

    How to Isolate Development Environments: Vagrant vs. Docker

    “It works on my machine.” This line has become an excuse often overused by developers to escape the burden of having to investigate problems experienced by end users that they are unable to replicate on their development machines. While this may excuse developers—after all, they didn’t experience the problem during development and therefore couldn’t have anticipated it happening to some users—it doesn’t solve the problem.

    Sometimes, issues are caused by end user mistakes, such as skipping a step in an installation process. Often, however, the problem arises from some disparity in the development and server or user environments. With the vast assortment of machine configurations in use—different operating systems, hardware specifications and software versions—even the slightest differences in development and production device configurations can cause dramatic differences in the behavior of many applications.

    This can be a serious issue, as it requires members of the development and operations team to identify the root cause of the problem, which potentially introduces unexpected and often significant delays in deployment and production schedules. Especially in the DevOps culture where rapid development, frequent deployment and highly dependable releases are of highest priority, such unexpected delays are completely unwelcome.

    Thankfully, there are a number of tools that have emerged to address this very problem. In this article, we take a close look at two popular tools with two different approaches to solving the problem of environment disparity: Vagrant and Docker. Like many DevOps tools and technologies such as continuous integration, these tools work well with all types of project setups, including IT outstaffing (dedicated development teams). Let’s compare these two solutions and see which types of scenarios each one is best fit for.

    Vagrant vs. Docker

    Vagrant offers to solve the aforementioned problem by enabling developers to easily create and manage virtual machines (VMs) in which they can develop, test and deploy applications. By using a VM, a developer or DevOps engineer is assured that as long as the application is run within the virtual machine, its behavior will be the same regardless of the actual hardware and operating system of the computer that the VM is running on.

    Docker offers a similar solution, but uses a different technology. Instead of using virtual machines, it uses containers, which are similar to Linux Containers (LXC) that are included in Linux systems. Containers serve a similar purpose as virtual machines, but at a much less extensive level and, therefore, are much more lightweight. Rather than isolating an application in its own virtual computer with a full operating system, containers simply isolate an application inside an environment with the minimum components necessary to run the application. This includes system libraries and tools, settings and configuration files and a runtime environment. Compared to virtual machines, containers consume much less resources from the actual machine on which it is being hosted. Docker has a comprehensive documentation library that includes information on what Docker and Docker containers are, how to install Docker and how to execute a Docker run.

    Vagrant and Docker share some common goals. For instance, in software development, both tools enable a more streamlined and consistent software development and deployment workflow by eliminating the need to worry about the application behaving differently in different machines. Moreover, it offers some degree of security to the host machine: Since the application is isolated from the rest of the system, issues caused by one application should remain within the scope of its environment and should not break the rest of the system.

    There are, however, a number of important differences between Vagrant and Docker that make them suitable for different types of applications. Let’s examine more closely how these two differ.

    Scope of Isolation

    While both Vagrant and Docker wrap applications into isolated environments, they differ in the degree to which these applications are isolated—or, effectively, the scope of the isolated environments. For Vagrant, the scope is the entire operating system: An application can access any and all components of the full virtualized machine and operating system it is being run in. For Docker, on the other hand, the scope is much narrower, as an isolated environment is limited to a single application or service: Each container is created specifically for an application. Effectively, this implies that with Vagrant, a single isolated environment can run multiple applications at once, while with Docker, running multiple applications will typically require the use of a separate isolated environment for each one.

    Resource Consumption

    Since Vagrant virtualizes an entire machine with a full operating system, it naturally has a high overhead cost and consumes a lot of resources from the host machine. With Docker, on the other hand, an app within a container shares the same kernel—the core module or component of an operating system—with both apps in other containers and the host machine itself. This enables containers to have much less overhead and subsequently consume much less resources from the host machines than do virtual machines. In effect, a host machine running apps with containers can run up to three times as many applications as it can with virtual machines. Moreover, since launching apps within containers won’t necessitate having to wait for the virtual OS to boot up, launching apps can also be substantially faster with Docker than it is with Vagrant.

    Limitations

    Vagrant and Docker also have their own limitations. Docker, for instance, is currently natively available to two operating systems: Linux, where it uses the Linux Kernel, and Windows, where it uses the Windows kernel. Docker is also available for MacOS, although it runs Docker containers on top of a Linux virtual machine. Moreover, Docker has some security issues—its use of containers make it less secure than Vagrant. Since applications within Docker containers share the same kernel with each other and with the host machine, it’s possible for a malicious program within a Docker container to affect other containers and even harm the host machine itself.

    While Vagrant, which uses virtual environments, is much more secure in this regard, it is limited in that it is meant only as a tool for development and generally not recommended for use in production environments. In other words, it is meant to provide a convenient way to virtualize the environment of the server to which an application is eventually going to be deployed, but once in production, the application must be run directly on the host machine. On the other hand, Docker provides a consistent environment for applications throughout the entire software development workflow, from creation to production.

    Conclusion

    Being able to isolate applications into their own controlled environments has proven to be extremely useful for software development, as it eliminates many hardware and software incompatibility problems that applications may run into when executed in different machines. This is particularly useful in DevOps environments, as it streamlines the whole software development workflow by eliminating sources of unexpected problems, thereby potentially shortening development cycles.

    We have looked into two popular tools for environment isolation, Vagrant and Docker. Both isolate applications from the host machine, although to varying degrees and using different technologies. Vagrant uses virtual machines, which can support multiple applications at once, but can be heavy on resource consumption and is only recommended for use during development. Docker, on the other hand, uses containers, which support only single applications, but is much lighter in terms of resource consumption and can be used both during development and during production.

    As such, these two tools cater to different business needs. If you require the development of a complex system of multiple applications interacting with each other, using Vagrant may be beneficial, but if you’re aiming to create a single portable application and want to minimize resource consumption, then Docker is the way to go.

    — Myron Monets