Category: DevOps Practice

  • Dynatrace Survey Sees Continuous Delivery Challenges Ahead

    Dynatrace Survey Sees Continuous Delivery Challenges Ahead

    A global survey of 1,300 application development and DevOps leaders conducted by the research firm Coleman Parkes on behalf of Dynatrace finds, on average, organizations expect to increase the frequency of their software releases by 58% over the next two years.

    Andreas Grabner, director of strategic partnerships at Dynatrace, an observability platform provider, said that while it’s clear organizations are embracing DevOps best practices to achieve that goal, the survey also found that more than a quarter (27%) of DevOps teams’ time is spent on manual continuous integration/continuous delivery (CI/CD) tasks. Nearly a quarter (22%) admit they’re often under so much pressure to meet the demand for application deployments that they must sacrifice code quality.

    In response, nearly two-thirds of respondents (62%) are investing in automation to eliminate manual tasks, while a similar percentage are looking to automate incident response processes. Another 45% are investing in observability tools, with nearly three-quarters (74%) noting that end-to-end observability will be essential to DevOps in the future.

    A full 98% also noted that extending DevOps to more applications will play a crucial role in driving digital transformation and optimizing customer experience. A total of 71% said a unified platform that seamlessly integrates their toolchains will be critical to scaling DevOps, while 79% said extending artificial intelligence to IT operations (AIOps) into the realm of DevOps is critical for their future success.

    Survey respondents, however, also identified siloed team cultures (75%) and application complexity (70%) as the primary barriers to achieving DevOps success. Organizations, as a result, are investing in the automation of manual CI/CD tasks (62%), eliminating manual incident response (62%) and end-to-end observability (45%).

    Grabner noted that, as more organizations build and deploy next-generation applications based on microservices constructed using containers and application programming interfaces (APIs), it will only become more challenging to automate DevOps processes. As part of an effort to reduce the cost of delivering those applications, Dynatrace donated Keptn, an open source enterprise-grade control plane for automating the continuous delivery of cloud-native applications, to the Cloud Native Computing Foundation (CNCF), added Grabner. The overall goal is to reduce the total cost of implementing DevOps as part of an effort to instrument more applications, he noted.

    While most organizations that have embraced DevOps have a good handle on how to implement continuous integration, achieving the continuous delivery side of the DevOps equation has proven to be more challenging. In the absence of standardization among the platforms, each application deployed on individual IT systems is a “snowflake,” in that it is unique to that platform. That issue, in part, is why so many IT teams still rely on manual processes to deploy applications.

    It’s only a matter of time before organizations begin to more aggressively automate the deployment of applications. That may become even easier to achieve if they standardize on a Kubernetes application programming interface (API) that can be implemented across any platform.

    In the meantime, however, it’s clear that, as the pace of digital business transformation increases, one of the most limiting factors organizations will encounter is the pace at which applications can be deployed and updated.

  • Postman Survey Shows Focus on Building and Deploying APIs

    Postman Survey Shows Focus on Building and Deploying APIs

    A survey of more than 28,000 developers and application programming interface (API) professionals published today by Postman found nearly half of respondents (49%) are now spending the majority of their time developing APIs. More than a quarter (28%) now spend 20 or more hours per week working with APIs.

    Kin Lane, chief evangelist for Postman, a provider of a platform for building APIs, said that shift reflects an increase in software development and integration activity that began at the start of the COVID-19 pandemic. Almost two-thirds of respondents (63%) said the pandemic somewhat or significantly affected their work, with almost half of those respondents noting that changes made with their organization were enabled and supported by APIs.

    Additionally, a full 94% of respondents said the investment of time and resources into APIs will increase or stay the same for the next 12 months. The biggest obstacle to creating APIs is lack of time (45%) while the biggest obstacle to consuming an API is lack of documentation (55%). In terms of API goals, the survey found that quality (80%), agility (66%) and reliability (65%) are the top three goals among survey respondents.

    However, the survey also noted only a third of respondents said they could build and deploy an API in anywhere from a single day to a week, with most requiring one week to a month. About one-third also said they deploy APIs to production between once per week and once per month. More than 80% of respondents noted that less than 25% of their changes fail while a similar percentage said they can recover in less than a day with a third reporting they fully recover in less than an hour.

    The Postman survey also found that more than three-quarters of respondents (76%) have less than five years of experience with API development. Only half of respondents indicated that they agree or strongly agree that the leadership of their API team has a clear sense of where their API practice should be in five years. However, microservices (58%) and Kubernetes (50%), containers (46%), serverless architecture (44%) and GraphQL (35%) were ranked among the technologies that respondents were most excited about heading into 2022.

    On the plus side, more than 60% of respondents felt their API leadership and governance teams demonstrated a “willingness to change” as well as duly considering “the interests and opinions of employees.” When it comes to regularly providing feedback and process, more than half of leadership and governance teams (53%) scored well.

    The top two ways API teams collaborate is via a dedicated collaboration platform (50%) or by publishing API artifacts to repositories such as GitLab, GitHub and Bitbucket (45%), according to the Postman survey. The most widely used DevOps tools are Jenkins (37%), Azure DevOps (26%), GitHub Actions (25%), AWS DevOps (23%) and GitLab Pipelines (22%).

    In terms of deploying APIs, continuous integration/continuous delivery (CI/CD) platforms are the most widely employed (57%), followed by deploying APIs in the cloud (38%), frameworks (34%) and custom-built deployment methods (27%).

    Just over 70% of respondents ranked security and performance as the top factors considered when integrating with an API. When producing an API, however, the top factors are integration with internal systems, integration with external systems, adding functionality to an internal system and enhancing functionality for an end customer. Similarly, when consuming an API the top factors are integration with external systems, adding functionality for end customers, adding functionality to internal systems and integration between internal systems.

    In general, Lane noted that, as more APIs are developed and deployed to drive various digital business transformation initiatives, organizations will need to pay more attention to API discovery and management. There’s a tendency for different teams within organizations to not only create redundant APIs but also forget about so-called zombie APIs that are no longer supported but can still be exploited by cybercriminals.

    Overall, Lane said the survey makes it clear more organizations are pursuing an API-first approach to digital transformation. The challenge now is managing all the APIs that can quickly become too much of a good thing.

  • What 30 Years of Linux Taught the Software Industry

    What 30 Years of Linux Taught the Software Industry

    Linux has become the largest collaborative development project in the history of computing over the last 30 years. Reflecting on what made this possible and how its open source philosophy finally imposed itself in the industry can offer software vendors valuable lessons from this amazing success story.

    The web may not have reached full adulthood yet, but it has already crafted its own mythology.

    August 25, 1991: Linus Torvalds, a 21-year-old university student from Finland, writes a post to a Usenet group: “Hello everybody out there using minix — I’m doing a (free) operating system (just a hobby, won’t be big and professional like gnu) for 386 (486) AT clones […]”. A few weeks later, the project, which will eventually be known as Linux, is published for the first time.

    This is the starting point of an epic that few could have foreseen.

    Fast-forward 30 years and the Linux kernel isn’t only running on most of the web servers and smartphones around the globe, but it also supports virtually all of the much more recent cloud infrastructure. Without open source programs like Linux, cloud computing wouldn’t have happened.

    Among the major factors that propelled Linux to success is security. Today, the largest software companies in the world are taking open source security to new levels, but the Linux project was one of the first to emphasize this.

    How Linux Became the Backbone of the Modern IT World

    Brief History

    Open source predates the Linux project by many years and is arguably as old as software itself. Yet, it is the success of the latter that propelled this movement in the 1990s. When it was first submitted for contribution in 1991 by Torvalds, the Linux kernel was the GNU project’s ‘missing link’ to a completely free software operating system, which could be distributed and even sold without restrictions. In the following years, and as the project started to incorporate proprietary licensed components and grow in popularity, a clarification on the meaning of “free software” became necessary.

    This led to the coining of the term “open source” as we use it today, thanks in part to Eric Raymond’s seminal paper The Cathedral and the Bazaar, a “reflective analysis of the hacker community and free software principles.” Open source was chosen to qualify software in which the source code is available to the general public for use or modification from its original design, depending on the terms of the license. People may then download, modify and publish their version of source code (fork) back to the community.

    Open source projects started gaining traction in the late nineties thanks to the popularity of software like Apache HTTP Server, MySQL and PHP to run the first dynamic websites on the internet.

    Facts and Figures

    Today, not only is Linux powering most of the digital era, but open source has become the leading model for how we build and ship software. Though most people don’t realize it, much of the technology we rely on every day runs on free and open source software (FOSS). Phones, cars, planes and even many cutting-edge artificial intelligence programs use open source software. According to the Linux Foundation, 96.3% of the world’s top one million servers run on Linux and 95% of all cloud infrastructure operates on it. Other infrastructure also relies on open source: 70% of global mobile subscribers use devices running on networks built using ONAP (Open Network Automation Platform).

    Linux adoption is very high in professional IT, where it’s become a de facto standard, especially with the advent of the cloud era. In fact, 83.1% of developers said Linux is the platform they prefer to work on. This success is due, in large part, to the community that contributed to its source code since its creation: More than 15,000 developers from more than 1,500 companies. Linux went on to become, arguably, the biggest success story of the free software movement, proving that open source could lead to the creation of software as powerful as any sold by a corporation.

    The Linux Foundation, a non-profit technology consortium founded in 2000 to support the collaborative development of Linux and OS software projects, is itself a big success. It now has more than 100 projects under its umbrella, spread across technology sectors like artificial intelligence, autonomous vehicles, networking and security. Several subset foundations have also emerged over the years, including the Cloud Foundry Foundation, the influential Cloud Native Computing Foundation, and the recently announced Open Source Security Foundation. The Foundation estimates the total shared value created from the collective contributions of its community to a whopping $54.1 billion.

    All these achievements may not have been possible without the embrace of open source by the enterprise world, which may represent its biggest win.

    Enterprise Adoption

    Companies began to realize that many open source projects were easier and cheaper to implement than asking their developers to build the basic pieces of an internet business over and over again from scratch.

    Twenty years ago, most businesses ran atop proprietary software from Microsoft, Oracle and IBM, and the idea of collaborating on big software projects might have sounded laughable to them. Today, these companies, along with relative newcomers such as Google, Facebook and Amazon, are not only employing thousands of full-time contributors to work on open source projects like Linux, they also regularly choose to open source some of their state-of-the-art projects; from Google Brain’s machine learning platform TensorFlow and container orchestration platform Kubernetes to Facebook’s React.

    There’s no question that open source software created a new wave of business opportunities. As more companies took an interest in open source projects, they realized they didn’t necessarily have the in-house expertise to manage those projects themselves and turned to startups and larger companies for help.

    Even Microsoft, which famously warred against the very concept of Linux for nearly a decade, made a strategic shift to embrace open source in the 2010s, led by CEO Satya Nadella. The IT giant finally joined the Linux Foundation in 2016 and acquired GitHub, the largest host for open source projects, two years later. It has since become one of the biggest sponsors of open source projects.

    As a consequence, the stakes have been raised for open source software, which is the engine powering the shift toward the cloud for virtually every company. In this context, security is becoming a topic of the utmost importance, and the commitment to secure the open source ecosystem is growing fast.

    Setting a Standard for Security and Trust

    Open Source Security Issues

    Following the OSS adoption boom, the sustainability, stability and security of these software packages is now a major concern for every company that uses them.

    The Census II report on structural and security complexities in the modern-day supply chain “where open source is pervasive but not always understood” revealed two concerning trends that could make FOSS more vulnerable to security breaches. First, the report said it is common to see popular packages published under individual developers’ accounts, raising the issue of security and reliability. Second, it is very common to see outdated versions of open source programs in use, meaning they contain fewer security patches.

    The 2021 OSSRA report agrees: “98% of the codebases audited over the past year contain at least one open source component, with open source comprising 75% of the code overall.” The report also noted that 85% of the audited codebases contained components “more than four years out of date”.

    This highlights the mounting security risk posed by “unmanaged” open source: “84% of audited codebases containing open source components with known security vulnerabilities, up from 75% the previous year. Similarly, 60% of the codebases contained high-risk vulnerabilities, compared to 49% just 12 months prior.” Not only is the security posture affected, but there are also compliance issues that can arise from unsupervised integration of open source content because licenses can be conflicting or even absent.

    Because large corporations are now a big part of the open source ecosystem, their sponsorship is a welcome source of financing for many people whose work had been done for free until now, yet it may not be enough. The open source community is well-known for its commitment to independence, its sense of belonging and its self-sufficiency, and expecting contributors to voluntarily address security issues is unlikely to succeed.

    This is where the experience of building Linux over 30 years and coordinating the work of thousands of individual contributors may be an example to follow.

    Linux Foundations

    In Linux kernel development, security is taken very seriously. Because it is an underlying layer for so many public and private software ‘bricks’ in the digital world means that any mistake can cost millions to businesses, if not lives. Since the beginning, it has adopted a decentralized development approach with a large number of contributors collaborating continuously. Therefore, it has consolidated a strong peer-reviewing process as the community development effort grew and expanded.

    The last stable release at the time of writing is 5.14, released on August 29th, 2021, only a few days before the 30th birthday of the project. The most important features in the release are security-related: One is intended to help mitigate processor-level vulnerabilities like Spectre and Meltdown and the other concerns system memory protection, which is a primary attack surface to exploit. Each Linux kernel release sees close to 100 new fixes per week committed by individuals and professionals from the likes of Intel, AMD, IBM, Oracle and Samsung.

    With such broad adoption and long history, the Linux project has reached a level of maturity that few, if any, other FOSS projects have seen. The review process and release model have built confidence for numerous downstream vendors. Although the world is not perfect and it is arguably difficult for them to keep up with such a high rate of change, they can at least benefit from strong security enforcement mechanisms and they can adapt their security posture in concordance to their “risk appetite”: Vendors are able to do the calculus of determining how old a kernel they can tolerate exposing users to.

    Pushing the Boundaries of Open Source Security

    Heartbleed and the Fragility of OS Security

    In April 2014, a major security incident affecting the OpenSSL cryptography library; disclosed as “Heartbleed.” The developer who introduced the bug acknowledged that, though he was working on the project with a handful of other engineers:

    “I am responsible for the error because I wrote the code and missed the necessary validation by an oversight. Unfortunately, this mistake also slipped through the review process and therefore made its way into the released version.” OpenSSL, an open source project, is widely used to implement the Transport Layer Security (TLS) protocol. In other words, it’s a fundamental piece used to secure a large part of the web.

    Open source was seen as fundamentally secure for a long time because the more people examine a line of code, the better the chances of spotting any weakness. Additionally, this model prevents “security by obscurity,” whereby the bulk of the protection comes from people not knowing how the security software works—which can result in the whole edifice tumbling down if that confidential information is released or discovered externally.

    This incident was a major turning point for a large share of the biggest web corporations: They realized that many open source technologies underpinning their core operations could not be “assumed to be secure” anymore. Any human error could have huge implications; therefore, a specific effort had to be made to improve the security in this specific space.

    A New Era for Open Source

    As we advance in an era where open source is omnipresent in codebases, tooling, networks and infrastructure and is even in fields other than software, security awareness is starting to take hold. But it needs a lot more work.

    A big part of the challenge, to begin with, is for the industry to understand the scope of the problem.

    Google just announced that it will be committing “$100 million to support third-party foundations that manage open source security priorities and help fix vulnerabilities.”

    The Secure Open Source (SOS) pilot program, run by the Linux Foundation, will reward developers for enhancing the security of critical open source projects that we all depend on.

    In doing so, Google leads the way in enlarging the financial sponsorship of big players like companies and governments — which are increasingly sponsoring open source both directly and indirectly. However, they also recommend that organizations “understand the impact they have on the future of the FOSS ecosystem and follow a few guiding principles.”

    What could these principles look like?

    A Roadmap to Safely Use and Contribute to Open Source

    The Linux Foundation proposed a specific Trust and Security Initiative which describes a collection of eight best practices (with three degrees of maturity) open source teams should use to secure the software they produce as well as by a larger audience to “raise the collective security bar.” Here they are:

    • Clarifying the roles and responsibilities, and making sure everyone is aware of their security responsibilities across the organization.
    • Setting up a security policy for everyone; in other words, a clear north star for all members of the organization.
    • ‘Know your contributors’ is defined as a set of practices to make risk-based decisions on who to trust and fight offensive cyberwarfare techniques, such as the poisoning of upstream code.
    • Locking down the software supply chain: This has become a preferred target as adversaries clearly understood that they can have a bigger and more effective impact with less effort than targeting individual systems.
    • Provide technical security guidance to narrow potential solutions down to the more appropriate ones in terms of security.
    • Deploy security playbooks to define how to do specific security processes, specifically incident response and vulnerability management processes, like creating roles and responsibilities or publishing security policies. This may feel formal, antiquated and old-school but having pre-defined playbooks means that teams can focus on shipping software and not learning how to do security, especially at the least convenient and most stressful time.
    • Develop security testing techniques with automated testing strongly recommended since it scales better, has less friction and less cost to the teams and aligns well to modern continuous delivery pipelines.

    However, the authors of the guide are aware that some major challenges are still facing the industry and, as such, need to be addressed. They mention:

    • The lack of open source security testing tools
    • The fact that open source package distribution is broken
    • The fact that the CVE format for vulnerability disclosure is also broken
    • The lack of a standard for a security build certificate which would allow any consumer to transparently verify that a product or component complies with the announced specifications

    “The types of verification can and should include the use of automated security tools like SAST, DAST and SCA, as well as verification of security processes like the presence of security readmes in repos and that security response emails are valid.”

    A scheme like this could have a significant and lasting effect on the security quality of open source software and the internet at large.

    The Linux project, born 30 years ago, is present in all layers of the modern software stack today. It is used by all the largest server clusters powering the modern web and any business going digital will use it at some point. This unparalleled longevity and success have demonstrated that the open source model was compatible with the requirements of enterprise-grade services and economically viable. Now that open source is all the rage in the software industry, a consensus and action plan on how to ensure the sustainability of this ecosystem becomes urgent. The top priority for businesses that depend on it is to adopt strong application security guidelines, like the ones promoted by the Linux Foundation, which have proven their value.

    One last note on the nature of open source: As businesses are now much more bound by the common use of open source components to build upon, they should not fall into the “tragedy of the commons” trap. This would mean waiting until others take action; for instance, to improve the global software security landscape. This might be one of the biggest challenges confronting our highly collaborative industry.

  • EP 19: How AI/ML are Used in DevOps Today

    EP 19: How AI/ML are Used in DevOps Today

    Artificial intelligence (AI) and machine learning (ML) help improve the performance of DevOps teams by automating repetitive tasks and eliminating inefficiencies across the SDLC. By using AI, teams can test, code and check software faster and more efficiently. In this episode of DevOps Unbound, Brian Dawson, Judith Hurwitz, Alan Shimel and Mitch Ashley discuss how AI and ML are transforming DevOps and what new use cases await AI and ML in 2021 and beyond. The video is below, followed by a transcript of the conversation.

    [Intro Music]

    Alan Shimel: Hey, everyone. I’m Alan Shimel, CEO of MediaOps, DevOps.com, Container Journal, Security Boulevard, and you’re watching DevOps Unbound. DevOps Unbound is sponsored by our friends at Tricentis, so many thanks to them. And DevOps Unbound is a biweekly show where we cover topics of interest to the DevOps audience.

    I am the host. My cohost is our CTO and CEO of Accelerated Strategies Group, my friend Mitchell Ashley. Mitchell, welcome.

    Mitch Ashley: Thank you. Good to be here as always, and with this illustrious panel.

    Shimel: Absolutely. And an illustrious panel it is. We have two panel members joining Mitchell and I today. Let me introduce you to both of them. They’re both great folks in their own right and I’m going to let them introduce themselves.

    Let’s start with our friend Judith Hurwitz. Judith, welcome to DevOps Unbound.

    Judith Hurwitz: Thank you so much, Alan. It’s a pleasure and an honor to be here.

    Shimel: It’s our pleasure.

    Hurwitz: So I’m Judith Hurwitz. I’m the coauthor of 10 books. Have been in the industry for 30-plus years. Focus on everything from DevOps, security, manageability in cloud, hybrid cloud, and really looking at how you take technology to transform organization. It’s a complex topic, not easy, but it’s what we’re in the middle of.

    Shimel: Absolutely. Then last but certainly not least, our friend Brian Dawson. Hey, Brian. Welcome.

    Brian Dawson: Hey, Alan. Thank you. Good to be on with you again. To tell the audience a bit about myself, as I’ve told you before, Alan, I’ve been in software development and delivery for about 30 years. I consider myself a technologist. And even prior to focusing on DevOps I’ve had a focus on optimizing software development and delivery.

    Excited to talk about AI. I kind of dabbled and dipped my toes in the space in my time that I spent at the company that is now PlayStation. Things have come a long way since. And during that time, I’ve spent the past 10 years of my career focused on identifying, applying, and spreading DevOps practices, so I’m excited to discuss the two together here with this group.

    Shimel: Absolutely. Brian, I’m not sure if you mentioned your present position with the Linux Foundation.

    Dawson: I did not actually, because also this organization I’m at today has a big footprint in the AI and ML space. So today I’m with the Linux Foundation. I oversee our developer relations and ecosystem development. And of note, within that is the LF AI & Data Foundation, which houses a number of impactful projects in this space.

    Shimel: Thank you. I just thought the folks at LF would welcome that, a little plug for them.

    Dawson: Well I appreciate it, thank you.

    Shimel: Yep. Alright. So the topic for today’s DevOps Unbound is artificial intelligence and machine learning. How can they help improve performance of DevOps teams? In other words, what’s their role in the DevOps world? Right? And let me preface our conversation by giving you sort of my view of it. DevOps for many people was all about automation.

    What can we automate? Let’s automate everything we can. Automate, automate, automate. And obviously in discussions around automation topics such as artificial intelligence and machine learning you would tend to think help with automation, and therefore anything that helps with automation is good for DevOps. And I should also say that we lump AI and ML together like they’re Siamese twins joined at the hip, and they’re not necessarily cojoined.

    You can have AI without ML and you can have ML without AI. At least I think so. I’d be interested in your thoughts. But has it lived up to the hype? Will it ever live up to the hype? Was the hype unfounded? Was it unrealistic?

    What role has AI and/or ML to this point played on DevOps and what will it play going forward? I think that’s our topic today. Any one of you, if you want to kick it off with your own feelings or respond, go right ahead.

    Dawson: Well I’d like to jump in as a troublemaker early on and say I challenge Alan that DevOps is really about automation as kind of the basis for the tie-in. If we look at it, DevOps is really a set of cultural practices and tenets that align DevOps and other software delivery stakeholders around the shared objective of delivering quality software reliably, rapidly, and repeatedly. Now the reliably, rapidly, and repeatedly component absolutely lends itself to some of the benefits that we could mine from AI, but I actually think it’s a great opportunity. If we don’t say DevOps equals automation equals AI, or rather we say DevOps equals a culture aligned around a shared objective and how can AI and ML help support those shared objectives.

    Hurwitz: I think you make a great point, Brian. I think one of the most important issues, and you mentioned culture. We have been for, what, 50 years through this development and operations perspective on how we get things done, and the promise of AI is, okay, I can push a button and it will take care of everything, and this promise has been there for, what, 20 years. The reality is it’s just not that simple. There are definitely things that we are doing today and we’re seeing evolve that is definitely helping the developers and the operational professionals.

    For example, if you have repeatable functions that happen all of the time, that, for example, if you press a button and a certain task should happen you can probably use a model and collecting massive amounts of data to do that automatically. And that’s a very good use of AI. We’ll work today – they call it MLOps or AIOps, and there’s a good reason why that’s what we’re focused on today, is because you’re looking for predictable patterns and predictable anomalies so you can avoid making stupid mistakes that, oh my god, why did I do that? I knew what the right answer was.

    But AI is not a panacea. And I think if we look back even two or three years ago, you had companies that all were saying, “Okay, we have automated, we’ve put AI into DevOps, and all you have to do is press a button and all of your problems are over.” That’s just not reality.

    Ashley: There’s the marketing AI and ML and then there’s real AI and ML. Marketing meaning everybody gloms onto the term and uses it in, let’s say, a case statement or an if statement in people’s logic and their software. Yeah, I started doing some work in AI in ’80s and ’90s programming in LISP and PROLOG and doing some corporate education in that area, some expert systems with triage, things like that. So I dabbled in a little bit there and then I was exposed to more recently about five or six years ago, worked with a gentleman named Dr. Bernard _____ who’s one of the experts in the field. And I asked him, “Help me understand why has machine learning taken off as a service.”

    He described it as a subset of AI, so that was his model anyway. What he told me really made sense and it kind of helps me understand where can we apply machine learning, and being kind of the most popular part of AI. He said machine learning takes massive amounts of data, and the fact that we have the cloud and all these applications creating data, a lot of the data exhaust, now people are going back and mining that data. So Judith, in your writing, in your books about data analysis and leading up to AI, machine learning is great for that because you can have supervised or unsupervised algorithms, supervised meaning that’s a cat, that’s a cat, that’s not a cat, or unsupervised which is just going to pour through the data and start to look for those patterns and trends and anomalies that you were talking ab out, Judith.

    So when people talk about using AI or ML, in our industry I always think about where’s there’s lots of data and can we leverage it in some impactful way? So as I look at products or technologies that claim they’re doing that, that’s at least one sort of criteria to sort of ferret out. Is it real there? Is there something real there? Or is it more spin and fluff to help us – you know, we all have case statements in our spot, right?

    Shimel: Absolutely. Actually, Brian, it looked like you were going to say something. I didn’t want to jump on you.

    Dawson: Alan, of course I have a lot to say, but nothing in particular. Since I’m off mute, I’ll say I absolutely agree with Mitch and Judith and underscore the points that they made.

    Shimel: Yep. You know what? I want to take a moment though and explore. Brian, you disagreed; DevOps isn’t about automation. And I get the whole cultural aspects of DevOps and all of that, but certainly automating as a way to be more efficient, to get more done faster, I think is part and parcel of the DevOps mindset.

    Dawson: Yeah. And if I may, without waiting to see where you wanted to go with that, I’d say it is absolutely important, but there’s a line Jez Humble would use in talking about CD. And frankly, I think the book that Dave Farley, Jez Humble and team wrote around continuous delivery is undercelebrated and under referenced. And in talking about that, one of the things he said is continuous delivery, and I’m going to say by extension some aspect of DevOps, don’t require any tools. I can do continuous delivery with a Bash script. The catch is is it’s not the most efficient in pursuit of effective collaboration, of delivery velocity so you can iterate.

    And as we’ve talked about in this past established, that controlled feedback loop, that requires things like automation to achieve those goals. Right? I just think sometimes when we talk about what we see going on with AI and ML and those terms we overload a principle or practice with expectations that aren’t core to it, and I worry a bit about that so I wanted to call it out. And sorry, Alan, I don’t know if that’s where you wanted to go with the commentary.

    Shimel: No, no, no. I want to go wherever you want to go, Brian.

    Dawson: Okay. [Laughs]

    Shimel: This is a collective. Judith, what about – I’m sorry, go ahead.

    Hurwitz: Oh, yeah. So Alan, I think one of the key issues is the whole area of continuous delivery. In previous generations, you would build an application and it would live pretty much as it was written, could be for 10 years. Today, applications are constantly having to be revised because customers change, partners change, the sources of data change. So unless you have the ability to constantly update and change and modify, you lose out. One of the values of using automation and using AI and machine learning models with lots of data is to support the ability to do this.

    You don’t have enough hands and enough brains to anticipate where problems may occur because you’ve changed things. How many times have we seen problems occur because somebody has added a new service to their environment and somebody forgot to change a configuration file? Now that’s not something that you need a massive brain to be able to do, but people get busy and they forget to do simple things.

    Ashley: I think, Judith, that’s a really good point, because I wanted to ask you about this in the software creation process. Given things are so dynamic now and constantly changing, understanding just the environment, the infrastructure-as-code all the way up through the application and how much all of that is changing, it seems like stepping in for humans in certain conditions in that environment is a great application of AI. For someone to synthesize all the factors that might go into where a problem exists or what might be causing a problem seems to be where some of those algorithms might be helpful. Do you agree with that? Has that been your experience of what people are thinking about for AI?

    Hurwitz: Yeah, definitely. I think what we’re seeing is this is where sort of the human factor comes in. You set it up so that if the printer is turned off don’t send me an alarm, fast, emergency, there’s a problem with the printer. We all have gotten used to that. But when there are problems that you’ve never seen before, that you don’t have data on and the model doesn’t take into account, then the AIOps or MLOps then gives you a message there’s something strange going on. I don’t know how to fix it.

    What do you want to do here? And so over time when that appears again, well now you had data this occurred once before. Maybe it was an anomaly twice. But then when you have enough data and enough experience over time then you build that into the model, so the next time that occurs you make a fix. On the other hand, you don’t want the system to say, “Oh, I know what that is,” make a fix, when it turns out no, no, no, you don’t understand the context of what’s going on here. And just because there’s a correlation doesn’t mean that there’s a cause for that.

    Shimel: That’s a good point.

    Ashley: It’s not always about automating a response to it, right? Everyone in the security world are very cautious or skeptical about those things happening, blocking legitimate traffic. In the financial world that’s a huge issue that we run into. So you point out a good scenario, whereas we see repetitive patterns over time and that can help machine learning algorithms now understand, okay, that’s what that pattern looks like. So you can identify what it is next time instead of it’s just an anomaly.

    Dawson: Yeah, it’s interesting, Mitch, that you say that. And going back to the starting topic about AI and ML not really achieving its promise yet, and as you called out getting data as an issue, it’s not necessarily applicable to every space. You need a level of determinism and predictable patterns that you can learn from and build on. And I have for a long time been excited that when we look at CI and CD, when we look at, Alan, the automated workflow of software development and delivery, or even if it’s not automated kind of the standard, there’s a couple of things that you do have.

    You’re doing builds, sometimes thousands a day, builds and deployment, getting that out into prop. You could be generating a ton of data. And also in its nature, you’re striving to achieve a level of consistency and repeatability in how you deliver software. And I’ll say I’m not an expert to the level some of the people on this episode are, but I get at a very top level get really excited about the opportunity for AI and ML to help better CI and CD and align with the principles of DevOps. What I see it really helping is reducing cognitive load so developers can focus on coding, innovating, and solving problems while helping ensure that quality and stability that’s difficult to maintain while you’re moving fast.

    So just thought I’d call out, and I am curious to see when vendors and others really start to do like what our friend Kohsuke has done with Launchable, and really apply AI and ML to the left-hand side or Dev side of the process to reduce the load and ensure quality and stability.

    Shimel: Guys, we’re all lumping AI and ML, AI and ML, AI and ML. Does it have to be AI and ML? In my experience, a lot of what we call AI and ML is a lot more on the ML than it is on the AI. Right? So it is fair to call it truly AI? Is it really ML? And maybe ML is for today and AI is a tomorrow thing. I don’t know.

    Hurwitz: So I think there’s definitely a problem of nomenclature here. What we’re really dealing with primarily now is models and modeling data and creating models from data. That’s the reality of today. I think that there is a lot of misuse of the term AI. There have been some absolutely wild predictions. I can’t remember the name of the computer scientist who predicted that he would be able to replicate the human brain –

    Ashley: Marvin Minsky.

    Hurwitz: – with AI. No, this was past Minsky.

    Ashley: Oh, was it after? Okay.

    Hurwitz: Yeah. This was like in the last five years.

    Ashley: Oh, okay, okay.

    Hurwitz: So over time, you’re always going to be dealing with models. You’re never going to get rid of the models. AI is sort of the next – models are a subset of what you eventually achieve with AI. But AI is really a concept that will probably take decades to evolve, and I think one of the problems we have right now is where you have vendors, and I’ve talked to hundreds of them over the years, where they say, “We have an AI application,” because it’s a hot buzz word.

    And you can look back and in the history over the last 30 to 40 years and see whatever the hot topic is all of the vendors say we do that. So I think that that’s one of the problems that businesses are facing right now. What is the difference? What does it really do? How does it make your company better? How do you use this technology to be prepared for change?

    Ashley: I think that’s a good way to break it down, Judith, too, because early days of AI were about emulating human thinking. We’re still long from – I’m not sure – all my intelligence is artificial, by the way. I acquired all of it. I don’t think I was born with any of it. But that was kind of where it started, and then AI became about expert systems largely. And then algorithmic learning, machine learning algorithms, was really where I think most of the activity is today because of that prevalence of data.

    It seems like most organizations are faced with sort of one of three strategies. What do we look for from our vendors and how they may use AI in a meaningful way or machine learning in a meaningful way that’s going to help my business? Do I build models myself from the data, like you were talking about, Judith, to apply to like a financial analysis kind of situation? More of an expert system. Or do I use machine learning algorithms in my own software to do interesting and valuable things that my software can do? And maybe you play in all three of those or a subset of those, but that seems to be the question I think most individuals or organizations are at.

    We’re not at a place where we can go build models, but we’re looking for these capabilities either in our own code or in third party products.

    Hurwitz: So I heard an interesting story from one of my clients a few years ago, maybe five years ago. He had a client that was very gung-ho about AI. So he went out and he hired five data scientists, paid them $1 million each, gave them their own space, and left them alone. These are the smartest people on the planet. Came back in six months.

    He didn’t want to bother them, they’re so smart. Alright. What have you found out? Have you written this application? And they said, “Well, we’ve been discussing this for six months and we have determined that algorithm we’re going to use.” The point is that they worked in isolation, they thought they were the smartest people on the planet, they did not talk to people on the business side about what business problems they had, they didn’t talk to the people who understand corporate data, they didn’t ask them what data do you actually have, what data do you need, they didn’t talk to people who knew the business strategy or the business processes that were in place or needed to change.

    So it really is a team sport, and I like Brian’s discussion in the beginning about culture because it really is about sort of hybrid organizations where you have leaders that know a little bit about all of these areas and then a team that’s brought together that can work across these areas.

    Shimel: Fair.

    Dawson: Judith, can I ask do you have any recommendations for DevOps teams on how to evaluate or investigate where ML is a solution? And I ask this based on observation – we’ll see if we agree – that oftentimes people are looking for a problem to apply the solution to as opposed to for ML as a solution to a problem they’ve identified. I’m just curious if you –

    Hurwitz: I violently agree with you. So I think a lot of times people get so enamored with new technology that they look at it as a way to solve all problems. And for a DevOps team I think we’re finally getting to the stage where there’s really reality in DevOps. It’s not the developers who are saying, “That’s not my problem; the operations people have to make this work.” There’s really beginning to be this collaboration between development and operations, and this shift left is definitely becoming real.

    So that’s definitely true, but for these teams to be successful they have to have a holistic view of where is your business going? What do they actually need? Why have they come to you and say we’ve go to do something? Is it just because it would be cool to do something and spend money or is there a real rationale behind this that they need? What’s the pain that’s out there that they can solve.

    So they have to start with that. They have to start not only collaborating between developers and the operations team but with the business leaders, with the people who understand all of the data, people who understand security. So all of this comes together in very much a holistic pattern.

    Shimel: Fair. Fair. Hey, guys, we’re way past halfway through here and I wanted to kind of turn our conversation to the future. We’ve had a discussion on sort of the history of AI and ML and lessons learned, et cetera, but when we look forward, Brian, you mentioned the Linux Foundation has, I don’t know if it’s a daughter foundation or a subgroup dedicated to AI and like technologies. What do we see when we look sort of near-term future? Forget, yes, one day we’ll mimic human brain patterns. Who knows if we’ll be alive by then. But near term, what do you see? What is Linux Foundation planning for?

    Dawson: Well, so looking forward, and it’s funny because you brought me in and I started to think about dream the impossible dream of what’s going to happen in the future, I will call out and will mention again I said at the start the Linux Foundation is a parent foundation of what we call a Linux Foundation open source project that hosts other projects. So LF AI & Data, you can call it a sub foundation of Linux Foundation because they host, I believe at this point, 12 graduated projects with about 20 to 30 projects in incubation. So we’re talking 30 to 50 projects under the LF AI & Data umbrella that are all working on various aspects of shared efforts, multiple large commercial organizations as well as standards bodies coming together to drive the future of AI and ML.

    What I do see coming out of LF AI & Data Foundation in the short term is standards and foundational implementations, i.e. moving sort of beyond the rudimentary discovery around AI, building packaged or gray box implementations that everybody agrees and collaborates on, which I think will help unlock the less initiated, less expert vendors to begin to deliver truly AI-based differentiating capabilities. So to put that in short, because it was a lot of words, is I think it’s about establishing a foundation for us to start to build on and accelerate our progress within the AI and data space applied to DevOps.

    Hurwitz: And so Brian, I think that you’re 100 percent right, and that’s when commercialization really happens is when we have those standards and when everybody agrees to use those foundational services. I think the challenges that we face are how to get the commercial vendors who don’t necessarily want to – they want to give lip service to these standards but they really want you to only use their version of the quote/unquote standard so that customers never leave. So it’s that stickiness factor that they are looking for. So I think it’s a hard journey.

    Dawson: Yeah. Well I think, Judith, you actually nailed the reason the Linux Foundation exists frankly, and if we look at Kubernetes as a model, it was hard pressed. Google could’ve easily said, “We’re not going to hand this over to the Linux Foundation. We’re going to dominate this space. We are going to be the modern cloud OS.” But they understood for it to gain traction, for it to grow and truly offer benefit industrywide, they had to hand it over to the Linux Foundation to grow and manage.

    They had to bring in Microsoft, they had to bring in Amazon to play in that space. And I see LF AI & Data serving that same role, what I tend to call in some language unlocking innovation, or as our tagline is, decentralized innovation. I would beg to say that that is – we didn’t call that out directly, but that’s one of the challenges that we’re seeing in the AI and data space. If there’s not short-term monetization we’re not going to do it, and if there is then we want to own it. So can we create an impartial playing field for everybody to come in and innovate together, and then build commercial solutions off of that.

    Hurwitz: Yeah, it’s a challenge. It really is. I think Kubernetes is a great example. I think data in some ways is more complicated because data is really the crunch.

    Dawson: Yeah. Well I know everybody wants to own it. Everybody wants to own the data.

    Shimel: No doubt about it.

    Ashley: There’s also discussion about AI needs to become an engineering discipline as opposed to this sort of edge specialty. It doesn’t mean that it necessarily is going to be applying everywhere, but I think how we apply AI to certain kinds of problems. It seems to me the two most ripe areas are that highly complex environment. So with more and more infrastructure that’s automated, more things have gone to digital, how do you manage the infrastructure or manage the triage problem solving? And then of course the other areas, people will find _____, continue to find _____ where AI can be applied to gain competitive advantage in a certain domain or space.

    And it seems like that’s the trajectory we’re on for quite a while. I don’t think it’s ever going to be AI takes over everything and it’s the thing that replaces DevOps or whatever. But it seems to me kind of a tool. Sorry. Go ahead, Judith.

    Hurwitz: No, what I was going to say is very interesting. If you look at healthcare, for example, if you look at the spectrum from I can automate certain DevOps functions that are repeatable, where I can identify patterns, and as I collect more data I can automate more things, you have something like healthcare, which in terms of orders of magnitude of complexity are just huge. And what I’m seeing is a lot of the vendors who think that I’m going to tackle healthcare with AI and we’re going to own the industry, a lot of them are getting out of the business because right now it’s just too hard and it will be too hard for quite a while.

    Ashley: That’s true. The medical industry in many ways [laughs] is a hard nut to crack.

    Dawson: Yeah. If I may start to dream a little and chime in based on something you said, Mitch, I do see that in the near term we are at a point where we talk about modern software development and delivery, the rapid pace with which we’re delivering change. We’re building on inventions and progress made over decades. Library reuse is very heavy. We are getting to a point where as we build more complex systems we have to figure out how can we outsource sort of maintenance and management, for want of a better word, to use it kind of grossly to solutions like ML?

    How can ML help us continue to improve, grow, and build on what we’ve done but manage the scale and complexity? And I think we’ll move from some standardization, foundational blocks, we’ll apply more ML in both the operations and development space to help manage that complexity to maintain stability, but then I also eventually see the next stage being now how do we apply ML and surface it to a developer at the time of a commit? Here’s the expected outcome of this change is, to help provide guardrails to the developer, the end state – or I wouldn’t even say the end state.

    I think we’d agree existentially there’s never an end state. We’re at a point where we don’t even have explicit CI/CD pipelines. We can commit code to a repository, the language can be inferred, we can give cues or signals to infer where we want it deployed, how we want it deployed, and I actually see ML and to an extent layers of AI just figuring out what to do with code at rest. So if you flash forward in 10 years and we’re truly applying these to technologies at scale in the cloud, I’d just change a line of code.

    That change automatically is delivered to production and AI and ML is helping us do that. So that’s sort of my dream. I don’t hit compile, I don’t hit build, I don’t build out stages and workflows. I just change code and that’s running in a system somewhere.

    Hurwitz: So don’t you also want to have the ability to say before you say – you look at what’s happening, and don’t you want to sort of at least at this stage say are you sure you want to do that? Are you sure you want to delete that pile?

    Dawson: Yes.

    Hurwitz: So until we get to the point – because you have to be able to trust that the system is smart enough to understand if I make this change what cause will that unleash? Because we’re not dealing with a perfect world in DevOps by a long shot.

    Dawson: Yeah. I do want that. I want protection. I want it to know where the vulnerabilities are and warn me, and I do think, Judith, that would be a prerequisite into this deploying code at rest or truly applying Dev AI.

    Shimel: Fair enough. Hey, guys, we are just about out of time. I think this was a great discussion. If there’s one thing I could take out of it though is that the crystal ball remains cloudy in terms of how this is all going to play out, and we’re going to have to wait for it to kind of come into focus. But it certainly will be an important part of software development, of operations going forward, and it’s an increasingly important part. But for now though we’re –

    Ashley: I think the crystal ball is a Magic 8 Ball. Ask again later.

    [Laughter]

    Shimel: Right, ask again – that’s a good one, Mitch. But for now, we’re going to call an end to this episode of DevOps Unbound. Again, thanks very much to Tricentis for their sponsorship. Thank you so much, Judith, thank you so much, Brian, for appearing here and we hope to see you on a future episode. Mitch, as always, great job riding shotgun with me.

    Ashley: Good to partner with you. Absolutely.

    Shimel: Absolutely. But this is it for this episode of DevOps Unbound. This is Alan Shimel. Have a great day, and we hope to see you soon on another DevOps Unbound as well as don’t forget every month we do a live roundtable open to you, our audience, with questions. So stay tuned for that as well. Take care, everyone. Bye-bye.

    [Outro Music]

    [End of Audio]

  • Intel Woos DevOps Teams with API and Processor Advances

    Intel Woos DevOps Teams with API and Processor Advances

    During the online Intel Innovation 2021 event, Intel announced today a unified Developer Zone for accessing application programming interfaces (APIs) that it makes available via a oneAPI toolkit to IT teams that want to more easily invoke a wide range of processor types and classes.

    At the same time, the company also revealed it is creating a set of oneAPI centers of excellence that will make it easier for DevOps teams to consume those APIs. Partners participating in that initiative include Oak Ridge National Laboratory, University of California Berkeley, University of Durham and University of Tennessee. Intel will also make the Intel Graphics Visualization Institutes of Xellence part of this program.

    Next year, Intel is also promising to deliver oneAPI 2022 toolkits that will add 900 additional capabilities including an ability to develop applications for CPUs and graphical processor units using what Intel described as the first unified C++/SYCL/Fortran compiler.

    The company is also planning on making available Data Parallel Python tools in addition to expanding its Advisor accelerator performance modeling tools to include support for VTune Flame Graph to visualize performance hot spots.

    There will also be additional oneAPI integrations to add support for Microsoft Visual Studio Code and the Microsoft Windows Subsystem for Linux 2 platform. Intel also created an Intel oneAPI AI Analytics toolkit to enable out-of-the-box AI development that is supported by workstations running Linux from Dell Technologies, HP and Lenovo. Additionally, Microsoft and Intel have agreed to create a complete data science toolchain to Windows 11 that will become part of the Surface Laptop Studio framework for building applications.

    Greg Lavender, chief technology officer, senior vice president and general manager of the software and advanced technology group at Intel, said it’s critical to make sure that DevOps teams add support for the acceleration engine and extensions that Intel makes available within its processors to the runtime environments they deploy. Otherwise, developers will never be able to routinely invoke those capabilities to build next-generation applications.

    The company also revealed that next-generation Intel Xeon Scalable Processors, code-named Sapphire Rapids, will have additional acceleration engines to both simplify deployments at scale and optimize processors’ core utilization in a way that reduces power consumption. Overall, Intel is promising up to a 30x total performance gain for artificial intelligence (AI) applications running on these processors.

    Other hardware advances announced today include a 12th generation Intel Core family based on 7-nanometer processors and a Mount Evans project through which Intel is collaborating with Google Cloud to build processors based on application-specific integrated circuit (ASIC) chips.

    The company also unveiled an Intel ArcTM Alchemist family of graphics systems on chips (SoCs) that take advantage of machine learning algorithms to optimize performance and touted an Intel Tofino fabric processor (IFP) that adds intelligence to network switching via support for P4 programming tools.

    Finally, the company noted that an Aurora supercomputer, due out in 2022, will exceed two exaflops of peak double-precision compute performance.

    As Intel seeks to regain the processor high ground from rivals such as NVIDIA, ARM and AMD, it’s clear that the future of IT will be defined by a broad range of processor classes that all have unique capabilities. The challenge now is deciding which of those capabilities to actually make available to developers that are largely dependent on the runtime environment that DevOps teams decide to make available.

  • BMC Looks to Advance ServiceOps Approach to Managing IT

    BMC Looks to Advance ServiceOps Approach to Managing IT

    During an online BMC Exchange event, BMC announced it expanded its portfolio of IT management offerings as part of an ongoing effort to unify traditional IT service management and DevOps processes under an integrated ServiceOps framework.

    The latest additions to the BMC portfolio includes an update to its Control-M workload automation platform that adds observability tools for monitoring application and data workflows along with additional integrations for cloud services such as AWS Glue, Google Cloud Dataflow and Function and Microsoft Azure Data Factory and platforms such the data lake from Databricks.

    BMC is also making available a preview of a Control M Python client that will extend the reach of the workload automation platform to the code data science teams employ to build artificial intelligence (AI) models.

    In addition, BMC is adding a BMC Helix Digital Workplace studio to make it easier for IT teams to customize the software-as-a-service (SaaS) platform it provides for IT service management (ITSM). Finally, BMC is also making available a version of BMC Helix that is optimized for communications service providers.

    BMC CEO Ayman Sayed said overall the current emphasis on digital business transformation is driving a need to converge the management of multiple IT platforms as organizations reinvent how core processes work across their organization. It’s not possible to drive that level of reengineering across multiple IT platforms without centralizing the management of those platforms using a ServiceOps framework that unifies DevOps and existing ITSM platforms, he noted.

    At the same time, Sayed said organizations need to invest more in artificial intelligence to automate IT operations, also known as AIOps, to augment IT staff that is hard-pressed by the need to manage both emerging and legacy IT platforms. The latest investment BMC has made in AIOps came earlier this month with the acquisition of StreamWeaver, a provider of a set of tools that make it easier to collect massive amounts of data that can be used to more easily train AI models.

    It’s too early to say to what degree IT management processes might become unified. In addition to centralized IT teams, most organizations have business units that often drive their own IT initiatives. However, as organizations realize how many platforms a digital process needs to access the need to centralize the management of IT becomes more apparent. The issue each organization will need to determine is the degree to which that centralization needs to occur.

    It’s clear in the wake of the COVID-19 pandemic that many IT organizations have never been more agile. In some cases, those IT teams are now able to drive a rate of change that is too fast for many businesses to even absorb. In fact, it’s arguable that entire businesses will need to adopt DevOps principles to manage that rate of change.

    In the meantime, IT teams will need to take a harder look at how much time is being spent on manual tasks that could be automated in a way that enables them to be lot more productive than they are today.

  • Observability Vs. Monitoring: What’s the Difference?

    Observability Vs. Monitoring: What’s the Difference?

    As more and more IT organizations pivot from strategies rooted in monitoring to ones that aim to achieve observability, one of the first questions that teams need to answer is, “What is the difference between the two?”

    That’s a somewhat loaded question because there are some differences of opinion out there regarding what, exactly, distinguishes monitoring from observability. But in general, the differences can be distilled into two main points, as we will explain.

    What is Observability and What is Monitoring?

    The first step in understanding the difference is to understand what each term means on its own.

    The classic definition of observability is that it is the use of external data outputs to understand the internal state of a system. In the IT industry specifically, observability could be defined as the use of logs, metrics and distributed traces to understand the state of a complex software system.

    Meanwhile, monitoring is the process by which data is collected from a system. In IT, monitoring is how teams collect logs, metrics and traces and move them to a place where they can be analyzed.

    Similarities

    There are some obvious similarities between the two. Both involve (at least in part) the collection of diverse sets of data. Both also serve the goal of helping teams identify problems within their software stacks and deliver a high-quality user experience.

    Two Key Differences

    But the similarities end there. Ultimately, monitoring and observability are distinct concepts and processes, with two main differences that distinguish them from each other.

    Monitoring collects data. Observability interprets it.

    The first is that observability focuses on interpreting and understanding data, whereas monitoring is merely the collection of data.

    In this sense, you can think of monitoring as one of the processes that makes observability possible. But observability requires more than monitoring. In addition to collecting data, observability also involves the correlation of data from multiple sources and the identification of relevant patterns or anomalies within that data.

    Monitoring Tells you What is Wrong. Observability Tells you Why it’s Wrong

    The second main difference is that monitoring simply alerts you when something goes wrong. Observability goes further by helping you understand why it’s wrong and how to fix it.

    For example, a monitoring tool might tell you that your application’s response rate is no longer adequate. But you need observability to figure out which specific microservices within the application are causing the problem. Using that information, you can plan and execute an effective response to reliability issues using an incident management platform.

    With monitoring alone, you only know that something is broken, not how to fix it.

    Observability and Monitoring: Better Together

    Although it’s common to speak in terms of “observability versus monitoring,” the reality is that you can’t have observability without monitoring. (You could monitor without observing, but doing so would significantly reduce your ability to understand and resolve problems quickly.)

    So, don’t think of it as an either/or proposition. Think of them as concepts and practices that go hand-in-hand, even if they perform different functions.

  • CircleCI Adds Test Insights Module to CI/CD Platform

    CircleCI Adds Test Insights Module to CI/CD Platform

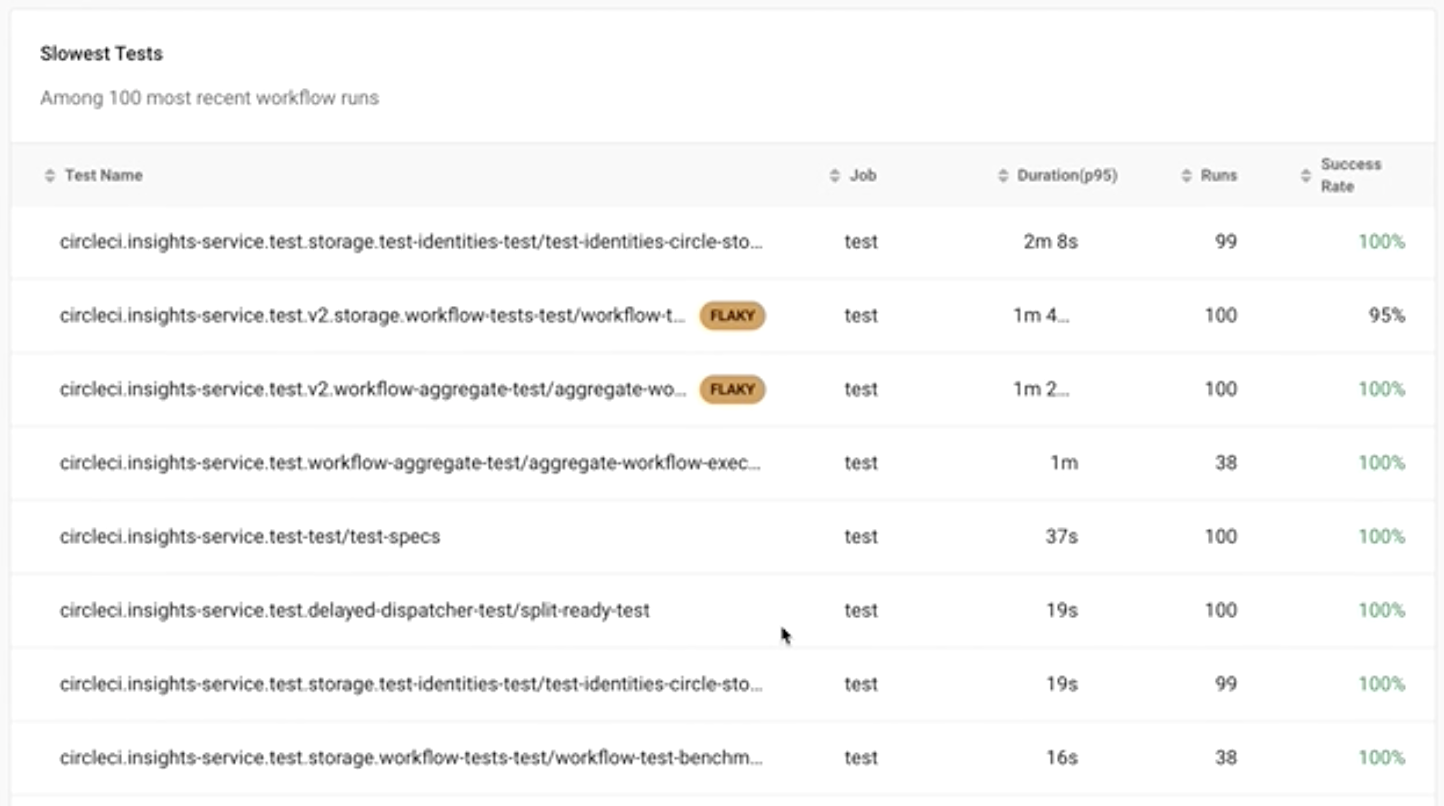
    CircleCI today announced it has added a Test Insights capability to its continuous integration/continuous delivery (CI/CD) platform to make it easier to identify tests that are either taking too long to run or simply exhibiting some form of anomalous behavior.

    Dawit Gebregziabher, product manager for data insights at CircleCI, said Test Insights is designed to make it simpler for IT organizations to shift more responsibility for testing further left toward DevOps teams that identify issues as applications are being built on the CircleCI platform.

    Each organization will still need to determine what tools to employ to create a test, but once it starts running, the Test Insights module will be able to surface the tests that, for one reason or another, are problematic to execute, he added.

    Test Insights, for example, will flag flaky tests and identify the longest-running and most failed tests. It will also enable DevOps teams to identify performance changes over time to pinpoint changes in application behavior.

    Finally, DevOps teams can track benchmarks at the organization, workflow and job level, as well as metrics for mean-time-to-recovery, throughput and durations for 24-hour, 7-day and 30-day windows of time.

    The challenge DevOps teams often encounter is a test may be run even when it’s apparent the application will fail. Test Insights makes it feasible for DevOps teams to manage the testing process much more efficiently, said Gebregziabher.

    It’s not quite clear how far testing is shifting left. There’s no doubt more developers are testing their code before it is loaded into a production environment to hopefully avoid issues that will only become more expensive to fix later. Other organizations have dedicated software engineers to create testing processes that are tightly integrated with CI/CD pipelines, noted Gebregziabher.

    However, many large enterprise organizations continue to also hire and retain dedicated application testing teams that are trained to identify issues that might either adversely affect the end-user experience or run afoul of compliance requirements.

    Regardless of who does what kind of testing, however, it’s clear there’s a lot more focus on addressing issues earlier when they are much less expensive to fix. The goal should be to make it easier to optimize when tests should run based on probabilities that ultimately reduce the time wasted running tests that either will fail or are, for one reason or another, flawed.

    Developers, of course, are all equally committed to running tests, so organizations will need to determine for themselves how far to shift that process left. However, at the very least, DevOps teams should be able to identify patterns that might indicate there is a need for additional developer training. After all, it’s unlikely a developer is going to understand there’s an issue until some meaningful metrics are shared.

    In the meantime, the more testing that occurs at a faster rate the more likely it becomes that an organization can provide a superior application experience the first time—and every time—an application is built and deployed.

  • InfluxData Simplifies AppDev for Time-Series Databases

    InfluxData Simplifies AppDev for Time-Series Databases

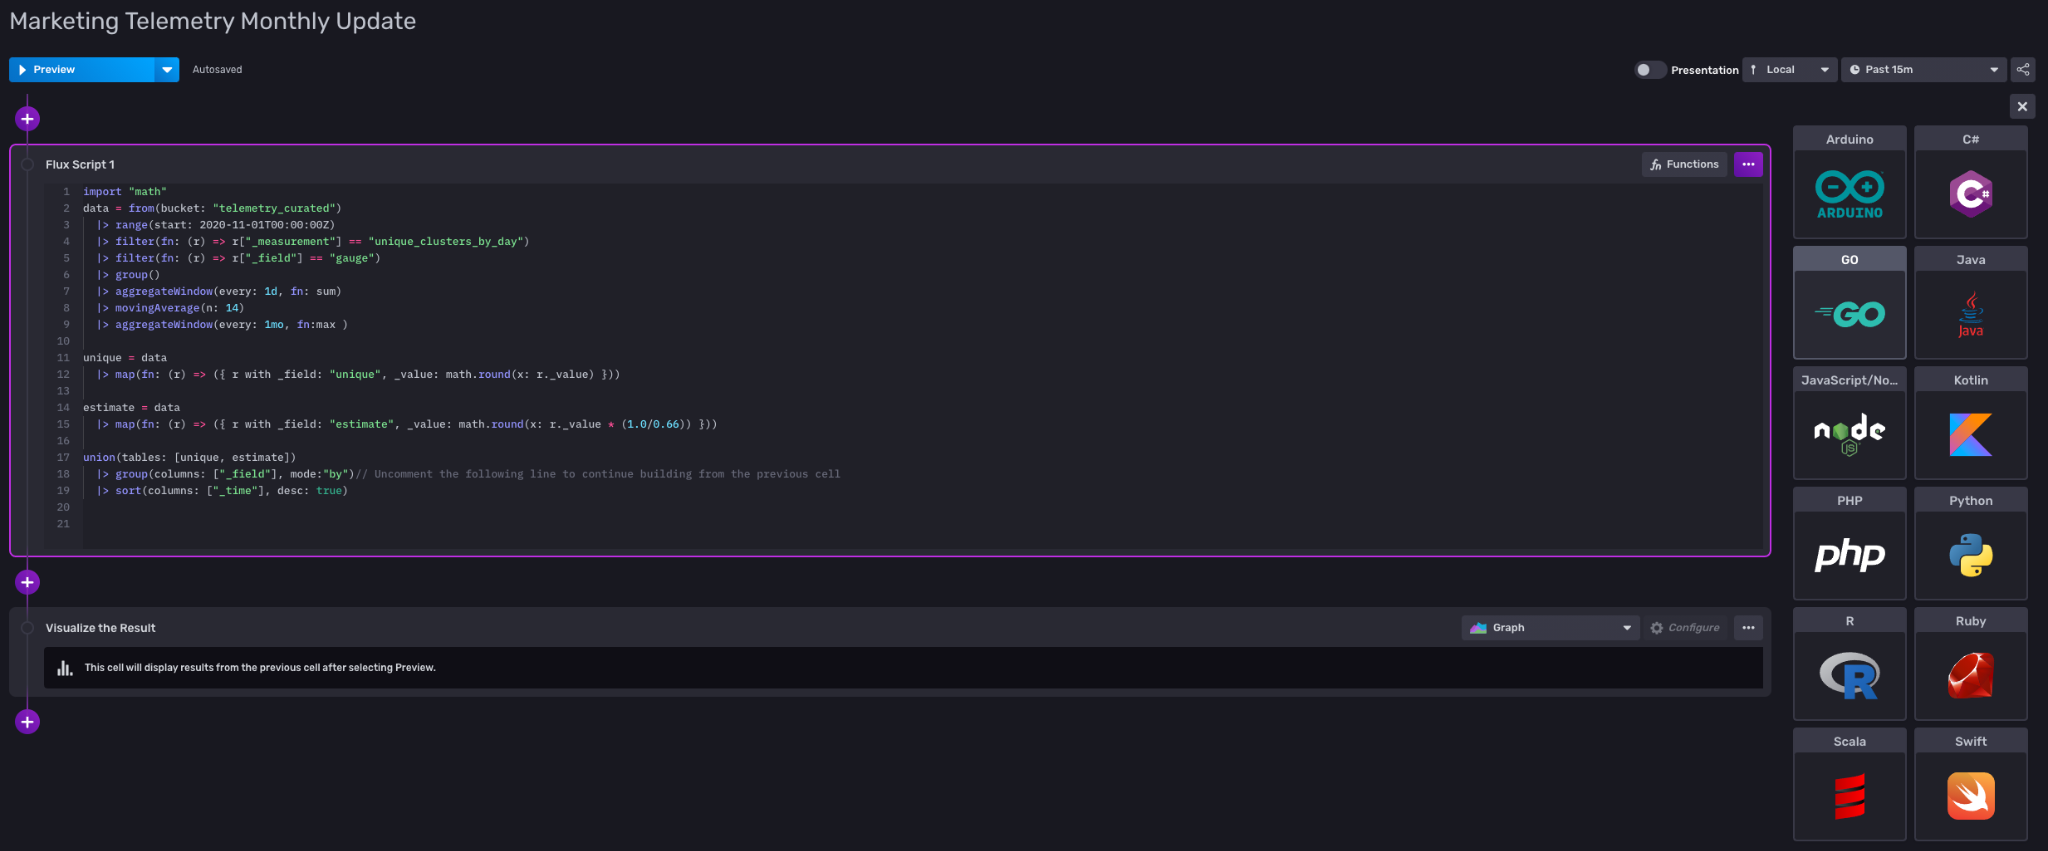
    During an online InfluxDays North America 2021 Virtual Experience conference, InfluxData today expanded the capabilities of its application development tools using its Flux query language on top of its time-series database.

    The company has enhanced its InfluxDB Notebooks tool to enable developers to quickly set up an alert, build a task or write a Flux script without having to leave their browser.

    In addition, developers can compose Flux queries to be included in client code that can then be autogenerated within applications written in more than 10 different programming languages. There is now also an extension of Visual Studio Code that makes it simpler to create Flux scripts, query InfluxDB, create Flux tasks and manage buckets.

    Finally, InfluxData added the ability to explicitly define the schema of a bucket within InfluxDB to safeguard against unwanted changes; an application programming interface (API) tool, dubbed API Invocable Scripts, to make it simpler to define parameterized Flux scripts and the ability to send notifications from Alerta, WebEx Teams and ServiceNow to the InfluxDB Cloud platform.

    Tim Hall, vice president of product for InfluxData, said the overall goal is to reduce the level of complexity developers encounter when building applications that run on a time-series database. Many of those applications are now core to digital business transformation initiatives that require data to processed and analyzed over time. In effect, time-stamped data adds yet another dimension to any application, noted Hall.

    Time-series databases are typically employed by either an independent software vendor (ISV) to create, for example, a monitoring application, or an enterprise IT team that is building an application that lends itself to data that needs to be tracked over some period of time.

    In most instances, applications built on a time-series database are being deployed alongside, for example, relational databases that are generally invoked using SQL. As a result, InfluxDB has made it simpler to join data across relational and time-series data via SQL integrations the company added to Flux, noted Hall.

    DevOps teams, of course, are not always anxious to add another database they need to support, but as applications continue to evolve, more organizations are employing a mix of purpose-built databases to develop applications as the volume of data that organizations are trying to manage and analyze continues to grow.

    In the longer term, it’s clear time-series databases will play a critical role in driving digital business transformation initiatives. The challenge most organizations are now struggling with is determining which of these initiatives to prioritize. A time-series database coupled with the developer tools provided by InfluxData will enable IT teams to build the applications that drive those processes much faster, said Hall.

    In the meantime, IT teams would be well advised to at least become more familiar with time-series databases, because knowing the time when an event occurred is becoming a bigger application requirement. After all, knowing when something happened is now just as important as the record of what actually occurred.

  • Eclipse Foundation Launches Open Source Edge Computing Initiative

    Eclipse Foundation Launches Open Source Edge Computing Initiative

    The Eclipse Foundation in collaboration with the OpenAtom Foundation today launched the Oniro project and working group to create an independent implementation of OpenHarmony, an open source operating system.

    Created by the OpenAtom Foundation, the OpenHarmony operating system is based on a HarmonyOS originally created by Huawei. It is designed to support multiple kernels but uses the Linux kernel if a device has a large amount of memory.

    It also includes a DSoftBus capability for integrating physically separate devices into a single logical super device that enables one device to control others in addition to facilitating data sharing among distributed devices.

    Huawei, in collaboration with Linaro, Seco, Array, NOITechPark and Synesthesia, has also been contributing to a continuous integration/continuous delivery (CI/CD) platform that is part of the larger Oniro project.

    Mike Milinkovich, executive director of the Eclipse Foundation, said the goal is to provide a common layer of abstraction platform that can be employed across a wide range of embedded systems that are typically being deployed at the network edge. That level of fragmentation surrounding platforms that don’t provide a lot of significant differentiated value only results in slowing down the deployment of applications, noted Milinkovich.

    As part of that effort, a dedicated working group has been created to provide a vendor-neutral structure through which contributions to the project can be made with greater transparency. The OpenAtom Foundation was created in Beijing last year with the support of Alibaba, Baidu, Huawei, Inspur, Qihoo, Tencent and China Merchants Bank. The alliance with the Eclipse Foundation brings more traditional governance rules for building open source software to the OpenHarmony project.

    In general, DevOps teams should be tracking the development of proposed de facto standards for edge computing platforms closely. More applications are now being deployed on edge computing platforms that make it possible to process and analyze data at the point where it is being created and consumed. The DevOps challenges associated with building and deploying applications across a highly distributed computing environment are considerable.

    In many cases, organizations that never really attempted or mastered continuous delivery of applications and their associated updates will be sorely challenged when it comes times to support hundreds, possibly thousands of applications, running on embedded systems based on a wide range of processors.

    In addition, many of those same DevOps teams will start to see traditional batch-oriented applications being superseded by applications based on event-driven architectures that process data in near-real-time. In most cases, those applications are going to be built on microservices-based applications that are typically more challenging to build and deploy than a traditional monolithic application.

    Arguably, IT organizations are on the cusp of a new era of IT that assumes most organizations have not only mastered DevOps best practices but are now also embracing DevSecOps best practices to secure those application environments.

    It may be a while before the open source software that will be developed by the Orino project finds its way into production environments, but it should be apparent that reducing complexity at the network edge should be a high priority for all DevOps teams heading into 2022.