Category: DevOps and Open Technologies

Editorial Calendar for February 2016

  • CNCF Provides Jaeger Distributed Tracing Update

    CNCF Provides Jaeger Distributed Tracing Update

    The Cloud Native Computing Foundation (CNCF) has made available a report detailing the progress being made around the open source Jaeger distributed tracing software. Among other things, the report notes there are now more than 300 organizations contributing to the project.

    Jaeger is designed to provide a framework for monitoring microservices-based applications in a way that captures every interaction as part of an effort to simplify troubleshooting.

    Originally developed by Uber, Jaeger has almost 2,000 contributors. Developers from Uber and Red Hat make the bulk of those contributions., while other developers work at Ryanair, IBM, Ticketmaster and CloudBees.

    Thus far, there have been nearly 40,000 contributions, 4,300 code commits and 3,200 pull requests for Jaeger.

    Yuri Shkuro, a software engineer at Uber who created and maintains the Jaeger project, said as open source agent software in the form of OpenTelemetry, a separate sandbox-level initiative also hosted by the CNCF, gains traction, the more feasible it will become for DevOps teams to embrace distributed tracing. Currently, most DevOps teams are dependent on sampling techniques typically employed via an application performance management (APM) platform. While that approach can indicate there might be an issue, distributed tracing makes it easier to pinpoint the precise problem.

    That’s critical because many DevOps teams can spend hours, if not days, trying to identify the source of an issue that often only takes a few minutes to fix. The trade-off is that distributed tracing collects a lot more data than sampling, so IT teams will need to decide how long they may want to store that data. Most organizations will only store tracing data that identifies anomalies based on a reasonable retention schedule rather than allocating storage resources to what could become massive amounts of tracing data, noted Shkuro.

    Providers of commercial observability platforms have been embracing OpenTelemetry to provide distributed tracing services, so it’s not clear to what degree IT organizations will opt to deploy Jaeger on their own or access a managed Jaeger-based service.

    Regardless of how they are invoked, next-generation observability platforms based on Jaeger should become more affordable at a time when microservices-based applications are being more widely deployed. Given the inherent complexity of those applications, observability platforms that are a core tenet of any best DevOps practice become a requirement. In comparison, the use of ALM platforms was typically limited to only the most mission-critical applications because of the costs associated with deploying proprietary tools.

    It may be a while before every application is instrumented by default. In the meantime, Shkuro said the Jaeger project is looking to recruit additional maintainers. As is often the case with any open source project, there are plenty of contributors. IT professionals willing to volunteer to maintain a project are often more scarce.

  • CDF Officially Graduates Jenkins CI/CD Platform

    CDF Officially Graduates Jenkins CI/CD Platform

    The Continuous Delivery Foundation (CDF) announced today that the open source Jenkins continuous integration/continuous delivery (CI/CD) has officially graduated.

    Jenkins was donated last year to the CDF, an arm of The Linux Foundation, along with Jenkins X, a CI/CD platform for Kubernetes; Spinnaker, a CD platform; and Tekton, a framework for building pipelines that will be employed as the foundation for next-generation CI/CD platforms.

    Tracy Miranda, CDF Governing Board Chair and director of open source community at CloudBees, said that although Jenkins traces its lineage back to 2004, the CDF wanted to make sure the same requirements that are being applied to graduate other projects are applied to Jenkins despite its obvious maturity. The CDF requirements for graduating a project are to demonstrate growing adoption, have an open governance process, feature maturity and a strong commitment to community, sustainability and inclusivity.

    The CDF also today published a public road map for Jenkins. Key features include improving the user/administrator experience and tighter integration with cloud platforms. Work has also begun on Operator tools for simplifying the deployment of Jenkins on a Kubernetes cluster.

    Longer-term, the CDF is focused on expanding the adoption of Tekton-based Trigger pipelines across both Jenkins and Spinnaker. Tekton pipelines are easier to create and can be reused across multiple platforms. Jenkins X already employs Tekton-based pipelines, which were originally developed by Google.

    The founding members of the CDF are CloudBees, Google, CapitalOne, CircleCI. Fujitsu, Huawei, IBM, JFrog, Netflix and Salesforce.

    In the nearer term, Miranda said the CDF is also attempting to standardize the glossary of terms applied to DevOps processes. The goal is to provide something akin to a “Rosetta Stone” that will help make DevOps more accessible to IT professionals just starting their journey.

    In theory, at least, platforms such as Jenkins X accelerate the development of microservices-based applications running on Kubernetes clusters. In practice, however, many IT teams continue to use Jenkins and other CI/CD platforms to build both monolithic and microservices-based applications.

    As Kubernetes gains momentum, however, the way applications are deployed may also evolve. Today most DevOps teams push application code from a CI/CD platform on to a target system. However, if Kubernetes is deployed on multiple platforms it may become easier to automate the delivery of code by enabling Kubernetes clusters to pull code from CI/CD platforms on demand.

    As organizations transition to building and deploying microservices-based applications, it’s also apparent there will be a much greater need to rely on best DevOps practices to manage all the dependencies that will exist between each microservice. Legacy application development processes will not be able to keep pace with the rate at which microservices based on containers are ripped and replaced.

    Of course, it’s not clear to what degree organizations may prefer to stay with Jenkins, which is built on a Java virtual machine, versus adopting Jenkins X or a CD platform such as Spinnaker. However, as the interoperability between these platforms continues to improve, it may not be surprising to one day find DevOps teams employing a mix of all of them across different application development projects.

  • Cassandra Update Boosts Recovery Speeds

    Cassandra Update Boosts Recovery Speeds

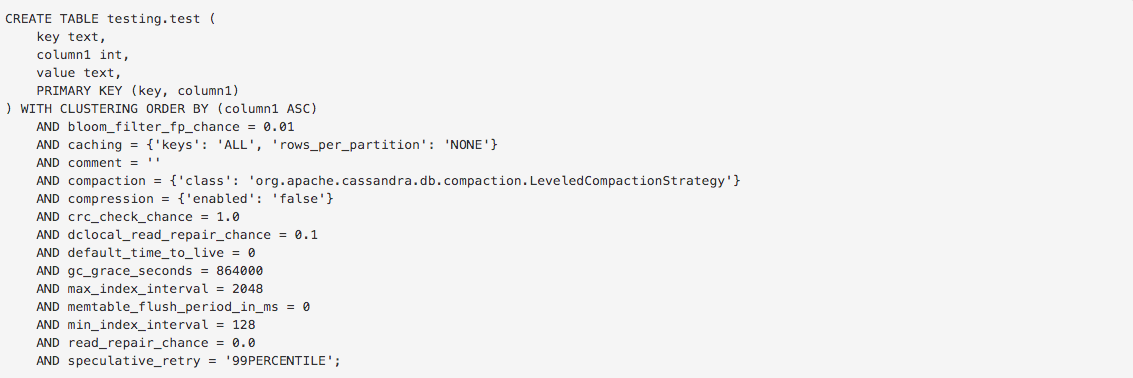
    Apache Cassandra is a row-oriented NoSQL database created by developers working at Facebook. With elasticity as one of its key features, open source contributors have added new streaming capabilities to Cassandra 4.0 for its beta launch. These improvements have been shown to enable the database to stream data between nodes at speeds up to five times faster than in the past.

    What this means is that if a node on a network crashes, for example, the data can be transferred that much more quickly to another replacement node. Conversely, during peak load data times, different nodes on the cloud or on-premises servers can more readily and quickly manage potential data overflows for improved operations elasticity, Cassandra’s contributors say.

    Elasticity—or lack of—was often seen as a weak point in previous Cassandra releases. Indeed, elasticity improvements, geared for DevOps taking advantage of distributed microservices environments are “really a key point,” said Josh McKenzie, a Cassandra committer and member of the project management committee. McKenzie is also the lead of open source strategy and vice president of software engineering for DataStax, which has historically funded the bulk of Cassandra’s contributions and support.

    The new streaming capability also could potentially serve as a welcome feature for database management, especially in highly distributed stateless environments of Kubernetes and microservices, said Clive Longbottom, an analyst for Longbottom Associates.

    “On the first one, this seems like an excellent update. It makes the ‘eventual consistency’ of Cassandra less of an issue, and the more guaranteed timescales of recovery across a range of scenarios is welcome,” Longbottom said. “I would hope that such a major change will get more to consider Cassandra for such data work—it can be, when implemented correctly and the right jobs put on it, an effective data platform.”

    The new streaming speed is made possible because the data is able to bypass the use of the servers’ CPUs, McKenzie said.  “Being able to get anywhere from four to five times the throughput when bootstrapping a new node on recovering from failure or scaling clusters up and down means the process is now a totally different ballgame.”

    An example of a six-node cluster setup.

    For DevOps teams, this means Cassandra’s modifications—including its now less complex and shorter-in-size code configurations—make for faster streaming speeds when bootstrapping a new node or during disaster data recovery. “Running repair and dealing with [server failures] means you don’t have to rebuild data so much and you can now run at line speeds as fast as your network,”   McKenzie said.

    The developers also sought to reduce the number of hours spent on performing what used to be an especially onerous task of transferring data to and from different database sources in a network. Multi-cloud and mixing and matching legacy and cloud environments further complicated the process.

    In other database platforms, the process of doubling database capacity can take five to seven months. Building in part on steady improvements past releases have offered, Cassandra 4.0 now can complete the process in just a few hours, McKenzie said. “I love hearing about how people can now run Cassandra with a script and it just takes maybe six hours on a Saturday morning with one person and one with one script instead of a whole weekend,” McKenzie said.”So it’s just really doubling down on those unique strengths that make Cassandra such a good fit for exactly where we are in the world today: in the state of always scrambling with massive influxes of data.”

    The committee members also sought to extend the timeline of the final beta release. Instead of adding more incremental improvements while attempting to accelerate the release cycle, Cassandra’s 4.0 contributors sought “to really take our time, making sure that we were hammering down and smoothing out all the dents,” McKenzie said. “We wanted to get things to where we have a really really stable platform to iterate on very rapidly.”

  • Okta Offers PASETO as Alternative to JSON Tokens

    Okta Offers PASETO as Alternative to JSON Tokens

    Okta today launched an open source library for using Platform-Agnostic Security Tokens (PASETO) as an alternative to JSON Web Tokens (JWT) to authenticate end users.

    Randall Degges, head of evangelism for Okta, said PASETO is quickly emerging as an easier, more secure implementation of the JWT specification. PASETO is a draft specification created by Scott Arciszewski that reduces the scope of the Javascript Object Signing and Encryption (JOSE) family of specifications in a way that makes it easier for developers to embrace tokens to secure application access.

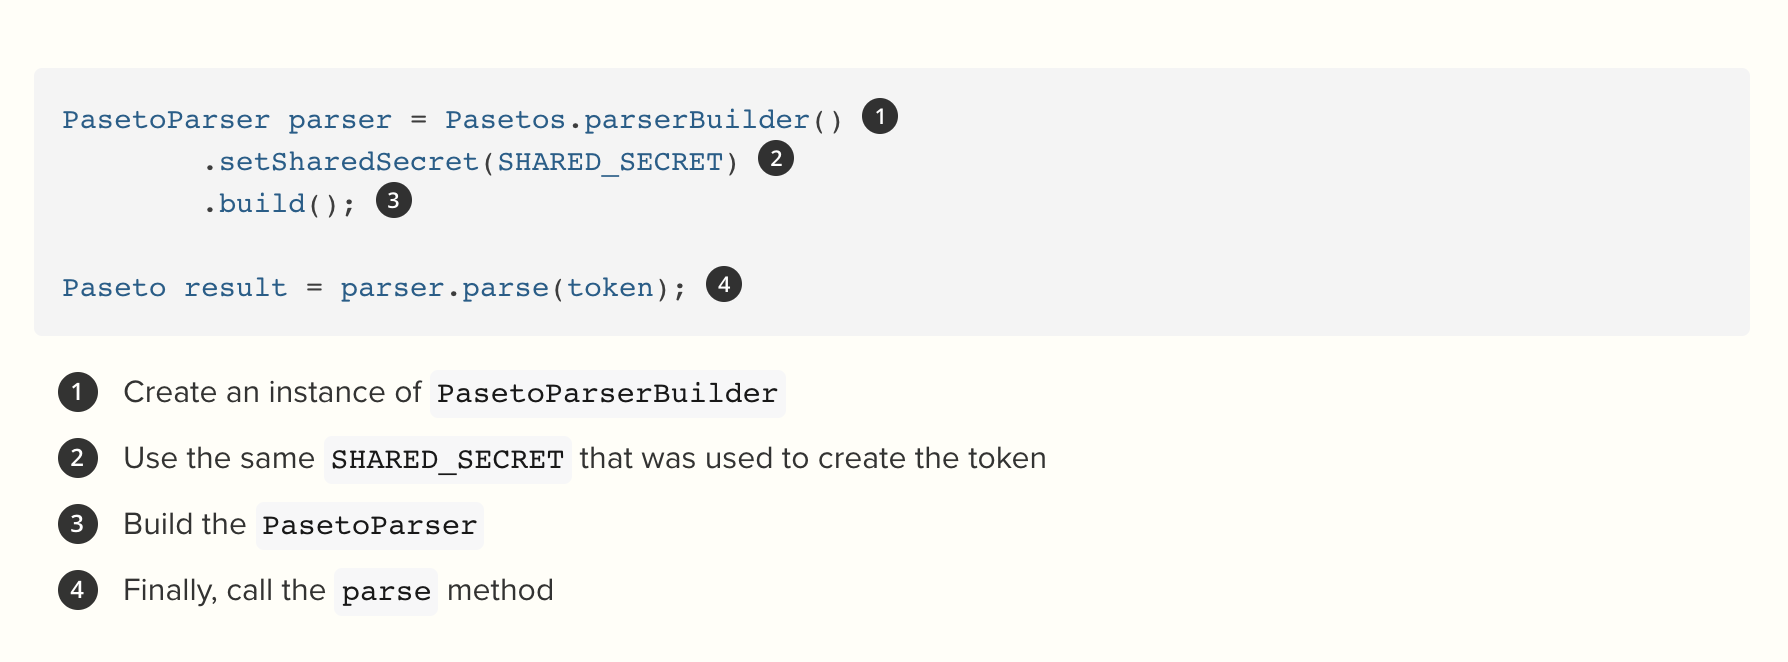
    Okta is trying to make it easy for developers to employ PASETO using a library written in Java, dubbed JPASETO, that has half the lines of code JWT token written in Java and is supported by a vendor, he said.

    While JWT tokens have been widely adopted, they are easy to misconfigure, which Degges noted has resulted in the recent discovery of many JWT vulnerabilities. Part of the fault for those vulnerabilities lies with the JWT specification itself, he added; JWTs support a wide range of cryptographic algorithms, including an option that employs no cryptography at all.

    In contrast, Degges said PASETOs are more cryptographically resilient and far easier to employ. The PASETO specification defines two types of tokens: local and public. Local tokens are always symmetrically encrypted with a shared secret key, which means no one can view the contents of a local PASETO unless they have the correct secret key. Public tokens are readable by anyone and are validated with a public key. There is no “none” option; there can’t be a security token that is not encrypted, he said.

    All PASETO formats are designed to be tamper-proof. The entire message is authenticated, so validation will fail if anything in the token changes, added Degges.

    That approach ensures higher levels of application security while at the same time aiding in the adoption of best DevSecOps practices using Okta’s JPASETO library, which can be incorporated easily into the application development process, he noted.

    In recent years software tokens such as JWT have gained traction as a way to implement two-factor authentication in place of creating a session in the server and returning a cookie. When a user successfully logs in using their credentials, a JSON Web Token is returned and must be saved locally.

    Software tokens, however, can still be vulnerable to attacks that either duplicate the underlying cryptographic software or phishing attacks that trick end users into giving up a password. There is no such thing as perfect security; however, software tokens provide a critical layer of security that should be employed much more widely.

    It’s not clear to what degree PASETO will further that goal. Many organizations may even mandate the use of either JWT or PASETO as part of their overall approach to DevSecOps. Regardless of approach, it’s clear that continuing to rely on sessions and cookies to authenticate end users is an antiquated approach to authentication that is not only more difficult to implement and manage but also ultimately less secure.

  • Snyk Tool Prioritizes Open Source Vulnerabilities

    Snyk Tool Prioritizes Open Source Vulnerabilities

    Snyk today announced it has enhanced the ability of its namesake vulnerability scanning tool by adding the ability to identify which open source vulnerabilities should be fixed first using a scoring tool that leverages data science and machine learning algorithms to analyze code.

    In addition, DevOps teams can now take advantage of automated pull requests to fix those vulnerabilities.

    Finally, DevOps teams also can define policies that require certain classes of vulnerabilities to be fixed whenever they are identified.

    Aner Mazur, chief product officer for Snyk, said given the number of open source modules employed and the dependencies that exist between them, staying current on patches and updates has become a major challenge. The only way to achieve that goal is to rely more on tools that help automate that process, he said.

    These days it’s easy for development teams to feel overwhelmed by patch requests to fix open source security vulnerabilities. The trouble is, not all those requests are of equal weight. Snyk provides tools that enable developers to understand which vulnerabilities are of the highest severity and how they might impact their code.

    Armed with that insight, Mazur said, it then becomes possible to prioritize remediation tasks within the context of a DevSecOps process. Otherwise, developers will simply fix vulnerabilities regardless of relevance as time allows. Developers may remediate dozens of bugs only to discover that a critical flaw that had been left unaddressed led to a major compromise.

    It’s also not uncommon for DevOps teams to fail to appreciate dependencies between open source code modules. When patches to code are applied in the wrong order, an application can break, resulting in DevOps teams having to start the whole process over. The prioritization tools provided by Snyk prevent that from occurring, Mazur said.

    In the absence of any ability to prioritize vulnerabilities, developers eventually become inured to patch requests because they don’t know whether their patching efforts are making any real difference, he added.

    Worse yet, all the time spent on patching low-level vulnerabilities reduces the amount of time developers have available to write new application code. In fact, one of the paradoxes of DevOps is as the number of applications deployed increases so too does the amount of time spent debugging them. Before too long, a DevOps team can find itself spending more time fixing existing code than developing new applications.

    As DevOps teams become more dependent on open source code, they benefit from the collective security efforts of all the contributors to that project. The result is more secure code, as patches to remediate specific issues are made available. The challenge now is finding a way to automatically apply those updates in a way that doesn’t conspire to slow down the overall application development process. Achieving that goal requires visibility into what is now a multitude of open source projects that no DevOps team is ever going to be able to consistently achieve on its own.

  • Google Exposes Old Wounds in Open Source Community

    Google Exposes Old Wounds in Open Source Community

    Things boiled over a bit last week with the announcement that Google launched the Open Usage Commons (OUC) consortium (see Mike Vizard’s article here). The announcement and subsequent angst it has caused has upset what had been a pretty stable environment that helped open source software become the dominant force in development and IT. While on its face OUC is about trademarks and usage guidelines, but make no mistake: This is about Google (and perhaps others) disagreeing with the management and direction of The Linux Foundation/Cloud Native Computing Foundation (CNCF).

    Hand-in-hand with the OUC, Google also announced it was making changes in the board composition of the Istio project. A new formula based on code contributed by companies, as well as community seats selected by the community of other contributors, would determine who governs the project.

    Together, this represents a clear bifurcation of managing the code of a project and the trademarks/IP of the project. This is not a new concept in open source, but in recent years has been seldom used. In probably the most famous example of this setup, Linus Torvalds controls a company that still owns the Linux mark, which the Linux Foundation manages it for him. It is separate from the Linux project itself, though.

    The concept of the code being open and free while the project owners retaining the IP and trademarks was very much the norm in open source years ago. However, it led to many companies’ reluctance to contribute code to projects for which they had no say in the governance or usage of the marks. One of the benefits of the foundations such as CNCF, Cloud Foundry, Eclipse and others was that under their model, everyone had access to the same code base and mark usage rules. What you did on top of that was up to you. Ironically, this is the same argument we are hearing now regarding the changes to the Istio governing board and the OUC.

    Perusing the Twittersphere on this subject turns up a few other issues that may be at play here:

    • The CNCF and the Linux Foundation, by implication, may be a victim of its own success. The amount of money they have generated and their “marketing” profile seems to have turned some people off.
    • The CNCF/Linux Foundation model of allowing major corporate contributors to, in essence, buy board seats and having just a minority of “at large” seats open to the community favors the big, rich vendors over the rest of the pack.
    • New leadership at Google and Google Cloud are having second thoughts about turning over the fruits of their work to foundations that they eventually lose control over. Recent former Oracle management is being rumored behind this, though that is not confirmed. In this scenario, second doubts about Kubernetes and other Google-donated projects that are now out in the market without a Google edge are causing them to rethink their approach.
    • Companies that rely on these open source projects and historically are decent corporate members, such as IBM, have been caught in the open here as evidenced by their reaction to the Istio affair.

    What I do know is that the loser in all of this will be the community. Open source works best when there are stability and predictability over its future and governance. The broader the base of management and ownership of a project, the more willing corporate contributors are to participate and contribute. I would hate to see us return to the maze of the Cathedral and the Bazaar. I sincerely hope we are not seeing the end of the golden age of open source software.

  • How to Source Vulnerability Data for True DevSecOps

    How to Source Vulnerability Data for True DevSecOps

    Open source comes with code vulnerabilities that must be considered in the DevOps process

    The war between open source and “only proprietary code” is long over. Open source won the day by convincing the opposition of the benefits of joining the open source community. “Vulnerabilities in the Core,” a report published by the Linux Foundation and the Laboratory for Innovation Science at Harvard in early 2020, explained: “Open source has now become an integral component of the modern economy and is a fundamental building block of everyday technologies like smart phones, cars, the Internet of Things, and numerous pieces of critical infrastructure.”

    Development teams have embraced open source for its inherent strengths: efficiency, speed, quality and innovation. As one Gartner report puts it, “In most modern DevOps development projects, the majority of code used in an application is made up of open source.”

    But open source comes with code management responsibilities that DevOps teams need to consider. Open source has the same security risks that plague all software—bugs or other defects that could be exploited by hackers. While larger open source projects have communities that generally issue patches for vulnerabilities much more quickly than commercial vendors, thanks to thousands of “eyes” on the code, keeping open source software secure is not as simple as enabling auto-updates, as is done for much commercial software.

    Unlike commercial vendors that automatically “push” patches out to users, open source operates on a “pull” model. As patches are made available, consumers of the open source component first need to be aware that the patch is out there and then “pull” it from a repository to accomplish the needed update.

    The NVD and Its Timeliness Problem

    Public sources such as the National Vulnerability Database (NVD) are a good first step for information on publicly disclosed vulnerabilities in open source software. However, you need to keep in mind that there can be significant lags in data reporting, scoring and actionability of the data in an NVD common vulnerabilities and exposures (CVE) entry, with some research reporting an average 27 days between the initial announcement and NVD publication. The format of NVD records also makes it difficult to determine which versions of any given open source component are affected by a vulnerability.

    For example, the Linux vulnerability CVE-2016-5195, popularly known as Dirty Cow, was announced Oct. 19, 2016. Proof-of-concept code exploiting the vulnerability was available a full two weeks before the Nov. 10 listing for the CVE in the National Vulnerability Database. That’s two weeks in which anyone relying on the NVD would have been left in the cold.

    The problem is more recently reflected in the findings of the 2020 Open Source Security and Risk Analysis (OSSRA) report, produced by the Synopsys Cybersecurity Research Center (CyRC). Four of the top 10 vulnerabilities found in the audited codebases did not have CVEs associated with them at the time of the report’s publication. The vulnerabilities without CVEs included high-severity flaws in jQuery and FileAPI. Those security issues can be fixed with updates of the respective open source components, as can the majority of vulnerabilities listed in the CyRC OSSRA report. But, to patch any of those CVE-less vulnerabilities, you first need to be aware of them.

    The issues impacting the NVD’s ability to publicize security vulnerabilities make it unwise to rely solely on that organization for vulnerability information. While I’m not recommending abandoning the NVD, DevOps teams should look to a secondary source of information that will provide better notification of vulnerabilities affecting your codebase and, ideally, supplement notifications with technical details and upgrade and patch guidance.

    Augmenting NVD Vulnerability Information

    Many commercial software composition analysis (SCA) solutions can provide you with more timely, richer vulnerability data than the NVD alone, proactively finding issues and helping you fix them quickly when warranted. If you’re considering an SCA solution, you should ask your vendor what they offer in the form of security advisories and alerts.

    For example, consider the Common Vulnerability Scoring System (CVSS), an industry standard for assessing the severity of a vulnerability. The CVSS score (v2 and v3) provides an overall base score that takes both exploitability and impact into account.

    A robust SCA solution will provide a temporal score in addition to the CVSS base, exploitability and impact scores. Temporal scores take into account metrics that change over time owing to events that are external to the vulnerability. Remediation levels (“Is there an official fix available?”) and report confidence (“Is the report confirmed?”) can help temper the overall CVSS score to an appropriate level of risk.

    Similarly, an SCA solution should offer key Common Weakness Enumeration (CWE) classifications—a list of software or hardware weaknesses that have security ramifications—for all vulnerabilities, providing insight into the type of weakness being exposed. A CWE classification tells developers which type of weakness leads to the vulnerability in question.

    Information such as this can help you understand what you’re dealing with and aids in assessing the severity of the vulnerability for mitigation purposes. For example, a development team may prioritize a SQL injection differently than a buffer overflow or denial of service.

  • DevOps Deeper Dive: Google Roils Open Source Community

    DevOps Deeper Dive: Google Roils Open Source Community

    Google this week agitated the bulk of the open source community by launching the Open Usage Commons consortium to protect the trademarks of open source projects, starting with the Istio, Angular and Gerrit projects it launched.

    Launched in collaboration with SADA Systems and some independent contributors, the stated goal of the Open Usage Commons is to help open source projects assert and manage their project identity through programs specific to trademark management and conformance testing.

    Istio is a service mesh that runs on top of Kubernetes, while Angular is a web application framework. Gerrit is a code collaboration tool.

    Unlike previous open source projects that Google played a major role in developing such as Kubernetes, Google has yet to contribute these three projects to an open source consortium. That decision has members of the open source community now questioning Google’s commitment to open source software.

    In fact, IBM, which launched the Istio project in collaboration with Google, this week said the Open Usage Commons does not meet the level of open source governance IBM expects. Originally, IBM said the expectation was that Istio would be contributed to the CNCF once it achieved a level of maturity. That contribution would include Istio intellectual property and the trademark. Now IBM is encouraging Google to reconsider its Open Usage Commons approach.

    If Google continues to hold on to the intellectual property rights for open source projects such as Istio, those projects will become little more than a community project that Google exercises control over, said Priyanka Sharma, general manager of the Cloud Native Computing Foundation (CNCF), which oversees the ongoing development of Kubernetes, among other open source projects.

    “It’s not in the spirit of open source,” said Sharma. “I don’t think you can even call it open source.”

    Other open source initiatives will be hesitant to build on top of projects such as Istio if the intellectual property belongs to a single vendor, added Chip Childers, executive director of the Cloud Foundry Foundation (CFF). The trademark is never the main issue, he said.

    “The trademark is only part of the consideration,” said Childers.

    In the case of Istio, the decision to launch Open Usage Commons might also draw more attention to a Service Mesh Interface (SMI) project being advanced under the auspices of the CNCF. That interface promises to make it easier to rip and replace one service mesh for another.

    In the meantime, Google may be trying to maximize its investments in open source projects that until now have tended to benefit rivals more. In terms of consumption of cloud services based on Kubernetes, Google is a distant third at best to Amazon Web Services and Microsoft.

    In general, there are more open source projects than ever. However, some of the entities that launch those projects have complained that cloud service providers simply turn those projects into cloud services in a way that consumes most of the revenue opportunities any open source project might generate.

    Google now appears to be exacerbating those tensions further by trying to retain control over the open source project it leads, while selling services based on other open source software projects. It’s not clear to what degree this rift might drive a wedge between multiple open source factions. Google with this move may just drive more members of the open source community into the arms of AWS and Microsoft. However, for the moment at least, none of the projects covered by the Open Usage Commons trademarks are so critical that they could not be replaced by any one of several alternative projects that are truly open source.

  • CNCF Looks to Increase Open Source Sandbox Projects

    CNCF Looks to Increase Open Source Sandbox Projects

    The Cloud Native Computing Foundation (CNCF) today announced it has simplified the process it employs to enable open source software to become a sandbox project managed under its auspices.

    Priyanka Sharma, general manager for the CNCF, said the organization is looking to increase the number of open source projects that make up the cloud-native ecosystem. While the CNCF is best known for its efforts to govern the development of Kubernetes, the organization’s mission spans a wide range of cloud-native technologies. Many of those projects are now applicable to both microservices-based and monolithic applications that can be deployed in the cloud or in an on-premises IT environment.

    Key changes to the sandbox process include a simplified submission process using an application that asks the project owners how their project fits as part of the cloud-native ecosystem. Applications are listed in a spreadsheet available publicly for comment, with review by the Technical Oversight Committee (TOC) scheduled on a bi-monthly cadence. The existing Special Interest Group (SIG) recommendation and TOC sponsorship requirements for sandbox projects have been replaced by a simple vote for acceptance by the TOC.

    There are currently 31 sandbox projects being developed under the auspices of the CNCF. The new process for approving sandbox projects has already been applied to 11 of them. Each sandbox project has signed over the rights to the intellectual property for that project to the CNCF, which then attempts to attract more developers to participate in the ongoing effort to increase the adoption of that project.

    In some cases, CNCF projects will compete with one another for acceptance. The CNCF is committed to not becoming a “king maker,” said Sharma.

    Obviously, the CNCF is not the only organization trying to advance the adoption of open source software. In addition to The Linux Foundation, of which the CNCF is a part, there are older organizations such as the OpenStack Foundation and the Eclipse Foundation, which, to varying degrees, compete with one another to become the entity through which open source projects are governed.

    The number of open source projects being launched has increased exponentially in recent years as IT vendors transform their business models. Many now contribute their core software to an open source project in the expectation that increased adoption will lead to demand for commercial support services.

    That shift in many ways has led to a change in terms of how innovative software is brought to market. Not too long ago open source software was viewed primarily as a way to create the free equivalent of an existing operating system or database. Today, the bulk of emerging software in the enterprise starts out as open source projects.

    Much of that transition began when more IT organizations adopted “open source first” approaches to IT in the wake of the economic downturn that began in 2008. As the current downturn brought on by the COVID-19 pandemic deepens, it’s probable the preference for open source software is only going to increase in the months and years ahead.

  • 5 Areas to Consider When Building an Open Source Stack

    5 Areas to Consider When Building an Open Source Stack

    Open source software has gone mainstream, propelled by the increasing maturity of many communities and tools working together with organizations seeking ways to deploy software faster and cheaper. According to Gartner Research, over 95% of them are deploying open source software, and while it brings many benefits, it also introduces a whole new set of challenges, beginning with choosing the right open source stack. There are multiple risks including disappointing software performance, tools that cannot connect well with others, surprise additional costs, lack of control and security problems.

    Choosing the right open source stack is not easy. Many organizations lack the internal expertise to know what to look for or don’t have the time to research open source software sufficiently. Software engineers can’t be expected to become open source market experts overnight.

    Some years ago I worked with a team that certified open source solutions to be used in production. We created a list of 42 necessary qualifications to consider, which is (at least part of) the answer: Start by knowing what questions to ask when selecting open source software.

    Open Source Considerations

    Here are five areas to consider when choosing open source software:

    Time: While the ability to download open source and get it running fast might be tempting, it is better to invest in due diligence or think about working with an external specialist who can carry out the research. Take time in building the right solution for your use case(s). It is important to note that open source is often purpose-driven and chosen to perform a specific task; you may need to combine several different projects together to arrive at a complete solution.

    The Backers: While volunteers play an important role in successful open source, the fact is that the majority of the most well-known tools have sponsorship. Having a committed backer with a strong track record is a good sign for both longevity and software quality. The example I often cite is the Cloud Native Computing Foundation, which is behind Kubernetes, Linux and Prometheus.

    The Community: The commitment and responsiveness of the community are essential. Essential questions to ask include:

    • How fast does the community respond to queries or bugs?
    • How well do its members document and share collective knowledge?
    • How active, large and stable is the community? Is it likely to be around long enough to support the required use case for which the software is being selected, or is the community and the software likely to pushed sideways by something else on the horizon?

    The Different Types: Even some very knowledgeable CTOs do not properly understand the different types of open source, especially the difference between copyleft licensing and permissive licensing. Each has very different implications for an organization. The first requires contributors to share their changes with the relevant software community, while the second doesn’t make that obligation. Businesses are nervous about having to share parts of their proprietary source code and possibly their IP, though this only applies if the business modifies the code.

    Unforeseen costs are implicit in all of the following categories:

    • Time: could be wasted instead of saved if the solution doesn’t end up matching the use case.
    • Solution updates: A project without “the backers” runs the risk of dying and not receiving any more updates, forcing a business to spend energy choosing a new solution. The same is true for the community.
    • Legal ramifications: Businesses have faced expensive legal action if they modify and distribute copyleft source code without sharing it back.
    • Availability and support: Will the organization be supported by a third party, the community and by its own team? Consider the potential costs of all of the options.

    Software Quality and Integrations: It’s important to look at coding practices (do they align with the organization’s own standards?), usability and support for distributed resources. Above all, scrutinize integrations, because one of the biggest risks when building an open source stack is ending up with a bunch of tools that won’t work together or are not all aligned on the use case.

    Examine integrations throughout the stack: platform, database, middleware, application runtime and monitoring tools. Look for solutions that have lots of backing and that are known to interoperate well with lots of other solutions, such as Kubernetes.  Concentrate on well-adopted language distributions such as OpenJDK, which can run tons of other enterprise-class open source on top.

    It can be difficult, but choosing the right components for an open source stack will help make future curation easier and benefits clearer to see. Spending the time on research and asking the right questions from the beginning could save a lot of headaches in the future.