Category: DevOps and Open Technologies

Editorial Calendar for February 2016

  • OpenTelemetry and the Future of Monitoring Instrumentation

    OpenTelemetry and the Future of Monitoring Instrumentation

    OpenTelemetry is an open source project to provide a de facto standard trace API and a metric and log agent to end vendor lock-in

    It’s no surprise that understanding the internal health of applications and systems is a high priority for developers and SREs. It’s a well-understood problem with dozens of vendors focused on helping companies diagnose application performance in real-time.

    While the actual platform doing the metric, log or trace analysis tends to see most of the focus, a critical component of the data pipeline is, and has always been, the actual instrumentation. That includes APIs and SDKs for application traces as well as installable agents to gather metrics and logs. In the past, this has been a highly fragmented space with both open source and proprietary agents and SDKs. Most APM vendors have provided their own proprietary instrumentation libraries that, intentionally or not, create a vendor lock-in at a code-level that isn’t ideal for most organizations.

    To address this challenge, an open source project was created with a highly aspirational goal of providing a de facto standard trace API along with a metric and log agent that would eliminate this fragmentation, create a unified standard and effectively end vendor lock-in.

    The project, OpenTelemetry, was officially started in May 2019. It is a Cloud Native Computing Foundation sandbox project and came out of the merger of the OpenCensus and OpenTracing projects. They’ve since expanded their goal to include not only application tracing and code instrumentation, but also metric and log collection. They are essentially covering all the critical telemetry points in a system or application.

    Imagine if, regardless of the platform you ultimately sent the data to, you could instrument your code with the same libraries, the same agents and a single set of binaries and libraries. It would dramatically simplify the deployment process, internal training and make it trivial to change or add analytics platforms as needed. This is the promise of the OpenTelemetry project.

    A project like this doesn’t get far without significant support. This is where OpenTelemetry shows incredible promise to realize widespread adoption quickly. Nearly all the largest monitoring and cloud vendors including AWS, Google, Microsoft, Splunk, New Relic and many more have thrown their weight behind OpenTelemetry. They’re actively contributing and supporting the project. One by one, these organizations have come to the agreement that the telemetry component is not the differentiating feature. Instead, they are working together to provide a best-of-breed experience at the telemetry layer.

    The project is in beta, and the potential is huge. OpenTelemetry modernizes every aspect of the telemetry system. It eliminates vendor lock-in. It will outperform the vast majority of existing agents. It simplifies installation and training by reducing dozens of agents and libraries to just one.

    So where to get started?

    It’s still early, but depending on your platform of choice, it may already support OpenTelemetry. If so, look into the existing libraries and test them out in your internal sandbox environments. You’re likely to find improvements over your existing telemetry tools, although there will certainly be gaps in things such as development language support and metric/log integrations. It should give you a sense of the scope, potential and maturity of the project and help to determine whether this is a viable solution for your next deployments.

    The big question mark is whether this will live up to its potential. With the high-quality team assembled, the support of the community and industry and with a truly impactful mission, it will. Ideally, within a few years, this will be how we instrument and gather data from our applications regardless of where we send that data.

  • Open Source License Compliance Tips for DevOps Pipelines

    Open Source License Compliance Tips for DevOps Pipelines

    Open source components are used in most modern organizations, either included directly into software as code or as tools integrated into workflows. In DevOps environments, often a combination of the two occurs. These components can help speed development processes, provide functionality that isn’t otherwise available and decrease operating costs of teams.

    To successfully implement open source components, in software or pipelines, teams need to carefully evaluate what projects are included. Although most open source is free and supported by developer communities, there is no oversight guaranteeing that components are well-made and licensing can vary widely. This means that teams are responsible for ensuring that code is safe, stable and implemented legally.

    DevOps and Open Source Software Development

    When you are considering including open source components in your projects and pipelines, it is important to evaluate those components first. A well-developed evaluation process can help teams verify open source components and protect from:

    • Security vulnerabilities—Components are made by a community of developers, many of whom do not have extensive security knowledge. Additionally, because projects are worked on by many developers, code may not be uniform, creating bugs that can turn into security vulnerabilities.
    • Operational risks—Open source projects are maintained voluntarily. This means that project support may wane or unexpectedly drop. Additionally, updates and patches may not be released as reliably as with proprietary software. Since continued support is not guaranteed, you may be left with significantly more responsibility for maintaining and updating components that you originally planned for.
    • Legal risk/license IP compliance—Not all components are freely available for use by every organization or project. If you use these components unlawfully you can later be held accountable for breaking license agreements, even if you were unaware of doing so.

    Why Open Source Compliance Is Important

    Open source license compliance and legal risk are especially important and complex for commercial development teams. There are more than 200 open source license variations, each with different standards for when projects can be used, by whom and in what capacity. Compliance strategies ensure that you are aware of the licensing requirements of any component you use.

    In particular, the things you need to be aware of when it comes to open source compliance is whether projects can be included in commercial products or used by teams of your size and type. If projects cannot be used in commercial projects or require projects to be made open source upon inclusion, you are risking your own intellectual property.

    Including open source projects against license can open you to legal action from project maintainers, contributors or third-party organizations. For example, some projects are part of a dual-licensing strategy with companies looking to protect their own financial interests. Or, cases may be brought as a means to raise awareness about open source licensing by concerned community members.

    Another possibility is being actively targeted for financial gain. Some projects are contributed to by open source trolls, software developers who have made a business of suing for license non-compliance. These developers take advantage of licenses such as GNU General Public License v2.0 (GPL-2.0), which terminates usage and distribution rights when breached, enabling developers to sue to stop distribution or to demand a portion of profits.

    Open Source Compliance Tips for DevOps Pipelines

    There are several practices you can implement to ensure that your pipelines and products are in compliance when it comes to open source. These practices are especially important to integrate throughout your pipeline to help identify and correct any issues that may exist before products are pushed to production. Below are some practices to get started with.

    Create an Open Source Review Board (OSRB)

    An OSRB is a group responsible for creating and enforcing open source policies and procedures within your organization. These boards often include members from development, operations, legal and management teams.

    OSRBs can serve as advocates for open source use with executives and stakeholders. They can also serve as a source of information for teams looking to incorporate or contribute to open source projects. These boards can help you ensure that you remain in compliance while deriving the greatest benefit from open source.

    Incorporate Compliance Processes Throughout Development

    Compliance policies should be created and incorporated into all steps of the software development life cycle (SDLC). These policies should outline how components are vetted, by whom, how and when components can be included, and how tracking is done.

    Ideally, compliance processes and policies should be built into your pipeline processes. For example, by returning builds to developers if they include blacklisted licenses. By incorporating compliance, you reduce the chance that it is overlooked and minimize interruptions to productivity. Incorporation also helps you ensure that licensing issues are found sooner rather than later, minimizing the impact if components need to be replaced or removed.

    Create ‘Playbooks’ for Commonly Used Licenses

    While there are many licenses that open source projects can fall under, there are several that are significantly more common than others. For example, MIT or Apache—for these licenses, you can simplify compliance procedures by creating playbooks.

    Playbooks outline the details of licenses, including license grants, obligations, restrictions and patent impacts. When a developer wants to include a component, they can use these playbooks to quickly determine whether that component is eligible for use. While this won’t eliminate all legal questions when it comes to licensing, it can significantly reduce how often you need to confer with legal counsel about inclusions.

    Use Software Composition Analysis (SCA) Tools

    SCA tools can help you identify open source components in your own products and in any tools you adopt. These tools enable you to scan source code to determine what components are inside and create an inventory that you can then use to verify compliance. As a bonus, these tools can also help you identify components with known vulnerabilities, which you can then mitigate.

    SCA is especially helpful when you are newly implementing open source compliance policies. It can provide information on the types of components you are already using and help you ensure that those existing components meet your newly applied standards. Some tools even enable you to set up alerts for license conflicts or irregular version use, making verification easier.

    Conclusion

    Open source compliance is a critical component of most DevOps implementations. To ensure compliance, teams need to carefully choose and then properly keep track of open source components. You can do that by creating an open source review board (OSRB), which can help enforce open source compliance policies. You should also incorporate compliance throughout your pipeline, create playbooks for commonly used licenses and leverage SCA tools.

  • Sonatype Advances Open Source Code Quality, Security

    Sonatype Advances Open Source Code Quality, Security

    Sonatype today launched an Advanced Development Pack service that surfaces dependencies between open source components in a way that makes it easier for developers to know which ones to employ to build the most secure application possible and what components offer the simplest upgrade path.

    Company CTO Brian Fox said the Advanced Development Pack service is an extension to the Nexus Lifecycle platform the company currently makes available to identify vulnerabilities in open source code.

    The Advanced Service Pack was created after studying development and cybersecurity practices across 30,000 software teams that Sonatype was able to analyze in its Maven repository, said Fox. The goal is to eliminate a vicious cycle that emerges as organizations develop applications using components that too often need to be either replaced or updated depending on the security and quality issues uncovered later in the development life cycle. By making it easier to identify the highest-quality modules available, the Advanced Development Pack serves to increase developer confidence in the quality of the open source components being pulled as they develop their application.

    A Component Chooser tool, currently in beta and slated for availability next year, will also make it possible to employ project hygiene ratings based on security and license compliance as well as identify where else that component may already be in use.

    The Advanced Service Pack makes it possible to evaluate open source components based on factors such as project quality, ease of upgrade and advanced knowledge of abnormal committer behavior, said Fox. Other factors evaluated include the cost of migrating to a newer or safer version of a module and whether it is possible to do so without breaking code, release frequency, the cadence of dependency updates, development team size and popularity.

    The Advanced Development Pack also furthers the adoption of best DevSecOps practices by identifying which dependencies have become vulnerable and have been remediated, as well as suspicious behavior involving project code commits that might be indicative of a malicious injection attack. It also applies machine and deep learning algorithms to automatically identify and block software supply chain attacks based on typosquatting and malicious code injection. In the past 90 days alone, the malicious code detection bots created by Sonatype have discovered 43 new malicious packages including electorn and loadyaml.

    Sonatype has also included a transitive solver capability that provides comprehensive remediation advice for solving both direct and transitive dependencies without violating policies or failing builds.

    Fox said that while there’s a lot of focus these days on making sure individual application components are secure, it’s also become apparent that cybercriminals are now targeting application development platforms as part of an effort to compromise the entire software supply chain. As such, DevOps teams now need to focus on securing both the components they employ and the platforms used to construct their applications.

    In the meantime, there may never be such a thing as absolutely secure open source code. However, it is becoming possible to greatly minimize the risks associated.

  • SOFIHUB Relies on DevOps to Support Independent Seniors

    SOFIHUB Relies on DevOps to Support Independent Seniors

    How DevOps is helping one company ensure an active older population can remain independent

    SOFIHUB home is designed to support older people who wish to live as independently as possible. However, its sensor-based system needed an upgrade to improve the user experience.

    The SOFIHUB technology connects wirelessly to sensors placed around the home and learns the individual’s habits. When it detects deviation from the user’s routine or other issues, it asks if they are OK. Unless the answer is affirmative, it automatically contacts a nominated carer.

    However, the existing products were created with a risk-aversion mindset and built to standards rather than user requirements, which sometimes impacted the user experience. “The market required a change,” said SOFIHUB CTO Ian Aitken.

    For example, personal alarm pendants intended to detect falls generated four false alarms for every real fall they detected. A common cause of false alarms was the pendant accidentally hitting a piece of furniture.

    In any case, only 4% to 12% of pendant owners actually used their devices, he said, mostly because they forgot to put them on after showering or dressing in the morning. Plus, many often regard pendants negatively, referring to them as “cowbells.”

    So SOFIHUB changed its approach, placing movement sensors around the home to detect when the person moves from one room to another.

    The SOFIHUB System

    The sensors communicate via Z-Wave with the Raspberry Pi-based SOFIHUB home, which processes the data. The Raspberry Pi is capable, stable and cheap, said Aiken. But the finished product required additional custom electronics to provide power management and other functionality. The designers also added a microcontroller that monitors the Raspberry Pi and restarts it if necessary.

    Caregivers receive alerts if the person is late to bed, late to rise or spends longer than usual in the bathroom, or if there is a lack of movement for longer than usual. Machine learning algorithms developed in conjunction with Monash University detect these patterns.

    SOFIHUB is also able to deliver reminders such as those for appointments and birthdays or, working with a medicine cabinet sensor, when it’s time to take medications.

    The optional SOFIHUB beacon is a panic alarm that can also generate alerts when it detects the user has left a geofenced area or has fallen. Since the hardware is basically a mobile phone without a dial pad, caregivers can call it to converse with the user.

    Where the use of conventional pendants was about 10%, the use of the SOFIHUB beacon is around 60%, partly because the system reminds people to keep the beacon charged and take it with them. For example, it suggests they pick up the beacon from the charger once it has reached 80%.

    The system transfers data collected by the SOFIHUB home to cloud-based infrastructure for longitudinal analysis and other purposes.

    SOFIHUB Under the Hood

    The company developed and must maintain several layers of software: code for the main board and the microcontroller within SOFIHUB home, code for managing Wi-Fi and cellular communications, and the code that runs in the cloud. SOFIHUB uses containers and infrastructure as a service (IaaS) rather than platform as a service (PaaS), so it can easily move from AWS to another host if necessary.

    “We’re reasonably sophisticated,” said Aitken. For example, the company created a separate domain for a new corporate customer in around a day and a half, thanks to the level of automation within its DevOps processes.

    The SOFIHUB service is also available through alarm center companies to ensure someone is always available to react in emergencies. Onboarding a new alarm monitoring company is usually a quick process, even if custom features are required. Sometimes implementing old protocols still used by some alarm centers takes longer.

    “We are a highly skilled team of developers” and database experts, said Aitken. This “small, very agile team” works without dedicated operations staff, although two people specialize in building and maintaining implementation scripts.

    The AppDev Toolkit

    The team has adopted widely used tools (eg, Jira, Confluence, Slack, GitHub and CircleCI), and a well-developed release mechanism sees code start in a developer’s instance before moving into the AWS environment for additional testing.

    From there, it progresses to the user acceptance testing environment to deal with any UI and browser-specific issues. After that, the code goes into production.

    SOFIHUB does not do automated testing. Aitken said that’s because it actually slows development to an unacceptable degree, roughly doubling development time due to the effort needed to write the tests.

    New releases occur every Wednesday with two fortnightly development cycles running side by side. Aitken said he expects the pace will slow as the product becomes mature and foresees monthly releases starting sometime in 2021.

  • Catchpoint Acquires Webpagetest.org Service

    Catchpoint Acquires Webpagetest.org Service

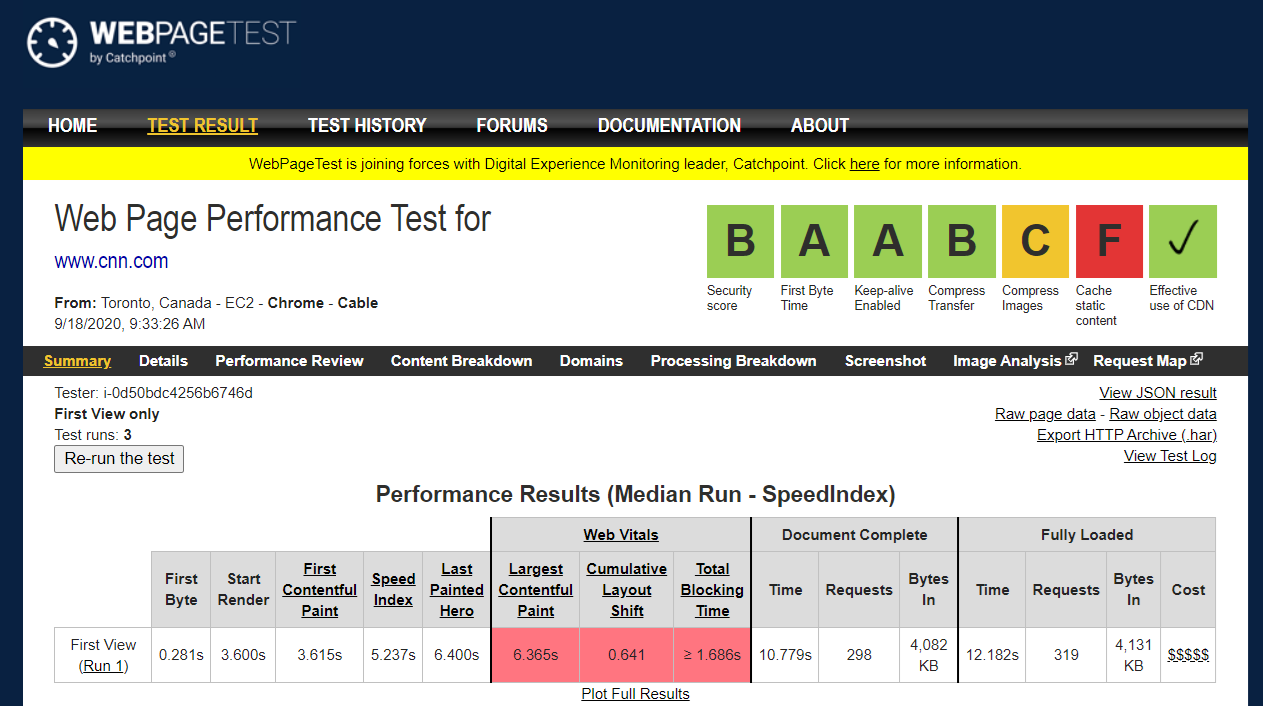
    Catchpoint this week announced it has acquired Webpagetest.org as part of an effort to expand use of the open source web performance testing service.

    Led by Patrick Meenan, the Webpagetest service is already relied on by more than 1 million users per month to instantly run tests of websites and applications from various locations, which are surfaced via a detailed audit that can be shared with developers.

    Meenan has been personally supporting Webpagetest as a side project while working for a series of IT organizations and vendors starting with America Online (AOL). Now, with Catchpoint’s acquisition of Webpagetest.org, he will have a staff of contributors as a full-time employee.

    Catchpoint CEO Mehdi Daoudi said the company will also incorporate Webpagetest into the tools it provides for monitoring digital experiences. The most appealing aspect of the Webpagetest service is that, rather than focusing on individual backend platforms, it tracks the actual performance that users experience across multiple types of browsers.

    Daoudi said that as organizations accelerate the rate at which they are building and deploying digital business applications in the wake of the COVID-19 pandemic, there’s now more focus on web application performance than ever. The experience any user has when accessing these applications now impacts everything from their willingness to complete a transaction to their perception of the corporate brand, he noted.

    In fact, a recent survey of 200 CIOs and 200 work-from-home managers conducted in July by ReRez Research on behalf of Catchpoint finds application performance is at the top of the list of concerns (66%), followed by network reliability, work-from-home technologies and security, at 63% each. Application performance is at the top of that list because both online revenue and employee productivity are now increasingly directly impacted by the overall application experience, said Daoudi.

    There’s never been a shortage of tools for testing application performance. The issue is how those tools are often employed, he noted. Too many IT organizations are monitoring individual application components rather than the actual user experience.

    Organizations that focus on end user experience in the age of digital business will, in time, separate themselves from rivals that merely make applications available online. A zealous appreciation for application performance needs to be ingrained in the culture of the organization for it to ultimately succeed, Daoudi said, noting that every employee, not just the DevOps teams, needs to be aware of the impact application performance has on the business.

    That challenge is as IT environments become more complex and distributed, ensuring application performance becomes more challenging than ever. Cloud-native applications based on microservices may be easier to deploy and manage, but the dependencies between all those microservices can conspire in ways that degrade application performance over time. Determining the root cause of intermittent application performance issues can take weeks. The maddening thing is, many of the fixes required to address that issue once it’s discovered can be deployed in minutes.

    Performance tools that surface those issues sooner than later are invaluable in a digital age, where time now quite literally is money.

  • Harmonizing Real-Time on Edge Platforms

    Harmonizing Real-Time on Edge Platforms

    Edge computing platforms sit at the boundary between the real-time world and the digital enterprise. Uninterrupted, uncorrupted data from the edge is a must if analytics in the cloud drive reliable business decisions. What’s the best approach: using Linux, an RTOS (real-time operating system), a hypervisor or something else for edge platforms?  Let’s talk about harmonizing real-time on edge platforms and introduce a new foundation project in the Linux Foundation’s LF Edge family.

    Real-Time and Deterministic

    Real-time only means events are captured, tagged and processed as they unfold in the real world. That cadence can be seconds, milliseconds or microseconds depending on how many events and how often they occur and how tasks and algorithms stay in control. Three operating system characteristics determine how well real-time execution keeps pace: prioritization, interrupt response time and context switch time.

    Prioritization ensures that tasks receive resources when needed. Tasks at a lower priority should pre-empt when a higher priority task requests service. A task refusing to yield to pre-emption can throw off the prioritization scheme, causing missed deadlines.

    Interrupt response time measures the latency from the time an event requests service via a hardware interrupt to when the handler task executes. Real-time hardware platforms often place high-priority events on hardware interrupts for fastest pre-emption.

    Context switch time is softer scheduling at work. It measures the time for a change in processing control from one execution entity to another, swapping out resources including registers, cache and memory as needed.

    Deterministic means there are no surprises in behavior. The faster real-time events happen, and the harder a system works, the more likely non-determinism surfaces. One venture into virtual memory paging or a burst of networking activity can show up at an inopportune time, even though under most conditions real-time performance is adequate.

    ‘Hard’ vs. ‘Soft’ Real-Time

    That’s why most people think of real-time as “hard” with a fast, deterministic operating system. RTOS platforms optimize the kernel and only build things in around it that are necessary, providing rigorous and sometimes mathematically proven scheduling for many tasks.

    “Soft” real-time is more forgiving. On a fast processor, interrupt response time is tiny compared to the execution window. A system that isn’t deterministic can, if there is enough margin in context switch time, keep up with real-time events on a slower scale. Linux, while not deterministic, can handle some real-time needs through minimizing packages and tuning the kernel for better prioritization.

    Linux also benefits from lighter context switching. Originally, execution entities in Linux were resource-heavy processes. Now, threads can handle tasks with far less switching overhead. POSIX threads standardized the approach with portability between Linux and RTOS environments.

    How fast are threads? According to a recent synthetic thread benchmark by Eli Bendersky, switching on server-class platforms with enough memory, cache and storage can be in the range of 2 microseconds with 10,000 threads under ideal conditions. Eli pointed out his test environment has more RAM than many edge hardware platforms provide, but most edge applications won’t need that many threads, either.

    So, the line for soft real-time has moved down into new territory, making the trade-off between hard and soft a bit blurrier.

    Hypervisors and Orchestration

    If your DevOps team commits to an RTOS, you may give up some familiar functionality and have a learning curve to deal with, but you get assured hard real-time performance. If you go with Linux, you get the tools and coding practices you’re used to, but soft real-time performance can be an issue as code piles up.

    The leaders in RTOS platforms with enterprise networking noticed this, too. Recently they’ve turned to hypervisors in a bare-metal approach. A hypervisor can capture the benefits of environments working together, so teams are not forced into an either/or operating system choice. This is especially important if the edge application requires some form of certification, such as in medical, industrial or defense applications. Certified code can be compartmentalized on an RTOS, while Linux runs alongside.

    Linux providers are turning more toward orchestration layers and containers. It’s an application focus speeding up deployment, with more scalability and less hardware dependence. It also brings the edge into the enterprise faster with the same application deployment strategy anywhere. More code means more determinism risk.

    Convergence is a faint hope on this landscape with competing objectives, but a new approach offers a path for software reuse and rapid deployment.

    Harmonizing the Edge

    The Linux Foundation is active across the spectrum of IoT development, from the Zephyr open source RTOS to various embedded Linux projects. One of the newest projects in the LF Edge initiative is a foundation targeting a blend of deployment models in a consistent, open approach.

    Project EVE (short for Edge Virtualization Engine) supports containers, clusters, virtual machines and unikernels simultaneously. It’s a slim bare-metal runtime offering hardware root of trust, device resource management and software update and patch functions. EVE can host any combination of apps in virtual machines or containers, including running an RTOS with its application in a virtual machine. It can even assign CPU and GPU cores to specific applications for enhanced determinism.

    On the EVE road map is support for the ACRN hypervisor (another LF Edge project) and shrinking the EVE runtime for smaller embedded-class edge platforms. These efforts are essential where real-time requirements become harder and a hypervisor plus an RTOS makes sense. For softer real-time environments, EVE is adding support for Kubernetes K3S, Docker Compose, VPNs for public clouds and mesh networking for data flow between edge platforms.

    While the project is still young, EVE holds great promise for DevOps teams working the edge. We’d look forward to seeing some benchmarking on a real-time scale; it likely handles soft real-time needs as well as Linux today. By harmonizing a range of diverse approaches into one foundation, EVE is creating a space for real-time on edge platforms no matter which development perspective teams come from.

  • Z is for Zowe – the Open Path to Mainframe DevOps

    Z is for Zowe – the Open Path to Mainframe DevOps

    The energy and excitement in the IBM Z mainframe community during the two years since the announcement of Zowe have not been seen in a generation.  By enabling mainframers to work like technologists who work on the cloud, mobile and distributed platforms, Zowe unlocks the power of DevOps for mainframers, ensuring the vitality of the platform for the long-term.

    It accomplishes this by opening up the world of enterprise DevOps tools, both familiar and special-purpose ones, for mainframe applications, allowing users to easily create toolchains that include the mainframe. This freedom to leverage any enterprise DevOps tools across the entire deployment pipeline is achieved simply and elegantly.

    The Zowe Backstory

    The Zowe journey began when Broadcom, at the time CA Technologies, along with IBM and Rocket Software realized the challenges they were hearing from customers—IT isolation, need for increased delivery velocity and recruitment and retention problems—were bigger than any single vendor could solve on its own. The challenges of this scale required an ecosystem-wide response.

    So the vendors came together with the Linux Foundation’s Open Mainframe Project to create the open source framework known as Zowe (as in David Bowie, for the uninitiated). The Zowe community operates transparently and welcomes contributions from all in the form of code, enhancement requests, educational content and shared experiences. A virtual meetup held earlier in the year attracted participants from 47 companies from across the mainframe ecosystem.

    Traditionally, mainframe application development and operations have been separate from the rest of the IT organization due to specialized processes, roles and tools designed around the platform. While they have served the mainframe community extraordinarily well over the decades, the world outside has changed with demand for ever-shorter software delivery cycles resulting in the DevOps model.

    In short, the tipping point has arrived and the time to normalize is now.

    What Is Zowe?

    Zowe is a modern interface to the mainframe that extends z/OS-based services and tooling to the greater IT landscape, including DevOps. As a framework, it consists of four main components:

    • Zowe API Mediation Layer (APIML)
    • Zowe Command Line Interface (CLI)
    • Zowe Explorer (Visual Studio Code extension)
    • Zowe App Framework (UI)

    Broadcom is proud to have initially contributed the first three of these components. The first two were created as part of our CA Brightside offering, which won an award for the Most Innovative DevOps solution—yes, a mainframe offering won a DevOps innovation award!

    These components provide a modern way of working that supports core DevOps practices such as empowering developers with shift-left testing responsibilities and DevOps engineers with robust automation options.

    This article describes the framework’s ability to onboard the mainframe to enterprise DevOps, so developers, systems programmers and others who work with the mainframe can now do so the same way their peers do with other IT platforms (i.e., cloud, mobile, distributed). These shared experiences close the gap between mainframers and others while preserving the core advantages of the platform. Common tools fuel a common language that benefits all, especially when deploying hybrid applications (e.g., web front-end with mainframe back-end).

    Through automation and script libraries, Zowe helps reduce the range of mainframe-specific knowledge necessary to be productive, enabling organizations to more easily recruit, onboard and retain the next generation of talent. By using modern DevOps tools and techniques combined with access to “big iron” applications, the next-generation now sees mainframe as an exciting career choice.

    Recent milestones achieved by the Zowe community include the launch of the long-term support (LTS) release ensuring the stability and longevity of the framework and a Zowe Conformance program ensuring the interoperability of a growing ecosystem of conformant tools.

    The framework drives mainframe DevOps in several ways:

    Zowe API Mediation Layer – Discover and Securely Consume

    As RESTful APIs become table stakes, the greater the challenge becomes, making those services easily discoverable and consumable in a secure way. The Zowe API Mediation Layer (APIML) addresses this need by exposing mainframe services, ranging from z/OS system level to database/transaction services to tool-based services, through a centralized gateway and catalog.

    Conformance of these APIs with the Zowe LTS standard eliminates breaking changes while bringing additional value, including the usability and productivity benefits of single sign-on (SSO).

    At Broadcom, we’ve leveraged Zowe to achieve conformance across our product portfolio and have a healthy pipeline of Zowe-conformant products soon to be announced. By spanning the traditional Dev and Ops domains, we’re facilitating true mainframe DevOps adoption—teams can combine their preferred mainframe-native tools with off-platform ones, including ones used by their peers working on other platforms, to optimize speed, quality and productivity.

    Zowe CLI – Orchestrate and Automate

    For DevOps Engineers and DevOps-savvy self-service developers, CLIs are a “go-to” tool. They use CLIs for a wide range of platforms including AWS and Azure, Git, Kubernetes and so on … why not mainframe? The use of CLIs paves the way for robust, script-based automation, which is a cornerstone of DevOps. The Zowe community already offers some basic scripts, free for anyone to use.

    Using a CLI may be new for some, so community members often share tips and tricks to help these users navigate the productivity curve quickly.

    Broadcom currently offers a dozen or so CLI extensions to mainframe-native tools, once again spanning the traditional Dev and Ops domains to improve productivity across roles and processes.

    Zowe Explorer for VS Code – Visualize and Navigate

    Visual Studio Code is exciting for any mainframers editing code, especially developers and sysprogs. While ISPF and Eclipse will remain viable options for the foreseeable future, the extraordinary success of the lightweight VS Code, which is backed by Microsoft, and the rapid emergence of browser-based editors/IDEs expand the range of options. With 11 million users around the globe, VS Code provides an experience users love and a marketplace of 20,000 extensions enabling users to personalize their UX and optimize their workflows.

    Zowe Explorer, which streamlines interaction with mainframe data sets, USS files and jobs, is only one of the many VS Code extensions available in the VS Code marketplace for mainframe users (and a successful one with more than 12,000 downloads). Unlike Eclipse extensions, all of the mainframe extensions from Broadcom are free, and many are open-sourced.

    In the Queue: SSO/MFA, SDK, Mobile App

    The Zowe community has been working diligently on the implementation of SSO and multi-factor authentication (MFA), which eliminates the drudgery of constantly logging on to multiple systems.

    Also, software development kits (SDKs) are in the works, the goal of which is to make Zowe services (and by extension, the mainframe) easier to use by providing reusable code for common mainframe operations in popular languages and runtime libraries. The beginnings of a Zowe Node.js SDK and Zowe Python SDK already exist.

    Finally, a Zowe mobile app to help systems and operations support staff improve system availability is, like the SDK, being incubated by the community.

    Decision Time – Zowe Open Path or Closed, Proprietary

    Mainframe teams face a choice: Continue with a vendor-controlled model, in which vendors determine which tools you use and how you work or adopt the open path. While the prescriptive (aka opinionated) approach of the former may have been acceptable for a siloed mainframe, the open approach is the foundation of enterprise DevOps.

    As an indication of the early success of the open path, we’ve been delighted to learn about many mainframe shops adopting Zowe on their own, with CI/CD integration and code analysis a common entry point.

    For those with reservations about open source, consider the prevalence of Git, Visual Studio Code, Jenkins, SonarQube and so on in the DevOps landscape. Microsoft CEO Nadella recently stated, “We’re all-in on open source” and Zowe co-founder IBM recently acquired Red Hat—more shining examples that open source tools are a trusted part of the technology stack.

    Change is never easy, which is why no-fee Design Thinking workshops are available to help adopters prioritize the DevOps use cases enabled by Zowe. Because so many see “open” as the least costly, least risky and fastest path to mainframe modernization, familiarity with Zowe is quickly becoming an industry standard. Ask your vendors if they’re joining the Zowe community and ecosystem.

    With ongoing commitment from IBM, Rocket and Broadcom and the guidance and support of the Open Mainframe Project, the excitement around will Zowe continue so join the open mainframe movement!

    To learn more about Zowe, visit Zowe.org and the community blog site.

  • Gitpod Open Sources Automated Local Development Environment

    Gitpod Open Sources Automated Local Development Environment

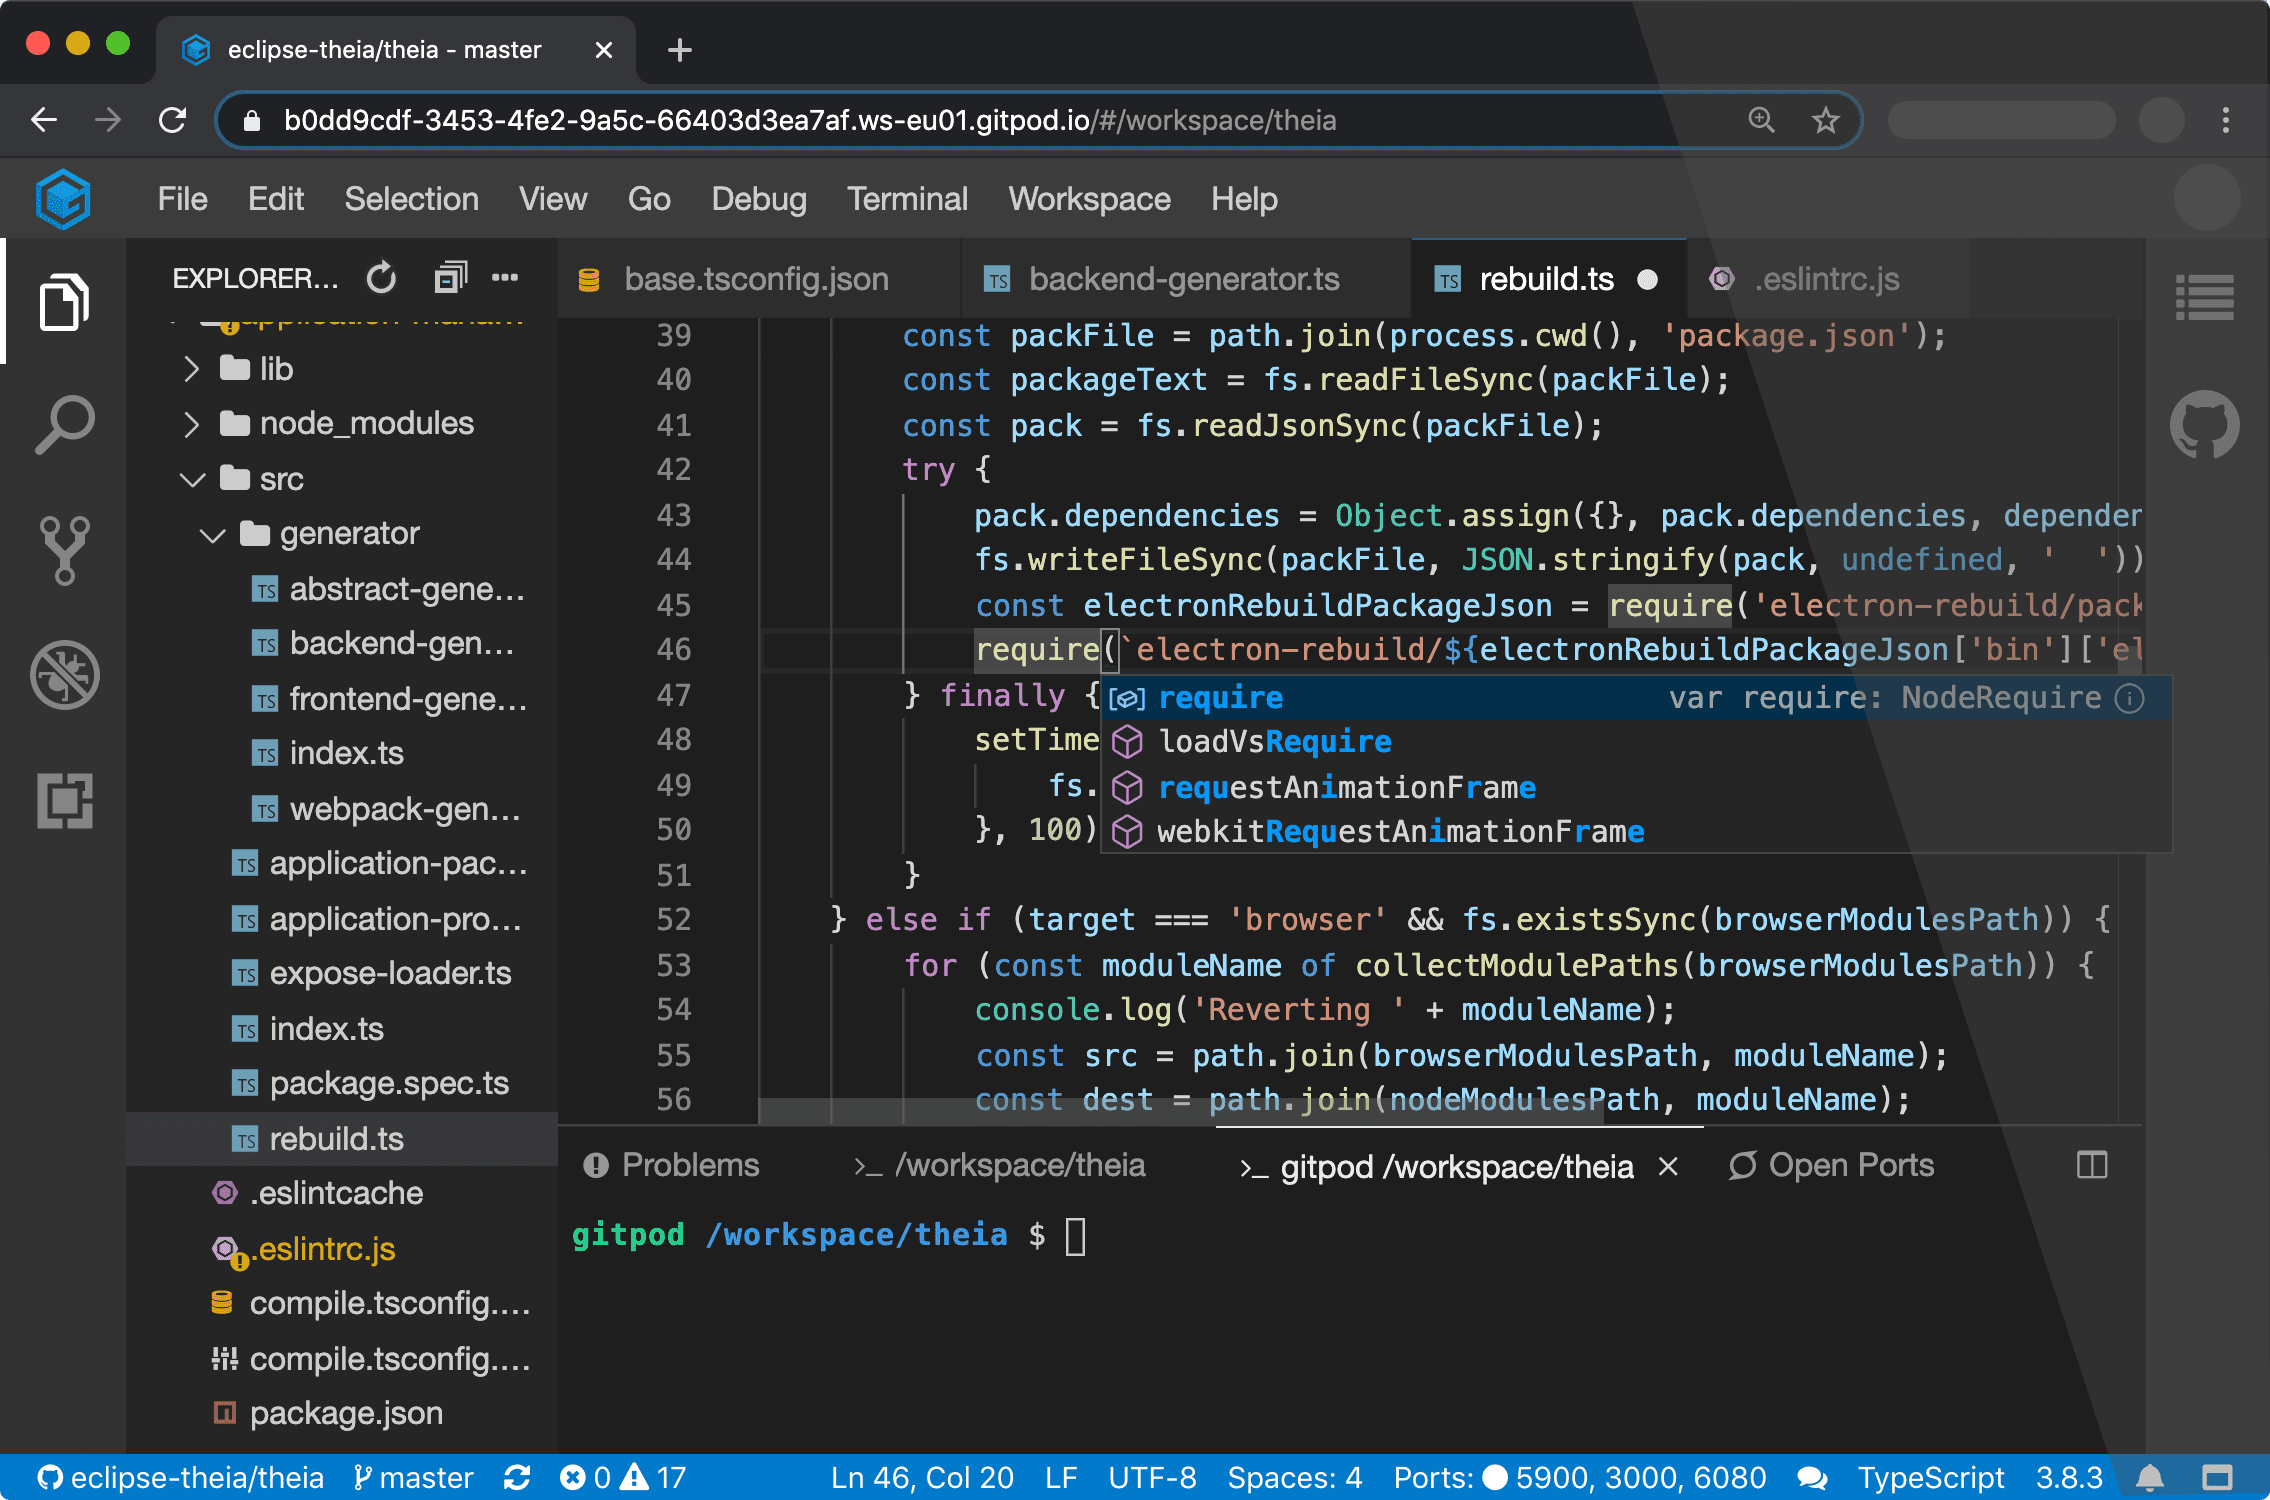
    Gitpod announced today it is making available an instance of its Gitpod integrated development environment (IDE) available under an open source license.

    Company CEO Sven Efftinge said DevOps teams will now have the option of deploying Gitpod themselves as an alternative to the existing cloud service provided by the company.

    Designed to be used in conjunction with repositories such as GitLab, GitHub Enterprise and Bitbucket, Gitpod automates the building of development environments on-premises, Efftinge said. It continuously monitors updates to any Git repository.

    Gitpod will then configure the right tools for a specific git branch, automatically compile machine-executable code and download all the dependencies required to allow developers to build code on-premises. Rather than having to manually configure a desktop environment, developers can start coding in seconds, Efftinge said.

    Gitpod borrows concepts from continuous integration platforms and applies them to development environments, he said, noting developers today typically spend multiple hours per week setting up and maintaining local developer environments.

    By automating that process, he said, the local development environment can also better align with production environments. One of the reasons why code doesn’t work in a production environment when it is first deployed is because the local development environment has been manually configured in a way that doesn’t accurately reflect the production environment, Efftinge noted.

    That issue becomes even more problematic when developers are working on multiple projects involving, for example, separate microservices that are all going to run in different production environments, he added.

    Gitpod also prevents drift by making sure all versions of a local desktop environment among developer teams remain consistent. Collaboration also becomes easier when the members of the teams have standardized on the same instance of a local desktop environment.

    Efftinge said there are already hundreds of thousands of developers using the Gitpod cloud service. The open source edition provides an option that will enable DevOps teams to self-host their own instance, he noted.

    Gitpod, formerly TypeFox, collaborated with Google, Ericsson, Arm and Red Hat to develop the open source Eclipse Theia project, which provides a foundation for building IDEs in the cloud using TypeScript, CSS and HTML. Theia, now being advanced under the auspices of the Eclipse Foundation, consists of a front-end running in a browser or in the local desktop application and a back-end running on any host. Both the front-end and back-end communicate through JSON RPC over WebSockets. Gitpod leveraged that project to build its own cloud-based IDE.

    In the wake of the COVID-19 pandemic, there’s naturally a lot more focus on automation and developer productivity. Most developers will be working from home for the foreseeable future to help combat the spread of the virus. Of course, most developers have been writing code outside the office for years. The challenge now is enabling teams of developers to develop applications as efficiently as possible regardless of where they are located. Eliminating inefficient manual tasks such as maintaining local development environments could be a significant step in that direction.

    It’s not clear yet whether DevOps teams are more or less productive since the onslaught of the COVID-19 pandemic. However, it is apparent the need for a consistent experience among teams of highly distributed developers is acute.

  • Why We Need a Software Bill of Materials Industry Standard

    Why We Need a Software Bill of Materials Industry Standard

    The SBOM concept is part of is an industry-led, multi-stakeholder process to improve software component transparency

    Have you ever gotten a recall notice for the vehicle you drive? Perhaps your car or truck was part of the big recall on airbags a few years ago. It’s standard procedure for auto manufacturers to notify owners of their vehicles when a component is defective and needs to be repaired or replaced. This is true even if the component was made by a third party because it’s still part of the overall makeup of the vehicle.

    Such recalls are possible because manufacturers keep a bill of materials to know every single original thing, including physical parts and internal software, that goes into each vehicle. Title registration records kept by government agencies keep track of current owners of the vehicles. When a recall is necessary, it’s possible to identify which vehicles are affected and who owns them.

    Now the computer software industry is undertaking a similar effort to track individual components such as libraries, executables or source code that go into a software program. Initiated by the National Telecommunication and Information Administration (NTIA), the effort is an industry-led, multi-stakeholder process to improve software component transparency. The NTIA working group is establishing a shared vision of transparency and a “software bill of materials,” or SBOM.

    What Is a Software Bill of Materials?

    An SBOM is effectively a list of ingredients that makes up a software program or application. Like the auto industry, where components come from hundreds or thousands of suppliers, modern software is stitched together from bits of code and subroutines from numerous sources, including open source and commercial solutions. Reusing software code like this means developers don’t have to create everything from scratch themselves. It’s a great time-saver and a very efficient way to develop applications.

    Fig. 1: Software component relationships


    Source: www.ntia.gov

    A software bill of materials identifies and lists all software components, information about those components and the relationship between them. Figure 1 below illustrates this concept. The chart on the left shows the information that is tracked, while the diagram on the right illustrates the relationships of the software components.

    As the NTIA working groups go through their development phases, they are mindful of the inherent complexity of building and maintaining a verifiable software components list. Issues they are currently working on include how to automatically generate an SBOM and keep it up to date; what standard data format to use for the information; how to distribute an SBOM to someone who acquires a software program or application; and how to verify the authenticity of the data in the components list and their inherited dependencies. The intent is to define specifications that can be used worldwide by both developers and consumers of software. The adoption of SBOM by individuals and companies writing open source software will be key to the initiative’s success.

    The Need for a Software Bill of Materials

    There are several benefits to establishing greater transparency of what code components are in software. Most importantly, it allows companies to control risk by enabling earlier identification and mitigation of vulnerable systems or license infringing source code. Further, it incentivizes secure software development practices by enabling developers to better vet the code they are embedding into their own work. For software consumers, greater transparency supports informed purchasing decisions, especially where compliance with software licensing requirements is concerned.

    Perhaps the greatest value of having a verified SBOM is in the realm of cybersecurity and risk mitigation.

    According to industry studies, the average codebase contains hundreds of open source software components, and the majority of those codebases contain at least one vulnerability. Thus, having insight into code components and their vulnerabilities is critical.

    Once you know precisely what components are in your software, you can get a clear vision of the risk factor this specific bill of materials brings to your environment when it runs. What’s more, the risk factor can change whether or not something in the software bill of materials changes since new vulnerabilities are discovered on a daily basis. The only way to know if you are affected is by having this level of transparency.

    This means of risk assessment is especially relevant when changes are attributed to insider or outsider threats. An insider threat occurs when an internal employee changes something without understanding the full impact of that change on the overall risk; for example, installing a foreign application to SBOM considered to be shadow IT. An outsider threat occurs when an attacker injects malware into your server or a device and tries to make it look like a legitimate component of your system by replacing or introducing a new software component. Either way, expecting to have one component and actually having another introduces a lot of risk to your system.

    Cybersecurity companies will be able to develop solutions that can consume the SBOM in a standard way and cross-reference it with everything running on the system, including the reference to known or new vulnerabilities in the listed software components, and augmented by threat intelligence. Recommendations for mitigations such as software patching can then be put forward. This is commonly called a healing process. In some cases, auto-remediations steps can be taken, such as blocking the malicious software from running until it can be removed.

    Governance over software licenses can be improved through SBOM adoption. Every bit of software comes with a license that dictates the legal use and distribution of the software. The snippets of code in a supply chain that comprises a complete application can have many different licenses for the individual components. Any company that deploys that application has a legal obligation to comply with the licenses. Without a software bill of materials, there may be no way to know what the licenses require, or how to comply with them. 

    Beyond Software: Devices, Too

    There’s another concept that goes beyond just software known as a digital bill of materials, or DBOM. A DBOM extends to the hardware configuration and its embedded firmware and includes the interaction between the components, i.e., the behavioral context. A DBOM would collect the same sort of knowledge about hardware devices and network communication patterns to understand the context of the software materials running on the device. This would apply mostly to IoT devices that otherwise are challenging to monitor, update and protect.

    When you buy a device, you are essentially buying a black box because you don’t know exactly what’s going on inside. If you install it on your network, you don’t know what risks come with this black box. If you knew the risks, you could put mitigations in place. Thus, it’s important to motivate the device manufacturers to get behind the adoption of both SBOM and DBOM specifications and help them recognize how it can improve their operations and security posture. There is value in complying with security certification requirements such as ETSI, allowing their end users to understand the risks they are assuming, and empowering them with the ability to mitigate these risks.

    The medical technology industry has been at the forefront of creating a proof of concept initiative in 2019 to understand the role that SBOMs can play in managing the operational and cyber risks associated with medical devices. Working together, device manufacturers and healthcare providers demonstrated the feasibility of SBOMs by generating, sharing, and using data to improve security practices in pre-defined use cases. NTIA is applying the lessons from that PoC to develop industry-agnostic specifications for the applications of software bills of materials.

  • Spotify Adds Custom Deployment Templates to Service Catalog Project

    Spotify Adds Custom Deployment Templates to Service Catalog Project

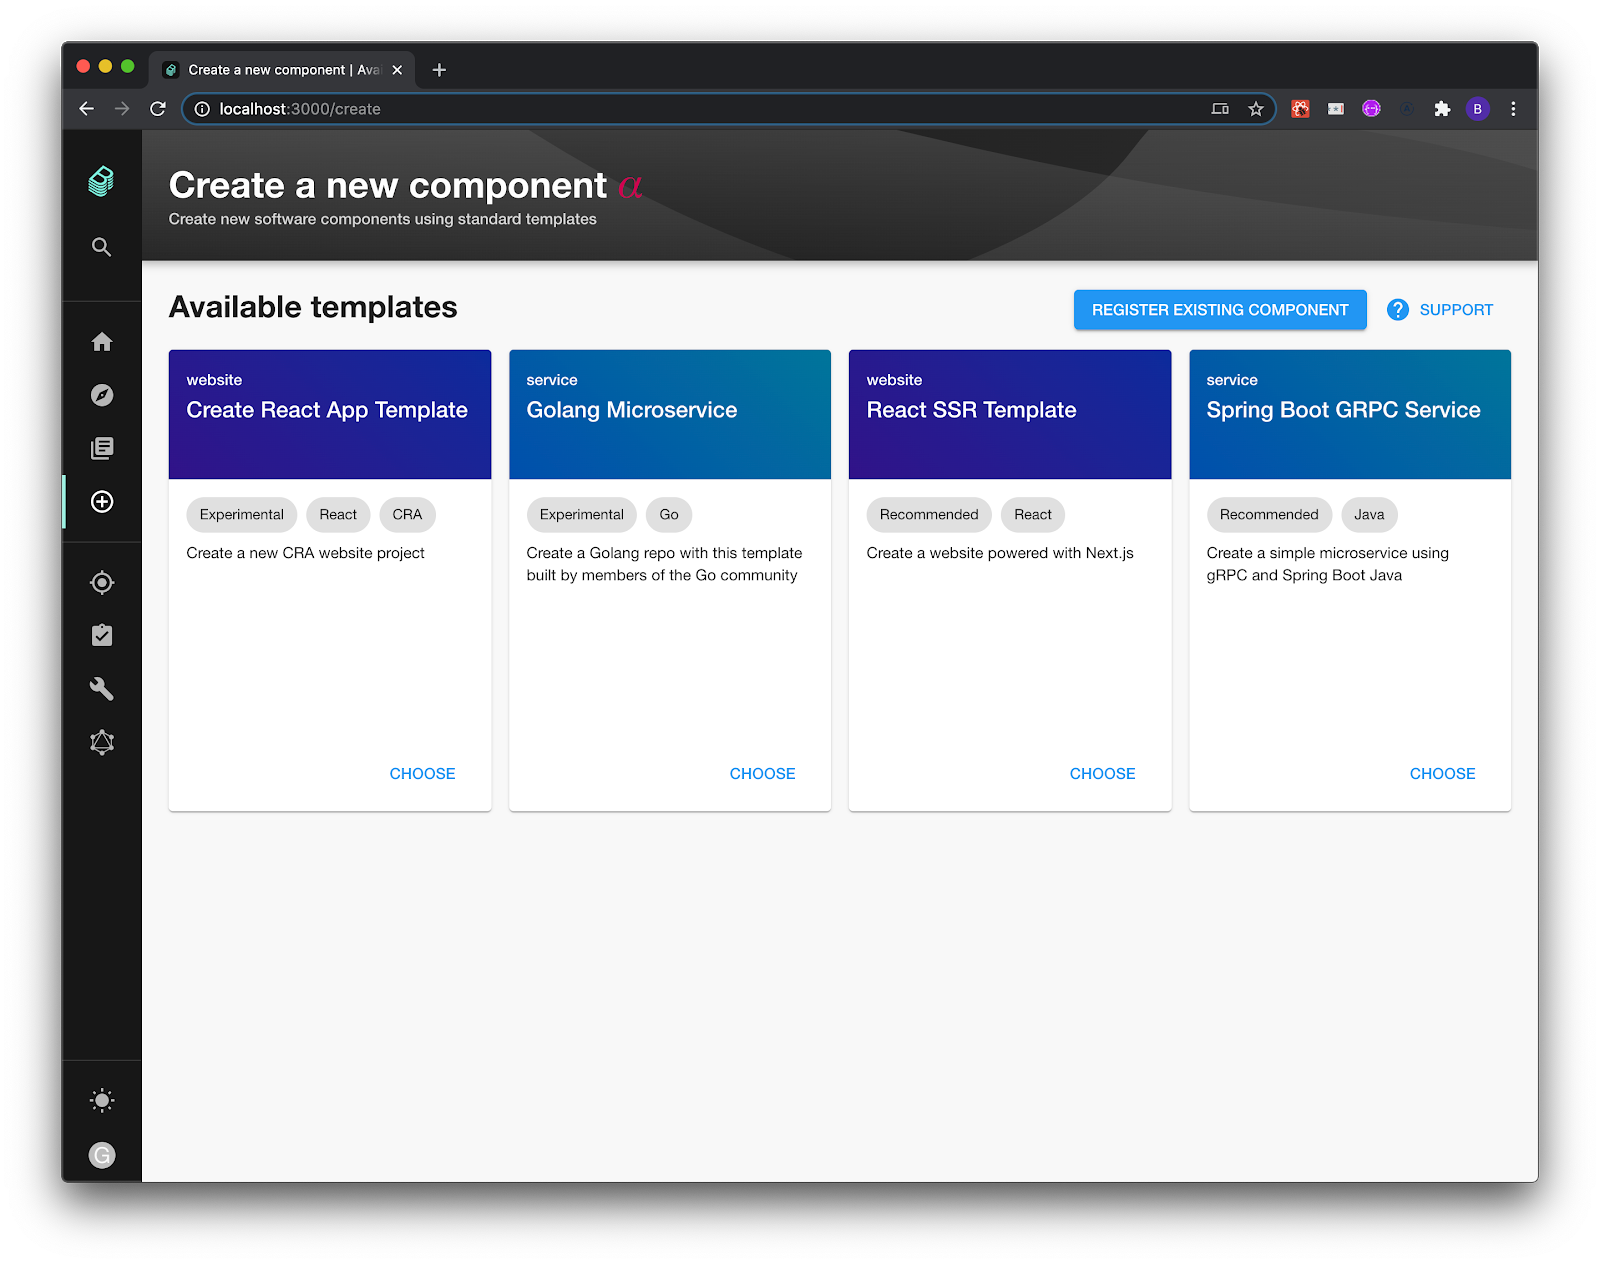
    Spotify has entered the next phase of the open source Backstage catalog project by adding support for templates through which the process of deploying software components now can be automated.

    Backstage was developed by Spotify to create an open source catalog through which DevOps teams could build portals through which developer tools are centrally managed.

    Stefan Ålund, platform developer experience product lead for Spotify, said the goal is to bring some order to what otherwise would be a chaotic IT environment. By standardizing the tools made available to developers, Backstage enables IT organizations to develop more consistent workflow processes, he noted.

    Ålund said DevOps teams via custom templates can automate those workflows to the point where a microservice, website or other software component can be deployed via a single click. That approach also serves to encourage reuse of both developer tools and the modules those tools were used to create, he said.

    In some instances, those templates will eliminate the need to depend on site reliability engineers (SREs) to deploy the same code over and over, he added.

    Spotify is currently proposing to make Backstage a sandbox-level project that would be further developed under the auspices of the Cloud Native Computing Foundation (CNCF).

    In the meantime, Alund said Spotify will continue to refine a service catalog that has been widely employed across DevOps teams for the past four years on top of a core instance of the open source Jenkins continuous integration/continuous deployment (CI/CD) platform.

    It’s not clear how DevOps-mature an organization must be to realize the need for a catalog through which modules of code could more easily be reused. In some cases, the transition to microservices may inevitably force the issue. Rather than having developers potentially reinventing the microservices wheel, a portal would make it easier to discover what software assets already exist and deploy them automatically.

    A catalog also provides the added benefit of making it easier to track the provenance of a project as well as who currently has operational responsibility for it within the context of a larger software supply chain enabled by best DevOps practices, Alund noted.

    Regardless of the level of DevOps maturity inside an organization, the need for a catalog to track services quickly becomes apparent as the number of microservices developed increases. It’s said that every company is now a software company. If software is to be managed as a digital business asset, then it’s critical for organizations to determine what modules of code they have and then determine which modules are the most valuable to the organization.

    Only then can every company that aspires to be a provider of software that happens to manufacture something or provide a service be managed like a true software company. Anything short of that goal is just a mere statement of aspiration.