Category: Doin’ DevOps

  • Continuous Testing vs. Test Automation: 3 Key Differences

    Continuous Testing vs. Test Automation: 3 Key Differences

    Testers have been wrestling with test automation for years, yet most teams are not satisfied with their current level of test automation or the overhead required to maintain it. Additionally, the past few years have brought a sea change in the way that applications are architected, developed and consumed—increasing both the complexity of testing and the business impact of software failures.

    How can software testing professionals help the business control risk in light of the increased complexity and pace of modern application delivery? Enter continuous testing.

    What is Continuous Testing?

    Continuous testing is the process of executing automated tests as part of the software delivery pipeline to obtain feedback on the business risks associated with a software release candidate as rapidly as possible.

    Test automation is designed to produce a set of pass/fail data points correlated to user stories or application requirements. Continuous testing, on the other hand, focuses on business risk and provides insight on whether the software can be released. To achieve this shift, we need to stop asking, “Are we done testing?” and instead concentrate on, “Does the release candidate have an acceptable level of business risk?”

    Why Do We Need Continuous Testing?

    Today, changes across the industry are demanding more from testing while making test automation more difficult to achieve (with traditional tools and methods, at least):

    • Application architectures are increasingly more distributed and complex, embracing cloud, APIs, microservices, etc., and creating virtually endless combinations of different protocols and technologies within a single business transaction.
    • Thanks to Agile, DevOps and continuous delivery, many applications are now released anywhere from every two weeks to thousands of time a day. As a result, the time available for test design, maintenance and especially execution decreases dramatically.
    • Now that software is the primary interface to the business, an application failure is a business failure—and even a seemingly minor glitch can have severe repercussions if it impacts the user experience. As a result, application-related risks have become a primary concern for even non-technical business leaders.

    How Is Continuous Testing Different From Test Automation?

    The main differences between continuous testing and test automation can be grouped into three broad categories: risk, breadth and time.

    Risk

    Businesses today have not only exposed many of their internal applications to the end user, they also have developed vast amounts of additional software that extends and complements those applications. For example, airlines have gone far beyond exposing their once-internal booking systems. They now let customers plan and book complete vacations, including hotels, rental cars and activities. Exposing more and more innovative functionality to the user is now a competitive differentiator—but it also increases the number, variety and complexity of potential failure points.

    Large-scale “software fails” have such severe business repercussions that application-related risks are now prominent components of a business’ public financial filing. Given that notable software failures resulted in an average -4.06 percent decline in stock price (which equates to an average of negative $2.55 billion loss of market capitalization), it’s not surprising that business leaders are taking note—and expecting IT leaders to take action.

    If your test cases weren’t built with business risk in mind, your test results won’t provide the insight needed to assess risks. Most tests are designed to provide low-level details on whether user stories are correctly implementing the requirements—not high-level assessments of whether a release candidate is too risky to release. Would you instantly stop a release based on test results? If not, your tests aren’t properly aligned with business risks.

    To be clear: We’re not suggesting that low-granularity tests aren’t valuable; we’re stating that more is needed to stop high-risk candidates from going out into the wild.

    Breadth

    Even if a business manages to steer clear of large-scale software fails that make the headlines, even seemingly minor glitches can still cause trouble these days. If any part of the user’s experience fails to meet his expectations, you not only risk losing that customer to a competitor—you also risk brand damage if that user decides to take his issues to social media.

    Just knowing that a unit test failed or a UI test passed doesn’t tell you whether the overall user experience is impacted by recent application changes. To protect the end user experience, you need tests that are broad enough to detect when an application change inadvertently impacts functionality which users have come to rely on.

    Time

    Now that the speed at which organizations ship software has become a competitive differentiator, the vast majority of organizations are turning to Agile and DevOps to accelerate their delivery processes.

    When automated testing emerged, it focused on testing internal systems that were built and updated according to waterfall development processes. Systems were all under the organization’s control, and everything was completed and ready for testing by the time the testing phase was ready to start.  Now that Agile processes are becoming the norm, testing must begin in parallel with development; otherwise, the user story is unlikely to be tested and deemed “done done” within the extremely compressed iteration time frame (often two weeks).

    If your organization has adopted DevOps and is performing continuous delivery, software may be released hourly—or even more frequently. In this case, feedback at each stage of the process can’t just be “fast”; it must be nearly instantaneous. If quality is not a top concern for your application (e.g., if there are minimal repercussions to doing a rollback when defects are discovered in production), running some quick unit tests and smoke tests on each release might suffice. However, if the business wants to minimize the risk of faulty software reaching an end user, you need some way to achieve the necessary level of risk coverage and testing breadth—fast.

    For testing, there are several significant impacts:

    • Testing must become integral to the development process (rather than a “hygiene” task tacked on when development is complete)
    • Tests must be ready to run almost as soon as the related functionality is implemented
    • The organization must have a way to determine the right tests to execute at different stages of the delivery pipeline (smoke testing upon check-in, API/message layer testing after integration, end-to-end testing at the system level, …)
    • Each set of tests must execute fast enough that it does not create a bottleneck at the associated stage of the software delivery pipeline
    • A way to stabilize the test environment is needed to prevent frequent changes from causing an overwhelming number of false positives

    Continuous Testing> Test Automation

    If you only take one idea away from this article, we hope that it’s this:

    Test automation ≠ continuous testing

    Continuous testing > test automation

    Even the teams that have achieved fair levels of success with traditional test automation tools hit critical roadblocks when their organizations adopt modern architectures and delivery methods:

    • They can’t create and execute realistic tests fast enough or frequently enough
    • The constant application change results in overwhelming amounts of false positives and requires a seemingly never-ending amount of test maintenance
    • They can’t provide instant insight on whether the release candidate is too risky to proceed through the delivery pipeline

    It’s important to recognize that no tool or technology can instantly “give” you continuous testing. Like Agile and DevOps, continuous testing requires changes throughout people, processes and technology. However, trying to initiate the associated change in people and processes when your technology is not up to the task will be an uphill battle from the start … and ultimately a losing one.

    If your organization is starting or scaling your continuous testing automation efforts, we encourage you to review two new pieces of research by Forrester and Gartner. Both reports provide insight into continuous testing and test automation trends as well as how the top continuous testing tools compare.

    About the Author/Wayne Ariola

    Wayne Ariola (1)Wayne Ariola, CMO of Tricentis, is a recognized thought leader on software testing topics such as continuous testing, risk-based testing, service virtualization, and API testing. Wayne has created and marketed products that support the dynamic software development, test, and delivery landscape. He has driven the design of many innovative technologies and received several patents for his inventions. He has been a contributor to the software testing space for fifteen years and in the software industry for more than 20 years. Connect with him on LinkedIn.
  • Spurring the DevOps Adoption Journey

    Spurring the DevOps Adoption Journey

    Every few years, the IT canvas is splashed with a new initiative that sparks enthusiasm among businesses and technologists alike. DevOps is one such philosophy gaining significant momentum in today’s digital transformation landscape. At the same time, the concept remains misunderstood and adoption is slow.

    DevOps embodies Development plus Operations within software development. Traditionally, these two parts of an organization have operated siloed from one another with marked differences in both ethos and approach. The result: delays in launching products and releases to the market. The fundamental principles of DevOps are to reduce barriers between Development and Operations; increase Development autonomy; and to automate Development and Operations activities to reduce wait time (and waste from a customer’s perspective), thus enabling faster time to market—all while keeping the end customer at the center.

    Planning the Adoption Journey

    Here are four different aspects an organization should consider before starting the DevOps adoption journey:

    Conduct an as-is continuous delivery assessment on product development practices and processes within the organization

    This will best determine an organization’s current maturity level across several different parameters, including:

    • Culture and organization
    • Build management and continuous integration
    • Environments and deployments
    • Release management
    • Testing and verification
    • Data management
    • Design and architecture
    • Information and reporting

    This process also includes identifying current automation levels and opportunities to automate, inclusiveness of tools and environments supporting continuous delivery, and an assessment of existing product design to determine if it lends itself to frequent and fast deployments.

    Map the journey of a piece of code from a developer’s desk all the way to when the consumers use it

    Utilizing a development pipeline assessment to study the life cycle of a piece of code through its journey from a developer’s desk to production will best identify “waste” during the life cycle. This assessment should bring out critical information, including the number of environment hops, test pyramid maturity and level of continuous testing, level of provisioning and deployment autonomy and its automation.

    Establish a culture of inclusiveness, autonomy and a sense of a ‘common goal’ within the organization

    Product management, development and operations teams should have a common mission and goal for the product, sprint or release they are working on. The definition here should be the value delivered to the customer as opposed to the value of code, test results, or individual deployment steps. Including operations roles within a close-working scrum team benefits this cause by:

    • Bringing in common views on what a product, release or sprint is intended to deliver.
    • Creating an opportunity to bring forward and address operations needs during the development cycle.
    • Creating a better understanding of mutual expectations and empathy for delivering outcomes that meet customer expectations.

    Measure and track

    Finally, determine parameters the organization would like to establish to track progress towards a successful adoption. The key here is to have a few, simple metrics that truly reflect “value to the end customer.” Here are a few commonly considered metrics:

    • Production deployment frequency: The number of product releases within a specified time.
    • Average lead time for a production change: The typical amount of time it takes for a piece of code to traverse from a developer’s desk through production.
    • Average production recover time: The time taken to bring back production systems after an incident involving a release, release rollback or system outage.
    • Change failure rate in production: The number of releases that did not stick in the live environment and needed either a rollback or an immediate emergency fix.

    The goal and a true measure of successful adoption would be an improvement of all these parameters over time. Internally, they would require strong engineering rigor and cultural realignment to be able to improve these customer-facing metrics.

    Navigating DevOps adoption successfully is neither easy nor fast for a number of reasons. DevOps encompasses different parts of the organization, which historically may have operated in silos and with different ethos. DevOps also questions the status quo regarding engineering roles and practices, and focuses on automation and reskilling, all of which need both upfront time and effort investment. Finally, DevOps believes in and propagates continuous learning and improvement, whereas many organizations may have more stepwise-based programs in place.

    For a midsized IT organization, it could take anywhere from 18 to 24 months or more to be able to reach a reasonable steady state. That’s why it is important to carefully craft a charter that encompasses the above parameters before embarking on this DevOps adoption journey.

    About the Author / Amit Gupta

    Amit Gupta is leader of Ness Digital Engineering’s DevOps practice. He has several years of software delivery background. He has keen interest and has developed deep expertise in establishing practical software development processes especially for globally distributed teams. Amit currently leads Ness Digital Engineering’s DevOps practice, and engages with several customers on such areas as improving engineering effectiveness, engineering tools and process transformation. Connect with him on LinkedIn.

  • SauceCon Speaker Profile: Shivani Sharma, Slack

    SauceCon Speaker Profile: Shivani Sharma, Slack

    Just Say No to Flaky Tests: Releasing Code with Confidence

    Shivani Sharma doesn’t like anything flaky—unless it’s baked goods.

    Shivani is senior engineering manager at Slack, working on test automation for Slack’s iOS, Android and web applications. An avid baker, Shivani thinks flakiness should stay in the kitchen.

    Although “flaky” is a common adjective describing automated tests, the Slack test automation team wanted to be better and create value by delivering deterministic results. The team’s mission is “to make our software development process simpler, more productive and our product more pleasant to use.”

    Worthy goals, to be sure. To that end, Shivani will present on, “Releasing Code with Confidence,” at the upcoming SauceCon conference in San Francisco June 6-8. Her presentation will discuss how Slack’s automation team approached the common problem of flaky tests to build a reliable feedback system into their continuous integration pipeline for code hundreds of developers write and release every day. This talk will provide actionable takeaways that can be used in other organizations, too.

    In addition to baking and “crème brûlée-ing,” as she describes it, Shivani is an avid runner and has run eight half-marathons. To give her knees a break, she’s excited to participate in her first Olympic distance triathlon this summer. She has spent 10 years working in Silicon Valley, holding positions at Google, BigFix and IBM, as well as Slack. Shivani holds a BS in Electrical Engineering from UCLA.

    SauceCon, the first-ever Sauce Labs user conference, is a three-day event filled with training, workshops, best practices and visionary content from the leading minds in automated testing. For more on upcoming SauceCon presentations or to register, visit the SauceCon website.

    About the Author / Rebecca Cramer

    Rebecca Cramer is a writer and communications strategist specializing in technology. With more than 20 years of experience across disciplines including marketing, internal and executive communications at companies such as Dell and Quest Software, Rebecca is passionate about creating and sharing good content of all kinds. In her spare time, she enjoys spending time at the beach and hiking in her native Southern California.
  • Improving DevOps Success with Well-Defined Metrics

    Improving DevOps Success with Well-Defined Metrics

    Collaboration within diverse project teams is often more difficult to achieve when there is no clearly visible aim, the planning is haphazard and the information shared is inadequate. However, these are crucial hurdles to overcome in any organization—and more so in product companies with globally distributed teams working on different parts of the product pipeline.

    Successful product development requires effective and constant communication between various teams through well-defined metrics, not only to reduce the engineering operations overhead but also to improve on the overall engineering deliverables.  These metrics, including  ROI or profitability, mean time to recover and deployment frequency provide a clearer picture to an engineering or business owner on how the Dev and Ops teams are working, their adherence to processes and guidelines and the technology they’re using.

    Every engineering owner likes to know if the technology investment they make is going to yield a significant ROI. It is no different with DevOps. It is important to identify the exact metrics by which the positive impact of DevOps can be measured.  The most effective way to illustrate these metrics in a way that would make sense to senior management is revenue impact.  Here are a few of them which have had proven success on internet of things (IoT) projects.

    Business metrics such as cycle time impacts incremental sales and customer satisfaction. Whereas other business metrics such as product investment and running costs impact profitability, DevOps implementation effectiveness can be measured by both. Cycle time is, in turn, derived from a number of product features delivered, sprint velocity and release planning metrics. The lower the cycle time, the more features get pushed and impacts the go-to-market. It also results in potential incremental revenue in terms of the value brought by reducing the cycle time.

    Another dimension to measure DevOps impact is engineering metrics. Companies today are worried about the cost of downtime in the operational phase as much as they worry about time it takes to bring the product to market. DevOps metrics are valid throughout the end-to-end implementation of a project.

    Build automation and code quality analysis, for example, can provide significant savings in build cycle time and build rollout time. Automating deployment process improves time to deploy and sprint velocity. Continuous testing improves mean time to resolve, and CloudOps monitoring tools can help reduce mean time to recover and uptime of any application. Further collaboration in automation through ChatOps tools can help improve mean time to respond. Once set in motion, all these matrices start improving the product quality, which leads to less rework. Intelligent automation also incurs direct productivity benefits.

    Organizations now measure these codes to release the metrics at the end of the day to get maximum ROI. A lot of these metrics also depend on the DevOps capability maturity. Organizations at the higher end of the maturity spectrum would tend to measure all of these metrics and try to optimize them. Also, the emphasis of these metrics vary with the domain and stage of the product life cycle being worked on. Home automation companies developing their IoT platform, for example, would emphasize build and deployment metrics, whereas companies in industrial automation with large infrastructure deployment would look at CloudOps monitoring metrics more closely. For telematics companies, test automation metrics become important when there is limited time and bandwidth to capture the data.

    DevOps is a cultural transformation and most of the time businesses measure the effectiveness in a very obvious way. However, a change in the way the organization operates should be looked in such a way that the metrics can generate long-term value. Thus, continuous measurement of the DevOps practice should also become one of the major focus areas of DevOps teams.

    About the Author / Urvashi Babaria

    Urvashi Babaria is a Product manager at eInfochips working in new age areas like IoT, DevOps and CloudOps. She is a techno commercial marketer with nine years of experience in product and project management, business analysis and transformation. She has keen interest in areas of data science including visualization, analytics and modeling. You can start a conversation with her at urvashi.babaria@einfochips.com

  • SauceCon Profile: Greg Sypolt, Gannett

    SauceCon Profile: Greg Sypolt, Gannett

    Using Design Patterns to Improve Automated Testing

    Test automation architect Greg Sypolt of Gannett | USA Today Network fell into a testing career by accident. As an on-call software engineer who spent many late nights early in his career discovering that many bugs were caused by a lack of test coverage, he developed a passion for optimizing software and building quality into every stage of the continuous integration pipeline.

    At the upcoming SauceCon conference, Greg will present on, “Using Design Patterns to Improve Automated Testing.” Attendees will learn how to transform their new or existing automated tests to speed development and reduce maintenance impact.

    A self-proclaimed technology geek, Greg is passionate about a few things: DIY projects (he recently finished his basement single-handedly), John Denver songs (one in particular, see below), outdoor sports and speeding up development with design patterns. In Greg’s view, a design pattern is a general reusable solution to reduce commonly occurring problems in software design. A design pattern is not a finished design that can be transformed directly into code. It is a description or template on how to solve a problem that can be used in many different situations.

    At Gannett | USA Today Network, Greg is responsible for leading the test automation architecture team to build and maintain testing solutions, evaluate test coverage, and champion continuous integration across 40+ Gannett products. The test automation organization at Gannett | USA Today Network has built a platform that enables teams to move at their desired pace through a balance of autonomy and collaboration. Their goal is to ensure every team is successful when using the self-service model. The vision is clear for test automation: they believe it starts with everyone on the team owning quality. Making this shift requires daily collaboration and planning to build quality into every stage of the pipeline.

    Greg grew up in a small town in West Virginia (Take Me Home, Country Roads!) and now calls Northern Virginia home. He is a husband, father of three kids and an avid do-it-yourselfer. Greg enjoys presenting at conferences and blogging about automated testing strategies, testing frameworks, standards and continuous integration.

    Join Greg and other presenters at SauceCon, the first-ever Sauce Labs user conference. SauceCon is a three-day event filled with training, workshops, best practices, and visionary content from the leading minds in automated testing. For more on upcoming SauceCon presentations or to register, visit the SauceCon website.

    About the Author / Rebecca Cramer

    Rebecca Cramer is a writer and communications strategist specializing in technology. With more than 20 years of experience across disciplines including marketing, internal and executive communications at companies such as Dell and Quest Software, Rebecca is passionate about creating and sharing good content of all kinds. In her spare time, she enjoys spending time at the beach and hiking in her native Southern California.

  • Measuring What Matters in Evaluating Software Performance

    Measuring What Matters in Evaluating Software Performance

     When developing and deploying a new feature or application, performance (speed, reliability) must be closely analyzed. After all, there’s no benefit to delivering a product if it doesn’t work well or users are forced to stare at a spinning wheel. To get a true view of performance, many organizations rely on metrics—a smart move since metrics, much like the scale, do not lie. Right?

    Unfortunately, that’s not always the case. Even when metrics are used, there often are different interpretations of performance, as well as debate over which metrics should be used in the first place. Metrics can be biased and manipulated, but does that mean we should stop using them? Of course not. Instead, we must learn to weed out bias and metric manipulation.

    What is Bias?

    Bias is not a bad thing; everybody is biased to some degree. Bias is defined as a particular tendency, inclination, feeling or opinion, especially one that is preconceived.

    Two common biases are anchoring and confirmation bias. Anchoring is the tendency to rely on a single piece of information, usually the first piece of information we encounter. The statistics presented first will most likely be remembered and drive decisions, responses and reactions.

    Imagine you’re about to launch a new application, but before doing so you run some performance tests to see how fast the application loads. The initial tests show the load time is 10 seconds. That’s too high, so the team looks for ways to improve performance. A few weeks later response times drop to 6 seconds, a 40 percent improvement. That’s great, and everybody celebrates. But what if initial tests showed page load times of 4 seconds and a few months after launch times crept up 40 percent to 5.6 seconds. Would you still be celebrating? No, you would be looking at what went wrong and trying to fix it. The initial anchor influences whether you see a time as positive or negative. 5.6 seconds is better than 6 but the initial anchor makes 5.6 seem worse.

    Confirmation bias is the tendency to interpret and search for information that confirms a pre-existing hypothesis. If you believe a new feature does not add value to an application, you may be more likely to focus on negative statistics rather than positive ones. If testing shows application load times will increase 15 percent with the new feature, you may use that as proof to delay or stop the release of the feature. If, however, you think the feature is a real game-changer, you will find the research about the 20 percent rule, which says people perceive changes in speed when the difference is at least 20 percent faster or slower. A change in 15 percent won’t be perceived by users. At the core, confirmation bias is about ego and not wanting to be wrong.

    The first step to avoiding biases is acknowledging they exist and everybody—yes even you—is susceptible. But there are ways to avoid them, or at least minimize their impact. Create your own anchor. Do research to determine what is an acceptable response time and use that as the anchor point. Search for facts that support and oppose your viewpoint, and don’t stop with a single site or fact; find multiple sources. Foster an environment where disagreement is encouraged in a positive and constructive manner, and listen to the dissenting viewpoints. Ask better questions and be willing to accept the answers even if they aren’t what you were seeking.

    Avoiding Metric Manipulation

    Metrics should be actionable and tied to business goals as opposed to being purely “vanity metrics”—those metrics that may make everybody feel good, but don’t reflect the true user experience and the consequent impact on the business.

    Specific to measuring web performance, there are countless metrics that can be selected to determine whether a user experience is positive or negative. If you choose to measure the time to the onload event as the core metric, you can recode a page to defer items to after the onload event. The metric will go down, teams will celebrate, but did this have any impact on the user experience? Was the goal really to reduce onload time or was it to better satisfy end users through a faster site in their eyes, increasing conversions and time spent on site?

    Here is a quick checklist you can use to choose the right user performance metrics:

    • Do improvements or declines in this metric impact what really matters: the user perception and business performance? Can this correlation be clearly made? How will this metric show progress towards the businesses goals and objectives?
    • Can the metric be gamed or influenced? Once something is being measured, people may look for ways to game the system and show improvement when in actuality there is none.
    • Is the metric “good enough”—i.e., the best one available, although it may not be perfect? Though not a performance-related example, popular website Medium’s choice of top-line metric illustrates this approach. While most websites rely on unique site visitor numbers as the ultimate gauge for their success, Medium, which views high user engagement as their key success factor, instead measures the time users spend reading articles on the site. This may not reflect the totality of user engagement (visitors who come to the site, but may just scan, not read) but it’s good enough and a more realistic indicator than alternatives.

    Whether we like it or not, people are heavily guided by bias and emotion, and they often manipulate reality (even subconsciously) to support their own motivations. Performance metrics are and always will be central to evaluating software performance, but it’s not enough to just lay out the facts. Organizations must frame and present metrics appropriately and sufficiently, and focus on those that are the most relevant and reliable. These are the keys to delivering the most complete, impartial canvas of performance information, helping guide the best decisions in the interest of the business.

    About the Author / Dawn Parzych

    Dawn Parzych is Director of Product and Solution Marketing at Catchpoint. She enjoys researching, writing and speaking about trends related to application performance, user perception, and how they impact the digital experience. In 15+ year career, Dawn has held a wide variety of roles in the application performance space at Instart Logic, F5 Networks and Gomez. Connect with her on LinkedIn.
  • Infographic: DevOps Strategies for Mobile App Development

    Infographic: DevOps Strategies for Mobile App Development

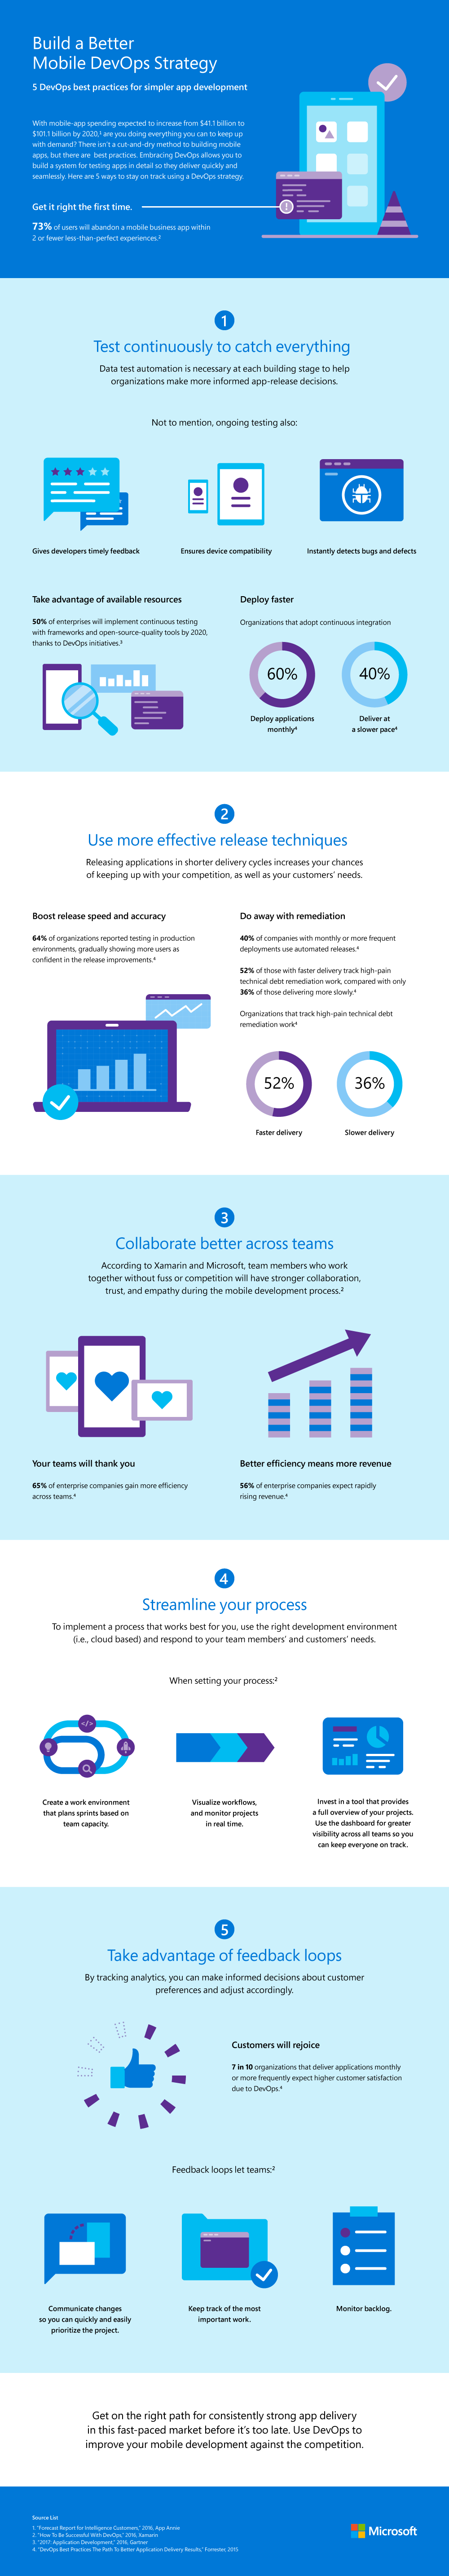
    Is DevOps a part of your mobile app development strategy? Are your teams working at their most efficient to keep up with the demands of an increasingly mobile-first society? Here are five tips and tricks to help you simplify and improve your app development process, courtesy of Microsoft Mobile Center.

  • DevOps: Trust, Obligations and Promises

    DevOps: Trust, Obligations and Promises

    Mark Burgess (@markburgess_osl) is a theoretical physicist, but in his keynote at the 2016 All Day DevOps conference, he talked more about economics and human interactives than physics. What does either have to do as the keynote for a conference on DevOps?

    Well, for a little more background, Mark Burgess is also the founder and former CTO of CFEngine, a configuration management and automation framework, and is the author of “Promise Theory.” While at CFEngine, Mark worked to apply a theory of how the autonomous agents in software interact with each other. Promise Theory was born.

    Exploring Promise Theory

    Promise Theory sits counter to obligation theories. Obligation theories view human interactions and behavior under the assumption that people (or agents, in the case of software) choose behavior based on their obligation to follow the rules. Agents are obligated to take a certain action. Promise theory contends the desire to follow the rules is voluntary and that agents can only be responsible for their own behavior, not the behavior of other agents.

    In his presentation, Mark started out looking at human behavior and trends in our society. For instance, with technological advances, our need for one another is decreasing, even as our interdependence through communication is increasing. For example, our smartphones enable us to do almost anything without the direct interaction of someone else.

    Looking at interactions in society, trust is the basis for our exchanges, working communities, and function as a society. He contends, “The promise is the source of intent by which all promises and observers may calibrate their expectations.” Money is an example of this. Money does not have intrinsic value, but we use it because we trust the backer will stand behind its value and it is more convenient than bartering goods. He explains that in the old monetary economy, banks and governments were the provider of trust; in the new service/IT economy, the service provider is the basis of trust.

    How Agents Make Promises

    How do you model this trust? Enter Promise Theory, which describes how agents make promises with each other and how this leads to trust between them. Mark outlines the “ingredients” of Promise Theory:

    1. Agents and super agents make promises in a scaling hierarchy.
    2. An agent can never make a promise about another agent’s behavior (only its own).
    3. An agent’s promise need not be accepted or used by its intended or unintended recipient!
    4. An agent makes its own valuations: what you have is only worth what another is willing to give you for it.
    5. Dependency invalidates promises.

    At the core of understanding this, you have to understand that collaboration is made up of semantics, what words mean and dynamics: all how things work.  And that our ever-increasing service economy is driving us to an explosion of semantics, because words matter so much more than the mechanics. As an example, Mark sketched the hierarchy of promise dependencies in the old and new economies. Looking at the old economy, where we have more dynamic money, the hierarchy is:

    Retail→ Money→ Banks→ Central Banks→ Government.

    In the new economy, where we have more semantic services, the hierarchy is:

    Client→ Network Availability→ Provider→ Internet Authorities→ Company/Service Organization.

    The Need for Cooperation

    None of these systems could work without cooperation at the bottom of it all. So, production is a cognitive process between the producer and the consumer, but also between the agents inside those organizations that have to interact. Often we create pipelines to describe these interactions, but the interdependencies within the systems are often much more complex than the pipeline can model.


    This is all just the tip of the iceberg. Mark has three books that dive into it in detail: “Thinking in Promises,” “In Search of Certainty,” and, “Promise Theory.”

    In the end, Mark made the point that technology does an excellent job of both binding us together and pulling us apart. We need to be careful that we don’t take ourselves out of the systems we create, or we could scale ourselves out of existence.

    devopsy.kinsta.cloud Supports the All Day DevOps Conference

    If this piqued your interest, you can watch Mark’s full All Day DevOps conference session (just 40 minutes).  When you do, you can view the other 56 presentations from the 2016 conference online and free of charge.  Finally, be sure to register you and the rest of your team for the 2017 All Day DevOps conference here.  This year’s event will offer 96 practitioner-led sessions (no vendor pitches allowed).  It’s free and online on Oct. 24.  devopsy.kinsta.cloud is a media sponsor for All Day DevOps 2017.

    — Derek E. Weeks

  • SauceCon Speaker Profile: Jeremy Stone, Code.org

    SauceCon Speaker Profile: Jeremy Stone, Code.org

    “Moving Fast and Changing the World”— Jeremy Stone and Code.org’s mission to transform CS education and America’s STEM workforce

     As quickly as the world is changing, how can we use this momentum and proactively contribute to this change? We need to start with the basics and focus on education. Jeremy Stone, CTO of Code.org, is doing just that by teaching children how to code.

    Jeremy leads the engineering team at Code.org. His team is responsible for Code.org’s software products, including Code Studio and Hour of Code, which are focused on bringing computer science education to all schools for all kids.

    Jeremy has worked in numerous fields including edtech, cleantech, video games, high-scale online services and operating systems. He was previously VP of Engineering at Clean Power Research, where he built enterprise software products for the renewable energy industry, and prior to that he worked at Valve building games and the Steam online service. He also was a founding member of the Internet Explorer team at Microsoft.

    Computer science has never been more important, and it is never too early to start coding. The mission of the non-profit organization Code.org is exactly that—to bring computer science to all kids and increasing the participation of women and underrepresented minorities.

    Jeremy’s talk, “Moving Fast and Changing the World,” focuses on Code.org’s mission to transform computer science education and America’s STEM workforce. It will also explain why it’s important for Code.org to move fast, and why deep and sophisticated automated test investments are critical to its success. Critical for Code.org is to be able to perform automated testing on a large browser matrix, as many schools tend to run older browsers. Smarter, better and deeper automated testing is one of the key stories in the industry right now and Code.org is pushing further every year.

    “I am excited to share our stories and experiences, learn great ideas from the other talks, and then go put those ideas into practice—looking forward to us all working as a community to advance the state of the art this year,” Jeremy says.

    When Jeremy is not trying to change the world, he is helping his 9-year-old son chase his dreams by proofreading his son’s literary pieces, including the recently published novel, “I Lost My Heart in the War of 1875: A Love Story.”

    SauceCon, the first-ever Sauce Labs user conference, is a three-day event filled with training, workshops, best practices and visionary content from the leading minds in automated testing. For more on upcoming SauceCon presentations or to register, visit the SauceCon website.

    About the Author / Elizabeth Hechtel

    Elizabeth is a passionate tech writer at Sauce Labs. As a Marketing Specialist she is focusing on delivering the best quality content on mobile testing. Personally, she loves learning new languages and reading up on recent advancement of modern technology.
  • SauceCon Speaker Profile: Mike Millgate, Optum

    SauceCon Speaker Profile: Mike Millgate, Optum

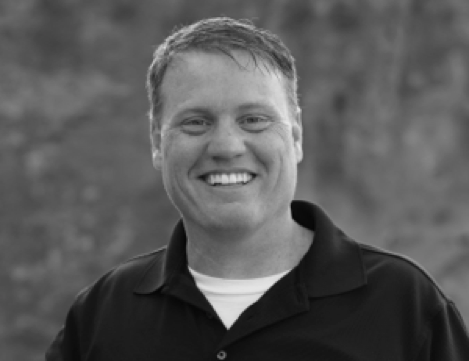
    Automation architect Mike Millgate wants to work himself out of a job. Of course, he doesn’t want to make himself obsolete. He simply wants to automate testing so that QA teams can free their time to do other strategic exercises, such as exploratory testing and focus on security.

    Mike knows what he’s talking about. At Optum, a health services and innovation company, he manages a suite of tests that runs in three hours, testing 18 different applications and more than 24,000 total test cases. He is passionate about parallelization, and notes that if the tests weren’t running in parallel, they would take 55 days to run.

    At the upcoming SauceCon conference, Mike will present, “Testing at the Speed of Concurrency,” taking attendees on a journey of in-house machine testing into cloud-based testing. He will show what works and what doesn’t, and how to use parallelization to improve efficiency as the machines are increasingly doing the work.

    Mike hopes his presentation will help attendees learn how to perform massive numbers of tests in parallel, whether they are using Sauce Labs or another test platform. His mantra is, “Quality is a team effort,” and says the entire team needs to be equally invested to be successful.

    Mike has been at Optum for 15 years. As an expert in test automation in the healthcare industry, he was brought into the tech surge to help fix healthcare.gov in 2013. His work in the industry helps Optum achieve its goal: to help people live healthier lives and to help make the health system work better for everyone.

    A resident of southern Utah, Mike loves hiking and exploring nearby national parks with his family. He is passionate about foster care and adoption, having adopted three young boys with his wife. Mike also runs daily and has competed in two marathons.

    Would he say test automation is a marathon or a sprint? “If you do it right, you can get a marathon’s worth of testing done in a sprint time frame,” he says.

    Join Mike and other presenters at SauceCon, the first-ever Sauce Labs user conference. SauceCon is a three-day event filled with training, workshops, best practices and visionary content from the leading minds in automated testing. For more on upcoming SauceCon presentations or to register, visit the SauceCon website.

    About the Author / Rebecca Cramer

    Rebecca Cramer is a writer and communications strategist specializing in technology. With more than 20 years of experience across disciplines including marketing, internal and executive communications at companies such as Dell and Quest Software, Rebecca is passionate about creating and sharing good content of all kinds. In her spare time, she enjoys spending time at the beach and hiking in her native Southern California.