Category: Continuous Delivery

Continuous delivery is a software engineering discipline that allows organizations to consistently develop and release quality software at a rapid pace. It is achieved by automating the software development lifecycle, enabling tasks such as development, testing and release to occur concurrently and continuously.

  • Why API Quality Is Top Priority for Developers

    Why API Quality Is Top Priority for Developers

    It is no secret that web APIs have become increasingly important to the operation of modern businesses. According to RapidAPI’s Developer Survey and Insights report, 61% of developers used more APIs in 2020 than 2019, with 71% planning to use even more in 2021. We are no longer tied to a small number of monolithic service providers. Businesses tend to gravitate toward specialized managed services, such as billing and authentication, which are backed by APIs. Business models for new products and services are constructed based on APIs. Trust has become a necessity for APIs. APIs that perform consistently and with high quality earn trust, and those that do not are abandoned for a competitor.

    Why Does Quality Matter?

    If a market exists for an API, it’s a given that there will be competition. To remain competitive, APIs must build and maintain trust with their consumers; sales and marketing can only go so far. The highest quality APIs will inevitably capture the largest slice of market share. Quality isn’t a destination, either—it is a collection of goals that require continuous investment.

    What Does Quality Mean for an API?

    Just like the code that drives an API, the quality of an API itself is quantifiable. The following facets describe some broad categories used to measure API quality. The weight of each facet will vary depending on how business-critical the API will be when in production.

    Resilient. An API is resilient when it continues to operate in the face of adverse conditions. Can an API continue to operate (even at reduced capacity) if the database is down? How does it handle network traffic spikes?

    Robust. A robust API is liberal in what it accepts, but conservative in what it sends. Will it crash when presented with a poorly formatted request, or respond with instructions on how the caller can fix the problem themselves? Can the code be restructured without breaking the API contract?

    Secure. API security is vital in most deployments. Are efforts made to check for OWASP Top 10 Web App security risks? Are open source vulnerabilities known and addressed in a timely manner? Are secure endpoints gated with authentication?

    Discoverable. APIs that are well documented and well structured are much easier to consume and integrate with other services.

    Consistent. A consistent API is one that changes without negatively impacting existing consumers. Changes are backward compatible or versioned as new features are introduced. API consumers should know far in advance if a breaking change will be coming if it cannot be avoided.

    How Do I Get There?

    Processes, tools and, most importantly, culture, are the key to high-quality APIs. Let’s explore how we can approach each API quality facet.

    Resilient. Processes such as chaos engineering, load testing and manual quality assurance can uncover situations where an API is failing to handle unexpected situations. Deploying your API to a cloud provider with a compelling SLA instead of your own hardware and network shifts the burden of infrastructure resiliency to a service, freeing your time to build features for your customers.

    Robust. A comprehensive suite of automated tests isn’t always sufficient to provide a robust API. Edge cases, unexpected code branches and other unplanned behavior may be triggered by requests that were not considered when writing the test suite. Traditional automated tests should be complimented by fuzz testing to help uncover hidden execution paths. Canary and blue-green deployments can further expose your API to the real world in a limited manner and prepare for when even more unexpected requests will hit.

    Secure. API security is a moving target. It is expected that most APIs are built on layers of open source libraries and frameworks. Software composition analysis is a necessity to stay on top of zero-day vulnerabilities by identifying vulnerable dependencies as soon as they are discovered. OWASP guidance is a must-have—directing API developers to implement attack mitigation strategies such as CORS and CSRF protection. Application logic must be well tested for authorization and authentication.

    Discoverable. For REST APIs, the OpenAPI initiative provides a consistent language for describing the API. Many frameworks, such as Spring Boot, can even generate OpenAPI documentation directly from your code. gRPC-based APIs offer similar benefits by providing both instructions for accessing the API and building the clients to communicate with it. Adding support for GraphQL allows developers to connect multiple APIs together with consistent tooling. Whichever direction you choose, it is vital to keep API documentation up to date and accessible.

    Consistent. To be consistent, the API development process should make incompatible changes obvious. Code reviews can catch many breaking changes right at the source. API contract testing and integration testing can be used to discover API changes as part of the build. When working in a microservices environment, staging environments may alert engineers if an API change will cause problems before production.

    Quality Builds Trust

    According to the RapidAPI survey, 58% of executives said participating in the API economy was a top priority for their organization. The figure was even higher in certain industries such as telecommunications, where the number is 89%. Whether you are building APIs for internal use or for public consumption, your goal should be to earn the trust of API consumers. Investing in the culture, tools and processes to build quality APIs will pave the way to building and maintaining that trust.

  • Leveraging AI in DevOps for Non-Linear Scaleup

    Leveraging AI in DevOps for Non-Linear Scaleup

    With technology evolving in leaps and bounds, AI is shaping the future of digital transformation for every business seeking speed, scalability, quality and flexibility.

    Since DevOps is on the verge of delivering exceptional software development environments, DevOps in AI is undeniably the next breakthrough in technology. We’ve witnessed every industry racing toward the adoption of AI to transform their business. To support this transformation, smart automation solutions coupled with AI implementations is becoming the new normal.

    So if you’re thinking about reinforcing your enterprise’s DNA by leveraging AI, DevOps principles for artificial intelligence are vital to these efforts. Here’s how businesses can unlock the true potential of AI and stay ahead of the curve.

    DevOps and AI

    DevOps has been s game-changer for numerous businesses. Applying AI can helps DevOps teams achieve the operational efficiency of machine learning (ML) models all the way through the journey from design to production.

    Artificial intelligence undeniably enhances automation and fast-tracks the performance of DevOps. Since the digital transformation process is quite challenging for diverse businesses, DevOps and AI ensures the right processes are in place that can further bring flexibility throughout the journey.

    DevOps enables continuous deployment and quick delivery of AI models via:

    • Speed: Improved overall development and delivery time by reducing unnecessary activities
    • Scalability: On demand and auto-scaling AI models
    • Quality: Boosting cleaning datasets and eventually promotes consistent learning that further enhances AI
    • Data monitoring: Decision making and computing helps handle huge amount of data with precise data monitoring

    Benefits of Integrating AI in DevOps

    There are endless benefits to integrating AI in DevOps.

    Analysis

    Data analysis is the key to business success, especially in times when there’s a huge list of competitors rushing to gain consumer trust. Since DevOps produces an enormous amount of data, it isn’t practical for humans to analyze the data without technological intervention.

    Artificial intelligence’s smart analytics eases the process by identifying and solving problems in a
    more systematic way, resulting in efficiency and increased consumer satisfaction.

    Data Correlation

    In the wider technology environment, development teams have their own set of issues and errors, which arrive while monitoring the processes. Since the communication scope is minimal and there’s a lack of mutual learning across teams, artificial intelligence can help to accelerate the learning cycle.

    Artificial intelligence helps to improve data insights from multiple platforms, which, in turn promotes better communication and establishes better data correlation.

    Failure Handling

    Machine learning is paving the way to better error resolution based on data, and eventually artificial intelligence will be able to predict signs of failure by examining patterns. Since humans cannot match the observation capabilities of AI, certain indicators of failure can only be analyzed through AI. This further enhances the overall development processes, as quick identification helps identify issues before they can impact the software development life cycle.

    Breaks Down Silos

    DevOps with AI has the ability to streamline business processes and establish proper communication among diverse systems, removing barriers that slow down the development and deployment processes. Furthermore, the ability to automate, continuously integrate and enhance communication helps business leaders to focus more on other aspects that can further accelerate business growth.

    Economic Growth

    Since the basic function of an AI-based model is automation, it can help businesses save money and enhance human resources. For any business, eliminating repetitive human work is a tough nut to crack. but a necessity when businesses are demanding continuous innovations. Artificial intelligence could be the best way for enterprises to cut costs and eventually helps the organization to use human resources more creatively and productively.

    Makes Software Intuitive

    Besides endless business benefits, AI-based software is more intuitive and user-friendly, since it prioritizes the reduction of human error. While DevOps is a well-known, reliable, business-driven approach for delivering software, intermingling artificial intelligence could enhance the user experience by integrating technology more deeply into the system.

    The perfect harmony of simplified interactions between humans and AI helps businesses achieve their desired goals of speed, efficiency, scalability and security.

    AI-driven systems are providing promising and scalable solutions for enterprises that are on a hunt
    for innovative and rapid ways to scale business growth. AI in DevOps is undoubtedly the best solution for accelerating growth through precise monitoring, automation and process improvement. This is the right time for businesses to ensure they operationalize artificial intelligence as a core business objective to stay ahead of their competitors.

  • Chicken Soup for the SLO

    Chicken Soup for the SLO

    Since time immemorial, humans have struggled to communicate. From myth to the modern era, our most memorable stories often involve individuals or groups seeking to be understood in order to avoid conflict. Be it the biblical allegory of Babel to the more recent Star Trek: The Next Generation episode of “Darmok,” a deep fascination with how people communicate seems to have collectively gripped our imaginations.

    It should come as no surprise, then, that communication between disparate teams and roles in the development of distributed software systems is a fascinating topic. There’s an almost primal struggle in the workplace—a dichotomy between “features” and “stability”—that teams have sought to overcome for decades. Indeed, much of the discipline of software engineering has implicitly evolved as a response to the needs of engineers to communicate with other parts of the business.

    How, then, do we improve this communication and build empathy toward our fellow developers, our coworkers, our PMs, our managers? We need a way to communicate with them, to express “how things are going,” how reliable our service or system is. Let’s step back, though, because this is only a small window we’re looking through—we need to communicate these desires and goals to a greater audience; Our bosses, their bosses, our customers, the entire world. Organizations rise and fall on their ability to communicate effectively.

    In the natural sciences, we observe that the tendency of a system is towards entropy; Energy tends to dissipate in the absence of a constraint. So, too, do human systems lose productivity as their scale and complexity increases. The rise in popularity of Agile methodologies and DevOps thinking tracks with this. They are, ultimately, designed to help us communicate better about needs and priorities. Site reliability engineering (SRE) is the latest in this line of disciplinary developments, providing rigor to the question of, “How do I operate very large scale systems in dynamic environments?”

    One of the more popularized elements of the SRE playbook is the concept of the service level objective, or SLO. To excerpt the excellent Implementing Service Level Objectives by Alex Hidalgo, a SLO is “a proper level of reliability targeted by a service,” a calculation of the amount of ‘bad’ events that can occur as part of the normal operation of a service. As Alex notes, the idea of SLOs and SRE have become almost inseparable in our collective consciousness—organizationally, it’s seen as strange to have one without the other.

    Let’s dive a bit deeper into what an SLO actually is. Again, I will excerpt and paraphrase from Alex’s book (it’s very good; you should read it if you’re interested in this topic). A SLO is simply a target, a set of defined criteria that represent some objective that you’re trying to reach. In a very general sense, the SLO expresses the threshold of ‘good’ to ‘bad’ events that you’re willing to tolerate over a time period. This simple ratio, however, unlocks a great deal of interesting and important ways of thinking about performance and reliability. It gives you, and your team, the ability to reason and communicate about reliability in a very quantitative and qualitative way.

    Now, you may be asking yourself what the qualitative component of a SLO is—after all, aren’t these measurements quantitative by definition? It’s in this dichotomy that I believe the true power and utility of SLOs lie; they’re not just a measurement of what you’re doing, they’re a communication vehicle for how you’re doing. Error budgets come out of this line of thinking—they represent the space between the current state of your SLO and its boundary.

    In plainer terms, it’s a measurement of how much you can miss your target before it becomes a problem. If my SLO targets 99% reliability, I have about three and a half days of unreliability a year to play with—or, about 14 and a half minutes a day. This way of measurement is certainly helpful in driving and determining engineering decisions, as it allows us to make snap judgements about how to prioritize the seemingly opposing buckets of “feature work” and “reliability work.” If we’re getting close to burning up our error budget for the month, do more reliability work. If we’ve got slack, do more feature work. Easy, right?

    How to Make Friends and Influence Budgets

    Reliability, SLOs, error budgets—these are all helpful ways to quantify performance and availability in software. There’s another way to consider them, though, and it’s through the lens of risk. If you’ve earned an MBA, you’re probably familiar with a ‘risk heat map.’
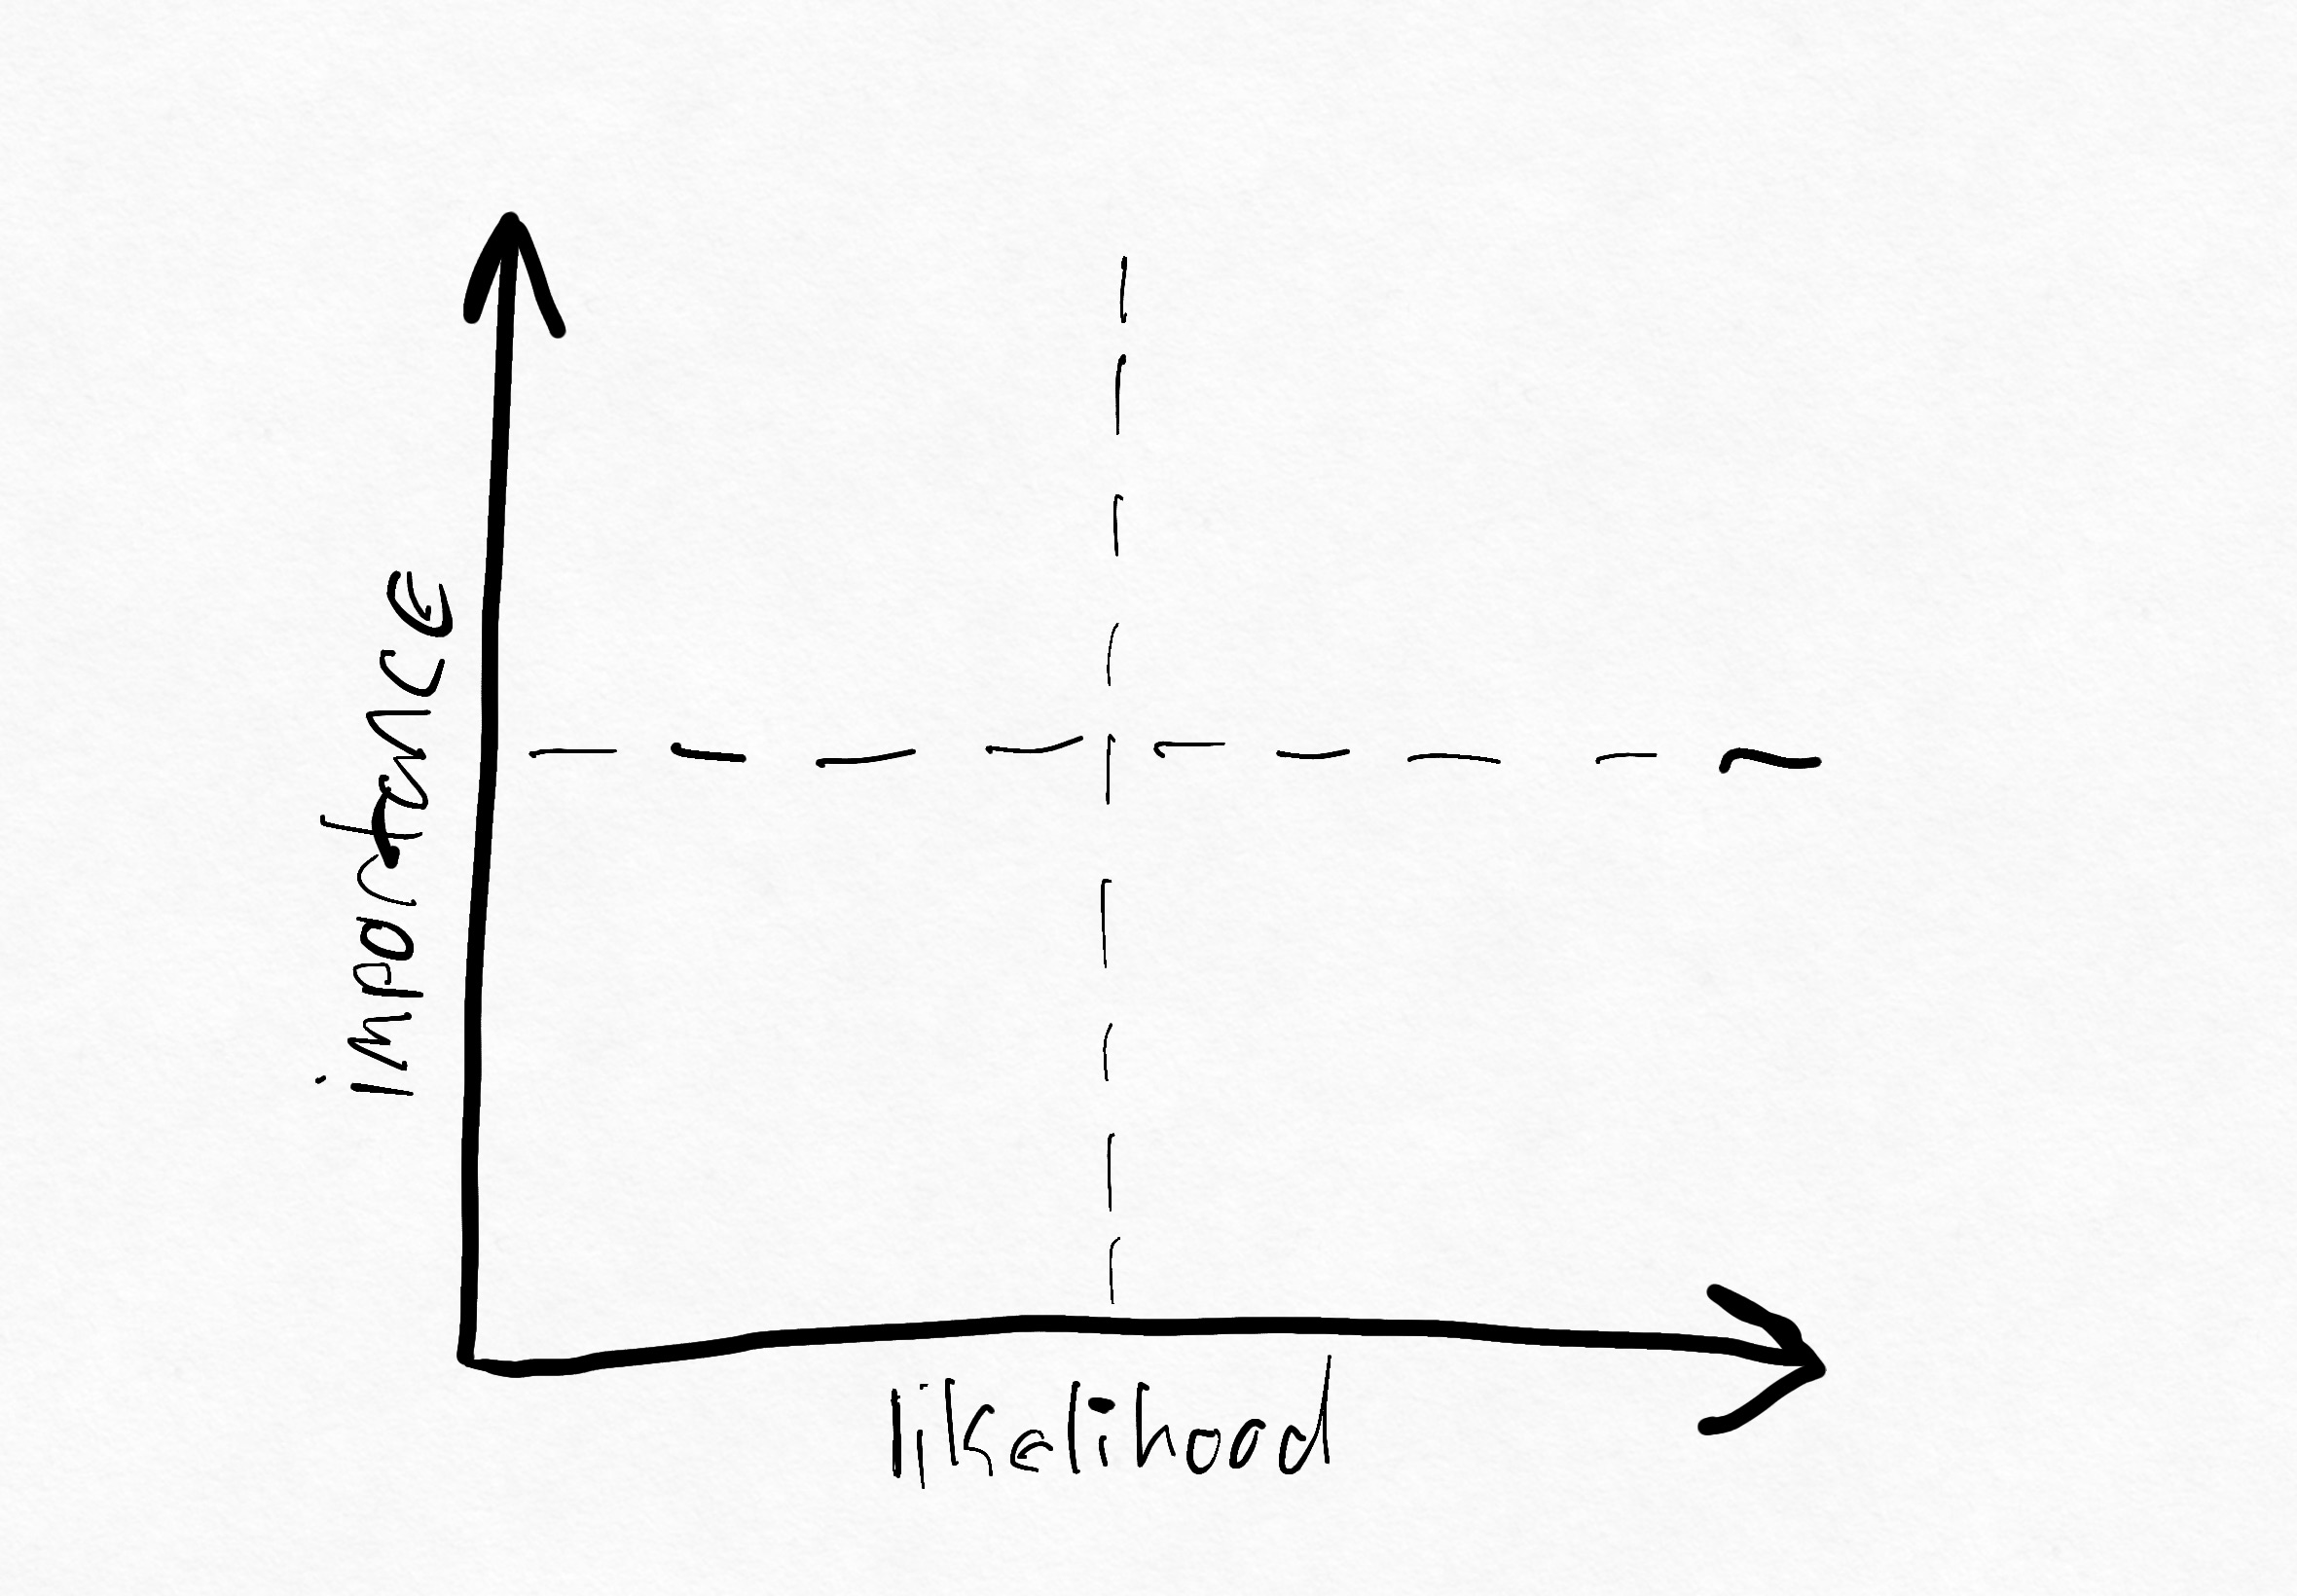
    SLO heatmap

    The x-axis on this quadrant represents the likelihood of a problem occurring; the y-axis represents the importance of that element. This is generally extensible to any element of a business—everything from your sales force to your customer success team to the availability of your data center or cloud resources.

    In many ways, this simple quadrant is responsible for many of the decisions that influence your work. While a business does many things, the business of operating a business can be thought of as an ongoing and unceasing process of risk management and abatement.

    The stuffy, MBA-fueled world of Six Sigma and process management doesn’t play terribly well in the more creative arenas of software development and maintenance, I’ve found. Much of this has to do with—you guessed it—risk. In manufacturing, the costs of failure or defects can be extremely high. Component defects can sideline million or billion dollar supply chains; projection and planning failures can disrupt just-in-time inventory and a single stuck ship or sudden winter storm can cause months or years of disruption to national or global economies. We should count ourselves fortunate that the actual costs of failure in a software system are so light; while us-east-1 going down for an hour would be bad, it probably wouldn’t wreck the global GDP for six months.

    The translation of ‘lower-level’ concerns, such as software system reliability or employee turnover, into ‘higher-level’ risk concerns acts as a curtain between the operational and the managerial aspects of a company. It is this curtain that we must consider when thinking about the true advantages, and the revolutionary potential, of SLOs. Remember, a SLO represents a ratio between ‘good’ and ‘bad’ and gives us a threshold value. These SLOs can be overlaid onto our risk maps extremely easily; SLOs for more critical services and processes rise to the top, newer services move to the right.

    In essence, we can give our SLOs a qualitative score with regard to overall business risk, and use this to shape the overall business direction. This is crucial, as in the absence of better qualitative measurements, businesses will often grasp at quantitative reliability measurements—“pages fired or tickets opened,” to quote Hidalgo. He continued, “[T]hese are prone to be inaccurate due to false positives or the whims of the people opening the tickets.” The types of measurements that we often rely on, such as categorization by severity or ‘mean time to x’ fail to accurately classify reliability or how it impacts the user experience.

    Let’s illustrate by example—a huge part of conversations about SLOs is talking about how they should be framed in terms of users; happier end users, happier engineers, happier managers and so forth. SLOs that correspond to user journeys—for instance, “Adding an item to the cart succeeds 99% of the time.”—are straightforward to understand from the perspective of an end user. We can discuss this in terms of risk by applying an importance and likelihood score to the SLO itself. If our site is an e-commerce platform, then the importance of the cart is very high. Since our threshold is very small (1%), then the likelihood of this risk is also very high—we don’t have a lot of wiggle room!

    A SLO for a targeted ad service might read, “A contextually appropriate display ad is served within 30ms 90% of the time.” In this case, our ad business might not be of high importance in terms of our business risk, so we should reduce the importance of the SLO. In addition, our threshold is very large, so we should reduce the likelihood of violation (since we have a lot more wiggle room). Over time, these positions and scores can (and should) change—perhaps the advertising segment of our business becomes more valuable, so we re-prioritize it on our risk maps.

    By speaking this language and quantifying our data in different ways, we can pull back the curtain between operational and managerial sectors and use it to influence things outside our immediate sphere.

    “Mommy, why is there a SLO in the house?”

    There’s an aphorism about war and fighting that goes, “Generals are always prepared to fight the last war.” I’ve seen this myself at every company I’ve worked for over the years—we tend to be reactive, rather than proactive, in planning and preparing for strategic business challenges. Some of this is due to the fact that none of us are oracles capable of divining the future, but much of it simply has to do with the aforementioned cycle of risk management that drives business planning and decision making. When introducing SLOs to a wider audience, you need to be able to plan for the pushback that executives and managers will almost certainly have to this new way of thinking.

    When you think about it, though, there’s not a lot of difference between what an SLO is trying to represent, and what an OKR or KPI or any other goal-oriented system is trying to represent. In each case, we’re creating some heuristic to sort events into ‘good’ and ‘bad’ cases, then creating a threshold of ‘Now there is a problem’ based on the ratio between them. In essence, this is, really, how you measure anything as a percentage.

    You could translate goals for your sales, marketing, customer success or people ops teams into SLOs. For example, “30% of POCs should convert into closed-won opportunities” is, basically, an SLO already, and is perhaps an existing goal for your salesforce. There are two big advantages to thinking about these as SLOs: consistent reporting and error budgets.

    Consistently reporting on SLOs means that you can express team and company goals in the same format and language across the entire organization. This brings teams together in a shared purpose, and allows for a shared language about how reliability benefits everyone. Being able to roll up reporting about how things are going not only encourages more shared ownership of goals, it helps you build connections and linkage between how different types of work align with each other towards a shared prosperity. More importantly, SLO reporting gives extremely clear signals about how teams—regardless of their function—should be addressing failure.

    If a consistent language around reliability is what builds empathy, error budgets are what unlocks creativity and problem solving for addressing issues in the business. In too many cases, organizations are loathe to give individual contributors, or even teams, the flexibility to experiment and measure the results of those experiments due to inertia, top-down command-and-control style processes or just the fear of screwing up.

    Let me give you an example—suppose your marketing team has a demo that generates a certain percentage of leads every month. Without a defined SLO for this demo’s performance, it becomes extremely difficult to change anything about how this demo works. Why? Because there’s a tendency for things to settle at their current state—we’re all so consumed with moment-to-moment crises or new work that evaluating the performance of existing things can be challenging.

    The work required to justify a change eventually outweighs the actual work being done to make the change, and so change withers on the vine and processes stagnate. Now, imagine that this demo flow had an SLO associated with it, something like “10% of clicks to our demo should result in a valid email capture.” Suddenly, we can report on this in a consistent fashion and, more importantly, we have a massive amount of headroom for experimentation. We can justify work being done to improve this flow in the context of not only its current status (are we running better or worse than our target?) but also in the context of our other goals (are we producing enough MQLs, in general, to support the sales funnel?) and prioritize appropriately.

    Ultimately, we can’t change the fact that there’s a bias towards dealing with the last thing that happened, but that’s not really the point. What we can change is how we think about expressing what’s happening now, and building a consistent language and verbiage around addressing these problems. SLOs are designed, broadly, as a way to communicate the reliability goals of complex distributed software systems. What is a business of people other than a complex distributed human system?

    As thinking, tooling, and processes around SLOs continue to mature (such as the recently announced OpenSLO specification), I’m excited to see what the future has in store for us. At the end of the day, we should be striving to reduce hierarchy, increase autonimity, and build collective ownership in the socio-technical systems that we rely on as human beings; SLOs are just another piece of this ever-evolving puzzle.
  • GitLab Acquires UnReview to Further AI Ambitions

    GitLab Acquires UnReview to Further AI Ambitions

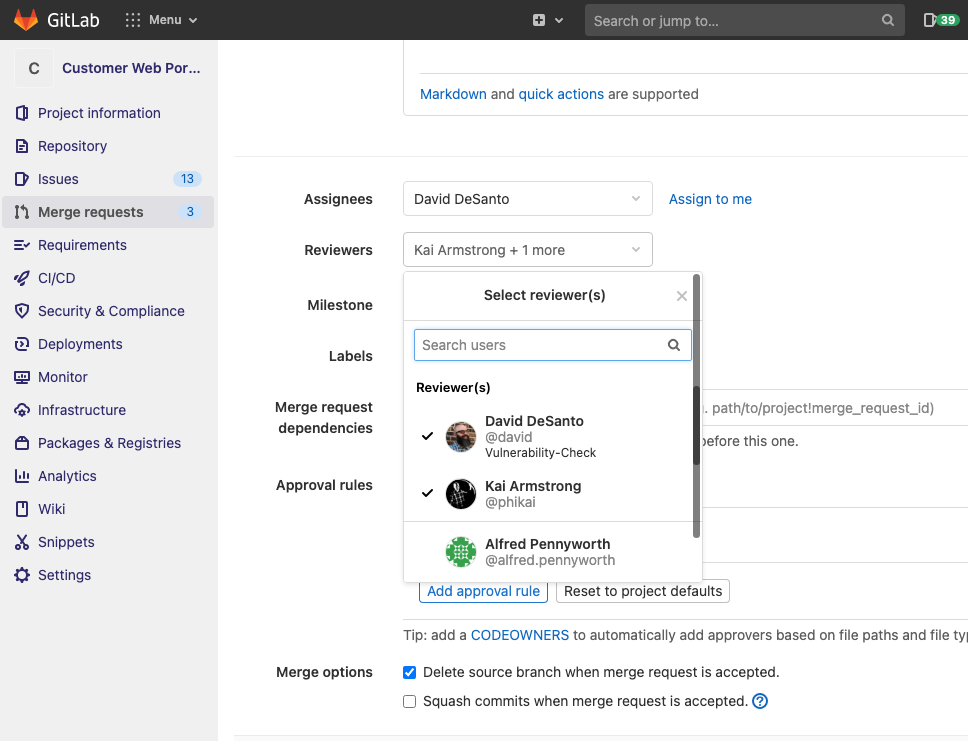
    GitLab announced this week it has acquired UnReview, a provider of a tool that employs machine learning algorithms to identify which expert code reviewers to assign to a project based on both the quality of their previous efforts and current workloads.

    David DeSanto, senior director for product management at GitLab, said the acquisition of UnReview is the latest step in an AI strategy that, in addition to optimizing DevOps processes, will eventually unify machine learning operations (MLOps) and DevOps workflows.

    Accessed via the Dev section of the GitLab platform, UnReview will also be employed to manage the overall code review process.

    GitLab

    DeSanto said GitLab is committed to employing AI technologies to automate workflows and compressing cycle times across all stages of the DevSecOps life cycle. The goal is to not eliminate the need for DevOps teams, but rather eliminate low-level tasks that conspire to hamper productivity while at the same time improving application security, noted DeSanto.

    Providers of DevOps platforms are now locked into an AI arms race on two separate fronts. Each of them clearly sees the opportunity to leverage machine learning algorithms and other forms of AI to automate a wide range of processes. At the same time, it’s apparent providers of MLOps platforms are borrowing heavily from DevOps best practices to manage the development of AI models. However, from the perspective of a DevOps team, an AI model is just another type of software artifact. Rather than deploying two distinct platforms, the goal should be to bring the data scientists that build AI models into the larger DevOps community, said DeSanto.

    The current challenge, of course, is the pace at which DevOps and data science teams work. It may take six months or more for a data science team to construct and validate an AI model that needs to be embedded within an application. Aligning the timetable for an AI model with the application development life cycle is difficult to accomplish if neither team has any meaningful visibility into each other’s workflows. As the rate at which AI models can be developed steadily improves, that alignment issue will only become all the more pressing.

    Going forward, it’s hard to envision any application that won’t have some sort of AI model embedded within it. The issue is that, just like any other software artifact, an AI model needs to be updated. As new data sources become available, an AI model is likely to drift beyond the parameters intended. A rapid change in business conditions may also require the replacement of an entire AI model. The same processes that DevOps teams apply to update any software artifact can also be applied to an AI model.

    It’s unclear how long it will take before some type of convergence of DevOps and MLOps inevitably occurs, as organizations look for more efficient ways to manage what will become thousands of AI models. The one certain thing is the longer it takes to make the effort, the more difficult it will become to overcome the organizational inertia that has been allowed to set in.

  • How Low-Code/No-Code Can Transform Your Organization

    How Low-Code/No-Code Can Transform Your Organization

    For many companies, IT transformation is no small feat. Between the technology, process and organizational changes needed, it can take time to see a return on your IT transformation efforts and investments. So it’s no surprise that low-code/no-code is starting to be seen as a compelling solution for some.

    With low-code/no-code, you can empower teams of ‘citizen developers’ and enable experienced developers to accelerate deployment and reduce IT backlogs. To gain insights on the ways that low-code/no-code can transform your organization, I asked several DevOps Institute Ambassadors for their thoughts. Here’s what they said:

    Brendan O’Reilly, DevOps Specialist, Daysha DevOps

    Low-code/no-code introduces urgency into an organization. By removing the bottleneck that is scarce development resources, you can reduce the lead time to value.

    Mark Peters, Technical Lead, Novetta

    Low-code situations are likely best for highly tailored situations, with clearly defined purposes and minimal changes. Low-code can work when your business depends on scaling rather than creating new code. If the business is good enough, and one is adding microservices or more instances of the same expanded for a larger market, low-code can be perfect. Implementing low-code then allows the next opportunity to move from some code to no-code, providing a graphical interface to change architecture, implement policy or change recurring controls through mouse clicks rather than code. This also provides an excellent chance for improved ops control; if one is scaling the number of users, controls can be implemented to ensure the graphical delivery does not hard-code a password into the system, instead of relying on approval checks within an alternative interface.

    Vishnu Vasudevan, Head of Product Engineering and Development, Opsera

    When an organization practices DevOps, they continuously expand by team, product, platform and application because of different solutions coming into the market. Incorporating a low-code/no-code approach gives enterprises the ability to speed time-to-market and expand engineering capabilities beyond IT.

    If you have a low-code platform that can help manage and provide visibility into technology and security compliance, that’s a gold mine for any developers or any organization. For example, anytime a new application comes in, teams can use a template from the previous application and put it over the new application. The same security quality of the audit governance is quickly established as a baseline, and all the developers have to do is focus on coding.

    Shriniwas Sathe, DevOps Chief Architect and CoE Leader at Capgemini

    Low-code/no-code tools can help change the way that regular employees interact with technology. With no-code tools, every employee, regardless of their background, can create custom applications, websites, forms, etc. With low-code tools, this can be taken a step further by building upon the offerings of a no-code tool by coding in the unique features needed by the organization. This is much less time-consuming compared to traditional development processes, even though it requires a general know-how of coding.

    With every employee able to contribute to new applications and tools, there’s a better chance of obtaining unique insights and unforeseen capabilities. You can also simplify processes to an extent where regular employees can benefit from the freedom from tedious and repetitive tasks. There are low-code/no-code tools for most industries, which gives you a choice of either a ready-made solution or one that can be customized to your particular requirements.

    Peter Maddison, Founder, Xodiac, Inc.

    Low-code development platforms are great at automating important procedures using drag-and-drop editors that allow citizen developers to create virtual models of an app’s business logic and user interface.

    A major advantage of having an enterprise no-code platform is the presence of built-in governance capabilities. No matter what an IT team’s size, a central console offers visibility for all applications and environments so that they can keep track of any issues or vulnerabilities.

    Business developers can use the solution to create applications that fit their unique business needs. And more than one developer, or a team of developers, can work on the same module at the same time.

    Of course, we need to ensure we are providing appropriate guard rails so our citizen developers are not able to accidentally expose data or create additional risks through the solutions they create.

    If you’d like to learn more about the latest in low-code/no-code and similar topics, check out the upcoming SKILup Day schedule. Or, learn more about the benefits of becoming a DevOps Institute Member.

  • Then and Now: The Evolution of DevOps Culture

    Then and Now: The Evolution of DevOps Culture

    There are many available resources dedicated to delivering better business value faster. Based on this advice, many organizations and teams are adopting common software delivery practices — even outside the usual use case of providing software (take, for example, SpaceX teams using agile, or leadership teams that use scrum practices and have daily stand-up calls). This progression into faster, better, cheaper and easier – no matter what you’re delivering – is what makes incorporating DevOps into business practices critical to delivering unmatched value for end users.

    Then and Now

    A great perspective to consider when approaching the subject of DevOps is how technology has changed just about everything – how we build, connect, share and educate. Up until the 2000s, for example, the standard turnaround time for taking and sharing pictures was one to three weeks, if not longer. This process used to involve film cameras, darkrooms to process the photographs, photo finishing labs and hard copy, physical prints. Today, our mobile devices allow us to snap hundreds of professional-quality images and share them immediately online.

    culture evolution

    These earth-shattering changes don’t apply to photography alone, but to many other industries including financial services, banking and IT. Consistently, technology is finding new ways to disrupt industries, priming them to be more efficient to fit into our fast-moving lifestyles.

    The DevOps Life Cycle

    Now, let’s look at software delivery. In the past, the process of traditional software delivery was linear and sequential; waterfall methodologies offered little flexibility and did not succumb to the nature of change and demand for technology services we see today. What we’ve experienced with software delivery now uses DevOps to leverage new insights through people, processes and technology, giving organizations the ability to deliver continuous business value. Yes, that means businesses are adding value to our lives all the time, whether you see it or not. For technology organizations, this process for delivering business value is modeled through what we call the DevOps life cycle — understood through the graphic below.

    DevOps culture evolution

    Getting to a DevOps Culture

    Often, an organization’s challenges with DevOps do not lie in the technology or processes themselves, but in the people part of the equation – how we work together to deliver value via cross-functional teams. To understand what building a DevOps culture means, we need to look at what culture encompasses and how our people, process and technology work together to enable a successful DevOps life cycle.

    culture evolution layers

    This layered graphic features all the various components related to culture. Each layer encompasses the next.

    ·      Mindset

    ·      Values

    ·      Principles

    ·      Practices

    ·      Tooling

    Getting to a DevOps culture involves articulating change both from the bottom up and top down in our organizations and is, therefore, no easy feat. Before we can introduce or discuss tooling, we need to understand how our practices and principles help us achieve our outcomes. Each inner layer requires the outer layer to be successful before we can truly get to defining and strengthening a DevOps culture.

    Here are my tips for getting to a DevOps culture:

    ·      Learn from and develop skills from mistakes

    ·      Focus on the important priorities

    ·      Capture collaboration

    ·      Perfect your tooling

    The DevOps Principles

    DevOps is the collection and collaboration of people, processes and technology to deliver software value continuously. Here are some core DevOps principles you can use to guide you on your DevOps journey.

    Create With the End in Mind

    High-performing teams work best when leaders and individuals understand their role in the team. Therefore, creating with the end in mind involves reassessing and often asking big picture questions, like “Who is this delivery for?” and “Why are we doing it this way?” Keep the vision in mind and make adjustments along the way.

    Even the most famous photographs in history involved many adjustments and numerous attempts to get it right. Creating with the end in mind means knowing we may not have everything right the first time around. That’s okay! Similarly, life isn’t without its own distractions, conflicts and changes. Keeping the target outcomes in mind helps us align to initiatives and actions, and to question when they don’t align.

    Cross-Functional Teams

    Many products and deliveries involve multiple people. For example, some of the best Marvel cinematic universe (MCU) movies were made thanks to the help of multiple production teams and partner companies coming together to build the powerhouse we know today. Not to mention, in my opinion, some of the best superhero movies of our time. We succeed with software delivery in the same way: by having fully responsible cross-functional delivery teams.

    The best engineering teams I’ve been on are made up of independent and autonomous individuals who know how they can contribute to the work in progress. They’re also willing and unafraid to collaborate with others to get this work done.

    Commitment to the Journey

    “I am not here to be right. I am here to get it right.” – Brené Brown, from the book Dare to Lead.

    Even with cross-functional delivery teams and creating with the end in mind, our teams still may not get everything right the first time around. Committing to DevOps is about accepting any failures that come during the journey. Committing to the journey doesn’t mean you can’t define what it involves, even if it’s out of the ordinary. Experimentation is also a part of how we, as developers, adapt to change and adopt novel approaches to delivering faster, cheaper and better software.

    The DevOps Principles as Guides

    Use these principles as the foundation for how to work together, but also use the right tools, and define and improve processes along the way. In photography, there are three components that serve as building blocks to the final images we capture: aperture, shutter speed and ISO. In DevOps, it’s our people, processes and technologies. Achieving high performance with DevOps involves all of these components working together and adjusting to our environment, situation or team.

    The key to getting to the results you desire? Not getting blindsided by any single component of getting to that result.

    The DevOps Practices and Tools

    I like to consider this section the call to action; the one says to our teams and individuals, “Gear up!” No reasonable photographer would leave for a photoshoot without their camera and camera gear, right? Similarly, DevOps practitioners and teams need the right tools to get the desired results.

    Source Code Management

    Source code management is about allowing teams to collaborate, have version control, correct and revert software code. This is fundamental for many teams to increase not only visibility and collaboration, but also start automation workflows.

    If you are an individual just starting out with writing code, I recommend learning the basics of Git, such as how to add, commit, push, merge, branch and clone code. If you’re a team, I recommend discussing the practices and standards you want to use for collaborating. Always fit your Git structure and workflow to your codebase and team dynamics.

    Continuous Integration

    What continuous integration (CI) does is take code away from local machines to package it into a deployable artifact in a CI server. What this is designed to do is automate the integration of newly committed code changes. This process is often triggered by code changes pushed into your Git repository. Using checks and other tools, teams can version and release artifacts that have already been vetted for quality and security.

    Continuous Delivery

    Continuous delivery, on the other hand, takes artifact code to production environments. CD aims to deliver code changes of all kinds to users in a fast, repeatable and safe manner. CI/CD consists of both CI and CD pipelines working together to deliver code to users.

    Infrastructure-as-Code (IaC)

    Infrastructure-as-code allows users to define hardware through code. We can improve how we provision, configure and maintain hardware systems. Infrastructure provisioning tools like HashiCorp’s Terraform and AWS Cloud Formation, configuration automation tools like Ansible, Puppet and Chef and package managers like Helm allow teams to accomplish much more when software scales and demand increases.

    Secrets and Identity Management

    Security is everyone’s responsibility. Secrets management and identity management tools make accomplishing DevSecOps easier by securing and managing sensitive information. Teams should consider how they are handling secrets and users within their architecture. HashiCorp Vault, KeyCloak, KMS and other similar tools can help you achieve your goals around security.

    There are many other practices and tools DevOps teams and organizations can use to achieve their desired outcomes. What works for one team may not work for another — hence the need to innovate and experiment in a controlled and well-led manner. Other practices that can increase your team’s ability to deliver value include value stream mapping, progressive delivery, GitOps and chaos engineering.

    People, processes, and technology belong together in a DevOps culture. While practice makes perfect, what’s more important than perfection is gathering the right answers along the way. Everything doesn’t need to be right the first time around. Just remember that no leader, individual or team in DevOps is alone. We started by defining what it means to build a DevOps culture, change mindsets and set principles and practices, so now I ask you: What does DevOps mean to you?

  • Atlassian Delivers on Forge App Dev Platform Promise

    Atlassian Delivers on Forge App Dev Platform Promise

    Atlassian this week made available a Forge platform for building applications that complements its existing portfolio.

    Mike Tria, head of platform engineering for Atlassian, said Forge is intended to provide an application development environment to both IT organizations and third-party partners. It provides developers with access to an integrated Atlassian DevOps toolchain to accelerate testing, deployment, debugging and to capture log data, added Tria. Forge also presents developers with a command line interface through which they can be onboarded to the Atlassian cloud where Forge runs to access documentation and application samples. It uses OAuth 2.0 to ensure applications deployed on the Atlassian cloud only access data they have permission to access.

    The overall goal is to provide developers with a more modern application development environment as an alternative to the application development platform the company previously made available.

    Once an application is built, developers can then publish their applications on the Atlassian Marketplace as free or commercial offerings. There are already more than 3,500 Forge apps that were created during a beta process that began late last year. Forge will soon be extended to the rest of the Atlassian portfolio, noted Tria.

    Forge is intended to complement an Open DevOps initiative launched earlier this month that tightens integration between the Jira project tracking and management tools provided by Atlassian and a wide range of other tools commonly employed by DevOps teams. The goal is to not only make it easier to correlate issues that are listed in Jira with artifacts found in various software platforms, but also to collect data from DevOps tools to automatically update Jira.

    That data will then be employed to inform key performance indicators (KPIs), based on graphs that Atlassian provides within Jira, to keep track of value streams. Rather than having to acquire a separate value stream management (VSM) platform to track software development progress, the insights needed to understand the impact of, for example, a delay to one project becomes a dividend of using Jira.

    Like most providers of software-as-a-service (SaaS) applications, Atlassian has been making available a platform for building applications on top of the same platform it employs to build its own applications. Atlassian claims there are more than 1,200 partners building applications in addition to internal IT that teams that have built custom extensions to its applications. Atlassian has already shown a proclivity for acquiring independent software vendors (ISVs) that build applications on its platform. As part of the overall Forge initiative, Tria said Atlassian will be working more closely to identify the white space that won’t be addressed by the Atlassian product roadmap at some future date.

    In the meantime, independent software vendors and internal IT teams will need to determine to what degree they will prefer to stand up their own application development environment versus opting to be dependent on Atlassian. In theory at least, applications built on Forge should be more tightly integrated with the rest of the Atlassian portfolio. The only potential downside is, of course, any potential conflict that might emerge with a provider of an application development platform that also happens to sell application software.

  • Serverless Computing Brings New Security Risks

    Serverless Computing Brings New Security Risks

    Attracted by lower costs and less operational overhead, serverless computing is an unmistakable undercurrent in the world of DevOps. Developers are drawn to the innovation because it requires no architecture to manage while offering continuous scaling for anything from a few requests per day to hundreds of thousands of requests per second.

    More than 50% of the developers using serverless functions today started using the computing model in the last three years. By some estimates, serverless computing is the fastest-growing segment in the cloud services market.

    While businesses are drawn by the opportunity to extend and integrate cloud applications at greater scale, there’s a dark underbelly to this DevOps phenomenon: security. In fact, organizations cite security concerns as the leading reason why they haven’t yet adopted serverless computing. For good reason!

    Serverless functions are introducing a new breed of threats – misconfigurations, code-level risks, injections and weaknesses – many of which are the underlying risk factors for a software supply chain attack. With adoption of this technology accelerating, organizations need security that delivers more than just visibility into these dynamic environments. They also need the ability to detect and block code-level vulnerabilities and misconfigurations that occur during development and through to production. Most importantly, this needs to happen seamlessly and with little to no impact on DevOps.

    Dynamic Environments Create Complex Security Risks

    The nature of applications has evolved, creating a new paradigm of security risk. In serverless environments, code sprawl makes it harder to identify vulnerabilities and patch them before they become business-level risks.

    In a monolithic application environment, an identified vulnerability could be efficiently patched by the developer through upgrading a single package, pushing a deployment and then testing and deploying the app.

    In a serverless computing model, patching and resolving vulnerabilities becomes a lot more complicated, given that there may be several hundred (or more) environments across different providers and regions. So, instead of having to patch a single application, developers will need to patch, deploy and test hundreds of individual functions that rely on that library.

    With 39% of developers saying they’re now fully responsible for security, it means they’ll carry the burden of having to patch an identified vulnerability – often taking them away from development work.

    With Serverless, You Need to Rethink Your Approach to Security

    Given the distributed nature of serverless functions – essentially, the reason for its flexibility and scalability – many existing security tools will provide little to no visibility, nor the control capabilities, for these computing environments. Many of the security attacks that will occur in serverless functions will be a result of misconfigurations and mistakes that happen outside the purview of the security team and due to legacy solutions which don’t translate to serverless architectures. Further, because abstracted workloads create blind spots, attackers will have more room to maneuver undetected.

    Serverless functions will even render some traditional DevSecOps tools less useful. Scanning tools must monitor hundreds of individual repositories instead of a single monolithic repository, while application performance monitoring (APM) tools lack security proficiency and cannot protect from the OWASP Serverless Top 10 risks.

    The challenge for security teams will be implementing solutions in a way that does not modify workloads or require changing business logic — both of which slow development. When applying security to serverless functions, it’ll be critical that the solution can do the following:

    • Go beyond monitoring and actually detect and block vulnerabilities without elaborate or manual steps involved. The scale of serverless functions will make it nearly impossible for security analysts to manage and keep up with every alert they receive. Instead, they need a tool that delivers actual security and can help them block malicious activity without stopping development altogether.
    • Enable a positive security model that provides protection against malicious changes, like zero-day exploits, within the function. This approach gives security teams more control by automatically detecting and blocking anything that isn’t explicitly allowed in a given function.
    • Provide forensic detail from log-level information so security analysts can fully understand the context of every attack with virtually no impact on latency. Further, with the risk of supply chain attacks soaring, security teams need the ability to identify and map third-party dependencies used during runtime.

    For many organizations, serverless architecture is a very different and unique computing environment – unlike anything they’ve experienced or had to protect before now. That reality means that organizations need a fresh approach to securing these environments and will need to look beyond the traditional tools they have in their tech stack today.

    Above all, developers and security teams will need to work together to ensure security is built-in from the start. Otherwise, serverless functions will quickly become a playground for cybercriminals.

  • Digital.ai Deepens Value Stream Management Integration

    Digital.ai Deepens Value Stream Management Integration

    Digital.ai announced today it has expanded usage of machine learning algorithms within its namesake value stream management (VSM) platform to include modules to optimize flow and improve application quality in addition to enhancing its risk prediction and process optimization modules.

    In addition, Digital.ai has expanded the number of pre-built integrations it now provides for hundreds of DevOps tools and platforms.

    Derek Holt, general manager of agile and DevOps for Digital.ai, said the goal is to expand the bi-directional flow of data between the core Digital.ai platform and modules and tools provided by the company and its third-party DevOps partners.

    Digital.ai was formed from the merger of XebiaLabs and CollabNet VersionOne. The combined company has rolled up Numerify, a provider of analytics tools infused with artificial intelligence (AI), Experitest, a set of testing tools and Arxan, a provider of an application security platform. With the latest release, these capabilities have been integrated into the core Digital.ai platform in a way that goes well beyond merely providing access via a common user interface, said Holt.

    The goal is to provide organizations with a VSM platform through which better decisions can be made to optimize software development and delivery by first collecting data from all the DevOps tools employed and then using machine learning algorithms to surface optimization recommendations, noted Holt. As application development environments become more complex to manage, it’s already apparent that most IT teams will require AI capabilities embedded in a VSM platform to manage interdependent projects, noted Holt.

    Armed with those recommendations, it becomes simpler to reallocate resources in the event a critical project is going to be completed later than planned or shift resources to make sure that project is completed on time. A VSM platform also enables IT organizations to assess the impact those decisions will have on the rest of the business at a time when organizations have never been more financially dependent on the timely delivery of software. The late delivery of a single application module can wind up having a profound impact on revenue projections for organizations that increasingly rely on digital processes to engage customers.

    A recent survey conducted by Digital.ai found that many digital transformation initiatives are struggling, to some degree. Nearly half of respondents (49%) said they are not seeing the results they expected from their digital transformation efforts, and 54% admitted they were worried about their ability to compete. Over 90% need to see a better return on their digital transformation investments.

    Digital.ai claims it currently has more than 1,200 customers, including Allianz, Commerzbank, eBay, Janus Henderson and Levi’s that are using elements of the Digital.ai platform to better manage software development projects. Many of the users of those tools now include business executives and other application stakeholders that are employing a VSM platform to track the progress of application development projects. Digital.ai Analytics Lenses that are domain-specific make it simpler for different classes of end users to access pre-built dashboards and metrics, noted Holt.

    The market research firm Gartner has predicted that 70% of organizations will employ a value stream management platform by 2023 to improve flows across their DevOps pipelines. However, as DevOps platforms and project management applications continue to evolve, many are also adding many of the analytics capabilities found in a VSM platform. Each IT organization will need to decide which approach makes the most sense for them, but Digital.ai is clearly betting that as application development becomes more challenging, the need for an integrated VSM platform will become much more apparent.

  • JFrog Adds Private Distribution Network for App Binaries

    JFrog Adds Private Distribution Network for App Binaries

    At its online swampUP conference today, JFrog launched a Private Distribution Network (PDN) that makes it simpler and faster to distribute application binaries across an extended enterprise.

    Yoav Landman, JFrog CTO, said the PDN provides the equivalent of a content delivery network (CDN) designed specifically for distributing application binaries using a peer-to-peer network managed by JFrog. Each binary distributed is an immutable signed release that provides visibility and traceability to validate the source destination as well as the integrity of the binary, added Landman. That approach essentially applies concepts from a blockchain network to the distribution of application binaries, noted Landman.

    The PDN is based on patent-pending network optimization technology that employs caching, distribution nodes and lightweight accelerators that enable IT teams to distribute binaries through inbound-only firewalls or to environments that have limited connectivity, said Landman.

    Finally, the PDN also comes with tools to analyze binaries for open source security vulnerabilities and compliance with license policies in addition to role-based access controls (RBAC).

    Landman said the goal is to provide a way to distribute binaries via a single click all the way to edge computing platforms in a way that is tightly integrated with the continuous integration/continuous delivery (CI/CD) pipelines and software development life cycle (SDLC) processes a DevOps team already employs.

    Currently available via a private beta, PDN is scheduled to become available in the third quarter 2021 with pricing based on a per-use model that requires no upfront costs.

    JFrog

    For years now, JFrog has been making a case for applying DevOps best practices to the deployment of binaries rather than just managing source code. As enterprise IT environments become more distributed, the need to manage the deployment of binaries at scale becomes more acute. IT teams are not going to be able to dispatch software engineers to manually install binaries on every edge computing platform employed. The goal is to provide IT teams with complete transparency into software distribution in a way that makes it simple to address compliance requirements, said Landman.

    Most organizations already find deploying software to be a major challenge. CI processes are generally well understood as part of any application development process. CD has proven to be a more elusive goal, because each target platform on which software is destined to run tends to be unique, which makes automating the delivery process challenging. That issue is only going to be more difficult to address as organizations attempt to install software across hundreds, or even thousands, of edge computing platforms that might be based on a wide range of types of platforms. A PDN alleviates many of these issues by providing IT teams with a network to centrally manage the process, noted Landman.

    At this point it’s now only a matter of time before most organizations confront this next major DevOps challenge. As organizations look to process and analyze data at the edge to drive any number of digital processes in near real-time, the amount of software deployed outside of a cloud or traditional data center is about to explode. The challenge now, of course, is finding the most efficient way to secure delivery of all that code.