Category: Continuous Delivery

Continuous delivery is a software engineering discipline that allows organizations to consistently develop and release quality software at a rapid pace. It is achieved by automating the software development lifecycle, enabling tasks such as development, testing and release to occur concurrently and continuously.

  • How to Successfully Scale Agile

    How to Successfully Scale Agile

    Agile has proved its value to businesses across industries and geographies. In fact, the pandemic elevated it to an absolute necessity for organizations’ success and survival. Business leaders around the world invested aggressively in Agile transformation as they scrambled to meet changing customer demands through newly hybrid and remote workforces. Not surprisingly, the faster they adopted Agile methodologies at scale, the higher the value it delivered for them. Research indicates that the value Agile delivers can be a chance to grow ahead of peers as high as 63%.

    What enterprises in the U.S. now need is to move the right Agile levers to maximize business outcomes. The same research prescribes an agenda to make that happen:

    Mapping Customer Journeys

    This involves assessing what purpose the company’s offering serves and how value flows through the systems that surround it to the customer. By identifying the critical path of value flow and prioritizing Agile investments at the nodes of value, both volume and velocity of value to customers can be impacted. For example, at Marcus by Goldman Sachs, every team, no matter which department they belong to, responds to the question about what they do with an answer that has clear customer focus: Enabling customer onboarding, improving the customer service experience or helping with the customer password journey.

    Using Customer Insights

    This can be achieved through A-B testing techniques and analytics platforms to unearth the attitudes and motivations that cause customer churn, build loyalty and convert emotions to action. This involves gathering customer feedback through surveys, discussions, and, in the case of digital channels, insight from the channel itself. Additionally, this lever enables diverse perspectives as customers are onboarded, with inputs all the way from design to operations. Kraft Heinz, as an example, leverages Snowflake’s platform to leverage data to drive new digital experiences for consumers. Snowflake gives them real-time ability to sense, respond and evolve, with insights resulting in more meaningful interactions with customers.

    Organizing Teams Around Offerings Rather Than Functions

    This involves bringing together skills and capabilities to launch disruptive products in the market and win back market share. Product-centric agile value delivery is especially helpful in scenarios that involve multiple handovers between internal teams that could lead to delays and siloed developments. For instance, Daimler draws on the principles of swarm to pull in expertise from various departments and create cross-functional teams to collaborate when developing new products.

    Upskilling the Workforce

    It’s imperative for organizations to upskill their workforce for continuous delivery, strategic vision and skill alignment within autonomous, cross-functional teams. The rapid pace of development required to meet changing customer needs often creates a skills gap that needs to be bridged. Siemens is a great example. They accelerated their digital transformation journey in 2020 and realized how vital it is for every employee to easily access upskilling and reskilling opportunities. To stay ahead of the curve, they deployed an agile digital learning platform for their employees while leveraging and simplifying their existing learning ecosystem.

    Taking the Minimum Viable Product (MVP) Approach

    This lever assesses real value delivery, validates hypotheses and enables quick course correction as required. Budgets are always limited, and an agile MVP approach also maximizes investment value with faster delivery, optimized processes and increased flexibility. A recent case in point is the approach bp took when started work on an integrated energy-as-a-service (EaaS) offering that will provide end-to-end management of a customers’ energy assets and services. Their first step was to pilot the plan in an innovation center/work campus before exploring opportunities to manage energy more broadly at industrial and business parks.

    Expanding the Agile Workplace

    Companies need to extend and adapt the agile workplace concept for a hybrid reality by creating remote analogs for meetings, sales execution and IT support along with advanced collaboration tools. A great example is GE Appliances; at the very start of the pandemic they accelerated their workplace with automation-driven agile services support across their global command centers and service desks.

    Amplify Agile with Cloud

    Scaling Agile without sound cloud infrastructure is a good job half done, especially when firms want to buttress speed and utility with business resilience. In fact, the very best firms stand to take a good share of the $414 billion in profits cloud generates across industries and regions every year.

  • Why You Should Use GitOps to Experiment With AI

    Why You Should Use GitOps to Experiment With AI

    As the pace at which artificial intelligence (AI) models are being constructed and inevitably updated starts to increase, it’s becoming more apparent that the pace at which data science teams are currently experimenting also needs to dramatically quicken.

    Many data science teams today are fortunate if they manage to successfully deploy two AI models in a production environment over the course of 12 months. It’s already apparent, however, thanks in part to the rise of digital business transformation, that there are potentially hundreds of use cases for AI models within each enterprise IT environment. Truth be told, it’s hard to envision an application being developed today that would not incorporate one or more AI models. The challenge is, the demand for AI capabilities is now far outpacing the ability of data science teams to deliver.

    The best way to solve this issue is to recognize that AI models and the components employed to construct them are, in reality, just another kind of software artifact. In fact, the need to accelerate the development of applications using artifacts is largely a problem already solved. Rather than reinventing the wheel, the time has come to apply what we already know to the development of AI models.

    The Rise of GitOps-Based Processes

    Modern software development teams today routinely make use of Git-based repositories to share code and collaborate. These repositories are jam-packed with vetted software artifacts that development teams continuously reuse via an opinionated instance of a DevOps workflow based on a set of GitOps best practices.

    As a subset of DevOps, a GitOps workflow enables data science teams to employ a Git repository that already exists within their software development environment to manage artifacts. Git enables versions of files to be created using what is known as a Git branch. They also employ concepts known as tags (Git Tag) and remotes (where the server is located). Those three different concepts, or references, exist under the hood in Git. In fact, the entire flow is based on those concepts. When a new feature is implemented, a new branch is created and then merged into the production branch with a tag that says something like “This is a new version that needs to be deployed.”

    An AI model, like any other software artifact, needs to be updated. As new data sources become available, an AI model is likely to drift beyond the parameters originally intended. A rapid change in business conditions may also require changes to an AI model. The same processes that DevOps teams apply to update any software artifact can also be applied to rapidly update an AI model. Employing a Git repository to also manage AI artifacts extends the benefits that software development teams enjoy to data science teams.

    Often, organizations will have an MLOps solution to streamline AI model development that is completely separate from their DevOps tools. These solutions will have dedicated features like version tracking for data and experiments specifically for AI models. But many MLOps solutions exist in a closed ecosystem, meaning they don’t work off of existing tools like GitHub used on the DevOps side. 

    Also, data science teams have to separately buy, deploy, and manage these closed MLOps solutions. Going with a GitOps-oriented solution streamlines management of added MLOps tools and makes it easier for both application developers and data science teams to gain visibility into each other’s respective efforts. The end result is not just faster AI experimentation at lower cost; the likelihood that more AI models will successfully be deployed in a production environment increases dramatically. 

    Software and AI Teams Working Together

    The convergence of DevOps and MLOps is already inevitable. The longer organizations continue to employ isolated MLOps platforms to build and deploy AI models, the more expensive it will become to meld MLOps and DevOps processes. 

    Data science teams are conservative by nature. The difference between success and failure often comes down to how thoroughly an AI model is validated. However, time to market doesn’t have to be sacrificed to ensure an AI model works as promised. There is no such thing as a great AI model that arrives late when rivals are racing to develop similar AI capabilities—there are only missed opportunities. Speed enabled by the reusability of artifacts that drives faster experimentation using GitOps workflows is of the essence now more than ever.

  • 5 Ways to Embed Accessibility in Your SDLC

    5 Ways to Embed Accessibility in Your SDLC

    Developing an accessible software development life cycle (SDLC) requires a commitment to inclusion from everyone at the beginning of every project. By committing to developing accessible products, you will avoid costly and timely remediation prior to deployment at the end of your product roadmap.

    Creating An Accessible Software Development Life Cycle (SDLC)

    An accessible SDLC is one in which accessibility is integrated into every stage from planning through maintenance. This includes accessibility policy, automated testing against that policy, incorporation into your QA processes as well as verifying and documenting conformance requirements such as voluntary product accessibility template (VPAT) creation.

    Integrating accessibility isn’t really all that different from testing for any other quality standard, like cross-browser compatibility or other bugs. Here are the five key elements required to support your efforts:

    Policy – Start by establishing your accessibility goals, then prioritize based on importance (which is helpful for future sprint planning). Define these goals and priorities in your policies so that you can use them to measure your successes and understand where you need improvements.

    Automated and Manual Testing – Automated testing works by using software to scan your digital assets—whether in production, dev or staging—with an accessibility rules engine to check for errors. It can quickly and efficiently catch machine-detectable web content accessibility guidelines (WCAG) failures—the accessibility standard—that engineers can fix during the development process. Automated testing can be performed in many ways; however, the approach that will work best for you will depend on the level of integration that your DevOps team can facilitate. Manual assessments are far more comprehensive than automated scans. They also take essential user experiences into consideration, and they can catch errors far beyond what is machine-detectable today.

    Integrated User Story Development or Continuous Integration/ Continuous Deployment (CI/CD) – Once you’ve found the failures, what do you do with them? They should be treated like any other bug or glitch that prevents customers from accessing or using your website or application. You’ll want to capture this information in your ticket tracking system. Many organizations use agile sprints and project management software to create tickets, which are then fed into the development pipeline and prioritized, assigned and completed. Finding a solution that will let you easily convert WCAG failures into user stories (either manually or, better yet, through automation) is key for feeding a prioritized pipeline of work to be done.

    Knowledge and Resources – There are specific development techniques used to solve accessibility failures. Without access to a comprehensive library of accessible code techniques, developers will spend a lot of time scouring the web for solutions. Yes, you can find good solutions if you look long enough, but even so, how do you know whether that solution is legitimate or optimal for your case? Having the relevant solutions for an issue at your fingertips (negating the need to do a ton of online research) lets your DevOps team work more smoothly with fewer disruptions.

    Accountability – Accessibility analytics establish accountability. How effective are your DevOps teams at reducing WCAG failures? Tracking failures across your digital properties on a defined cadence lets you see and document trends over time. You can also track activities like the volume of tickets that are tagged as accessibility remediation or bugs, or new features or capabilities to represent active efforts.

    Whether you’re on a small or large development team at any size organization, adopting an accessible SDLC by implementing continuous accessibility checks at each phase of your development cycle is the most efficient and effective strategy to ensure that your website or applications are WCAG and ADA conformant.

  • Measuring Value Streams by Analyzing Flow Metrics

    Measuring Value Streams by Analyzing Flow Metrics

    There is increasing pressure and demand for IT administrators to bring software to market quickly and cost-effectively. To achieve that goal, IT departments frequently compile various metrics that measure specific development processes.

    Data and metrics are important tools, but administrators sometimes don’t think to look at projects through a wider lens—by measuring total production workflows. This can curb production and adversely affect business outcomes as inefficiencies go undetected across the value stream.

    In other words, total visibility across the entire value chain is needed to accomplish lean project management and optimize DevOps workflows.

    Let’s talk about the different kinds of flow metrics, why they matter and how to begin measuring them.

    Flow Metrics: What do They Mean?

    Flow metrics indicate the rate of value delivery with regard to desired business outcomes. This allows organizations visibility into production at a macro level so that they can make more effective decisions. Flow metrics can also produce an analysis of historical performance over time, which can be valuable for businesses that focus on continued growth.

    IT leaders now widely use flow metric analysis to bridge the gap between business teams and technology, because it can uncover a variety of problems that affect critical objectives. For instance, teams can identify prioritization challenges, why projects take longer than expected, pinpoint technical debt and more.

    When evaluating flow metrics, IT departments measure individual work units—also known as flow items—that clients or product teams hand over to their colleagues. This may be a request for a new software feature, a security flaw or something that needs a fix.

    What Are the Different Kinds of Flow Metrics?

    With a better understanding of flow metrics, we can now delve deeper into the five flow metrics that organizations should assess throughout the development process.

    1. Throughput

    Throughput measures the rate at which total number of flow items are completed. By measuring this, throughput can determine the total amount of value attained and distributed during a specific project.

    Throughput is generally measured week-over-week. Measuring and evaluating throughput on a historical basis also helps work out how clashes in priorities affect value overall.

    Optimizing throughput results in greater end user experiences and customer satisfaction, which naturally drives revenue and growth.

    2. Cycle Time

    Cycle time is the speed at which an IT team can deliver value. This means timing how long it takes for flow items to progress from work start to work complete, taking into account active and wait times.

    Cycle time is just as important as throughput when it comes to driving revenue and growth. Measuring cycle time can streamline the process of determining project estimates and allocating resources, resulting in stronger workflows and enhanced efficiency.

    3. Flow Efficiency

    Flow efficiency is the proportion of active time to wait time. Measuring flow efficiency uncovers where roadblocks are happening and whether process waste is rising or falling. The desired flow efficiency rate should be higher than 15%.

    Most flow time comes from waiting, resulting in roadblocks and increased production costs. Measuring flow efficiency can enable teams to pinpoint when workflows are taking too much time, and they can then take active measures to accelerate individual processes.

    4. Work in Progress

    Work in progress involves measuring demand. Teams achieve this by measuring the amount of flow items either pending or in active development within a value stream. Measuring work in progress generally enables IT leaders to identify whether value streams are overused or underused.

    Nobody’s perfect. That’s why leaders have to be conscious of how each employee’s time is being used. By doing so, they can systematically assign workloads and enhance quality where required. This, in turn, lowers burnout and turnover while also cutting down on mistakes that need to be reworked.

    5. Work Profile

    Measuring work profile is important when determining priority alignment. It’s analyzed as a ratio of the four other flow items completed in a specific time period.

    Assessing work profile allows for optimal quality and productivity. This raises customer experience (CX), which results in better retention and reviews.

    Why Should I Track Flow Metrics?

    In the past, DevOps professionals largely went without the necessary tools for tracking and enhancing flow metrics, but recent improvements in tracking these metrics have made the process much more efficient and easy.

    There are three key reasons for flow tracking:

    1. Boost Communication

    A lack of communication can be a common issue between business and software teams. Flow tracking enables IT administrators to delve into flow metrics and gain insight into the value stream. This helps teams provide accurate project estimates along with real-time updates, which makes communication with stakeholders much easier.

    2. Determine Desired Business Outcomes

    Having total visibility across a value stream helps IT and business leaders cooperate on identifying and prioritizing key projects and establishing goals.

    Improving software quality could be a goal, for example. Teams can examine various flow metrics to determine what is causing issues in software quality, how to fix those issues and how prioritizing adjustments to software quality could affect other workflows.

    3. Act on Intelligence

    Software organizations spend a lot of time and money attempting to expedite software development. They hold meeting after meeting, hire consultants or even bring on new team members, but the solutions they need to streamline workflows can be simple. They just need to be discovered.

    Organizations can gain total and real-time visibility into the value stream with flow tracking. This makes it quick and simple to act on intelligence and enhance development, leading to accurate, data-driven decisions that don’t require guessing.

    Elevate Your Value Stream With Flow Metrics

    Achieving optimal efficiency in workflows requires end-to-end visibility, which is made easy by analyzing flow metrics.

    Using flow metrics to maximize the value stream improves visibility, accelerates development and cuts software production costs.

  • How Third-Party Security Assurance Enhances DevSecOps

    How Third-Party Security Assurance Enhances DevSecOps

    Enterprises are constantly trying to do more with less today, and do it faster to gain competitive advantages and grow revenue. Nowhere is this more prevalent than in their internal software development processes. The movement to third-party or external sources of code is a natural reaction to “faster” release cycles. However, this need for speed can have unintended downstream security consequences for application development teams.

    As cybercrime has grown parallel to the explosion of digital processes in many enterprises, “security by design” needs to go from a nice-to-have concept to a hard reality. This is the reason DevSecOps has gone from buzzword to practice for many development teams. Implementing a software security assurance program, which embeds security as part of the coding and assembly process rather than a separate, after-the-fact quality testing function performed by security staff, is vital to limiting the cost of fixing vulnerabilities and preventing data breaches.

    Software Attacks are a Growing Problem

    One of the recent and most high-profile cybercrime incidents involved hackers using the SolarWinds software platform as a launching pad to breach companies. With threats specifically targeting software on a growth curve, organizations need to secure both the software they develop and that which they acquire from suppliers. This often includes a lot of reused code picked up from vendors and open source libraries that offer the building blocks for software and applications to help developers work faster and cheaper—but with a potential security cost.

    Maintaining software security has become more complicated as enterprises rely more on third parties for the components to develop software faster and cheaper and keep up with digital disruption. The share of code developed in-house for enterprise software has dropped from 43% to 38% in the last five years, while the use of commercial and open source software has grown in its place. Rather than rely on custom code, many developers are leveraging open source components or API libraries to build applications. Some software vendors provide application libraries that can have third-party components purchased by that vendor for their customers.

    Leaning on third-party code can leave software open to abuse, as developers have less visibility into the content of the components they use as the building blocks of their programming. Some vendor libraries get reused by the vendor for different applications, and some use open source components in their code; a developer may be using third- and fourth-party code from who-knows-what source. Vulnerabilities can be hiding many layers deep in the code, and unless developers know the source, they are difficult to detect.

    This is where a well-established software security assurance program can reduce the risk of cybersecurity incidents and the impact of security weaknesses. It protects users and the enterprise by establishing cybersecurity practices, fulfills the organization’s risk management and compliance requirements and offers the C-suite visibility into the process.

    A Checklist for Software Security Assurance

    A well-organized security assurance program ensures that security requirements have been established for the software and the software development process and that any software deployed is free from vulnerabilities. If any are found, it also establishes remediation steps to handle them.

    Some important practices:

    ● Trust but verify: Ensure that a security evaluation has been performed for the software throughout the software development life cycle (SDLC). Proactively validate the security and integrity of software code and provide results identifying any vulnerabilities found and assign remediation steps to correct them before release into production.
    ● Know what’s in the software: Since many developers and software vendors rely on open source and third-party code more frequently, it’s more important than ever to know what those components are and where they come from. Software security
    assurance should include the software bill of materials (SBOM) for any open source code and third-party components.
    ● Put it in writing: Produce documented proof, such as the SBOM mentioned above, and generate a vulnerability report proving the integrity of the software. If vulnerabilities are found, determine the cybersecurity risk and the potential impact based on the Common Vulnerability Scoring System (CVSS) score, an industry standard, to guide remediation.

    A good software security assurance program makes sure that each software review or audit includes an evaluation of the security requirements for the enterprise. These can vary by industry—and even within the organization—based on which function the software is running. A program running mailing lists for a power generation company is not as mission-critical as the software running the power grid.

    With all industries in the crosshairs of cyberattackers, an effective and diligent software security assurance program will make it harder for them to find a back door and can help keep your organization safe.

  • Real-Life BDD: Getting the Best Out of Dev Teams

    Real-Life BDD: Getting the Best Out of Dev Teams

    If we want our software to have value, we need to improve it every day, rather than wait three months for the next release. If someone finds a bug and we know how to fix it, we want to deliver the fix that day. The challenge is deploying to production many times a day.

    If the developer is coding right now, we want to see their work in production today. However, when you increase the speed of delivery, you need to be sure that the code you deploy works. To increase speed and quality at the same time, you need a safety net and a lot of automation.

    Sometimes we need to change the mindset of developers. This affects interactions between the developers and product management. It also changes the way developers code and how they approach their work.

    Break It Down

    Behavior-driven development (BDD) helps all of my teams. My mature teams use the three stages of BDD: discovery, formulation and automation. To increase speed and quality in a team that isn’t as mature (not much test automation, a lot of manual testing), one of our challenges is to develop small pieces of code they can deliver.

    When we groom an item in the backlog, the product owner (PO) explains what’s needed, but sometimes when the developers start working, they find other stories that may take two weeks each. With BDD discovery, the PO and developers can reach a shared understanding of what’s needed before coding starts. If the story is too large, example mapping helps them split it. They need to obtain stories that will take less than three days.

    More Ideas, More Examples, More Agile

    To simplify collaboration between the engineering and business units, the product team needs to understand the size of the ask for the developer. You can improve communication by showing all the different cases that exist for this feature and by using example mapping.

    Here’s an example of how this works in practice: the product team asks for a feature and explains it in about 10 minutes. The developers say this will take two to three weeks. However, after the developers completed user story mapping and example mapping and began to split the big features into smaller stories with examples, they realized it would take much longer. There were simply too many things the product team hadn’t known about.

    The product team had lots of ideas, but ideas take time to implement. Now that they had more examples, they could make better decisions about what was mandatory and what would be great but was not essential. Working in this way allows us to be more agile.

    The particular aspect of BDD that helps here is discovery with example mapping. I like to use user story mapping to see different versions of the same feature to understand the value brought by the feature’s different potential iterations.

    Whenever Possible, Push Live Code

    I’ve transformed the way my team works to help them to release more often. The key is to add a continuous integration server with the first automated test and a staging environment where the code is deployed many times per day. This allows us to automate the process from the code, so when a developer pushes the code, we have the beginning of a safety net. When the safety net says everything is okay, deployment is triggered to a staging production environment. The production can be a staging production, but it’s better when it’s live. When it’s not possible to deploy directly in production, then you should at least deploy in a staging environment.

    From the developer’s point of view, when they push the code, there’s an impact on production, even if it’s just within a staging production environment. For the next step, they need to create the first unit test each time they have to add code. In other words, every time you write code, you need to have an automated test at the same time. These tests should be run by the continuous integration server.

    Once you have that, the next question is about the size of the code you push. If you wait a few days to push or use another branch, you won’t have the value to see the increment of the code you’ll push.

    Developers Should Own Quality

    Quality has traditionally been the responsibility of the QA team, but it should be owned by the developers. As a developer, you can’t wait for someone else to read your code and tell you it’s okay and then talk to the QA team to make sure you didn’t introduce a bug. If more unit tests are needed, you should write them and you should be using test-driven development (TDD) and BDD. You also need a lot of feedback. You need to be the owner of quality, and help your team achieve it.

    To summarize, here are my top three tips:

    • Automate the process of deployment with continuous integration/continuous delivery
    • Create examples with all the stakeholders of the project together—product, development and testers
    • Create small stories that you can deliver in less than three days
  • Google Unveils Tool to Better Secure GitHub Repos

    Google Unveils Tool to Better Secure GitHub Repos

    Google today launched a GitHub app that provides automated continuous enforcement of security best practices for GitHub projects.

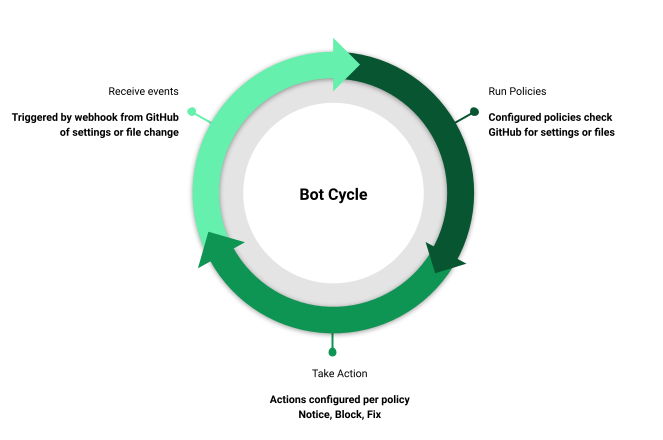
    Kim Lewandowski, a product manager for open source software security at Google, said the Allstar application enables IT teams to assess any project on GitHub to check for security policy adherence. In addition, Allstar sets desired enforcement actions and automatically applies those rules when triggered by a setting or file change in a repository.

    The goal is to provide the open source community with a tool that makes it possible for organizations to have more confidence in the open source software that is being employed within a software supply chain, said Lewandowski.

    Allstar is intended as a companion application for Security Scorecards, a tool that Google made available last year to assess whether, for example, an open source project employs branch protection to ensure that malware isn’t inadvertently committed to a project. Allstar continuously checks expected GitHub API states and repository file contents against security policies and the enforcement actions defined by an IT organization. After it detects a policy violation, the tool can be configured to simply send an alert or to automatically enforce a specific policy to remediate the issue, said Lewandoski. Specifically, she said the options available are to log the security policy violation without taking any additional action, open a GitHub issue or modify the GitHub setting to match the original Allstar configuration.

    At present, Allstar provides a limited number of security policy checks, but more will be made available over the coming months, said Lewandowski. Current security policy checks include branch protection, vulnerability disclosures, access controls and detection of binary artifacts that can’t be scanned. Additional checks that will be added include automatic dependency updates and frozen dependencies.

    Lewandowksi said Allstar and Security Scorecards are part of an ongoing Google effort to give back to the open source community that is being targeted by cybercriminals attempting to compromise software supply chains. Just about every application is now dependent on open source components, to some degree. The maintainers of those projects, however, don’t always have the tools or expertise required to check for malware that has been injected into a codebase, she noted.

    In general, Lewandoski noted that achieving DevSecOps best practices will require a lot more automation of application security. It’s not possible for each developer to become a world-class cybersecurity expert. The challenge is finding a way to introduce that automation into the application development process as early as possible, which, she noted, in many cases starts with open source components that are incorporated in applications.

    It may take a while for every maintainer of an open source project to revamp the processes through which code is added to their project. However, the easier it becomes to continuously review that software, the more confidence organizations that use it will have in its security. In fact, the maintainers of those projects should expect the downstream users of that software to be asking some pointed questions about how security is being managed in the wake of a series of recent high-profile breaches of software supply chains.

  • DataOps Vs. DevOps: What’s the Difference?

    DataOps Vs. DevOps: What’s the Difference?

    There is a mindboggling amount of data today; to even measure it requires using a byte measurement called a zettabyte, which is one sextillion bytes (that’s 21 zeros). Currently, because such a ridiculous amount of data exists, there is a growing urgency to end wasteful data processes. From this environment, DataOps was born. Similar to the way that enterprises adopted DevOps to formalize and streamline wasteful development practices in the past, today, many large organizations turn to DataOps to formalize modern data management practices.

    What, Exactly, is DataOps?

    Primarily, many companies are adopting these principles because they are either trying to avoid or rectify data debt, which is the amount of money required to fix data problems due to the mismanagement of data processes. Data debt is a strong motivator for revamping outdated processes and policies, particularly when decision-makers and stakeholders require metrics before implementing change. Unpaid data debt can be detrimental to a business; the longer it remains unpaid, the more it costs to maintain a data landscape.

    By implementing DataOps principles and data governance, an organization can effectively reduce its data debt and prevent it from growing any larger. Moreover, DataOps practices and software engineering can be used to detect inefficiencies, minimize knowledge loss and capitalize on missed opportunities related to data usage.

    Similarities Between DataOps and DevOps

    Much of the processes that enable DataOps were borrowed initially from the same foundations that built DevOps. Likewise, just as companies need DevOps to provide a high-quality, consistent framework for software and feature development, data enterprises also rely on these same features to realize rapid data engineering and analytics development. For organizations that already have a DevOps framework in place, leveraging DataOps is relativity straightforward. Several important DevOps concepts adopted by DataOps include:

    • Agile development
    • Focus on delivering business value
    • Continuous integration and continuous delivery (CI/CD)
    • Automated testing and code promotion
    • Reuse and automation

    The Differences

    Despite the similarities between the underpinnings of DevOps and DataOps, there are several major differences.

    The human factor: The people using DataOps and DevOps have divergent personalities and skillsets. DataOps participants may be tech-savvy, but often their knowledge is theoretical. DataOps professionals can include data engineers, data scientists and analysts who focus on creating models and visual aids. DevOps, however, was made for software developers and engineers–coding is in their DNA.

    The process: The life cycles of DataOps and DevOps do share similar interactive properties. But, the former deviates in that it consists of a data pipeline and an analytics development process, both active and intersecting. While conceptually, the pipelines of DataOps resemble the development processes of DevOps, typically, experts note that the DataOps process is more challenging.

    Orchestration: In the DevOps process, application code does not require complex orchestration. However, for DataOps, both the data pipeline and analytics development orchestration is an essential component. Although orchestration in the DataOps pipelines occurs frequently and drives data flows, there is usually no such coordination of pipelines in application development and DevOps processes.

    Testing: Again, the two pipelines of DataOps create a significant difference from DevOps; testing in DataOps occurs during both the data pipeline and the analytic development process. These tests attempt to catch anomalies, flag abnormal data values and–unlike DevOps–validate new analytics before deployment. Likewise, these tests get embedded into a data quality framework for continual monitoring.

    Test data management: In most DevOps environments, test data management hardly takes priority; with DataOps, it’s vital to accelerate analytics development so that innovation keeps pace with agile iterations.

    Tools: DevOps is the ‘father’ of DataOps, and as such, the tools needed to support the latter are still in their infancy. While testing in DevOps is primarily automated, DataOps doesn’t have the same luxury – most users modify testing automation tools or build their own from scratch.

    Exploratory environment management: Generally, data teams use more tools than software development teams. Moreover, exploratory environments in data analytics are more challenging from a tools and data perspective; data teams also naturally depart from data islands across the enterprise.

    While foundationally, the concepts of DevOps serve as a starting point for DataOps, the latter involves additional considerations to maximize efficiency when operating data and analytical products. Nevertheless, both serve their intended audiences, reducing data debt and evolving data products or shortening systems development life cycles or providing continuous delivery. For businesses looking to make internal data-related processes more efficient, they should start by examining best practices associated with DevOps.

  • Continuous Delivery: The Secret to 5G’s Success

    Continuous Delivery: The Secret to 5G’s Success

    New technologies are evolving the way societies function, and as a result, how businesses are carried out. In the networking industry, these emerging technologies coupled with the long-lasting impact of the past year–such as remote working–are changing the way customers and communication service providers (CSPs) interact. To that end, these shifts in behavior subsequently bring in a new demand for how communication services are delivered.

    Networking technologies have made some remarkable leaps in recent years. For example, system-on-a-chip advancements have elevated IoT devices to the next level. Moreover, edge computing, high-performance computing and a revolution in software, analytics and AI gave real-time local data processing a dramatic boost in its value proposition. But perhaps it is 5G that has brought forth some of the most astounding enhancements. 5G connectivity enables secure and reliable commercial and industrial operations–all of which can occur with zero latency and in real-time–that are driving the acceleration of OT/IT convergence and more.

    With every new generation of wireless networking, CSPs are bound to ask the burning question: What’s the “killer app” that will help bring in more customers and revenue? In the past, each generation found its answer in the evolution of mobile device usage. However, 5G has changed the game as we know it. Through 5G, CSPs can now tap into various new opportunities in previously inaccessible enterprise markets. Because of this, there is no single killer app that fits all verticals. For example, a 5G killer app in the transportation industry will look very different to one in the health care sector.

    So then, what is the killer app for 5G? To start, we should take a step back and recognize that for 5G, the killer app will be the network itself. This is because the network enables the rapid creation and launch of tailor-made 5G services to meet unique customer needs and use cases across different vertical markets. In the 5G era, the ability to bring new services with faster time-to-market while optimizing costs is the key to generating real business value.

    Achieving the flexibility and agility needed for 5G services will first require an established foundation. A critical step to build that foundation is establishing a cloud-native network core and adopting automation-driven continuous integration and continuous deployment (CI/CD) functions. That way, CSPs can begin to add real value to their networks.

    Why a 5G Cloud-Native Core is Mission-Critical

    Cloud automation isn’t just a buzzword, and it’s becoming increasingly important. With 4G, a cloud-native core may have been a preferred option, but for 5G services–which enables a range of applications and will continually need updated capabilities–a cloud-native design is mission-critical. Through a 5G cloud-native core, the possibilities are endless, as it enables services-based architecture, improved session management, end-to-end network slicing and access-agnostic connection for seamless mobility and more.

    5G networks with cloud-native cores will also continue to offer new communication features and services, of which automation will be a key enabler. This is where DevOps comes in. DevOps can improve automation to a greater extent, and help CSPs automate delivery, installation and testing. Thus, CSPs ought to embrace continuous delivery as the basis of DevOps, as DevOps automation becomes more cloud-centric. Today, many public and private cloud computing providers support cloud DevOps systems on their platforms, such as continuous integration and continuous development tools. When you consider connectivity services’ high complexity–with multi-vendor and multi-domain software supply chains and multiple production environments–an added level of process focused on delivery operations is crucial.

    Embracing Continuous Delivery to Harness 5G’s Power

    Continuous delivery may be a familiar concept to the cloud world, but it’s fairly new to the telecom industry. For CSPs, embracing continuous delivery in telecom networks requires the capability to meet the needs of distinctive environments and their associated challenges. One way CSPs can do that is by implementing a delivery operation (DelOps) solution: A reimagined DevOps. What makes DelOps ideal for telecom environments is its ability to leverage a many-to-many delivery and operations process–complete with design, deploy, test and operate phases.

    In the telecom industry, each network and operational environment is unique; therefore, solutions aren’t “one size fits all.” For CSPs, implementing the best DelOps CI/CD solution requires them to form the right partnerships with operators. That way, they can establish a CI/CD architecture that is flexible, complements their operational environment and can be integrated with any cloud architecture.

    With DelOps CI/CD solutions, seamless automation in delivery and operations can become a reality. It is the “secret sauce” to 5G success as it:

    • Leverages agile processes to reduce rollout cycle times and product/services time-to-market
    • Ensures the CSP’s network is up-to-date and launches new services efficiently and swiftly
    • Requires less effort to conduct acceptance testing, tracking and management of release features
    • Resolves issues rapidly to ensure seamless customer experience and satisfaction

    As the 5G era continues to grow and evolve, the adoption of CI/CD services by CSPs should be done sooner rather than later to achieve a smooth operational journey. In doing so, CSPs can evolve their networks to the best possible level of performance—ultimately boosting their competitiveness to generate new revenues and achieve long-term success.

  • What is Continuous Delivery?

    What is Continuous Delivery?

    [pdf-embedder url=”https://devopsy.kinsta.cloud/wp-content/uploads/2022/02/what-is-continuous-delivery.pdf”]