Category: Application Performance Management/Monitoring

  • How to Improve Cloud Management

    How to Improve Cloud Management

    Cloud technology underpins emerging technologies like artificial intelligence (AI), IoT, edge computing and containerization. Organizations must prioritize implementing effective cloud management practices to avoid spiraling costs and potential security and compliance violations.

    The COVID-19 pandemic has vastly accelerated cloud adoption. To support remote work, many businesses have moved workloads from on-premises servers to the public cloud. At the same time, thanks to the proliferation of technologies like AI and machine learning, organizations are generating more data than ever, much of which is also being stored in the cloud. It’s no surprise then, that the explosion in demand for cloud services is showing no sign of slowing down. Gartner predicts that worldwide end-user spending on public cloud services is forecast to grow by 23.1% in 2021 to total $332.3 billion.

    But, it’s not all smooth sailing. As the average organization’s cloud infrastructure grows in complexity and size, it becomes increasingly difficult for teams to manage it effectively. This has significant security, compliance and cost implications. According to Accenture, an astronomical 30% of organizations’ cloud spend is currently wasted.

    So, what can you do to ensure you avoid the most common cloud management pitfalls?

    See the Big Picture

    It’s surprising just how little visibility many businesses—even those with large teams of cloud architects—have into their cloud infrastructure. For instance, one recent survey found that over 25% of IT departments have no idea what their monthly cloud spend actually is.

    Before taking steps to optimize your cloud management practices, it’s crucial that you gain full visibility into your current situation. You need to understand your cost history, audit trail and CPU utilization patterns to identify where you’re overspending.

    Plus, make sure you’re using tagging consistently. A well-defined organization-wide tagging policy is essential, enabling you to accurately visualize expenditure by category. It’s also good practice to set up alerts which are triggered when a user launches instances without tags. This prevents any potential oversights.

    Develop a Change Management Process

    Gone are the days of rigid change management processes handled solely by IT teams. Nowadays, business units can acquire cloud services without even involving IT.

    In the cloud, change management is a series of continuous integrations, deliveries and deployments. Given this fast-moving environment, it’s crucial to implement a robust change management process or risk spiraling costs and potential compliance violations.

    It’s important that your change management process gives you visibility into and control of each infrastructure change without compromising on delivery speed. To achieve this while establishing strong policies and rules, it’s worth considering automation for at least part of the application delivery process. By auto-approving all routine and low-risk changes, you can free up time for your developers to focus on more complex projects.

    In addition, it’s worth integrating your change management process with your DevOps tool stack. You can use collaboration tools like Slack, Teams and/or Jira to ensure everyone has visibility into changes and resolve any issues quickly.

    Continuously Optimize your Cloud Infrastructure

    Unfortunately, when it comes to effective cloud management, your work is never truly done. Conducting a one-off review of your existing cloud infrastructure will only get you so far.

    Many businesses make this mistake and find themselves falling back into their old bad habits a few months down the line. To keep your cloud infrastructure in check, it’s best to continuously track a whole host of factors, including costs, changes, users, permissions and compliance breaches. After all, it’s much easier to solve an issue when you are able to spot it before it gets out of control.

    Now you have an idea of where to start when it comes to improving your cloud management practices. However, manually juggling all of the above considerations is a significant undertaking. It’s prohibitively time-consuming for many organizations whose DevOps teams are already overstretched. This is why a whole host of SaaS-based cloud management tools have sprung up in recent years. These offer unparalleled visibility into changes, resource utilization, costs, security, compliance, performance and more. Yes, they come at a cost. But, most businesses find that the savings such tools enable them to identify significantly exceed any outlays.

  • CircleCI Bets on Webhooks to Streamline DevOps Integrations

    CircleCI Bets on Webhooks to Streamline DevOps Integrations

    CircleCI today announced CircleCI webhooks, a feature that enables software engineering teams to build integrations that react to CircleCI job and workflow status notifications in near-real-time.

    Tom Trahan, vice president of business development at CircleCI, said this latest iteration of the company’s implementation of webhooks, which send messages any time an event occurs, will become the foundation upon which CircleCI will expand the ecosystem surrounding its continuous integration/continuous delivery (CI/CD) platform.

    For example, the CircleCI platform can now employ webhooks to integrate with a CI visibility tool from Datadog that can now be used to surface CicleCI metrics. Sumo Logic is similarly employing webhooks to enable its Continuous Intelligence observability platform to track events on the CircleCI platform. Those capabilities are now available via the software-as-a-service (SaaS) edition of the CircleCI platform.

    Trahan said the primary goal is to reduce the amount of friction within DevOps workflows that span multiple platforms by increasing the level of orchestration DevOps teams can take advantage of without having to create and maintain integrations using low-level application programming interfaces (APIs).

    Webhooks make it possible to streamline developer workflows while also increasing overall engineering velocity, he added. In addition, it should also become simpler for DevOps teams to triangulate events in a way that results in incidents being resolved faster, noted Trahan.

    CircleCI is relying on webhooks to strengthen its case for a best-of-breed approach to DevOps that enables organizations to mix and match tools as they best see fit rather than getting locked into a single integrated DevOps platform. The best-of-breed approach often makes it simpler to take advantage of new tools as they become available. The downside is the level of integration that DevOps teams need to maintain after they integrate all the tools that make up a DevOps workflow.

    It’s not clear what impact relying on webhooks to share messages in real-time about events as they occur across multiple platforms will have on integrations. However, any effort to streamline DevOps environments without requiring DevOps teams to abandon one tool for another is likely to be well-received. After all, every minute spent managing a DevOps platform means much less time that can be applied to building and deploying applications.

    It will be up to each DevOps team to decide to what degree a best-of-breed approach to DevOps suits their organization. As more organizations realize how dependent they have become on software to, for example, drive digital business transformation initiatives, many IT leaders are making a case to standardize DevOps platforms across their organization. Achieving that goal, however, may be difficult given all the various departments within an enterprise that have already adopted a wide range of tools and platforms.

    In the meantime, the focus on developer and engineering productivity will only increase as organizations look for ways to further accelerate application development and deployment at a time when software updates can now have a profound impact on profits and revenue. In fact, a delay to one software project can have a cascading impact on a wide range of initiatives that can’t go forward because of their dependency on a delayed project. Given the impact all those delays might have on revenue, the tolerance organizations have for delays to software development projects is understandably lessening by the day.

  • How to Achieve Cloud Operational Excellence

    How to Achieve Cloud Operational Excellence

    Cloud operational excellence means delivering the right mix of cloud-based services at the optimal cost and quality to support your organization’s mission and strategy. You might be thinking, “Why go to the trouble? Isn’t ‘almost good enough’ sufficient?” It turns out that it matters—a lot. The difference between the top 10% and the bottom 10% in cost per relevant delivery metric can vary by an order of magnitude or more.

    In the mid-1990s, Gartner acquired an IT metrics firm called Real Decisions. They offered benchmarking services so customers could compare their IT efficiency with similar organizations. With hundreds of “Global 2000”-sized customers, their database was rich. Over time, the Real Decisions team refined their catalog of metrics and enriched their data with repeat studies over time, to develop indices of efficiency. 

    Within their user population, the difference in cost per unit of productive work was 11 times better in the top 10% compared with the bottom 10%. That doesn’t mean 11% better, it means 1,000% better. 

    Note that the user base was self-selected. All participants wanted to get objective metrics of performance relevant to their business goals and paid for extensive studies involving questionnaires, financial audits and technical benchmarks. Notably, all participants had cost recovery programs (beyond chargeback) in place. The bottom 10% of this segment is still within the top 10% of the IT industry—and their score is 11 times worse than the best of the best. 

    Which raises the question: What is the industry average for IT efficiency? Is it possible that the hundreds of benchmarking users are all doing IT wrong, and the search for relevant metrics is misguided? I think not. 

    Choosing the Right Metrics

    In 1911, Fredrick W. Taylor published The Principles of Scientific Management, which discussed approaches to optimizing two important variables: Output quality and worker compensation. Taylor recognized that successful firms work collaboratively, with management and workers jointly setting goals and developing methods and tools to achieve both profitability and proportionate compensation. Nowhere in this text—or in any of his recorded speeches or documents—does he say, “If you can’t measure it, you can’t manage it.” He never said that for two reasons: First, he did not believe it; second, it is not true. What he did emphasize was that if you do measure it, you will manage it. That was a warning: Pick the right metrics or you will exert effort pursuing a meaningless goal. 

    Here are some potential cloud performance metrics compiled from several cloud providers and users across various industries, not-for-profits and governmental agencies: 

    • Service Metrics 
      • Reliability – mean time between failure (MTBF)
      • Availability – Uptime, expressed as a meaningful percentage of demand
      • Serviceability – Mean time to repair (MTTR)
    • IT Metrics
      • Capacity 
      • Latency
      • Bandwidth
      • Response time
    • Strategic Metrics  
      • Business agility 
      • Customer engagement 
      • Customer reach 
      • Financial impact 
      • Solution performance 

    The journey to cloud excellence starts with developing the metrics that are most relevant to your business goals. Picking the right metrics with the right scale matters. As a rule of thumb, generally right beats precisely wrong. 

    Sustaining Excellence 

    After you agree on a set of metrics that are both statistically reliable, repeatable, objective and aligned with your firm’s mission, how do you achieve and sustain excellence? 

    In the 1970s, the U.S. Department of Defense bought a lot of custom software. Sometimes it worked well, other times it didn’t. So, the DoD funded research on code quality. It turns out that the key difference between great and mediocre quality code flowed from how the organization managed problems. More specifically, how did the team react to an unexpected event? The spectrum runs from confusion and dismay through fire drill chaos to calm, rational assessment and remediation. That methodology gets baked into the code itself. This study produced the Capability Maturity Model (CMMi), which was created by the Software Engineering Institute at Carnegie Mellon University. 

    The CMMi framework identifies five levels of process maturity. A simplified assessment of an organization’s process maturity level comes down to two questions. First, is there current comprehensive documentation for the process, including how to deal with defects? If the answer is yes, the organization is at level three or higher. If the answer is no, the second question is, “Does anyone know what’s going on?” If the answer is yes, that’s level two; if no, level one. 

    A level one organization has no standard method in place to deal with problems. When something goes wrong, everybody grabs tools and tries to figure out what went wrong and how to fix it. Organizations like this do not spend much on training or analysis. Their focus is continuing to produce whatever they are trying to make. Over time, an individual may develop expertise in diagnosing a component, and when things go wrong, the call goes out to “Get Fred in here!” to troubleshoot the problem. Organizations with pockets of expertise are moving into level two. Most organizations fall within one of these two levels. 

    Organizational transformation is very difficult, and often requires significant changes in the management team, as well as funding different activities. Training and communications skills are crucial to proceeding beyond level two. Management rewards heroes who can shoot the most difficult bugs. They get the big bonus, the promotion, the better office, a parking space near the door. This behavior reinforces the culture of heroes. But moving forward requires the heroes take on a new role.  

    Once the organization creates documentation, it is on the path to level three. Note that these transformations are wrenching. It is not easy to tell the heroes that their greatest value to the organization is now how well they can write or teach. But with proper management attention, it can be done. And the benefits of moving forward are many: 

    • Dramatically fewer crises. Staff could make plans and keep them – no emergencies interrupting a family gathering, a school event, or a get-together with friends. 
    • High quality code. Maintenance tasks became much simpler, and customers experienced improved reliability. The documentation was helpful, and troubleshooting became routine rather than overwhelming. 
    • Reliable planning. In a mature organization, plans hold true because they are based in proven metrics, continuously validated processes and uniformly high competence within the team. Project estimates are accurate because the data stems from reliable, repeatable evidence. 

    Cloud excellence is not a phantom or an unachievable goal. It is the result of clear thinking and sound documentation. Over time, practices improve, skills build. To quote Macklemore, “The greats weren’t great because at birth they could paint, the greats were great because they painted a lot.”  With practice and focus, your organization can achieve cloud excellence.

  • CNCF Advances OpenTelemetry Initiative

    CNCF Advances OpenTelemetry Initiative

    The Technical Oversight Committee (TOC) of the Cloud Native Computing Foundation (CNCF) has voted to accept OpenTelemetry as an incubating project as part of an ongoing effort to simplify instrumentation of software using open source agent software.

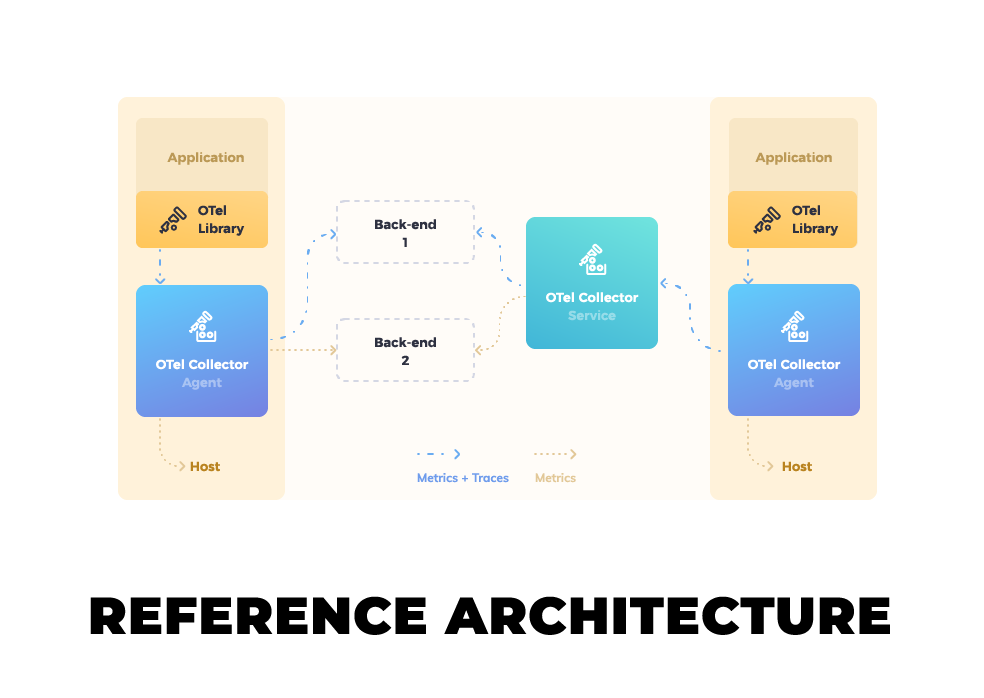
    OpenTelemetry is a collection of tools, application programming interfaces (APIs) and software development kits (SDKs) that can be employed to collect metrics, logs and traces that make it simpler to determine the root cause of an application issue.

    At its core, OpenTelemetry is based on an OpenTelemetry Protocol (OTLP) specification that describes the encoding, transport and delivery mechanism of telemetry data gathered from sources, intermediate nodes and backend platforms. An OpenTelemetry Collector provides a vendor-agnostic implementation for receiving, processing and exporting telemetry data. APIs and SDKs that make it possible to instrument applications are available for 11 different programming languages.

    Previously a sandbox-level project within the CNCF, the next step would be for OpenTelemetry to become a graduated level project alongside other open source offerings such as Kubernetes and Prometheus, a platform used to monitor IT environments.

    The OpenTelemetry project was created via the merger of the OpenCensus and OpenTracing projects in May 2019. Since then more than 500 developers from 220 companies, including Amazon, Dynatrace, Google, Honeycomb, Lightstep, Microsoft, Splunk and Uber have contributed to the project.

    Most providers of observability platforms have at least signaled their intent to support OpenTelemetry as an alternative to proprietary agent software they had previously created to collect metrics, logs and traces.

    Ben Sigelman, one of the co-creators of both OpenTracing and OpenTelemetry and CEO of Lightstep, said different elements of the OpenTelemetry project are at varying stages of maturity. As such, support for the elements of the project are being added to platforms depending on the degree to which a vendor has confidence in, for example, the ability of OpenTelemetry agent software to collect logs.

    Liz Fong-Jones, principal developer advocate for Honeycomb.io, a provider of an observability platform, said that, in time, most observability platforms will support all the elements of the OpenTelemetry initiative to reduce their own engineering and support costs. In time, those savings will be passed on to organizations that will be able to instrument applications more affordably, she noted.

    It may take a while longer for OpenTelemetry to be widely employed, but the faster organizations transition to microservices-based applications the more pressing the need for open source telemetry software becomes. The dependencies that exist between all the microservices that make up multiple applications will be unmanageable without some form of telemetry. The challenge organizations face is finding an affordable way to instrument all those microservices.

    Of course, organizations have been instrumenting applications for decades. However, the time, effort and cost associated with instrumentation have tended to limit its use to only an organization’s most mission-critical applications. The issue now is that not only do microservices-based applications require instrumentation to manage them but in the age of digital transformation the percentage of applications deemed mission-critical is also steadily rising.

  • Popular iOS Apps Request Excessive User Data Permissions

    Popular iOS Apps Request Excessive User Data Permissions

    Most apps require some sort of user data to function properly. Google Maps needs location data to offer routing services. Twitter needs photo library access to upload a photo, and so on. Many users are quick to allow access to personal information without hesitation. However, in recent years, it’s become apparent that many apps are collecting (and leaking) an excessive amount of personal data, resulting in serious privacy issues. This has led Apple to give user privacy a heightened focus in recent iOS updates and marketing campaigns.

    Often, user data is being collected in the background for legitimate use cases, such as tailoring personalized user experiences and refining app performance. But, many apps are also monetizing user data by reselling it to third-party advertising data brokers without explicit user consent. More seriously, recent studies show that commercially available “anonymous” data can be de-anonymized. If location data is exposed, it could put at-risk people in actual danger. These are nuanced privacy violations that U.S. regulators have yet to respond to and address.

    To shed light on the data that apps are collecting, a recent study conducted by Jamf analyzed the iOS permissions requested by nearly 100,000 popular apps on the App Store. The study found the four most-requested mobile app permissions to be photo roll, camera, location data and microphone. The findings also revealed that popular apps are consistently requesting access to data that does not serve the application’s core purpose.

    Users should consciously be aware of the data they allow apps to access. Yet, the onus is also on business leaders and app developers to limit unnecessary data collection and reduce the potential for data overexposure. In the wrong hands, access to device hardware, such as a microphone or camera, could be used to steal sensitive material. And, if leaked, personally identifiable information (PII) exploits could be disastrous to the business.

    Below, I’ll review the key takeaways from the Jamf study and consider if the constant barrage of permissions requests is exacerbating privacy issues during the application development process.

    Four Most-Requested App Permissions

    The Jamf research found the top four types of app permissions were photo library access, camera access, location data and microphone access. In addition, other popular areas included calendar information, contacts and Bluetooth. Less-requested app permissions included voice processing, health data and local network access. The study arranged apps by their App Store categories, such as business, education, entertainment, news, shopping, travel and other areas.

    user data permissions

    1. Photos

    By far, the most requested data access type is photos. At least half of apps across all categories request access to user photo libraries. Naturally, this request is most common among photo and video apps such as YouTube, FaceApp or Splice; 96% of such apps request access to photos. This is followed by 87% of shopping apps (Amazon, Shop, eBay, etc.), and 84% of social networking apps (Facebook, Instagram, Twitter, etc.).

    At issue here is that the level of intended photo library access can be highly variable. For example, granting access to an entire camera roll along with decades of old personal photos just to upload one picture grants a rather invasive privilege. This has led Apple to enhance privacy controls—users can now choose to allow access to select images only or their entire roll.

    With these new constraints in mind, app developers should take steps to respect user privacy. Be aware of potential photo limitations and design apps to only collect necessary photos for the task at hand.

    2. Camera

    The next-most requested permission is for camera access. This is most common among photo and video apps, among which 90% request camera access. This is also common among shopping and social networking apps (83% each) and business apps (75%) like Zoom, Slack or WebEx. Similar to findings about photo library access, enabling camera access is ubiquitous. However, it is also one of the most dangerous permissions to grant indefinitely. If a bad actor obtained account access, this vulnerability could enable them to spy on users.

    Again, developers should consider introducing camera functions only when it’s essential for the task at hand. Obviously, it’s unethical to invoke camera access when users are unaware. Even camera-related bugs can have extreme repercussions. For example, a 2020 lawsuit against Instagram argued the app was spying on users. Due to its threat potential, high-security facilities have disabled camera hardware entirely.

    3. Location

    Location tracking is another permission that can be very useful but is, at times, overprescribed in modern app development. Location data includes cellular, Wi-Fi, GPS and Bluetooth data used to determine a user’s approximate location. The categories that collect location data most often include shopping and food and drink, both at 81%. Social networking and photo and video app categories follow at 72% and 68%, respectively.

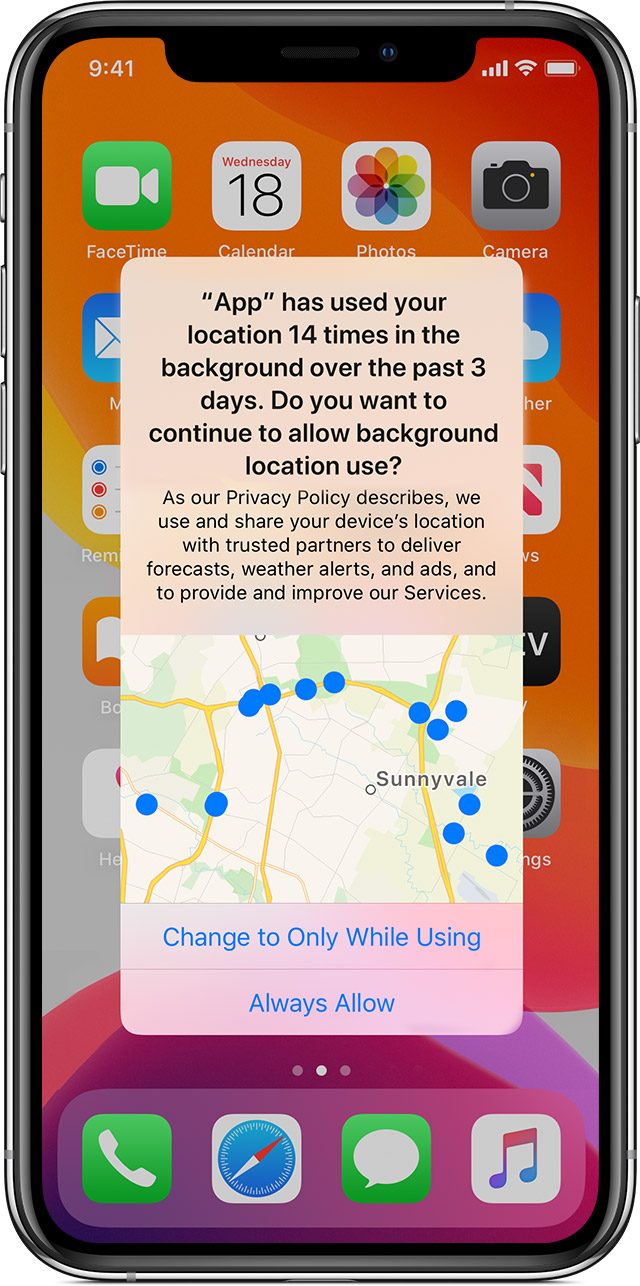
    Nowadays, iOS privacy settings offer a check against tracking location data in the background. iOS users can now choose between: ‘Allow While Using App’, ‘Allow Once’ or ‘Don’t Allow’.

    user data

    When an app tracks data in the background, a blue indicator now displays in the status bar to increase user awareness. iOS also reminds users when apps use significant amounts of location data and offers ways to turn location services completely off. Android has followed suit with an ‘Allow only when the app is in use’ function, too.
    user data

    Location tracking feels a bit creepy. In the wrong hands, it could easily be leveraged for nefarious purposes. Out of all the permission-granting options, location data presents much more of a physical safety concern for the end user. From the user’s standpoint, they should only enable access to location tracking while using an app. From a developer’s standpoint, they should be extremely careful when collecting and storing such PII to ensure regulations aren’t broken.

    4. Microphone

    Lastly, access to the user’s microphone is the fourth most commonly requested permission. The survey found 69% of social networking apps, 64% of photo and video apps and 41% of both business and productivity apps (Asana, Google Calendar, TimeTree, etc.) all want to be handed the mic.

    Here, potential privacy concerns are similar to those involving camera access. Bad actors could potentially activate the mic to listen to private conversations, record ambient noise and sell findings to advertising brokers. To increase user awareness, iOS 14 now requires an orange dot to display, indicating when the mic is in use.

    Other User Privacy Concerns

    User behavior tracking and app-to-app information exchange is another ongoing area of privacy concern. Companies often resell such information to data brokers, which is then used to refine highly targeted ad campaigns on third-party sites. This is how your search on Google results in product advertisements popping up in your Instagram feed. Apple is just starting to counter this practice with their App Tracking Transparency feature. In iOS 14.5, app devs must ask whether they can track your activity.

    Recent analysis has confirmed that commercially available consumer data, though labeled as “anonymized,” can successfully be used to piece together an accurate picture of a user by corroborating behavior on other apps. For example, users were able to track and pinpoint behavior that resulted in the outing of a catholic priest on Grindr. Smartphone app data could similarly be used by predators to spy on celebrities or politicians, posing a tangible security threat.

    Another cause for concern is metadata associated with photos. People often enable GPS-embedding into images to help organize their photo memories. If this is inexorably linked to photos, it essentially permits location data sharing to parties with photo library access who might not otherwise have location tracking permissions.

    From Big Data to Big Problem

    Perhaps the most curious finding of this report is that all apps are requesting permissions that seem irrelevant to their core value proposition. For example, why do 87% of shopping apps need access to a user’s entire photo library? Do 46% of food and drink apps really need access to a user’s personal contacts to place a food delivery order? Do navigation apps really need your personal calendar information to calculate a route downtown?

    The answer is not a pretty one. There has been a business imperative, for years, to track and collect large amounts of user data. There is undoubtedly an argument to be made for enhancing the user experience with innovative features and the role of big data in AI. However, this ongoing practice continues to creep into ethical gray areas. The fact is, the more personal data an app collects, the more potential privacy issues and security threat vectors are created in the process.

    Requesting permissions to on-device hardware and data collection is not always necessary. Thus, to stay safe and limit data overexposure, don’t overprescribe data collection. If it’s not fundamental to your app’s core function, don’t collect it, and don’t store it. Think twice before requiring many device permissions, and regularly audit app permissions requests to keep them to a minimum. As iOS and Android introduce new platform guidelines to elevate user privacy, developers should be prepared for users to grant fewer and fewer data collecting permissions. This is their right.

    It would be great if tech companies invested in honest, ethical business models that didn’t rely on harvesting and reselling user data to shady advertisers. And for those that mine user data but say it’s anonymous, I would point to reports that show anonymous data is nothing but pure myth.

  • How DevOps Can Address CX Challenges

    How DevOps Can Address CX Challenges

    Delivering a seamless customer experience (CX) has become a top priority for companies undergoing digital transformation initiatives, as 85% of buyers are willing to pay more for a great customer experience. However, customers aren’t only willing to pay more for a positive experience–they’ll go elsewhere if their experience isn’t positive. In fact, 33% of customers will leave a brand they previously loved after just one bad experience, and 92% of customers will completely abandon a company after just two or three negative experiences. So, delivering a positive CX has become a major priority for companies that want to retain their current customers while winning over new prospects from competitors.

    To assure CX quality for customer-serving technology products and services, established DevOps processes and strategies should be applied to the unique aspects of customer experience software. DevOps for CX enables the delivery of software where the customer’s experience is paramount and quality is imperative. However, there are six major pitfalls in deploying DevOps for CX that customer-serving organizations must overcome.

    What is DevOps for CX?

    To understand the challenges, we must first understand the purpose of DevOps for CX.

    DevOps for CX refocuses the DevOps software methodology on the unique aspects of CX software to enable greater efficiency and quality. The constant delivery of expanded CX capabilities through new software developments and features has become a priority in organizations undergoing digital transformation. But when it comes to software products for CX and customer services, quality cannot be sacrificed for speedy development. At the same time, companies must still meet the demand for rapid innovations and tight deadlines on software delivery.

    Customers have higher expectations than ever before. These days, there aren’t any second chances when it comes to a customer’s experience. Social media has empowered customers to broadcast CX failures for the whole world to see. Due to the visibility of CX mishaps and negative customer interactions, a brand’s CX reputation depends on flawless execution from the customer’s first impression.

    The customer is always right; so, the customer’s perspective must be the primary consideration in software development and testing. This puts significant demand on the DevOps solutions and processes specific to user experience (UX) design, as well as CX testing and monitoring. Software must be designed, developed and continuously tested and monitored in real-time. Companies need to know all the different ways a customer might use the software to accomplish their goals and quickly identify and fix any potential issues before the customer experiences them.

    6 Potential Pitfalls of DevOps for CX

    Underinvestment in Executive Sponsorship and Cultural Evolution

    For CX transformation initiatives to succeed, they must be empowered by an executive leader who can champion the need to drive cultural change and strategic investments. An executive leader is necessary because CX initiatives typically span multiple departments: Operations, development, marketing, sales and services, for example.

    Whether the leader taking on this responsibility is an existing executive or a brand new position will depend on the company’s organizational structure. Some companies assign this duty to the COO, CIO or CMO, while others create an entirely new chief CX officer role so that the leader can give their full attention to the CX transformation initiatives at hand. Regardless of the DevOps for CX champion’s title, they must have a broad authority over budget, people and processes to make their role effective.

    Competing and Misaligned Incentives

    DevOps is a multi-team effort. Ensuring that the teams’ objectives and incentives are aligned is key to ensuring that DevOps for CX projects are executed harmoniously. Each team should have objectives that fit their team function but do not oppose other teams’ objectives, such as speed or a low defect rate on the development side and high reliability for the operations side. These functional team objectives should be centered around respective business objectives for customer satisfaction.

    Unclear Key Performance Indicators (KPIs)

    Adopting DevOps forces organizations to take on a more collaborative mindset. Due to the multi-team, collaborative nature of DevOps for CX initiatives, it’s critical that KPIs are clearly communicated, widely understood, and monitored across teams. KPIs should also be widely distributed so CX can be viewed at an operational level.

    Lack of DevSecOps Prioritization

    Many organizations fail to recognize the importance of DevSecOps from different aspects of DevOps. Not only must customer data be protected, but larger organizations that operate globally must also ensure they are complying with regional data privacy regulations. Organizations that don’t comply with regulatory requirements risk fines and other punitive setbacks.

    You must be able to test security features in production to protect both customers and your organization itself. Unfortunately, security is too often one of the last DevOps aspects to be discussed.

    Different Configurations Across CX Delivery Environments

    Shifting between development, quality assurance, staging and production is a major source of frustration for DevOps teams, as the environments are often configured differently. As code moves through the software life cycle and different environments, having a consistent approach to the solutions and environments via deployment automation will prevent wasted time fixing bugs that suddenly pop up when the code is moved.

    Errors Introduced by Manual or Outdated Processes

    Manual processes introduce opportunities for human error, causing delays and defects that result in unplanned work. Performing software testing manually is a sluggish process that not only causes quality issues and delivery delays but also reduces the amount of time developers have to execute any unplanned work or rework that must be done post-testing. Automating the CX systems’ testing results in higher quality and reliability at faster speeds, providing more time post-testing for developers to ensure the product meets quality requirements.

    DevOps for CX enables companies to innovate CX rapidly by delivering high-quality software and maintaining exceptional customer interactions. As CX leaders innovate new products and services through software, DevOps for CX practices will continue to be honed over the coming years. In the meantime, following the best practices outlined here to avoid the six major pitfalls of DevOps for CX will ensure customer experiences are maintained at an elevated level.

  • Infrastructure-as-Code Security will Improve Your Cloud Security

    Infrastructure-as-Code Security will Improve Your Cloud Security

    Moving to the cloud creates a tremendous opportunity to get security right and reduce the risk of a data breach. Most organizations start their cloud security efforts by ‘shifting security left’ thereby addressing issues in the CI/CD pipeline. Fixing known vulnerabilities and risky configurations before pushing images to production makes sense. But there is an opportunity to shift security even further left—as you set up your cloud infrastructure—to reduce risk. Infrastructure-as-code (IaC) security allows you to define security controls as you configure your cloud infrastructure.

    Getting Started on Your Cloud Journey

    Before we dive into IaC security, let’s talk about why platform teams want to deploy infrastructure-as-code as they move through their cloud journey. Most organizations have not yet tackled IaC. They start their journey by experimenting with cloud configurations until they have defined a stack that works for their teams. In this early stage, application teams may be defining their own cloud stacks. They are manually configuring infrastructure or using scripts. Configurations may not be standardized across teams.

    Standardization of Infrastructure Saves Time

    Although experimentation is reasonable early on in the journey, standardization of infrastructure saves time. Cloud services are no different than applications that run on premises. When your teams are using different versions of tools in their stack, getting an application up and running can be a nightmare. Interoperability between services is challenging, and it can feel like you are fixing a different flavor of the same problem over and over.

    Mature cloud platform teams typically prefer to create a ‘golden image’ with a baseline set of services for development teams. They may create a menu of a few standard options to meet different teams’ needs. Because they are standardized, the platform team can take time to validate that they interoperate and are secure. For example, these golden images will be regularly scanned for vulnerabilities and updated to ensure they meet internal security standards and any relevant regulatory requirements.

    IaC security cloud

    Automating Infrastructure Deployment Reduces Errors

    Manually configuring the environment in the cloud for each team is tedious. Once these configurations have been standardized, the cloud infrastructure can be provisioned as code using templates. A declarative approach defines the desired end state, whereas an imperative approach defines the detailed steps to achieve the end state. The templates are normally stored in a Git repository and version controlled. Automating the configuration of infrastructure not only saves time but also reduces errors that can disrupt operations.

    IaC Security Shifts Security Further Left

    Once you have templates that define your infrastructure, standardizing permissions and access rights for services-as-code is a logical next step. The security team typically defines the guardrails or policies for accessing cloud services. These policies can then be defined as code along with the infrastructure configurations. This IaC security is a further ‘shift left’, allowing security to be embedded into infrastructure, even before an application can be deployed. Implementing policy-as-code minimizes the opportunity for human error in configuring security services. By defining these policies and enforcement guidelines together, the DevOps and security teams can establish a trusted partnership.

    Although some organizations may start their journey by implementing IaC security, for most organizations it happens later in the cloud journey. The order is less important than ensuring you take a DevSecOps approach and embed security at each stage to manage risk. Be sure to address the following areas as part of your cloud and container security program:

    Continuously Check Cloud Permissions and Configurations

    Even if you have IaC templates, you need a program to regularly take inventory of all cloud assets and confirm permissions and configurations. The Center for Internet Security (CIS) benchmarks are commonly used to check passwords and access rights. Beyond enforcing these best practices for security on cloud services, continuously checking for changes to permissions and suspicious activity is critical. The cloud vendors capture logs across all of their services, and your security tool should continually monitor and alert using those logs.

    Scan Images for Vulnerabilities and Risky Configurations

    Scanning for vulnerabilities and ensuring configurations use best practices allows you to shift security left into the development pipeline. Scan everywhere you have images—including within registries, pipelines and also check for new vulnerabilities identified for images running in production. Be sure to scan hosts as well as containers. Defining scanning policies and enforcing through the development process creates guardrails for the development team and clarifies expectations. Most regulatory compliance standards have image scanning requirements as well.

    Detect Threats and Respond to Alerts

    Prevention is fundamental but must be supplemented with threat detection and response. Alerting on unexpected behavior can identify the presence of a threat. Initially, teams may use out-of-the-box detection rules as a way to get started and then customize rules over time. Checking configs against dockerfile best practices is a good way to get started. Overly permissive access rights for containers is common in Kubernetes environments and should be allowed only when required.

    As your team develops more expertise with containers and Kubernetes, you can also implement zero-trust network security policies to block unexpected communication between pods, services and applications.

    Some DevOps teams handle triage of alerts, as they can quickly determine if the issue is a configuration issue or an indicator of compromise. Teams often map detection rules to the MITRE ATT&CK framework, allowing their security teams to manage alerts consistently across their environment. For any team to effectively respond to a security alert, it is important to capture a detailed record of exactly what happened before, during and after that event. This visibility can be particularly challenging with containers but it is critical because containers have short lives. The 2021 Sysdig Container Security and Usage Report revealed that about half of containers live less than five minutes.

    Complying with Regulatory Standards

    Complying with regulatory standards can be painful. Some standards were written with cloud computing in mind, like NIST 800-53 and SOC2, and others were not. With those broader standards, it is important to understand the controls that are relevant to containers and the cloud.

    As you consider your compliance program, be proactive—don’t wait until you are ready to roll into production. Start early by engaging your compliance team and helping them get up to speed. Your role is to provide evidence of compliance to pass an audit at any time using the documentation from your security platform.

    Getting Cloud and Container Security Right

    The move to the cloud creates a tremendous opportunity to get security right and reduce risk. The fact that physical security and a chunk of operations are delegated to cloud vendors frees up security and development teams to focus on their more narrow scope within the shared security model. By taking a secure DevOps approach and inserting security into every stage of the application life cycle, your team can confidently and securely run cloud and containers.

  • Kentik Open Sources Five Projects to Advance Network Observability

    Kentik Open Sources Five Projects to Advance Network Observability

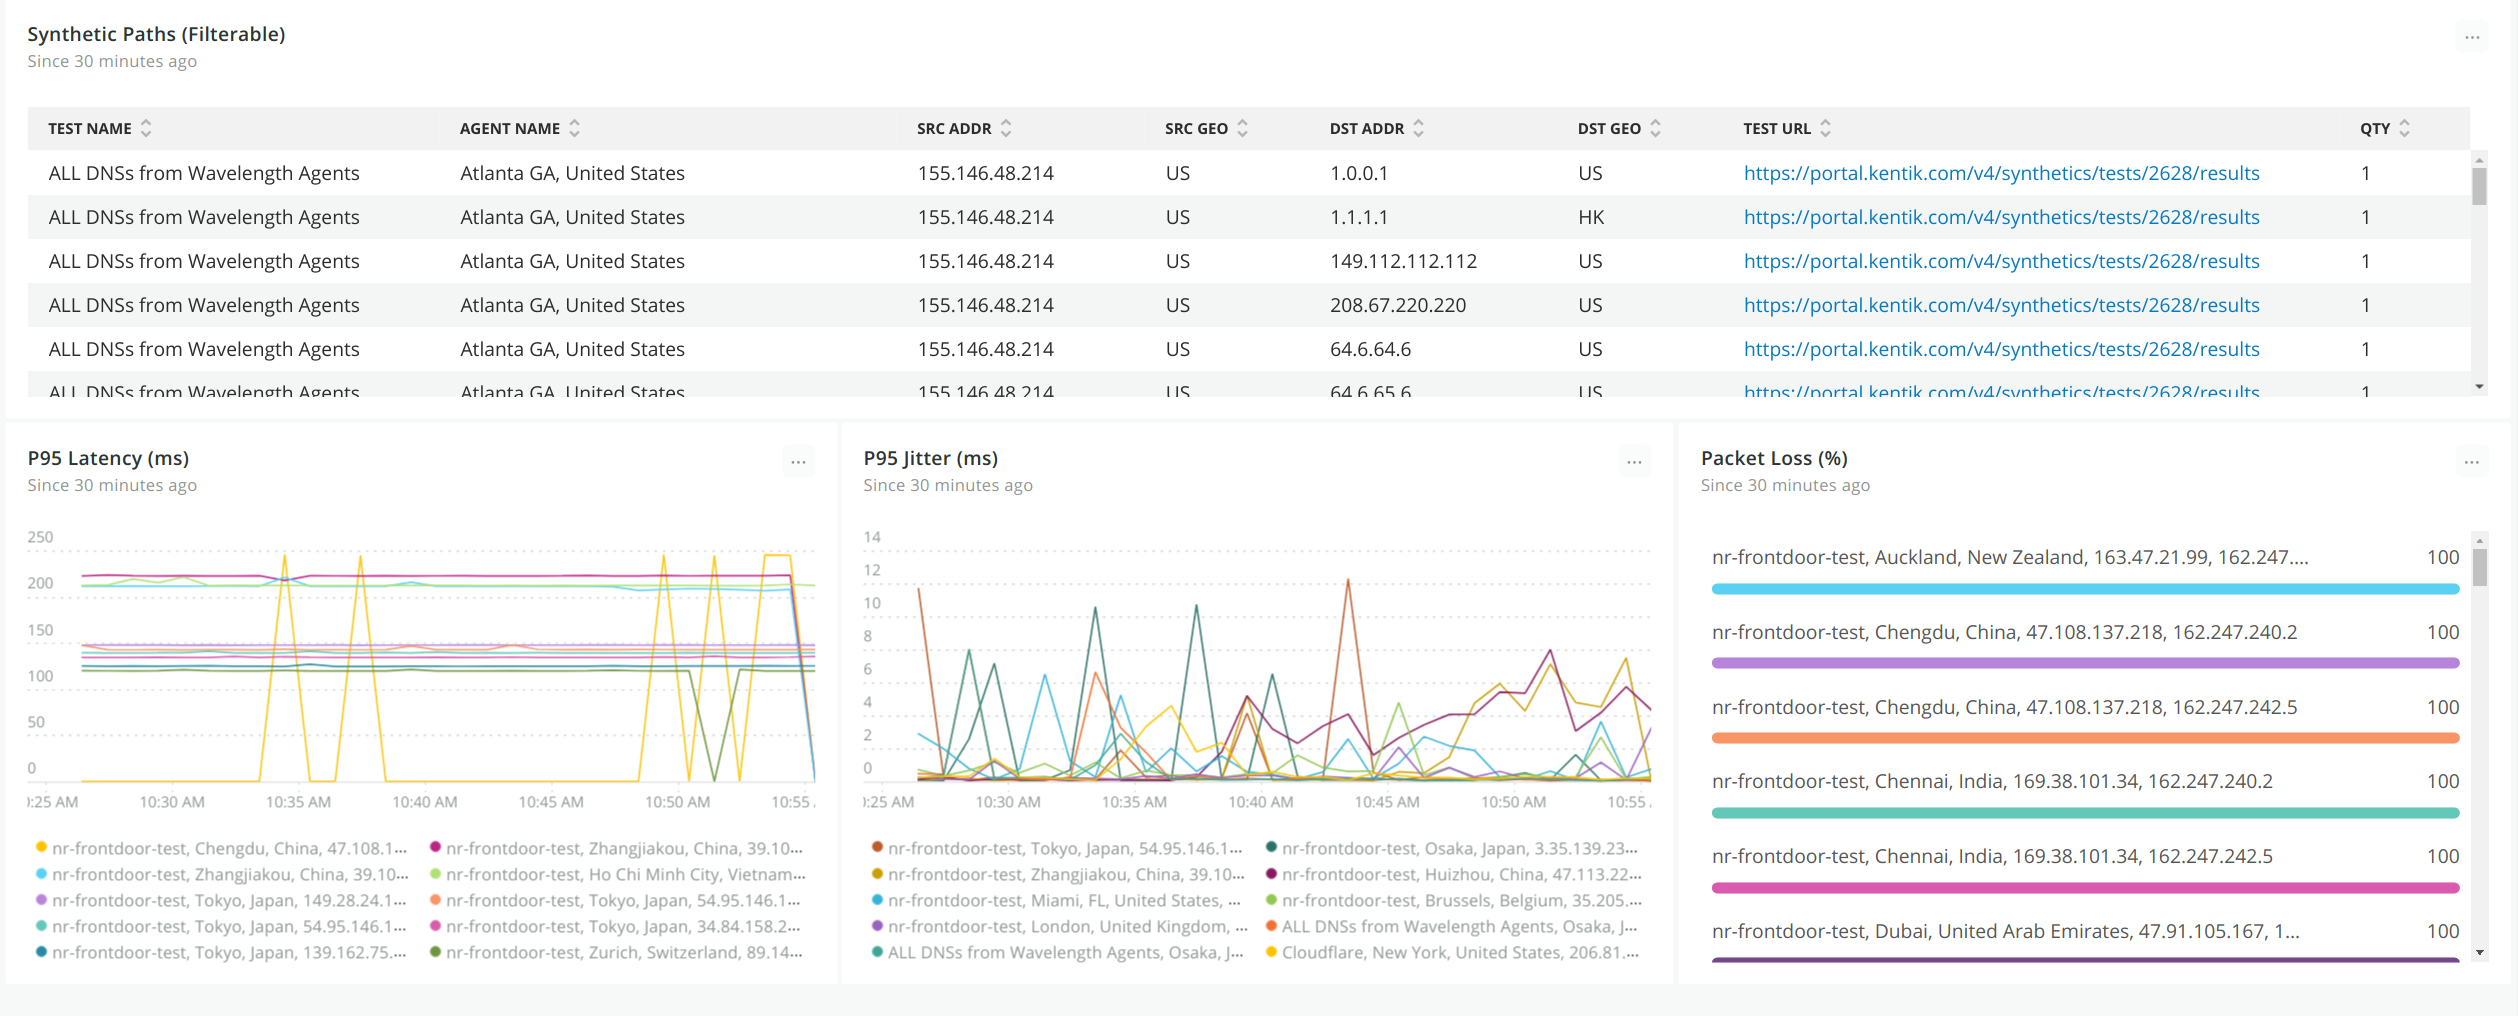
    Kentik today unfurled a developer hub, dubbed Kentik Labs, through which it is making five open source projects available as part of an effort to advance observability across network operations (NetOps).

    The five projects are:

    kTranslate: A system for pulling and pushing network data that is the basis of the Kentik Firehose integration the company created for the New Relic observability platform

    NetDiag: Scalable, asynchronous implementations of low-level network diagnostics

    Convis: Example code showing how to attribute process and container information to network traffic via the Linux kernel using eBPF

    kProbe: A high-performance host and sensor network probe (PCAP)

    Grafana App: A real-time tool for ingesting and querying network data

    Nick Stinemates, vice president of business development at Kentik and co-chair of Kentik Labs, said the goal is to enable DevOps teams to incorporate NetOps within the workflows already being employed to programmatically manage the rest of IT.

    Stinemates noted that, as IT environments become more distributed, managing NetOps has become more challenging. If there is a failure, it can be difficult for DevOps teams to determine if the issue is due to application code, the underlying infrastructure or some other root cause. Kentik Labs is committed to providing tools that will help DevOps teams reduce their mean time to recovery (MTTR), he added.

    Most NetOps teams increasingly rely on software to manage distributed networks either in the form of graphical tools provided by router and switch vendors or by using the Python programming language and the open source Ansible automation framework that enables IT teams to declaratively manage IT infrastructure.

    As the teams that manage network operations gain more proficiency with those tools, it becomes simpler to incorporate them within the construct of a larger DevOps team. While DevOps teams have been programmatically managing IT infrastructure-as-code (IaC) for years, network management has largely remained in a separate silo. However, as more applications are deployed in the cloud, it’s clear NetOps needs to become more integrated with the rest of the workflows employed to deploy and manage a highly distributed IT environment, said Stinemates.

    Less clear is to what degree the networks that make up a hybrid cloud computing environment will continue to be managed by network administrators versus site reliability engineers (SREs) that are starting to assume responsibility for managing compute and storage.

    Regardless of who manages the network, the next generation of microservices-based applications that are dependent on application programming interfaces (APIs) to call various services are much more latency-sensitive than previous generations of applications. Many of those applications will regularly experience performance issues due to networking issues that are often not readily apparent to DevOps teams. The goal should be to, at the very least, arm those DevOps teams with the tools required to confirm the source of those issues before a “war room” is convened to determine how to address the issue.

  • How CIOs Can Measure Digital Transformation ROI

    How CIOs Can Measure Digital Transformation ROI

    To fully grasp how to measure success and gauge progress toward goals in any digital transformation, it’s important to understand the shifting expectations of CIOs who must report these objectives and outcomes. The pandemic has substantially changed the role of the CIO, giving them heftier goals and a shift away from IT.

    Today’s CIO is no longer solely responsible for the IT department. Instead, the expectation is for them to have a greater influence in solving strategic business challenges. CIOs are now held to higher standards and have great responsibilities, with the assumption that they excel at communication and facilitation. Today’s CIO role also includes business planning and monitoring, transformational development, testing and security and compliance.

    Gartner states that, in a technology-driven workplace, 41% of tech producers are within other business units, not in IT. Solutions are being created from those in charge of the bottom line, who make organizational and business decisions. Further, the rise of low-code platforms has accelerated the shift from IT to the business. Finally, as Generation Z moves into the workforce, there will be a significant shift in what this workforce wants and needs to be their most productive and fulfilled. Typically, this generation of workers are masters of autonomy and they strive to impact everything they touch and have greater control over what they handle and take on.

    Within this shifting landscape, it can be difficult to understand how to measure and set goals.

    Acquire the Right Tools and Frameworks

    The first thing CIOs need to provide to this decentralized organization is the right tools and frameworks. These tools, such as value stream delivery platforms (inclusive of CI/CD, testing, artifact management, etc.) coupled with agile frameworks like SAFe provide a consistent method to deliver apps within the organization.

    CIOs need platforms that allow them to visualize, manage and monitor progress on an ongoing basis. While this was largely a manual process before, solutions have vastly improved and, luckily, we no longer need to sit in a room and manually whiteboard progress.

    Leverage Value Stream Management

    This is often new territory for CIOs and can be daunting. CIOs need to be able to protect the organization, facilitate the quality of its solutions and take accountability for the tools being used and sold to its customers. Fortunately, this new power and influence can be managed with value stream management. It is what allows CIOs to keep track and monitor the bottlenecks in the development process. Further, the CIO can provide collaboration tools to help connect users around common processes.

    Value stream management can be a powerful improvement tool for organizations. It can serve as a material and information flow map that helps workers and executives continually view their performance and improvements. “Value” emphasizes that the purpose of the work process can prove the value and worth to the customer, while the term “stream” means that the flow of this value is being measured throughout the process.

    Set Business Goals, Not Just IT Goals

    Digital transformation success for the CIO not only means that technology works, but that it works for the business. That means the goals CIOs set for technology need to meet whatever bottom-line goals are set for the business, too.

    Define KPI objectives that align specifically with the business’ goals and focus on relevant metrics that matter. There are a number of types of metrics that CIOs should consider, but each organization will have to choose which are most relevant to their unique business, industry and their business goals: User engagement, customer experience, reliability, availability, active usage (think: Conversion rates, repeat customers/users, daily active users) are all examples.

    When choosing your metrics, find those that you can accurately benchmark against past performance. A baseline will prove your worth; without it, it’s difficult to understand value gained. Ultimately, the CIO must ensure that these metrics are valuable to everyone, and stakeholder buy-in is critical. Finally, everyone in the organization needs to be on board with these goals and metrics.

  • 5 Ways to Embed Accessibility in Your SDLC

    5 Ways to Embed Accessibility in Your SDLC

    Developing an accessible software development life cycle (SDLC) requires a commitment to inclusion from everyone at the beginning of every project. By committing to developing accessible products, you will avoid costly and timely remediation prior to deployment at the end of your product roadmap.

    Creating An Accessible Software Development Life Cycle (SDLC)

    An accessible SDLC is one in which accessibility is integrated into every stage from planning through maintenance. This includes accessibility policy, automated testing against that policy, incorporation into your QA processes as well as verifying and documenting conformance requirements such as voluntary product accessibility template (VPAT) creation.

    Integrating accessibility isn’t really all that different from testing for any other quality standard, like cross-browser compatibility or other bugs. Here are the five key elements required to support your efforts:

    Policy – Start by establishing your accessibility goals, then prioritize based on importance (which is helpful for future sprint planning). Define these goals and priorities in your policies so that you can use them to measure your successes and understand where you need improvements.

    Automated and Manual Testing – Automated testing works by using software to scan your digital assets—whether in production, dev or staging—with an accessibility rules engine to check for errors. It can quickly and efficiently catch machine-detectable web content accessibility guidelines (WCAG) failures—the accessibility standard—that engineers can fix during the development process. Automated testing can be performed in many ways; however, the approach that will work best for you will depend on the level of integration that your DevOps team can facilitate. Manual assessments are far more comprehensive than automated scans. They also take essential user experiences into consideration, and they can catch errors far beyond what is machine-detectable today.

    Integrated User Story Development or Continuous Integration/ Continuous Deployment (CI/CD) – Once you’ve found the failures, what do you do with them? They should be treated like any other bug or glitch that prevents customers from accessing or using your website or application. You’ll want to capture this information in your ticket tracking system. Many organizations use agile sprints and project management software to create tickets, which are then fed into the development pipeline and prioritized, assigned and completed. Finding a solution that will let you easily convert WCAG failures into user stories (either manually or, better yet, through automation) is key for feeding a prioritized pipeline of work to be done.

    Knowledge and Resources – There are specific development techniques used to solve accessibility failures. Without access to a comprehensive library of accessible code techniques, developers will spend a lot of time scouring the web for solutions. Yes, you can find good solutions if you look long enough, but even so, how do you know whether that solution is legitimate or optimal for your case? Having the relevant solutions for an issue at your fingertips (negating the need to do a ton of online research) lets your DevOps team work more smoothly with fewer disruptions.

    Accountability – Accessibility analytics establish accountability. How effective are your DevOps teams at reducing WCAG failures? Tracking failures across your digital properties on a defined cadence lets you see and document trends over time. You can also track activities like the volume of tickets that are tagged as accessibility remediation or bugs, or new features or capabilities to represent active efforts.

    Whether you’re on a small or large development team at any size organization, adopting an accessible SDLC by implementing continuous accessibility checks at each phase of your development cycle is the most efficient and effective strategy to ensure that your website or applications are WCAG and ADA conformant.