Category: Application Performance Management/Monitoring

  • OpsRamp Extends AI Reach to Incident Management

    OpsRamp Extends AI Reach to Incident Management

    OpsRamp today extended its IT operations platform infused with machine learning algorithms, also known as AIOps, into the realm of incident management.

    The Summer 2021 release of the company’s namesake platform adds alert predictions for preventing outages and incidents, alert enrichment policies for faster incident troubleshooting and enhancements for automatically ingesting metrics data collected from the Alibaba Cloud environment and open source Prometheus monitoring software as well as Hitachi, Poly, VMware and Dell EMC platforms.

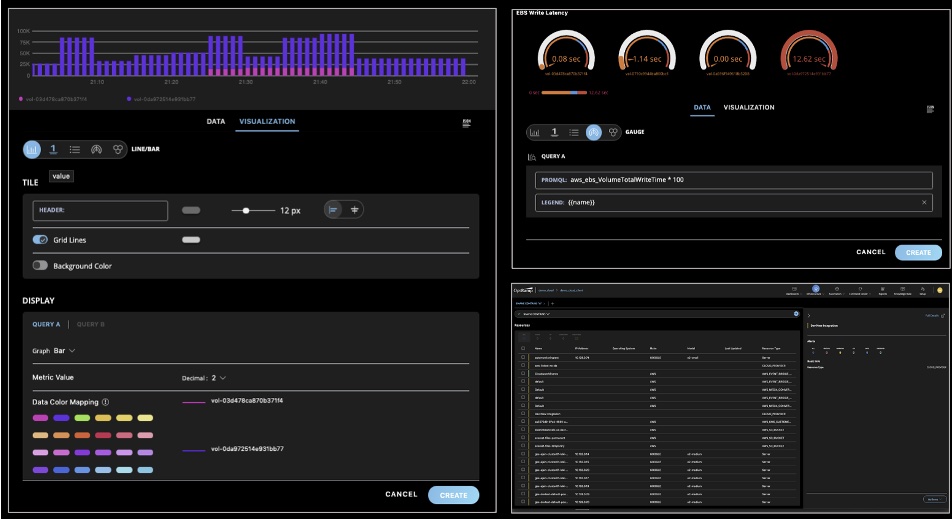
    IT operations teams can now also visualize metric values that can increase or decrease within a fixed range using Gauge charts. IT teams can also now add alert context details to provide more relevant information. There’s also now a mobile app for both Apple iOS and Google Android devices through which IT teams can now respond to alerts and incidents.

    Finally, OpsRamp is also making available a beta release of dynamic Workflows, which enable IT team to maintain a single decision table to address specific operational scenarios.

    Sheen Khoury, chief revenue officer at OpsRamp, said the goal is to leverage artificial intelligence (AI) to increase application availability by enabling IT teams to better predict when there are indicators of an incident caused by, for example, higher volumes of seasonal traffic that could lead to an outage.

    At the same time, IT operations teams can improve overall time-to-value by leveraging the automatic monitoring tools that are embedded in the platform, he added.

    OpsRamp is betting that rather than waiting for incumbent providers of IT operations platforms to add AI capabilities, many IT teams will opt to deploy a new IT management framework altogether. Many of the manual tasks IT operations teams regularly perform today can then be automated faster, noted Khoury.

    Naturally, it takes time for machine learning algorithms to be trained, so the benefits of AIOps are not instantaneous. However, those algorithms will continuously learn the unique attributes of an IT environment in a way that makes it easier for IT teams to manage an IT environment more proactively. The algorithms provide the added benefit of making it easier for new members to join an IT operations team without having to spend months learning all the nuances that are unique to that environment.

    Each IT team will need to decide for itself the degree to which they want to rely on an AIOps platform to manage their IT environment. Initially, most IT teams will need to evaluate the recommendations made by an AI platform. However, as they gain confidence in the recommendations, they will trust the platform to automate more processes in response to events occurring in the IT environment in real-time.

    Regardless of how much faith IT teams put in AI, it has become apparent that enterprise IT environments are only going to become more complex. Many IT teams will not be able to manage some environments without the aid of an AI platform. Many IT professionals may not want to work for organizations that don’t provide some way to augment their skills using AI—the stress level would simply be too high.

    One way or another, DevOps teams that are highly committed to ruthlessly applying automation will be at the forefront of AI adoption in the enterprise.

  • Sentry Integrates Code Observability Tool with GitHub, GitLab

    Sentry Integrates Code Observability Tool with GitHub, GitLab

    Sentry this week extended its namesake observability platform for code to provide tighter integration with the DevOps platforms provided by GitHub and GitLab.

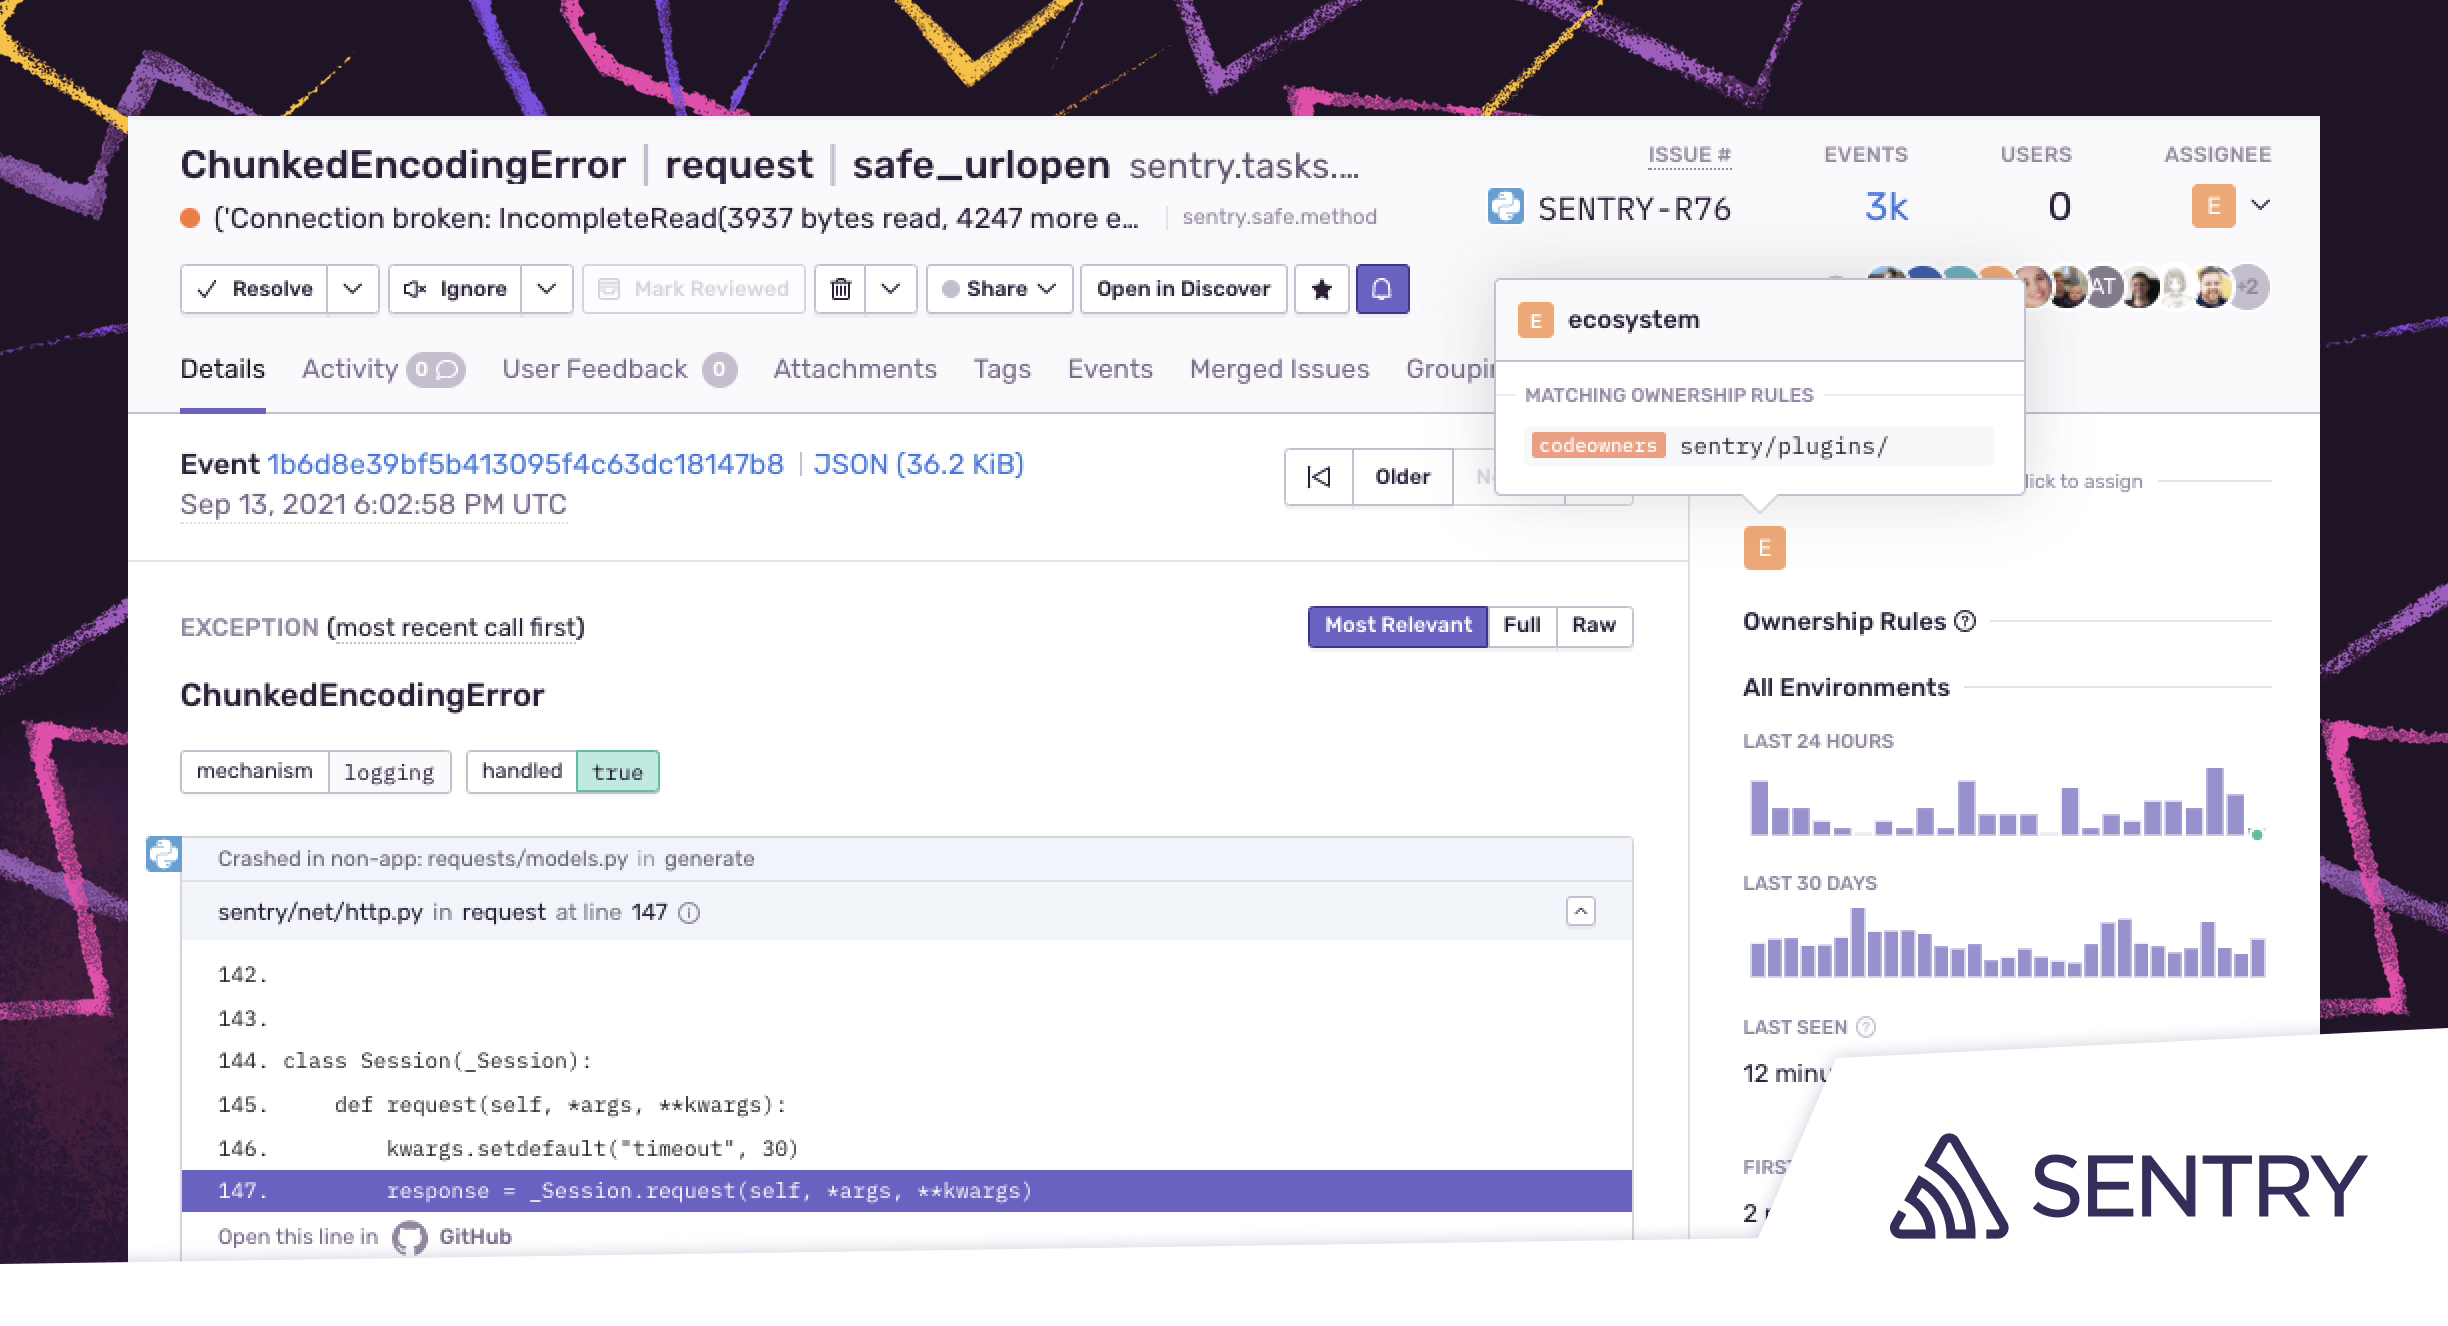
    Application development project managers can now assign issues to DevOps teams by integrating directly with the CODEOWNERS file in GitHub or GitLab. Error messages, for example, can now be automatically routed to individuals or teams that own the code via notifications in Slack.

    IT teams can now also identify and prioritize issues based on user impact by setting alerts based on when an issue exceeds a certain percentage of user sessions within a specific amount of time.

    Sentry CEO Milin Desai said that the percentage-based approach to alerts reduces the overall noise being generated in a way that enables DevOps teams to better prioritize their remediation efforts.

    Finally, Sentry has added an integration with the Okta identity management platform to make it possible to automatically provision and de-provision users and teams using the system for cross-domain identity management.

    As more responsibility for managing the application environment shifts left toward developers, there needs to be a way to streamline communications between developers and the rest of the IT operations team, noted Desai. Most developers today already spend less than one-third of their time writing code.

    The Sentry platform is already used by more than 75,000 organizations to enable developers to better observe and analyze code behavior. The company is now moving to bridge the divide between developers and site reliability engineers (SREs) by streamlining communications and workflows, noted Desai.

    As the responsibility for managing applications shifts left, developers don’t necessarily want to use the same tools that IT operations teams have relied on for years. Most developers want to be able to troubleshoot their applications with minimal interaction with IT operations teams.

    Historically, IT operations teams have relied on application performance management (APM) platforms to manage IT operations. Those platforms are now evolving into observability platforms that promise to provide more context by correlating events as they occur across both applications and IT infrastructure platforms. That approach, however, typically requires developers to insert agent software into their applications. Once inserted, that agent software needs to be maintained and updated, added Desai.

    The Sentry approach provides developers with a tool for collecting data from an application in a way that consumes just tens of kilobytes of memory after being embedded directly within an application. That approach eliminates the need to rely on much larger agent software to achieve observability of application code. Developers can then diagnose and possibly remediate issues in code without ever having to create a ticket asking a DevOps team to investigate an issue.

    Regardless of how developers go about instrumenting their applications, most everyone in IT agrees that the current state of observability needs to improve. The issue now is determining how best to achieve that goal in a way the benefits both the DevOps team and the developers that are now being asked to not just write code but also manage the entire application life cycle.

  • New Relic Survey Shows Greater Appreciation for Observability

    New Relic Survey Shows Greater Appreciation for Observability

    A global survey of 1,300 software engineers, developers, IT leaders and executives found half of respondents (50%) are in the process of implementing an observability platform. Another 23% of respondents said that they cannot gain end-to-end observability at all, while 26% said they believe they have mature observability practices in place. The survey, published today, was conducted by CITE Research on behalf of New Relic.

    The majority (94%) of IT professionals said observability is important for their job role, while nearly three-quarters (74%) said there is still room to grow their observability practice. In fact, 81% of the 450 C-suite executives that participated in the survey said they expect to increase observability budgets in the next year, with 20% expecting those budgets to increase significantly.

    Overall, the survey finds that lack of resources (38%), skills (29%), understanding of the benefits (27%) and strategy (26%) are top barriers to achieving observability.

    Observability, in one form or another, has always been a core tenet of DevOps best practices. Most DevOps teams have relied on monitoring tools to observe a specific process or function. The challenge is those monitoring tools track a pre-defined set of metrics such as resource utilization. Ideally, observability combines metrics, logs and traces—a specialized form of logging—to instrument applications in a way that makes it simpler to troubleshot issues without having to rely solely on a limited set of pre-defined metrics.

    Nearly three-quarters of respondents (72%) noted that IT teams today need to toggle between at least two different tools to manage IT, with 13% having to use more than ten different tools to monitor the health of their systems.

    In contrast, observability platforms make it possible to correlate events across both applications and infrastructure. This capability makes it easier for analytics tools to identify anomalous behavior indicative of the root cause of an IT issue. Armed with these insights, it becomes a lot simpler for IT teams to resolve issues faster.

    The New Relic survey notes that 60% of respondents still monitor telemetry data at the application level, which indicates that a massive amount of valuable telemetry data is largely going unused. A full 91% of IT professionals that responded to the survey noted that observability is critical at every stage of the software life cycle, especially when it comes to planning and IT operations.

    Top benefits cited include faster deployments (27%), more cost-effective use of IT resources (25%), better digital experiences (23%) and improved productivity (22%). The top use cases cited involved digital transformation initiatives (42%) followed by cloud optimization (37%), DevOps processes (36%) and bringing products to market faster (36%).

    Buddy Brewer, group vice president and general manager for New Relic, said observability will become a more pressing issue in IT environments, thanks to the rise of microservices-based applications running on Kubernetes. A full 88% of IT decision-makers New Relic surveyed said they are exploring Kubernetes and containers at some level right now, but only 10% said they have deployed them in a production environment. A total of 40% expect to be in production within three years.

    In general, it’s become critical for IT teams to be able to query data in real-time to resolve issues that are becoming more challenging to resolve at a time when organizations have never been more dependent on IT. Sampling data in the hopes of discovering issues is no longer sufficient, noted Brewer.

    The challenge, of course, is that most IT teams have been using legacy monitoring tools for so long that it’s still hard to imagine there might be a better approach. That doesn’t necessarily mean all those legacy tools will be immediately replaced, but it does mean many of them may simply fade away over time.

    One way or another, most IT teams will soon be able to observe IT environments more deeply. Developers increasingly are taking advantage of open source tools like OpenTelemetry to instrument applications in a way organizations can more easily afford, regardless of whether they fully appreciate the nuances of modern observability versus traditional monitoring.

  • Choosing the Right Metrics for DevOps Adoption

    Choosing the Right Metrics for DevOps Adoption

    DevOps adoption has skyrocketed in recent years. Its impact on traditional development platforms has long been well-documented, but in more recent years it has started to influence low-code platforms, too. In its recent survey on the state of Salesforce DevOps, Gearset found that 69% of teams are already using source control and another 20% plan to start this year. Additionally, 45% of companies have implemented CI/CD, and that number is set to increase by 33% this year. However, for high-performing developer teams to recognize the benefits of DevOps and strive for further DevOps adoption, they must use the right KPIs.

    While it can be tempting to take a ‘big bang’ approach to DevOps adoption, teams see more success when they take it one step at a time, with each stage building on the last.

    That said, to experience the full ROI of DevOps adoption, it’s still critical to see the journey through to the end. It’s not uncommon for teams who begin the process of DevOps adoption to stop halfway through or, worse still, lose motivation and halt the process entirely. DevOps adoption is a process full of technical and cultural change, and one of the most common causes of its failure is an emphasis on the technical at the expense of the cultural.

    The best way to tackle this is to encourage teams to take a product mindset and apply it to DevOps adoption. Simply put, rather than tasking your teams with “adopting CI” for instance, they should be asked to solve a specific business problem. For example, “When we finish work on a story, it takes weeks for it to get released!” It sounds obvious, but focusing teams around business impact rather than on individual tasks makes sure that there’s a direct correlation between the work that’s happening and the desired business outcome. This is the crux of adopting a DevOps mindset, rather than a purely technical and perfunctory approach to DevOps adoption.

    One of the key things a team can do to drive this type of change—and to avoid common causes of failure—is to use the right metrics at each stage of their DevOps journey.

    There are a number of well-recognized metrics for measuring DevOps success, including:

    • Deployment time
    • Change failure rate
    • Release cadence
    • Lead time
    • Recovery time

    These metrics serve two purposes. They’re well-documented and benchmarked indicators of performance that can help teams focus on their biggest problem areas. And they’re measurable outcomes that prove the business benefits of DevOps, such as agility, improved collaboration, higher quality systems and resilience, not to mention significant time and cost savings and efficiency.

    Choosing the Right Metrics

    Teams must choose the right metrics at the right time to identify their opportunities for improvement and to measure the impact of each stage of DevOps adoption. The right metric empowers a team to solve their most pressing challenges, and to demonstrate the value of their work to their leadership.

    Here’s how the benefits of each stage of DevOps maturity should be measured: 

    Stage of DevOps maturity

    Most relevant metric(s)

    Choosing your release tools

    Deployment time

    Adopting version control

    Change failure rate

    Recovery time

    Automating testing

    Change failure rate

    Automating deployments (CI/CD)

    Release cadence

    Lead time

    Integrating backup into DevOps tools and process

    Recovery time

    Let’s expand on each stage and the appropriate KPI.

    Choosing Your Release Tools

    This is more relevant to low-code platforms, but still broadly applies to the wider tech world. Even in the most mature of development processes, there will be manual steps. Getting changes into version control, reviewing changes, resolving conflicts, triggering releases—each of these is a manual step, and the effort involved in each of these manual steps is heavily dictated by the tools you use.

    Finding the right tool for each stage of your development and release process can therefore have a massive impact. The right deployment tool, for instance, can cut down deployment time by as much as 90%. This step alone increases efficiency and ultimately saves companies vast amounts of time and money. In extreme examples, teams that save so much time by picking up a couple of new tools to patch up their manual processes can be tempted to stop there. This is why teams need to look at other metrics as they proceed to adopt more DevOps processes.

    Adopting Version Control

    For most teams, a world without version control is unthinkable, having built their development and release processes around it a decade or more ago. For others, particularly in the low-code space where it’s yet to reach ubiquity, it can feel like an unnecessary burden. The introduction of version control is an extra step in the releases process and another level of complexity, with new tools and practices to learn. But version control is the foundation of an automated DevOps workflow. This step allows for more team collaboration and visibility into that collaboration, with code reviews and a detailed change history. Version control also allows teams to deal with merge conflicts early, rather than in the middle of a release. 

    After adopting version control, teams will see a reduction in their change failure rate due to code reviews and their recovery times will be shorter as version control offers rollback and a quasi-backup of the code and config captured by their version control system. But the real benefits of version control are in the DevOps processes it unlocks. 

    Automating Testing  

    It goes without saying that the purpose of testing is to improve the quality of releases. It does this in a few ways:

    • Unit testing – Exercising individual methods and functions in isolation generally results in more maintainable code, which has positive benefits for developer productivity and even things like handling merge conflicts.
    • Static code analysis – While this is not testing in the strictest sense, automatically verifying that code adheres to a set of best practices similarly improves code maintainability.
    • Integration testing – This type of testing ensures that combinations of classes interact and generate the expected results when combined together. This brings another level of validation that changes being made are likely correct.
    • End-to-end testing – UI testing is an example of this; exercising the system in the way a consumer would and verifying that the results are deterministic and correct. This also includes regression testing for key workflows and sometimes even acceptance testing.

    The more of these testing approaches a team uses, the more confidence they’ll have in their changes and the less human verification and intervention will be required. As teams’ DevOps processes mature, it’s often the human element that becomes the biggest bottleneck, so confidence in deploying changes is very valuable.

    When teams introduce more testing and test automation to their release pipeline, the right metric to watch is change failure rate—the proportion of releases that include a bug or error. The immediate benefit of higher-quality code translates to savings in the long term as less time is spent finding and fixing bugs or reworking code.

    Automating Deployments (CI/CD)

    If choosing the right deployment tool significantly reduces deployment times, automating deployments with a CI/CD workflow eliminates the time it would usually take to run those deployments manually. However, deployment times aren’t the key metric for measuring the success of CI/CD implementation. The most important metrics to pay attention to here are release cadence and lead times, which are dramatically improved thanks to painless, automated deployments. 

    With automated deployments, teams can increase their release cadence; rather than releasing huge batches of changes once a month, they might begin to release smaller packages every week. Ultimately, the goal is to have a steady stream of incremental improvements being released on-demand, and usually multiple times per day. Accelerated release cadences then result in reduced lead times—the period between work being finished and finally released to production. This is beneficial for developers and their end users as more frequent releases create more opportunities to act on user feedback earlier in the process. 

    Integrating Backup Into DevOps Tools and Process

    Recovery times are a key metric for DevOps success, as robust DevOps processes will improve the speed at which teams can restore after an incident. For even better resilience and faster recovery times, teams should integrate backup into their DevOps tools and processes.

    Restoring from a backup is comparable to a deployment, and this means that restore processes also can harness the power of DevOps so they feel like a familiar process—not something unusual that teams struggle to execute at the point when it matters most. It’s also important to make it as easy as possible to back up on demand just before a risky release.

    Downtime and data loss are massive costs to any business, so improving recovery times is a huge benefit of a fully mature DevOps process.

    See the Benefits of Maturing your DevOps Process

    When teams pay attention to the right metrics, they understand the benefit of each DevOps process individually and they are motivated to keep maturing their DevOps processes as a whole. It’s all well and good to take the pain out of deployments and releases, but high-performing DevOps teams effectively make deployments an asset for releasing more often and getting feedback earlier. As a result, they are better equipped to deliver more value to their companies—sooner.

  • JFrog Acquires Upswift to Push DevOps to the Edge

    JFrog Acquires Upswift to Push DevOps to the Edge

    JFrog today revealed it has acquired Upswift as part of an effort to extend its DevOps reach to edge computing platforms. Terms of the acquisition were not disclosed.

    Upswift has created agent software that is deployed as a binary file on an edge computing platform that makes it possible to continuously deliver software across a fleet of edge computing devices and platforms. That approach makes it possible for organizations to deploy software regardless of whether the target platform is only running Linux, containers or a virtual machine.

    JFrog CEO Shlomi Ben Haim said the agent software developed by Upswift will be integrated with the continuous integration/continuous delivery (CI/CD) platform created by JFrog to make it easier for organizations to manage the full life cycle of application workloads deployed on edge computing platforms.

    JFrog Upswift

    Organizations that deploy software on edge computing platforms and devices today typically have massive backlogs of updates that they are unable to deploy in a timely manner, said Ben Haim. By connecting the Upswift agent software to a (CI/CD) platform designed from the ground up to support binaries, it becomes possible to reduce that backlog as part of what JFrog describes as its ‘liquid vision’ for deploying software, he noted.

    In addition, after acquiring Vdoo to gain access to a set of analytics tools that discover vulnerabilities in application binaries, JFrog will also be able to bring DevSecOps best practices to edge computing applications as well, noted Ben Haim.

    The number of application workloads being deployed on edge computing platforms is rising sharply as organizations seek to process and analyze data closer to the point where it is being created and consumed. In fact, that shift is at the core of digital business transformation initiatives that depend on edge computing platforms and devices running, for example, internet of things (IoT) applications to process data in near-real-time.

    Upswift CEO Amit Ezer said it has already become apparent that the existing processes of updating software on edge computing platforms and devices are capable of handling that influx of software. Upswift created its tool to enable developers to assume more control over those processes, as responsibility for managing and securing software continues to shift left, he added. The issue in many cases is that organizations lack the ability to consistently deploy software on edge computing platforms, which results in a hodgepodge of homegrown tools being created to deploy software on edge computing platforms using largely manual processes.

    It’s too early to say just how much software will be deployed on the edge, but there may come a day when there is more software at the edge than there is in the cloud. Of course, the real challenge will be unifying the management of DevOps processes, regardless of where any given piece of software might be deployed. In fact, as edge computing continues to evolve, the line between edge computing and cloud computing will continue to blur until they are little more than natural extensions of each other.

  • 3 Pillars of Autonomous IT Ops

    3 Pillars of Autonomous IT Ops

    Imagine a future where human IT operators and intelligent systems work together in a virtual operations room; the systems do the heavy lifting while the humans supervise. This may seem like science fiction, but the truth is we are already on the way to that future with AIOps. While actual AI-augmented teams are still quite a way off, AI/ML tools are slowly but surely becoming more ubiquitous within IT Ops, NOC, DevOps and SRE teams and leading us into this not-too-distant future.

    In the last five years, the number of internet users grew by 50%. In the last two years alone, more data was generated than in the entirety of human history up to that point. Today, 5 quintillion (that’s 18 zeros) bytes of data are produced by smart devices daily. These massive volumes of data are having a huge impact on digital operations.

    Looking at the enterprise, we see similar trends: More tools generating more data and with it, greater complexity. This is due to many factors, including the transition to the cloud, M&A activity that introduces new tools and data into an existing organization and the adoption of new technologies and methodologies such as CI/CD, microservices and more. At some point, there is so much data and everything becomes so complex that IT Ops teams reach a breaking point where they can no longer manually manage the data being generated.

    And when that point is reached, outages and service disruption become an everyday reality, as IT teams are pulled away from their strategic, business-critical projects into what is essentially firefighting. 

    Implementing more observability and monitoring tools simply exacerbates the problem, and scaling teams isn’t cost-effective in the long term. The more forward-thinking solution is automation, and even more so, autonomy. 

    The Road to IT Ops Autonomy 

    Autonomy is the ability of IT Ops to operate with minimal to no human intervention. It relies on the automation of the incident management life cycle so that humans are needed only for supervision, in the same way that a single operator can supervise a modern and highly complex robotic car assembly line.

    How can we hope to reach IT Ops autonomy?  The following three proposed pillars can act as a guide: 

    Pillar One: Automate

    Pillar Two: Predict and prevent 

    Pillar Three: Democratize

     Pillar One: Automate

    We must automate as much as possible across every step in every aspect of incident management. It won’t happen overnight, but with time and with the help of AI/ML it is doable.

    Consider the autonomous driving analogy.

    Just a few years ago, cars were manual, with little to no automation. Then we moved through partial autonomy to where we are today–conditional autonomy–where the car can drive itself in ideal conditions. This is a level of automation that we are beginning to accept; some of us cautiously, others with more enthusiasm! Meanwhile, progress continues toward higher levels of autonomy, in which vehicles will be able to drive themselves in most conditions. One day, maybe, we’ll get to the holy grail of full autonomy, where the car will drive on its own–perhaps we won’t even need a steering wheel!


    Similarly, in IT Ops, automation is a process and it will take time to build not only the capabilities required but also the necessary trust in AI/ML technology. Such a journey typically begins with human-driven automation, as “if-then-else” types of automation are added manually. For example, if a certain alert appears, a ticket will automatically be assigned to a specific person. As our confidence grows, the next stage could be AI-driven suggestions, whereby AI applies what it has learned from previous human actions to suggest what to automate, but the human expert decides whether to accept the suggestion or not. 

    At some point, we will progress to allowing AI to partially automate some tasks—perhaps those that are less risky, such as collecting diagnostic information and adding it to the alert, so that the incident responder automatically receives both together. We may even automate some parts of our system; perhaps within a staging environment that isn’t production-critical and, as such, is a good place to validate that the automation is working as expected. Over time, as our AI and ML capabilities develop and our trust in them grows, we may eventually reach full AI-driven automation, with no human involvement at all—the AI will simply detect the fault and resolve it. 

    Pillar Two: Predict and Prevent 

    Typically, when assigned an incident, a responder will take note of the incident’s priority. But they will also rely on their common sense and past experience in deciding how to respond. So, for example, if a P3 incident had recently escalated to a P1 in 30 minutes and a similar P3 incident now appears again, our responder will probably prioritize it, even over other incidents, to avoid a similar escalation.

    While this is one of the advantages of human logic, the flip side is that the IT environments in which we work are vast and complex—no human can possibly remember every potentially relevant detail. What’s more, if a different responder dealt with the earlier incident in our example, the current responder would not have the same insight. What is needed is an element of enrichment that can input leading indicators into the platform for the next operator to see and act upon to prevent an incident.

    This is where AI can help. 

    By identifying patterns in the data haystack—linking different incidents to the same root cause, for example—AI not only generates insights that help resolve these incidents faster but can also predict a certain outcome. This is done by anticipating a future chain of events so that appropriate preventative action can be taken before the event occurs. For now, this preventative action may be manually taken by the operator, but at some point in the future automation may enable the problem to be identified and fixed by the AI with no human intervention before it results in an outage.

    Pillar Three: Democratize

    The last pillar that will help us achieve full autonomy in IT Ops is democratization of AI. AIOps should not just be accessible to advanced, mature organizations with an army of data scientists working behind the scenes. Just as anyone can accomplish almost anything online these days with just a few clicks, any organization should be able to adopt AIOps and enjoy its benefits! 

    Democratization is about making relevant information accessible to anyone who needs it, when they need it, and in a manner that is easily applicable and actionable. AI should be accessible through simple user interfaces, with no need for coding; the benefits of machine learning should be available to people that don’t (need to) understand machine learning models. 

    This democratization can be achieved by making AIOps platforms simple and accessible to all—from the admin to the user. For example, an AIOps platform might automatically suggest how admins should prioritize incidents for operators, to make triage easier and provide instructions that even a non-expert can follow. The more such features are built into AIOps platforms, the more democratized AIOps will become.

    Data volumes will continue to grow exponentially in the coming years, and the only way to eventually conquer the tyranny of overwhelming data will be to reach autonomy in IT Ops. 

    If you’re an AIOps vendor, keep the three pillars in mind so your customers can continue to progress towards autonomy.  If you’re an IT Ops leader or tooling architect, and IT Ops autonomy is part of your vision, make sure that your AIOps vendors’ platforms and tools have been architected with these pillars and their principles in mind. 

    How far are we from achieving autonomy? Only time will tell. But one thing is for sure—we will get there, and if the COVID-19 pandemic has taught us anything it’s that we may be seeing machine-augmented teams sooner rather than later. 

  • Google Donates Sqlcommenter to OpenTelemetry Project

    Google Donates Sqlcommenter to OpenTelemetry Project

    Google announced today that Sqlcommenter, an open source project that provides access to an object-relational mapping (ORM) auto-instrumentation library, is being merged with OpenTelemetry, an open source project for building agent software to instrument applications.

    Nimesh Bhagat, a product manager for Google, said Sqlcommenter is designed to make it simpler to correlate application and database telemetry. OpenTelemetry provides a mechanism for collecting logs, metrics and traces that is being advanced under the auspices of the Cloud Native Computing Foundation (CNCF).

    The challenge organizations using OpenTelemetry to collect that data will face is the need for tools to query that data in whatever platform it ultimately resides, noted Bhagat. OpenTelemetry previously lacked a common standard by which application tags and traces can be sent to databases and correlated with an application stack. Google envisions that IT teams will either employ Sqlcommenter to explore data or access via platforms such as Cloud SQL Insights or a third-party application performance management (APM) platform.

    Google made Sqlcommenter available as open source software earlier this year. It is designed to enable object–relational mappings (ORMs) to augment SQL statements before execution by, among other things, providing access to comments containing information about the application code that caused its execution.

    Sqlcommenter also allows OpenTelemetry trace context information to be propagated to the database, enabling correlation between application traces and database query plans that ultimately should make it easier to, for example, determine the root cause of a performance issue involving a microservices-based application making calls to a database. Sqlcommenter is primarily designed to be employed by full-stack developers that have some familiarity with how to use SQL to query data residing in an observability platform, noted Bhagat.

    Specifically, Sqlcommenter is designed to provide deeper insights into the performance of backend databases by simplifying the process of correlating slow queries with source code. It currently supports Python, Java, Node.js and Ruby languages along with ORMs such as Django, Sqlalchemy, Hibernate, Knex, Sequelize and Rails.

    As the number of applications that are instrumented using open source software continues to steadily increase, the amount of data that a DevOps team could potentially query also will steadily increase. Cloud storage platforms have made it easier to store that data at an affordable cost but the next challenge is clearly going to be finding a way to surface meaningful insights from all that data. Undoubtedly, achieving that goal will require everything from query tools to machine learning algorithms capable of identifying patterns at a level of scale that would not otherwise be possible.

    In the meantime, DevOps teams can look forward to being able to attain a level of observability that previously could only be achieved at a cost that tended to limit the number of applications organizations would instrument. At a time when the dependencies between applications increases with each passing day, that level of observability will soon prove indispensable.

  • 4 Ways to Simplify Cloud Performance Monitoring

    4 Ways to Simplify Cloud Performance Monitoring

    Over the past 18 months, technologists across the globe have played a crucial role in the survival of brands and organizations via digital strategies. Across all industries, their skill and dedication have enabled businesses to rapidly launch innovative new digital services to meet huge fluctuations in customer needs and allow entire workforces to operate from home during the pandemic.

    This hasn’t been easy, even as end users’ expectations for seamless digital experiences are on the rise. In fact, the recent 2021 App Attention Index reaffirmed found 76% of consumers’ expectations of digital services have increased in the last year. And an overwhelming 85% noted that applications and digital services have become a critical part of their daily lives. This has placed even greater pressure on the technologists who are responsible for keeping applications and cloud experiences running smoothly.

    Often IT teams are challenged with monitoring companies’ digital services, but they lack the visibility they need to monitor health and performance across an increasingly sprawling IT estate, exacerbated by a seismic shift toward cloud architectures over the last 18 months. IT departments don’t yet have the right tools and data to optimize health and performance in their cloud environments.

    As a result, technologists are constantly addressing the same issues because they can’t easily isolate and identify them, and don’t know where to prioritize their actions. Hiccups can lead to brands losing customers—the same report revealed that over half of consumers indicated that brands have one shot to impress them, and that if their digital service does not perform, they won’t use them again.

    After a year and a half since the start of the pandemic and with adoption of cloud technologies set to accelerate even further over the next few years, it’s time for technologists to get ahead. Here are four things technologists can do to take the stress out of managing performance across the cloud.

    Implement Visibility from the Ground Up

    Having visibility into applications and the underlying cloud infrastructures that support them can be challenging without the right tools, which has contributed to some of the pressure technologists are experiencing. Traditional monitoring has allowed technologists to identify and catch issues in certain areas of an IT stack, but this approach is of little use in dynamic, distributed and software-defined environments where organizations are continually scaling their use of IT and the cloud up and down.

    As a result, the performance of the digital services can be impacted, potentially hurting end-user experience and eroding trust in the brand.

    To keep up with the rising demands from consumers in the digital world, technologists need the ability to monitor the full IT estate, from cloud infrastructures to customer-facing applications through to core infrastructure such as compute, storage and network; including the open web and security. With access to tools like observability platforms, technologists can lessen the burden of individually monitoring the performance of each item supporting the digital service. Instead, they can achieve one holistic view into alerting, root cause and analysis of correlated metrics, events, logging and tracing (MELT) data from the cloud to enable early and easy troubleshooting.

    Consider tools that link infrastructure (compute, storage and network) with the services and applications they execute. When there is an application-level issue, it is easy to take a closer look and identify problematic areas in what makes the application run or the application itself.

    Align IT Performance to Business Results

    After aggregating a full-stack view of applications and the cloud infrastructure behind them, technologists can then link performance data identified by the observability platform with real-time business metrics.

    Linking the two provides technologists with the ability to identify where and how the digital services are impacting the business and end-users. Full-stack observability automatically provides technologists with these linked insights, enabling them to address the areas that matter most.

    Educate Teams

    In addition to having the right tools to help take advantage of the cloud, it is important that an IT team is well-versed in the technology itself. Managing the performance of the cloud is complicated and there is a finite pool of talent available to businesses. Therefore, business leaders should provide appropriate resources to ensure teams are educated and equipped to succeed.

    To support a seamless implementation of cloud infrastructure to support a business’ digital services, business leaders must invest in upskilling their teams or recruit others who are knowledgeable about cloud monitoring.

    This will ease the pressure on existing teams and give technologists the skills and confidence to progress in their careers.

    Leverage Automation

    Even with the best observability solutions in place and teams equipped with the necessary skills, there is still concern that there will be an overwhelming amount of data generated by accelerated digital transformation over the coming years, especially those involved in large-scale public cloud environments. It can become a challenge for technologists to dedicate the level of resources and skills required to manage and optimize performance across the IT estate.

    To avoid these potential circumstances in the future, it’s worth considering how to minimize the impact of a data deluge by reducing an IT department’s reliance on manual interventions to monitor health and performance and resolve issues.

    Two things that will play an increasingly vital role in tracking health and performance across the entire IT estate are automation and AI. This is particularly the case in large-scale public cloud environments, which are fast becoming the biggest headache for some IT teams.

    With AI deployment to identify and fix issues in real-time, technologists can spend less time firefighting thanks to the AI/ML guiding hand. This will lead to increased job satisfaction and fulfillment and a better work-life balance.

  • Progress Expands Chef Automation Portfolio

    Progress Expands Chef Automation Portfolio

    In advance of its ChefCon 2021 conference, Progress today unveiled a series of enhancements to its Progress Chef automation platform that includes managed services and a software-as-a-service (SaaS) edition of its offerings as well as tighter integration with cloud services and other third-party tools.

    Sudhir Reddy, vice president of engineering for the Chef business at Progress, said the SaaS platform, now available in beta, combined with the managed services provided by Progress will make the automation platform much more accessible to a wider range of organizations.

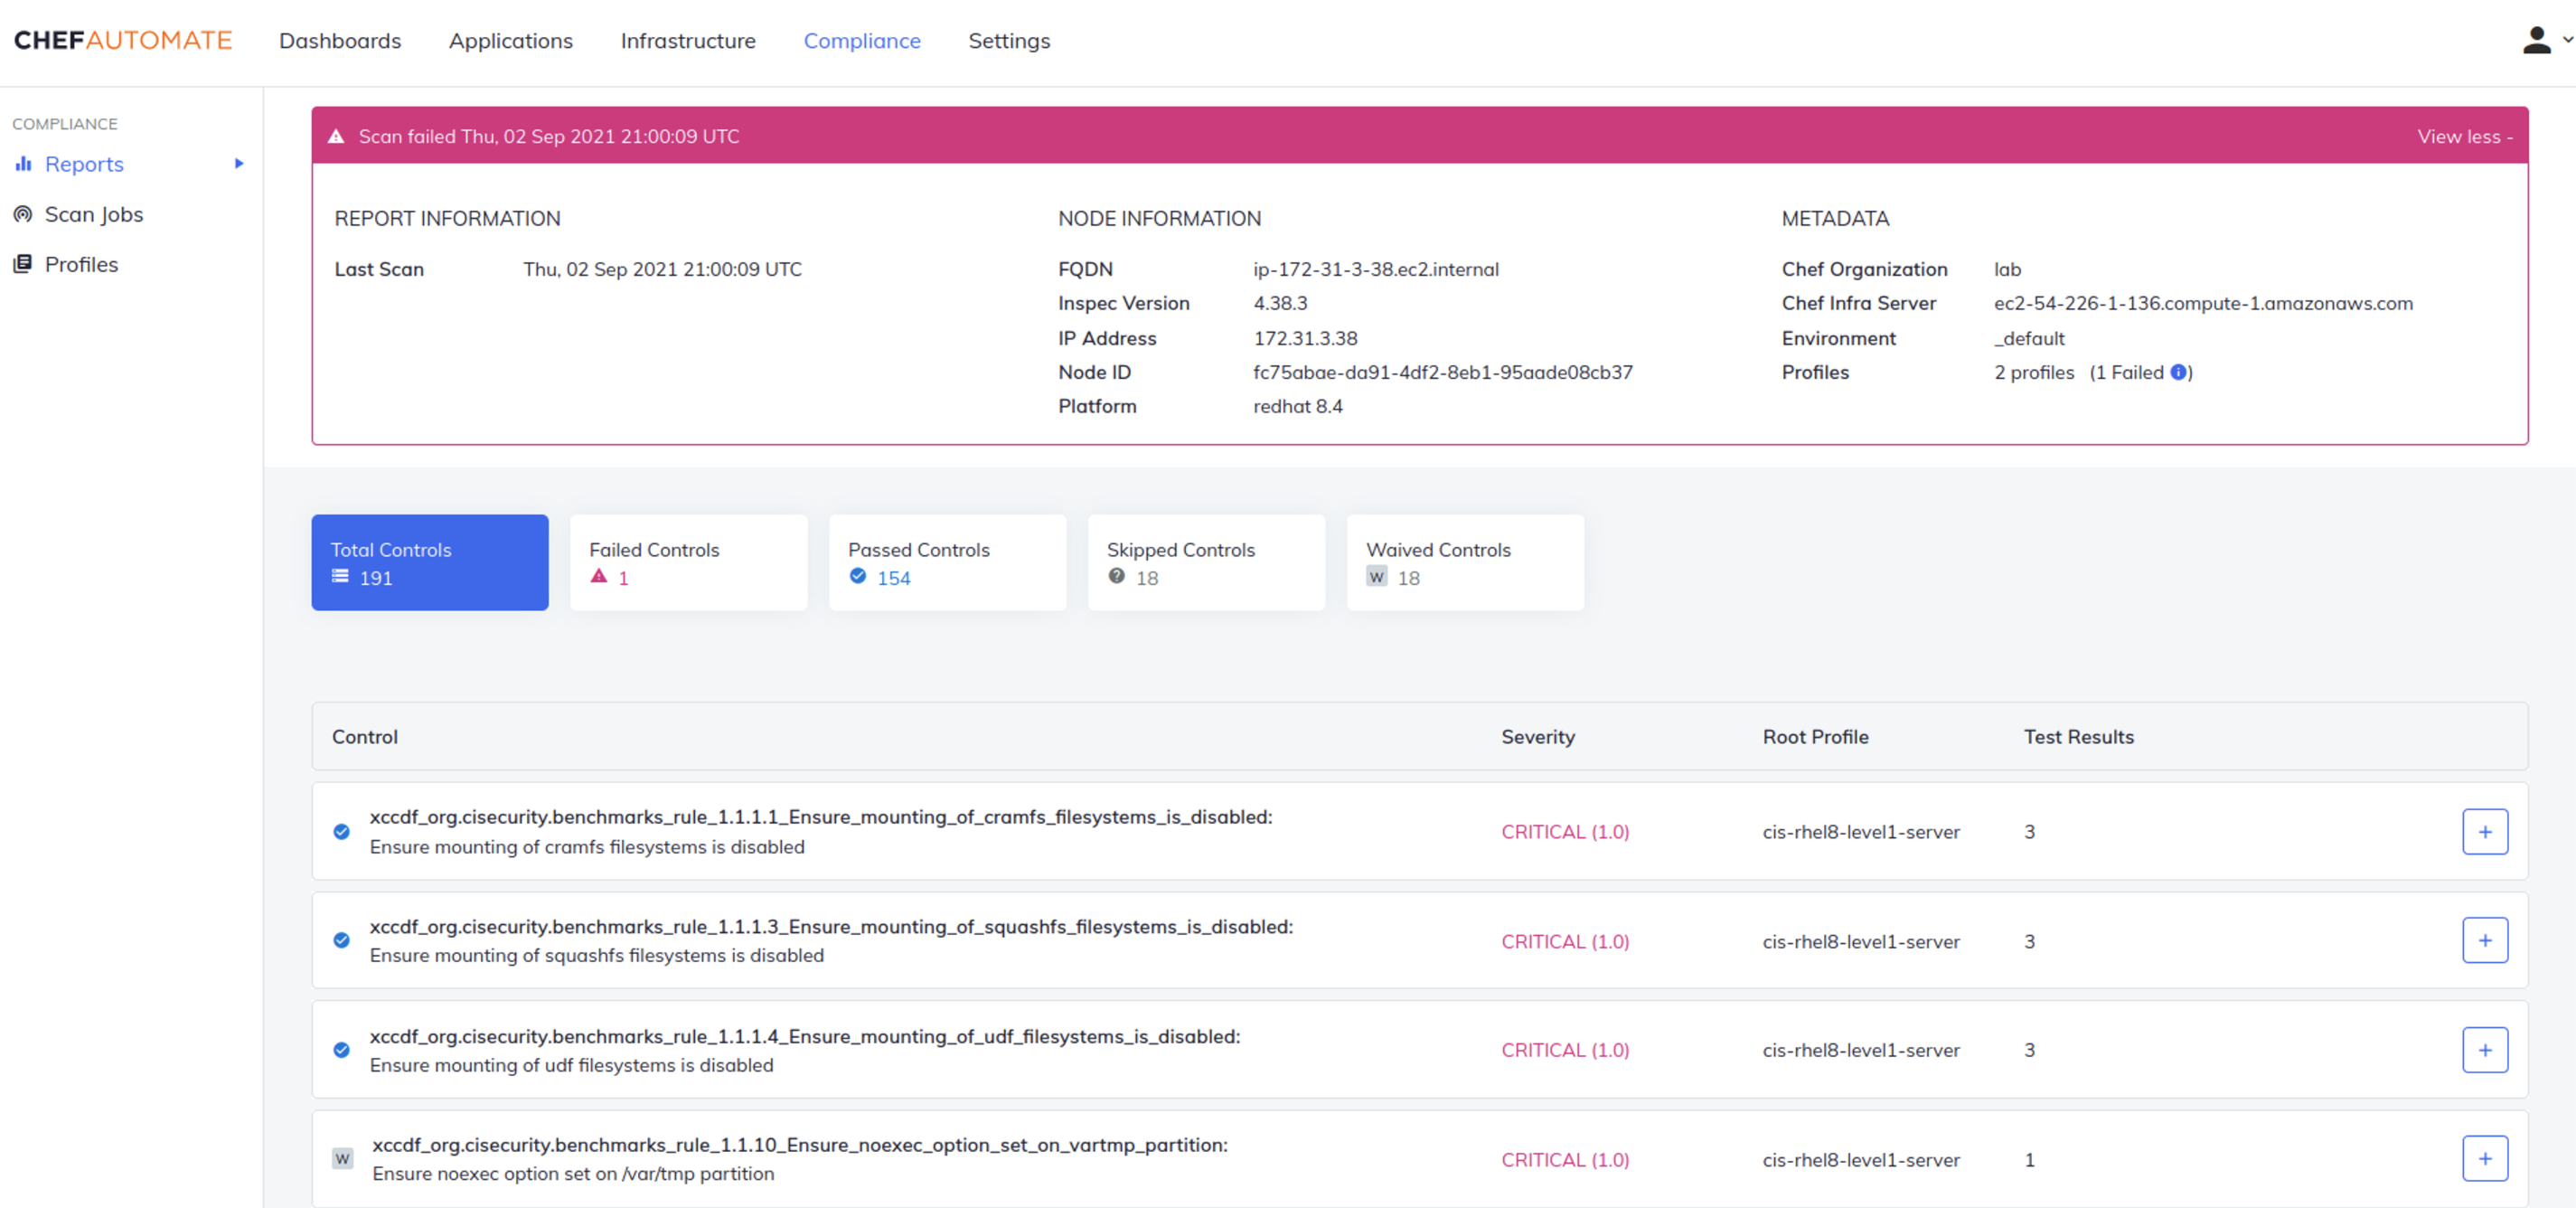
    Progress is now also extending the reach of its Chef Compliance Automation for Cloud Resources offering across Amazon Web Services (AWS), Microsoft Azure and Google Cloud Platform (GCP) to include Chef premium content that aligns with best practices for each cloud environment in addition to providing integration with Azure Policy, a suite of tools from Microsoft that compares resources to a set of business rules that define how cloud infrastructure should be employed.

    Chef

    Finally, Progress has enhanced Chef Enterprise Automation Stack to provide tighter integration between compliance and infrastructure automation along with adding infrastructure operations dashboard, support for Windows patch management, integration with third-party secrets management tools, and improvements to Chef Workstation and Chef Test Kitchen to simplify testing within application development processes.

    With the release of a SaaS platform and the availability of managed services, Chef is joining a long list of IT vendors that are removing responsibility for deploying and securing their platforms from internal IT operations teams. It’s clear more organizations now want to spend more time on building and deploying software than managing the platforms that automate those tasks on their behalf, said Reddy.

    It’s not clear how many IT teams that have already deployed a platform might shift over to a SaaS platform or rely on an IT vendor to manage that platform on their behalf. However, in the wake of the COVID-19 pandemic, many IT teams continue to work from home to help combat the spread of the virus. Many of those organizations have either shifted platforms to the cloud themselves, adopted SaaS platforms or outsourced the management of IT platforms altogether. There are also many small organizations that simply don’t have the internal expertise and resources required to stand up an IT automation platform on their own.

    That approach also makes it simpler to converge security, compliance and IT operations management within the context of a larger DevSecOps workflow, noted Reddy.

    The great paradox of IT automation has always been the level of expertise required to achieve it. Organizations that lack the expertise required to create automated playbooks, for example, don’t derive much value from an IT automation platform. It’s only been larger companies that have mostly derived the most benefit from investments in IT automation. However, as IT automation becomes more accessible via SaaS platforms and managed services, the level of expertise required to benefit from it naturally drops. In fact, with the advent of artificial intelligence (AI) for IT operations (AIOps), many manual IT tasks are increasingly being automated.

    It’s too early to say whether the IT industry as a whole is on the cusp of the next wave of automation, but the raw ingredients that make up the primordial soup needed to achieve that goal is, at this point, only awaiting a catalyst.

  • SRE’s Guide to Pragmatic Incident Response

    SRE’s Guide to Pragmatic Incident Response

    In my past experience as an SRE, I learned some valuable lessons about how to respond to and learn from incidents. If you want the TL;DR, I’ll summarize them here:

    • Declare and run retros for the small incidents. It’s less stressful, and action items become much more actionable.
    • Decrease the time it takes to analyze an incident. You’ll remember more, and will learn more from the incident.
    • Alert on pain felt by people – not machines. The only reason we declare incidents at all is because of the people on the other side of those machines.

    Now, let’s dive into each of these lessons a little deeper, and explore how they can help you build a better system for pragmatic incident response.

    1. Focus on the Small Incidents First

    The bad habit of ignoring small issues often leads to bigger issues. You should run retrospectives for small incidents (slowdowns, minor bugs, etc.) because these often have the most actionable takeaways—instead of shooting the moon and creating “rearchitect async pipeline” as a Jira ticket that never happens. Focusing on low-stakes incidents and retrospectives are a great introduction to behavior change across your organization.

    Let’s look at an obvious example of how a focus on small incidents can have an outsized impact. Case in point—my apartment. I live in an old candy factory retrofitted into apartment units. We have an elevator (thank God), but some of the buttons don’t light up when you press them. The LED display doesn’t match up with the numbers on the floor buttons. Yes, the elevator goes up and down, but overall, you can tell that things are wrong with it.

    One day, I came home and noticed an “Out of Order” notice on the elevator door. Was I surprised? Not at all. Of course an elevator with mislabeled buttons and broken LEDs would stop working!

    This isn’t dissimilar from an important software lesson—ignoring small issues often leads to much bigger issues. What starts as an inconvenience can lead to a complete breakdown. This is why you should focus on the small incidents first. I hear a lot of companies say, “We need to fix incident response! Every time we have an incident, it’s just chaos!”

    They are talking about unexpected downtime during a high severity level incident and they want to improve it.

    I say that’s the wrong type of incident to use to fix your incident response system and process. Focus on the small incidents first. Running retros for small incidents can help you build strong incident response models, because they have the most actionable takeaways and they are the best way to change behavior through repetition and practice.

    If you have a high-stakes, 12-hour incident and you run a one-hour retrospective you’re not going to get the results you want. You need to start small. Run retros for bugs that were introduced; maybe a bad data migration that didn’t really impact anything but took up a couple of hours of your day.

    Heidi Waterhouse captured this idea really well in this piece on reliability. Every airplane you’ve ever flown on has many tiny problems, Waterhouse said, “… like a sticky luggage latch or a broken seat or a frayed seatbelt. None of these problems alone are cause to ground the plane. However, if enough small problems compound, the plane may no longer meet the requirements for passenger airworthiness and the airline will ground it. A plane with many malfunctioning call buttons may also be poorly maintained in other ways, like faulty checking for turbine blade microfractures or landing gear behavior.”

    I couldn’t agree more. Extrapolating to software: The small things are typically indicators of bigger issues and could cause catastrophes down the road.

    2. Track Mean Time to Retro (MTTR)

    It’s important to think about what you measure in your organization. You should be measuring how you’re improving, and the most important metric here is mean time to retro (MTTR). Everyone should be tracking MTTR. It’s a great statistic to improve incident response in your team because it helps you understand the delay between incidents and retrospectives.

    The easiest way to have a bad incident retro is to wait two weeks. It’s better to get into a room quickly and hash out what happened than wait a long time until you’ve got everything perfectly prepared.

    Tracking MTTR can help you hold prompt and consistent retrospectives after incidents. Set a timer and make an SLO or SLA for yourself that says, “This is how long we take for retros.”

    Retro time will vary depending on the severity of the incident itself. If it’s a SEV1, clear everyone’s schedules, because you need to have retro within 24 hours of the incident. For SEV3 incidents, you have much more leniency.

    I also like tracking the ratio of retros to declared incidents. This is a metric that should go up; you should see your ratio of retrospectives to incidents increasing. You can break down that number by severity, as well. If you have a low retro ratio for a SEV1 versus a SEV3 incident, that might be okay at first (remember, start small) but you want those metrics to eventually become equal.

    3. Alert on Degraded Experience with the Service, and Not Much Else

    The severity of incidents is directly linked to customer pain. We would not declare SEV1s if there weren’t a lot of people feeling a lot of pain.

    Alerting on computer vitals is an easy way to create alert fatigue and burnout. As your company starts to scale, you are going to use more CPU; you’re going to use more memory. Tying alerts to computer vitals is not a good sign.

    If I run, my heart will beat faster—it’s just doing its job. Paging people at 2:00 a.m. because disc capacity is at 80% even though you won’t run out of space until next month is a good way to lose great teammates. I have worked with people who left their previous companies strictly because they got paged too many times for stuff that didn’t matter.

    This is why you need to alert on a degraded experience with the service and not much else. A CPU burning hot at 90% is not necessarily a bad thing, but you need context to decide. Create SLOs that are tied to customer experience and alert on those. People experiencing problems with the service is the only thing you should alert on—for the most part.

    One of the best ways I’ve seen to think about this came from Soundcloud developers, who explained that you should alert on symptoms, not causes. My fast heartbeat is not necessarily a problem. But if my elevated heart rate leads to lightheadedness and I fall—that’s a problem. So, I need to be able to alert on something like that. Paging people at 2:00 a.m. because disc capacity is at 80% and you won’t run out until next month is not good. But paging people because you know that disc capacity problems cascade into other, systemic problems is. You can apply the same thought to other potential causes of an outage. Paging alerts that wake you up in the night should only be based on symptoms.