Category: Application Performance Management/Monitoring

  • API Sprawl a Looming Threat to Digital Economy

    API Sprawl a Looming Threat to Digital Economy

    New estimates say the total number of public and private APIs in use is approaching a whopping 200 million. APIs are becoming increasingly crucial to the global digital economy. They are the backbone of many digital platforms and drive the composable enterprise model. But this ubiquity presents sprawl issues.

    F5 recently released a study that examines the conditions of the API economy at large. Authored by Rajesh Narayanan and Mike Wiley of F5, the paper, Continual API Sprawl: Challenges and Opportunities in an API Driven Economy, articulates the state of API sprawl and the conditions behind its arrival.

    According to Narayanan and Wiley, “If data is the new oil, then APIs will become the new plastic.” This looming reality will require a continuous approach to API management to avoid further polluting the digital ecosystem.

    Below, I’ll review the report’s main takeaways to see what has given rise to API sprawl and consider how IT leaders should respond.

    State of API Growth

    APIs have evolved as a standard mechanism for businesses and services to connect and share value. And, as more companies begin to rely on them, the API economy is becoming big business—83% of organizations today consider API integration a critical part of their business strategy, according to the 2020 Cloud Elements State of API Integration Report.

    There is a proliferation of API styles. Thousands of public productized APIs exist, but more private and partner APIs are in use. Technically speaking, APIs come in many different forms—they may be web-based, browser-based or embedded into devices. The report also identifies single-purpose APIs and those that aggregate multiple data providers.

    API use cases are pervasive, from hotel bookings to weather, stock tickers, transportation, IoT, DevOps workflows and many other areas. “API-powered apps have permeated every aspect of our lives,” said the report. Yet, typical market estimates are usually quite conservative when sizing up this market, said F5. According to F5’s aggressive calculations, we will be approaching 1.7 billion active APIs by 2030.

    APIs present a high value from startup use cases to enterprise applications. However, a downside is that this growth is leading to sprawl, said Narayanan and Wiley.

    API sprawl is the term used to describe both the exponentially large number of APIs being created and the physical spread of the distributed infrastructure locations where the APIs are deployed.

    Factors Driving API Sprawl

    Sheer growth. Sources predict the number of developers will grow to 45 million by 2030. SlashData also estimates that 30% of developers already use APIs. As the number of APIs on the market moves into the millions, managing growth poses a significant challenge, especially without proper governance and best practices.

    Lack of standards. “The lack of a common shared model contributes to API sprawl,” the report said. API design standards do exist, yet guidelines often leave room for nuances between services. Standards have also emerged around specific industries, like financial data exchange (FDX). While helpful for a single sector, this doesn’t advance multiple industries simultaneously. A lack of standardization leads to differing versioning approaches and integration challenges.

    New development approaches. Integration requirements are forcing many new APIs to unite disparate business apps. The microservices architecture trend is also adding to sprawl, as “APIs are both northbound to interfaces via microservices and horizontally between microservices.”

    Continuous software development. Continuous development, paired with the need to connect business units with bespoke requirements, could produce multiple versions of the same API. This quickly leads to maintenance difficulties, out-of-date documentation and broken clients. The report also cites rising data creation and “everything-as-a-service” trends as harbingers of an API sprawl.

    Various computing evolutions. New computing trends are also prompting a sprawl, says the report. Business units may be operating on different on-premises or cloud environments. When this hybrid situation occurs, APIs could get dispersed over many locations and become difficult to track. Specific connections may be created to cater to new environments like edge computing and IoT devices, further increasing sprawl.

    Problems With API Sprawl

    A digital economy reliant on APIs also relies on the underlying stability and availability of these services. Yet, “APIs have a shelf life and become unsupported if ignored by the developers,” the paper acknowledged. It could be hard to maintain service reliability for APIs sprawled across a distributed cloud. In addition to reliability issues, there are many other possible repercussions of an API sprawl.

    For one, management and operation at scale become difficult. Not all APIs are based on a specification, like OpenAPI. This means that API documentation may not be as streamlined and accessible, thus hurting discoverability and onboarding. “A simple means to connect these APIs may not be possible with conventional or legacy networking approaches,” the report added.

    As developers are top consumers of APIs, a sprawl could negatively impact their integration experience. Maintaining a swelling library of API dependencies can be cumbersome. Plus, APIs are prone to evolve and version over time and when endpoints are altered without advance notice, it leads to broken clients. Even small changes in API functionality can have a huge impact since all observable API behaviors will become relied upon, whether documented or not. (This is known as Hyrum’s Law).

    But the security ramifications of API sprawl are perhaps the most troubling. A whopping 91% of enterprises experienced an API security incident in 2020. Malicious API traffic also rose by a staggering 300% in mid-2021, Salt Labs found. Increased API use will undoubtedly cause more frequent attacks.

    “Unmanaged API sprawl is a security breach waiting to happen,” said the report. APIs typically adopt API keys for authentication and authorization, but this method is prone to misuse. Credentials are often exposed or misconfigured. Bad actors can use APIs to steal loads of data and computing power. As a result, sprawl is undermining trust in API connections and responses.

    Mitigating The Sprawl

    With the growth of the API economy slated to reach the billion mark in the next ten years, figuring out secure, stable inter-cluster communication will become more critical. According to F5, existing solutions (gateways, ingress controllers, service mesh and forward and reverse proxies) are not an adequate response.

    “We believe the solution should hence involve an intermediary (proxy) device focused on solving inter-cluster connectivity, security and integration challenges.” The writers call this solution API Gateway 2.0, which they describe as a bi-directional application-level proxy. The technology exists to implement such middleware and perhaps it could help companies address sprawl issues.

    Outside of Narayanan’s and Wiley’s recommendations, there are plenty of actions API owners can take to avoid adding to the sprawl. Here are a few:

    • Treat the API as a product
    • Improve developer experience
    • Use spec-driven development
    • Ensure up-to-date documentation and code libraries
    • Use consistent endpoint naming
    • Set clear guidelines for versioning and deprecation
    • Go beyond API keys with OAuth and OpenID Connect

    For more context, check out Continual API Sprawl: Challenges and Opportunities in an API Driven Economy for free without an email gate here.

  • Sumo Logic Extends Observability Reach to AWS Lambda

    Sumo Logic Extends Observability Reach to AWS Lambda

    At the AWS re:Invent conference this week, Sumo Logic announced that in addition to collecting log data, metrics and traces, it now can collect telemetry data from the Lambda serverless computing service provided by Amazon Web Services (AWS).

    In addition to collecting telemetry data, Sumo Logic also revealed that the Sumo Logic Continuous Intelligence Platform hosted on the AWS cloud can now analyze how functions used on the AWS Lambda service perform during transactions.

    That data can then also be correlated against the performance of other AWS services that Sumo Logic tracks via integrations with the AWS CloudWatch and AWS CloudTrail monitoring services.

    George Gerchow, chief security officer for Sumo Logic, said the company is making extensive use of the OpenTelemetry agent software created under the auspices of the Cloud Native Computing Foundation (CNCF) to make it simpler to instrument IT environments. That data is not only being used to improve application performance but also to surface anomalies indicative of a security breach, he added.

    As part of this ongoing security effort, Sumo Logic this week also added Sumo Logic AWS Quick Start integrations for rapid access to security and compliance insights along with support for Amazon Inspector, a vulnerability management service provided by AWS.

    AWS this week named Sumo Logic as its independent software vendor (ISV) partner of the year. The two companies have a longstanding relationship that began with Sumo Logic’s decision more than 10 years ago to build a monitoring platform hosted on the AWS cloud.

    As IT monitoring tools continue to evolve into observability platforms, Gerchow said it’s becoming much easier to leverage machine learning algorithms and open source agent software to identify the root cause of an issue before it results in a major disruption.

    Most IT teams today are still relying on legacy monitoring tools that only tack a set of predefined metrics to identify when a specific platform or application is performing within expectations. The metrics tracked generally focus on, for example, resource utilization. In contrast, observability combines metrics, logs and traces—a specialized form of logging—to instrument applications in a way that makes it simpler to troubleshoot issues.

    Observability, of course, in one form or another, has always been a core tenet of DevOps best practices. Initially, DevOps teams focused on continuous monitoring as the most effective way to proactively manage application environments. However, it can still take days (and sometimes weeks) to discover the root cause of an issue. Observability platforms promise to make it easier to manage IT environments even as the overall complexity of those environments continues to increase.

    It’s not clear at what rate IT organizations will be transitioning to observability platforms. However, it generally takes only one major outage before IT organizations start looking for better tools to manage their IT environment. As those IT environments become more complex, the probability that there will be a significant disruption is now higher than it’s ever been. The challenge and the opportunity is to find a way to instrument applications more widely; the expectation being that an observability platform will be able to analyze telemetry data to reduce the number of issues that lead to service disruptions.

  • AWS Unfurls Bevy of Automation Tools to Streamline DevOps

    AWS Unfurls Bevy of Automation Tools to Streamline DevOps

    At the AWS re:Invent conference, Amazon Web Services (AWS) added a bevy of tools to its portfolio intended to accelerate the pace of application development while simultaneously simplifying DevOps processes.

    AWS development tools unveiled this week include AWS Amplify Studio, a visual development environment that allows developers to create web application user interfaces (UIs) with minimal coding.

    Ken Exner, head of product for developer tools at AWS, said as an extension of an existing AWS Amplify Studio tool, this latest addition allows developers to customize application UIs at a higher level of abstraction using a library of components while enabling them to drop down to a lower level of coding to customize their application further whenever required. After the UI is designed, AWS Amplify Studio automatically generates the associated JavaScript or TypeScript code for the developer.

    In general, AWS is committed to improving developer productivity by providing, for example, automated reasoning tools that automate processes without locking devs into a layer of abstraction that, ultimately, may create a wall that blocks them from meeting customization requirements, he said.

    Other developer tools launched by AWS this week include updates to Amazon CodeGuru Reviewer that adds a secrets detector that uses machine learning algorithms to identify hardcoded secrets that can be secured using AWS Secrets Manager; a revamped Amazon Inspector vulnerability management tool that provides automated assessment scans, automated resource discovery, support for container-based workloads, improved risk scoring, integration with Amazon EventBridge and AWS Security Hub and the removal of the stand-alone Amazon Inspector scanning agent.

    AWS also revealed it has eliminated the need to manually pull images from the Amazon Elastic Container Registry (ECR) repositories by adding automated synchronization capabilities that keep private and public registries consistent with each other.

    In terms of IT operations tools, AWS added a managed database service to its Amazon Relational Database Service portfolio that allows IT teams to customize the underlying database and operating system using an RDS Custom option, a new table class for Amazon DynamoDB designed to reduce storage costs for infrequently accessed data and a service for RDS, dubbed Amazon DevOps Guru, that extends existing machine learning capabilities to automatically detect and diagnose performance bottlenecks and operational database issues.

    Jeff Carter, vice president for relational databases at AWS, said that as databases are increasingly managed by DevOps teams rather than traditional database administrators (DBAs), the cloud service provider is moving to reduce friction by automating as many manual tasks as possible. That’s critical at a time when IT teams are deploying a much wider range of purpose-built databases that are optimized for different classes of applications, he added. The overall goal is to rely more on automation to reduce friction across the IT environment, said Carter.

    Overall, there are two classes of AWS customers: The first are development teams that are increasingly relying on managed services provided by AWS to automate a wide range of DevOps processes. The second tend to be enterprise IT organizations that prefer to manage cloud services themselves.

    Mitch Ashley, a principal for Techstrong Research, an arm of the parent company of devopsy.kinsta.cloud, noted that, in many cases, enterprise IT teams are managing DevOps workflows that span multiple clouds. As such, they tend to prefer tools and platforms that can be applied to both multiple clouds and on-premises IT environments. The more those organizations rely on managed services provided by a cloud service provider the more difficult it becomes to consistently manage DevOps workflows across multiple IT environments.

    It’s too early to say just how much IT organizations will rely on managed services going forward. However, at a time when more organizations are using more IT platforms than ever, it’s clear the DevOps management challenge increases with each new platform introduced into the IT environment.

  • AWS re:Invent Roundup: Private 5G | Graviton3 ARM Chips | DevOps Guru++

    AWS re:Invent Roundup: Private 5G | Graviton3 ARM Chips | DevOps Guru++

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: Three things that caught my eye from Amazon Web Services’ re:Invent 2021 conference: Private 5G, Graviton3 chips, and something called DevOps Guru for RDS (yes, really).

    Private NRaaS vs. Wi-Fi

    First up this week: AWS Private 5G is a new turnkey service, offering local private cellular data infrastructure, for places where Wi-Fi just doesn’t cut it. Despite the name, it offers a 4G/LTE fallback to 5G/NR. Because it’s AWS, the hardware is free—you just pay for usage.

    Analysis: Combine with an Outpost for a sharper edge

    Wi-Fi is unreliable and low powered. 5G over the 3.5 GHz “citizens’ band” seems like a great alternative (just don’t tell the lunatic fringe of the anti-5G brigade).

    And, of course, AWS makes it easy to buy—Amazon ships you all the private radio gubbins for “free” and just bills you based on capacity and usage. It’s automatically configured and remotely maintained. You just take your internet connection and plug it in.

    Aisha Malik: Amazon launches preview of new AWS Private 5G managed service

    “AWS Private 5G” … is a new service that aims to make it easy to deploy and manage your own private network. … AWS CEO Adam Selipsky said that with AWS Private 5G, you can set up and scale a private mobile network in days instead of months.
    …
    There are no upfront fees or per-device costs: … Customers pay only for the network capacity and throughput they request. [It] scales capacity on-demand.
    …
    AWS Private 5G is available in preview in the United States.


    And this is better than Wi-Fi how, exactly? Ballu counts the ways:

    Industrial area coverage: Where you need 50 Wi-Fi radio units, you can provide service with 3–4 p4G/p5G radios.
    …
    Hazardous areas: Where you can’t provide the networking at all the corners or areas, one p5G radio blast area (esp with beam technology) can.
    …
    Packet loss: Less packet loss compared to Wi-Fi (believe me, it’s a big deal in the Industrial world)
    …
    Compatibility: What’s a negative for 5G modems (not many devices are available), is positive to some extent. Once investment is made with 5G modems, the devices can be on the road too.


    Unsurprisingly, Brian Roemmele feels vindicated:

    Precisely as I wrote about in 2017 to great ridicule from an analyst at a famous VC firm: Amazon is becoming a phone company.
    …
    From the Sidewalk Network to the Kuiper satellite system to local 5G. The network is no longer just “dumb pipes.”


    Graviton3: AWS ARM SoC is PDQ

    Graviton3 is the latest version of Amazon’s ARM server chip. It looks like it’s based on a 5nm process implementing the latest ARMv9 ISA. AWS is making the usual claims about it being much faster than the previous generation, but it also has new security features.

    Analysis: Cool chips

    AWS is deadly serious about low-power, high-performance compute. Amazon is just one licensee that would be distressed to have Nvidia owning Arm.

    As I said last week—and the week before that—ARM chips are an increasing fixture in the datacenter, especially ones that value “performance per Watt.” Other IaaS providers might bleat about how they’re reducing the energy used to cool their data centers, but surely it’s a better plan to start with less waste heat.

    Maria Deutscher: AWS debuts new compute-intensive and AI instances powered by custom chips

    AWS’ new Amazon EC2 C7g instances target compute-intensive workloads such as analytics tools and scientific modeling software. The C7g series is based on the AWS Graviton3 chip, the third iteration of the cloud giant’s internally-designed processor.
    …
    Companies that plan to use C7g instances for machine learning workloads can expect an up to threefold performance jump in AI performance. The speed jump is partly the result of the processor’s support for bfloat16, a specialized data format [that] enables applications to process floating point numbers faster and using less memory than FP32, the data format historically used for the task.
    …
    For cryptographic tasks, Graviton3 delivers as much as double the performance of the Graviton2. … The chip introduces a feature called pointer authentication to reduce the risk of cyberattacks.


    Tim Anderson has been sifting through the re:Invent announcements:

    Top of the list perhaps is Graviton3, the next generation of AWS’s homemade [ARM] server processors. These chips will be used in new C7g instances previewed offering DDR5 memory (50 percent more bandwidth than DDR4) and up to 25 per cent better compute performance compared to instances powered by Graviton2.
    …
    Adam Selipsky gave his first Re:Invent keynote as AWS CEO. [He] said Graviton uses “up to 60 per cent less energy.” … Graviton matters because it is among those leading a charge to get more [ARM] microprocessors into data center and cloud infrastructure, and because if it’s more energy and cost efficient to operate, it’s critical to Amazon’s bottom line, sorry, today’s environmental concerns.


    And is that pointer-authentication feature useful? Yes, very, says spijdar:

    Very useful. … If the performance is good, this is a nice extra layer that makes return-oriented programming more difficult. Combined with NX bits, it really raises the difficulty in developing/using many types of exploits (it’s not impossible to bypass … but there’s no perfect security).


    DevOps Guru Adds RDS Support

    DevOps Guru for RDS is the latest upgrade for AWS’s oddly-named smart monitoring features.

    Analysis: Silly name; useful tool

    Laplace and Gauss were right: Your DevOps team aren’t all rockstars. “Average” ops staff are in the majority. So extending AWS’s monitoring automation to your database instances should be a positive step.

    But that branding: Can anyone take it seriously?

    Stephanie Condon: AWS brings more automation to database management

    The new Amazon DevOps Guru for RDS automatically can find and fix database issues … helping developers using Aurora detect, diagnose and resolve database performance issues. [It] can help remediate a range of issues, such as over-utilization of host resources, database bottlenecks, or misbehavior of SQL queries.
    …
    Last year, AWS introduced DevOps Guru, a service that uses machine learning to automatically detect and alert customers of application issues. … Amazon DevOps Guru for RDS builds on that
    …
    Users can view [issues] in the DevOps Guru console or via notifications from Amazon EventBridge or Amazon Simple Notification Service (SNS).


    Sounds interesting, says u/random_dent:

    I thought the DevOps Guru for RDS sounded interesting. You need to enable performance metrics first, which have their own charges, but it still looks not too expensive, plus three months free-tier, so we may try it out.

    We’ve had some odd issues with RDS performance that are too inconsistent to lock down. It would be interesting to see if this could give us some insight.


    But that name! Here’s Thomas LaRock—@SQLRockstar:

    I’m old enough to remember when DevOps Guru for RDS was just called “database performance monitoring.”


    And @shmick is young enough to say it like this:

    such a cringe name


    The Moral of the Story: Misfortune tests the sincerity of friends


    You have been reading The Long View by Richi Jennings. You can contact him at @RiCHi or tlv@richi.uk.

    Image: Andrew Svk (via Unsplash)

  • Fugue Marries Compliance-as-Code Tool to AWS Well-Architected Framework

    Fugue Marries Compliance-as-Code Tool to AWS Well-Architected Framework

    Fugue has infused the best practices defined by Amazon Web Services (AWS) within its software-as-a-service (SaaS) offering for provisioning infrastructure using its infrastructure-as-code (IaC) platform.

    Fugue CEO Josh Stella said that IT teams can now evaluate templates for provisioning AWS infrastructure that were created using AWS CloudFormation or Terraform tools to ensure they comply with the AWS Well-Architected Framework.

    The AWS Well-Architected Framework spans five pillars that AWS has defined for designing and operating reliable, secure, efficient and cost-effective systems in the cloud. AWS has defined a set of best practices for each pillar and rewards organizations for following those by making available additional cloud credits. The goal is to improve overall cloud security by providing guidance that ultimately reduces the number of misconfigurations so that cybercriminals can’t discover and exploit them.

    The Fugue platform complements that effort because it is based on Open Policy Agent (OPA), a general-purpose engine for managing compliance-as-code that is being advanced under the auspices of the Cloud Native Computing Foundation (CNCF). Fugue extended OPA by creating Regula, an open source tool that evaluates IaC files for potential security and compliance violations. Fugue then created a SaaS platform that makes extensive use of the AWS Lambda serverless computing platform to make it easier to enforce compliance policies.

    Those policies include turnkey coverage for specifications such as SOC 2, NIST 800-53, GDPR, PCI, HIPAA, ISO 27001, CSA CCM, CIS Controls, CIS Docker and CIS Foundations Benchmarks for AWS, Microsoft Azure, Google Cloud and Kubernetes.

    Stella said Fugue has now incorporated the technical aspects of the AWS Well-Architected Framework. However, it’s still up to each IT team to navigate the cultural aspects of the shared responsibility model of compliance and security that cloud service providers like AWS follow.

    Unfortunately, developers that employ IaC tools to provision cloud infrastructure often make some faulty assumptions about the level of security maintained by the cloud service provider. The result is often a raft of security and compliance issues that arise mainly because most developers don’t have a lot of domain knowledge expertise in either area.

    It’s not clear how many organizations have adopted the AWS Well-Architected Framework, but as various tools make it easier to implement these best practices defined by AWS the more secure and efficient cloud computing environments should become. In fact, in many cases, those tools are being embedded within a larger set of DevSecOps best practices that are being implemented across multiple clouds.

    Stella said he doubted there will ever be any standardization when it comes to security and compliance frameworks that could be applied to multiple clouds; however, it’s clear that cloud service providers are at least making available frameworks that borrow concepts from one another.

    Regardless of the approach, the overall state of cloud security and compliance will continue to improve as more guardrails are automatically implemented. The issue then becomes not only finding a way to ensure that cloud infrastructure is secure when deployed and also determining how much of the infrastructure being relied on today is less secure than it should be.

  • Digital Transformation Driving VSM Adoption

    Digital Transformation Driving VSM Adoption

    The number of organizations using value stream management (VSM) to bridge the divide between DevOps and the rest of the business is expected to dramatically increase over the next two years. The shift is due, in part, to investments in digital business transformation initiatives.

    A survey of more than 500 executives, IT and business leaders conducted by Dimensional Research on behalf of Broadcom, a VSM platform provider, finds the percentage of organizations employing VSM will rise from 42% today to 70% in the next two years. Nearly three-quarters of organizations (72%) that are not currently using VSM plan to do so in the next 18 months or more.

    The survey also finds that 85% of organizations are collecting some subset of value stream metrics today as part of an effort to deliver solutions faster (56%), improve decision making (55%) and increase transparency (54%).

    Laureen Knudsen, chief transformation officer at Broadcom, said that as organizations embrace DevOps best practices more broadly to drive digital business transformation initiatives, they need more visibility into the application development process. VSM surfaces the insights required to not only identify bottlenecks but also track how changes in application delivery timetables will impact key performance indicators (KPIs).

    VSM traces its lineage back to lean manufacturing methods, which called for each step of a manufacturing process to be continuously measured. As software development has evolved from being a craft to an automated process using DevOps best practices—and as organizations realize just how dependent they are on software—an appreciation for the value of monitoring the impact of missed software development deadlines on the business is growing steadily. VSM platforms automatically collect technical metrics from DevOps tools that are then correlated against the KPIs the organization decides to track.

    The Broadcom survey found more than 96% of respondents’ companies are already in the process of adopting digital transformation. Strategic objectives include increasing efficiencies (70%), improving product quality (67%) and improving customer value (63%).

    Most respondents (92%), however, are anticipating product development challenges for 2022. The biggest product development challenge cited is a lack of visibility throughout the product life cycle (45%) followed by inefficient processes (44%), lack of resources (42%) and enterprise-wide lack of understanding of how products deliver customer value (42%). A full 89% of the business leaders surveyed also noted they continue to struggle with organizational silos between strategic development and operations; 93% noted that better alignment between teams would improve their organization’s overall return on investment (ROI) in software development. A total of 95% said they believed VSM would optimize their product life cycle processes.

    Knudsen said that, in time, artificial intelligence (AI) technologies will increasingly be infused into VSM platforms to enable automated feedback loops between the business and DevOps teams. In the meantime, DevOps teams should be prepared to adjust project priorities based on the needs of the business and to endure a higher level of scrutiny as business stakeholders become more involved in setting the software development agenda.

  • Logz.io Extends Open Source Observability Platform

    Logz.io Extends Open Source Observability Platform

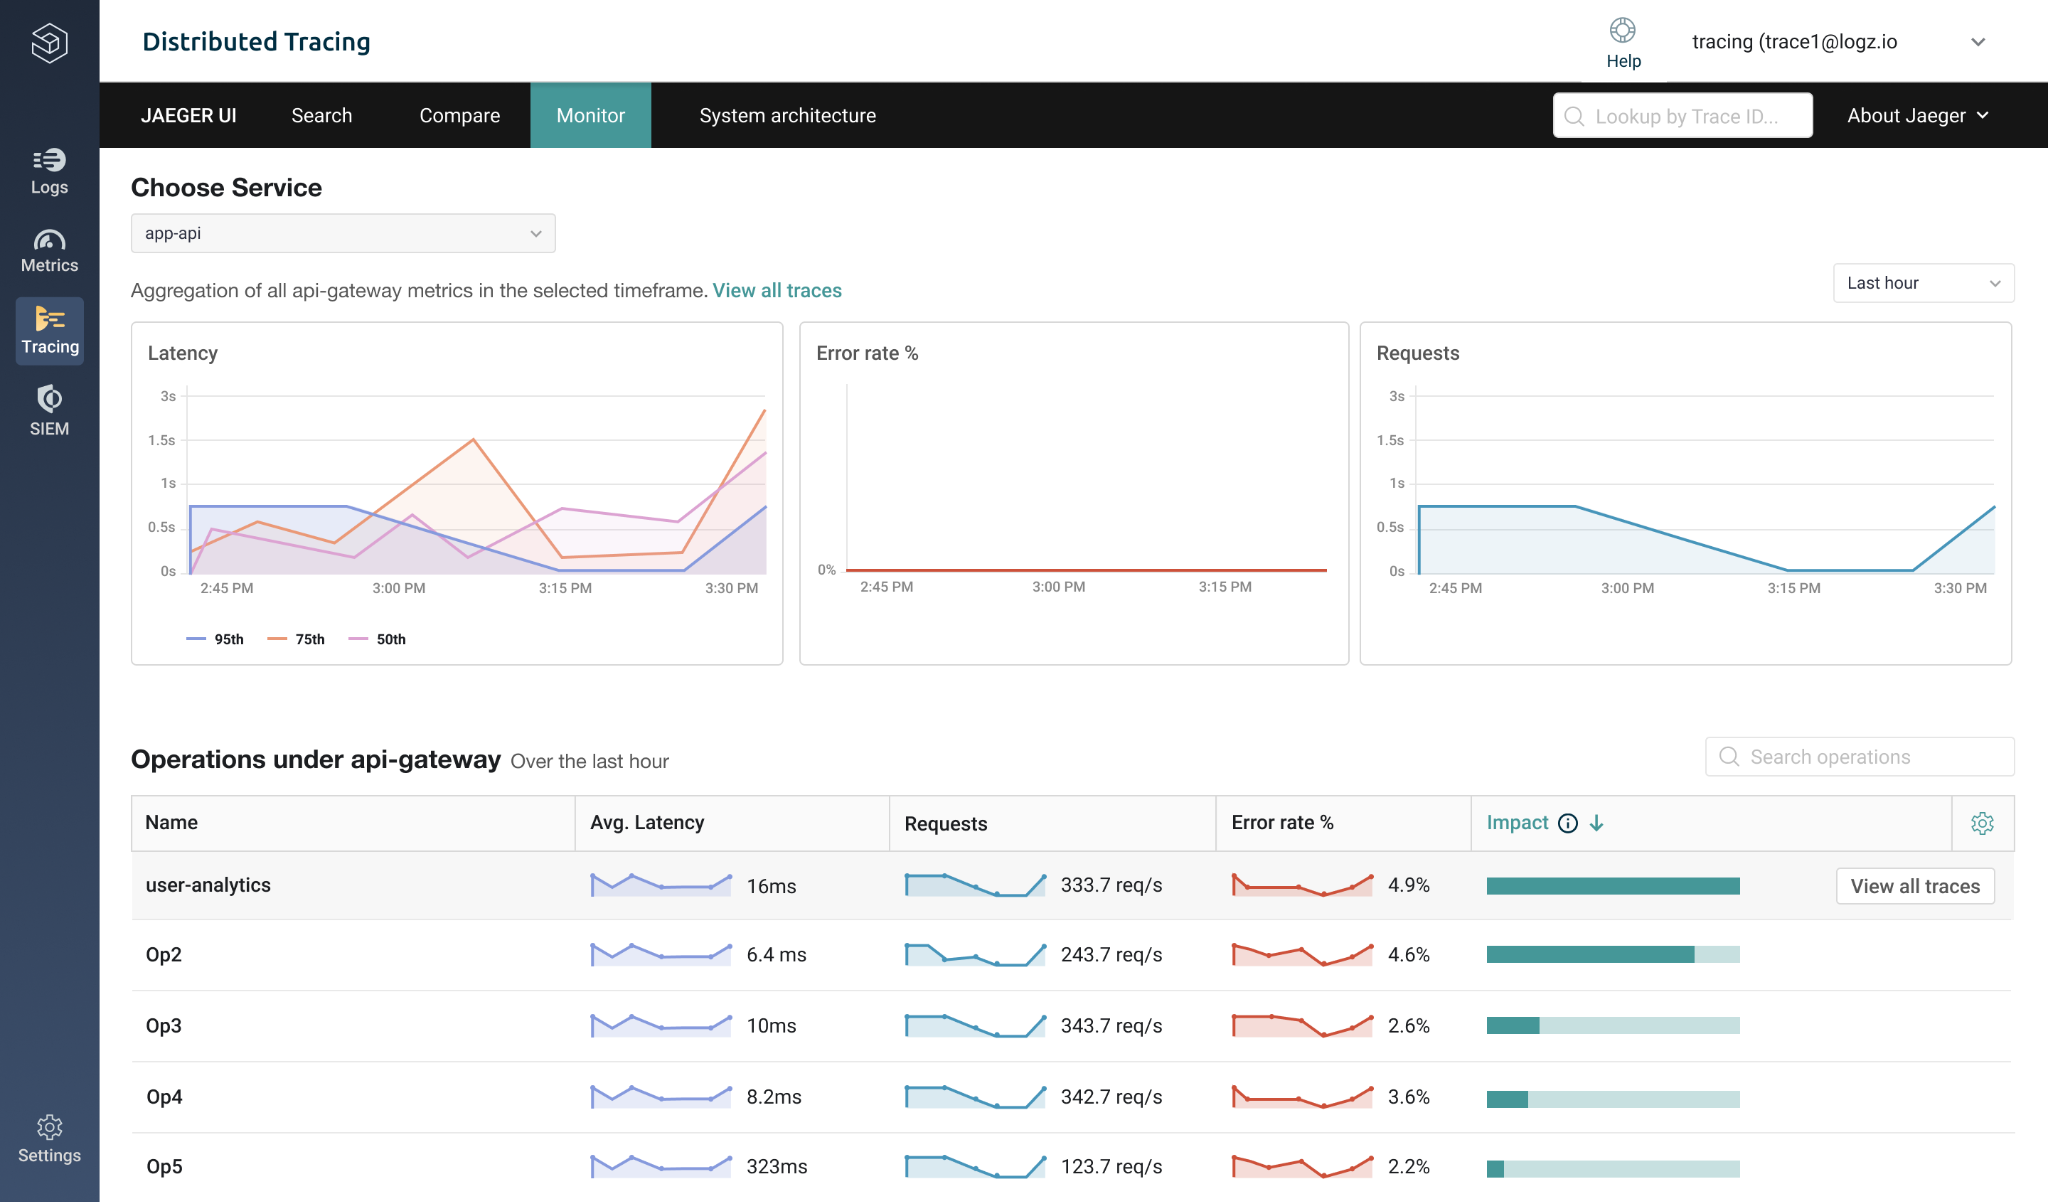
    Logz.io has enhanced its observability platform to include both unified dashboards and support for distributed tracing to monitor service performance enabled by the open source Jaeger agent software being advanced under the auspices of the Cloud Native Computing Foundation (CNCF).

    At the same time, Logz.io is making available a preview of an anomaly detection capability that leverages machine learning algorithms to build an artificial intelligence (AI) model to monitor data.

    The company has also added support for OpenSearch, a fork of the open source ElasticSearch software project that is no longer available via an Apache license. OpenSearch was created by Amazon Web Services (AWS) and Logz.io as an alternative search engine.

    Finally, Logz.io has added a security event management capability that makes it easier to classify, prioritize and collaborate on mitigation of cyberattacks as they are discovered.

    The Logz.io observability platform is entirely based on open source software. In addition, the company has made contributions to enhance both Jaeger and the OpenTelemetry project, including contributing an OTEL Span Metrics Processor that makes it easier to aggregate metrics.

    Logz.io CEO Tomer Levy said that, in general, it’s still early days as far as observability is concerned. As a concept, observability traces its lineage to linear dynamic systems. Observability at its most basic level measures how well internal states of a system can be inferred from knowledge of its external outputs. The overall goal is to make it easier to query machine data in a way that enables DevOps teams to proactively discover the root cause of issues before they cause further disruption. That’s a major advance over monitoring platforms that typically only provide predefined metrics to identify when a specific platform or application is performing within expectations. The issue, however, is most IT teams really don’t know what questions to ask to take full advantage of an observability platform, said Levy.

    However, as more organizations are exposed to observability platforms, it will become easier to advance both DevOps and DevSecOps as more platforms continue to leverage AI to provide remediation capabilities and automate processes based on the massive amounts of data collected via these platforms, said Levy. There is simply no way the average IT team will be able to manage all the microservices being strewn across a distributed computing environment without the aid of an AI model trained using observability data, he added.

    As DevOps continues to evolve, it’s more than likely that the best DevOps engineers are not going to want to work for organizations that have not invested in some form of observability. The odds of being consistently successful as a DevOps engineer decline sharply as IT environments become more complex.

    On the plus side, it should soon become a lot easier as the overall level of application instrumentation increases to manage those complex environments and to do so at a level of scale that doesn’t require a small army of DevOps engineers.

  • Top 10 DevOps Things to Be Thankful for in 2021

    Top 10 DevOps Things to Be Thankful for in 2021

    Thanksgiving has been observed in the U.S. since 1861 and was officially designated as an official holiday in 1863 by president Lincoln. Of course, the tradition itself traces its lineage to the early days of the Pilgrims.

    This past year, of course, has been one of recovery from a pandemic that caused the deaths of millions of people around the world. Vaccines have saved the lives of countless more, so there is much to be thankful for despite all our recent trials and tribulations. In that spirit, there are more than a few things for DevOps professionals, in particular, to be thankful for this year starting with:

    Digital business transformation: Organizations of all sizes have had to adjust their business models because of both major changes in buyer behavior and an ongoing supply chain crisis. DevOps teams are at the core of any major digital business transformation initiative, so the demand for DevOps expertise continues to outstrip the available supply. Going forward, it’s been predicted we’ll see more digital transformation in the next 10 years than in all the last 40 years combined. The vast majority of those initiatives would never see the light of day if it were not for the expertise of developers and engineers working hand-in-hand to build and deploy applications faster than ever.

    Low-code platforms: As the demand for applications to drive digital workflows spiked in the wake of the pandemic, professional developers relied more on low-code platforms to decrease the time required to build an application. While many complex applications will still be built using procedural code, it’s clear not nearly as many applications could have been deployed without relying on low-code platforms to build them. It remains to be seen how many of the next generations of low-code applications will be built by so-called citizen developers that may soon be flooding DevOps pipelines with application code.

    Microservices: As an architecture for building applications the core concept of employing loosely coupled services together to construct an application goes all the way back to when service-oriented applications (SOA) were expected to be the next big thing in the 1990s. Microservices have, of course, been around for several years themselves. However, with the rise of containers as a software artifact for building microservices, it’s only now becoming apparent that building an application constructed using microservices not only takes less time but is easier to maintain and also more resilient.

    Observability: As a concept, observability traces its lineage to linear dynamic systems. Observability in its most basic form measures how well the internal states of a system can be inferred based on knowledge of its external outputs. In the past year, a wide range of IT vendors introduced various types of observability platforms. These make it easier for DevOps teams to query machine data in a way that enables them to proactively discover the root cause of issues before they cause further disruption. That’s a major advance over monitoring platforms that typically only provide predefined metrics to identify when a specific platform or application is performing within expectations.

    Biden’s executive order: In the wake of a pernicious attack against IT service management software from SolarWinds, the Biden administration published a sweeping executive order that requires federal agencies to implement a wide range of security best practices. Foremost among them is guidance concerning the security of software supply chains; which resulted in many organizations reviewing their entire software supply chain to make sure similar breaches will not occur.

    DevSecOps: As an extension of any DevOps best practice, DevSecOps generally describes an overall shift left in terms of making developers more responsible for application security. While still in its relative infancy, DevSecOps is starting to gain traction as DevOps and cybersecurity teams look to bridge a cultural divide that is as wide as any in IT. The ultimate goal is to deliver more secure applications without reducing the speed at which they are being built and deployed.

    GitOps: At its core, GitOps is an operational framework that takes DevOps best practices used to automate application development and extends them to infrastructure. The basic idea is that the configuration software created to manage infrastructure-as-code is just another software artifact to be stored in a Git repository. The approach provides a means for IT teams to achieve a continuous delivery goal that, more than a decade after DevOps best practices were defined, remains elusive. It’s still early days as far as GitOps best practices are concerned, but this has been the year when GitOps become part of the mainstream DevOps conversation.

    Kubernetes: Simultaneously one the most powerful and most complex IT platforms ever to come down the proverbial enterprise IT pike, Kubernetes has emerged as a de facto standard for building and deploying container applications that can more efficiently scale up and down as required to consume IT infrastructure. The challenge (and the opportunity) now is to make Kubernetes much more accessible to mere mortal IT administrators that typically don’t have the programming skills of a site reliability engineer (SRE) and which are both hard to find and retain.

    GraphQL: Employed as a query language for application programming interfaces (APIs), GraphQL provides a more efficient means of accessing data than the REST APIs that have been employed by developers in the past. Originally developed by Facebook, GraphQL adoption is still in its infancy but it’s clear APIs based on GrapQL will one day be as plentiful as REST APIs. That’s especially critical for microservices-based applications that rely on APIs to access data across a highly distributed computing environment that requires a more efficient means for transferring data.

    Venture and Wall Street capital investments: Investment firms are helping fuel DevOps advances as they continue to make capital available for companies vying for their share of a market that is expected to see compound annual growth rates of 24.7% through 2026. There will, of course, eventually be a wave of consolidation as merger and acquisition activity inevitably ensues. In the meantime, however, there is a wide range of DevOps technologies that might not otherwise be as broadly adopted if it were not for all the cash being poured into DevOps companies.

    The most important thing, of course, is that so many DevOps professionals are still here to build and deploy applications. It’s been a trying year for all concerned; however, as the pandemic crisis continues to recede, we can all be thankful for the opportunities that lie ahead.

  • Ensuring Network Connectivity With SD-WAN and AIOps

    Ensuring Network Connectivity With SD-WAN and AIOps

    Recently, Facebook experienced an outage. If companies relied on that app to do business, their IT teams were likely swamped with end-user complaint calls. 

    How would teams traditionally respond? They’d dive deep into the rabbit hole, analyzing issues on a case-by-case basis, asking countless questions, including: 

    • Could there be a problem with the enterprise network?
    • Is the service provider experiencing issues?
    • Are just a few users affected or is the issue more systemic?

    Traditionally, this manual process requires significant knowledge sharing and time to complete as teams break the problem into smaller pieces to triangulate an issue’s root cause.

    Oftentimes, it’s an enterprise network that experiences connectivity issues—not apps like Facebook. 

    Some companies pay an arm and a leg to leverage highly reliable WAN links, such as MPLS, for connecting to the internet and connecting branches to their data centers. Conversely, they may save a buck or two by using commodity links, like cable or DSL, which deliver less reliability. Both choices introduce tough tradeoffs—could there be a better way to ensure enterprise-wide connectivity?

    Enter SD-WAN. 

    Combining the same service-level agreement (SLA) as a dependable WAN link with the affordability of a commodity link, SD-WAN specializes in handling brownout situations, rerouting link traffic to maintain network connectivity — ensuring users’ access to their must-have apps. 

    And by incorporating artificial intelligence for IT operations (AIOps), teams can harness the power of analytics to radically reduce their response time, ensuring that if problems do happen, they get fixed fast. In fact, 90% of IT professionals acknowledge that powering network management with AIOps will improve their companies’ business outcomes.

    Drowning in Data: Understanding Traditional Network Issue Investigation Headaches

    To determine the root cause of a service disruption, teams spend considerable time assessing the landscape of all the different apps that people use and the links they follow to use them. These apps could be located anywhere—forcing teams to find needles across vast haystacks of data to determine what went wrong.

    And this data is exploding at such an extraordinarily high rate that it’s practically impossible for anyone to keep track of it all. Only by leveraging an advanced analytics system like AIOps can teams gain the necessary insights to swiftly solve problems. 

    SD-WAN and AIOps: A Problem-Solving Dream Team

    How do SD-WAN and AIOps work together to enable a highly reliable, always-connected network?

    SD-WAN quickly addresses all potential local issues and optimizes performance and connectivity across multiple WAN links—or even just a single WAN link that may be unreliable. SD-WAN also ensures that business-critical apps are prioritized correctly and are offered the precise amount of error correction that avoids any issues or disruptions as much as possible over the WAN. 

    Where does AIOps come into play? It analyzes data at a far more granular level for extended periods over a global topology. What is it looking for? Everything. It’s examining emerging patterns that are impacting individual apps. It’s searching for systemic issues that affect multiple SD-WAN edge devices simultaneously, worldwide. It could also be investigating how edges or apps are being affected over a particular time period. 

    By surfacing all that data, AIOps analyzes much more than SD-WAN can. And by deriving insights from that data, it highlights issues affecting everything from a lone user on a single application to a systemic issue that’s impacting an app across a far broader cohort of users. In certain cases, AIOps can cue the SD-WAN to heal itself and automatically fix the problem, then verify that the issue was fixed. As a result, end-users remain connected to their network.

    Inside a Wholly Adopted SD-WAN/AIOps Environment

    Imagine you’re an IT admin, supporting an extremely complex enterprise network, spanning thousands of different sites that use diverse security services for connecting to apps. Even if you’re on a huge team that’s charged with monitoring the network, it would be nearly impossible to have full visibility across the network to solve problems as they occur.

    By adopting SD-WAN together with AIOps, you gain a superpower. No, you won’t be able to fly or become invisible, but AIOps will make you omniscient, enabling you to:

    • Harness powerful analytics firepower to find and fix network trouble spots instantly and precisely before users complain—in some cases before they even notice
    • Understand which sites perform better than others to pinpoint where improvements can be made
    • Propose configuration changes that help the network self-optimize and self-heal
    • Detect and optimize degraded links to boost user experience

    And if issues ever do arise, AIOps advises you immediately as it monitors the network 24/7, providing you with full situational awareness and insights, solving problems as they occur.

    SD-WAN & AIOps: Maintaining Connectivity by Self-Healing

    The Facebook event was unusual in that it globally impacted the world’s users, who couldn’t access the app through any Facebook data center. In that scenario, AIOps simply identified the app disruption and noted the root cause.

    But what if the situation had been different? For example, imagine if Facebook’s U.S. west coast datacenters were deemed unavailable but its east coast datacenters were operational. By combining SD-WAN with AIOps, a similarly affected company could have performed diagnosis and ensured app connectivity. 

    How could that have played out? 

    First, AIOps would have detected the issue and its root cause. It would have reported that the application was unreachable to users on the west coast but available to users on the east coast. Finally, SD-WAN would have self-healed by rerouting end-user application traffic to the eastern data centers to maintain app connectivity.

    Using the old-school method of manually monitoring and troubleshooting networks is nearly impossible for most IT teams. Instead, teams are relying on SD-WAN and AIOps. This combined capability gives teams an unbeatable superpower, enabling them to substantially improve connectivity across the enterprise and rapidly respond to issues as they occur.

  • Cortex Expands Microservices Catalog to Improve Collaboration

    Cortex Expands Microservices Catalog to Improve Collaboration

    Cortex, a provider of a catalog for tracking the ownership of microservices, today announced it has added a service creation capability that enables developers to use templates to scaffold new services in five minutes.

    In addition, the company has added a Cortex Teams offering that improves collaboration across teams of developers working on interdependent microservices.

    Fresh from raising an additional $2.5 million in funding, Cortex claimed it has increased its customer base by a factor of 10 since initially launching last May. Those customers include Rappi, Grammarly and 8×8.

    Cortex CTO Ganesh Datta said the company’s microservices catalog makes it simpler for teams of developers, DevOps engineers and security professionals to collaborate at a time when software development is becoming more complex. While microservices-based applications are easier to update and generally more resilient than monolithic applications, composing an application based on interdependent microservices created by different development teams can be more challenging to build and maintain.

    In some cases, organizations can even discover that different teams within their organization have built redundant microservices. Part of the reason that occurs is many IT teams still rely on spreadsheets to keep track of what microservices are being built and which ones are already deployed in a production environment.

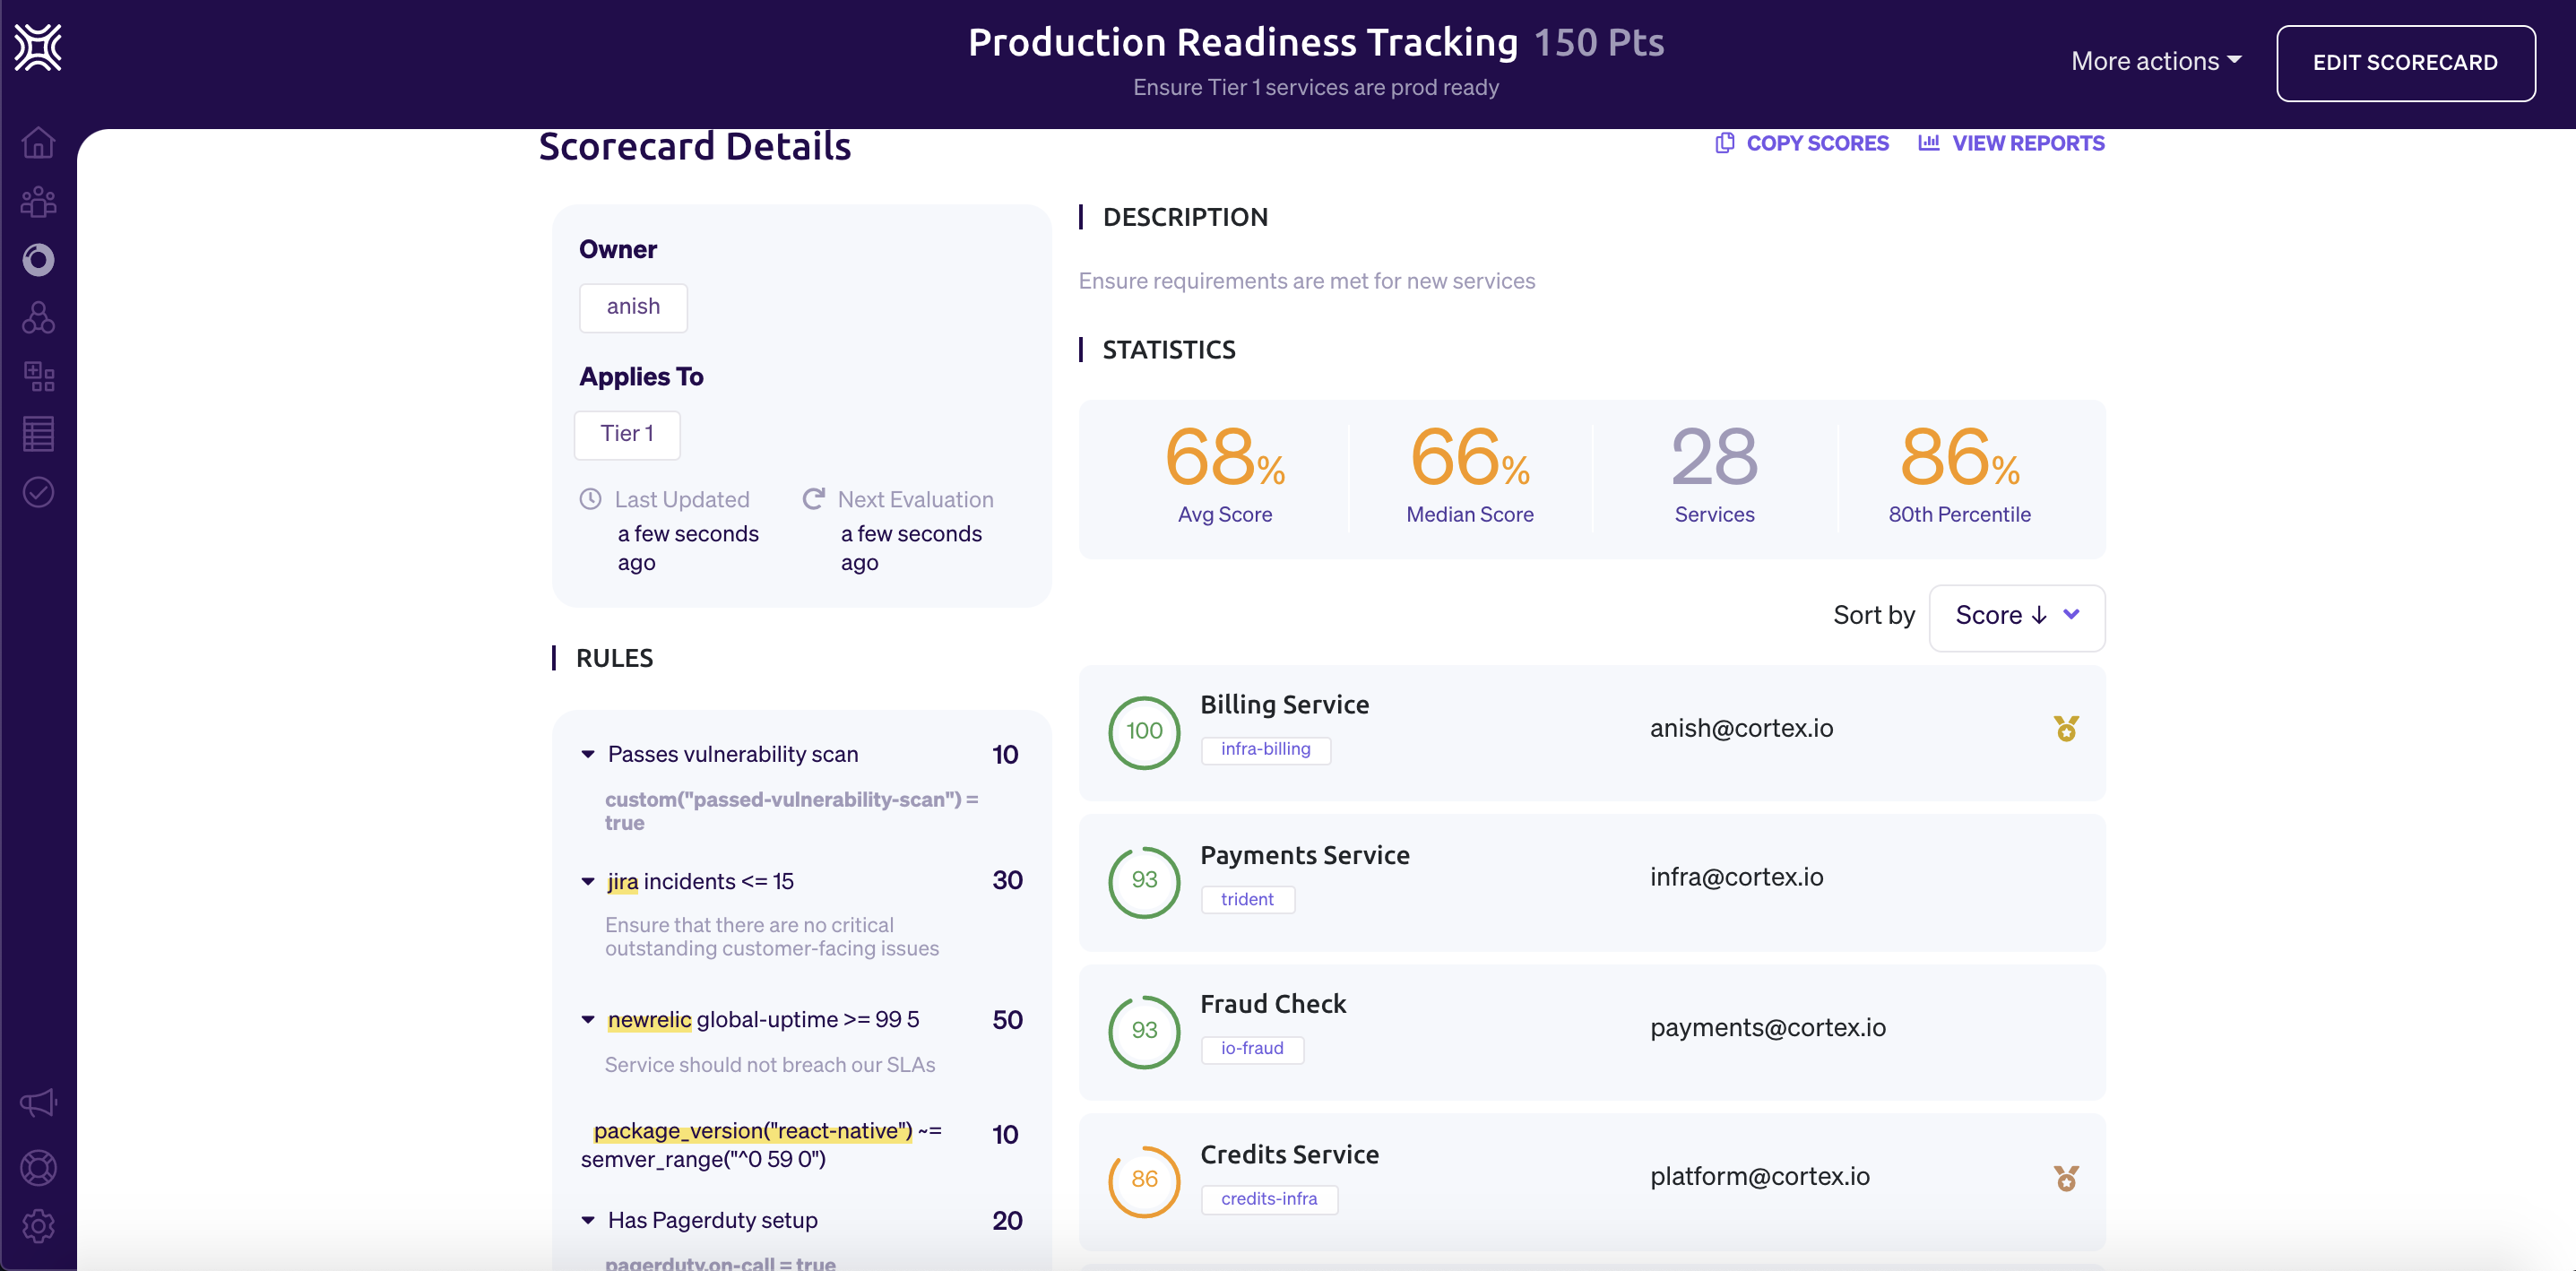
    Cortex, in contrast, automatically imports data residing in developer tools to surface who within an organization is responsible for maintaining which microservices. A Cortex dashboard also enables DevOps teams to see which developers are on-call in the event of an unexpected incident as well as monitor and track the latency rate microservices are experiencing and which vulnerabilities have yet to be remediated.

    At the core of the platform is Cortex Query Language (CQL), a domain-specific language that allows DevOps teams to define granular rules that can be applied to, for example, on-call rotations, security vulnerabilities, package versions, service level objectives (SLOs) and the overall health of the microservice. Engineers can employ code in the form of YAML files to set reliability standards across teams and types of services.

    Grades can also be assigned to specific microservices based on associated metrics. That approach allows DevOps teams to apply gamification techniques using a scorecard to encourage developers to continuously improve their microservices. That capability makes it apparent to other developers which microservices can be most reliably employed.

    It may be a while before microservices-based applications dominate the enterprise landscape. Monolithic applications will be running in production environments well into the next decade. However, many of those monolithic applications are essentially being converted into a larger microservice that other applications can invoke via application programming interfaces (APIs) before being eventually being re-engineered into a set of logically connected microservices.

    The one thing that is clear, however, is that as the number of microservices expands, it becomes more difficult to determine precisely what capabilities are already available to highly distributed application development teams.