Tag: ServiceNow

  • Bringing Trust and Governance to AI-Driven DevOps

    Bringing Trust and Governance to AI-Driven DevOps

    At swampUP 2025 in Napa Valley, Alan Shimel sat down with three industry leaders whose companies sit at the heart of today’s AI-driven DevOps transformation: Rahul Tripathi, general vice president and GM of ITSM at ServiceNow; Justin Boitano, vice president of enterprise AI at NVIDIA; and Shlomi Ben Haim, co-founder and CEO of JFrog.

    Tripathi, only months into his role at ServiceNow, stressed the importance of grounding product strategy in lived practitioner experience. Having led DevOps teams himself, he emphasized that ITSM remains the “bread and butter” of ServiceNow, but AI integration is reshaping expectations for productivity and security across IT operations.

    Boitano reflected on NVIDIA’s long journey from pushing CUDA adoption in 2008—when many thought GPU computing was a stretch—to today, where GPUs and AI frameworks have become central to enterprise computing. He noted that partnerships with companies like ServiceNow and JFrog are critical to building out the ecosystem, particularly as organizations look to infuse AI into every layer of their development lifecycle.

    Ben Haim underscored the urgency behind what he called “AI FOMO.” With board-level pressure driving 40% of CIOs to expand AI budgets, enterprises are rapidly embedding AI into software supply chains. For JFrog, that means positioning itself as the “system of record” for DevOps, launching new platforms like JFrog Fly to simplify AI agent adoption while strengthening governance, traceability and security.

    Together, the panel painted a picture of an industry balancing excitement with pragmatism. AI agents may not replace developers anytime soon, but they are already changing workflows, tooling expectations, and the economics of software delivery. As the panelists made clear, success will depend less on hype and more on how well organizations align AI adoption with trust, verification, and long-term resilience.

  • StarCoder2 LLMs Designed Specifically to Generate Code Arrive

    StarCoder2 LLMs Designed Specifically to Generate Code Arrive

    ServiceNow, Hugging Face and NVIDIA have once again combined their efforts to advance a generative artificial intelligence (AI) platform that has been specifically trained to generate higher quality code than rival approaches based on general-purpose large language models (LLMs) such as ChatGPT.

    StarCoder2 is a family of LLMs created by the BigCode community led by ServiceNow. Three iterations are starting now with a 3 billion‑parameter model trained by ServiceNow; a 7 billion‑parameter model was trained by Hugging Face, while NVIDIA built a 15 billion‑parameter model.

    The 3 billion‑parameter model is capable of matching the performance of the original StarCoder 15 billion‑parameter model.

    Nicolas Chapados, vice president of research for ServiceNow, said as AI research continues to advance, each successive wave of LLMs becomes more efficient. Each organization, depending on the use case and total cost, can then opt to deploy StarCoder LLMs either on a local machine or in the cloud. The more parameters an LLM has, the more infrastructure resources are needed to run any inference engine based on it.

    The StarCoder2 LLMs were trained using 619 programming languages and can be extended to, for example, provide summarizations of code. The foundation of StarCoder2 is a new code dataset called The Stack v2 that is more than seven times larger than version 1 of the dataset. In addition, additional training has enabled the model to understand low‑resource programming languages such as COBOL, mathematics and program source code discussions. Organizations can also fine‑tune models with industry or organization‑specific data using open source tools such as the NVIDIA NeMo platform or Hugging Face transform reinforcement learning (TRL) techniques. StarCoder2 was built using data under license from the digital commons of Software Heritage hosted by Inria.

    The overall goal is to provide development teams with LLMs that, in addition to being less likely to hallucinate, also generates code with much fewer vulnerabilities because the code generated is based on exampled vetted by the BigCode community, said Chapados.

    It’s not clear right now how much of the code finding its way into production environments is being generated by machines versus humans. However, as LLMs continue to advance, the percentage created by machines will undoubtedly increase. The challenge DevOps teams now face is determining how to apply AI to pipelines that will increase in number as codebases not only proliferate but also become inevitably larger.

    In the meantime, DevOps teams would be well-advised to become familiar with what type of LLM is being used to train the generative AI platforms being used to create code. The more general purpose an LLM is, the more likely it is to generate suboptimal code that DevOps teams are only going to need to eventually replace, especially if that code is consuming expensive infrastructure resources inefficiently.

    There is, of course, as far as generative AI is concerned, no going back at this point. The issue now is determining how to keep track of the provenance of all the code being generated to determine how best to fix it whenever needed.

  • Identify Needs First

    Identify Needs First

    In several projects of late, I have noted a trend in otherwise rockstar IT departments: They identify an area that they wish to implement or approve and then set out to address it. So, “We need a new CI tool,” spawns a project to choose and implement a new CI tool, for example.

    But there are so many details that these projects are missing from the start that should have been put right into the charter/project kickoff documents.

    Let’s start with, “What CI tools do we currently have in place?” This is the 2020s. How is it possible we are still starting these projects as if there was no solution in the virtual building already doing the job? We need to start from, “Here are the tools that can do this job that are currently running in our environment.” Only then should we move on to, “Here are other options to consider.” But I will humbly suggest that if there is a single tool that can solve your issues, it should be used–and if, of all of the tools running in the organization, none of them can solve all of your issues, then a new product should be chosen that can.

    The same is true for things like alerting. When I am analyzing a given vendor’s solutions, I ask about how many places they can raise issues–it is important that a vendor asking you to purchase their product can report and alert to whereever the organization needs it to. So that could mean Jira or ServiceNow, Slack or email, centralized logging—all of the above and sometimes more (SIEM for security events, for example) need to be supported. But when a given organization is implementing? Choose a reporting method.

    The most common is, “We do Slack, but we also do email. And, of course, we coordinate though issue management like Jira …” Stop. Seriously. This is not about, “Oh, they made it easy, so we just implemented every option.” This is about, “We need to keep track of conversations and resolutions.” If two people are discussing an issue over Slack while a separate team is discussing over email, you’re failing to communicate. Even if there is linkage to ServiceNow or Jira and that is where conversations should happen, we all know that final resolution—but not troubleshooting steps—is what ends up there. So offer one robust and widely available alerting mechanism and let people run with it.

    That type of redundancy is all over IT. Organizations that would not implement per-team email solutions (not servers, solutions) will happily allow for per-team DevOps toolchains. Why? What, exactly, is different? The purpose of a mail server is to deliver mail. Choosing which mail vendor/service to run with is based upon how a given product does so and what additional services come with it. How is that different than, “The purpose of the DevOps toolchain is to deliver applications, and selection is based upon what vendor/product best serves the way our organization does so?” There isn’t a difference; we imagine one. We latch on to one feature that we must have to keep our current favorite, and the compromise is that the next team over can keep their tools, too, because they must have some other feature.

    Evaluate what the organization as a whole needs, identify tricky bits like must-have features and determine if that really is a requirement. If it is, ask why it isn’t a requirement for every project not using that tool.

    And keep moving those apps along! You are building and deploying more apps more securely than ever before. Continue to sanitize the build and delivery process, and continue to crank out apps that make the business hum. But don’t make it part of your job to support fifteen tools that all do the same job. Streamline and improve. And keep rocking it.

  • ServiceNow Adds Observability Platform to SaaS Portfolio

    ServiceNow Adds Observability Platform to SaaS Portfolio

    At its Knowledge 2023 conference, ServiceNow launched an observability service that runs on its software-as-a-service (SaaS) platform.

    Based on the observability platform the company gained with its acquisition of Lightstep, the ServiceNow Cloud Observability platform makes it possible to collect and analyze data collected from software running on infrastructure and also from workflows created using ServiceNow applications.

    Pablo Stern, senior vice president and general manager for technology workflows products at ServiceNow, said the goal is to make it simpler to investigate IT issues involving applications and workflows that have multiple dependencies. That makes it possible to quickly diagnose an issue, determine the root cause and then dispatch the right site reliability engineering (SRE) team to troubleshoot it, he added.

    ServiceNow Cloud Observability uses both open source OpenTelemety agent software to collect logs, metrics and traces in addition to a log management tool that ServiceNow gained last year with its acquisition of Era Software.

    In addition, ServiceNow is employing a Service Graph Connector that makes it simpler to pull data from, for example, OpenTelemetry and Kubernetes clusters into the ServiceNow IT Operations Management (ITOM) without requiring any additional tooling. ServiceNow is also making available its Unified Query Language to make it possible for IT teams to query the data residing in ServiceNow Cloud Observability.

    As application environments become more complex, the need for entire IT teams to have access to an observability platform is growing. While observability has always been a core tenet of DevOps best practices, Stern said it’s clear that these capabilities also need to be made available to IT administrators. In fact, as observability becomes more democratized, it will drive the rise of services operations that will enable IT teams to be better aligned around specific processes, he added.

    Most IT organizations today employ a wide range of tools that enable them to monitor a set of pre-defined metrics. Observability platforms, in contrast, enable IT teams to collect data from systems in a way that can be investigated using a query tool.

    It’s still early days as far as the adoption of observability platforms is concerned, but as the collection of logs, metrics and traces becomes more unified, an opportunity to better converge IT practices based on DevOps principles and the ITIL framework that many IT administrators rely on to manage IT will emerge.

    The challenge, regardless of what methodology is used, is that IT teams need to be able to frame the queries they use to discover the root cause of an IT issue before any potential disruption occurs. In the long term, however, it’s expected that machine learning algorithms will leverage the data collected by observability platforms to automatically identify those issues.

    Regardless of how an IT issue arises, the metric that matters most is how quickly it can be resolved—no matter who in the IT team is tasked with resolving it. The issue is finding a way to provide IT teams with better tools to achieve that goal.

  • Five Great DevOps Job Opportunities

    Five Great DevOps Job Opportunities

    devopsy.kinsta.cloud is now providing a weekly DevOps jobs report through which opportunities for DevOps professionals will be highlighted to better serve our audience.

    Our goal in these challenging economic times is to make it easier for DevOps professionals to advance their careers.

    Of course, the pool of available DevOps talent is still relatively constrained, so when one DevOps professional takes on a new role it tends to create an opportunity for others.

    The five job postings shared this week are selected based on the company looking to hire, the vertical industry segment and, naturally, the pay scale being offered.

    We’re also committed to providing additional insights into the state of the DevOps job market. In the meantime, for your consideration:

    LinkedIn

    SiriusXM
    Associate Director for Software Delivery
    Deerfield Beach, Florida
    $157,000 or $250,000

    SimplyHired

    Nagarro
    Remote
    Senior Staff Engineer – DevOps
    $155,000 to $196,000

    Dice.com

    Engage Partners
    Davie, Florida
    DevOps Architect
    $130,000 to $160,000

    Indeed.com

    ServiceNow
    Orlando, Florida
    Staff DevSecOps Engineer
    $114,000 to $144,000

    Monster.com

    Swift Group
    Fort Belvoir, Virginia
    DevOps Engineer
    $80,000 to $180,000

  • ServiceNow Acquires Era Software to Unify Observability

    ServiceNow Acquires Era Software to Unify Observability

    ServiceNow today announced it has agreed to acquire Era Software as part of an effort to add support for log data to the Lightstep observability platform the company acquired last year.

    Ben Sigelman, general manager for the Lightstep business unit at ServiceNow, said rather than reinventing the same log management capability that Era Software already has, it makes more sense to integrate that capability with the Lightstep platform that collects metrics and traces.

    The integration of those two platforms will then make it possible to unify observability rather than requiring DevOps teams to navigate two separate silos, he added.

    As observability continues to evolve and mature, the most immediate goal is to make it simpler to navigate the alert storm that inevitably ensues any time there is a disruption, said Sigelman. The alert storms generally occur after there has been a change made, but unraveling how exactly that change impacted an IT environment is challenging, he noted.

    An observability platform reduces the time and effort necessary to achieve that goal by surfacing a set of statistics that guide DevOps teams through that process, added Sigelman. The challenge, of course, has always been finding an efficient means of storing all the telemetry data that’s generated. In fact, as organizations start to deploy microservices-based cloud-native applications, many of them are starting to see the amount of telemetry data increase exponentially.

    Era Software uses an object storage system to index and analyze log data collected from cloud applications, Kubernetes and IT infrastructure platforms. The company has also made available in beta an Era Streams tool that reduces the volume of observability data collected without sacrificing fidelity by dynamically reconfiguring data pipelines in real-time.

    Once the acquisition is completed, log data analytics will then be shared with the IT service management (ITSM) tools that ServiceNow provides alongside the Lightstep observability platform. The goal is to make it easier to correlate those IT events with their potential impact on the business, said Sigelman.

    Era Software CEO Todd Persen said the long-term 10-year goal is to get to the point where issues are both automatically detected and remediated. In the meantime, the amount of context switching that IT teams encounter can be sharply reduced via a unified observability platform.

    There is, of course, no shortage of unified observability platforms these days. DevOps teams have also been relying on legacy monitoring tools that track specific metrics for years. The issue is that those legacy monitoring tools only track a narrow range of pre-determined metrics. As IT environments become more complex, the need to launch more open-ended queries to determine the root cause of IT disruption has become more pronounced.

    It may be some time before observability platforms are widely adopted, but the need for them is generally apparent to anyone managing a modern IT environment. Less clear is the degree to which observability platforms will remove the need for legacy monitoring tools; however, right now the focus should be on gaining as much visibility and transparency as possible into what are still opaque IT environments.

  • Lightstep Extending Beyond Observability with Lightstep Incident Response – Techstrong TV

    Lightstep Extending Beyond Observability with Lightstep Incident Response – Techstrong TV

    Ben Sigelman and RJ Jainendra discuss ServiceNow’s latest announcement that Lightstep is extending beyond observability and creating a differentiated portfolio for app development with the general availability of Lightstep Incident Response, helping make organizations’ digital products and services more reliable and resilient. The video is below followed by a transcript of the conversation.

    Alan Shimel: Hey, everyone. Welcome to Techstrong TV’s segment today. We’ve got some breaking news I wanna bring to you, and I’m really happy to be joined by two gentlemen who are gonna tell you the news. I’ve had the pleasure of having them on before.

    They’re two really bright guys from ServiceNow. Let me introduce you to Ben Sigelman and RJ Jainendra from ServiceNow. RJ, I think I left out an “N” somewhere in that second or third syllable, but we’ll let you correct it. I’m gonna ask you to go first, RJ. Introduce yourself to the audience.

    RJ Jainendra: Hey, Alan, good to see you again. And no, you got it right, RJ Jainendra. I’m a VP and GM at ServiceNow, unlocking product growth at the company. It’s great to be here.

    Alan Shimel: Excellent. It’s good to see you again. And of course, RJ, you’re general manager, but you’re the portfolio you are GM with includes observability. I believe it includes value stream as well, yeah?

    RJ Jainendra: So, ServiceNow does have offerings for value stream management, which brings together a number of different product lines. Our IT business management, which we recently rebranded as Service Portfolio Management, SPM, that’s one. The second is it also brings in elements from devops and ITSM offerings to provide a value stream management.

    But I’m here today to talk about Lightstep Incident Response. That’s the product line that we’ve been building out for a little while now, and ready to launch here today.

    Alan Shimel: Absolutely, so, we’re gonna talk about Lightstep. Gotta have Ben here. Ben, welcome. Why don’t you give people a little bit of – give the folks a little bit of your background?

    Ben Sigelman: Yeah, thanks, Alan, for having us. So, I’m Ben Sigelman. I was one of the cofounders at Lightstep and was the CEO up through last year, when we were acquired. ServiceNow wasn’t willing to let me remain the CEO of ServiceNow after the acquisition, so now I’m also a VP and GM, along with RJ. 

    Lightstep’s brand and certainly our products and many aspects of our culture have actually been intentionally retained as part of the acquisition, and the brand has actually been expanded to be a multi-product brand, which is what we’re talking about today.

    Most of my day-to-day is spent doing a combination of thinking about the product vision for observability specifically within Lightstep as well as the longer-term strategy within ServiceNow, and what we can do for our customers by unifying the world of ServiceNow with the world of high-volume customer-facing applications that Lightstep tends to play in.

    Alan Shimel: Absolutely. I think the ServiceNow team already has a pretty good guy in its CEO, but hey.

    Ben Sigelman: I actually, when I talked to Bill during the acquisition, I told him he had my condolences for being a CEO of a much larger company. I knew how stressful it was for Lightstep, so I can only imagine what it’s like for him. But he’s a fantastic guy.

    Alan Shimel: Absolutely. Yes, until you’ve been a CEO, and I don’t care whether it’s a really, really big company or a really small company, yeah, it’s a lot. Anyway, guys, let’s talk Lightstep, observability. Let’s talk about the expansion. Just to level-set things – you both referenced it – Lightstep was one of the leaders in this observability revolution or wave that we saw overtake the industry, let’s say, in the last three, four years, certainly, it really caught fire.

    Lightstep, Ben and your two cofounders, I believe, all came from Google, and really in many ways helped initiate the whole observability revolution there. Then leveraging open source and working with open source, open telemetry, et cetera, really built quite a community and following.

    ServiceNow, one of the most dynamic companies in our industry, recognized this and made Lightstep and observability an important part of the ServiceNow offering. But from what I’m hearing and reading between the lines is why stop there, right? There’s more.

    There’s more that the marriage of ServiceNow’s know-how market intelligence and skill set, and the Lightstep platform can do more, and today marks a significant expansion of that. So, you’re both GMs. Who wants to go first to talk about what this new expansion is?

    RJ Jainendra: So, I can talk a little bit about what the expansion is, and Ben can, I think talk through why it makes a ton of sense, what we’re doing. The thing that we see that’s happening in the market is just the amount of investment going into what’s been called digital transformation.

    It’s just increasing significantly, and I think by some accounts, IDC forecast, it’s gonna be something like north of $10 trillion cumulative by 2025. So what Marc Andreessen said a long time ago, I think it has come to pass, which is every company is a software company, and increasingly, with the adoption of cloud, organizations are prioritizing cloud operations and software development teams they build, and they run these millions of new customer-facing, revenue-generating applications and services.

    So from that perspective, the SREs and developers who really are responsible for keeping applications reliable and resilient, they really start impacting the business outcome. That’s where if you have incidents that occur, maybe it’s a bug or some sort of an outage or poor performance, it has a major impact on revenue, on customer loyalty, on the brand perception.

    That’s why you see the option in the market to introduce a new offering around incident response, which really leverages the power of the ServiceNow platform, but then it brings together the observability capabilities that Lightstep has into sort of a holistic offering that we can bring into market to help customers become more proactive and more effective in addressing issues. Ben, do you wanna add to that in terms of your perspective from an observability side?

    Ben Sigelman: Yeah, for sure. I think the way I’d explain it is observability, Alan, I would agree with you that it’s the wave, but it’s a very confusing, diffuse – it’s a body of water right now that can be hard to wrap your head around, and you frankly have a lot of what I would call legacy observability companies trying to take what they have and call it observability, because that’s easier than reforming it.

    So, it might be helpful to spend just one very quick, 30 second snippet talking about what observability actually is, architecturally. You have some layer at the bottom of integrations and data acquisition. You mentioned Open Telemetry earlier. The Lightstep Incident Response product that we’re announcing today also has an integration ecosystem built around it.

    But you have the acquisition of data, you have some kind of data platform where you store that, which I’m not gonna talk about in detail right now but I think is an interesting topic, slightly far afield. Then you have workflow been made with your full knowledge and workflow built on top of that, and that’s where the actual value is delivered.

    A lot of the conversation around observability today is that you have a silo for your metric system, a silo for your logging system. Maybe you tack on some kind of tracing or PM system, and then you integrate them in the browser.

    Then you also have this Incident Response thing over there. That’s some other vendor, and it does not make any sense. When we talked with our customers, the three things they are prioritizing are overall performance, velocity, and actually, most importantly, incident response and timed resolution.

    It’s the most important thing for observability. Then you have not just a separate tab, but a separate product to do incident management and incident response, which is not sensible from a workflow standpoint.

    So, for the brand, this is a very obvious and natural thing, to have incident response and observability integrated into a single experience, especially incident response where seconds matter, and a context switch like that is very expensive. So, anyway, that’s why this makes a ton of sense to us.

    It goes right at the heart of the MPTR problem, to have a single platform to manage the full lifecycle of incident management on the observability side and on the incident response side.

    Alan Shimel: Absolutely, and you know, Ben, to your point – well, first of all, I think you call them “legacy observability vendors.” Really, they’re APM, application performance management vendors who – 

    Ben Sigelman: Or infrastructure monitoring vendors, more to the point.

    Alan Shimel: Right, or infrastructure – 

    Ben Sigelman: It’s not the –

    Alan Shimel: You know, everyone loves a good name.

    Ben Sigelman: Right.

    Alan Shimel: A company I had started, we had come out with a product that Gartner would later name the category NAC, network access control. We had some stupid name for it before, but Gartner, you know, did that.

    All of a sudden, out of the woodwork, all these people who were doing totally different things started calling what they do NAC. A very similar thing happened with observability, right?

    Ben Sigelman: Yeah.

    Alan Shimel: Anyone who’s doing monitoring, all of a sudden it was observability. But I think, also to your point, was that observability got siloed into just observing. Almost by definition, observing, observability, is not actionable. It’s almost like observability is a passive word, where actionable is active word.

    Ben Sigelman: You’re exactly – that’s a very good point. If you go – I tend to be a little academic, but I think this is an interesting point. Observability really originates from control theory in the 1960s, and it was this smaller, kind of lesser cousin to controllability, which is kind of what you’re talking about.

    Controllability is really the thing that matters. If you can control a system, there are scientific ways of talking about that. Mathematical ways talking about that. To a certain extent, you can think of incident response as being the controllability side of what we’re talking about here.

    It’s like we’re making insights from observability actionable with the Incidence Response product, and that’s a really important part of actually closing the loop on the control theory of modern distributed systems. That’s a great insight that you’re making, Alan.

    Alan Shimel: Yep, thank you. Every once in a while, even a blind squirrel finds something, right? So, RJ, let’s talk about this. ServiceNow is not a trivial size company. To decide that – you didn’t really have an incident response solution in market prior to this, as far as I know. I’m not an expert on everything ServiceNow, but I’m not aware of it.

    To say okay, we are going to build this in as the logical next step in the Lightstep platform, just the inertia sometimes in an organization your size, it’s difficult. Let’s hear from your point of view what it took to make that happen, turn that ship.

    RJ Jainendra: Yeah, so, Alan, we actually do have capabilities in the ServiceNow platform through our IT Service Management and IT Operation Management products, around things like event technology around event correlation, being able to take large-scale number of events from the observability tools and bring them in and understand what those events mean.

    We also do have functionality in ITSM around notifying the right person. But really, the ServiceNow technology, we have great adoption with IT organizations and a large number of customers. But what we’re seeing really is as our customers are going through the digital transformation, they’re reorganizing, and the product teams that are out there are the ones that are sent to adopt these technologies on observability. 

    That’s why we felt that we wanted to bring an offering into market that could be adopted by teams. So, the entire experience for Lightstep Incident Response is as a modern SaaS application. If you’re a developer on the team – and what we’re finding right now is a lot of our initial customers are smaller companies.

    They’re early growth-stage companies that are post-revenue. They have customers, they wanna make sure that their systems are highly available for them. So, what we’re finding is that they can come online, they can sign up, and within a few seconds get access to the system, start using it, and if they see value, then they can swipe the credit card and they’re off to the races.

    So, very much a different motion, really suited to how teams out there in smaller companies are adopting technology. And of course, the startups of today are the ones that become the unique ones tomorrow, so that’s what we’re doing that’s a little bit different. But for ServiceNow customers, they need to have those capabilities within the ServiceNow platform.

    Alan Shimel: Excellent. So, guys, let’s talk – if you don’t mind, I gotta do a little meat-and-potatoes here. You guys announced this today. Is it available? When will it be available?

    RJ Jainendra: It is available today on Lightstep.com. So, we have had the product in the market for a little bit. We did a soft launch earlier last year. So, it’s been battle-tested, and we have a number of customers that have come online. They’re using it in production. So, it is available today, and it doesn’t take more than an email to sign up and get going.

    Alan Shimel: What’s the offering? How is it priced? If you’re an existing Lightstep or ServiceNow customer, how do you – firing off an email, yeah, but how do I – what’s this gonna set – you know, what’s involved here?

    RJ Jainendra: Yep, so, actually, it isn’t a whole lot more complicated than what I just said, which is just as you sign up for a lot of consumer-type services online, developers and SREs can get started with an email. We do have a couple of different tiers. So, we do have a free tier, where if you are just getting started and you may have just a couple of services that you’re monitoring and addressing issues for with Incident Management, that’s free.

    Now, if you’re gonna start scaling up and you have more than two, that’s when the pricing kicks in. We are taking an innovative approach in terms of pricing, which is it’s based on usage. So, we look at the number of active services that a team has, and then we charge by the number of active services, which is very different than some of the other solutions in the market, which charge by the number of developers that you have in the system.

    We really think that we wanna align to the value that our customers are trying to deliver, which at the end of the day, if you’re a developer or if you’re an SRE, your goal is to deliver these resilient, reliable services. So, we feel that aligning to the services – and no matter whether you wanna bring in your whole team or maybe you also wanna bring in sort of extended folks into the solution to be able to collaborate and figure out what the problem is.

    So, we don’t wanna let the number of seats become an impediment. We really would like to have our customers drive this notion of service ownership across the entire team, as opposed to being owned by a few key people, because there’s a lot of burnout that happens.

    So, there’s different models, but after a 30-day free trial, if customers see value and they have these active services, that’s when the billing kicks in. It’s all done by credit card, so it’s a fairly streamlined experience.

    Ben Sigelman: I will add that Lightstep observability experimented with seat-pricing several years ago and abandoned it, because it’s very important for us to deliver value to our customers, and there’s nothing quite as frustrating as hearing people say, oh, we really wanna be using this, but we don’t wanna add another seat license and blah, blah, blah.

    I think especially in large organizations, for incident response, it’s just immensely frustrating to be kind of wanting to use something, like, sporadically, maybe once every couple of months, and then being blocked out of the application because of concerns over seat licensing.

    So, with Lightstep Incident Response, there’s really no restriction on that. You can have a thousand-head engineering organization and put them into the product, and that doesn’t change your bill at all. The pricing is more correlated to the value that we believe we’re delivering, and the resiliency of the services themselves.

    Alan Shimel: Sure. So, I’ve gotta ask the question. I’m gonna ask it of you, Ben. This is a step of taking observability down the control, as you mentioned, the control path, for full control. What’s next?

    Ben Sigelman: That’s a good question. We’re gonna move into crypto. No, I’m just kidding, we’re not.

    RJ Jainendra: Join the crowd, yeah.

    Ben Sigelman: I’m not here to talk about specific products, but directionally for Lightstep as a brand, I think that we see there’s an entire ecosystem out there of – I think you can kind of extrapolate from where I was going with the workflows.

    I think where we – actually, Lightstep and ServiceNow are incredibly similar in our belief in workflows being paramount, and there are a number of other workflows where people have to do a major context switch when they’re involved with the work of making reliability and velocity happen for cloud-native applications and for customer-facing applications. That’s kind of a hint as to, I think, where we’re headed with future products. But this certainly isn’t the last one yeah.

    Alan Shimel: Great. Guys, we’re way past 15 minutes, but for people who wanna go get Lightstep and Lightstep observability up and running today, where do they go?

    RJ Jainendra: www.Lightstep.com.

    Alan Shimel: That’s what I was looking for, RJ. Hey, gentlemen – Ben, RJ – thanks so much for coming on and breaking this exciting news and offering, new offering from the Lightstep/ServiceNow team. Keep us posted, best of luck with it. It sounds like a winner. We hope to hear more soon.

    RJ Jainendra: Thanks, Alan.

    Ben Sigelman: Thank you, Alan.

    Alan Shimel: Thank you, guys. All right, go check it out, Lightstep.com, their new observability and incident response now as part of it, from ServiceNow. We’re gonna take a break. We’ll be right back.

  • ServiceNow Adds Lightstep Notebooks to Visualize Observability Data

    ServiceNow Adds Lightstep Notebooks to Visualize Observability Data

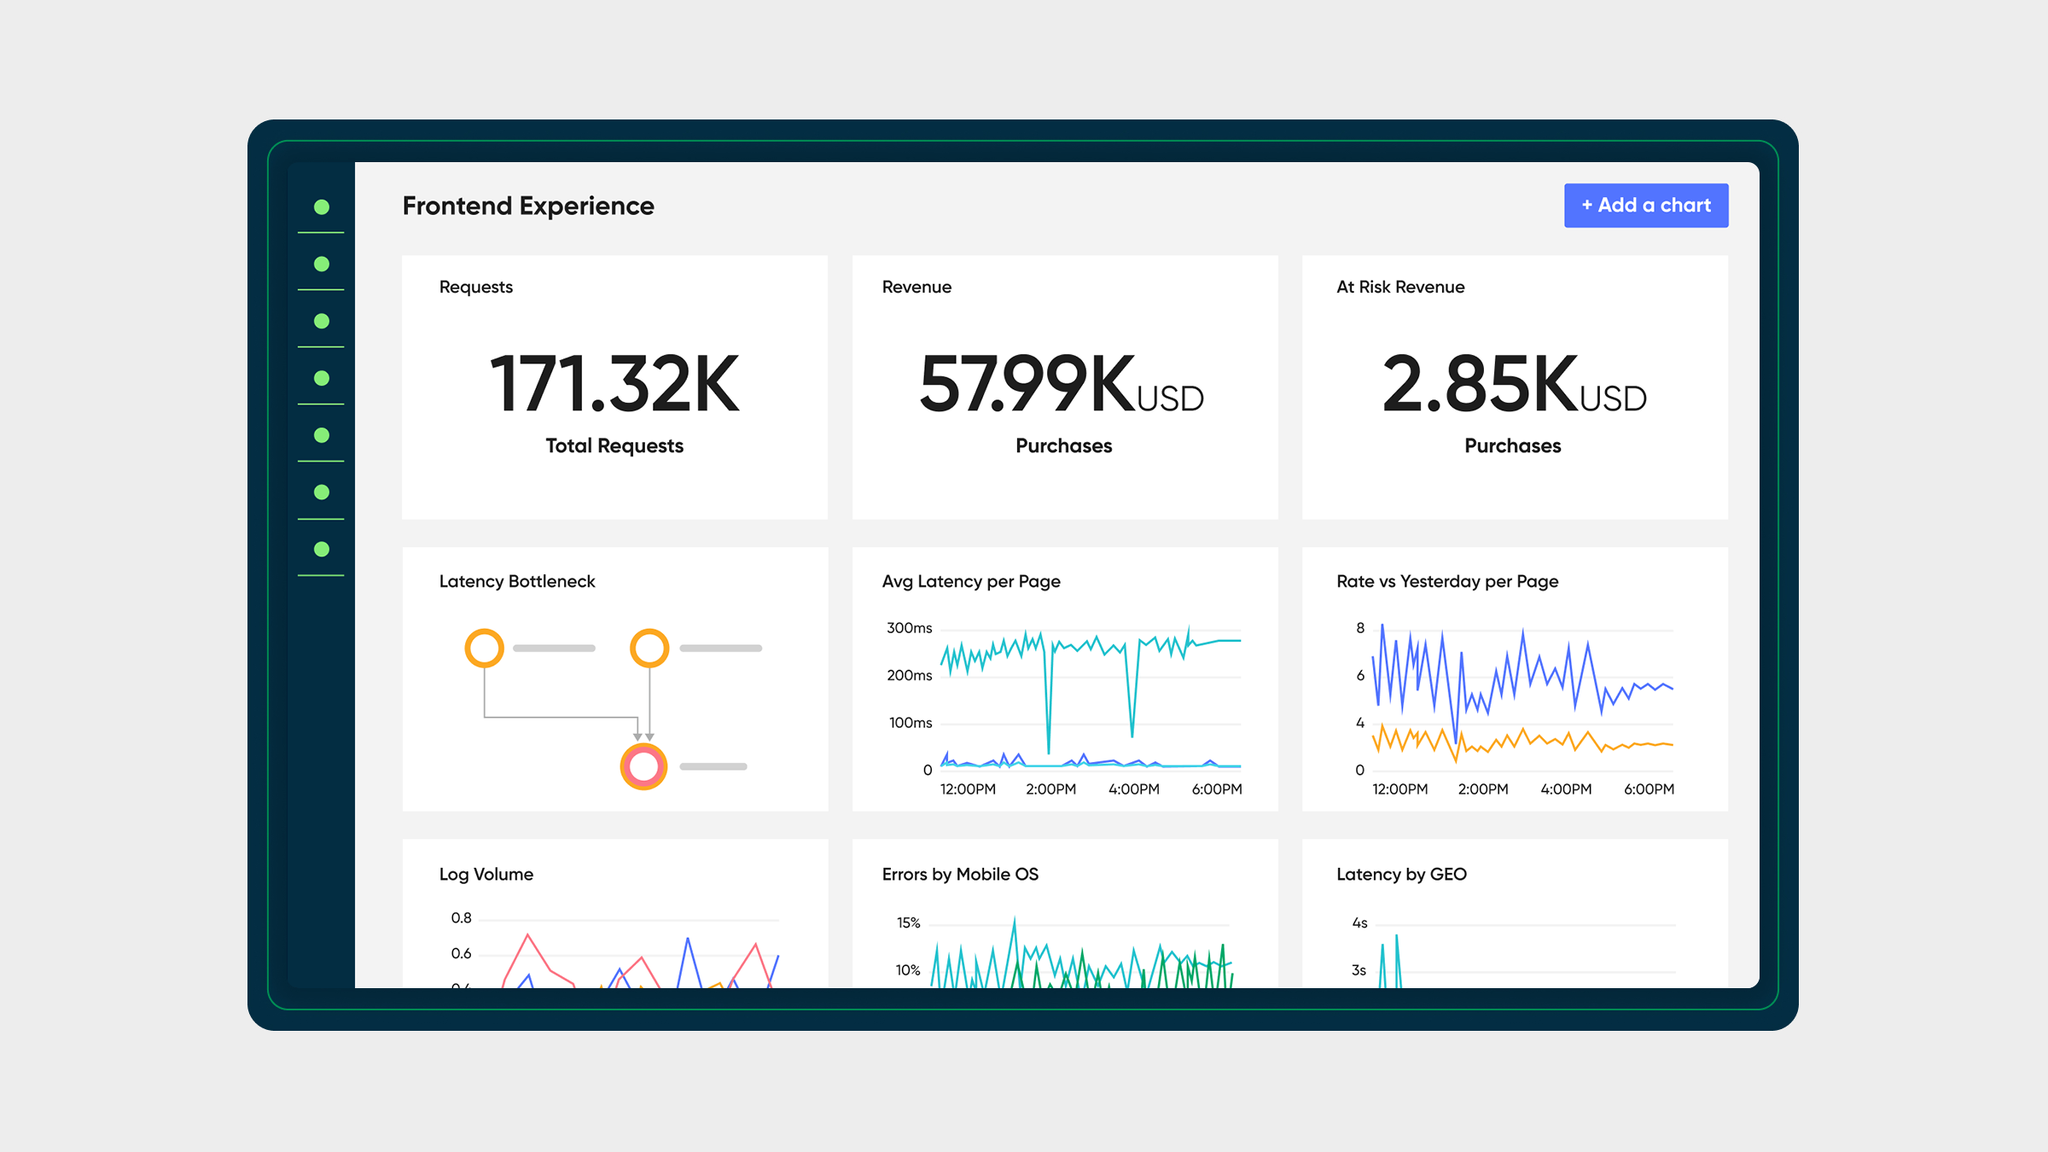
    ServiceNow today added a visualization tool to its Lightstep observability platform that will make it simpler for DevOps teams to correlate metrics, logs and traces.

    Ben Sigelman, general manager for Lightstep at ServiceNow, said Lightstep Notebooks will make it easier for DevOps teams to make sense of the massive amounts of data collected by the observability platform.

    Lightstep Notebooks is an extension of the Change Intelligence analysis engine that ServiceNow already makes available within an observability platform it acquired in 2021.

    Included with Lightstep Notebooks are a set of ad hoc charts that include access to heat maps and time-series data with trace exemplars using the database at the core of the Lightstep observability platform.

    An instantly generated investigative path also makes it simpler to identify the root cause of any issue, and each instance of Lightstep Notebooks can be shared with other members of the IT organization via an embedded link. Finally, 100% of trace data can be retained for up to three days.

    Sigelman said the ability to share Notebooks via embedded links will also help bridge the divide between DevOps and IT service management (ITSM) teams that often need to collaborate to resolve an IT issue.

    Naturally, the level of collaboration between those teams tends to vary widely by organization. However, as DevOps best practices are more widely embraced, the number of organizations that are trying to achieve that goal continues to steadily increase. Earlier this year, ServiceNow added an incident response offering to orchestrate on-call escalation, group alerts and provide analytics in further pursuit of that goal.

    Observability platforms aggregate the collection of logs, metrics and traces in a way that makes it possible for DevOps teams to query that data. The goal is to make it easier for DevOps teams to both identify the root cause of an IT issue and pinpoint any anomalies that might disrupt an application environment. The goal is to eliminate the need to convene a “war room” meeting that requires IT teams to suffer through the painstaking process of elimination to identify the root cause of an issue.

    Of course, before an IT environment can be observed, it needs to be instrumented. Thanks to advances in the form of open source agent software being advanced via the OpenTelemetry project managed under the auspices of the Cloud Native Computing Foundation (CNCF), it’s becoming less costly to instrument IT environments. That’s especially critical at a time when more DevOps teams are deploying microservices-based applications that are more complex to manage than legacy monolithic applications. While generally more resilient, the dependencies that exist between the microservices that make up an application can be difficult to identify without the aid of an observability platform.

    As a core DevOps tenet, the need for observability and instrumentation has always been apparent. The challenge has been finding the best way to achieve that at an acceptable cost, Fortunately, there is now no shortage of observability platforms. The only remaining issue is to determine which one best fits within the construct of the organization’s defined DevOps workflow.

  • JFrog Integrates with ServiceNow to Improve Software Security Vulnerability Response Times with “ServiceOps”

    New JFrog Xray Integrations with ServiceNow Lightstep Incident Response and Spoke Help IT and SRE Teams Proactively Secure the Software Supply Chain with Real-Time, Cross-Department Visibility & Team Activation for Security Incidents

    Sunnyvale, CA and San Diego, CA, May 26, 2022 — (swampUP 2022) – JFrog Ltd. (“JFrog”) (NASDAQ: FROG), the Liquid Software company and creators of the JFrog DevOps Platform, today unveiled new integrations for JFrog Xray with ServiceNow’s Lightstep Incident Response and Spoke products for IT Service Management. Available immediately, the JFrog Xray integrations with ServiceNow (NYSE: NOW) provide IT leaders with real-time insights on security vulnerabilities and compliance issues to quickly engage necessary team members from across the organization for more immediate response and remediation.

    “Successfully securing the software supply chain at the speed of business is a team sport, requiring efficient, cross-team collaboration for timely security incident remediation,” said Shlomi Ben Haim, Co-Founder and CEO, JFrog. “Our integration with ServiceNow aims to change the relationship between developers and the rest of the business, so they can maintain the speed and frequency of releases, while avoiding downtime and loss of trust from end customers.”

    The new integration enables IT teams to proactively address security issues before they become major concerns. The combination of JFrog Xray and ServiceNow delivers a robust software composition analysis (SCA) tool that can quickly scan binaries for vulnerabilities and license compliance issues, then share those insights with the appropriate parties across the organization. The JFrog Xray-ServiceNow solution is unique in that it helps DevOps engineers, site reliability engineers (SREs), IT system administrators, and others, more securely build, deploy, run, and monitor applications effortlessly, in a single view. It also enables real-time security alerts and insights with assigned actions across all the tools, people, and processes needed for timely resolution.

    JFrog Xray & ServiceNow: Delivering Incident Response & Enterprise-wide Workflow Design for Security Incidents

    Identifying and effectively responding to malicious attacks must transcend business units and operational functions. By improving real-time insight, collaboration, and communication amongst and between enterprise security and IT teams, the JFrog Xray-ServiceNow integrations ensure swift responses to emerging security threats.

    The JFrog Xray integration with Lightstep Incident Response enables developers, SREs, and Security Administrators to:

    • Monitor, collect and respond to license compliance and security vulnerabilities impacting the software supply chain across all stages of the software development and release lifecycle.
    • Streamline vulnerability response by pulling-in the right team members across the organization for faster remediation.

    The JFrog Xray Spoke for ServiceNow allows IT operations staff to:

    • Generate violation reports, create ‘ignore rules’, re-scan builds, add custom item properties, and more.
    • Automate workflows that meet audit demands and avoid penalties for improper use of code segments obtained from the open-source community.
    • Identify problems earlier in the application development pipeline and incorporate change management solutions.

    For more information on the new JFrog Xray integrations for ServiceNow Lightstep Incident Response, read this blog or solution sheet.  Further details on the JFrog Xray integration with Spoke can be found in this blog. You can also connect with JFrog and ServiceNow solution experts during swampUP 2022 taking place in San Diego, May 25 – 26, 2022. For more information and to register, visit https://swampup.jfrog.com/.

    About JFrog

    JFrog Ltd. (NASDAQ: FROG), is on a mission to power all the world’s software updates, driven by a “Liquid Software” vision to allow the seamless, secure flow of binaries from developers to the edge. The JFrog Platform enables software creators to power their entire software supply chain throughout the full binary lifecycle, so they can build, secure, distribute, and connect any source with any production environment. JFrog’s hybrid, universal, multi-cloud DevOps platform is available as both self-managed and SaaS services across major cloud service providers. Millions of users and thousands of customers worldwide, including a majority of the Fortune 100, depend on JFrog solutions to securely manage their mission-critical software supply chain. Once you leap forward, you won’t go back. Learn more at jfrog.com and follow us on Twitter: @jfrog.

    ServiceNow, the ServiceNow logo, Now, Now Platform, and other ServiceNow marks are trademarks and/or registered trademarks of ServiceNow, Inc. in the United States and/or other countries.