Tag: monitoring

  • Finishing the Pipeline: Monitoring, Tools, Automation and …

    Finishing the Pipeline: Monitoring, Tools, Automation and …

    It is true that DevOps has grown to be the beast in the room. I’ll co-opt the “cloudwashing” term to call it “DevOps-washing” because it seems every tool you’ve ever used to develop and deploy applications now has a DevOps angle to it. For example, the Jenkins update center is kind of overwhelming. While I can’t be certain, there’s a chance that our new coffee maker has a plugin for Jenkins.

    But it’s also true that DevOps really is coming of age. The success of Jenkins is largely based on CI/CD, and the tools built both up and downstream from it are folding in more and more of the DevOps process, making life easier—if not exactly easy—for IT.

    Even with platforms, the choices are growing and the automation is, too. Whether one of the major cloud vendors, where deployment can be fully automated or hyperconverged infrastructure and where deployment can be fully automated, we’re moving toward a future of not caring about physical infrastructure but rather, “Can I get a connection to it?” Of course, it’s not that simple, but running Docker or Kubernetes on hyperconverged infrastructure means we have on-demand deployment, and the cloud does much the same.

    Tooling for monitoring is also getting better, whether you are monitoring user experience or a particular API’s CPU usage. For the most part, we are not yet to the point where automation can deal with the majority of alerts from monitoring, but that boundary is being pushed daily. We certainly can tool our systems—both the infrastructure and the app sides—to offer us more data about application health than we’ve been able to get in the past. From physical hardware all the way up through containers we have a wealth of options for monitoring, and application monitoring is getting even more attention than infrastructure monitoring.

    Heading Down the Trail: Monitoring and More

    Which leaves one wondering where this is bound. Let’s assume that the areas that are a bit behind—like over-arching network configuration from ARA tools—catch up. They will, and that’s pretty obvious, so I’m trying to remove the short-term roadblocks to talk about what we might be planning for and facing moving forward.

    If we can assume a place to deploy that has reasonably unlimited capacity—such as the cloud, where cost is the limit, or hyper-converged, where capacity is a limit but expandable in chunks—and we can assume that ARA is running the Dev/Test side, then pairing it to a preferred server configuration (be that VM or container, depending on app, group, company, etc), and pushing out the deploy, then we’re left with the monitoring piece, and automating the responses to monitoring issues. That is growing, too.

    Right now, the standard in the DevOps world for a server that is malfunctioning in some way is to kill it and start a new instance. This often masks real-world problems, and if it appears to “fix” the problem, reduces the priority of resolving what went wrong. This is, in a nutshell, the real error for Cloudbleed. They were seeing servers spew errors, when one appeared to core, they simply started another. It allowed a simple programming error to persist over months and become a security issue.

    So the next great leap will be to find a quick way for monitoring to determine exactly where problems are occurring, and force a developer to fix it. There are tools that can auto-generate bug reports, but they’re rudimentary at this point in time, and we need them to be more advanced. There will also always be the trade-off of how much in resources you use for monitoring when the point of the app has nothing to do with monitoring. And like so many things, the hidden cost of keeping that monitoring up to date will be a technical debt—one of many that the DevOps community seems slow to acknowledge.

    There Always Seems to be More

    On the “time we waste” side, the fight over internal/external needs to end. The fact is that internal cloud isn’t going anywhere anytime soon, and if you’re running in containers, you don’t have to care. My company is currently looking at a tool that can run hundreds of containers in a very (physically) small space. We can deploy to the cloud or deploy there, as long as we have container templates. It doesn’t matter what the business need forces us to use; containers really will run pretty much everywhere. It does no one any good, harping about internal/external. A deployed app is a deployed app.

    Now, talking about the differences in networking between internal/cloud, external/cloud, and container manager (regardless of where it sits): That is a discussion worth having.

    — Don Macvittie

  • AIOps: Managing the Second Law of IT Ops

    AIOps: Managing the Second Law of IT Ops

    Or, why IT systems keep breaking

    The tension between the two halves of DevOps is long-standing, going back long before the term was even invented. What underlies the split between Development and Operations is a fundamental difference, like an actual physical law. Let’s explore that analogy together.

    IT Ops is fundamentally a constant fight against entropy, meaning disorder. Sysadmins expend significant energy trying to keep everything up and running, in a process which can sometimes feel like trying to shore up a sandcastle while the tide is coming in. Systems are constantly breaking down; users need changes made that introduce risk; and, as if that wasn’t enough, the whole shebang is constantly under attack from malicious outsiders. It’s no wonder that sysadmins have a reputation for being a bit grumpy!

    Homer: In this house, we obey the laws of thermodynamics!
    It’s not just a good idea, it’s the law.

    In contrast, Dev actually increases the level of entropy. Every new release, be it as small as a one-line fix or finding that errant semicolon, is a change that has to be made, reducing the order that Ops fights so hard to maintain. Dev is entropogenic, embracing change as a positive force.

    The interaction between Dev and Ops is analogous to the second law of thermodynamics: Entropy can only increase over time, unless energy is introduced to the system from outside. In other words, unmanaged change will eventually cause something to break, unless people put in continuous effort to prevent those breaks.

    Thermodynamics: Lots of Heat, not Much Light

    These conflicting goals, taken to extremes, can get unhealthy, with Ops actively fighting change or Dev going around Ops to increase their velocity of change. Left unchecked, this tension can turn into a vicious cycle, as frustration with the “Department of No” drives developers into unmanaged “shadow IT.”

    The good news is that the analogy with hard laws of physics is not perfect. The process of increasing entropy is not irreversible, and does not require constant inputs of energy to prevent. New agile approaches to IT Ops are emerging that are light and flexible, taking their structure from that tension. In the physical world, this is called “tensegrity,” and was originally formulated by Buckminster Fuller, one of those annoying polymaths who seem to make breakthroughs in every field they touch.

    Tensegrity structure
    Tensegrity structure

    IT Ops needs its own equivalent to tensegrity, a flexible, holistic structure that is able to embrace change while maintaining its shape. Structures that try to resist change through rigidity are brittle and ultimately fragile.

    Today, this flexible strength is enabled by AIOps, a term coined by Gartner to describe a new way of operating IT, based on augmenting human skills with automated analysis enabled by modern algorithmic and machine-learning approaches.

    Complexity Breeds Complexity

    Modern IT is too complex for any single person or even team to keep track of, instead requiring multiple specializations. In turn, each of these functions requires its own specific support tools that enable that particular role. Beyond a certain point, it becomes very difficult to combine these partial views to gain a holistic understanding of what is actually happening in the environment.

    Because of the scale of modern IT environments and the sheer rate of change that businesses require, old-style rules-based “Managers of Managers” can no longer keep up, requiring more effort to build and maintain their worth. Especially as infrastructure becomes more and more self-modifying in response to changing conditions and demand, IT Operations needs to accelerate just to keep up.

    AIOps brings developing issues to the attention of sysadmins before they become visible to customers and end users, and gives them the tools to collaborate effectively between different teams and specialist roles to avoid outages or restore service quickly and efficiently. In this world, automation is used to augment the capabilities of the human operators to make them more effective, letting people concentrate on adding value, not just fighting fires.

    This is how Ops can get out of the business of fighting Dev, and instead become a supportive partner. AIOps can catch issues that are affecting services and flag them to the right people early on, including the DevOps engineers that are responsible for production support.

    For developers, one of the fears around DevOps is that in “picking up the pager,” they are opening themselves up to a constant stream of irrelevant alerts. Old Ops hands nod wryly at this, or maybe try to share their personal approach to filtering the noise. Instead, AIOps ensures that only valid, actionable alerts get as far as being shown to a human being and taking up their valuable time.

    Eyes on the Prize

    It’s not all roses. As the AIOps market begins to mature, there is a certain amount of “algorithm-washing” going on, with more and more vendors trying to claim that either their legacy tool was AIOps all along, or that their one-trick pony is actually a whole three-ring circus. What gets lost in the excitement is what all of those algorithms are actually supposed to achieve.

    Me too!
    Me too!

    In considering a shift toward AIOps, the goal should not be simply to build a better mouse trap, meaning a smarter filter for monitoring events. The success of the project can be measured not so much in the mathematical results of the algorithms, but in the smoother exchange between the human users. This easier collaboration is especially important across team boundaries, whether these be different specialist units within the Ops function or developers and software engineers who need to work with Ops to understand the performance of their code in production.

    The benefit of transforming operations this way—moving from sequential, waterfall Ops to abile, collaborative Ops—is to turn DevOps-enabled teams into a sort of perpetual-motion machine, able to continue operating without requiring constant massive inputs of energy from outside the system. Modern applications and the complex infrastructures that support them cannot be managed with the sorts of rigid, cobbled-together, industrial approaches that were appropriate in the mainframe days. AIOps is the agile, flexible approach that can not only accomodate that complexity, but thrive on it.

    — Dominic Wellington

  • 4 Ways to Give DevOps Teams the Support They Need

    4 Ways to Give DevOps Teams the Support They Need

    If it weren’t hard enough for IT infrastructure teams to innovate and keep the lights on, a host of technologies designed to drive efficiencies are introducing new levels of complexity across the data center. Virtualization, cloud computing, software-defined storage and digital are making it much more difficult for the infrastructure team to control, manage and administer an organization’s IT.

    Just when IT professionals think they’ve figured out the support model, DevOps steps in. As the number of apps continues to explode, more organizations are adopting a DevOps model to accelerate development efforts.  A recent Coleman Parkes Research survey of 1,770 senior business and IT executives revealed 87 percent have adopted DevOps.

    Unsurprisingly, the growing emphasis on DevOps is placing an added burden on infrastructure teams already struggling to cope with the digital transformation of their organizations. Traditional storage systems are often unable to match DevOps’ requirements for an enterprise infrastructure that is simple, flexible and automated. Some DevOps teams also work in silos, which produces an additional level of complexity and opportunities for failure.

    Also, occasional tensions between development and IT operations can flare up over different approaches to infrastructure and competition for resources.

    IT operations teams with traditional storage hardware backgrounds are normally focused on accelerated release cycles, availability, reliability and streamlined data management. Developers, on the other hand, spend little time thinking about what technology they need versus keeping test data up to date with production and having easy access to capacity when needed.

    A Support Structure That Works

    Set against this backdrop, choosing the right platform to underpin these growing changes within the enterprise cloud can play a big part in ensuring a DevOps model that works and makes life easier for the IT infrastructure team. Here are four ways to help make the enterprise cloud infrastructure fit a DevOps model:

    Copy Data Management

    Copy data management provides up-to-date, “virtual” copies of production data to the DevOps team, eliminating the need for physical data duplication. Copy data management helps remove the load on production storage and protects the performance of applications. With snapshots, cloning and replication, modern enterprise cloud systems can enable data copies. The same technologies make it possible to protect and manage the development side of the environment in case of failure or data corruption.

    QoS and Performance Guarantees

    Quality of service (QoS) and guaranteed performance is a significant concern when adopting DevOps. QoS enables IT to allocate different storage workloads to control performance. QoS can set levels of maximum and minimum input/output operations per second (IOPS) or bandwidth. IT can also configure QoS at the virtual machine (VM) or virtual disk (vDisk) level. With the power of all-flash, DevOps can be consolidated on the same platform as production. This makes it easier to access production data sets and reduce the storage footprint.

    Monitoring and Troubleshooting

    The ability to monitor the infrastructure and correct problems and misconfigurations rapidly is valuable when moving to a DevOps environment with continuous integration and continuous deployment. Ideally, the foundations of an enterprise cloud platform should provide basic and advanced monitoring capabilities, predictive analytics, integration with other monitoring tools and VM-level monitoring.

    Automation

    From an infrastructure point of view, it is also critical to provide the capability to provision and manage IT infrastructure programmatically. Automation enables organizations to create and break down environments as needed, incorporate advanced features such as snapshots and cloning as daily workflows, and eliminate the potential for error from manual or interactive configuration.

    As organizations move relentlessly to a mixture of virtual and physical, on-premises and cloud-based IT, infrastructure teams have to manage, control and administer all those resources while matching them to a diverse range of business, development and user requirements. By implementing an enterprise cloud platform that can work across physical and virtual environments, infrastructure teams can help DevOps teams achieve their goals without constraints around performance, scalability, manageability, resilience or flexibility.

    IT organizations are achieving this level of support by replicating the agility of public cloud within the data center to make it easier to manage enterprise and cloud-native applications. This approach can help support the DevOps model and ensure it is implemented with as little friction and disruption to the infrastructure as possible.

    About the Author / Chuck Dubuque

    Chuck Dubuque is the VP, Product Marketing at Tintri. Prior to Tintri, he was at Red Hat where, as director of product marketing for the virtualization business unit, he was responsible for Red Hat Enterprise Virtualization (RHEV) and Red Hat Enterprise Linux OpenStack Platform (RHEL-OSP) market strategy. Before Red Hat, Chuck worked at a value-added reseller for VMware, NetApp and Cisco and also spent several years in biotechnology in marketing and business development. Follow him on Twitter.
  • Site Reliability Engineering: How to Make the Operations Side of DevOps Actually Work

    Site Reliability Engineering: How to Make the Operations Side of DevOps Actually Work

    The DevOps movement often has been accused of focusing too much on the first half (Development) and not enough on the second half (Operations). Certainly there has been more attention paid to deployment of payloads than to operating running systems, leading to the dismissal of the handover between Dev and Ops as “throwing it over the wall.”.

    Lately, we have seen the emergence of a new focus on the stability and reliability of the systems that are the targets of those deployments, with the creation of the new practice of site reliability engineering (SRE). This has been a welcome addition to the IT toolbox, but it can still seem to put all the onus on Ops teams to catch whatever comes over the wall.

    The Problem with Site Reliability Engineering = IT Infrastructure

    In SRE, the IT infrastructure is expected to be highly automatic and self-healing in the face of any events. Here is the problem: That approach works well for foreseeable events, but less well for the unforeseen ones. Because of that factor, it works well in environments that run few types of individual workload types, but do so at very large scale. If you’re thinking that sounds like Google and Facebook, you’d be right.

    What this amounts to is massive engineering of the infrastructure to withstand known or foreseeable problems. However, typical enterprise IT environments are not like that. A large bank might have thousands of applications, each of which must accommodate changes on a pace that is dictated from outside the IT environment. Applying assumptions from one environment to the other is asking for trouble.

    To illustrate this, let’s look at an example from outside IT. Recently was the anniversary of the sinking of the Titanic, on April 15, 1912. The RMS Titanic itself embodies the principles of SRE, engineered to prevent or survive all manner of emergencies. The ship was equipped with state-of-the-art everything to transport its passengers in comfort and safety across the Atlantic.

    As we all know, that plan did not quite work out. A combination of unexpected changes in the environment (more icebergs than normal), business imperatives to maintain speed and mishandled warnings about the ice from other ships led the Titanic to disaster.

    While the consequences of an IT failure are rarely quite as dramatic as the sinking of an ocean liner, many of the same factors apply. IT administrators may believe that in the worst case their backups and disaster recovery plans will be sufficient to handle any problems, but these plans are designed around known and foreseeable problems. Unexpected circumstances can easily lead to cascading failures, which is why it is critical to be ready for the unexpected when it—inevitably— occurs.

    The Problem with Traditional IT Ops = Static Models

    The key flaw in IT Ops is reliance on static models of the world. These models come in many shapes – the CMDB is the “model” that many think of first, but static rulesets are also a model. The most dangerous models, though, are the ones that are invisible: namely, the filters that are put in place to determine which alerts and events are even worth considering.

    This is the flaw that ultimately sank the Titanic: The crew were unable to correctly priorities events and react to them in time to avoid failure. It is also the flaw that causes countless much more minor issues every day in data centers everywhere: the filesystem that filled up with logs, taking down the database that the critical business application relied on—and the filter that had not forwarded that alert because it usually was harmless. Or the loss of one leg of the redundant network link, which was ignored because the other leg was still up, so there was still a link—until that one failed too, and an entire site went dark.

    The key factor is that the filters were not wrong to suppress those alerts. By definition, informational or warning alerts are not the same as major or critical ones, and most of the time they can be safely ignored, to be dealt with later.

    Every now and then, though, a pattern of those alerts, if understood correctly, can identify a future problem in the making. These developing issues could be nipped in the bud, if only Ops teams had enough hours in the day to look at them and review them. But, of course, they don’t—every Ops team I have ever met is drowning in issues, and behind those there is a long and lengthening to-do list.

    What Can DevOps Do to Make Operations Better

    New approaches are emerging to make the principles behind SRE more widely accessible and applicable. In particular, more dynamic noise reduction and correlation is now possible, to sift those important alerts from the constant background noise and put them together into a picture of what is really happening. The key factor is to be able to do this in real-time and without a human having to plan out laboriously what are all the possible scenarios that they might need to know about in the future.

    Gartner has called this new approach Algorithmic IT Operations, or AIOps. The idea is to bring together all possible sources of events, whether those are alerts from the compute or network infrastructure, transaction slowdowns reported by an APM tool, automated deployments being run from a CI/CD toolchain, or anything else the might conceivably be relevant. All of this information then can be sifted by algorithms to understand what is actually important to Ops and brought to the attention of the right specialists who can work on the issues and get them solved fast. Part of that process is also the integration with systems of record (which generally means IT service management), and with automation and orchestration tools that can accelerate remediation activities.

    This is how we can get the Ops side of DevOps to where they need to be to be able to accommodate the ever-accelerating pace of change—whether from Dev teams wanting to run ever more frequent deployments, or from business users needing help with their own goals—or from the next unexpected issue to come down the line.

    — Dominic Wellington

  • The Top 10 Reasons to Use Cassandra

    The Top 10 Reasons to Use Cassandra

    The Apache Cassandra database is the right choice of database if you are looking for scalability and high availability without compromising performance for your mission-critical applications. Additionally, Cassandra’s support for replicating across multiple data centers is best-in-class, providing lower latency for users and the peace of mind of knowing that you can survive regional outages. To that end, we’ve compiled a list of the Top 10 reasons why enterprises onboarding and deploying mission-critical applications should use Cassandra (Apache Cassandra, DataStax Enterprise).

    1) Requirement for fast writes: Easily deals with data velocity, data variety and data complexity issues

    Many of the challenges associated with next-generation cloud applications center around data volume and data velocity. Is Cassandra able to handle the speed of data coming into the system? The answer is “yes” based on the amount of data and cluster size. Not only does Cassandra come with this ability out of the box, but there are systems of data pipeline architectures being built around ingestion speed. And to top it off, it scales linearly, making it easy to determine the right amount of capacity based on data flow.

    But, there are also two often overlooked components it provides: 1) data variety and 2) data complexity. Data variety is an alternate way of saying that data coming into one database can come in different forms. An example of this would be sensor input from a heart monitor and sensor input from an IV both for the same patient. The second component, data complexity, extends the previous example. The heart monitor might report 100 metrics twice per second under normal operating circumstances and up to 125 metrics once per second while the wearer is sleeping. This means the write patterns, locations, and frequencies can vary. Cassandra handles these situations gracefully.

    2) Can handle massive data sets

    If there were any questions about whether Cassandra is capable of handling large data sets, there is no need to look any further than the companies using it. They operate at massive scale—Netflix, Hulu, Instagram, eBay, Apple, and Spotify all have Cassandra working in interesting ways as part of their offerings.

    The other way you know Cassandra is up to the challenge is in use case examples. Many organizations use it for applications where data grows in an unbounded way very quickly. These include Twitter clones, a web log analytics data warehouse and telemetry or sensor data.

    3) Homogeneous environment

    Unlike some of the legacy distributed systems, Cassandra does not require outside support for synchronization. All of the required components for basic operation are built in. Since Cassandra also operates in a peer-to-peer fashion, this means that there is no master-slave or sharding setup and that all nodes in the ring are equal. Additionally, there is only one machine type that an administrator needs to worry about.

    4) Highly fault-tolerant

    Cassandra employs many mechanisms for fault tolerance. Since it is masterless, there is no single point of failure. There is also the potential for zero downtime rolling upgrades. This is because Cassandra can support the temporary loss of multiple nodes (depending on cluster size) with negligible impact to the overall performance of the cluster.

    The safety net Cassandra offers extends outside of your data center as well. Cassandra allows you to replicate your data to other data centers and keep multiple copies in multiple locations. This helps satisfy many regulatory requirements in addition to being a part of an strong disaster recovery and business continuity plan.

    5) Proven success across enterprise applications and in many use cases already

    There are already many examples where Cassandra is being used effectively. Banks and other financial institutions are storing large quantities of financial data in Cassandra. Analytics companies are using Cassandra to store web analytics data. Medical companies are using Cassandra to store sensor data and other time series inputs. There are also many companies making use of Cassandra for storing internet of things (IoT) data.

    6) Ease of administration

    Cassandra is a straightforward system to administer. With Cassandra being a masterless system, all nodes in the ring are the same—a homogenous system. It’s fault-tolerant and can support the temporary loss of nodes with minimal impact to production performance. This means that nodes are easy to replace and the requirement to replace downed nodes immediately isn’t as strict.

    7) Custom tuning

    There are a lot of knobs and levers that can be turned to get Cassandra to perform optimally for your workload and environment. You can set it up to operate in a way that is consistent with your workload. For example, if you write lots of log data and read infrequently, then there are configuration tweaks to be made for write-heavy systems. If you write heavily to one data center and then do all your reading from another data center, then you can adjust the settings on a data center-by-data center basis.  This idea of tuning isn’t just available at the application level; you can also tune the JVM and Java settings, including GC and logging levels. Changes can even be made by the drivers at connection time to aid in the performance of your system.

    8) Easy to integrate core applications

    A lot of work has been done on data manipulation and parsing systems to integrate with Cassandra. For instance, the full text search engine Apache Solr has been packaged to work with Cassandra to provide full featured search capabilities to an existing Cassandra database. Apache Spark, a big data analytics engine, also has been plugged in to work on an existing database. There are entire suites of tools that can be integrated or bolted on to increase its capabilities. These include Apache Mahout, Kafka and Zipkin, to name a few. This is important because the more tools you have available to you, the more powerful your data becomes. You also have the ability to gain more insight about your data without having to build and maintain the application systems that were previously required.

    9) Excellent Monitoring Options

    Included in the system of tools referenced in No. 8 are monitoring packages. If you are a user of automated monitoring platforms such as Datadog or Netuitive, you’ll find examples of prepackaged agents to monitor the important parts of Cassandra. You can then tack on your own additions of other metrics that are important to you. This is made possible by Cassandra taking advantage of Java MBeans and exposing them to the client. You can use these to get at much of the internal information Cassandra uses to make its own decisions and decide on its own health. Datastax also offers its own monitoring and control application called Opscenter.

    10) Amazing community

    One of the best things about any piece of software is having a great community of developers and experts available to you for help or guidance. There is a huge yearly database summit put on by Datastax, the primary backer and largest contributor of code to Cassandra. It also sponsors community events all over the world so you can meet and interact with other developers around you.

    For open-source software to be successful, there needs to be an ecosystem that develops around it. In the case of Cassandra, there are consultancies, monitoring and troubleshooting systems, plugins, instrumentation systems and backup systems. That is all a set a competencies that your organization no longer needs to own and can use what the greater community has already created. There are even PaaS companies that will completely take over the management for you, leaving you just the development of your application to focus on.

    Given the sizable number of organizations and people that are a part of the ecosystem and the Cassandra community as a whole, there is no shortage of articles, documentation and people willing to help. A welcoming and helpful community isn’t always a given, but in the case of Cassandra, it’s alive and thriving. This is important because software is always about people.  The more of them that you can interact with that have shared your experiences, the better. It also will be easier to find solutions to your problems having a network of people who might have faced them before.

    There are many reasons why Cassandra could be the right tool for your application. Knowing your systems requirements, workloads and future will help you make the right choice. As you can see, if you do choose Cassandra, you are bound to be in good company.

    — Michael Colby

  • Predictable Progress: Tracking DevOps Maturity Metrics

    Predictable Progress: Tracking DevOps Maturity Metrics

    As DevOps methodologies continue to evolve, we’re naturally seeing an increased emphasis on the cultivation of related maturity metrics.

    For instance, in the 2016 State of DevOps Report, researchers with DORA took an initial stab at creating relevant ROI measurements.

    Similarly, a new report issued by researchers Coleman Parkes, sponsored by CA Technologies, offers additional evidence that as agile and DevOps processes continue to expand, today’s practitioners are increasingly employing metrics to optimize their efforts.

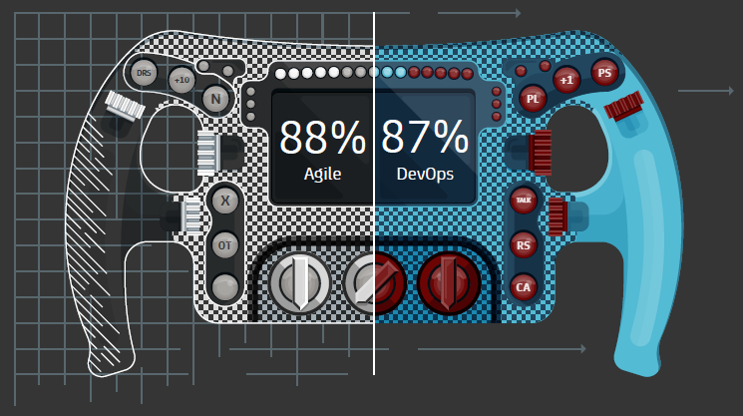
    The report, titled, “Accelerating Velocity and Customer Value with Agile and DevOps,” finds some form of adoption among nearly every enterprise, with 87 percent having adopted agile to some degree and 73 percent leveraging DevOps.

    Related to the overall maturity of these practices, those organizations that are moving to embrace the techniques most broadly are predictably seeing greater returns. Yet, despite the widespread adoption, only a third have deployed either practice widely, according to the research.

    Percentage of Advanced Adopters Reporting Improvements in Customer Experience


    Based on a survey of 1,770 senior business and IT executives, the study also closely investigates the specific KPIs that organizations are using to gauge how agile and DevOps initiatives are translating into customer interactions.

    Most notably, “advanced” agile and DevOps adopters have observed more than an 87 percent improvement in overall customer experience, compared to “basic” adopters.

    In terms of how those efforts are affecting business drivers, Coleman Parkes finds:

    • Advanced agile practitioners are experiencing a 40 percent improvement in time-to-decision, compared to 33 percent for basic users.
    • Advanced DevOps adopters have noted a 42 percent improvement in speed-to-market, compared to only 24 percent for basic practitioners.

    Key Performance-Invoking Indicators

    To that end, the research highlights specific KPIs that organizations are using to measure the impact the agile and DevOps practices are having on customers. In fact, the study finds that between two thirds and three quarters of all the organizations surveyed have established such measurements.

    At least half of these focus on business or customer-related metrics, reflecting how “critical software has become to businesses’ ability to achieve their core mission,” Coleman Parkes researchers note.

    Among the mostly widely invoked metrics, include:

    • Business growth (specifically revenue): over 73 percent
    • Operational or process efficiency: over 73 percent
    • Employee productivity: over 73 percent
    • Customer experience: over 71 percent
    • IT-related costs: over 71 percent
    • Speed-to-market: over 71 percent
    • Customer satisfaction (via NPS): over 70 percent
    • Time-to-decision: over 70 percent
    • Quality of development: over 70 percent
    • Employee retention: over 64 percent

    If increasing applications delivery speed and overall organizational velocity are, in fact, the primary goals of engaging agile and DevOps, the research bears out that the techniques are having the desired effect. After all, the survey finds that time-to-decision and speed-to-market are being accelerated among approximately a third of the organizations studied.

    Related to other notable KPIs, Coleman Parkes highlights that a full three-quarters of adopters have moved the needle on overall customer experience, along with employee recruitment and retention, a significant benefit that was also highlighted in the State of DevOps Report.

    Along with positively impacting customers, the reality is clearly that agile and DevOps are also making a big difference in allowing companies to improve the atmosphere for their workers—a huge benefit when you consider the shortage of talent in IT today, and how much it typically costs to attract new employees, just as DORA’s researchers noted.

    Other key findings by Coleman Parkes include “before and after” metrics that many organizations are observing related to their continued adoption and advancement of the involved methodologies themselves.

    I encourage you to download the entire report, and leverage it to measure how far you’ve come with Agile and DevOps transformation—and where you may need to re-examine your efforts.

    — Aruna Ravichandran

  • Top Reasons to Use Node.js

    Top Reasons to Use Node.js

    When considering the architecture of a new web app, it might be a good idea to include Node.js in the discussion as a key part of that architecture. Node.js could provide you with additional speed, can be used on numerous platforms and has an active community from which to get modules and other assistance.

    What is Node.js?

    Node.js is a server-side platform developed by Ryan Dahl in 2009. It was built on Chrome’s V8 JavaScript engine and designed with a non-blocking, event-driven I/O. It is also cross-platform, able to be run on Windows, Linux and OS X. Its non-blocking I/O is due to its use of asynchronous functionality, which keeps the server from waiting on data to be returned before being able to move on to other tasks.

    Why Use It?

    Given the architecture of Node.js, a number of advantages are provided both to developers and the resulting apps they develop. A few of these advantages include speed, programming language consistency, real-time apps developed easily and a large number of modules/packages for developers to use while creating new apps.

    Speed

    Node.js offers speed advantages in many cases. First, it uses the Google V8 engine, which is optimized for JavaScript speed. Also, its use of non-blocking asynchronous behavior can ease the time it takes for users to see actions as complete, since things can be going on in the background while the user moves on to other tasks.

    One Language

    JavaScript is listed as the most popular programming language. Source: Thenewstack

    Using Node.js, front-end and back-end code can both be in JavaScript, so your developers don’t have to transition between languages as they move through the stack. Some architectures, such as the MEAN stack (MongoDB, Express.js, Angular.js, Node.js), are designed around this principle. In this case, the stack uses JavaScript for Express, Angular and Node. MongoDB uses BSON for database queries, which uses the same syntax as JSON (JavaScript Object Notation).

    Seeing full-stack developer as the largest occupation and JavaScript as the top language among both back-end and front-end aligns with what we’ve been seeing in overall JavaScript adoption.

    Source: Mikeal Rogers, Node,js Foundation Community Manager 

    For developers, this can help both with moving across the stack during development as well as help communication among developers, as they will be referencing the same language (JavaScript) while discussing programming decisions.

    Real-Time Apps

    Node.js is a great platform for creating real-time apps. With a module such as Sockiet.io, you can create real-time chats, games and more. Along with its non-blocking asynchronous architecture, real-time apps can be developed with plenty of speed and responsiveness.

    Modules

    The Node Package Manager (NPM) makes it easy to install packages that others have developed to perform any number of tasks. This helps to encourage code-sharing among developers and to reduce the amount of custom development that has to be done when one or more packages can take care of that coding for you.

    Notable Examples

    Some notable examples of Node.js use are Paypal and Uber, showing that it can, indeed, be useful for large projects.

    Paypal

    Node.js and an all Javascript development stack helped PayPal bring efficiencies in engineering and helped rethink and reboot product, design and operational thinking.

    Source: Sameera Rao, Paypal Sr. Business Products Engineering Manager 

    Back in 2012, Paypal had a single app running all things, including UI, API and more. This included a lot of duplicated code that was copied and pasted from one app to another to make apps for different locations.

    Using Node.js, the company was able to modularize and clean up its code and processes, which in turn sped the development of apps it needed at any given time.

    According to Paypal’s engineering team, they were able to build the Node.js app with 33 percent fewer lines of code and 40 percent fewer files, and were able to build it twice as fast and with fewer people than before. Certainly, Node.js proved to be advantageous to their development.

    Uber

    Uber used Node.js from the beginning, and its distributed system was a perfect fit, since a lot of network requests are made. The non-blocking asynchronous I/O used by Node.js helped to ensure those requests could be made and handled quickly to provide the best service possible.

    Conclusion

    The benefits of Node.js have been proven. It helps speed development, can be used on numerous platforms and has an active community from which to get modules and other assistance. Include Node.js in your future conversations about website architecture.

    — Brian Wheeler

  • Assembling the Key Components of Continuous Delivery

    Assembling the Key Components of Continuous Delivery

    As agile methodology was popularized at the start of last decade, engineering teams gained the opportunity to begin producing software in shorter cycles, while releasing it reliably at more frequent intervals.

    This concept garnered greater attention in 2009, when Tim Fitz published his thoughts on continuous deployment. By the time Jez Humble authored his seminal book, “Continuous Delivery: Reliable Software Releases through Build, Test, and Deployment Automation,” in 2010, the approach started to get significant mindshare. In the book, Humble advanced the three building blocks of continuous delivery: configuration management, continuous integration and continuous testing.

    Thereafter, Agile Operations—the practice of using end-to-end monitoring, fueled by analytics, to increase operational agility—appeared. This complemented continuous delivery, with the goal of increasing the quality and velocity of software delivery while minimizing overhead.

    Since then, and particularly over the last six years as DevOps adoption has exploded, there’s been significant discussion (and confusion) over the opportunity to embrace “continuous everything” across the software development life cycle (SDLC) to deliver functionality continuously and optimize end-user experience.

    Today, having spoken to hundreds of organizations employing agile and DevOps, it’s possible to expand on these concepts to better define the key components of continuous delivery.

    In this blog, I’ll detail the precepts of “CD” that CA’s customers recognize as critical in reducing the time, risk and expense of software delivery by frequently releasing smaller batches of code with extensive visibility and traceability.

    These building blocks of continuous delivery are:

    • Continuous development & integration,
    • Continuous testing. and
    • Continuous release.

    Continuous Development and Integration

    When it comes to delivering quality apps faster, every second counts.

    That’s why it’s important to automate the planning, development, unit testing and integration of code with different inter-dependent components, all while packaging it for quality assurance. We categorize these activities under continuous development and integration, as shown in Fig 1.

    This all starts with sprint planning and modeling of requirements in agile management software. Unit tests can be created automatically, based on requirements and use case stories. These unit tests then can be executed automatically based on pre-defined criterion, using automatically generated synthetic data.

    Fig 1: Continuous Development and Integration

    Next, virtual service interfaces can be generated automatically by simulating unavailable systems across the SDLC, allowing developers, testers, integration and performance monitoring teams to work in parallel—driving faster delivery, along with higher quality and reliability.

    The integrated code can be built and tested automatically against validation criterion, and upon passing, made available for continuous testing. This later phase, after code development and before QA, is also commonly referred to as continuous integration.

    Continuous Testing

    Continuous testing across app delivery not only enables enterprises to shift testing left, engaging it earlier in the SDLC, but it also helps them shift right, leveraging the same processes throughout staging and production.

    After the unit tests are passed and integrated builds are made available for QA, functional and performance tests can be completed—before the build is made available for staging and production. Various activities during continuous testing are shown in Fig 2.

    Before the functional and performance tests are performed, the build promotion criterion and configuration also need to be validated. Testers require provisioning of QA environments to deploy the build, along with virtual services and test data. Using test data management to create a subset of production data and mask sensitive information is another continuous testing requirement.

    Fig 2: Continuous Testing

    It’s also important to engage application performance monitoring in the QA environment before running automated tests, providing feedback about any problems back to developers.

    After the automated tests are executed and promotion criterion are met, the build is ready for deployment in staging or production environments.

    Continuous Release

    Continuous release matches release velocity to development velocity through controlled and scalable deployments.

    The goal of continuous release (sometimes referred to as continuous deployment) is to continually and automatically deploy the build into production; similar activities also can be performed in a staging environment.

    As shown in Fig 3, build configuration needs to be validated, with the production environment configuration updated before being sent to production. As with application code, configuration is also maintained in the version control system and can be automated for deployment.

    Fig 3: Continuous Release

    After the build is deployed into production, application monitoring should be initiated to track performance and customer experience. Feedback from the production environment can be passed back to developers to guide enhancements or sprint backlogs.

    This blog aims to outline core CD activities, and in subsequent articles I’ll provide additional details on entry and exit criterion, as well as metrics useful in tracking continuous development & integration, continuous testing and continuous release.

    In the meantime, check out, “DevOps for Digital Leaders: Reignite Business with a Modern DevOps-Enabled Software Factory,” a new book authored by my colleagues Aruna Ravichandran, Kieran Taylor and Pete Waterhouse.

    Based on learnings gained from numerous customers who have already embraced CD and DevOps, it highlights key practices for starting this journey, related ROI metrics and other useful tips.

    — Anand Akela

  • 12 Tips for Managing Your Multi-Cloud Environment

    12 Tips for Managing Your Multi-Cloud Environment

    No single cloud vendor has the perfect solution for your unique business situation. The only way to maximize the benefits of cloud services to your business is by dealing with several cloud providers and monitoring all of them simultaneously. That’s the IT equivalent of singing an aria while standing on your head and scrambling eggs. (Not really, but it can seem that way.)

    Here are 12 things to keep in mind when planning your company’s multi-cloud strategy:

    • Map your entire network, and then identify where the cloud fits in it. Get a clear picture of the cloud’s role in your overall system-management strategy to avoid having to backfill gaps in the data needs of business managers and other customers. Different lines of business will be best served by different cloud providers.
    • Work with vendors that respond quickly and positively to the unexpected. There will always be unforeseen situations when you’re stitching together multiple cloud services. Your partners should report regularly on the state of their services, enhancements, and new features.
    • Automate low-level monitoring and maintenance tasks. Two primary reasons for adopting cloud services are cost savings and more efficient operations. One way to achieve both is by reducing the amount of human oversight required to keep your systems humming.

    The potential complexity of multi-cloud management is shown in this flowchart encompassing the many elements that need to be stitched together precisely. Many of these low-level operations must be automated to optimize your strategy. Source: Carl P. Lehrmann, 451 Research

    • Follow your users. Pay close attention to how the “consumers” of your apps and systems are actually putting the tools to use. They are the best indicators of which processes are the biggest productivity boosters. You can also learn about any new services the users discover that help them get their work done faster, more efficiently and/or less expensively. This lets you get a jump on the kinds of tools the users are most likely to need in the future.
    • Double down on cost controls. You can’t control what you can’t see. Dealing with multiple vendors complicates the process for requisitioning new services. To avoid unnecessary impediments to quick implementation of useful new services, devise a purchasing process that is as flexible as the services themselves. However, not long after the service honeymoon period, evaluate whether each new service is proving to be worth the cost and whether there are better and/or less-expensive alternatives.
    • Application life cycle continues to dictate cloud migration. Data centers may be shrinking, but they are definitely not disappearing. For reasons related to security, compliance, insurance, and any number of other factors, some systems are staying in house for the foreseeable future. You certainly want to avoid attempting to lift and shift an in-house app to a cloud service, particularly one that is only a couple years old and thus hasn’t yet paid for itself. Once an older system is ready for a reinvention, it’s easier to make a business case for going cloud-native.
    • Take advantage of the power of pre-emptable virtual machines. Because they persist for no longer than 24 hours, pre-emptable VMs are a good choice for batch processing and fault-tolerant deployments, according to ComputerWeekly’s Matthew Cooter in a November 2016 article. Pre-emptable VMs are as much as 80 percent less expensive than Google’s regular instances, and their fixed price help companies plan and manage their costs.
    • Adopt an integrated data center management system designed for virtual environments. This is the only way to ensure your server, storage, network, security, operations and applications teams are working as a single unit toward common goals, according to Jay Litkey, president and founder of cloud service provider Embotics, in a November 21, 2016, article in Virtual Strategy magazine. Any organization structured around traditional physical infrastructure boundaries is destined to struggle with the shift to hybrid and multi-cloud environments.
    • Identify the apps in your organization that are best suited to cloud-native implementation. Traditional apps are monolithic, run as VMs, use a scale-up architecture and are generally more difficult to develop, deploy and maintain. By contrast, cloud-native apps are more modular and service-oriented, comprised of collections of containers and services, based on a scale-out architecture, and easy to automate, move, and scale.

    Focus on the apps in your organization that will benefit most from a cloud-native approach, and wait on those that are better served by deployment on a traditional data-center platform. Source: TechTarget

    • Match your apps to the services that play to their strengths. Big-name services such as VMware and AWS have bifurcated to meet the diverse needs of their customers. For example, VMware’s vSphere-based Enterprise Hybrid Cloud is intended for traditional apps, and the company’s Native Hybrid Cloud is designed for modular, microservice-based systems. Similarly, AWS’s Elastic Compute Cloud, Elastic Block Store, EFS file system and VPC private networks mimic in-house data centers, while the company also supports higher-level services such as NoSQL databases, BI processing, Hadoop-like clusters, message queues, push notification services, media transcoders and search engines.
    • Automate policy across cloud environments. The only efficient approach to use of multiple cloud services is to have a single standard for policies that are applied automatically to each environment. The policies cover such areas as virtual servers, workloads, data storage, traffic flows, compliance/regulation, reporting and security. It’s also easier to apply updates and changes when you have a single configuration across different infrastructures because the changes propagate seamlessly from environment to environment.
    • Vendor lock-in becomes a thing of the past. When you rely solely on one public cloud service, it can be difficult to migrate virtual machines and other resources to another service. Among the factors to consider are comparable read/write loads, data transfer needs and network latency. By relying instead on your custom combination of cloud services, all of which share policies and configurations, you find yourself managing the change instead of the change managing you.

    — Brian Wheeler

  • Datadog Monitoring and JIRA Integration

    Datadog Monitoring and JIRA Integration

    Operations uses monitoring to provide early detection of issues with systems/servers/networks. Among those monitoring options is Datadog, a software-as-a-service (SaaS) cloud service/application monitoring tool that allows Operations to be notified of issues with their applications in near-real time. Development teams, meanwhile, use JIRA to track tickets and manage overall agile development.

    But what if your product is the very thing that Operations manages? The sweet spot for DevOps is that location where the app is internally developed, and managed by Operations, because the entire stack is under IT management.

    That’s why Datadog and JIRA are now integrated.

    Datadog can monitor an infrastructure and application on a variety of levels at a variety of locations in the infrastructure stack, from disk availability to response times to memory usage. Datadog has the ability to monitor and emit alerts when things are abnormal or out of specified ranges, or they outright fail.

    JIRA is Atlassian’s Agile project management software, with issue tracking and all of the usual agile tools in one place.

    From Datadog Monitoring to JIRA ticket.
    Configuring Monitoring’s alerting to JIRA.

    Now, Datadog can create JIRA tickets, update them as more information becomes available and populate them with relevant information from the running systems.

    Say, for example, one cloud instance runs low on memory and passes over a threshold. Datadog detects the issue and opens a ticket in JIRA that shows what system and when, as well as whatever other information Operations has defined. That ticket is now in the system like any other, and a developer can grab it and look at memory use for the portions of the overall application that run on the instance in question.

    According to the press release, these are the three automations included in this integration:

    1. Creating JIRA tickets when performance issues are detected within Datadog.
    2. Populating JIRA tickets with pertinent information about identified issues.
    3. Updating existing JIRA tickets when new information surfaces.

    I’m an analytical person, so my first thought was, “How cool,” and my second was, “But what if it spams JIRA with non-development issues?” Since Operations configures what goes to JIRA, and Datadog supports alert rollups (multiple alerts in one or two notifications), it is possible to keep such spamming under control. An overzealous Operations staff initially might configure the reporting to send too much, but as experience grows, this should become a viable way to automate bug reporting. In particular, tagging of Datadog-generated events should show quickly what alerts are creating too many tickets, and give the team opportunity to change the way tickets are created—or, if it turns out they’re created because of a serious application-impacting error, raise the priority of the fix.

    Which brings us to the updating status part. In Datadog, operations can leave a comment on an issue with an “@jira-update” tag and JIRA will get notified of the comment. That means Operations can raise awareness of an issue that may seem mundane but has larger impact than is obvious, or add detail to a JIRA ticket if needed, all from within Datadog.

    It is interesting that Datadog is also integrated with BitBucket, another Atlassian product, so it is possible that opened tickets can be marked as “in test” when an integration build includes reference to the ticket. In short, BitBucket integration means that Datadog’s monitoring is aware of commits and checkouts, and Operations staff will be able to correlate that to issues that occur. Adding in JIRA integration means that Operations sees the commits, gets the alerts and updates JIRA. The wealth of information is such that you’ll want to use their various filtering techniques just to make certain you’re getting the important stuff.

    There are some areas that are intriguing to me, such as the impact of a particularly complex set of queries/reductions on a big data platform. I haven’t tried the Hadoop integration, but it appears that this agent would be able to communicate that a given reduction is the source of the problem to the JIRA interface. Even if these complimentary integrations aren’t there yet, you can feel it coming to where “This reduction caused systemwide issues” is what is generated in JIRA. That’s pretty cool.

    Overall, the integration of Datadog and JIRA is a DevOps dream come true, tying Operations closer into Development, and allowing Development changes to be tracked closer in Operations. After all, the point is to keep the systems running as close to peak efficiency as possible, and automate as much as can be. The issues spawning from Datadog alerts into JIRA tickets also pretty much guarantees increased need for development and operations to talk, as problems that crop up by the automated system are discussed and researched.

    If you’re dedicated to a cooperative environment for Dev and Ops—even if you aren’t calling it DevOps—the Datadog/JIRA integration is worth a look.

    — Don Macvittie