Ingo Averdunk, leading architecture and solutions for cloud service management and site reliability engineering for IBM Cloud, contributed to this article.
Christine White, architect at IBM Consulting, also contributed to this article.
When many people think of operations, they often associate it with manual, labor-intensive work. This is because operations traditionally encompass a wide range of activities that involve managing and executing tasks related to producing, distributing and maintaining goods and services. Information technology (IT) is not different: Manual work has traditionally been a significant component of various tasks and processes. Examples are server maintenance, software installation, troubleshooting and network configuration, which historically required manual intervention and human expertise. Much of the work is inherently repetitive by nature, time-consuming and prone to errors. We call this work “toil”, the kind of work tied to running a production service that tends to be manual, repetitive, automatable, tactical, devoid of enduring value and that scales linearly as a service grows.
Toil
This toil has always been there. And toil leads to burnout, increased errors and reduced scalability. Only how we have addressed it has changed. While toil remains, toil mitigation has evolved.
In the beginning, toil was addressed through labor arbitrage. Between 2000 and 2010, we leveraged labor arbitrage to reduce the cost of manual work by outsourcing and out-tasking activities to near-shore and later off-shore countries. When there is a problem, the person who can solve it steps up. Then, to manage it better, we started to do workload or work item management. You have systems, like prioritized backlogs, and we started putting a structure on how we solve these problems. But still, it was all resource-based; everything was resource-intensive. And that is why the engineers became more of the subject matter experts (SME). Being a subject matter expert took time, and being critical to operations became exhausting. And the repetitive manual activities required took time and effort they didn’t have.
As issues became repetitive, we started thinking about scripting. We evolved from a complete labor arbitrage mentality to writing spot scripts. Engineers began to use scripts to solve a small part of the most oppressive problem.
Tools started to be developed to enable and automate some of the work. Organizations purchased tools, and education of the tools commenced. It became important to be an SME in your area and an SME of the tools in your area. However, the tools were specific to certain functions and features that they provided, and the software development life cycle (SDLC) had a lot of nuances that many of the tools did not capture. So even when the tools helped, it created this mass of white spaces that could not be integrated easily. Tools were very format-specific and didn’t have the flexibility end to end integration. Newer problems emerged as formats were different, speeds were different, and other differences manifested. Even as this initial approach was an improvement over the labor arbitrage mentality and reduced the amount of manual effort required, it often resulted in complex and brittle systems that were difficult to maintain and debug.
Automation
From 2015 to 2020, automation became more prevalent. On one side, the cost levers of labor arbitrage were reduced, and due to low skill, quality suffered. Thanks to technological advancements, automation in various flavors became a viable alternative: Runbook automation, robotic process automation, etc.
Aligning tool isolation with SDLC nuances required an end-to-end automation philosophy. We need to do automation across the board. Toil elimination was a goal of end-to-end automation, and that obsession led to SRE thinking and the principle of capping operational load. An SRE spends only 50% of his time on operational activities, and the other 50% on “engineering” (improvements): Identification and elimination of problem areas, improving and integrating tooling, etc. And thus, the genesis of the next wave of reliability engineering principles began.
Parallel to this, adopting DevOps and Agile practices as well as cloud computing enabled IT teams to define and manage infrastructure and application configurations through code, allowing for automated provisioning and scaling. Applications are designed for reliability and instrumented for observability, providing insights into the production use. Traditional organizational barriers are broken down and teams cooperate across the entire SDLC with a shared goal that balances velocity and quality.
The new focus on leveraging cloud-native technologies and practices to build scalable, flexible and resilient systems allowed SRE teams to adopt cloud-native technologies such as Kubernetes, containers and serverless computing to build systems that are designed to be highly available, fault-tolerant and easy to maintain.
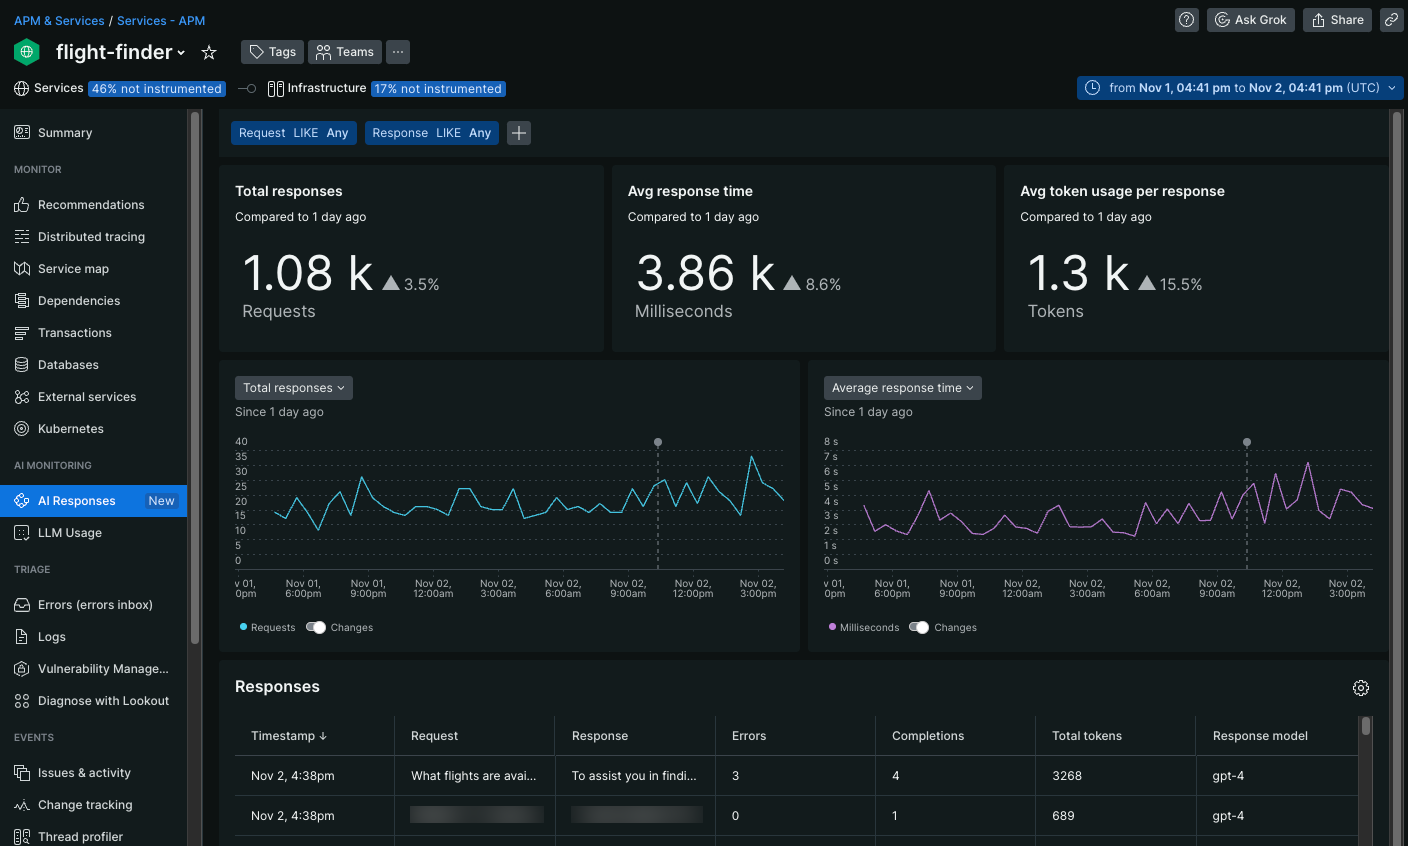
Toil mitigation and the SDLC lifecycle have evolved from reactive handling of problems to a proactive approach to operations, where alerting is maturing, and other sophisticated instrumentation is implemented. A proactive approach underlined the importance of observability and monitoring. SRE teams are using observability tools such as Prometheus, Grafana and New Relic to monitor their systems in real-time. The ability to identify potential issues before they become incidents emerges.
AI Infusion
The next step is being more prescriptive and predictive. That calls for a good bit of AI infusion. We have historical knowledge management systems that will tell us what went wrong, how it went wrong, how it got resolved and how long it took. We can augment that knowledge base with publicly available and curated knowledge.
Starting in 2020, AI and machine learning are being used in IT for tasks such as anomaly detection, predictive maintenance, risk assessment and automated incident response, reducing the manual effort required for monitoring and maintaining systems.
AI systems can learn from all this and not only predict issues, but when issues happen, they also auto-resolve. An extension of AI, Generative AI, will disrupt this event more. Prediction of a problem will also lead to the generation of executable runbooks and playbooks, which are agnostic to specific types of automation or automation tools. New challenges such as data quality, model training and explainability have arisen simultaneously and human intervention is still required until we can reach a certain comfort level. There will need to be a manual effort to look at Generative AI proposed solutions, approve them and prove the solutions in lower-level environments, before applying them into production environments.
In the next 18 – 36 months, we will see that morph into risk-taking, where Generative AI will become digital operations. If we look at an Ops team or a SRE team, there are different personas, and we firmly believe that those personas will be assisted by an AI bot. These bots will participate in daily standups, and they will learn. They will participate in issue-resolution processes, and they will learn. They will start participating in retrospectives, and they will learn. This “AI persona” will become a digital worker in a highly integrated digital team. The manual tasks that once were solved through AI are now becoming complex decision-making processes. We are entering the 4th wave of automation improvements using Generative AI.
Be Prepared
Just as the invention of fire, tires, the printing press, the telephone and the lightbulb, what we do with this advancement will greatly shape our future. We must be prepared. And the best way to be prepared is to upskill our practitioners with newer technology skills like AI. The upskilling needs to include all the core and peripheral benefits and concerns to help them manage and improve upon the current day. We need to clarify roles amongst practitioners so there is not an “I’m being replaced by a bot” mentality, and most importantly being open-minded about the possibilities, building on those possibilities and embracing risk rather than fighting it!