Tag: devops

  • A Ferrari and DevOps: More Similar Than You Might Think

    A Ferrari and DevOps: More Similar Than You Might Think

    In a world where customers aren’t short of options, all businesses are characterized by the need to achieve customer delight. From a technological standpoint, a large part of that hinges on fast-tracking the release of high-quality software. A release every quarter is being replaced by a release every week and sometimes even sooner. Expectations have skyrocketed while the timelines have shrunk even more. It is now imperative for all the different components to sync together effectively to create a competitive advantage for the business that can be sustained over a period of time.

    All the water-cooler talk around DevOps notwithstanding, it’s true identity still varies vastly based on the passionate opinions of participants with varied schools of thoughts. It also bears mentioning that while all of their varied opinions carry a sliver of truth, they also are significantly separated from the heart of the matter.

    To better understand the situation, let’s jump into a story: Once upon a time there was a monk who owned a Ferrari and had no interest in selling it. Every morning when the monk left to teach his mindfulness class, there were three blind men who were captivated by the sound of its engine and the smell of burning rubber. And, yet, they couldn’t see the very object that had captured their fancy. So, one fine day they decided to touch the Ferrari and exchange notes.

    The first man touched the broad wheels of the Ferrari and exclaimed that it was a large contraption made of soft rubber. The second man ran his hands across the exquisite curves of the car and said it was like an ancient Greek statue, while the third one placed his hand on the Ferrari’s windows and concluded it was a moving glass palace on wheels. Although each was right in his own way, none came even remotely close to capturing the essence of a Ferrari.

    By now, you don’t need a monk to tell you that the story of DevOps is very similar. For some, DevOps is all about inculcating the right culture so that different groups can work together seamlessly to achieve a unified goal. For others, it is about establishing the right processes and practices that are in sync with an organization’s business goals. And for those with an axe to grind or proprietary tools to sell, DevOps is all about achieving automated nirvana.

    However, the ground reality is that software development teams constantly are facing increased pressure from business leaders to deliver faster than ever before. The business leaders, in turn, are under the hammer of market forces that require them to accelerate or die. The need of the hour is to deliver high-quality software at the rate of knots, while untangling any that might impede the time to market.

    Continuous Everything

    We at Happiest Minds believe the simple approach to DevOps is one that is “continuous” and at its core has the agile mantra of “people over processes and processes over tools.” The idea of continuously evolving and adapting to changing requirements and demands has been captured in what we call the 7Cs of DevOps:
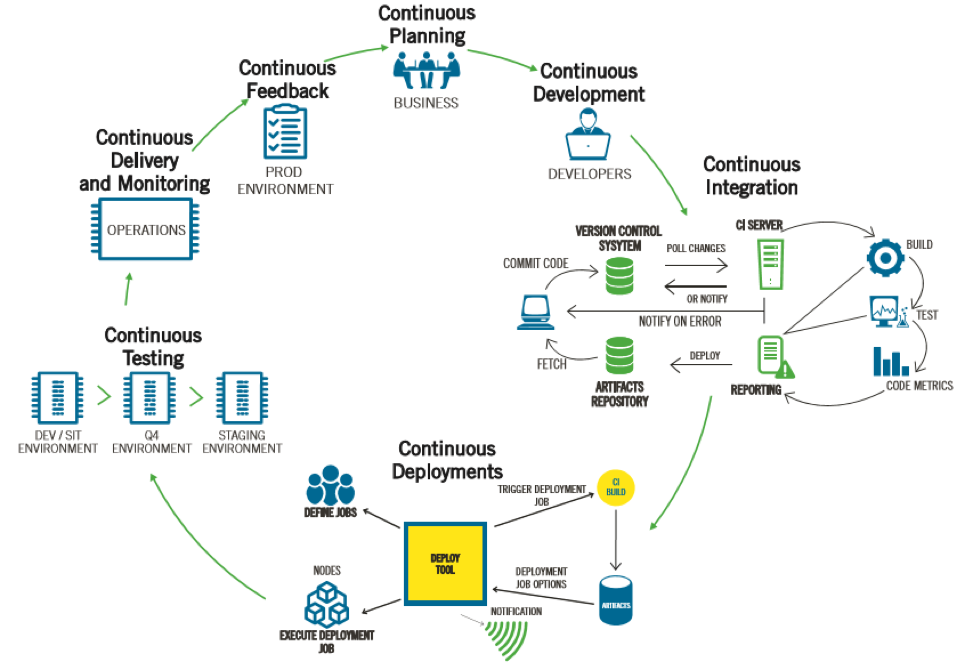
    picture1The main objective is to ensure agile delivery by embracing continuous planning, continuous development, continuous Integration, continuous deployments, continuous testing, continuous monitoring and continuous feedback.

    However, the cultural component of DevOps cannot be overemphasized. A large part of the success or failure of any DevOps engagement depends upon how willingly it is embraced within an organization and the kind of executive sponsorship it receives from the powers that be. The three widely recognized cultural models that most organizations come under are pathological, bureaucratic and generative. Needless to say, organizations that are riddled with a pathological or bureaucratic culture are likely to experience the least amount of success with DevOps because such organizations tend to cover up failures and eventually pin them on the most susceptible scapegoats.

    The breeding ground that DevOps needs to flourish is a generative culture where information is shared freely and openly, the leadership encourages employees to learn and experiment with new ideas and failure isn’t looked at as the end of the world but rather an opportunity to learn and grow.

    Eventually, organizations will have to embrace DevOps as an integral part of their strategy and not just as a liberal, forward-thinking experiment that scores them some brownie points. But it will take some doing, both at the grass roots and in the board rooms. One has to remember that a lot of people are easily attracted to a Ferrari, but perhaps not to the grind that goes into owning one.

    The idea of having a successful DevOps program is much the same—it’s not just about engaging the best vendor or choosing the right tools or paying lip service to creating the right culture; ultimately, it requires overcoming organizational inertia, resistance to change and making a long-term commitment to the philosophy that takes a larger view of how DevOps can help businesses stay one step ahead.

    About the Author / Arsalaan Kashif

    arsalaan-kashifArsalaan Kashif is associate director of Marketing, Product Engineering Services at Happiest Minds Technologies and has a keen interest in all emerging areas of technology and innovation. Having worked with Unisys, Oracle and HCL Technologies for over a decade, he has experience with taking to market products and services across areas as diverse as application services, cloud computing, DevOps and big data analytics to name a few. Outside of work, Arsalaan enjoys watching noir films and reading John Irving classics. Connect with him on LinkedIn.
  • Mainframe Apps and the Long View of DevOps Strategy

    Mainframe Apps and the Long View of DevOps Strategy

    IT is constantly under intense short-term pressures. Line of business (LOB) executives demand a competitive advantage in digital customer engagement now. Marketing leaders demand better customer analytics now. Legal demands better audit reporting now.

    In fact, much of the investment that companies are making in Agile, DevOps and continuous delivery is due to the urgent, short-term demands of the business.

    But short-term actions alone are insufficient for business success. IT leaders must also strategically navigate the vagaries of the digital economy over the long term—or, as Wayne Gretzky’s father taught him, to “skate to where the puck is going to be.” Otherwise, today’s small wins inevitably will lead to tomorrow’s egregious failures and inefficiencies.

    And integration of your mainframe apps and data into your enterprise DevOps tool chain is central to that long-term digital strategy.

    Here’s why.

    The Mainframe: Big, Nimble Iron

    A DevOps tool chain is only as fast as its slowest link. For most large enterprises, that slow link is the mainframe.

    Slow, waterfall-bound and underautomated mainframe dev/test processes are non-trivial—because mainframe applications and data are non-trivial. They typically are an organization’s most important apps and data. So if you can’t modify your mainframe application logic quickly or leverage your mainframe data in new ways easily, you’re uncompetitive toast in today’s fast-moving markets.

    Also, mainframe applications and data typically serve as the back-end systems of record for front-end mobile and web-based systems of engagement. Your ability to innovate and remain competitive when it comes to digital engagement and digital perceived value is, therefore, almost universally contingent on lessons learned from frequent and timely mainframe code drops.

    In other words, everything IT is under pressure to deliver—new mobile apps, better analytics, fulfillment of increasingly stringent compliance mandates, etc.—depends on bringing Agile, DevOps and (ultimately) continuous delivery to the mainframe.

    Just about everyone realizes this. Sure, there are some holdouts who still advocate something they call “bimodal IT”—which prescribes allowing the mainframe to languish in obsolete waterfall and dev/test practices while the rest of the enterprise moves forward. But bimodal lT has proven to be a mistake. An Oct. 31, 2016, Forrester Research report titled, “Predictions 2017: CIOs Push For Speed Amid Volatility,” shines a light on the fatal realities of bimodal IT:

    “In early 2016, many CIOs fell for the false promise of a bimodal strategy. They only pushed part of their team to adopt an accelerated pace — and left others unchanged. But those CIOs are already experiencing the shortcomings of operating at two speeds. Business peer frustration, polarizing and deteriorating cultures, and unsustainable operational complexities will continue, ultimately spurring most of these CIOs to course correct in 2017.”

    Given the explosion of mainframe-related innovation that has taken place in the past couple of years, enterprise IT leaders and industry analysts agree that “mainstreaming” it into enterprise DevOps is the right and necessary strategy (see as examples here and here).

    Some Good Things Take Time

    While instant gratification may be the order of the day—and gain without pain may be an all-too-frequent vendor promise—the reality is that great IT achievements all require effort, investment and time.

    Inclusion of the mainframe into your cross-platform DevOps tool chain is no exception. No CIO can achieve mainframe agility and cross-platform DevOps orchestration by simply waving a magic wand. But there is a clear, practical path to these goals for those with the requisite foresight and leadership.

    That path includes:

    • Modernizing the developer workspace. Most mainframe development is still performed in “green screen” TSO/ISPF environments that require specialized knowledge and limit staff productivity. A modernized, graphical workspace as part of a preferred DevOps tool chain will allow staff at all experience levels to perform dev/test tasks on both mainframe and non-mainframe applications.
    • Graphical visibility into existing code and data structures. Mainframe applications typically are large, complex and poorly documented. These attributes are a major impediment to mainframe transformation. The right tools enable new participants in mainframe DevOps to quickly and easily “read” existing application logic, program interdependencies and data relationships.
    • QA “shift left.” Early detection and correction of quality issues is a central principle of modern programming—and it’s particularly important on the mainframe, where there’s an especially low tolerance for error.
    • Initial Agile training and adoption. Once you put the right development environment in place, you can start shifting your process from a traditional waterfall model with large sets of requirements and long project timelines to a more incremental model that allows teams to quickly collaborate on user “stories” and “epics.”
    • Use operational data throughout the dev/test life cycle. By using operational data in the dev/test life cycle, your DevOps team can ensure that applications perform optimally in production. They also can significantly reduce your MIPS/MSU-related costs by avoiding excessive CPU consumption caused by inefficient code.
    • Agile-enable source code management (SCM) functions. Traditional mainframe SCM environments are inherently designed for waterfall development and thus are incapable of supporting Agile requirements such as parallel development on user stories. The shift to Agile-enabled SCM is, therefore, absolutely essential for mainframe transformation.
    • Automated release management. To keep pace with today’s fast-moving markets, you must be able to quickly get new code into production. That means automating and coordinating deployment of all related development artifacts across all targeted environments.
    • Cross-platform DevOps. Ultimately, you need to fully de-silo your enterprise environment so the mainframe becomes “just another platform”—albeit an especially scalable, reliable, high-performing, cost-efficient and secure one—that can be modified quickly as needed to meet the relentlessly evolving needs of the business.

    ‘What’s My Motivation?’

    With as much as IT departments have on their plates, it’s easy to continue putting off mainframe DevOps integration. But, ultimately, there are only two alternatives to doing so:

    • Re-platform your mainframe applications. This alternative has proven to be a costly and extremely risky undertaking that delivers zero benefits while it consumes resources and potentially disrupts IT operations, or
    • Continue doing nothing. This alternative puts your company at further competitive disadvantage and hastens the day when you’ll experience total mainframe paralysis due to the loss by attrition of all your veteran mainframe developers, QA specialists and operations staff.

    Viewed in this context, genuine investment in the mainframe—whether you call it modernization, mainstreaming or “Millennializing”—is the only reasonable course of action. Such investment starts improving your digital competitiveness immediately, while paving the way for a future where you can make the most of all your resources and confidently transfer platform responsibilities to your next generation of IT professionals. Including the mainframe in your broader DevOps efforts (while extremely valuable) does require commitment, and there are resources available to help. Just be wary of those who may talk a good game, but whose actions don’t really convey a strong commitment to users’ best interests. Fortunately, there are truly dedicated experts who can help every step of the way, and have direct experience modernizing on platform within their own organizations.

    It’s the smart, viable long-term DevOps strategy every CIO of a mainframe-enabled enterprise needs to adopt ASAP.

    About the Author / Christopher O’Malley

    chris-omalley2Christopher O’Malley is CEO of Compuware. He has nearly 30 years of IT experience with past positions including CEO of VelociData, CEO of Nimsoft, EVP of CA’s Cloud Products & Solutions and EVP/GM of CA’s Mainframe business unit, where he led the successful transformation of that division. Connect with him on LinkedIn and Twitter.

  • Continuous Integration vs. Delivery vs. Deployment: What’s the Difference?

    Continuous Integration vs. Delivery vs. Deployment: What’s the Difference?

    “Continuous” is one of the most popular words in the DevOps lexicon. What does it really mean, and what is the difference between continuous delivery, continuous deployment and continuous integration? Keep reading for some perspective.

    Like many technological concepts, continuous integration, continuous delivery and continuous deployment are terms that DevOps teams tend to use without defining them precisely. For that reason, it’s worth taking a closer look at what each of these terms actually means.

    Continuous Integration

    Continuous integration can really mean one of two things, depending on the context.

    In the narrower sense, continuous integration refers to the work done by a continuous integration server, such as Jenkins or Bamboo. A continuous integration server automatically tests code written by individual developers to make sure it can be merged into the main code base. By automating this process, continuous integration servers help developers to write and test small chunks of code on an ongoing basis, which minimizes the risk that a code change could cause serious problems and force developers to revert their application to an earlier state.

    In a broader sense, continuous integration means the constant integration of changes to an application at all stages of the delivery chain. This includes but is not limited to the automated integration testing and code merging performed by an integration server. In this broader definition, continuous integration can include the integration of new design concepts to the delivery pipeline, for example. It also can involve other types of software testing beyond just automated integration tests.

    Continuous Delivery

    In most definitions, continuous delivery refers to the process of delivering software updates to users on a nearly constant basis. Continuous delivery is made possible by continuous integration and other optimizations at earlier stages of the development process. But the definition of continuous delivery gets a little cloudy when you start comparing it to continuous deployment.

    Continuous Deployment

    What’s the difference between continuous delivery and continuous deployment? For some DevOps teams, nothing. People tend to use these terms interchangeably. In fact, they are usually simply abbreviated as “CD,” leaving it up to the listener to decide what the speaker is actually talking about when he hears the term during a conversation about DevOps.

    Some developers draw a distinction between continuous delivery and continuous deployment, however. For example, Mirco Hering writes that continuous delivery requires that the DevOps team manually release updates to users. In contrast, the continuous deployment pipeline is fully automated; users get updates as soon as they are written and tested, with no manual intervention by developers.

    This distinction is a good way to think about the difference between the closely related concepts of continuous delivery and continuous deployment. It’s a distinction that will become increasingly important as technologies such as Docker make it easier to automate application deployment by allowing DevOps teams to drop new container images into production.

    What Does Continuous Mean, Anyway?

    It’s worth mentioning, too, that the word “continuous” is usually something of an exaggeration when used by DevOps folks. It implies that software changes roll down the pipeline in a totally constant, never-stopping fashion.

    That is an exaggeration. Integration, delivery and deployment are almost never completely continuous. In practice, a “continuously” integrated application is likely to be rebuilt and delivered something like every 24 hours, not every single time a code change reaches the end of the pipe.

    That rhythm is still a lot faster, and closer to continuous, than the “waterfall” delivery pipelines that were common before the introduction of DevOps. But it’s still important to understand that, even with all of the automation tools available today, software development is rarely completely continuous.

    — Chris Tozzi

  • Infrastructure Management in the Age of DevOps

    Infrastructure Management in the Age of DevOps

    DevOps has emerged as the de facto cure-all for all that’s wrong with enterprise IT, breaking down silos and replacing them with agile and transparent relationships between developers and operations and seamless, fast workflows that drive greater efficiencies across IT. But legacy IT systems still need tending, even in a DevOps world. They must be secured and scaled, load-balanced, configured, backed up and monitored for compliance, without interruption to the enterprise—all considered infrastructure management tasks.

    And that’s a problem, because these tasks often are handled manually using pre-DevOps processes, which breaks down the very promise of agility, speed and rapid service delivery that DevOps delivers.

    Oleg Chunikhin, chief architect with EastBanc Technologies, emphatically agrees. “If an organization goes down the DevOps path, invariably old habits get carried over into the new world over. For example, if there’s a glitch with release management or a broken disaster recovery process, these problems are dealt with as they occur, or not at all, until they reach a point of critical mass.”

    Chunikhin and I sat down to further discuss the issues and infrastructure management options available to any organization embarking on a DevOps strategy. Here’s our conversation.

    Wolf Ruzicka: Why do infrastructure management tasks pose such a risk to DevOps success?

    Chunikhin: One of the key problems is that there is a limited set of clear leaders in the DevOps tools and architectures market. There are tools for one thing (e.g. containerization) and tools for another (software configuration), and so on. But the market lacks a repeatable, standardized, off-the-shelf solution for infrastructure-level problems.

    Instead, organizations could look to re-architect what’s already there. But this can turn out to be a risky, painful and expensive business. So, you’re left with few options.

    As a result, making the move to DevOps becomes a challenging and risky endeavor for any CIO. If they take that risk, they end up attached at the hip to the time-consuming and manual processes that they already know—which go against the very promise of DevOps.

    Ruzicka: What are the key DevOps infrastructure management considerations that IT needs to bear in mind?

    Chunikhin: First and foremost, don’t delay. CIOs must recognize the problem of infrastructure management in a DevOps environment, before it’s too late. As they explore DevOps, forward-thinking organizations need to consider how its concepts and challenges can fit their organization:

    • How can manual processes be eliminated?
    • How can you strike a balance between the demands of the business and the need to operate in a compliant, stable and secure environment?

    By addressing these challenges early on, you’ll ensure that each of these co-interdependencies is manageable. Before processes break down and critical systems are out of sync.

    Ruzicka: Don’t emerging trends like cluster management and containerization address this very problem?

    Chunikhin: Yes and no. Cluster management is an important part of any DevOps architecture. By abstracting out everyday management tasks, such as backups, and using orchestration to introduce efficiencies into complex environments, it’s a useful tool. But, cluster management software is notoriously difficult to set up for production use. While it can help developers manage many aspects of complex production environments, it isn’t a complete solution in and of itself.

    Containerization helps with multitude of DevOps-related problems (software configuration, package conflict resolution, dependency management, etc.), but containerization alone is also not a complete solution.

    Cluster management software combined with containerization, a.k.a container orchestration technologies, on the other hand, is the most recent and very promising development in the area of DevOps technologies. It promises out-of-the-box SaaS-like capabilities for fast service delivery, production quality, reliability, security, disaster recovery and so on—with less expertise needed for overarching DevOps workflows. This relieves much of the pressure on DevOps teams by eliminating the need for custom software development, lowering maintenance costs and introducing automation.

    Although each solution has its benefits, neither is a panacea for DevOps infrastructure management. Today’s cluster management software, containerization and container orchestration systems differ wildly in their capabilities and are often incompatible with older/legacy software. The task of integrating each with existing back-end systems and ensuring compatibility with existing environments is a perpetual challenge in hybrid deployments, where everything must work together for seamless DevOps. In our experience, each presents unique issues that prevent them from becoming standard on any client project.

    Ruzicka: Without a standard “one-size-fits-all” offering, how do organizations address their DevOps infrastructure management challenges?

    Chunikhin: There are several key capabilities that organizations should be looking at:

    • Portability and vendor-independence.
    • Extensibility and openness, i.e. compatible with widely used modern DevOps standards.
    • Easily deployable business components (such as data storage systems, deployment and release cycle automation tools, application server clusters, etc.)
    • Ease-of-use and immediate readiness for production deployments.

    That’s a lot to check off, but key to this approach is a combination of best practices and the use of open-source DevOps containerization and cloud technologies such as PaaS. PaaS is critical here since it uniquely provides the extensible and ready-to-use pluggable infrastructure services needed to easily configure new services, introduce development efficiencies and take care of the operational concerns that can impinge any DevOps strategy.

    DevOps automation and container orchestration technologies also augment cloud strategy and multiply its benefits by an order of magnitude.

    About the Author /  Wolf Ruzicka

    wolf-ruzickaWolf Ruzicka is chairman of EastBanc Technologies, joining the company in 2007 as CEO. During his tenure, he has overseen the organic growth of the company, taking it from 35 employees to more than 150, with staff turnover of virtually zero. He serves on numerous boards and groups, including the Microsoft Customer Advisory Board for Microsoft Azure and the World Economic Forum’s “Partnering for Cyber Resilience” initiative. Prior to joining EastBanc, Wolf served as president of APIphany (now part of Microsoft) and held leadership positions with MicroStrategy, Mercedes Benz, Lufthansa and more. Wolf holds an Master of Business Administration from Ingolstadt School of Management.
  • DevOps Ascending: Guardrails, Not Guidelines – DevOps For Digital Leaders

    DevOps Ascending: Guardrails, Not Guidelines – DevOps For Digital Leaders

    The season of DevOps is upon us, if not only related to widespread adoption, then certainly in terms of industry emphasis.

    This week, at the CA World ’16 conference, my colleagues and I will be interacting with thousands of practitioners, all of whom have evolving DevOps narratives. Meanwhile, CA was a founding sponsor of the AllDayDevOps conference, held earlier this week, attracting more than 12,000 registered attendees worldwide.

    These events come on the heels of a successful DevOps Enterprise Summit held last week in San Francisco, where many of the industry’s brightest minds gathered to discuss and debate the current state of play. If activity is a reliable indicator of relevance, the growing noise around DevOps adoption has been amplified into a deafening roar.

    All of this stands as further evidence that DevOps is no longer an emerging phenomenon, but rather a ubiquitous movement transforming the manner in which nearly every organization builds and operates software.

    As a result, the DevOps movement is finally ready to move from initial framing of emerging techniques into the domain of defining best practices. Yet, at the same time, given the fluid nature of DevOps itself and its unique correlation with the individual needs of every business and environment, even this notion of best practices is one that mandates flexibility.

    Increasingly, we hear leading experts in the field espouse the need for these practices, but those that serve as “guardrails” that set useful parameters for DevOps adoption and refinement rather than concrete guidelines that dictate specific requirements.

    Such is the tone and goal of the new book that my co-authors Kieran Taylor, Peter Waterhouse and I released this week to help practitioners understand common DevOps challenges, methods and milestones.

    Titled “DevOps for Digital Leaders,” the book examines the genesis and increasing maturity of DevOps, all with the explicit intention of helping to inform further refinement among today’s organizations. After reading it, I’d argue that any practitioner, from total neophytes to hardened DevOps vets, should walk away with a greater understanding of how to bring today’s best practices to bear within their own work.

    Beyond looking at precisely how DevOps has grown in response and parallel to use of agile methodologies in the world of manufacturing thereby transforming the modern software factory, the book offers specific examples of leading adopters that are using these techniques, and related tooling, to re-engineer the very DNA of their business.

    From the core competencies of building, testing and deploying applications to continuous monitoring and management of software to help stay attuned to changing customer expectations, we sought to offer a practical guide to DevOps transformation. Other chapters touch on finer points related to key topics including creation of success metrics and measurement of ROI.

    In one of the analogies invoked throughout the book, we highlight how DevOps-empowered software factories are not unlike the engineering, design and race day teams present in the world of today’s Formula One racing series.

    Pushing themselves and constantly innovating on the fly—clawing for every second in the name of winning the overall title—the comparison fits nicely as we watch this season’s contenders fight it out down to the final race in Abu Dhabi later this month. As with winning customers in today’s applications economy, clearly every little bit counts.

    Again, no matter what—or how much—you think you know about DevOps, we’d like to think that there are tactical “learnings” sprinkled throughout the book that will broaden and deepen your understanding.

    Download your copy today, and let us help drive you down the road to victory. Alternatively, you can order a hard copy of the book via Amazon, with all proceeds being donated by the authors to fund Foundation for Excellence, which provides STEM scholarships to children in India.

    — Aruna Ravichandran

  • Accelerating DevOps with Service Management (and Vice Versa)

    Accelerating DevOps with Service Management (and Vice Versa)

    One of the great misconceptions of service management is what it means. This also is the reason why so many service management initiatives fail. Consider a call center, for example, with many people answering phones and replying to emails. It’s true that a service desk is one of the functions (and in some organizations, maybe even a cornerstone) of service management. It’s also true that the customer or user is one of the main characters in the story of service management. The very word “service” implies there is a customer at the end of that service.

    However, service management is, at the very core, about designing, delivering and redefining services to the customer base—whether those are internal, external or occasional users of the service. User roles may vary over time and users may become part of the supplier chain, and vice versa. A great example of this is knowledge management, wherein users are typically both consumers and producers of information and, thus, the service.

    When we take this higher-level view of the service management practice, our eyes open to new possibilities. In particular, we can see beyond the service desk. The scope of service management widens to the end-to-end delivery of the services in question, retaining the focus on the customer.

    Finding the Cure: It’s All About the Customer, and Communication

    The happy medium and the much sought-after goal of the harmonization of service management and DevOps can be achieved when stakeholders find common drivers. In both worlds, the respective goals focus on the business, delivering value and doing so quickly.

    The following sections present actionable recommendations that can be implemented incrementally across the entire organization. They offer a bottom-up approach. In conjunction with implementing them, senior management needs to support the culture change that is a vehicle, a catalyst and a byproduct of the improvements. In this way, the full benefits of the changes can be analyzed and achieved.

    Tip 1: Stop playing ping-pong with issues

    We’ve all identified an issue with a system, logged it with IT as a ticket and received updates of the progress while the ticket is handed over from team to team—only to discover weeks later that the development team knew about the bug but had de-prioritized it due to lack of interest.

    Surely, by the time the final bit of information reaches users, they are less than satisfied with the result. What’s more, the organization has wasted everyone’s time, not least the time of network, storage and other team members who had to prove it wasn’t their fault in the first place. Finally, development team members could have prioritized their work correctly if they had known about the customer need in the first place.

    With so many implications in the above scenario, why does this happen? The reason is simple: less than optimum process interfaces and lack of information flow. When you’ve identified the problem, the solution is easy: Include relevant data from the development teams, such as defect information, in your chosen IT service management solution.

    Sometimes, the easiest way is to integrate the defects created in development’s chosen tool set to IT service management’s “problem” records. This way there is no need to change the processes per se, as problem records can be linked to issues (or incidents) easily in the service management tool. The integration simply allows for the information to flow between systems and enables a collaborative approach to issue handling.

    In this scenario, when the development team opens a defect, it creates a problem record in the service management system, which, if feasible, could be displayed automatically to users on a self-service portal. Thus, users can search known errors before logging a ticket, resulting in time savings across the whole organization.

    Tip 2: Communicate bugs and known issues to everyone impacted

    But what happens when a user finds a new issue that has emerged due to a bug that has yet to be discovered by developers and testers? Traditionally, the user might log a ticket, which is then analyzed by the IT service team and forwarded to developers for analysis, coding and testing. That might be last of the ticket the user sees, as the feedback loop often is missing.

    The benefits of forwarding the defect information from the user to developers are realized only when there is a way to easily track the whole life cycle of the issue regardless of where it has been initiated. Instead of batch importing records from one system to another, the most advantageous way is to mirror the record sets in the two systems.

    In this example, the feedback loop between the customer and the service desk to the development team is achieved when synchronizing problems and defects in the two solutions.

    Tip 3: Empower the customer by crowdsourcing bugs and new features

    One key metric that contributes to employee satisfaction and retention is the ability of employees to do their jobs well. To accomplish this, they need resources. When employees have all the resources they need to do their job well, more often they are happy than not.

    We are all dependent on technology; there are few professions that do not require technical resources to perform their jobs. If there is a hiccup in the finance solution, for example, the finance assistant may well be the first to find an issue after a version upgrade. Or, a team-wide brainstorming session may result in some great “if-only-our-analytics-software-could …” ideas of how to improve the efficiency of the team.

    But how best to communicate these issues, and capture the many ideas? Possibly, you might even perform real-time impact analysis on which improvement ideas are important to various business processes, and communicate the urgency of each one to the development organization. The inherent problem in many organizations is that users have only one touchpoint to the “DevOps cycle,” most commonly through the IT service management practice. Meanwhile, the rest of the IT organization may use a number of disparate systems to communicate and assign current work tasks that form a basis of shipping new features and functionalities.

    Again, it may be useful to look at the tools already employed throughout the organization, and understand the existing processes and practices. Understanding team functions is important as well, though many teams are fluid in their roles and tool sets used. Once relevant tools are identified, look for mutually beneficial interfaces between them to ensure that users’ requests for new features are not forgotten but logged and picked up by the development team.

    In this example, you could integrate a tool that supports the back office (such as a defect management tool) and tools that support users (such as requirements management and project management tools). This allows you to effectively crowdsource and track upcoming features and bugs, keeping the whole organization informed.

    Tip 4: Don’t forget suppliers

    Include the entire software supply chain in the equation. After an era of outsourcing, insourcing, and multisourcing, many organizations have a diverse supply and sourcing strategy. One of the main reasons for this is to manage risk and ensure business continuity.

    Thus, the last remark is to ensure that all the above examples work in a multisupplier environment. This typically involves contractual preparation. New frameworks such as service integration and management (SIAM) help identify risk and reward in supplier collaboration. These are useful tools for both IT service management and DevOps practices.

    A great example of supply chain integration is an end user reporting an issue. Once it has been reported, it is then centrally analyzed to find the root cause of the issue and the underlying problem is routed to the correct supplier automatically. By synchronizing the information between supplier and customer, not only is each party kept up to date about current issues, but the pipeline and project customer demand are built by integrating incidents, projects and requirements across the software supply chain.

    One of the core aims of both service management and DevOps initiatives is to respond to customer demand as quickly and effectively as possible. Real-time synchronization between solutions is merely a technical solution, but one that has true potential to elevate the response speed.

    Reflections

    Having examined the above four ways to improve the collaboration of DevOps and service management, there are clear solutions to reforming the partnership to drive quicker customer response and satisfaction. But be forewarned: The four recommendations offered are but advice to improve; an organization’s leadership must truly be committed to a culture change to make change happen.

    About the Author /Tuuli Bell

    tuulibellDr. Tuuli Bell is a Partner Account Manager, EMEA at Tasktop. She is a member of the BCS, the Chartered Institute for IT, and the Institute of Physics. For her, happiness is about discovering opportunities to challenge the status quo and about embracing change, be that organizational change, or professional or personal development. Tuuli’s interests outside work include art, science, and nature. Follow her on Twitter or find her on LinkedIn.


  • Are We Leaving Developers Out of DevOps Spinoffs?

    Are We Leaving Developers Out of DevOps Spinoffs?

    SecOps. DataOps. NetOps. Reading these terms, you get the sense that the key to IT efficiency is to make IT Ops work with everyone else. But that’s a mistake, because it leaves developers out of the picture.

    It’s no secret that the DevOps movement has generated a number of other *Ops initiatives, including those listed above. The driving idea behind all of them is that IT Ops teams should work more closely with security teams (in the case of SecOps), data analytics teams (in the case of DataOps) or networking teams (in the case of NetOps). These are only a sampling of *Ops movements; the list could go on.

    To be sure, there are advantages to gain by having IT Ops collaborate more closely with other parts of the organization. But there are an equal number of advantages in doing the same thing with developers.

    To optimize security operations, you need developers, IT Ops and the security team to work together. If Dev is left out of the picture, it’s much harder for the other two parts of this equation to make sure that the code the organization deploys and manages is secure.

    For similar reasons, DataOps, NetOps and almost all the other *Ops you can come up with work well only when Dev also participates. The people who actually design and write the applications are important.

    Rethinking Ops

    Why does this matter? My point is not merely that terms like SecOps and DataOps are misleading because they don’t mention developers.

    On the contrary, giving equal weight to developers is important because if you don’t, you risk isolating developers. Some are already complaining that DevOps is “killing” them. The trend of defining new *Ops practices that don’t mention developers is not helping.

    So, maybe we should start mentioning and thinking about developers more prominently when we are talking about ways to extend the DevOps philosophy to other parts of the IT organization. This is already being done somewhat in the case of SecOps, which you sometimes hear called SecDevOps. But Google lists nearly 13.5 times as many results for “SecOps” as for “SecDevOps.” The numbers are similar if you search for “NetOps” as compared to “NetDevOps.” And I’ve never heard anyone say “DataDevOps.”

    The takeaway is this: Developers are as important as IT Ops to DevOps. Don’t leave them out.

    — Chris Tozzi

  • 4 Essential Practices to Succeed at ChatOps

    4 Essential Practices to Succeed at ChatOps

    We know enterprises are embracing messaging apps and incorporating so-called “ChatOps” into their workflow. ChatOps is, potentially, a powerful way to facilitate more swift decision-making and problem-solving and to receive quick, expert guidance. “With the rise of cloud services that can be easily deployed, and increased awareness and importance given to productivity and collaboration within the workspace, enterprise chat is gaining priority,” says Narain Muralidharan, a market analyst at online customer support software and help-desk software maker Freshdesk.

    As most readers are aware, ChatOps has been fueled by the growth of tools such as HipChat, HuBot, Slack and others for chat-style and instant collaborative software development and project management. But these tools also execute scripts and automate tasks and get workflow approvals to deploy code, kick off software tests and more. As an added bonus, within the chat application exists a clear record of all discussions and scripts executed—something very handy for root cause analysis and troubleshooting.

    With all of that in mind, how are enterprises embracing chat?

    Chatting Down Silos

    “At Threat Stack, we’ve long embraced Slack as a collaboration tool that removes silos within the organization and helps busy operations teams to move quickly and have a fully informed view,” says Pete Cheslock, senior director of Ops and Support at Threat Stack. “We’re seeing this migration toward ChatOps with our customers.”

    Bhaskar Roy, head of growth at Workato, sees chat being embraced at companies ranging from small businesses to Fortune 500 firms. “There are groups in large enterprises who are adopting different chat products and are always looking for what they can do to make chat the center of all communication. When we talk to these companies we find that they believe that chat is a more natural, human, fast way to communicate—which can help in getting things done faster,” Roy says. Chat, he adds, is becoming a “command center for business apps. [Organizations] are using chat to get information from various applications and are looking for ways where they can easily interact with the application from the comfort of their chat/conversational interface.”

    According to the most recent VictorOps State of On-Call survey, ChatOps continues to grow, with 40 percent saying they practice ChatOps during event remediation. That’s up significantly from 28 percent last year.

    Getting the Most Out of ChatOps

    With the tremendous growth in ChatOps, what practices have enterprises learned to bring the most success? Below we list the four essential practices that will help organizations succeed in their ChatOps engagements:

    Embrace adoption: “The main problem that enterprises have in chat penetration internally is adoption. People are resistant to change, and it is usually difficult to change user behavior, especially in the way people work every day,” says Muralidharan. “Some practices are set in stone, like emailing or the good old face-to-face meetings. Start small with pilot teams, get buy in, and create evangelists within the company. A lot can be gained by having a top-down approach to adoption; hence, management buy-in is very crucial.”

    Fine-tune notifications: “The biggest problem that we see is that bots and app notifications that are being pumped into the chats today are making things very noisy, resulting in loss of productivity overall,” says Roy. “What we believe is needed is utilizing bots to enhance the overall individual productivity, where people are notified only for things that are urgent, relevant and something that they need to act on right away. And bots are intelligent so that they understand and learn based on user interactions and are proactively prompting / helping as and when required.”

    Adopt a DevOps mentality: Eric Sigler, head of DevOps at PagerDuty, suggests that “to make the most of chat within your enterprise, it is important to adopt a ‘DevOps mentality,’ where individual teams are more responsible for, and empowered to maintain, their own services. Without this, it’s too easy for teams to ‘throw things over the wall’ and for ChatOps-based tooling to remain restricted to a limited set of users.

    “Existing infrastructure teams need to be a part of this ride as well,” he adds. “If they don’t take the time to understand how their engineers—their user base—want to interact with the tooling and invest in ‘making the easy things easy, and the hard things possible,’ then ChatOps-style tools will get relegated to shiny demos with little practical utility.”

    Avoid DevOps fatigue. Chat alerts can be nagging distractions throughout the day, sucking worker concentration and clamoring for their time. “Customizing notification preferences in your chat client can help enterprises reap the benefits of chat. By personalizing notifications, it ensures that they see the most important chats and are accessible when it matters, but still have the ability to focus without being disrupted by constant pings,” Sigler says.

    What Does the Future Hold for Enterprise Chat?

    What does the future of ChatOps look like? Most of the experts we spoke with say it’s bright. “In an age of digital transformation where slow is the new down, conversationally driven interaction with software is going to play an important role for collaboration and increased agility,” says Sigler. “Overall for founders, hackers and investors, there’s room to innovate when it comes to humans and bots, and there’s a lot of really poor user experiences and bad workflows out there that can be improved by thinking about them through the constraints chat provides.”

    — George V. Hulme

  • Debating the Future of DevOps

    Debating the Future of DevOps

    Change happens at an astronomical pace in the DevOps world, and I constantly see organizations shifting in their needs as the weeks and months go by. One week, the most essential need will be a specific configuration management tool and the next, it will be an urgent requirement to work on containerization.

    Many companies forget that simplicity often is the key and the focus should be on transferring to engineers the requirements of the business and product owners. It’s not always about implementing every new tool just because another awesome engineering team is using it—they might have different business needs and end goals than yours.

    Whether you are consulting for another client or working on your own internal applications, is your focus on how exciting the new container management system is or how to build the best possible end product that the business requires? Your DevOps organization should be focused on understanding these needs as well as the needs of every team across the technology function and more. So how, then, do we find the line between leading, following or resisting trends to create the most competitive advantage for our organizations?

    The DevOps movement will continue to break down silos and increase collaboration. I see DevOps and big data coming closer together; for example, our DataOps teams will have the usual deep understanding of infrastructure, the ability to automate processes, write scripts, build CI pipelines and continuously deploy new code. However, there also will be increasing demand to work with the likes of Splunk and Hadoop to process large sets of data as well as monitoring and logging.

    The cultural idea of bringing our teams closer together, to understand each other and to increase productivity will drive such shifts in skill sets. Other technology touchpoints such as containerization and serverless architecture will continue to spread deeper into organizations, while security and privacy may creep further up our list of priorities as we continue adopting more technologies into our organizations. However, it may take some tough learning curves before we really understand the implications caused by not taking SecOps seriously.

    Every organization has different needs based on the stakeholders, the tech stack, the infrastructure architecture and more. DevOps will continue to shift, take on other aliases and functions, but the truth is that the future of DevOps is simply the future of your organization.

    Understanding what that future holds, however, is up for debate. That’s why we’re hosting an event designed to push DevOps thinking beyond current boundaries among practitioners of varying backgrounds. The Future of DevOps Debate, an invitation-only event, is happening Nov. 10. Salt, host of the event, plans to share footage of the event as well as posting further blogs and articles, providing everyone a glimpse into the day’s conversations and, well, debates.

    The day includes a dedicated session discusses the pain points, experiences and successes leaders have had in their past and current positions. The day’s conversations will be in debate-style format so that everyone gets their opportunity to share thoughts and contribute. The core focus is to work toward the future of DevOps.

    This is the first Future of DevOps Debate, and Salt plans to run a series of events on a quarterly basis. It also contributes to the local New York DevOps community, sponsoring events such as DockerNYC and hosting ServerlessNYC, to name a few.

    It’s clear we are at an inflection point in DevOps, as new technologies and processes strive for attention. Together, we can help shape the future of DevOps and push the industry well beyond its current boundaries.

    About the Author / Conor Delanbanque

    conordelanbanqueConor Delanbanque is managing consultant and head of DevOps USA at Salt. Previously, he was supporting and consulting clients across Europe with their DevOps transformation efforts. Connect with him on Twitter at @ConorDevOps.

  • Why DevOps Needs Cloudified NPM

    Why DevOps Needs Cloudified NPM

    One of the three “ways”—or principles that DevOps guru Gene Kim articulates as defining DevOps—is amplifying feedback loops. One of the key ways that Ops contributes to this amplification is by implementing rich monitoring instrumentation of operational conditions. The move toward more automated configuration management and the rise of cloud-friendly application performance management suites have gone a long way to providing strong feedback loops. However, network performance monitoring (NPM) is sorely in need of cloudification to become relevant to DevOps.

    In one of my previous articles on devopsy.kinsta.cloud, I wrote about the impact of DevOps on IT operations management, and noted that infrastructure management tools have largely lagged behind APM in terms of becoming cloudified and API-friendly. NPM is a case in point. Just to be clear on terms, by network performance monitoring, I’m talking about monitoring that collects metrics such as latency, TCP retransmits and out-of-order and fragmented packets. These four metrics can tell a network engineer a lot about whether the network is the root cause or a major contributing cause to application performance issues. Other metrics and data points that are highly relevant to NPM are interface utilization percentage, traffic flow statistics and, for any apps or services that rely on internet communications, BGP paths. These latter metrics and data sets help engineers locate underlying causes in the network, such as congestion on an interface, large spikes in flows, internet path changes or correlation of performance issues with traffic traversing a particular ISP’s network. Sounds great, right?

    The problem is, the way these metrics have been collected is all wrong for DevOps practice. For the last two decades, NPM tools have fallen into two main buckets: free, manual tools such as TCPDUMP, MRTG and WireShark; and monolithic, siloed commercial tools. Nobody will ever dispute the value of free tools, but at a certain point, chasing problems around with manual tools just doesn’t scale, so sooner or later most NetOps organizations have to invest in commercial tools.

    Commercial NPM tools were primarily architected in a pre-cloud, pre-DevOps era, when data centers all were inside the WAN, applications were centralized and monolithic and all users were somewhere else on the WAN in a campus or branch office.  Metrics collection was performed by appliances via connecting to the span interfaces of major routers and switches at choke points—the junctures of LAN and WAN connectivity.

    That era is disappearing rapidly. Most new applications are being built on a distributed basis, leveraging hybrid cloud. With distributed application components, there is a much more complex mesh of communications at play, much of which will cross networks and the internet. Further, in most cloud environments, you simply can’t deploy an appliance—not even a virtual one, since in many cases there simply are no span ports.

    The problem with traditional NPM goes beyond a lack of fit with modern application architectures. NPM appliances are designed as vertically integrated systems with a GUI as the only real way to get data out of them. As a result, their APIs are usually at best second-class citizens. This is problematic for DevOps because amplifying the feedback loop means being able to serve meaningful real-world data up across different teams.

    The cloud and DevOps gap in NPM is pronounced enough that major analyst firms have taken notice. In May of this year, Gartner analyst Sanjit Ganguli published a research note titled, “Network Performance Monitoring Tools Leave Gaps in Cloud Monitoring.” It’s a fairly biting critique of the NPM space that says, essentially, that the vast majority of current NPM approaches were largely built for a pre-cloud era, and are unable to because the new complexities brought by decentralization and full-stack virtualization. As a result, network managers are left in the lurch when trying to adapt to the realities of digital operations.

    What is needed to cloudify NPM and make it DevOps-friendly?  First of all, with distributed, hybrid cloud applications, there need to be options to embed NPM metric collection agents in cloud server deployments, either directly on app servers or load balancers such as NGINX or HAProxy. With container management and configuration automation tools, deploying lightweight NPM agents to more distributed points is very doable. By collecting NPM metrics on or very close to application servers, you get the most accurate read on “is it the network?” when app performance issues arise.

    Another key aspect of cloudifying NPM is where the analytics happens. Appliances have severe compute and storage constraints. In the era of big data and cloud-scale compute economics, relying on appliances for NPM analytics is beyond outmoded. There are a plethora of open-source big data platforms as well as a growing number of  emerging commercial SaaS options for NPM analytics. Today, big data network analytics platforms allow engineers to perform deep ad-hoc analyses on billion-row datasets and get answers in seconds.

    DevOps’ mandate for amplifying the feedback loop plus the availability of copious cloud compute capacity means that there is no excuse to not aggressively measure everything, including network performance. Networking teams can and must go beyond config automation to change the way and the scale they gather and share metrics to server and app dev teams. Cloud-friendly NPM is a needed step to bring about Net DevOps as a lived reality in IT.

    About the Author / Alex Henthorn-Iwane

    AlexAlex Henthorn-Iwane is the vice president of Marketing at Kentik. He has more than 20 years of experience bringing new technologies in networking, security and software to global markets. Henthorn-Iwane leads the global marketing strategy for Kentik and helps the company bring its story and solutions to network-dependent organizations around the world. Connect with him on LinkedIn, Twitter or SlideShare.