Tag: Cybersecurity

  • Synopsys Taps NowSecure and Secure Code Warrior to Improve DevSecOps

    Synopsys Taps NowSecure and Secure Code Warrior to Improve DevSecOps

    Synopsys has partnered with NowSecure and Secure Code Warrior to enable organizations to better identify where they can improve DevSecOps best practices.

    Scott Johnson, senior director of product management for the Software Integrity Group at Synopsys, said the data captured by the application security testing tools can now more easily be used to identify ongoing issues that, for example, can be used to create better mobile application security tests using the NowSecure platform.

    That same data can also be fed into the online learning platform Secure Code Warrior provides to enable developers to improve their cybersecurity skills.

    Collectively, those observability capabilities will significantly reduce the overall level of application security risk that organizations today experience, noted Johnson.

    Secure Code Warrior CTO Matias Madou noted that improving the cybersecurity expertise of developers is more critical than ever. The more expertise they have the easier it becomes to remediate issues before and after applications are deployed in a production environment.

    That’s going to become an even more crucial requirement as the rate at which code is being written increases exponentially with the rise of artificial intelligence (AI). While AI can improve the quality of code being written, it’s also likely an AI platform trained using code collected from the internet is going to introduce vulnerabilities. This is because the code used to train an AI model, such as ChatGPT, from a quality perspective is inconsistent, he added.

    It’s not clear at what rate application security is improving due to the adoption of DevSecOps best practices, but as AI becomes more widely employed by developers a paradox is starting to emerge. There is no doubt vulnerabilities developers have inadvertently introduced are being eliminated by AI tools that surface examples of secure code for developers to copy and paste. However, not every example of code is completely devoid of risk, so there is going to be more code that needs to be scanned for vulnerabilities.

    This issue will become particularly problematic as regulations making organizations more accountable for application security will become law in the months ahead. Thanks to AI, there is no doubt organizations will be building and deploying applications containing vulnerabilities at much faster rates.

    The hope is that AI tools specifically trained to identify vulnerabilities will soon be embedded in the tools that developers and DevOps teams rely on to initially build and deploy applications. However, a gap is emerging between the pace at which AI tools are being used to build applications and the availability of tools using AI to first detect vulnerabilities and help automate the remediation process. As a result, application security issues, at least for the immediate future, will continue to bedevil DevOps teams.

    Unfortunately, given the insecure code that has already been deployed, it may be years before application security issues are resolved to the point where the current level of stress for all concerned is meaningfully reduced.

  • Communicating Common Web App Security Threats to Developers

    Communicating Common Web App Security Threats to Developers

    Automated security testing tools enable us to identify web application vulnerabilities early and often, but what happens after a vulnerability has been identified? Does your security team have the coding skills to mitigate it themselves, or are your developers suddenly security experts once a vulnerability is discovered? Most likely not. So, how do we go from finding vulnerabilities to fixing them? Enter a key component of shifting left: Collaboration between security and developer teams. And a portion of that involves providing developers with the context they need to prioritize and remediate threats appropriately.

    Useful context includes (but is not limited to):
    – The vulnerability type
    – How it works
    – What malicious actors can accomplish by exploiting the vulnerability
    – Ways to mitigate

    The list below provides context around five common web application security threats to help you collaborate on resolutions with your developers. A shared understanding of these threats and how to mitigate them early in the development life cycle will significantly improve overall security posture without impacting software delivery.

    SQL Injection

    A SQL injection attack is executed when an attacker injects malicious code into an application’s database through user-controlled data. While these types of attacks can accomplish many different things, there are several common outcomes. SQL injection attacks can enable attackers to gain unauthorized access to sensitive data stored in the database, and largely depending on what data is stored in a particular database, can result in access to authentication information, financial information and personal data. The second key outcome is the manipulation or removal of data. Malicious actors can then leverage this outcome to access the larger infrastructure and find even more sensitive information.

    To help protect against SQL injection attacks, organizations should never implicitly trust and always validate user input and utilize input encoding, prepared statements, parameterized queries or stored procedures instead of dynamic SQL statements whenever possible. By combining frontend and backend standards to prevent SQL injection from happening, your application can increase its security against this type of threat.

    Cross-Site Scripting (XSS)

    Another common web application attack is cross-site scripting (XSS) which involves inserting malicious code or script into a website. The website will then execute on the given script, enabling attackers to steal sensitive user data, such as session tokens and cookies.

    There are three main types of XSS attacks we regularly encounter: Reflective, stored and DOM. Reflective XSS attacks insert malicious code into a website that is immediately executed, whereas a stored XSS attack involves injecting malicious code into a website that is stored and executed later. DOM XSS is an attack pattern that is used more in single-page applications but acts similarly to reflective XSS. If successful, a cross-site scripting attack can lead to the theft of user session IDs and/or website defacement and lead to redirection to malicious sites, thus enabling phishing attacks.

    Similar to SQL injection attacks, to protect against cross-site scripting, organizations must never implicitly trust and always validate user input and use output encoding techniques while also using auto-sanitization libraries such as OWASP AntiSamy and implementing a content security policy.

    Cross-Site Request Forgery (CSRF)

    Cross-site request forgery (CSRF|XSRF) attacks trick users into performing an action on a website without their knowledge or consent. This is often achieved by inserting a malicious link or form into a website where a user is already authenticated. When the user clicks the link or submits the form, the action is performed on their behalf, leading to potential data loss or unauthorized access.

    Mitigating these types of attacks requires leveraging CSRF protections which are built into the framework you are using, if applicable. Using CSRF tokens, which are unique, randomized values associated with a user’s session and can verify the authenticity of a request will also help migrate an attack. In addition, SameSite cookie settings can help prevent attackers from being able to send requests on behalf of a victim.

    Insecure Direct Object References (IDOR)

    Insecure direct object references (IDOR) occur when an application exposes direct object references, like URLs or database keys, which allow attackers to gain access to restricted data by manipulating these references.

    Safeguarding against IDOR requires the implementation of proper access controls and session management, ensuring that only authorized users have access to certain resources or data. Also, avoid using predictable references and instead utilize globally unique identifiers (GUIDs) to prevent attackers from guessing the direct object references they need to access restricted data.

    It is important to remember that IDOR-based vulnerabilities don’t occur singularly and are coupled with other vulnerabilities to become an effective attack vector.

    Remote Code Execution (RCE)

    Remote code execution (RCE) gives an attacker the ability to execute arbitrary code on a server, which can lead to the compromise of entire systems and offer unauthorized access to highly sensitive data. RCE attacks can occur through an array of means, including exploiting vulnerabilities in code libraries or injecting malicious code through user input fields. As illustrated by the critical zero-day exploit discovered in the Java logging library Log4j in December 2021, RCE can be a determinantal vulnerability.

    A successful RCE attack can cause denial-of-service (DoS) attacks, expose sensitive data, lead to illicit cryptocurrency mining and the execution of malware. In more severe instances, a successful RCE attack can allow an attacker to gain full control over the compromised machine.

    The good news is organizations can implement the same tactics used for protection against SQL Injection and XSS—never implicitly trust user data and adhere to strong user input sanitization and validation.

    Understanding Common Threats

    Safeguarding applications and ensuring a sound security posture requires both security and developer teams to have a shared understanding of common threats and the associated risks.

    The details provided in these examples only scratch the surface in terms of useful context for developers. When you can pinpoint when a vulnerability was introduced, which repository branch and code commit it’s associated with and whether it is exploitable from the outside, you create a powerful feedback loop that accelerates fixes.

  • Bionic Extends Application Security Posture Management Platform

    Bionic Extends Application Security Posture Management Platform

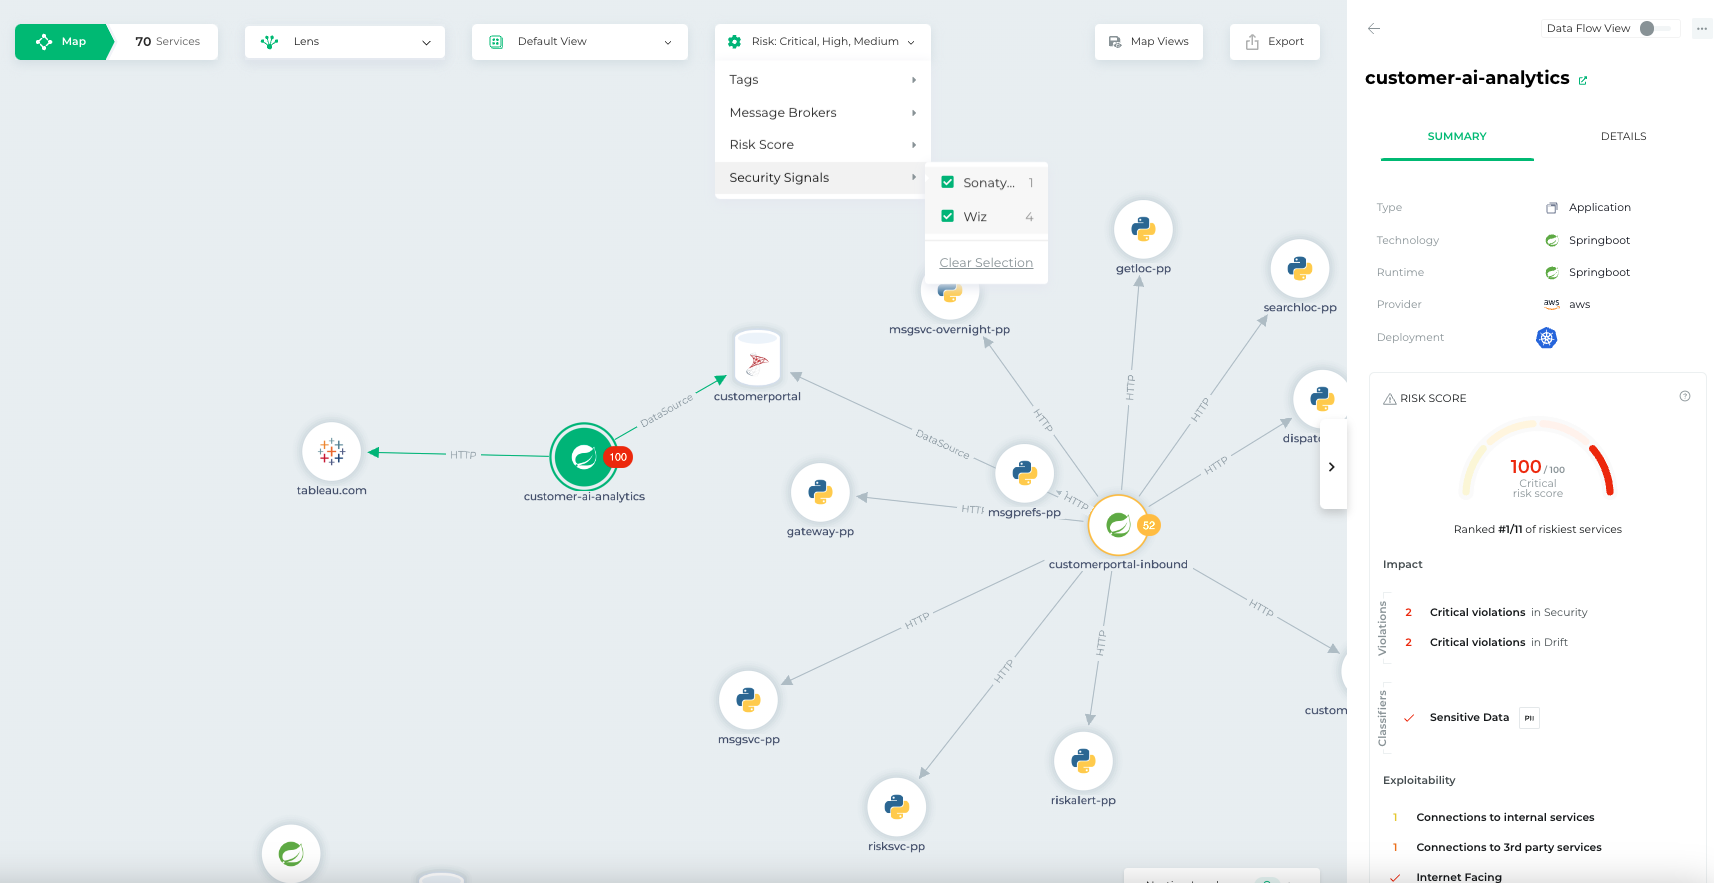
    Bionic this week added a pair of tools to its application security posture management (ASPM) platform that make it simpler to triage threats based on severity and attach a risk score.

    Josh Cho, senior director of global systems engineering at Bionic, said the Bionic Signals and Business Risk Scoring tools ingest data from third-party security tools to provide analytics capabilities. The first two vendors with which Bionic has integrated its ASPM platform are Wiz and Sonatype.

    The goal is to partner with additional vendors that provide unique cybersecurity capabilities that don’t compete with one another, said Cho.

    The agentless Bionic ASPM platform enables organizations to manage application risks by continuously collecting data from services and their dependencies, application programming interfaces (APIs) and DevOps data flows both in pre-production environments and after applications are deployed. Bionic then assesses any changes made to those environments based on a set of cybersecurity policies it provides. If an issue is discovered, the platform will create an alert informing the appropriate development team of best practices that eliminate the issue.

    While there is a lot of effort being made to shift more responsibility left toward application developers, there is often not enough cybersecurity context provided, said Cho. Bionic’s ASPM platform aggregates data from multiple tools to enable DevSecOps teams to better prioritize their remediation efforts, he added.

    It’s not clear how much organizations have embraced DevSecOps best practices, but one of the issues that needs to be addressed is the often-conflicting alerts generated by the various tools being used. Bionic is making a case for an ASPM platform that synthesizes data from multiple sources to streamline DevSecOps workflows.

    One way or another, more organizations will be embracing DevSecOps to better secure their software supply chains as more regulations are mandated. The challenge they face today is that most application developers—and the DevOps teams that support them—don’t have a lot of cybersecurity expertise. As a result, it becomes difficult to discern which vulnerabilities require immediate attention and which can be addressed in a regular update. In some instances, an alert generated by a cybersecurity team may not even been relevant—because the application in question is not internet-facing or the impacted module has not been loaded.

    In fact, it’s that very lack of context that often results in application developers disregarding the alerts generated by cybersecurity teams. Whenever there is a breach, however, cybersecurity teams always demand to know why their alert was ignored.

    No developer, of course, deliberately sets out to build and deploy vulnerable applications. In the race to meet delivery deadlines, there are always going to be tradeoffs. The issue then becomes keeping track of the cybersecurity technical debt that accumulates over time. An ASPM solution provides a means to keep track of that debt to enable DevSecOps teams to keep the risk in perspective.

  • How to Empower DevSecOps in a Complex Multi-Cloud Landscape

    How to Empower DevSecOps in a Complex Multi-Cloud Landscape

    Organizations are embracing cloud-based application delivery for speed of delivery and scale. However, the proliferation of multi-cloud systems to access and maximize the cloud’s capabilities is driving complexity in IT environments. Many organizations do not consider how multi-cloud adoption is expanding their attack surface—and the risk is growing: The 2023 CrowdStrike Global Threat Report found cloud exploitation cases grew by 95% year-over-year and cases involving threat actors targeting cloud environments were up 288% from a year prior.

    The expansion of cloud infrastructure and services has increased the pressure on organizations to protect assets within their multi-cloud environments. To alleviate this burden, more businesses are turning to DevSecOps, a practice that incorporates security at an earlier point in the development life cycle. This practice of shifting left helps improve the quality and reduces risk of applications, as well as makes the delivery of these applications more efficient since any potential issues are found earlier in the development process.

    DevSecOps is being adopted rapidly by organizations today to address the expanding array of threats and increasingly sophisticated attacks targeting multi-cloud environments. However, securing the cloud can be tricky due to its dynamic nature and multi-cloud makes shift left security even more complex. For DevSecOps to truly be effective, here are three things that organizations should consider doing.

    1. Strive for Complete Visibility in a Multi-Cloud Environment

    It is important that DevSecOps teams have a comprehensive understanding of their multi-cloud environment. Without it, they will not be able to identify a variety of security risks including vulnerabilities, privileged credentials, misconfigurations and other threats that may leave their organization’s cloud assets vulnerable.

    The best way to get full visibility across multi-cloud environments is through a cloud security posture management (CSPM) tool. With a CSPM tool, DevSecOps teams can identify misconfigurations and proactively detect threats. In addition, DevSecOps teams should also use a cloud infrastructure entitlement management tool (CIEM) to manage identities across all of their cloud infrastructure resources. The primary goal of a CIEM tool is to mitigate the risk that comes from the unintentional and unchecked granting of excessive permissions of user credentials.

    2. Visibility and Compliance Do Not Guarantee Security

    Organizations need to develop a comprehensive security strategy to mitigate issues within the development process. This may include implementing tools, automation and standards to enable developers to follow the desired security behavior. These approaches reduce developer friction, as well as diminish the likelihood that unsafe or default configurations will be used. Historically, DevOps teams have pushed back on integrating security since their concern is that it slows down the development lifecycle. However, DevSecOps is gaining traction in recent years because organizations are realizing integrating security sooner in the development lifecycle is more efficient than reactively patching problems as they arise.

    A tool that DevSecOps teams should look to leverage is cloud workload protection (CWP) because it offers breach protection for workloads, containers and Kubernetes, while enabling them to continue to build, run and secure applications with speed and confidence.

    3. Create Consistency With Security Tools

    Ideally, organizations should opt for a single platform that consolidates capabilities such as CSPM, CWP and CIEM. The reason for consolidation is to eliminate security gaps from having multiple security solutions. As a result, DevSecOps teams should turn to cloud-native application protection platform (CNAPP) tools to create more consistency within the multi-cloud environment.

    Securing multi-cloud environments can be complex. By empowering DevSecOps teams using these best practices, organizations will be able to move faster than today’s adversaries and have the agility to quickly adapt to present and future cybersecurity challenges in their multi-cloud environments.

  • GitLab Adds More AI and Cybersecurity Capabilities to CI/CD Platform

    GitLab Adds More AI and Cybersecurity Capabilities to CI/CD Platform

    GitLab this week delivered an update to its continuous integration/continuous delivery (CI/CD) platform that adds additional generative artificial intelligence (AI) and cybersecurity capabilities.

    The GitLab 16 release included cybersecurity capabilities such as centralized policy management, expanded compliance reports and controls, compliance dashboards and default Level 3 attestation for the supply-chain levels for software artifacts (SLSA) framework.

    At the same time, GitLab this week also made available an emergency patch for two modules that have a path traversal flaw, tracked as CVE-2023-2825, that could allow unauthenticated users to read arbitrary files on the server under certain circumstances.

    In terms of generative AI, GitLab 16 added a value stream forecasting capability that automatically generates workflow summaries for senior managers. GitLab is also adding a code refactoring capability and the ability to automatically resolve vulnerabilities to an update to GitLab 16. Previously, GitLab made available a ‘suggested reviewers’ features, an ‘explain this code’ and an ‘explain this vulnerability’ capability that are all enabled by large language models (LLMs) developed by Google. GitLab has also partnered with Oracle to provide additional AI capabilities enabled by machine learning algorithms. In 2021, GitLab acquired UnReview, a provider of a tool that uses AI to identify which expert code reviewers to assign to a project based on the quality of their previous efforts and current workloads.

    David DeSanto, chief product officer at GitLab, said with 10 AI capabilities GitLab is providing more of these types of capabilities than any other DevOps platform provider. In addition, those capabilities are distributed across the entire software development life cycle rather than being focused solely on making developers more productive, he noted.

    That’s critical, because if AI capabilities are only focused on developer productivity, an imbalance is created; DevOps workflows will not be able to absorb the increased amount of code that will soon be moving simultaneously through pipelines, DeSanto added.

    AI will also further fuel adoption of platform engineering as a means for centralizing DevOps management. It’s becoming more apparent that infusing these types of capabilities into DevOps platforms built and maintained by an internal IT team is going to be a major challenge, he added.

    There is no doubt that generative AI capabilities will soon become widely integrated across DevOps workflows. That will enable developers to build more secure code faster while at the same time making it simpler for software engineers to maintain large codebases. Just about every job function imaginable will be impacted to varying degrees. In the case of DevOps teams, the ultimate impact should involve less drudgery as many of the manual tasks that conspire to make managing DevOps workflows tedious are eliminated. In fact, AI may ultimately make DevOps, as a methodology for managing IT, more accessible to a much wider range of organizations.

    As AI advances, there should still be plenty of demand for human expertise. For better or worse, the nature of the expertise required, however, will undoubtedly be at a much higher level than it has previously been as more low-level tasks are automated. The challenge is determining how and where to refocus the efforts of the DevOps teams to add higher value.

  • Four Trends Defining the Observability Market in 2023

    Four Trends Defining the Observability Market in 2023

    Observability is a market that has grown exponentially over the past few years. It started as a buzzword in late 2015 and early 2016, and since then we’ve seen dozens of insurgent companies rush in, eager to stake their claim in a new (albeit loosely defined) market. Incumbent companies also rebranded their wares, hoping to capture some of the momentum that comes from the new term.

    Venture capital saw the market opportunity, too. By my conservative estimate, observability companies raised nearly $2 billion over roughly the last two years alone (I’m including some cybersecurity companies, which I’ll explain later).

    In the seven or so years since its inception, the observability market has fragmented and specialized into categories such as application, data, network and edge observability. On the artificial intelligence and machine learning side, there is model observability and AIOps. Connecting it all are observability pipelines.

    While more businesses than ever know about observability and have built it into their tech strategy, category awareness still has a long way to go. And though the dollars were flying fast and furious a couple of years ago, the economic cycle has turned against risk, and growth funding rounds are harder to come by. It’s time to step back and examine the key trends defining today’s observability market.

    Staffing Shortages: A Blessing and Curse to Observability

    Many companies in the observability space, regardless of their subcategory, represent net-new work for IT and security teams. A new application performance monitoring (APM) platform may offer a marginal improvement around APM’s golden signals, but that marginal improvement is a substantial lift for the end users tasked with implementing and deploying the new platform. While software may get sold, overworked ITOps and SecOps teams may decide the effort isn’t worth the perceived ROI, leaving the software on the shelf.

    On the other hand, observability products that reduce toil for operators will continue to outpace market growth rates. IT departments face acute shortages in skilled staff, leaving companies with little choice but to seek out software that automates high-effort, low-value tasks or otherwise offers a force multiplier to existing teams. Subcategories like AIOps and observability pipelines can address those needs.

    Consolidation is Needed to Simplify the Market

    Another looming hurdle for the nascent observability market is feature similarity between companies in a subcategory. Two subcategories where this is apparent are application and data observability. In the application observability space, several companies were founded in the wake of the availability of extended Berkeley Packet Filter (eBPF) technology. eBPF allows you to extend the capabilities of the Linux kernel at runtime, and a common use case is to trace applications running in user space. While this is a great technology with several uses, there are simply too many companies with the same idea, the same go-to-market strategy and same limited feature set.

    Data observability is another subcategory riddled with clones. Data observability started as a reaction to operational brittleness in the modern data stack, and there are only a few companies with marked differentiation here. I agree with Matt Turck’s assessment that data observability products will drift into the well-defined (but arguably less sexy) data quality category.

    CFOs are Looking to Reduce Tool Sprawl and Cut Costs

    The challenges with raising growth rounds have been well documented. VC funding represents the supply side of the finance puzzle and IT budgets are the demand side. The demand side is getting squeezed as CFOs clamp down on budget growth. Deals are taking longer to close and often involve more parties eager to reject a budget request from another team because it means more money for their team.

    A common refrain from CFOs today is that any new spending must be more than offset by corresponding savings somewhere else. This puts the products representing net-new work with little marginal utility at risk. Observability vendors today need a strong consolidation (e.g. can reduce tool sprawl, serve multiple teams, etc.) and cost savings story to survive in a difficult budget climate.

    Cybersecurity remains a budget bright spot. According to a recent survey from IDC, 27% of respondents stated cybersecurity budgets were immune from budget cuts. With changing SEC rules highlighting the need for board-level cybersecurity expertise and reporting of breaches, coupled with the new National Cybersecurity Strategy, the priority around preserving these budgets is clear.

    Cybersecurity is Pure Greenfield for Observability

    A few short years ago, SecOps teams, threat hunters and incident response teams didn’t have enough data to create an accurate picture of their environment. Endpoint data was sparse and incomplete, cloud-based application deployments were still uncommon, the network remained between the office and data center, and so on.

    Today’s SecOps teams, threat hunters and incident response teams have too much data to understand their environment. There are too many alerts and too little context, making finding the signal through the noise a difficult, if not impossible, proposition. From a compliance perspective, much of this data must be retained for longer periods, driving up storage costs.

    This is where the principles of observability benefit cybersecurity teams. Much like site reliability engineers need to trace an error well after it occurred, cybersecurity professionals need to trace a breach or find threats over huge volumes of data. They need robust exploration tools, rational data storage and routing options, and, most of all, the ability to do this while maintaining budgets. This is where observability and cybersecurity converge.

    Seven years young, observability remains a nascent market despite its rapid growth. Though the market will face growing pains, the opportunities and upside are bright.

  • Technical Debt is a Major Threat to Innovation

    Technical Debt is a Major Threat to Innovation

    A survey published today suggested that technical debt is starting to take a heavier toll as IT environments continue to become more complex to manage.

    The survey of 400 IT leaders at organizations with 1,500 employees was conducted by Foundry, the market research arm of International Data Group (IDG) on behalf of Insight Enterprises, a provider of IT services. The survey found that 86% of respondents reported their organization was impacted by technical debt over the past 12 months, with the top areas affected being the ability to innovate (43%), meet service level agreements (41%) and avoid downtime (37%).

    Technical debt is created when organizations cut corners and leave known bugs in the race to meet application delivery deadlines. Application code is often not as thoroughly tested as it should be. In some cases, it turns out that what was intended to be a minimum viable product doesn’t scale all that well. Quick fixes needed to improve performance are also frequently undocumented. Inefficient code also winds up consuming more IT infrastructure than required, which adversely impacts everything from cloud costs to the amount of carbon generated.

    Juan Orlandini, chief architect for the Cloud + Data Center Transformation (CDCT) division of Insight Enterprises, said every organization struggles with technical debt; it will never be eliminated, but it does need to be contained, he added.

    The challenge is instead of trying to keep the proverbial IT lights on during the COVID-19 era, IT teams are now being asked to innovate to advance digital business transformation initiatives, said Orlandini. A full 87% of survey respondents cited modernizing critical applications as a key success driver.

    As a result, many organizations are embracing platform engineering to bring more structure to their DevOps processes, he noted. The challenge, however, is striking a balance between a more centralized approach to DevOps and maintaining the ability of developers to innovate, said Orlandini.

    The issue, of course, is that in addition to massive technical debt, the latest generation of applications are more distributed than ever. The survey found 91% of respondents now rely on multiple public cloud providers for different workloads, with 54% of data residing on a public cloud. However, the survey also found on-premises IT environments are still relevant, with 20% planning to repatriate select public cloud workloads to an on-premises model over the next 12 months.

    Nearly three-quarters (72%) of respondents also noted data volumes are growing faster than their ability to manage them, with 64% ranking implementation of a data governance program to improve data management as their top data-related objective this year. Just over a third (35%) of the data estate is now, on average, driven by edge workloads, with 29% of respondents reporting that at least 50% of data volumes now reside on the edge. Nearly two-thirds (64%) expected that to increase in the next 12 months.

    A total of 85% of respondents also indicated their organization is using artificial intelligence (AI) to some degree to drive business insights and/or efficiencies, although only 36% reported having optimized their use of AI and machine learning (ML) across the enterprise.

    Finally, cybersecurity also remains problematic, with 51% reporting they were impacted by a cybersecurity breach over the past 12 months. Just 20% resolved their issue in one day, while 31% needed less than a week. Nearly half (49%) required one week or more to recover.

    It’s clear that IT isn’t becoming any easier to manage. IT teams need to find ways to build and deploy new applications while reducing technical debt so it doesn’t strangle future innovation.

  • Predict 2023: Stand and Deliver

    Predict 2023: Stand and Deliver

    It’s that time of year again—the New Year’s ritual: Time to predict the big trends in your world for the new year. By now you have probably seen dozens of headlines, articles, videos and interviews telling you what big trends will shape the coming year. Here at Techstrong Group, our Predict virtual event is built around this New Year’s ritual. This year, Predict is January 12, 2023 and, not to blow our own horn, but I think it is our best Predict event yet.

    What sets this event apart? Well, we have a real Techstrong Research team now headed up by Mike Rothman and Mitchell Ashley who are leading this year’s Predict event. We will have four tracks: DevOps, cybersecurity, cloud-native and digital transformation. Each track will kick off with either Mitchell or Mike presenting a Techstrong Research trends report for that market.

    After the trends report, there will be a keynote panel featuring some of the top thought leaders in each of these fields. This will be followed by other sessions that explore what this upcoming year has in store. Many of these sessions will be streamed live on January 12, 2023 and allow for audience questions and input.

    But wait—there’s more! One session I am really looking forward to features John Willis and Damon Edwards live at Techstrong Group Studios giving us their personal predictions for 2023. John and Damon need no introduction to the DevOps community. This should be a great session, so don’t miss it. I am also moderating two great panels; one is with C-level executives from CloudBees, JFrog and GitLab and Kohsuke Kawaguchi (KK), the creator of Jenkins and co-CEO of Launchable. The other panel features my friend Emmet Keefe of Insight Ignite who has his finger on the pulse of the digital transformation market.

    The best part? We’ll have a live chat available so you can interact with the speakers and network with your fellow attendees. And you can register and attend Predict 2023 for free. That’s right—this analyst-led, daylong virtual interactive event is free. Don’t wait! Head over right now and register here.

    Another highlight will be the announcement of our DevOps Dozen winners at the event. This year, the DevOps Dozen broke all of our previous records for both nominations and community votes. It has been quite a tough job selecting the winners from such incredible submissions and nominations.

    I haven’t even mentioned the amazing cybersecurity sessions hosted by Mike Rothman or the sessions covering the cloud-native vision with Mitchell Ashley and digital transformation with Mike Vizard. There is just so much great insight you won’t want to miss.

    A big thank you to all of the sponsors, panelists and speakers who help us make this event a true standout. If you want to get a head start on learning about big trends for 2023 and how they’ll impact cloud-native, cybersecurity, DevOps and digital transformation, check out these articles and register for Predict 2023 on January 12, 2023. We hope to see you there! 


  • Best of 2022: Measuring Technical Debt

    Best of 2022: Measuring Technical Debt

    As we close out 2022, we at devopsy.kinsta.cloud wanted to highlight the most popular articles of the year. Following is the latest in our series of the Best of 2022.

    What is enterprise technical debt? Technical debt slows down organizations and hampers their ability to deliver. Studies show that technical debt can triple the cost of support for technical products and services. Beyond this, technical debt can cripple a company’s ability to make the rapid changes needed to compete in today’s marketplace. Those all describe the effects of technical debt, but doesn’t get to the heart of its definition. Therein lies the problem.

    Technical debt is a term that many in technology are familiar with but few seem to understand. Fewer still have a clear way to measure it. Are security vulnerabilities debt? What about teams or applications that have not been migrated to standard communications platforms or shared processes? And, if all of this is debt, how do you measure it?

    Technical debt is often too narrowly scoped, focusing primarily on software defects and other code-related ‘debt’. However, the technical debt that large enterprises acquire goes far beyond code and has much more serious consequences. To truly address issues related to technical debt, we need to understand it not just in terms of software defects and backlog, but also security debt, process debt and organizational debt. Once we understand the scope, we can leverage financial tools as the basis for our measurement. 

    History of Technical Debt

    The term technical debt was originally coined as a metaphor by Ward Cunningham, one of the original authors of the Agile Manifesto. He introduced the concept to justify the work his team was doing to refactor a financial application, saying, “If we failed to make our program align with what we then understood to be the proper way to think about our financial objects, then we were going to continue to stumble on that disagreement which is like paying interest on a loan.” In Introduction to the Technical Debt Concept, the Agile Alliance noted that, “ … [I]n 1992, at the OOPSLA conference, Ward provided additional details (slightly paraphrased here based on feedback from Ward): ‘Shipping first-time code is like going into debt. A little debt speeds development so long as it is paid back promptly with refactoring. The danger occurs when the debt is not repaid.’”

    So, the original definition provides a metaphor that compares the impact on companies’ ability to deliver code based on the need to refactor to the financial debt incurred on a loan. While this concept has gained wide acceptance, there remains no single agreed-upon definition nor a single way to quantify the concept.

    This concept of debt is, however, very useful as it recognizes there is a cost involved with code defects; defects impede the ability to deliver. However, in modern enterprise environments, this concept needs to be expanded to include other elements which impact the ability to deliver value to the customer, including security-related debt and even organizational debt. There are many items that can (and should) be understood as part of technical debt including:

    • Known bugs that go unfixed 
    • Problems associated with poor code quality or poor design
    • Lack of code test coverage including tests to ensure quality, security and performance
    • Code or artifacts that aren’t cleaned up when no longer in use
    • Obsolete technology that is expensive, difficult to manage and unable to meet the demands of digital transformation
    • Incomplete or outdated documentation or missing comments
    • Known security issues that need to be remediated
    • Diversified tool sets that are not aligned with organizational standards
    • Technology organizational constructs that are not aligned with organizational standards

    It is important to note that, just as with financial debt, not all technical debt should be repaid. There is a concept of “good debt” or, to further the financial metaphor, money borrowed because the opportunity for investment earnings is greater than the rate of cost incurred by the debt. If, for example, one can borrow at 3% and earn at 10%, then it makes good financial sense to accrue debt. Similarly, if the money a firm can make by introducing a new feature outweighs the cost of resolving some debt then the team should prioritize feature work. This cost calculation will often change based on the product life cycle stage, as well. During early product development, the opportunity offered by new feature development often far outweighs the potential cost associated with the risk of compliance issues. However, as a product matures and gains more customers, the risk increases and the benefit of new features may decline. This is important because we do not want to imply that all technical debt should necessarily be fixed. There are many times when the right business decision is to invest in other areas rather than in the remediation of technical debt. However, by applying economic calculations to decisions around technical debt, we can make a more informed and calculated decision based on data. 

    Risk as Technical Debt

    Of the different forms of technical debt, security and organizational debt are the ones most often overlooked and excluded in the definition. These are also the ones that often have the largest impact. It is important to recognize that security vulnerabilities that remain unmitigated are technical debt just as much as unfixed software defects. The question becomes more interesting when we look at emerging vulnerabilities or low-priority vulnerabilities.

    While most will agree that known, unaddressed vulnerabilities are a type of technical debt, it is questionable if a newly discovered vulnerability is also technical debt. The key here is whether the security risk needs to be addressed and, for that answer, we can look at an organization’s service level agreements (SLAs) for vulnerability management. If an organization sets an SLA that requires all high-level vulnerabilities be addressed within one day, then we can say that high vulnerabilities older than that day are debt. This is not to say that vulnerabilities that do not exceed the SLA do not need to be addressed; only that vulnerabilities within the SLA represent new work and only become debt when they have exceeded the SLA. 

    Organizational Debt

    Another type of technical debt often excluded from standard analyses is organizational debt and toolchain debt. These types of debt are often seen in mergers and acquisitions where the organizations are not fully integrated. If one portion of an organization does not adhere to the standard processes or organizational structure for the broader organization, this also can impact the ability of the company to deliver value to customers and represents another form of technical debt. This same paradigm can often be seen in toolchain disparity within companies. If one part of a company is using Slack to communicate while another uses Microsoft Teams, the lack of standardization can cause friction that impedes the organization’s ability to deliver. This is not to say that companies must all use the same toolset or that perfect organizational structure parity is the only way to operate—but understand that there is an ongoing cost for companies that do not standardize. Where standards have been set, they should improve efficiency. When these standards are not met, there is a loss of that efficiency; another form of technical debt.  

    If, for example, a company’s standard chat platform is Slack, that company has chosen to be standardized because they believe standard communication between all teams improves the flow of value to the customer and reduces cost through consolidated license purchasing. If that company purchases another company that uses Teams, that toolchain disparity should be considered technical debt until the platforms are unified. Alternatively, if a company is a portfolio company, there may be limited or no value in standardizing on a chat platform. It may be completely appropriate for that company to decide that the purchased company is free to use whatever chat tool they choose, as that difference will have no impact on the ability of either part of the company to deliver value.

    Mik Kersten discusses this type of debt in his book From Project to Product where he introduces the concept of “accidental complexity” which he says “includes all of the heterogeneity in the tool stack that does not improve the flow of business value. Tools inherited as a result of mergers and acquisitions, or independent selection of similarly functioned tools due to a lack of centralized governance, fall into this category.” He goes on to say that “[r]educing the accidental complexity of tools should be an ongoing effort, as this is a form of value stream debt.” 

    It is important to note that, while many mergers and acquisitions can bring with them significant technical debt, discontinuity in organizational structures or toolchains do not necessarily equate to technical debt. Whether this type of organizational misalignment is construed as technical debt depends, to some extent, on the company merger and acquisition strategy. For companies where there are standards around organizational structure and tooling where some of the benefits of the merger or acquisition are based on the assumption of integration, unintegrated processes and tools should be considered technical debt if they are not remediated within the timeframe projected by the integration business case. If, however, a company is a portfolio company and takes a federated approach, then it is completely acceptable to leave processes and tools unintegrated and these should not be considered technical debt. Organizational technical debt only occurs when tools and processes do not meet standards that align with organizational strategy. 

    By looking across the enterprise, we recognize that there are many forms of technical debt including software debt, organizational debt and risk-related debt. It is important to consider all of these forms of debt. Given this broader understanding of technical debt, we can re-define technical debt as: 

    Unmet demand for technical resources which reduces the ability to deliver value to customers or increases risk. 

    Calculating Enterprise Technical Debt

    With this expanded view of technical debt and the understanding that it can include software defects, organizational complexity and toolchain heterogeneity, we can begin to look at ways to measure technical debt. 

    Quantification of each type of technical debt presents unique challenges. However, the term technical debt itself provides a useful starting point for how to measure all of these. The term technical debt implies a cost and each of the types of debt we have discussed can be quantified in monetary terms—giving us an overall debt cost for a large organization. 

    Interest Rate of Technical Debt

    From a financial perspective, what we are looking at when we are calculating the cost of technical debt is the interest rate on that debt. That is, how much does the technical debt cost an organization over a given period of time? Ward Cunningham discussed this concept in his video on the debt metaphor when he says, “With borrowed money, you can do something sooner than you might otherwise, but until you pay back that money you will pay interest.” Organizational complexity may create delays in developing new products and these delays can be calculated as lost revenue. Unmitigated risks may cost the software due to security breaches and the associated impact on that brand. As time goes on, these costs continue to grow. 

    This is useful because it is also possible to calculate the cost to mitigate the debt. For example, the cost to mitigate a software defect is simply the cost to fix that defect. It is important to note that the cost of mitigation may change over time. The cost to fix a software defect goes up the farther away from creation we get, as familiarity with the worked segment decreases. So we must calculate this cost based on a specified point in time. If we understand the cost of mitigation, we can then look at the cost of debt and weigh that against the cost to mitigate that debt. That helps us to make informed business decisions about the return on investment for remediating technical debt. 

    Software Debt

    While this economic approach to measuring technical debt gives us a common framework for approaching debt, different types of debt still require different measurement approaches. The cost of software-related debt can include defects, unneeded complexity and lack of documentation as well as code that is no longer used but which remains in an application. All of these increase the cost of code maintenance and changes and that may also cause incidents and even outages. We can therefore calculate the cost for this type of debt relatively easily by looking at the cost of support activities related to the issue and adding that to the impact on productivity for the development of new code. The cost of the debt can also be easily calculated by looking at the time and resources required to fix the problem. 

    For example, at one large educational company, there was a bug in the code that caused load spikes. Once or twice a week, the entire team needed to jump on an incident bridge to remediate the load issues by restarting application servers in sequence. Because the application was old, the location of the defect was unknown and difficult to troubleshoot. However, it was easy enough to estimate that the cost to fix the issue would not exceed a couple of weeks worth of effort. As an estimate, let’s say this work would cost $10,000 to mitigate. Comparatively, due to the issue, the entire team, incident management and operations center took one to two hours per week remediating the impact. Let’s estimate this cost at $2,000/week. Based on this high-level analysis, it is clear that the ROI for fixing this defect would be realized five weeks after fixing the bug. 

    Risk Debt

    The cost of risk-related debt is somewhat more complicated to calculate but we can, again, use dollar values as a basis for our calculation. These sorts of debts include security risks as well as compliance-related risks. One of the reasons it is difficult to determine the cost of risk-related debt is because risks do not always become reality. That is, just because there is a risk of a security breach does not mean there will be a security breach. The very fact that it is a risk implies that there is a chance of something happening; it is not a certainty. However, risk analysis provides a very useful tool for calculating this sort of value in the form of annual loss expectancy (ALE). Annual loss expectancy is a means of measuring the expected financial loss during the period of a year. It is calculated by multiplying the expected loss by the probability that it will happen in a given year, or:

    ALE = SLE * ARO

    where SLE is the single loss expectancy, or the amount of loss if the risk occurs ,and ARO is the annualized rate of occurrence, or percent chance that the event will occur in a year. So, if the expected loss due to a given breach would be $100,000 and that type of breach is likely to occur once every five years—giving it a 20% chance of happening in any one year—the ALE for that risk would be $100,000 x 20% = $20,000. Because this number estimates the potential loss due to a risk, it serves as a valuable estimate of the interest for technical debt in the form of that risk.

    Similar to software defect-related debt, the value of the risk-related debt can be calculated as the cost to remediate the risk. This might include activities such as patching outdated systems, software changes to prevent hacking or even process changes to remediate compliance-related risks. For each of these cases, we can look at the cost of resources to remediate the issue and weigh this against the ongoing interest, expressed as ALE, to determine if the investment should be made to remediate the risk. 

    Organizational Technical Debt

    Organizational technical debt is the debt caused by organizational structure, processes and tools that do not align with the standards of the organization and which create delays in the delivery of value to customers. This is frequently seen in mergers and acquisitions where two separate organizations are brought together. Until and unless these organizational structures and tools are aligned, as in our Slack versus Teams example, there may be misalignment which makes it more difficult for the company to deliver as a whole. One way to think about this type of debt is the lack of alignment within tools and ways of working that impedes the flow of value. The “accidental complexity” described by Mik Kersten is a great example of organizational debt. 

    Organizational debt can be measured in terms of the cost of delays in delivering value to the customer. If, for example, handoffs between teams are taking a long time because they are using different development platforms, this delay can be measured and then quantified by the cost of delay. With this type of debt, it is also possible to look at the cost to overall productivity. If the productivity of the organization is negatively impacted because of a proliferation of communication systems that hampers the flow of information, then the cost of the impact to productivity should be calculated; this represents a lost opportunity and another form of technical debt. 

    As with development-related debt and risk-related debt, the cost of the debt itself can be estimated by the cost to remediate the organizational debt. This provides a useful mechanism for determining if the investment should be made to remediate the debt.

    Conclusion

    For large enterprises, the scope of technical debt is expansive. There are many types of technical debt and different methods to calculate the cost of the debt as well as the interest rate on that debt. Software-related debt must be calculated by the impact to the customer or impact to productivity of the people working on the software. Risk-related debt can be calculated by looking at the ALE of that debt. Organizational debt can be calculated by looking at delays in the delivery of value to the customer.

    All this information comes with a lot of uncertainty and a lot of calculations to consider. What is certain is that there are tremendous costs associated with technical debt. The interest on that debt is being repaid every day even if organizations are not aware of it. While it may not make sense or even be possible for enterprises to truly know the full extent of their debt or the amount of interest they are paying, by looking at the cost to remediate and the cost of the interest, we can at least quantify the impact and make calculated decisions based on return on investment for the work necessary to remediate technical debt in the enterprise.


  • Why Backups and Compliance Go Hand-in-Hand

    Why Backups and Compliance Go Hand-in-Hand

    It’s hard to run a business. Besides the numerous challenges you have to deal with daily, ensuring the security of your business and customer information is essential for operating smoothly. In order to mitigate information security risks that would affect companies and their users, a number of security regulations have been created, including a set of best practices that companies must follow.

    Compliance with these regulations will allow you to:

    ● Reduce security and privacy risks
    ● Strengthen control of key processes
    ● Align cybersecurity requirements with business processes
    ● Better understand cybersecurity goals and how to handle business security challenges
    ● Maintain effective cybersecurity programs
    ● Build customer trust and improve company reputation

    One critical requirement to achieve compliance is backups. Organizations back up information that’s vulnerable to threats like software or hardware failures, cyberattacks or human error. Any one of these problems could potentially lead to data loss, system malfunctions, financial losses and reputational damages. In this post, you’ll learn more about why data backups are an important part of compliance and about the benefits of having a robust backup strategy.

    Why are Backups Important for Compliance?

    Regulations like GDPR, PCI-DSS and HIPAA, along with others, were created to ensure that organizations implement the most reliable methods to secure all types of sensitive data from infrastructure failures and malicious attacks.
    Compliance can’t be achieved unless an organization handles data in a way that adheres to the outlined regulations.

    Certifications like ISO 27001 and SOC 2 are considered the most thorough audits an organization can go through to prove they have taken all the necessary steps to protect business and user data. Unlike the regulations mentioned above, ISO 27001 and SOC 2 aren’t legal requirements, but they’re especially beneficial to SaaS companies, data centers and organizations that deal with sensitive information. They make it very clear that the company takes data security very seriously and considers it a top priority. By properly implementing the data and privacy controls required, you can increase reliability and user trust as well as gain a competitive advantage over other companies.

    To be able to obtain such certifications and comply with regulations and different standards in general, you’ll have to maintain robust, up-to-date backup processes that ensure data is always protected but also available to users—even in cases of unexpected events like natural disasters, cyberattacks, data losses and human error. In other words, to comply with regulations, your backup processes must match your business continuity plan and the data backup tools you are using should be able to handle your backup processes.

    Backups, of course, do more than enhance business continuity, as mentioned above. Although they can’t prevent an attack or a data loss from happening, they’re an integral part of your overall security strategy since they allow you to restore lost or corrupted information, mitigating the consequences of such an event.

    There’s no fixed rule for how frequently you should back up. Still, ideally, to secure valuable information, you should implement a combination of full and partial backups as often as possible. Fortunately, great data backup solutions can efficiently handle this complex but crucial task.

    The Difference Between Backups and Compliance

    Backups and data availability are just one of the many requirements for a company to comply with any regulation. It’s an important part, but it’s not enough on its own. Obtaining a security certification isn’t a quick and easy process that you can decide to do and then finish a month later. It’s a time-consuming process that will require buy-in from every member of your team and will ultimately involve in-depth tests and evaluations of how you secure data.

    Although each certification is slightly different, all of them require a company to implement a wide range of security procedures. For example:

    ● Structure your organization in a way that allows optimal management of your services.
    ● Have a strong disaster recovery plan.
    ● Communicate in detail with users about how your system works, your security policies and your processes.
    ● Perform risk assessments regularly to identify risks, measure their impact and create a plan to address them quickly and effectively.
    ● Continuously monitor your security controls to verify they’re operating as expected.
    ● Make adjustments as needed to stay ahead of the latest security threats.
    ● Control physical access to your devices and prevent unauthorized access to your systems.
    ● Integrate best practice security procedures into your day-to-day workflows.
    ● Optimize system operations to detect vulnerabilities early and deal with security incidents.
    ● Clearly describe how you handle changes in your infrastructure to ensure that they won’t affect your business operations.

    The above is far from an exhaustive list, nor will it guarantee regulatory compliance. There are numerous criteria you need to fulfill. Although compliance might seem a huge undertaking, the benefits surpass the difficulties.

    As the security risks in the technology world are constantly changing and becoming more sophisticated, organizations must be able to deal with them or face the consequences. For businesses that want to protect their customers and themselves, following security standards has become necessary. But security compliance isn’t an easy task, and it’s made more complicated by the fact that all of the vendors you use must also be compliant.

    Having a reliable data backup strategy is a crucial step for compliance with regulations and achieving business continuity. Fortunately, there are top-notch data backup tools that can make this complex process easier. These tools allow you to back up regularly to secure your valuable data, and will often automatically run backups on a schedule of your choosing. If you wish to remain compliant and ensure your data is protected, I highly recommend installing a backup service.