Tag: code

  • Bringing Development Environments Into the Modern Age

    Bringing Development Environments Into the Modern Age

    It’s time to rethink how we deliver distributed access to software development environments.

    We know how to write code. And there are plenty of well-established tools, techniques and processes for doing so.

    We know what kind of code to write: Functional, scalable and efficient code that’s inherently secure and that we can readily modify whenever and however we need to modify it.

    We know why we write code. We write it to enhance the value we offer customers, to expand our market reach, outperform the competition, cut costs, minimize risks and otherwise engage in what we call “digital transformation.”

    We know who writes code—or, more accurately, the various “whos” who write it. We need developers with a diverse range of skills. And as our needs keep changing, we keep adjusting the mix of in-house and contract developers accordingly.

    We also know when to write code—which is now and for the foreseeable future.

    The one thing we still struggle with is where to write code. Not ‘where’ in the physical sense; we’re way past that. We know that for development teams to be optimally productive, we have to enable everyone to work from any physical location at any time. COVID-19 has dramatically reinforced this principle.

    The ‘where’ we struggle with is the virtual ‘where’ of the developer workspace. Yes, we already provide developers with remote access to development resources. Sort of. But there are a lot—a lot—of problems with the way we do that. These problems adversely impact development every day by, among other things,

    • Bogging developers down in annoying technical problems that hamper their ability to set up their environments.
    • Forcing developers to wrestle with the maddening complexity of configuring and managing the multiple dependencies associated with each project.
    • Trapping developers in an endless cycle of building, terminating and recreating environments as projects begin, end and are resurrected for updates and enhancements.

    Unfortunately, we’ve become so accustomed to these problems that we tend to accept them as normal. But we cannot afford to accept them any longer. Here’s why.

    Development Environments: Insecurity, Lost Productivity and Technical Debt

    One big problem for both developers and the enterprise is that developer workspaces aren’t fully portable. The methods we use to give developers remote access to their environments invariably come with unacceptable insecurity. There’s also the issue of onboarding. When a developer joins a team—whether as a new hire, temporary contractor or current employee switching to another project—it can take days for them to get them fully up to speed with access to all the project-specific resources they need. That ramp-up time invariably frustrates developers.

    On the other hand, offboarding developers can be a security and compliance issue. Piecemeal provisioning of the multiple resources developers need inherently results in the piecemeal deactivation of those same resources. So when a developer quits or is fired—or when a contractor’s contract is up—we can’t be 100% certain that all their permissions have been revoked.

    Moreover, what happens when a developer needs to go back into a project that no one has touched in months or even years? How does a developer recreate the full workspace associated with that project and have high confidence that they’re doing it right?

    The answer is that we can’t. Instead, some unfortunate developer inevitably has to spin their wheels trying to piece together a long-dormant project. All your aging code is thus guaranteed to become “legacy” (which is just another name for ‘code no one is quite sure how to work on’), thereby guaranteeing that your organization will forever be burdened with an ever-growing mountain of resource-draining technical debt.

    The Shoemaker’s Children

    So how can we re-engineer the delivery of remote workspaces so we make life easier for developers while also fulfilling the security and compliance requirements of the enterprise?

    Here are a few ideas to consider:

    • Host developer workspaces in the cloud. Developers provide everybody else with a wealth of cloud resources, yet rarely take full advantage of the cloud themselves. Some resources they need may reside in the cloud, but the complete workspaces they require to be fully productive do not.
    • But why not? Everything a developer needs for every project should exist as a complete, unified, project-specific workspace that’s available to them anywhere—just like all the other SaaS solutions developers build for end-users every day.
    • And given the sophistication of today’s browsers, cloud-based workspaces can be made available to developers without requiring them to install a desktop client. The cloud also enables workspaces to be hosted anywhere to avoid latency delays.
    • Nothing should leave your secure workspace repository. Ever. To ensure the security of all developer work-product, no actual code or data should ever leave the hosting environment.
    • Only screen pixels and keystrokes should move across the network. This remote-access model makes developers’ workspaces fully secure and fully portable. It also provides the best protection against data exfiltration.
    • Simplify the definition and administration of project-specific workspaces. You don’t want developers looking around for tasks in progress, relevant datasets or process workflows. Instead, administrators should be able to configure workspaces that give developers access to all the resources they need for each project via a single sign-on (SSO).
    • Leverage containerization into your workspace hosting. Better, safer enterprise development isn’t just about re-engineering remote workspace access. It’s also about making those workspaces easier to manage on the back end. The best way to do this is containerization, which allows you to flexibly mix-and-match workspace elements. That way, you don’t have to build every workspace from scratch.

    And those workspaces don’t exist as monolithic, “all or nothing” environments that you pray you’ve gotten right. Instead, with containerization, you can build project-specific workspaces more quickly, at less cost and with less risk.

    Effective hosting of fully portable developer workspaces requires other important functionality as well: Inactivity time-outs, cloud cost/utilization controls, etc. Before addressing these details, however, development leaders must first come to terms with the fact that developers need a much better way to work remotely—and that every remote workspace must be a secure one.
  • GitHub Updates CLI to Make Creating Extensions Easier

    GitHub Updates CLI to Make Creating Extensions Easier

    GitHub this week made available an update to its command-line interface (CLI) that enables DevOps teams to add extensions to workflows.

    Billy Griffin, director of engineering for GitHub, said the company’s initial focus was providing DevOps teams with a set of workflows that could be invoked easily via a CLI. Now GitHub is encouraging developers to extend those workflows using version 2.0 of its CLI that hopefully will be shared with the larger community, he added.

    For example, extensions have already been created that order branches by how recently they were created and then display all associated pull requests.

    At the other end of the spectrum, developers are creating simple screensaver extensions for their own amusement.

    The level of interest in extensions varies widely across DevOps teams. Many of them simply want to employ an opinionated workflow that has been created on their behalf. Other DevOps teams want to be able to make modest modifications. Others prefer to customize workflows as much as possible to fit their specific purposes. Version 2.0 of the CLI provided by GitHub enables each DevOps team to decide how much to modify their workflows. However, as a DevOps team gains more experience, increasingly they tend to want to customize workflows.

    The number of workflows being created around the GitHub repository continues to increase steadily as more organizations embrace best GitOps practices. GitHub is the most widely employed repository for managing software artifacts, and the level of sophistication of workflows built using either scripts or GitHub actions is increasing steadily. Much of that effort is focused on streamlining processes that otherwise would get in the way of enabling developers to spend more time writing code.

    Of course, the pressure on developers to write more code faster has never been greater. As organizations embrace digital business transformation, they are discovering how dependent they are on software to create customer experiences that drive revenue. The challenge comes at a time when many developers are working from home to help combat the spread of the COVID-19 pandemic and many existing workflows need to be re-engineered. At the same time, development teams are becoming more distributed as organizations become more comfortable with hiring developers anywhere in the world.

    It’s not clear to what degree the changing application development landscape might drive organizations to re-evaluate what platforms they are employing to drive DevOps processes. Many on-premises development platforms have been replaced by cloud-based alternatives in the past year. However, because necessity is the mother of invention, the workflows relied on prior to the pandemic are not only now forever changed, but they will also likely be altered again as development teams work more intermittently in-office and from home once the pandemic subsides.

    Regardless of how those workflows evolve, the single-valued DevOps attribute is going to be flexibility. The challenge now is determining which platform does the most to enable that flexibility at a time when uncertainty continues to prevail.

  • Python Remains Popular in Programming Language Study 

    Python Remains Popular in Programming Language Study 

    A ranking by analyst firm RedMonk reflects on Python’s continued popularity as a leading enterprise programming language for a number of reasons. According to a recent study by RedMonk, JavaScript also remains widely popular as the web development programming language of choice for a significant number organizations. 

    In many ways, Python’s strong showing in the ranking — drawn from GitHub pull requests and Stack Overflow data — indicates its long-term viability among DevOps developers. 

    “One lack of change that is worth surfacing is Python’s number-two spot,” Stephen O’Grady, a RedMonk co-founder and analyst writes in The RedMonk Programming Language Rankings: January 2021. “Java was extremely hot on Python’s heels – and was, in fact, closer to the number-one ranking than to PHP behind it – but Python’s ability to defend its new high ranking is notable.” 

    RedMonk

    Python’s prolonged high ranking is notable because of its versatility, Rachel Stephens, a RedMonk analyst who is responsible for the RedMonk Language Rankings’ design, told devopsy.kinsta.cloud. “The breadth of use cases — and associated libraries that support those use cases — means there are a number of possible entry points for developers. The number of toeholds for the language within the enterprise helps its ubiquity,” said Stephens.

    There also remains much discussion about what accounts for Python’s continued popularity beyond the scope of the study. A popular subject in forums, including Reddit, Python is typically described as highly versatile, relatively easy-to-learn and a simple, yet elegant language. While not cited in the RedMonk study, some software engineers and coders — such as this writer — appreciate how Python can make more intuitive sense, and is also less rigid compared to, say, a classic language such as C++. While JavaScript is largely used for web apps and scripts, of course, Python could arguably be the most popular language outside of the sphere of web development, thus accounting for its second-highest ranking in the study.

    As such, “due to the accretive nature of our methodology, movement within the top-ranked languages is an infrequent occurrence,” Stephens said.  

    “[However], Python overtaking and sustaining its ranking over Java was a big deal. That said, we remain strong believers in the future of Java and the Java ecosystem, and we know there is a vast amount of enterprise Java that isn’t captured in the metrics we use,” Stephens said. “We don’t view Python’s ascendence as a zero-sum gain over the use of Java.”

    For JavaScript, “in spite of all of the competition from up-and-coming languages, all the discussion of fragmentation – and even criticisms of JavaScript the language itself – it remains remarkably popular,” O’Grady said.  

    “Simply put, JavaScript remains – its detractors notwithstanding – a force of nature like no other within the industry, and there are no indications in the data that this is likely to change any time soon,” O’Grady added.

    Meanwhile, in the book Hardcore Programming for Mechanical Engineers, published by No Starch Press, JavaScript trails Python in other rankings, while Python is also more popular than JavaScript for other reasons than those described in the RedMonk study. Python, for example, is cited as the ‘The Most Wanted Language,’ based on a Stack Overflow survey. 

    While Python is not the fastest language, as measured  in benchmarks listed in Hardcore Programming for Mechanical Engineers  — Go consistently outperforms it, for example, in execution times — Python’s popularity remains very high overall, according to the book’s author.

    “These results are not surprising; Python is an extremely versatile and productive language,” author Ángel Sola Orbaiceta wrote. “Writing code in Python is a delight, and its standard library is well-equipped: for just about anything you want to do, Python has something ready to help.” 


  • Up Your DevOps Game: It’s Time for NoOps

    Up Your DevOps Game: It’s Time for NoOps

    NoOps is here and it’s more than just a buzzword or an ideal. The next generation of platform-as-a-service (PaaS) platforms are evolving to minimize the developers’ operational burden and reduce dependency on DevOps for deployment. Dev teams that don’t want to deal with operations or don’t have in-house operations resources should consider deploying applications on a NoOps platform.

    To understand the concept of NoOps, we need to start with an understanding of how deployment management has evolved over the decades.

    From Hardware and Software and Back Again

    It’s been a long trend of back and forth between developers and “deployers.”

    It was once mandatory for software developers to be fluent in the hardware for which they were creating software. They wrote the code and then worked with the operations team to deploy it on in-house servers. Everything was tightly coupled. The first mainframes—IBMs and SiliconGraphics machines—ran on custom-built software, and the developers were responsible for the deployment and management. The developers had the machine first, and then had to create the code to make them run—assembly or low-level language or even hardware code; rope memory, in some cases.

    Then came the x86 revolution, when hardware became more standardized and was decoupled from the complexities of deployment. Developers started focusing on the software and organizations had separate teams that would manage the deployments.

    With the advent of virtualization and infrastructure as a service (IaaS), the deployment of software now depended on APIs for infrastructure provisioning, and we returned to an integrated development and deployment function—in other words, DevOps.

    The Problems DevOps Created

    The problem then became one of choice: As APIs multiplied, developers had to decide which APIs would be most relevant, efficient and useful to deploy their software—and on what infrastructure: bare metal, virtual machines such as EC2 and VMWare, Kubernetes, Swan, OpenShift, serverless, Lambda, Knative, etc.

    Not only did the teams have to decide on what IaaS to deploy the actual software, but they needed to also choose how and where the layers and logs would be monitored—and even where those logs would be stored. They need to consider things such as traceability and horizontal or vertical scaling issues, to name a few.

    This has resulted in the creation of bespoke permutations and combinations that work great … until vendors’ upgrades require them to keep up with tens or hundreds of configuration changes. Most teams are keeping it together, but it definitely can be done more efficiently.

    Now It’s time to Up the Game to NoOps

    It’s time for the next approach: Limit the number of choices to create standard best-in-class operations that deliver economies of scale and easily evolve with minimal hassle.

    NoOps simplifies cloud operations—everyone can do things the same way. NoOps aims to “completely automate the deployment, monitoring and management of applications and the infrastructure on which they run,” according to Forrester, which coined the term.

    NoOps is about standardizing the approach to deployments and reducing the number of variables, bringing simplicity. At its core, NoOps is focused on automating deployments and executions that are predictable and repeatable.

    NoOps & Standardization

    The development and increasing adoption of containers are critical to the entire NoOps philosophy. Containers provide the ability to independently deploy services and applications, automating and standardizing the process to deploy anything, anywhere. Using containers delivers the tremendous portability that hasn’t been seen since the development of generic hardware.

    With encapsulation within the container, whatever is running inside will behave the same no matter where it is deployed.

    The NoOps-containers movement will transform the entire DevOps industry.

    Let’s go back even further. In the 1800s, few homes had electricity. They hooked up whatever appliance they had to whatever generator they were running and kept their fingers crossed. Once governments took over the role of bringing electricity to every home with standardized voltages and outlets, the appliance industry took off.

    A true NoOps platform will provide a standard “socket” that works for everything. The developer will simply build the app, and it will “plug in” anywhere. With NoOps, developers don’t have to worry about how the application will work, deploy or scale, nor do they have to consider reliability or elasticity. The platform will deliver it automatically.

    The “Gift” of Containers

    Containers free developers from managing infrastructure and reduce the operational burden associated with building and deploying applications. They also minimize application conflicts among different environments and improve portability and team collaboration.

    Containers make application deployment easier than ever before. Continuous integration doesn’t change as part of this process. Adopting containers as part of NoOps simply automates continuous delivery—developers write the code, commit the changes and push it to the container’s remote repository. Based on the Docker file, an image will be built and the containers that run your application will be deployed. Since all deployments are rolling, no downtime occurs.

    Leveraging containers provides speed, agility and flexibility to any infrastructure, thus bringing cost savings and dynamism. Containers can flexibly host microservices, which can be scaled individually, as necessary. Using CPU, memory or even custom business rules, developers can set auto-scaling policies so applications are ready to serve an increased number of requests whenever needed. As the platform monitors application performance, it can use these insights to intelligently architect a right-sized infrastructure.

    Putting NoOps Into Play

    If you’re considering adopting NoOps, look for a PaaS provider with the expertise to make the right platform choices for you based on your application development language of choice. For example, if you are looking to host a Ruby application, ensure that the provider has the requisite Ruby expertise.

    A true NoOps platform will streamline deployment, automatically scale based on your business requirements and provide outstanding performance. The automation dramatically boosts productivity and reduces costs associated with deploying and managing applications.

    NoOps platforms monitor operations and automatically resolve issues using built-in observability mechanisms and intelligent alerts. Centralized logging, metrics and traceability make it easy to identify issues and initiate fixes without expensive downtime. Moreover, the platform should ensure strong security boundaries and adhere to applicable compliance regulations.

    When “going NoOps,” also make sure that the solution provides comprehensive documentation and 24×7 support for emergencies that would normally be handled by an in-house DevOps team.

    Wrapping It Up

    NoOps can eliminate much of the work associated with deploying and monitoring applications by simplifying and streamlining operations and reducing the need for extensive in-house DevOps support. While it’s not a one-size-fits-all solution, it delivers great value helping companies of all sizes from start-ups to enterprise teams save time and money and better redirect their resources toward high-value activities, creating the best code to deliver the highest quality products.

  • Two-Part Training Required for Developers to Slay the Security Beast

    Two-Part Training Required for Developers to Slay the Security Beast

    Developers’ defensive qualities are only as good as the training they receive

    The playing field between the heroes and villains in cybersecurity is notoriously unfair. Sensitive data is the new gold, and attackers adapt quickly to circumvent defenses, exploiting security bugs large and small for potential paydirt.

    The volume of code being produced is too great for security experts—who are becoming increasingly scarce—to contend with, and the rising cost of data breaches is proof that something has got to give. Fortunately, for the sake of our digital safety and the sanity of CISOs everywhere, the DevSecOps movement is helping to bring developers on the security journey from the beginning of the software development process. They are being recognized as the first line of defense against cyberattackers, with the power to eliminate common vulnerabilities at their fingertips.

    However, their defensive capabilities are only as good as the training they receive, and that is yet another gauntlet for security teams to run. For many developers receiving on-the-job training in secure coding, their key challenge is staying awake during mind-numbing, hands-off activities that are neither effective nor inspiring them to keep security front of mind. Soulless video courses aren’t getting us there, token annual ‘tick-the-box’ events are a waste of time, and nobody is winning against the potential malicious threat actor waiting to jump on a small window of opportunity.

    At this stage in our industry, we have worked out that contextual, hands-on education that is delivered in relevant programming languages and frameworks, with challenges that mimic those a developer might come across in the real world, is a far more engaging approach.

    This is phase one of a developer’s quest to help AppSec gurus slay common vulnerabilities, but phase two is where scenarios must get real for a supercharged, security-aware defensive force.

    Scaffolded Learning Is Critical in Adult Education

    When it comes to extracurricular courses or on-the-job training, it is often overlooked that adults bring with them a certain level of experience and existing knowledge. Good training adds to this foundation and is structured in a way that allows for deeper understanding and faster autonomy in the learning process.

    Scaffolded education is a potent, positive method of learning that seeks to activate and enhance prior experience while continuing to build new skills—in manageable chunks—that allow the learner to tackle increasingly difficult tasks with more confidence. Typically, it is a methodology best served with healthy portions of demonstration, visual aids and student-led exploration.

    If we tie this approach back to developer security training, it comes as no surprise that the dynamic, learn-by-doing method has long been preferred over the drudgery that is theory-based static learning. They are free to be the masters of their domain and should see that their time is being well-spent.

    In that sense, learning to code securely in a hyper-relevant, contextual environment is key, but the ‘level up’ from this step is to see an exploit of vulnerable code in action. With the context of front-end and back-end views side-by-side, there is a tangible link between actions taken during the coding process and what an attacker can potentially do with cut corners, misconfigurations or accidents that are not caught and remedied.

    Move From Recall to Application for a Truly Preventative Security Approach

    Experiencing the impact of security vulnerabilities firsthand is a vital piece of the education puzzle, and it’s a fairly rare beast, even with the most modern security training options for developers. The foundational work spent on honing skills in spotting and remediating vulnerabilities and recalling that experience to eliminate the same bugs in code as it is being written is extremely important, but it’s not the whole picture. Seeing how vulnerable code is exploited by a malicious actor adds a powerful layer of context, one that really drives home the importance of securing code and applying hard-earned security knowledge to close every window of opportunity.

    It is generally accepted that developers don’t love security, and they have even less affection for security training. Their experiences with AppSec specialists can be very frosty, and the rework caused by the security team bouncing vulnerable code back to developers for remediation is the bane of their existence. To an engineering team that is already spread thin, security is someone else’s problem, not their priority, and a hindrance to their natural creativity and primary objective of building features. However, there is simply too much code, too many breaches and too much risk to the world’s data for this mindset to continue.

    A functional DevSecOps process has developers working in harmony with security teams right at the beginning of the software delivery life cycle (SDLC). Likewise, the opportunity for applied learning, where they can interact with a simulated exploit and see the impact of poorly secured code, goes a long way in getting developers on the same page as those pesky AppSec people (who aren’t so bad after all).

    Interactive Learning Prepares Developers for the Boss Fight

    At the time of writing, there were two major breaches reported in a seven-day period: Razer announced that more than 100,000 sensitive data records had been exposed, while office supplies retailer Staples also reported a similar data leak. More than a billion sensitive records have been exposed so far in 2020, and this worrying trend shows no signs of slowing down. Simply put, malicious actors have the upper hand and security-aware developers are sorely needed to serve as the front line of defense.

    Interactive challenges that focus on simulating such breaches move developers from passive recall, to applying skills that have an impact on the real boss fight: stopping attackers in their tracks.

  • GrammaTech Discovers Vulnerabilities in Third-Party Code

    GrammaTech Discovers Vulnerabilities in Third-Party Code

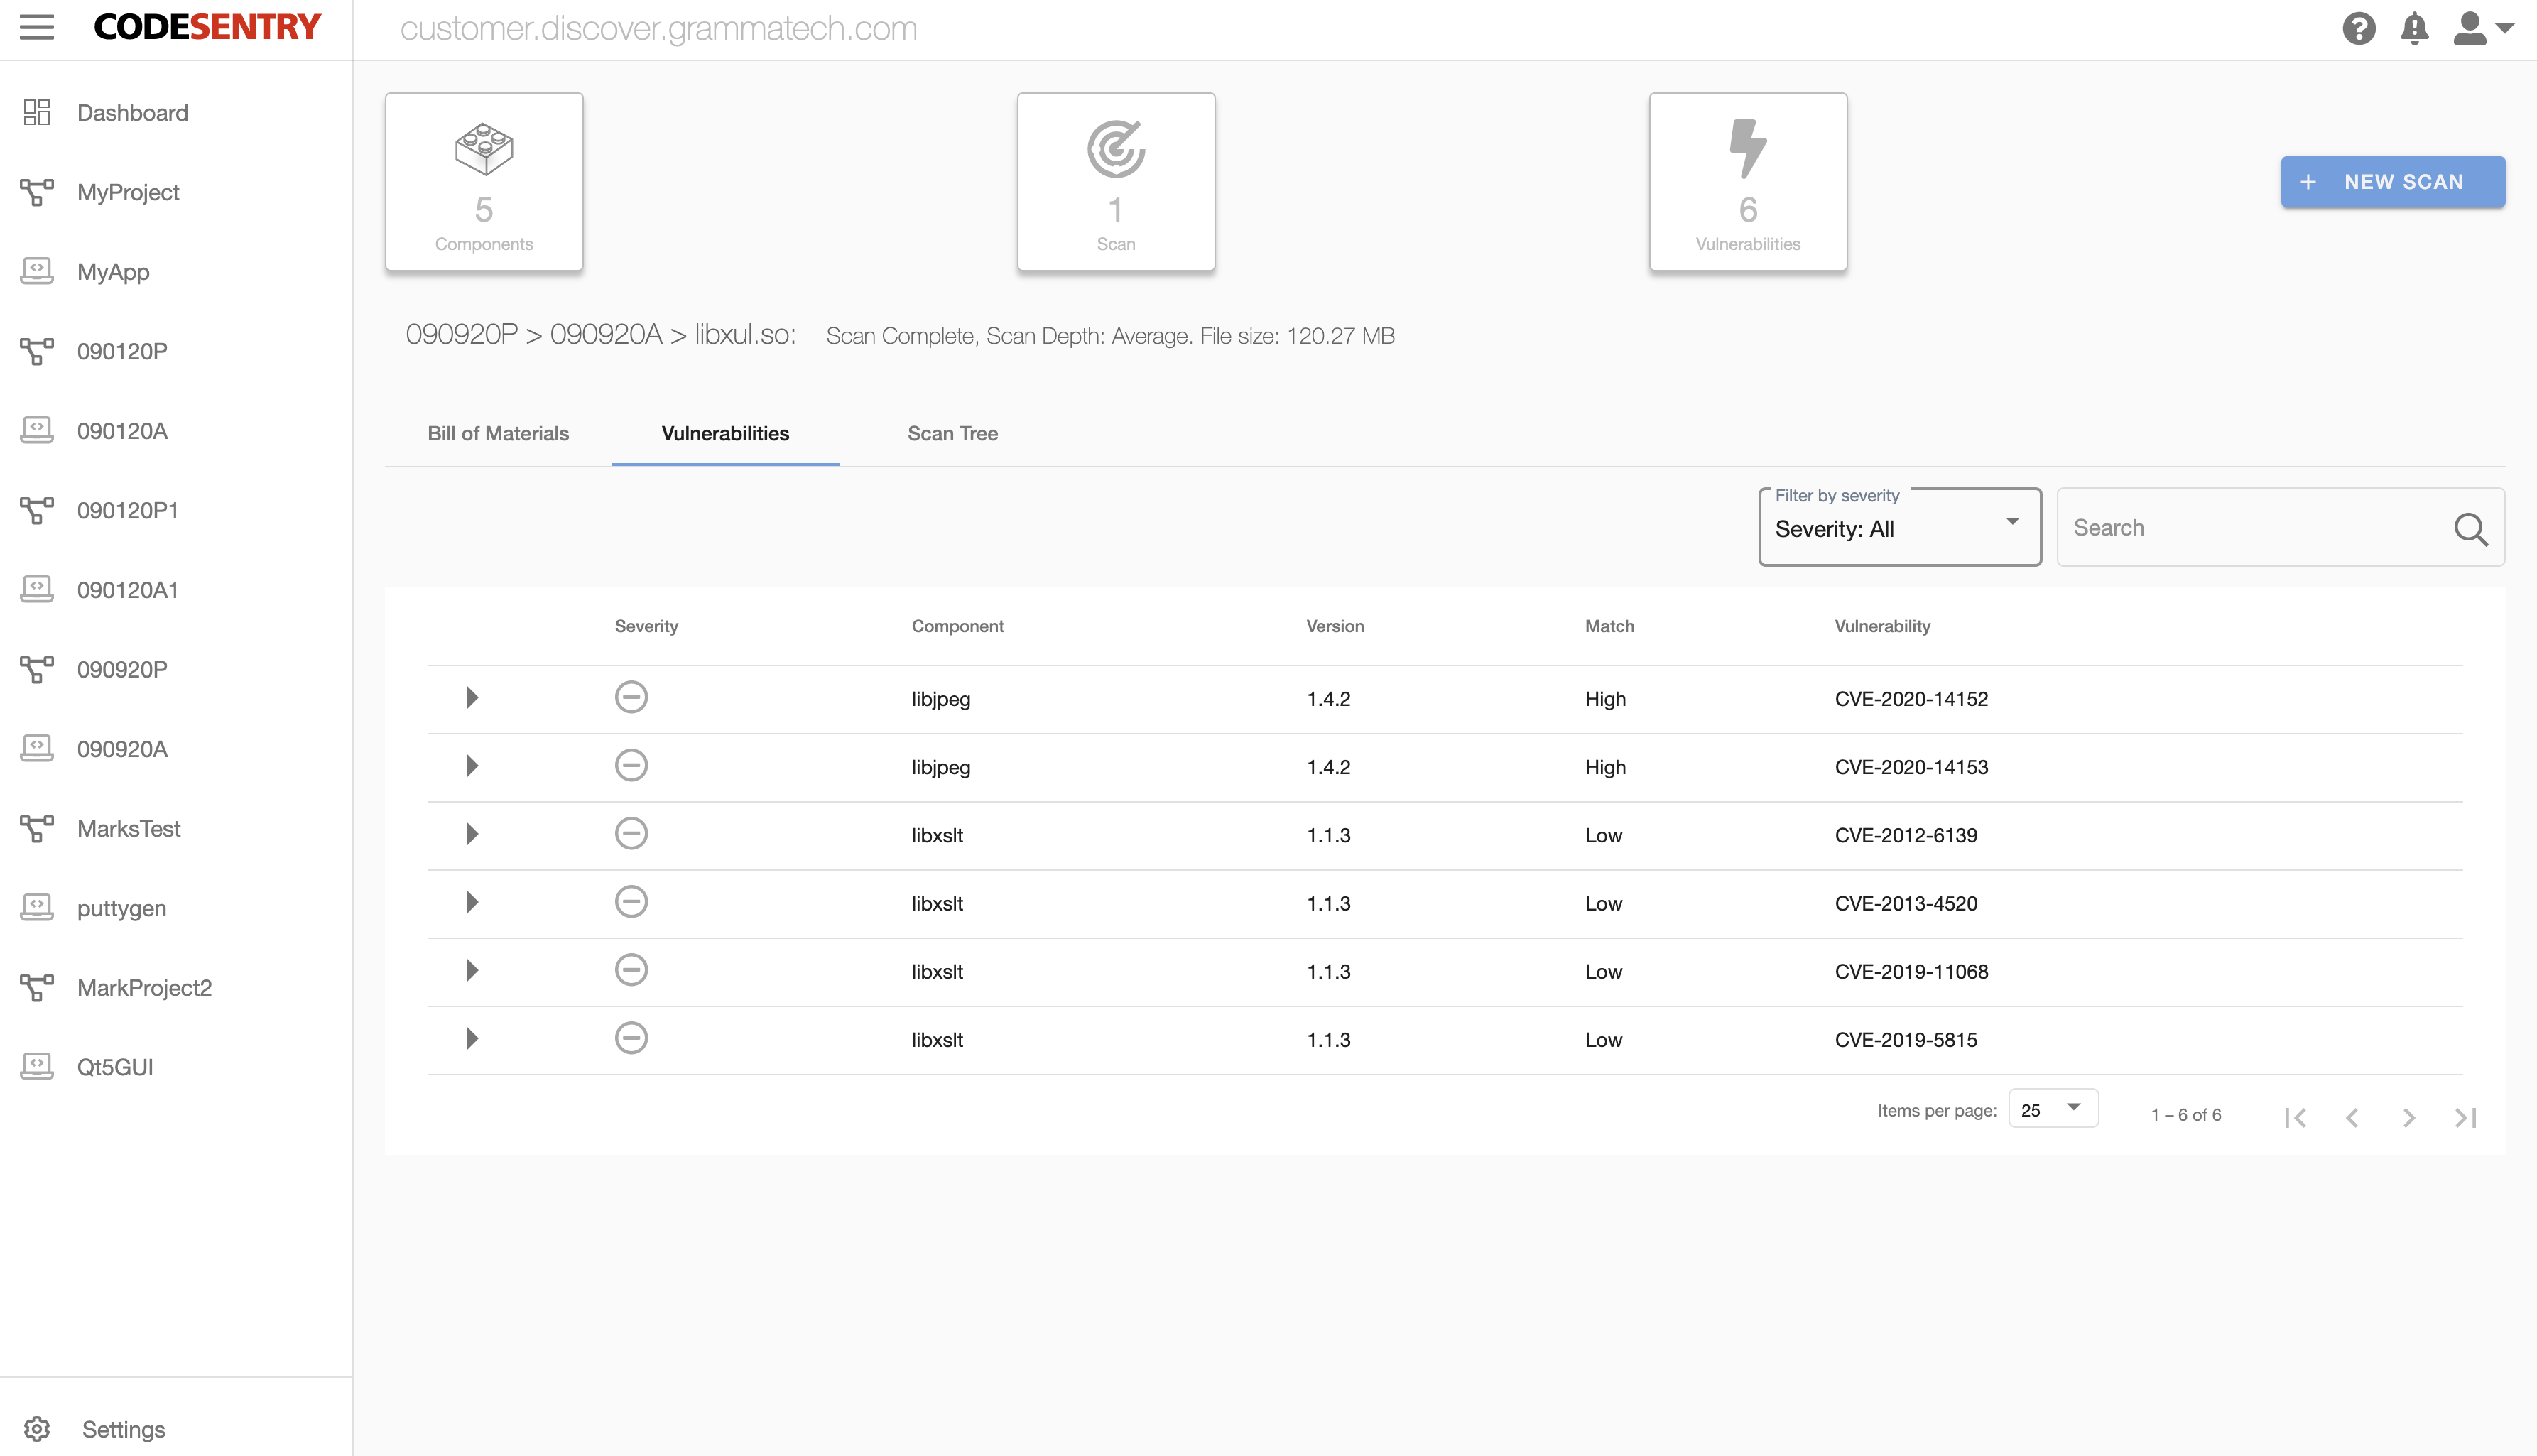
    GrammaTech today launched a CodeSentry software composition analysis (SCA) for binaries that inventories third-party code used in custom applications and identifies known vulnerabilities.

    Vince Arneja, chief product officer for GrammaTech, said the bulk of custom applications today are made up of binaries based on components developed by a third-party that comes in the form of open source, commercial-off-the-shelf (COTS) or existing custom software.

    CodeSentry detects these components and vulnerabilities associated with third-party code, including network components, graphical user interface (GUI) components or authentication layers. It uses deep binary analysis to create a detailed software bill of materials (SBOM) and a comprehensive list of known vulnerabilities.

    Arneja said that as responsibility for security continues to shift left toward developers, there is a need for tools such as CodeSentry that make it easier to identify vulnerability issues in binaries because many developers may not have access to the underlying source code used to construct the binary. CodeSentry identifies components present in native binaries using a range of matching algorithms to gather version number ranges, create an SBOM and provide links to CVE and CVSS scores, said Arneja.

    CodeSentry extends algorithms that GrammaTech developed to detect components in applications, including strings used in natural language processing. It maps components to multi-dimensional vectors and compares them to vectors derived from the components. The upload interface for the tool accepts native binaries, zip files and other archives. Once those files are loaded, CodeSentry analyzes the code that will run rather than the build environment to reduce the number of false positives that would be generated in build environments or components that are not actually being employed.

    GrammaTech next year intends to make CodeSentry available via a software-as-a-service (SaaS) platform, noted Arneja. GrammaTech ultimately envisions CodeSentry being employed as part of DevSecOps workflows driven by a continuous integration/continuous delivery (CI/CD) platform using a set of open application programming interfaces provided by the company, said Arneja.

    While there’s a lot of focus these days on melding DevOps and cybersecurity workflows as part of an effort to embrace best DevSecOps practices, the easiest vulnerability issue to resolve is the one that never existed in the first place. As developers gain access to cybersecurity tools, the number of vulnerabilities making it into applications should significantly be reduced in the months ahead. The challenge IT leaders face is making sure developers have access to those tools, which in turn will ultimately boost the confidence level cybersecurity teams have in application developers, who are often viewed as the primary cause of the problems cybersecurity teams are trying to resolve.

    Regardless of how IT organizations achieve that goal, the return on that investment is likely to be substantial. The amount of time and effort IT teams spend tracking down vulnerabilities that are much more expensive to fix after an application is deployed in a production environment is incalculable.

  • 6 Advantages of Microservices

    6 Advantages of Microservices

    Microservices have recently gained in popularity, but you may be unsure whether this architecture is right for your environment. What’s great is microservices are not necessarily a new beast, as the concepts behind them have been a solid part of software development for decades. Topics such as modular programming, separation of concerns and service-oriented architecture (SOA) all align with the objectives of a microservices architecture. In fact, many development teams have adopted microservices without necessarily calling them that—event-driven architectures are one example.

    Before discussing the advantages of microservices, let’s make sure we’re aligned on a definition and the key principles:

    • Microservices are a set of software applications that work together, each designed with a limited functional scope.
    • They work with each other to form a larger solution.
    • Each microservice has minimal capabilities for the sake of creating a highly modularized overall architecture.

    Does this sound like an architecture your development team has been utilizing? If not, there are several advantages for use within the enterprise, especially as businesses build more complex solutions for customers.

    Easier to Build, Easier to Enhance

    Microservices are “micro,” requiring much less code than their monolithic application counterparts. The sum of code may compare to a monolithic application, but it’s the physical separation of code that draws cleaner, distinct lines between different functions for microservices. They also excel in experimentation and testing because the focus is on one small feature or capability, making incremental code updates simpler. As a result, companies increase agility, bringing higher-quality systems that have less complex code, require lower testing effort, support easier unit testing and reduce problem risk.

    Microservices also free users from concerns of how one task will affect the next. When coupled with a messaging system such as Apache Kafka, they can actually simplify the development process. Each microservice can write to the messaging system in a standardized format the next can understand—no strict messaging format required. By opening the architecture to a system of smaller applications you can also base each microservice on almost any programming language. This grants you freedom in a few ways because:

    • A variety of development teams can work together on a single microservice architecture without commonality on technologies.
    • Each team can use a software stack they choose for their specific skills.
    • You can incrementally incorporate or experiment with new technologies.

    Gone are the days of worrying about updates impacting your system or waiting to update all your microservices at once, too. As long as you adhere to the simple input and output messaging formats, you can update a single microservice at your leisure without having to shut down the entire system.

    Deploy With No Hesitation

    Microservices are easier to deploy than monolithic applications for the same reason they’re easier to build and enhance: they’re small and modular. Consider the various dependencies between development and production environments like OS or the amount of random-access memory (RAM) and you begin to understand how complex deployment within a tech stack can be.

    By reducing dependencies to a smaller scope, thus decreasing the potential for dependency conflicts, microservices become advantageous for deploying in a container with other virtualized technologies. Further, there are no limits to a single deployment option. Whether on-premises, in the cloud, in serverless environments or at the edge—which will continue to gain in significance and popularity—the possibilities are nearly endless.

    Maintain, Troubleshoot and Extend With Ease

    Maintenance is key to making our most valuable investments last. This is especially true for large-scale software environments where monolithic architectures can prove challenging. Microservices offer a way to seamlessly enable ongoing maintenance and fault tolerance, as well as troubleshooting, as individual outputs make isolating the source of problems easier.

    Moreover, single points of failure are not an issue because the distributed nature of microservices means any given one can be deployed redundantly, in parallel, and on a continuous basis. If any single microservice for a given task fails, the others associated will pick up the slack.

    Another benefit is they help extend your systems to provide more outputs. Making incremental updates is relatively low-risk because microservices are highly modular and can be plugged in easily with new or updated code. Should an unforeseen error occur, you needn’t fret about shutting down the entire system and stopping the flow of data. Instead, you can shut down a given task and temporarily stop data flow, with the messages queued in the messaging layer to be read once it is restored.

    Simplify Cross-Team Coordination

    Many companies overcomplicate large projects and software development is no different, with integration points serving as cumbersome, headache moments. In a microservice, internal workflows are as straightforward as:

    • Reading data from a source.
    • Performing an action on the data.
    • Sending output to a destination.

    Since microservices are designed to navigate small bits of data at a time from an otherwise large data set, managing and sharing output is straightforward. Teams simply coordinate what their respective microservices do and how the exchanged messages are formatted. Lightweight messaging systems are recommended for allowing communication, as they further support simplifying coordination across development teams by providing a fast and reliable means for exchanging data.

    Speed and Scalability

    It may seem with the many independent, moving parts in a microservices architecture that performance will take a severe hit, whereas a monolith runs as a single process. However, keep in mind there is a clearer opportunity for parallelism with microservices, so any task can be spread across multiple CPUs/cores and be run with much higher overall throughput. For example, machine learning models that require complex calculations in addition to lookups in external databases can be parallelized to process more data at once.

    The scalability of microservices is tied in with this capability. As the workload grows with more and faster data, additional microservices can be deployed to run in mirror to spread the load across further hardware resources. In contrast, refactoring a monolithic application to handle more load—which will require significant changes—potentially creates greater risk for introducing errors.

    Streamline Real-Time Processing

    Demands for immediacy are only continuing to grow. As a result, businesses must increase performance and function in real-time to stay ahead. Microservices provide that competitive advantage by enabling efficient, instantaneous processing and streaming architectures.

    Real-time processing is centered on fast data, often in the form of streaming. As data continues to flow in from a source such as an internet of things (IoT) device, applications must keep up with the input rate and operate reliably. A microservices architecture provides the parallelism and redundancy to maintain the load and respond quickly in a consistently reliable way. Additionally, as the flow increases, more microservices can be deployed to accommodate the growth. This structure also allows easy identification of bottlenecks that can be addressed to maintain immediate responsiveness.

    The swath of consumer data available to enterprise business today is at a scale never seen before. Thinking strategically about how to handle and process it for the benefit of the business—and the consumer—is an important priority today. Microservices are just one strategy to leverage on this journey and could serve as the advantageous choice for increasing performance, speed and ease on the workloads of many.

  • Survey: Organizations Knowingly Deploy Vulnerabilities

    Survey: Organizations Knowingly Deploy Vulnerabilities

    A survey published today by Synopsys, a provider of electronic design automation (EDA) and application security tools, finds nearly half (48%) of respondents admit they consciously push code with known vulnerabilities into production because of time constraints.

    Based on a survey of 378 cybersecurity professionals conducted by Enterprise Strategy Group (ESG) on behalf of Synopsys, the survey also finds 65% of respondents said developers in their organization are participating in a formal security training program.

    However, only a third (34%) are employing application security tools across more than three-quarters of their codebase. And, as the rate at which code is created increases, only 30% expect they will be able to protect more than three-quarters of their codebase 12 months from now despite the fact that more than half (56%) said they apply highly integrated sets of security controls throughout their DevOps process.

    Nearly three-quarters (72%) also said their organization makes use of 10 or more application security tools.

    Patrick Carey, director of product marketing for the Software Integrity Group at Synopsys, said the survey shows many organizations are making trade-offs between potential risks to the business and the desire to deliver software faster. As the rate at which updates to applications are being delivered increases, thanks largely to the adoption of best DevOps processes, Carey noted it becomes easier to justify knowingly allowing vulnerable code to be deployed in a production environment. The assumption is that most severe vulnerabilities will be prioritized while less critical vulnerabilities are addressed over the course of the application lifecycle management process.

    In most organizations, the survey finds either a development manager or the application security analyst is responsible for making these decisions. Just under a third of organizations make both jointly responsible. More than three-quarters (78%) also report their security analysts are directly engaged with their developers. Just under a third (31%) work directly with developers to review individual features and code, compared to 28% who work with developers on threat modeling and 19% that participate in daily scrums.

    The survey finds that integrations that complement high-velocity application development process are critical for 43% of respondents. As a result, more organizations are looking for application security tools that can be directly embedded within an integrated development environment (IDE), noted Carey.

    However, the fact that application security tools are shifting further left does not mean organization won’t also have to invest in other tools that are embedded within DevOps platforms that manage runtime deployments, added Carey.

    As is always the case when it comes to best DevSecOps practices, the two biggest challenges are getting the right tools in the hands of developers and then aligning workflows between development and cybersecurity teams. The survey suggests substantial progress has been made on the latter, while tools for developers are increasingly becoming available. After all, most developers want to do the right thing when it comes to application security. The issue is determining what precisely that means.

  • Apollo GraphQL Brings Caching to Client Software

    Apollo GraphQL Brings Caching to Client Software

    Apollo GraphQL this week updated its namesake GraphQL client software that among other things improves performance using in-memory caching application programming interfaces (APIs).

    GraphQL has emerged as a popular alternative to REST APIs because it provides developers with a query engine that provides more control over what data is requested. Similar in concept to SQL, developers GraphQL also makes it possible for developers to describe the data they are exposing via an API.

    Finally, GraphQL APIs are organized in terms of types and fields rather than endpoints. That allows developers to organize APIs within a graph that makes them available via a single request rather than requiring every communication between APIs to occur on a point-to-point basis.

    Apollo GraphQL has created client software that allows developers to employ GraphQL to both query external data in addition to making use of a graph to catalog the services made available within the front end of an application.

    Version 3.0 of Apollo GraphQL client software addresses a caching limitation that stems from the fact generic HTTP caching doesn’t work with GraphQL. Every time an HTTP request is made for slightly different data the cached value is invalidated. When the Apollo GraphQL client fetches data from your server it caches that data using a normalized structure that matches the Apollo GraphQL schema, which allows it to locally reconstruct a subset of the back-end data graph. The next time Apollo Client queries any of that same data it can fetch it directly from the cache.

    Developers can now also define a field policy for any GraphQL field that appears in your cache. A field policy can include a read function that customizes what occurs when the field is read from the cache and a merge function that customizes what occurs when it’s written.

    Apollo Graph CTO Matt DeBergalis said by defining all of this custom field logic in one place developers can avoid repeating code. Other developers can also interact with the types and fields without needing to understand how they’re stored or fetched, he said.

    Version 3.0 of the Apollo client library also now includes support for a reactive variable value that registers a dependency when read.

    Originally developed by Facebook, GraphQL is gaining a lot of traction on backend systems because it allows developers to describe the data that can be accessed. However, because it also makes it more efficient to query data it’s also now being more widely deployed on clients as well. It’s not clear to what degree REST APIs might be replaced by GraphQL, but at the very least reliance on REST APIs in new application development projects is likely to decline significantly.

    The implications of that transition for DevOps teams are significant because the overall performance of applications that rely on GraphQL versus REST APIs should substantially improve. In fact, the biggest inhibitor to GraphQL adoption at this juncture may be simple inertia. Too many developers simply build REST APIs as a matter of reflex without necessarily investigating alternatives. However, it should not be too long before everyone on the DevOps teams starts to appreciate just how much the end user experience really is when GraphQL is employed.

  • Rookout Extends Reach of Debugging Platform to On-Prem

    Rookout Extends Reach of Debugging Platform to On-Prem

    Rookout, a provider of a software-as-a-service (SaaS) platform designed to simplify the debugging of applications, has extended the reach of its tools into on-premises IT environments.

    Company CTO Liran Haimovitch said its new Data On-Prem capability extends the reach of a bytecode manipulation capability developed by Rookout to insert a snapshot capture of a specific line of code to an on-premises IT environment. This eliminates the need for DevOps teams to upload code and associated data to the Rookout platform manually.

    The Data On-Prem capability is made available via a software development kit (SDK) provided by Rookout, he said.

    Legacy approaches to debugging code are essentially broken because the processes employed to fix code are too cumbersome, said Haimovitch. Rookout is designed to collect full-stack data without requiring code to stop running or impact code execution. That approach allows developers to debug live code on the Rookout platform and then reinsert the code into their applications.

    Haimovitch said Rookout is making a case for transforming how application debugging is addressed within a DevOps process. Rather than relying on tools that need to be tightly integrated and maintained within a continuous integration/continuous deployment (CI/CD) pipeline, it will be easier for developers to debug live code on the Rookout platform, said Haimovitch.

    That approach will enable DevOps teams to go well beyond simple observability to embrace true understandability of how applications work down to individual lines of code, he added.

    Debugging applications has always been problematic. In an ideal world, developers would have a much better handle on what bugs need to be fixed earlier rather than later. By making it easier to debug live code, the number of issues that developers could address before an application is deployed in a production environment should increase. It may never be possible to address every issue before an application is deployed; however, the number of critical issues theoretically should decline. Many code issues go unaddressed simply because the effort required to debug that code is too great. Many developers too often put off fixing those issues until the next update usually because they are rushing to meet a delivery deadline.

    At the very least, developers should repeat the same mistakes less often as they work to debug live code.

    Regardless of how the debugging issue is addressed, issues within code in the age of microservices are starting to have a bigger impact. An issue within a line of code in a single microservice can have a cascading impact on all other elements of an application that depend on that microservice.

    Debugging application code is never going to be enjoyable. The challenge is finding a way to make the entire process less painful. There may come a day soon when machine and deep learning algorithms help automate much of the debugging process. In the meantime, DevOps teams might want to re-evaluate existing approaches to debugging code that clearly leave much to be desired.