Category: News

  • Digital Transformation Driving VSM Adoption

    Digital Transformation Driving VSM Adoption

    The number of organizations using value stream management (VSM) to bridge the divide between DevOps and the rest of the business is expected to dramatically increase over the next two years. The shift is due, in part, to investments in digital business transformation initiatives.

    A survey of more than 500 executives, IT and business leaders conducted by Dimensional Research on behalf of Broadcom, a VSM platform provider, finds the percentage of organizations employing VSM will rise from 42% today to 70% in the next two years. Nearly three-quarters of organizations (72%) that are not currently using VSM plan to do so in the next 18 months or more.

    The survey also finds that 85% of organizations are collecting some subset of value stream metrics today as part of an effort to deliver solutions faster (56%), improve decision making (55%) and increase transparency (54%).

    Laureen Knudsen, chief transformation officer at Broadcom, said that as organizations embrace DevOps best practices more broadly to drive digital business transformation initiatives, they need more visibility into the application development process. VSM surfaces the insights required to not only identify bottlenecks but also track how changes in application delivery timetables will impact key performance indicators (KPIs).

    VSM traces its lineage back to lean manufacturing methods, which called for each step of a manufacturing process to be continuously measured. As software development has evolved from being a craft to an automated process using DevOps best practices—and as organizations realize just how dependent they are on software—an appreciation for the value of monitoring the impact of missed software development deadlines on the business is growing steadily. VSM platforms automatically collect technical metrics from DevOps tools that are then correlated against the KPIs the organization decides to track.

    The Broadcom survey found more than 96% of respondents’ companies are already in the process of adopting digital transformation. Strategic objectives include increasing efficiencies (70%), improving product quality (67%) and improving customer value (63%).

    Most respondents (92%), however, are anticipating product development challenges for 2022. The biggest product development challenge cited is a lack of visibility throughout the product life cycle (45%) followed by inefficient processes (44%), lack of resources (42%) and enterprise-wide lack of understanding of how products deliver customer value (42%). A full 89% of the business leaders surveyed also noted they continue to struggle with organizational silos between strategic development and operations; 93% noted that better alignment between teams would improve their organization’s overall return on investment (ROI) in software development. A total of 95% said they believed VSM would optimize their product life cycle processes.

    Knudsen said that, in time, artificial intelligence (AI) technologies will increasingly be infused into VSM platforms to enable automated feedback loops between the business and DevOps teams. In the meantime, DevOps teams should be prepared to adjust project priorities based on the needs of the business and to endure a higher level of scrutiny as business stakeholders become more involved in setting the software development agenda.

  • WhiteSource Adds SBOM Tool That Lists Vulnerabilities

    WhiteSource Adds SBOM Tool That Lists Vulnerabilities

    WhiteSource has added a software bill of materials (SBOM) tool to its portfolio that, in addition to capturing the components of an application, also surfaces vulnerabilities that should be addressed.

    Many organizations are becoming more rigorous about making sure SBOM are attached to every software development initiative in the wake of an executive order issued by the Biden administration that requires federal agencies to employ them. While not every organization builds applications for federal agencies, the fact that the federal government is requiring them in the wake of a series of high-profile breaches has led other organizations to review their software supply chain processes.

    An SBOM facilitates those reviews by making available a formal, machine-readable inventory of software components and dependencies that can be used to track their supply chain relationships and identify dependencies and hierarchical relationships.

    Ori Bach, executive vice president for product at WhiteSource, said WhiteSource SBOM takes the concept a step further by also identifying open source libraries. It will also automatically update the SBOM when changes are made to make it easier to identify unintentional or malicious content being installed during application builds.

    Finally, WhiteSource SBOM also provides remediation guidance that ensures updates won’t break the build.

    Bach said it’s already apparent cybercriminals have significantly increased their effort to compromise supply chains as part of an effort to compromise as many downstream applications as possible. In many cases, cybercriminals are now specifically targeting open source projects that create software that tends to be employed across a wide range of use cases.

    An SBOM in and of itself doesn’t make applications more secure. However, it can provide visibility into the components of an application that can then be used to inform DevSecOps best practices, which organizations are implementing more broadly as responsibility for application security continues to shift left toward developers.

    There are two primary specifications that organizations can use to create an SBOM. The Software Package Data Exchange (SPDX) specification is an open standard for communicating SBOM information including components, licenses, copyrights, and security references. Defined by the Linux Foundation, SPDX is now recognized as the ISO/IEC 5962:2021 international standard. The second is the Software Identification (SWID) format that is today widely used by publishers of commercial software.

    Regardless of the format used to construct the SBOM, Bach said there’s an opportunity to more closely align the increased visibility it enables with the application security goals of the organization building the application.

    The primary reason SBOMs are not as widely used as they might be by now has as much to do with inertia as it does with technology. However, as organizations start to expect an SBOM to be made available, it’s clear application developers and builders will need to find a way to automate the SBOM process as applications are continuously updated. The challenge, of course, is that applications are now being updated with greater frequency—thanks mainly to widespread adoption of DevOps best practices—that now need to be integrated with any tool for creating and maintaining an SBOM.

  • Logz.io Extends Open Source Observability Platform

    Logz.io Extends Open Source Observability Platform

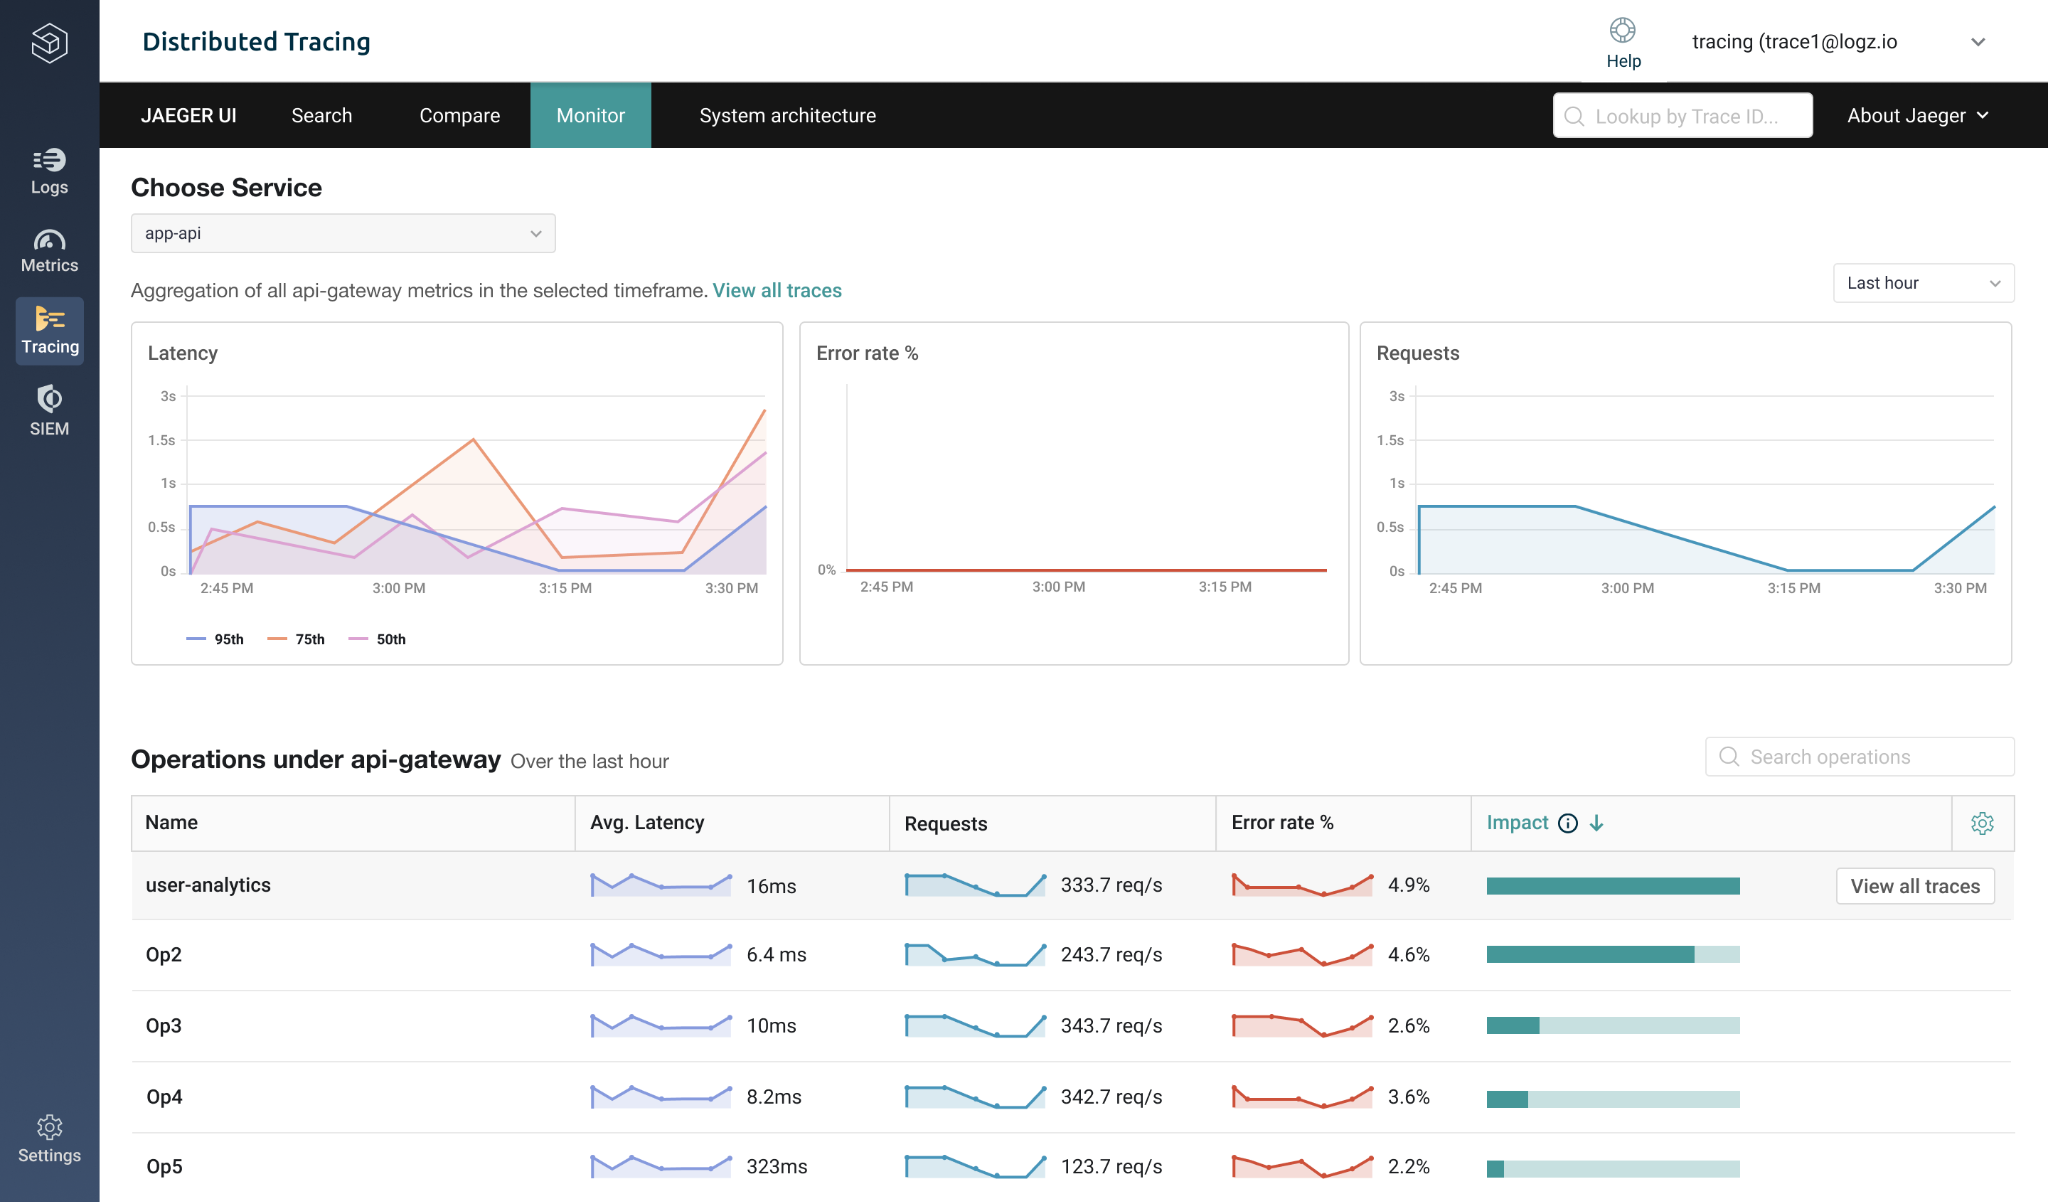
    Logz.io has enhanced its observability platform to include both unified dashboards and support for distributed tracing to monitor service performance enabled by the open source Jaeger agent software being advanced under the auspices of the Cloud Native Computing Foundation (CNCF).

    At the same time, Logz.io is making available a preview of an anomaly detection capability that leverages machine learning algorithms to build an artificial intelligence (AI) model to monitor data.

    The company has also added support for OpenSearch, a fork of the open source ElasticSearch software project that is no longer available via an Apache license. OpenSearch was created by Amazon Web Services (AWS) and Logz.io as an alternative search engine.

    Finally, Logz.io has added a security event management capability that makes it easier to classify, prioritize and collaborate on mitigation of cyberattacks as they are discovered.

    The Logz.io observability platform is entirely based on open source software. In addition, the company has made contributions to enhance both Jaeger and the OpenTelemetry project, including contributing an OTEL Span Metrics Processor that makes it easier to aggregate metrics.

    Logz.io CEO Tomer Levy said that, in general, it’s still early days as far as observability is concerned. As a concept, observability traces its lineage to linear dynamic systems. Observability at its most basic level measures how well internal states of a system can be inferred from knowledge of its external outputs. The overall goal is to make it easier to query machine data in a way that enables DevOps teams to proactively discover the root cause of issues before they cause further disruption. That’s a major advance over monitoring platforms that typically only provide predefined metrics to identify when a specific platform or application is performing within expectations. The issue, however, is most IT teams really don’t know what questions to ask to take full advantage of an observability platform, said Levy.

    However, as more organizations are exposed to observability platforms, it will become easier to advance both DevOps and DevSecOps as more platforms continue to leverage AI to provide remediation capabilities and automate processes based on the massive amounts of data collected via these platforms, said Levy. There is simply no way the average IT team will be able to manage all the microservices being strewn across a distributed computing environment without the aid of an AI model trained using observability data, he added.

    As DevOps continues to evolve, it’s more than likely that the best DevOps engineers are not going to want to work for organizations that have not invested in some form of observability. The odds of being consistently successful as a DevOps engineer decline sharply as IT environments become more complex.

    On the plus side, it should soon become a lot easier as the overall level of application instrumentation increases to manage those complex environments and to do so at a level of scale that doesn’t require a small army of DevOps engineers.

  • Top 10 DevOps Things to Be Thankful for in 2021

    Top 10 DevOps Things to Be Thankful for in 2021

    Thanksgiving has been observed in the U.S. since 1861 and was officially designated as an official holiday in 1863 by president Lincoln. Of course, the tradition itself traces its lineage to the early days of the Pilgrims.

    This past year, of course, has been one of recovery from a pandemic that caused the deaths of millions of people around the world. Vaccines have saved the lives of countless more, so there is much to be thankful for despite all our recent trials and tribulations. In that spirit, there are more than a few things for DevOps professionals, in particular, to be thankful for this year starting with:

    Digital business transformation: Organizations of all sizes have had to adjust their business models because of both major changes in buyer behavior and an ongoing supply chain crisis. DevOps teams are at the core of any major digital business transformation initiative, so the demand for DevOps expertise continues to outstrip the available supply. Going forward, it’s been predicted we’ll see more digital transformation in the next 10 years than in all the last 40 years combined. The vast majority of those initiatives would never see the light of day if it were not for the expertise of developers and engineers working hand-in-hand to build and deploy applications faster than ever.

    Low-code platforms: As the demand for applications to drive digital workflows spiked in the wake of the pandemic, professional developers relied more on low-code platforms to decrease the time required to build an application. While many complex applications will still be built using procedural code, it’s clear not nearly as many applications could have been deployed without relying on low-code platforms to build them. It remains to be seen how many of the next generations of low-code applications will be built by so-called citizen developers that may soon be flooding DevOps pipelines with application code.

    Microservices: As an architecture for building applications the core concept of employing loosely coupled services together to construct an application goes all the way back to when service-oriented applications (SOA) were expected to be the next big thing in the 1990s. Microservices have, of course, been around for several years themselves. However, with the rise of containers as a software artifact for building microservices, it’s only now becoming apparent that building an application constructed using microservices not only takes less time but is easier to maintain and also more resilient.

    Observability: As a concept, observability traces its lineage to linear dynamic systems. Observability in its most basic form measures how well the internal states of a system can be inferred based on knowledge of its external outputs. In the past year, a wide range of IT vendors introduced various types of observability platforms. These make it easier for DevOps teams to query machine data in a way that enables them to proactively discover the root cause of issues before they cause further disruption. That’s a major advance over monitoring platforms that typically only provide predefined metrics to identify when a specific platform or application is performing within expectations.

    Biden’s executive order: In the wake of a pernicious attack against IT service management software from SolarWinds, the Biden administration published a sweeping executive order that requires federal agencies to implement a wide range of security best practices. Foremost among them is guidance concerning the security of software supply chains; which resulted in many organizations reviewing their entire software supply chain to make sure similar breaches will not occur.

    DevSecOps: As an extension of any DevOps best practice, DevSecOps generally describes an overall shift left in terms of making developers more responsible for application security. While still in its relative infancy, DevSecOps is starting to gain traction as DevOps and cybersecurity teams look to bridge a cultural divide that is as wide as any in IT. The ultimate goal is to deliver more secure applications without reducing the speed at which they are being built and deployed.

    GitOps: At its core, GitOps is an operational framework that takes DevOps best practices used to automate application development and extends them to infrastructure. The basic idea is that the configuration software created to manage infrastructure-as-code is just another software artifact to be stored in a Git repository. The approach provides a means for IT teams to achieve a continuous delivery goal that, more than a decade after DevOps best practices were defined, remains elusive. It’s still early days as far as GitOps best practices are concerned, but this has been the year when GitOps become part of the mainstream DevOps conversation.

    Kubernetes: Simultaneously one the most powerful and most complex IT platforms ever to come down the proverbial enterprise IT pike, Kubernetes has emerged as a de facto standard for building and deploying container applications that can more efficiently scale up and down as required to consume IT infrastructure. The challenge (and the opportunity) now is to make Kubernetes much more accessible to mere mortal IT administrators that typically don’t have the programming skills of a site reliability engineer (SRE) and which are both hard to find and retain.

    GraphQL: Employed as a query language for application programming interfaces (APIs), GraphQL provides a more efficient means of accessing data than the REST APIs that have been employed by developers in the past. Originally developed by Facebook, GraphQL adoption is still in its infancy but it’s clear APIs based on GrapQL will one day be as plentiful as REST APIs. That’s especially critical for microservices-based applications that rely on APIs to access data across a highly distributed computing environment that requires a more efficient means for transferring data.

    Venture and Wall Street capital investments: Investment firms are helping fuel DevOps advances as they continue to make capital available for companies vying for their share of a market that is expected to see compound annual growth rates of 24.7% through 2026. There will, of course, eventually be a wave of consolidation as merger and acquisition activity inevitably ensues. In the meantime, however, there is a wide range of DevOps technologies that might not otherwise be as broadly adopted if it were not for all the cash being poured into DevOps companies.

    The most important thing, of course, is that so many DevOps professionals are still here to build and deploy applications. It’s been a trying year for all concerned; however, as the pandemic crisis continues to recede, we can all be thankful for the opportunities that lie ahead.

  • SAP Extends Developer Tool Portfolio

    SAP Extends Developer Tool Portfolio

    At an online SAP TechEd conference this week, SAP announced it has added additional low-code/no-code tools to the SAP Business Technology Platform (BTP) to enable both professional and citizen developers to build applications that invoke application services provided via the company’s cloud platform.

    The effort to increase the number of custom applications invoking those services revolves around a no-code development and automation platform dubbed SAP AppGyver, launched this week, and an existing set of low-code tools dubbed SAP Business Application Studio that the company also enhanced. SAP Process Automation, a robotic process automation (RPA) platform for automating workflows, is also being previewed.

    JG Chirapurath, chief marketing and solutions officer for SAP BTP, said the goal is to make it easier for organizations to build applications faster using tools that provide higher layers of abstraction through which they can invoke, for example, backend RPA and AI services via an application programming interface (API). SAP makes it possible to achieve that goal via an SAP BTP platform it provides to IT teams. The BTP platform allows teams to build applications that can be integrated with SAP application services running on a public cloud or managed by SAP on behalf of the customer. In either case, the goal is to make it possible for developers to spend more time building business logic versus building and maintaining integrations, he said.

    As part of the effort, new capabilities were also added to the SAP Conversational AI service and the company has promised to launch a personalized recommendation service based on a neural network.

    At the same time, the company also revealed it has updated the SAP Integration Suite for SAP BTP to provide access to additional prepacked integrations that are available on the SAP API Business Hub.

    In addition, the company said by the end of this year it plans to make the SAP Integration Suite available on the Google Cloud Platform alongside support it provides for other public clouds.

    Finally, a revamped training site, dubbed SAP Learning, will make it simpler for developers to advance their skills.

    The challenge SAP application developers are trying to navigate is determining which business processes are best served using packaged cloud applications versus ones that require actual customer code. The number of processes packaged in a suite of enterprise resource planning (ERP) applications has greatly expanded over time. With each successive update, ERP platform providers such as SAP identify new processes that could be beneficial to the bulk of their customers. For example, the processes that organizations use to track invoices and issue payments are all pretty much the same. It doesn’t make a lot of sense to write a custom application to manage a set of tasks that are already well-defined within a packaged application.

    Custom application development is typically where organizations have an opportunity to differentiate themselves. After all, if every organization is relying on the same core processes provided by a packaged application vendor, there is no real difference from one organization to the next. Custom applications, on the other hand, built using no-code or low-code tools or procedural code written by developers, should either be used to extend a workflow in some way an application doesn’t or should be used to create an application that provides a sustainable competitive advantage. That challenge—and the opportunity—is first identifying those processes and then finding the simplest way to build and maintain the applications that drive them.

  • Netlify Acquires OneGraph to Integrate GraphQL APIs

    Netlify Acquires OneGraph to Integrate GraphQL APIs

    Netlify this week announced it has acquired OneGraph, a provider of a platform that simplifies the integration and management of application programming interfaces (APIs) based on the GraphQL query language.

    At the same time, the company is committing $1 million to sponsor open source projects and setting aside $10 million for a Netlify Jamstack Innovation Fund that will help drive the development of emerging technologies. Those technologies will be consumed via the platform the company created based on Javascript, APIs and a markup language (referred to as Jamstack) to accelerate web application and website development. Rather than becoming investors in those companies, Netlify intends to make those funds available to advance the development of technologies that benefit the overall community.

    Fresh from raising an additional $105 million in funding, Netlify CEO Matt Biilmann said Netlify is committed to an ecosystem through which developers will be able to consume a wider range of services via both REST and GraphQL-based APIs. OneGraph will provide the core foundation for adding support for GraphQL to the Netlify platform, he noted.

    Overall, Netlify is trying to reduce the friction that developers encounter building web applications and the sites they run on, added Biilmann. That’s becoming especially critical as developers increasingly build microservices-based applications that invoke APIs to consume backend services that are made available via the Netlify platform, he added.

    Earlier this year, the company made available Netlify Build Plugins that provide DevOps teams with a set of continuous integration/continuous delivery (CI/CD) workflows for building websites and web applications. Designed to be launched from within a Netlify platform, those plugin makes it possible to build a web application or website that can be launched directly from within a Git repository.

    The overall Jamstack philosophy enables DevOps teams to separate the development of frontends and backends of websites and applications. That approach is agnostic as far as any specific JavaScript framework is concerned, but it does define a way to automate the build process for a web application or website.

    A recent survey of more than 3,000 Jamstack developers published by Netlify finds one-third of survey respondents have worked on sites serving millions of users over the last year. Nearly two-thirds of survey respondents (62%) work outside the tech industry, including in advertising and marketing (21%), media and publishing (14%), education (14%), financial services (13%) and business support and logistics (13%). Well over a third (38%) work for a technology company. About a quarter (26%) have more than 10 years of experience. Top Jamstack benefits cited by all types of developers are performance, uptime, speed of development, security, compliance and avoiding vendor lock-in, the survey found.

    Jamstack is, of course, not the only framework for building web applications and the sites they run on. DevOps teams are increasingly being tasked with building a much wider range of external applications to drive digital transformation initiatives that are typically built using some type of JavaScript framework. The next big DevOps challenge, of course, is that as the number of applications being built continues to increase, so does the number of applications that need to be maintained and continuously updated.

  • Kyndryl Aligns with Microsoft in the Cloud

    Kyndryl Aligns with Microsoft in the Cloud

    Following its spinout from IBM, Kyndryl has allied with Microsoft to increase the scope of IT services it provides on the Azure public cloud.

    Stephen Leonard, leader of global alliances and partnerships for Kyndryl, said that as part of this initiative, Kyndryl will be expanding the scope of the services it provides to both organizations building and deploying applications as well as those looking to migrate existing applications to the Microsoft Azure cloud.

    Over time, Kyndryl will expand its cloud services to include additional public clouds as part of a larger effort to enable organizations to embrace a hybrid cloud approach to enterprise IT that spans multiple on-premises and cloud computing environments.

    In the meantime, as part of the first partnership established by Kyndryl, the two companies are committing to providing services to address data modernization and governance, security and application workloads infused with artificial intelligence (AI) capabilities. The two companies also plan to establish a co-innovation lab. Microsoft is also committing to establishing a Kyndryl University for Microsoft.

    Leonard said given the overall shortage of IT expertise, more organizations than ever are relying on external IT services to, for example, accelerate application development. Kyndryl plans to work with those organizations to best evaluate where specific classes of application workloads might best be deployed, he noted.

    It’s become increasingly clear that more organizations are attempting to integrate third-party IT services within DevOps workflows. In some cases, that means standardizing on an opinionated DevOps workflow defined by the IT services provider. In other cases, the IT services provider is focused on a specific task such as securely provisioning infrastructure on behalf of developers.

    Regardless of the approach, however, DevOps workflows are evolving into a team sport made up of both internal and external IT professionals that are trying to bridge the cultural divide that always exists between different organizations. Which IT services provider organizations ultimately select often has as much to do with how flexible they are from a cultural perspective as much as it does their technical expertise.

    For its part, Microsoft is counting on IT services providers such as Kyndryl to increase the total number of workloads running on its cloud. Now that Kyndryl is independent of IBM, it is free to establish partnerships that previously would have been more complex to navigate.

    Of course, it’s up to each organization to determine the degree to which they prefer to work with a larger IT services provider versus a smaller rival that may specialize in one specific area or that is simply a better fit for a smaller company. The one thing that is certain is that as IT continues to become more complex, it’s not feasible for organizations to hire all the IT talent they require on a full-time basis. Organizations will need to carefully evaluate when it makes more sense to consume certain IT services as a function provided by someone else versus attempting to hire and retain talent to maintain that service themselves.

  • Nvidia/ARM Wavering | Google Outage Outrage | Backblaze IPO on Fire

    Nvidia/ARM Wavering | Google Outage Outrage | Backblaze IPO on Fire

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    Nvidia Can’t be Allowed to Buy Arm

    First up this week: Nvidia’s faltering attempt to buy Arm: Regulators around the world are alarmed by the idea. And now the UK—the legal home of the company—has taken the next step, which could nix the deal.

    Analysis: RISCy home for ARM

    This matters because ownership of the ARM ISA and the core designs would be a huge strategic stick to beat Nvidia’s competition with. Arm doesn’t make chips—it licenses technology to Nvidia and many of its competitors—AMD, Apple, Broadcom, Samsung and Qualcomm, to name but five. So this deal really shouldn’t go through, regardless of Nvidia’s fluffy PR reassurances.

    ARM chips aren’t just found in 99% of smartphones, but are an increasing fixture in the datacenter—especially where “performance per Watt” is important. They’re even found in exascale iron, including the Riken Fugaku, the world’s fastest supercomputer.

    Helen Thomas: Nvidia faces tough Arm wrestle

    It is one thing for a regulator to give your deal a thorough going-over. It is another for it to imply publicly that your assurances [aren’t] credible. … Nvidia got both from the UK’s Competition and Markets Authority. … The CMA’s full phase 1 report doesn’t make for easy reading.
    …
    The transaction, which was announced in September 2020, is bogged down in regulatory reviews around the world: … Arm’s “neutral” business model has always made it a difficult acquisition. … Arm licenses its designs to other chipmakers, providing scope to restrict rivals’ access.
    …
    Arm was a political talking point in 2016, when its sale to SoftBank … was waved through with embarrassing ease. There is now a much more muscular political take on UK national security concerns with a particular focus on tech.


    But if it’s owned by a Japanese company, why is the UK getting involved? Glad you asked—Aighearach answers:

    What did they buy? Shares of a UK company. … Then it is a UK company! … Buying shares is buying ownership, but it doesn’t move the company to another jurisdiction.
    …
    This blathering about “sold to a Japanese firm” is getting old.


    Nvidia claims, “The transaction will … boost competition and innovation.” Falmari finds that hilarious:

    Did Nvidia’s spokesperson previously work as a stand-up comedian? Because as jokes go, “boost competition” is a whopper. [Do you think] that’s what a company like Nvidia wants—to boost the competition?


    Google Cloud Outage has Ripple Effect

    Google’s load balancers all went offline for two hours on Tuesday. Aside from the knock-on Google Cloud failures, DevOps tools such as BigCommerce, Datadog, Deno, Discord, Egnyte, Evernote, Linear, Netlify and Toggl were reported to be affected. But perhaps the worst impact was felt by the poor, unfortunate users of Pokémon GO.

    Analysis: Paralysis

    In theory, putting all your eggs in one basket is okay—so long as that basket can reliably stop your eggs smashing on the pavement. But this isn’t the first time we’ve seen Google Cloud issues such as this; I can’t imagine it’s the last.

    Steven J. Vaughan-Nichols: Google glitch triggers major internet outage

    The result? Many of us have seen 404 errors when trying to get to some of our favorite web pages. … There appears to be more major sites having problems than not.
    …
    The specific problem seems to be with the GCP load balancers. These, working with Google’s Cloud Delivery Network (CDN) [are] designed to stop website failures and Distributed Denial of Service (DDoS) attacks by putting your website behind a single anycast IP.


    Are you feeling a touch of déjà vu? jeffbee, too:

    This is a sort of repetitive outage for Google. They’ve wiped out the GSLB configs before.

    A year ago there was also that big outage where they blanked out the whole Gmail delivery config and started rejecting all mail. … Config safety is not their strong suit.


    The #3 IaaS provider won’t get to #2 if it keeps this up. Here’s u/totopapa:

    I’m trying to convince my company to switch from AWS to GCP but an outage like this one is definitely a showstopper.


    Backblaze IPO Burns Brightly

    Backblaze is now NAS:BLZE. In its first week, the stock jumped 60%.

    Backblaze is well known for its tiny-margin consumer backup product and its open-source “storage pod” hardware—but is less well known for its DevOps-focused “B2” cloud storage service.

    Analysis: Can it Avoid Death-by-Packrats?

    Backblaze is trying to grow this newer DevOps business, without losing its classic consumer chops. But many of its former competitors have essentially dumped their “unlimited” offerings—it’s the old tragedy-of-the-commons problem.

    Jordan Novet: Backblaze [goes] public on small valuation and minimal funding

    In an era of blockbuster market debuts preceded by astronomical private financing rounds, Backblaze … a cloud service for backing up data … is a throwback to a time when sub-billion-dollar companies routinely went public to raise capital and build their profile … to win the trust of customers.
    …
    Backblaze shares climbed 24% in their debut on Thursday and another 12% on Friday, lifting the price to $22.31 and giving the company a market cap of around $650 million. … By the standards of its peers, Backblaze is a micro-cap.
    …
    One of Backblaze’s competitors is Amazon, the world’s fourth most valuable U.S. company. … Backblaze currently stores two exabytes of data — that’s 2 million terabytes — and has a half-million paying customers.


    Donovan Jones: Backblaze Targets $100 Million IPO

    The firm provides cloud-based storage services to small businesses and individuals worldwide. BLZE has grown revenue and gross profit impressively through the 2020 pandemic period and the IPO appears fairly valued, so is worth a close look.
    …
    The firm’s financials show strong revenue and gross profit growth. … The firm’s dollar-based net revenue retention rate for 2020 was 114%—a solid result. … The market opportunity for providing cloud-based storage services to small businesses and individuals is large and expected to grow at a material rate. … As for valuation, compared to partial competitor Dropbox, management is seeking the same Enterprise Value/Revenue multiple. [However] the combined revenue growth rate and EBITDA percentage rate … was 3% as of June 30, 2021, so the firm needs improvement in this regard.


    But there’s a long way to go, opines John Kozubik (aka rsync):

    Of the ~500,000 customers, 70,000 are B2 customers and 430,000 are “backup” customers—which are flat-rate “unlimited” users. … Roughly 85% of the user-base are paying $7/mo for “unlimited backup.”
    …
    These flat-rate users are very fickle and price-sensitive. … Roughly 85% of the user-base are paying $7/mo for “unlimited backup.” … It’s a fools errand to pursue this market and I assume the pivot to B2 was to build something more sustainable with a much higher price and usage ceiling.


    The Moral of the Story: Success is a journey, not a destination


    You have been reading The Long View by Richi Jennings. You can contact him at @RiCHi or tlv@richi.uk.

    Image: Kristin Wilson (via Unsplash)

  • Cortex Expands Microservices Catalog to Improve Collaboration

    Cortex Expands Microservices Catalog to Improve Collaboration

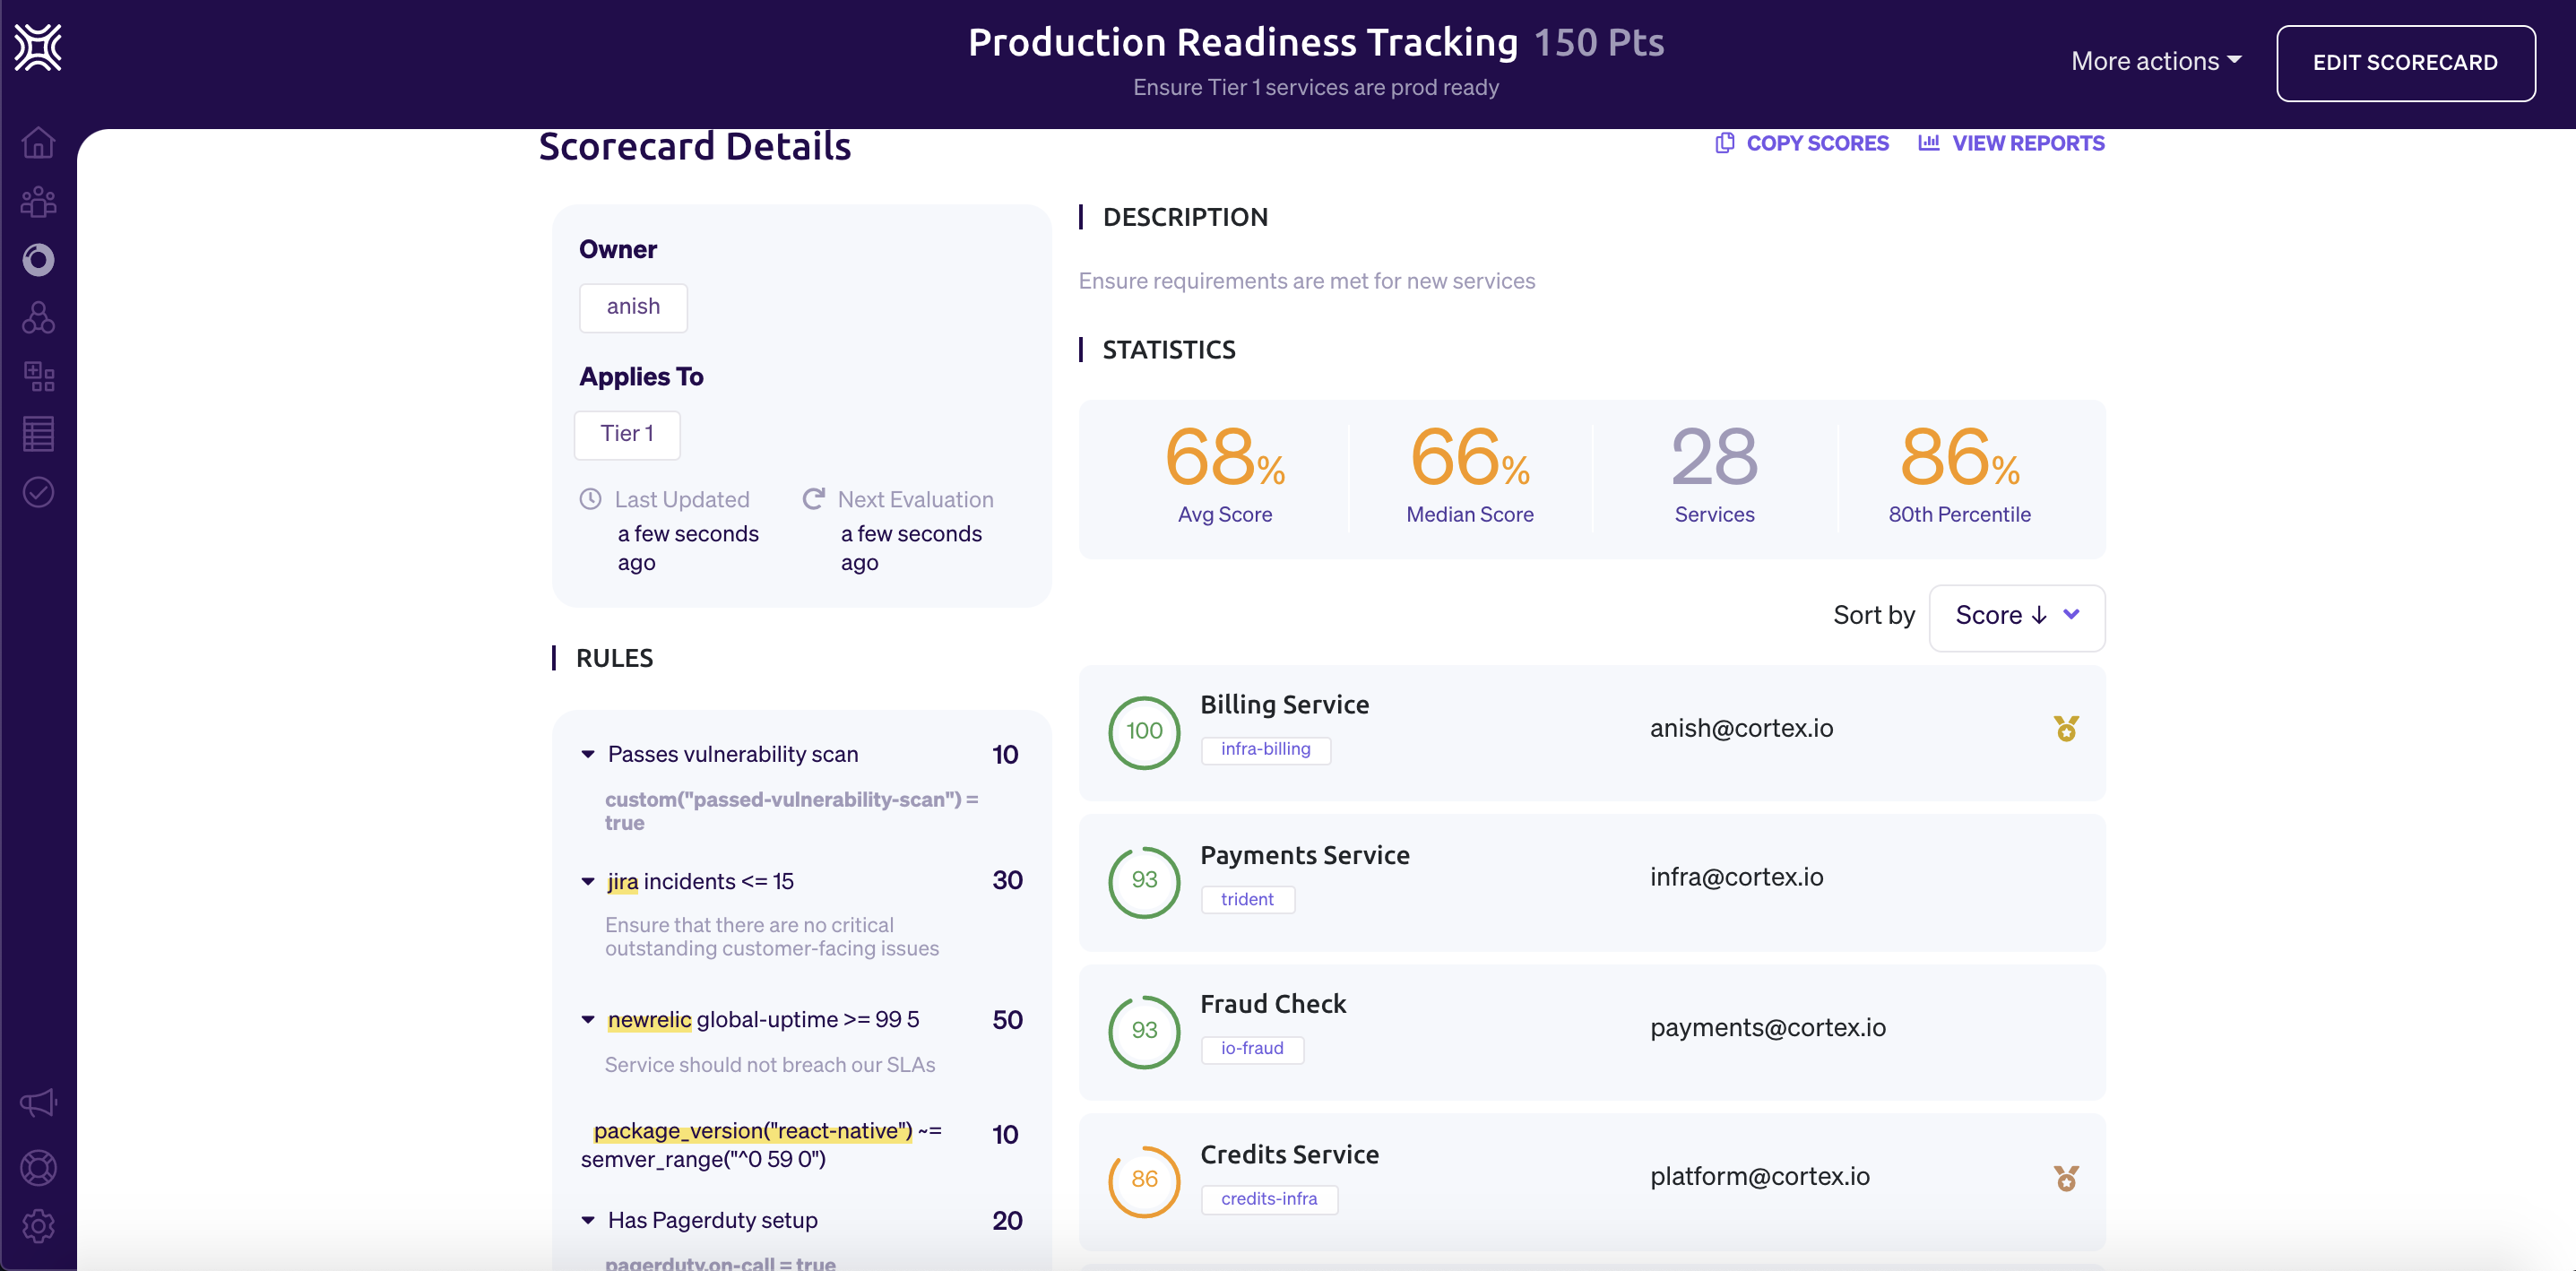
    Cortex, a provider of a catalog for tracking the ownership of microservices, today announced it has added a service creation capability that enables developers to use templates to scaffold new services in five minutes.

    In addition, the company has added a Cortex Teams offering that improves collaboration across teams of developers working on interdependent microservices.

    Fresh from raising an additional $2.5 million in funding, Cortex claimed it has increased its customer base by a factor of 10 since initially launching last May. Those customers include Rappi, Grammarly and 8×8.

    Cortex CTO Ganesh Datta said the company’s microservices catalog makes it simpler for teams of developers, DevOps engineers and security professionals to collaborate at a time when software development is becoming more complex. While microservices-based applications are easier to update and generally more resilient than monolithic applications, composing an application based on interdependent microservices created by different development teams can be more challenging to build and maintain.

    In some cases, organizations can even discover that different teams within their organization have built redundant microservices. Part of the reason that occurs is many IT teams still rely on spreadsheets to keep track of what microservices are being built and which ones are already deployed in a production environment.

    Cortex, in contrast, automatically imports data residing in developer tools to surface who within an organization is responsible for maintaining which microservices. A Cortex dashboard also enables DevOps teams to see which developers are on-call in the event of an unexpected incident as well as monitor and track the latency rate microservices are experiencing and which vulnerabilities have yet to be remediated.

    At the core of the platform is Cortex Query Language (CQL), a domain-specific language that allows DevOps teams to define granular rules that can be applied to, for example, on-call rotations, security vulnerabilities, package versions, service level objectives (SLOs) and the overall health of the microservice. Engineers can employ code in the form of YAML files to set reliability standards across teams and types of services.

    Grades can also be assigned to specific microservices based on associated metrics. That approach allows DevOps teams to apply gamification techniques using a scorecard to encourage developers to continuously improve their microservices. That capability makes it apparent to other developers which microservices can be most reliably employed.

    It may be a while before microservices-based applications dominate the enterprise landscape. Monolithic applications will be running in production environments well into the next decade. However, many of those monolithic applications are essentially being converted into a larger microservice that other applications can invoke via application programming interfaces (APIs) before being eventually being re-engineered into a set of logically connected microservices.

    The one thing that is clear, however, is that as the number of microservices expands, it becomes more difficult to determine precisely what capabilities are already available to highly distributed application development teams.

  • LogicMonitor Introduces Unlimited Log Data Retention

    LogicMonitor Introduces Unlimited Log Data Retention

    LogicMonitor today announced it will provide an option that allows IT organizations to retain an unlimited amount of log data on its software-as-a-service (SaaS) platform.

    Tej Redkar, chief product officer at LogicMonitor, said one of the issues that is holding back advances in observability is the cost of storing log data. LogicMonitor has decided to remove that issue by allowing IT teams to store log data on its LM Logs service for as long as they require, Redkar said.

    That data will also always be readily available as hot storage with no need to wait for data that has been stored offline to be rehydrated, he noted. Instead, that data is readily accessible alongside the metrics and distributed tracing data that LogicMonitor also collects, said Redkar.

    In general, LogicMonitor is making a case for centralizing observability for the entire IT organization via a SaaS platform infused with machine learning algorithms that automatically surface anomalies in real-time based on millions of events captured via log data. The issue many organizations encounter today is silos of decentralized observability data that are more complex to maintain while providing less visibility at a higher total cost, said Redkar.

    The LogicMonitor platform, in contrast, is designed to be equally accessible to, for example, a network operations team as it is to a DevOps team, he noted.

    Not every organization needs to store log data forever, but Redkar said as IT management continues to evolve, more organizations are moving toward storing metrics, traces and logs for longer periods of time. The rise of open source agent software is also making it less costly for organizations to capture that data in the first place.

    It’s not clear to what degree other providers of observability platforms will provide unlimited retention of data, but as the cost of storing data in the cloud continues to drop it’s apparent that billing IT organizations for storage costs is becoming untenable. There is always going to be some cost associated with storage, but it’s not enough to charge extra beyond the core cost of the service. The only thing accomplished by billing separately for storage is discouraging IT teams from storing the data required to both attain observability and better train the machine learning algorithms that surface anomalies.

    Observability, in one form or another, has been a core tenet of DevOps best practices for years. Initially, DevOps teams focused on continuous monitoring as the most effective way to proactively manage application environments. Observability platforms infused with machine learning algorithms make it possible to correlate events so that analytics tools can more easily identify anomalous behavior in real-time. Armed with those insights, it becomes a lot simpler for IT teams to resolve issues faster.

    In fact, there may even come a day when the so-called “war room” meetings that are convened to identify the cause of an IT issue via a painstaking process of elimination are no longer required. In the meantime, however, the total number of IT incidents that actually lead to disruption should steadily decline, even as IT environments become more complex.