Category: Features

  • AWS Outage Exposes Weaknesses of DevOps Resilience

    AWS Outage Exposes Weaknesses of DevOps Resilience

    The December 7, 2021 Amazon Web Services (AWS) outage severely disrupted services from a wide range of businesses for more than five hours and highlighted just how reliant businesses have become on internet-delivered services. The outage mostly impacted web services in the eastern U.S., yet the implications are universal: It’s a reminder that many businesses blindly ignored the old axiom about putting all your eggs in one basket and instead are relying on a provider with a single point of failure.

    Services ranging from airline booking systems to streaming video to e-commerce were disrupted during the outage, causing millions of dollars in lost revenue and countless hours in productivity. One of the more interesting aspects of the outage is the impact it had on services from collaboration vendors such as Slack, Trello, Asana and Smartsheet—tools that many development and DevOps teams have come to rely on.

    Furthermore, core AWS services, such as the company’s Elastic Compute and DynamoDB cloud tools were also impacted, disrupting many third-party services and severely hampering business processes that use those services. While the obvious victims of the outage are well known, like Amazon’s own e-commerce operation, there is a troubling undercurrent: The disruption to DevOps frameworks and those using them.

    AWS has been rather tight-lipped about the root cause of the outage thus far; however, there are still many lessons to be learned for the DevOps community and questions that must be asked such as “Can the DevOps process survive during IaaS/SaaS disruptions?” and “Can multi-cloud failover solutions be baked into the applications DevOps builds?”

    There are no simple answers to those questions, but the outage highlights the need to understand the underlying architecture and framework of a deployed DevOps system. Take, for example, how many developers in the DevOps community have embraced SaaS tools to accelerate the development process and to feed CI/CD pipelines. SaaS applications such as code scanners, pipeline orchestration and even IDEs have become common in the world of DevOps. But has anyone bothered to ask what happens if a single one of those tools fails?

    What’s more, the reliance on SaaS tools in the development process has led to the creation of potential liabilities in the applications created by DevOps developers. DevOps applications have come to rely on APIs, are often driven by microservices and are frequently deployed into containers that run on SaaS. If any of those elements become non-functional, numerous applications could fail, ultimately putting the onus on developers to explain why they are creating applications with a single point of failure.

    Moving forward, the DevOps community needs to take a serious look at the components of their frameworks and determine if there are any single points of failure—including their IaaS/SaaS providers. While it may be impossible to remediate every single one, there is a lesson to be learned about how fragile the development process can become if no one bothers to build an inventory of the tools used and take into account how a failure of any one of those tools could impact workflow. There are numerous examples of how an external failure of a single component impacted the functionality of an application, while the discovery process of the root cause has taken days or even weeks. This can be mostly attributed to not only a lack of knowledge, but a lack of visibility into the components used.

    Those lessons can be extended to the development process itself, where the best practice of rooting out single points of failure can be extended to the applications themselves. Leveraging that intelligence starts with understanding the concept of a software bill of materials (SBoM), a piece of supporting documentation that is becoming increasingly important to the purveyors of applications. A properly-defined SBoM reveals all of the components (libraries, APIs, etc.) that are baked into an application and can be used as a map to define where weaknesses may lie.

    For the DevOps community, the recent AWS outage has become a clarion call to look inward and discover how the applications they are building may be part of the problem. With continuity and resiliency becoming major topics in the IT and business realm, it’s about time that DevOps practitioners start to look at how they can support both of those business-critical needs. The days of finger-pointing to shift blame must come to an end, and if businesses that rely on software want to grow, someone needs to take responsibility for providing answers when outages occur and learn from those outages to create applications that are more resilient.
  • Vercel Acquires Turborepo to Gain Build System

    Vercel Acquires Turborepo to Gain Build System

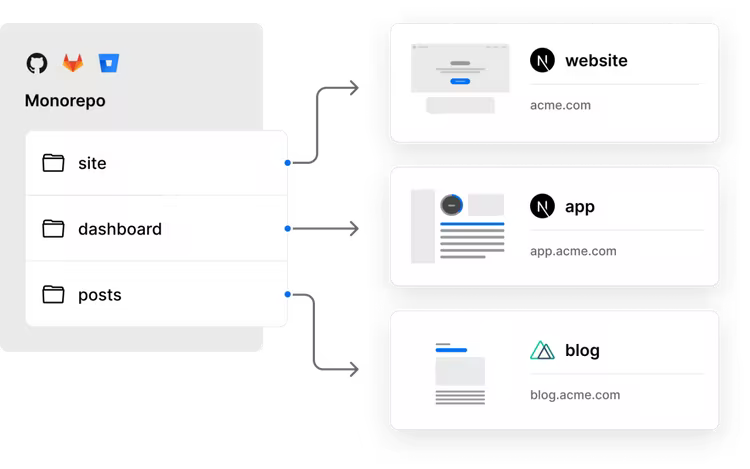
    Vercel today announced it has acquired Turborepo, a provider of a build system for JavaScript and TypeScript applications that provides developers with access to an easy-to-use monorepository for their code.

    In the wake of that acquisition, the command line interface (CLI) for accessing Turborepo will now be available under an open source license.

    Jared Palmer, creator of Turborepo and other popular open source projects including Formik and TSDX, will continue working on accelerating Turborepo’s capabilities as the new leader of a build performance team at Vercel.

    The goal is to move existing users of the Turborepo cloud service to a Vercel platform for building applications using the Next.js framework, which makes it possible to build web applications based on the React library for creating user interfaces that enable both static site generation (SSG) and server-side rendering (SSR).

    Palmer said monrepositories such as Turborepo not only make it easier for developers to manage builds but also reduce the amount of time required to process those builds using a continuous integration/continuous delivery (CI/CD) platform.

    Rival build systems are also much more complex to configure and manage, which Palmer said is a primary reason many developers have not yet set up their own mononrepositories.

    As the number of applications that organizations want to build and deploy in the digital business transformation era increases, the focus on developer productivity is intensifying. Rather than having to maintain a complex build system, Turborepo is designed to be simple to configure. As a result, more developers can reduce build times by as much as 50%, noted Palmer.

    In effect, front-end developers are able to more easily become full-stack developers by combining that build system with the Next.js framework, he added.

    DevOps teams will need to adjust to applications capable of providing richer application experiences without relying as much on backend infrastructure. That shift has implications for everything from the amount of network bandwidth consumed to the performance of web applications. The Vercel platform employs caching, routing and a React framework to optimize application performance in a way that reduces the dependency on backend infrastructure to optimize application performance.

    As web application development continues to evolve, the overall rate at which they web apps are built should increase significantly. Naturally, DevOps teams will need to consider the implications of having more applications move through DevOps pipelines and the need to continuously update those after they are deployed.

    It’s not clear whether or how much DevOps teams will nudge developers toward frameworks such as Next.js to develop web applications that might not tax backend infrastructure as much as previous generations of applications. In effect, developers can take advantage of frameworks that enable them to treat the underlying IT infrastructure as if it were serverless whenever possible with tools that have a familiar JavaScript construct. Vercel claimed there are already more than 30,000 sites running Next.js in production at organizations like Airbnb, Hulu, Nike, Ticketmaster and Uber.

    One way or another, it’s clear that the way web applications are being built is fundamentally changing. The only issue now is determining to what degree the rest of the IT organization is prepared to absorb that level of change.

  • AWS Outage Outrage | Rusty Linux | ARM Latest

    AWS Outage Outrage | Rusty Linux | ARM Latest

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: Amazon Web Services falls on its face, Linux’s move to Rust takes the next step, and the FTC stabs another fatal wound in the horrible Arm/Nvidia deal.

    AWS us-east-1 Breaks the Internet

    First up this week: Amazon Web Services’ outage on Tuesday sent scads of DevOps teams scrambling. But what was the cause?

    Analysis: DNS DDoS?

    While we still don’t officially know, there is some chatter to speculate on. Could it be that AWS’s DNS infrastructure is vulnerable to DNS reflection attacks?

    Hello. It’s Dave Lee: From angry Adele fans to broken robot vacuums

    It started early on Tuesday morning. Robot vacuums ceased sucking, Wi-Fi cameras stopped watching and eager Tinder daters were left unable to “swipe right.”
    …
    Within Amazon itself … the unthinkable occurred: grounded delivery drivers were unable to load packages and deliver to customers’ doorsteps, just as the peak Christmas season begins to step up. … Drivers at multiple facilities across the country were sent home … some dreading whatever workload may await.
    …
    An outage at Amazon Web Services … had rippled through the online economy, crippling services used by millions of people. … An “impairment of several network devices” in … US-EAST-1 was the “root cause” of the disruption, Amazon said.


    I was wondering what DevOps’ers learned? Enter Max Rozen:

    AWS took approximately an hour to update their status page to indicate anything was happening. … While our infrastructure is hosted across 20 AWS regions, a single point of failure was hosted in us-east-1.
    …
    What we learned: … I learned the saying, “Friends don’t let friends deploy in us-east-1.” As a result, we’ll be moving some things over to us-east-2 to start with. Secondly, we’ll be adding redundancy and the ability to failover to another AWS region.


    Getting inside the business, here are Eugene Kim and Katherine Long, to go over everything:

    Even inside AWS … information on the outage remained sketchy [and] rumors spread among staff. One AWS employee speculated that the outage was caused by an “orchestrated DNS attack,” while another employee downplayed those concerns.
    …
    According to a screenshot of an internal AWS communique … ”firewalls are being overwhelmed.” … A separate internal note said … the network issue “specifically impacted” Amazon’s internal DNS servers.


    Linux Officially Gets Rust Code

    The Rust language has taken the next step toward being part of Linux kernel development. Some “drivers and other non-core kernel programs” written in Rust can now be PR’ed. But there’s still no plan to go further.

    Analysis: Still needs lubrication

    Rust is much better than C for writing memory-safe code, and coding provable implementations. However, bootstrapping the toolchain is still stupidly hard.

    Steven J. Vaughan-Nichols: Linux is getting more Rust in it by the day

    It wasn’t that long ago that the very idea that another language besides C would be used in the Linux kernel would have been laughed at. [But] this has been coming for several years now. … Why? Because it’s much safer than C, especially at handling memory errors.
    …
    The next “patch series [adds] support for Rust as a second language to the Linux kernel.” … While he’s encouraging a slow but steady approach to introducing Rust into Linux, [Linus Torvalds] has also said that using Rust interfaces for drivers and other non-core kernel programs makes sense. [But] no one’s going to rewrite the kernel’s 25 million lines of C in Rust.
    …
    The Rust code proposed for the kernel now relies on the stable Rust compiler rather than the beta compilers. … As Linux kernel and lead Rust on Linux, developer Miguel Ojeda, put it, “By upgrading the compiler, we have been able to take off the list a few unstable features we were using.”


    How is it “safer than C”? ssokolow shares this fascinating insight:

    Rust tries to encourage that through good API design which allows it to be proven at compile time that the invariants will be upheld, thus avoiding the need to choose between safety and performance. My favourite example … is “the typestate pattern” which lets you teach the Rust compiler to prove correct traversal of any state machine.
    …
    A more mundane example would be the iterator APIs: No need for bounds checking if the iterator looks up the length once at the beginning and the APIs prevent you from wandering out of each entry it hands you. … Rust programs tend to run faster than their C and C++ counterparts because the developers feel comfortable introducing and maintaining more aggressive optimizations.


    “And then a miracle occurs,” quips @dave_universetf:

    I’m intrigued [but] I can’t help but feel sorry for the people doing bootstrapping work. C is hard enough to bootstrap, but Rust is a whole new level of pain.
    …
    Rust is literally not source bootstrappable. [The compiler] that works right now is Rust 1.39. So then you have to compile 18 more Rust compilers to get up to the current version.


    Nvidia’s ARM Woes Continue

    As I’ve said before, this deal really shouldn’t go through. Ownership of the ARM ISA and the core designs would be a huge strategic stick to beat Nvidia’s competition with. ARM chips are an increasing fixture in the datacenter—especially those that value “performance per Watt.”

    Analysis: Stick a fork in it

    Nvidia’s attempt to buy Arm from SoftBank is suffering death by a thousand cuts. And the latest wound comes from the FTC’s Higonokami knife.

    Paul Thurrott: FTC Sues to Block Sale of Arm to Nvidia

    The U.S. Federal Trade Commission … sued to block Nvidia’s $40 billion acquisition of … Arm, citing competitive concerns. … Nvidia announced its intention to purchase Arm from Softbank for about $40 billion, over one year ago, in September 2020. But the deal fell under immediate criticism from the major industry players that rely on Arm’s … designs, and the UK government announced … it would “intervene” for national security reasons.
    …
    Now, it may not happen at all. “We will continue to work to demonstrate that this transaction will benefit the industry and promote competition,” Nvidia said.


    Explain like I’m 5? Here’s swillden:

    ARM has a non-trivial and increasing share in the data center. … ARM is much, much bigger than phones … Arm is an important competitor to Intel and AMD. … Arm licensing IP to Qualcom, nVidia, Mediatek, Unisoc, Samsung, Apple, Google, etc., has been great for many areas of technology.
    …
    Arm acting as a common … designer for a bunch of different chip vendors has been extremely good for … progress in CPU/SoC design. … It would be really unfortunate if a lot of the industry were to shift back to x86, eliminating all of the competition on hardware features that we get from the many ARM chipmakers.


    But what of SoftBank? Ian King runs the numbers:

    Wall Street analysts are all but calling the deal dead. … According to Citibank analysts, the chances of the Nvidia purchase closing are now just 5%.
    …
    The company faces the prospect of losing a jackpot of roughly $74 billion. … Other suitors are unlikely to match such an offer. … So SoftBank’s best alternative may well be an initial public offering for the Arm business—but that is likely to value the company at … $19.8 billion—only about 27% the value of the … Nvidia deal.


    The Moral of the Story: It’s no secret that the both of us are running out of time


    You have been reading The Long View by Richi Jennings. You can contact him at @RiCHi or tlv@richi.uk. (It’s so typical of me to talk about myself—I’m sorry.)

    Image: Ləman Şirinzadə (via Unsplash)

  • Digital Business Transformation Driving More API Adoption

    Digital Business Transformation Driving More API Adoption

    A global annual survey of 2,200 developers published today by RapidAPI, a provider of an application programming interface (API) hub, finds digital business transformation initiatives have led to an increase in reliance on external-facing APIs.

    According to the survey results, nearly three-quarters of developers (74%) are using APIs for internal applications. However, nearly half (49%) said they are working on third-party APIs, with 44% working on partner-facing APIs. That’s up from 35% a year ago.

    RapidAPI CEO Iddo Gino said it’s clear APIs are a key enabling technology for driving digital business transformation initiatives.

    More than three-quarters of developers (75%) indicated that participating in the API economy is a top priority for their organization now or in the near future, according to the survey results. Companies are realizing the opportunity for new revenue streams, with growth in API monetization strategies increasing to 41% from 35% in 2020.

    In addition, more than two-thirds of developers (68%) said they expect to increase API use in 2022, with 61% relying on APIs more in 2021 than in 2020.

    However, well over half (56%) noted that a shortage of developer talent is a top concern, followed by lack of internal prioritization around digital transformation efforts (34%), lack of API development resources and tools (32%) and lack of alignment with other departments (29%). A full 90% also noted that security and data privacy is a key issue to consider when employing APIs.

    The results also show the use of REST and SOAP APIs in production environments fell 3.7% and 1.4%, respectively, in 2021. That drop reflects the rise of alternative API technologies such as GraphQL and Async APIs, said Gino, However, he noted it’s unlikely any new class of APIs is likely to supplant legacy APIs anytime soon; instead, most organizations will be employing a wide range of APIs for many years to come.

    The survey results reveal that JavaScript is the most used (71.6%) and preferred (51.9%) programming language for building APIs. TypeScript is also gaining traction in terms of usage (20%) and being preferred (12%).

    The most troubling aspect of the survey, however, may be the fact that well over half of respondents (56%) said they are open to switching jobs. The top five reasons developers said they might switch jobs are higher compensation or improved benefits (60%), interest in a specific product or technology at a different company (54%), desire for a more flexible working environment (38%), interest in a specific company or market (25%) and an opportunity to work with former teammates or friends (17%).

    It’s not clear to what degree the so-called Great Resignation phenomenon might be impacting DevOps teams in general. However, it’s apparent no class of jobs is immune from a general sense of restlessness that pervades the market as the global economy continues to recover from the COVID-19 pandemic. The challenge and the opportunity for DevOps leaders is to encourage the best talent available to join and then remain with their organization versus pursuing a job somewhere else that, at least from afar, appears to have greener pastures.

  • Iterative Adds Experiment Versioning to MLOps Platform

    Iterative Adds Experiment Versioning to MLOps Platform

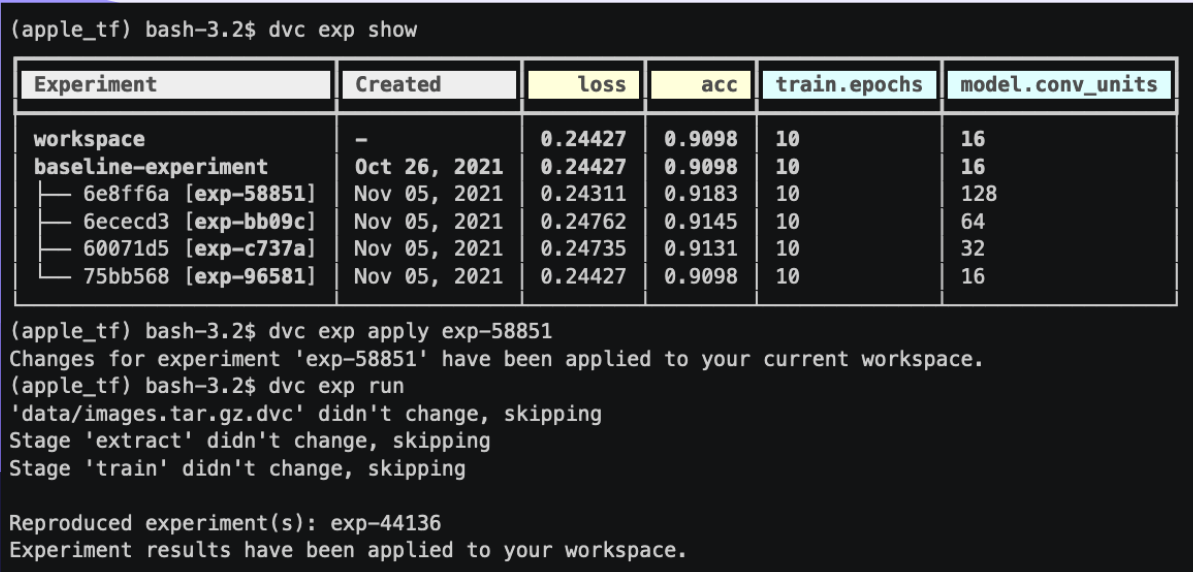
    Iterative today added an experiment versioning capability to an open source platform for managing machine learning operations (MLOps) using GitOps workflows.

    Dmitry Petrov, Iterative CEO, said the latest version of the Data Versioning Control (DVC) platform makes it simpler to save, compare and reproduce machine learning (ML) experiments at scale without requiring organizations to set up an additional repository to track them. Instead, organizations can store those experiments alongside other software artifacts in a Git repository, he said.

    As a result, IT teams will no longer need to try to keep track of experiments using spreadsheets or notebook tools such as Jupyter, he noted. Organizations that are building AI models for applications constructed using DevOps workflows will also find it easier to comply with a wide range of existing and forthcoming compliance mandates, added Petrov.

    The DVC platform makes use of a Git-like interface to enable organizations to track multiple versions of data sets, models and pipelines across an MLOps workflow. That capability is being extended to make it easier to manage the experiments data science teams create during the construction of an AI model.

    Iterative is at the forefront of an emerging debate over how best to infuse AI models into applications. Providers of platforms used by data science teams are making a case for separate repositories for tracking the artifacts used to construct an AI model. Iterative, on the other hand, is arguing for the use of an AI model build framework that uses the same Git repositories where any other type of software artifact is stored and shared. Iterative’s argument is that, in effect, AI models are just another type of software artifact, noted Petrov.

    In addition to reducing the total cost of building AI models by reducing the number of platforms required, a Git-based approach also makes it simpler for DevOps and data science teams to collaborate because the DevOps team will have more visibility into what AI models will eventually need to be incorporated into an application.

    It may be a while before the development of AI models and applications fully converges. Data science teams today typically have defined their own workflow processes using a wide range of graphical tools. However, as it becomes obvious that almost every application is going to be infused with machine learning and deep learning algorithms to some degree, the need to bridge the current divide between DevOps and data science teams will become more acute.

    In the meantime, DevOps teams should assume that many more AI models are not only on the way but that those models will need to be continuously updated. Each AI model is constructed based on a set of assumptions; however, as more data becomes available, AI models are subject to drift that results in less accuracy over time. Organizations may even determine that an entire AI model needs to be replaced because the business conditions on which assumptions were made are no longer valid. One way or another, the updating and tuning of AI models is likely to soon become just another continuous process being managed via a DevOps workflow.

  • CI/CD Is Still All About Open Source

    CI/CD Is Still All About Open Source

    One of the lessons I’ve learned in my years at the helm of DevOps.com is that the heart of DevOps is CI/CD. And at the heart of CI/CD is open source. While the names have been changed to protect the innocent (and the obsolete), these lessons are as true today as they ever were. CI/CD is still all about open source.

    When we first started DevOps.com, folks said that DevOps was just a symptom; CI/CD was the cure. For many of you, that cure was delivered via open source—probably using Jenkins. Jenkins, which itself was a fork of the open source Hudson project, was created by Kohsuke Kawaguchi.

    Jenkins was a CI tool at heart and later morphed into a CI/CD tool. Many people think that this fork in the road may have hurt the continued evolution of continuous delivery in the long term. But that is an argument for another DevOps.com article (or maybe even a panel discussion at an upcoming DevOps live event).

    Regardless of where you stand on that issue, as an open source project, it is hard to argue with the success of Jenkins. Driving a lot of that success is the Jenkins plug-in architecture. There are literally thousands of plugins that allow Jenkins to work with just about anything. That is the engine that powered Jenkins, yes; but its secret superpower was and is open source.

    That said, Jenkins has grown a bit long in the tooth over the years. It’s not that it doesn’t do what it always did, it’s that what we do and how we do it has changed. Microservices, Kubernetes and even cloud have changed the very fabric of the tapestry in front of which Jenkins sits. The open source community that supports Jenkins should receive enormous credit here: It has tried mightily to keep up with the many changes. 

    Jenkins X sought to bring Jenkins to Kubernetes, for instance. But ultimately, nothing lasts forever and, as it says in the Bible, “For everything there is a season, and a time for every purpose under heaven: A time to be born, and a time to die.” Now, I am not saying Jenkins is dying, but I think its time as the leader of the pack is behind it.

    The good news is there are a host of new CI/CD tools that have risen to fill the vacuum left by Jenkins. Some of them are entirely open source; some are based on open source. Solutions such as Buildkite, Harness, Codefresh, GitLab, GitHub, CircleCI, JFrog and Tekton to name but a few. 

    Another major development has been the rise of GitOps. Weaveworks has led the way in adoption, not to mention coining of the term GitOps itself, but clearly, they are not alone. What these solutions all have in common, though, is open source.

    I used to think it was sort of a chicken-or-the-egg question when it came to CI/CD and open source. But I realize now that it is not. I firmly believe that, if not for open source, CI/CD would not be the force it is today. Make no mistake, it is truly a force. CI/CD has become the dominant method for software development.

    Of course, you could say “Why stop at CI/CD? Open source has become the dominant software development foundation in observability, OS, cloud and so much more!” Yes, I agree—we are living in the open source age. This rising tide may in fact lift all boats, including CI/CD.

    This wave is forcing all vendors to either go entirely open source or at least support open source. What’s more, for the foreseeable future, I don’t see that changing. Open source has also wrought other changes in the market. How software tools, including CI/CD, are distributed and consumed. Who is hiring enterprise software salespeople anymore? Doing large POCs? No, open source has resulted in getting software into the hands of developers and DevOps teams directly and delivering delight. If your product works, they buy it. If it doesn’t work, they won’t, either—and they will let you know, too!

    This meritocracy is another benefit of open source and is helping to speed the development of better, next-gen CI/CD tools in the market. And at the end of the day, we are all better off for that.

  • API Sprawl a Looming Threat to Digital Economy

    API Sprawl a Looming Threat to Digital Economy

    New estimates say the total number of public and private APIs in use is approaching a whopping 200 million. APIs are becoming increasingly crucial to the global digital economy. They are the backbone of many digital platforms and drive the composable enterprise model. But this ubiquity presents sprawl issues.

    F5 recently released a study that examines the conditions of the API economy at large. Authored by Rajesh Narayanan and Mike Wiley of F5, the paper, Continual API Sprawl: Challenges and Opportunities in an API Driven Economy, articulates the state of API sprawl and the conditions behind its arrival.

    According to Narayanan and Wiley, “If data is the new oil, then APIs will become the new plastic.” This looming reality will require a continuous approach to API management to avoid further polluting the digital ecosystem.

    Below, I’ll review the report’s main takeaways to see what has given rise to API sprawl and consider how IT leaders should respond.

    State of API Growth

    APIs have evolved as a standard mechanism for businesses and services to connect and share value. And, as more companies begin to rely on them, the API economy is becoming big business—83% of organizations today consider API integration a critical part of their business strategy, according to the 2020 Cloud Elements State of API Integration Report.

    There is a proliferation of API styles. Thousands of public productized APIs exist, but more private and partner APIs are in use. Technically speaking, APIs come in many different forms—they may be web-based, browser-based or embedded into devices. The report also identifies single-purpose APIs and those that aggregate multiple data providers.

    API use cases are pervasive, from hotel bookings to weather, stock tickers, transportation, IoT, DevOps workflows and many other areas. “API-powered apps have permeated every aspect of our lives,” said the report. Yet, typical market estimates are usually quite conservative when sizing up this market, said F5. According to F5’s aggressive calculations, we will be approaching 1.7 billion active APIs by 2030.

    APIs present a high value from startup use cases to enterprise applications. However, a downside is that this growth is leading to sprawl, said Narayanan and Wiley.

    API sprawl is the term used to describe both the exponentially large number of APIs being created and the physical spread of the distributed infrastructure locations where the APIs are deployed.

    Factors Driving API Sprawl

    Sheer growth. Sources predict the number of developers will grow to 45 million by 2030. SlashData also estimates that 30% of developers already use APIs. As the number of APIs on the market moves into the millions, managing growth poses a significant challenge, especially without proper governance and best practices.

    Lack of standards. “The lack of a common shared model contributes to API sprawl,” the report said. API design standards do exist, yet guidelines often leave room for nuances between services. Standards have also emerged around specific industries, like financial data exchange (FDX). While helpful for a single sector, this doesn’t advance multiple industries simultaneously. A lack of standardization leads to differing versioning approaches and integration challenges.

    New development approaches. Integration requirements are forcing many new APIs to unite disparate business apps. The microservices architecture trend is also adding to sprawl, as “APIs are both northbound to interfaces via microservices and horizontally between microservices.”

    Continuous software development. Continuous development, paired with the need to connect business units with bespoke requirements, could produce multiple versions of the same API. This quickly leads to maintenance difficulties, out-of-date documentation and broken clients. The report also cites rising data creation and “everything-as-a-service” trends as harbingers of an API sprawl.

    Various computing evolutions. New computing trends are also prompting a sprawl, says the report. Business units may be operating on different on-premises or cloud environments. When this hybrid situation occurs, APIs could get dispersed over many locations and become difficult to track. Specific connections may be created to cater to new environments like edge computing and IoT devices, further increasing sprawl.

    Problems With API Sprawl

    A digital economy reliant on APIs also relies on the underlying stability and availability of these services. Yet, “APIs have a shelf life and become unsupported if ignored by the developers,” the paper acknowledged. It could be hard to maintain service reliability for APIs sprawled across a distributed cloud. In addition to reliability issues, there are many other possible repercussions of an API sprawl.

    For one, management and operation at scale become difficult. Not all APIs are based on a specification, like OpenAPI. This means that API documentation may not be as streamlined and accessible, thus hurting discoverability and onboarding. “A simple means to connect these APIs may not be possible with conventional or legacy networking approaches,” the report added.

    As developers are top consumers of APIs, a sprawl could negatively impact their integration experience. Maintaining a swelling library of API dependencies can be cumbersome. Plus, APIs are prone to evolve and version over time and when endpoints are altered without advance notice, it leads to broken clients. Even small changes in API functionality can have a huge impact since all observable API behaviors will become relied upon, whether documented or not. (This is known as Hyrum’s Law).

    But the security ramifications of API sprawl are perhaps the most troubling. A whopping 91% of enterprises experienced an API security incident in 2020. Malicious API traffic also rose by a staggering 300% in mid-2021, Salt Labs found. Increased API use will undoubtedly cause more frequent attacks.

    “Unmanaged API sprawl is a security breach waiting to happen,” said the report. APIs typically adopt API keys for authentication and authorization, but this method is prone to misuse. Credentials are often exposed or misconfigured. Bad actors can use APIs to steal loads of data and computing power. As a result, sprawl is undermining trust in API connections and responses.

    Mitigating The Sprawl

    With the growth of the API economy slated to reach the billion mark in the next ten years, figuring out secure, stable inter-cluster communication will become more critical. According to F5, existing solutions (gateways, ingress controllers, service mesh and forward and reverse proxies) are not an adequate response.

    “We believe the solution should hence involve an intermediary (proxy) device focused on solving inter-cluster connectivity, security and integration challenges.” The writers call this solution API Gateway 2.0, which they describe as a bi-directional application-level proxy. The technology exists to implement such middleware and perhaps it could help companies address sprawl issues.

    Outside of Narayanan’s and Wiley’s recommendations, there are plenty of actions API owners can take to avoid adding to the sprawl. Here are a few:

    • Treat the API as a product
    • Improve developer experience
    • Use spec-driven development
    • Ensure up-to-date documentation and code libraries
    • Use consistent endpoint naming
    • Set clear guidelines for versioning and deprecation
    • Go beyond API keys with OAuth and OpenID Connect

    For more context, check out Continual API Sprawl: Challenges and Opportunities in an API Driven Economy for free without an email gate here.

  • ArgoCon ’21: Get More Done with Kubernetes

    ArgoCon ’21: Get More Done with Kubernetes

    Argo is an open source suite of projects that helps DevOps teams deliver software more rapidly and safely. Argo Workflows, Argo CD, Argo Rollouts and Argo Events are open source tools for Kubernetes to run workflows, manage clusters and do GitOps right. On Dec. 8, the Argo community will come together at ArgoCon ’21 Virtual Event to share their Argo journey, some less known details about the project and offer a glimpse into what the future may hold.

    The agenda for ArgoCon ’21 features technical sessions, demos, deep-dives and case studies covering a variety of topics, including:

    • How GitOps workflows relate to DevOps movement and how it paves the way toward a successful DevOps adoption
    • How to use Argo Workflows, Events, CD and Rollouts to create a flexible, customizable developer experience for CI/CD
    • Argo CD production best practices and how to customize your Argo CD setup
    • Building medical grade AI with Argo Workflows
    • Bridging into Python ecosystem with cloud-native distributed ML pipelines
    • How to enable and empower teams to manage their own Argo-based CI/CD pipelines across multiple multi-tenant clusters
    • How scalable is Argo
    • GitOps-ifying your K8s management with Argo CD and Codefresh

    Speakers

    ArgoCon ’21 features outstanding DevOps and GitOps leaders from the Argo community, including:

    • Alex Collins, Argo project lead at Intuit
    • Alexander Matyushentsev, Argo project lead at Intuit
    • Anaïs Urlichs, SRE at Civo
    • Aya Ivtsan, senior computer scientist at Adobe
    • Christian Hernandez, senior principal technical marketing manager at Red Hat
    • Dan Garfield, co-founder and chief open source officer at Codefresh
    • Edgar Magana, senior principal software engineer at Splunk
    • Hannah Seligson, developer advocate at Codefresh
    • Hong Wang, founder and CEO at Akuity
    • Hui Kang, platform engineer at Salesforce
    • Ian McGraw, lead platform engineer at Arthur.ai
    • Jesse Suen, Argo project lead, co-founder and CTO at Akuity
    • J.P. Zivalich, CTO at Pipekit
    • Kelsey Hightower, principal engineer of Google Cloud Platform at Google Cloud
    • Mike Bowen, director open source program office, cloud native engineer at BlackRock
    • Omri Fima, chief architect at Diagnostic Robotics
    • Pratik Wadher, SVP, product development at Intuit
    • Ravi Lachhman, field CTO at Shipa
    • Ryan Umstead, BlackRock
    • Saad Malik, CTO and co-founder at Spectro Cloud
    • Sergio Méndez, DevOps engineer at Yalo
    • Severin Ryberg, senior infrastructure architect at ACCURE Battery Intelligence
    • Siamak Sadeghianfar, product manager at Red Hat
    • Venkata Gunapati, staff software engineer at Intuit
    • Yuan Tang, founding engineer at Akuity

    Giveaways

    There will be six sponsor giveaways at ArgoCon ’21:

    • A mouse pad and wireless charger giveaway by Red Hat
    • A $100 Amazon gift card raffle by Akuity
    • The Kubernetes 2021: Operationalizing for Scale study by Dimensional Research (sponsored by Spectro Cloud) is freely available for download
    • A $200 gift card raffle by Shipa
    • A brand new Quest 2 and Pipekit swag package giveaway
    • 15 Argo Codefresh branded Bluetooth speakers giveaway

    For more information on how to participate on the raffles and giveaways, visit the ArgoCon ’21 website.

    There will also be a virtual exhibit hall to interact with partner sponsors and download information. All attendees will receive a link to access the virtual environment on-demand once the live event is over. To see the full agenda and to register, please visit the ArgoCon ’21 website.

  • 22 Engineering Leaders Weigh in on APIs

    22 Engineering Leaders Weigh in on APIs

    Every business today is a digital business … and if it’s not, it will be soon.

    A recent survey by Deloitte found that digitally mature companies are better able to navigate rapid change and, as a result, perform much better financially.  Nearly two-thirds of survey respondents asserted that organizations that don’t digitize in the next five years will be “doomed.”

    Application programming interfaces (APIs) are the cornerstone of these digital transformation efforts. APIs aren’t just technical conduits that let applications communicate with each other. In a software-driven world, they allow developers to build services more quickly, enable innovation, open up new markets and drive competitive advantage.

    A new State of the API report from Postman, which surveyed 28,000 developers and other tech pros, offers a vivid snapshot of APIs’ central role in modern organizations. It showed that API-fueled innovation has helped companies respond to the pandemic; that the global API ecosystem is growing; that developers are spending more time than ever with APIs and that almost everyone believes investment of time and resources into APIs will increase or stay the same in their organizations for the next 12 months.

    To learn more about APIs’ status in the enterprise, I’ve spent part of 2021 interviewing 22 engineering leaders from various companies for my podcast, Breaking Changes. I wanted to dive deeper into how and why these leaders view APIs as critical to business strategy and hear what lessons they’d share with others.

    Here, in 20 bite-sized chunks, are the recurring themes:

    Business. The greatest value generated from API operations is rarely directly from any single API, but around the partner enablement APIs make possible. Over and over, companies see that building an API ecosystem helps extend their business’s reach and deepens the connection with partners and customers.

    Strategy. Without proper planning, an organization will always be stuck in reactive mode when it comes to the applications that API operations are powering. It’s much better to have a comprehensive API strategy.

    Third-party relationships. Reliance on third-party systems—the vast supply chain of partners and vendors that organizations share data with via cloud-based technology—is exponentially increasing, pushing organizations to develop a more formal and external API strategy.

    Resources. The resources surrounding API operations need to speak to developers, support them and help make their lives easier as they work with a company’s APIs.

    Governance. It’s important to be cautious in automating governance at the pipeline level before developing relationships across teams and a centralized API governance approach is vital, too. API governance is the practice of applying common rules and security policies for APIs. 

    Management. The management of APIs is a continuous journey and not a destination, requiring a significant amount of planning and attention to reach desired objectives.

    Global. We are all increasingly reaching a global audience with APIs, and every organization’s message and resources need to reflect the increasingly diverse audience.

    Multi-Protocol. The future of APIs is multi-protocol, requiring a diverse toolbox of API protocols and patterns to properly grow ecosystems over the next decade.

    Enablement. Companies need to be enabling their API development teams, not governing them; making sure they have what they need to do APIs well while also failing safely.

    Regulations. API regulations are here and are pushing mainstream enterprises to become technology companies, requiring that they have an API strategy for the future.

    Mobile. The world reached a milestone in 2019: There are now more cellphones than people. APIs are how digital resources are made available on these devices in both leading and emerging markets.

    Opinionated. Informed and opinionated approaches to the API life cycle will make a bigger impact than any single technology used in the infrastructure stack.

    Intelligence. There is a massive opportunity in deriving intelligence in aggregate across the millions of API requests we make each day across core business applications.

    Quality. Organizations should prioritize not just testing APIs but testing the API tests themselves. This ensures a level of quality and reliability across all APIs, regardless of the team working with them.

    Education. Ensuring that teams have the proper ongoing training and education around the API life cycle must be a top-line priority across API operations.

    Authentication. The authentication layer of the API infrastructure holds a wealth of intelligence. Having humans study this dimension is critical for security.

    Data. Challenges and opportunities at the API data layer are massive, and machine learning is giving teams an exoskeleton to support failing and iterating faster during development.

    Privacy. Ensuring that privacy is a basic building block of the API life cycle helps developers focus on what they do best, resulting in higher-quality applications that also respect privacy.

    Observability. API analytics have matured in the last few years; becoming much more about observability across the API infrastructure and helping organizations see and respond to what matters.

    Open Source. Open-source technology is an essential part of growing and supporting an API ecosystem, providing both the technical and human nutrients needed to be healthy.

    By keeping these 20 points in mind, organizations can maximize APIs’ role as an extremely powerful mechanism for leveraging data and application functionality for business success. APIs will underpin digital transformation for many years to come, so it’s important to cover all the bases.

  • Sumo Logic Extends Observability Reach to AWS Lambda

    Sumo Logic Extends Observability Reach to AWS Lambda

    At the AWS re:Invent conference this week, Sumo Logic announced that in addition to collecting log data, metrics and traces, it now can collect telemetry data from the Lambda serverless computing service provided by Amazon Web Services (AWS).

    In addition to collecting telemetry data, Sumo Logic also revealed that the Sumo Logic Continuous Intelligence Platform hosted on the AWS cloud can now analyze how functions used on the AWS Lambda service perform during transactions.

    That data can then also be correlated against the performance of other AWS services that Sumo Logic tracks via integrations with the AWS CloudWatch and AWS CloudTrail monitoring services.

    George Gerchow, chief security officer for Sumo Logic, said the company is making extensive use of the OpenTelemetry agent software created under the auspices of the Cloud Native Computing Foundation (CNCF) to make it simpler to instrument IT environments. That data is not only being used to improve application performance but also to surface anomalies indicative of a security breach, he added.

    As part of this ongoing security effort, Sumo Logic this week also added Sumo Logic AWS Quick Start integrations for rapid access to security and compliance insights along with support for Amazon Inspector, a vulnerability management service provided by AWS.

    AWS this week named Sumo Logic as its independent software vendor (ISV) partner of the year. The two companies have a longstanding relationship that began with Sumo Logic’s decision more than 10 years ago to build a monitoring platform hosted on the AWS cloud.

    As IT monitoring tools continue to evolve into observability platforms, Gerchow said it’s becoming much easier to leverage machine learning algorithms and open source agent software to identify the root cause of an issue before it results in a major disruption.

    Most IT teams today are still relying on legacy monitoring tools that only tack a set of predefined metrics to identify when a specific platform or application is performing within expectations. The metrics tracked generally focus on, for example, resource utilization. In contrast, observability combines metrics, logs and traces—a specialized form of logging—to instrument applications in a way that makes it simpler to troubleshoot issues.

    Observability, of course, in one form or another, has always been a core tenet of DevOps best practices. Initially, DevOps teams focused on continuous monitoring as the most effective way to proactively manage application environments. However, it can still take days (and sometimes weeks) to discover the root cause of an issue. Observability platforms promise to make it easier to manage IT environments even as the overall complexity of those environments continues to increase.

    It’s not clear at what rate IT organizations will be transitioning to observability platforms. However, it generally takes only one major outage before IT organizations start looking for better tools to manage their IT environment. As those IT environments become more complex, the probability that there will be a significant disruption is now higher than it’s ever been. The challenge and the opportunity is to find a way to instrument applications more widely; the expectation being that an observability platform will be able to analyze telemetry data to reduce the number of issues that lead to service disruptions.