Category: Features

  • Key Findings From the 2022 State of GraphQL Report

    Key Findings From the 2022 State of GraphQL Report

    GraphQL, the open source query language, has been steadily growing in popularity over the past few years. The language is excellent for frontend development, as it creates a usable interface to fetch precisely the data required for the specific client at hand. You can also use it to aggregate multiple backend services and data sources.

    Studies show that the ecosystem around GraphQL is maturing—it has a very global user base and a growing number of tools exist to aid in its adoption. The 2022 State of GraphQL Report found that 61.8% of developers are happy with the overall state of the ecosystem. Yet many native GraphQL features go unused by developers, which suggests there is a wide range of experience levels, from novice to advanced users, working with the technology. This indicates there is plenty of room for growth and knowledge sharing.

    Below, I’ll review the key takeaways from the 2022 State of GraphQL Report, considering overall usage data and focusing on the popularity of specific features. We’ll also highlight the state of standard tools used in conjunction with GraphQL to get the job done.

    Analyzing Overall Usage Statistics

    First off, there is a wide variance in the types of GraphQL APIs in production today, ranging from private to public endpoints. The report found 47.9% of developers use GraphQL for exposing an API intended for a personal website or app, 40.4% use it for private unexposed APIs for internal usage and 19.5% use GraphQL for publicly available APIs intended for third-party developer consumption. This demonstrates its flexibility to cater to multiple scenarios. And while the majority of clients that connect to GraphQL APIs include browsers (62.3%), it’s commonly consumed by other client types such as native mobile apps, other servers and desktop apps.

    Previously, we discussed using GraphQL as a composition layer to combine underlying APIs and services. And the report backs up this idea that developers commonly use it to aggregate various data sources: 55.4% of GraphQL APIs hit databases, while 35% consume REST APIs and 14.6% eat other GraphQL endpoints.

    In terms of benefits, one strong point is the ability to enforce and validate types for every object in the API. Users find other top benefits to be avoiding overfetching and aggregating requests. Yet, some hurdles still present themselves. These top drawbacks include error handling, performance issues, client-side caching and security woes.

    Regarding user base statistics, most users have been working with GraphQL for less than five years. If we look at the type of sector utilizing GraphQL, we see it primarily leveraged in the programming and technology sector. This is followed by e-commerce and retail (16.4%), finance (8.9%) and news, media and blogging (7.2%).

    Many Advanced Features Go Unused

    Many of the more advanced GraphQL features still go unnoticed by the majority of users. For example, live queries is a feature that helps obtain live data from a GraphQL server, yet only 25% who know about it have used it. Over half of respondents had never heard of @skip, a directive that skips a field based on a value passed to it. Similarly, other directives like @specifiedBy, @defer and @stream also share little-to-no awareness or use.

    Analyzing feature usage becomes a bit more serious if we consider the unadopted security and performance features. For example, only 43.2% of respondents have disabled query introspection. Disabling query introspection is a suggested security best practice to limit a hacker’s ability to perform surveillance. But as we’ve previously covered, security by obscurity isn’t enough to protect GraphQL, and an additional security emphasis is often needed.

    As most GraphQL APIs are intended for personal or private scenarios, you would think that more security features would be leveraged to limit the threat of introspection and denial-of-service attacks. Yet, the report discovered low usage and awareness of security and performance features like query timeouts, query rate limiting and query cost analysis, all of which could be turned on to curb malicious behaviors.

    Tools Used In Conjunction With GraphQL

    Developers often seek to combine, aggregate or merge GraphQL schemas from different APIs. To do so, Apollo Federation is the most common solution, used by 22.5% of respondents. This is followed by Schema Stitching (16.9%), GraphQL Modules (4.4%), and GraphQL Mesh (2.9%).

    Looking at other technologies used in connection, Next.js is the most popular framework and PostgreSQL is the most common database used. TypeScript and JavaScript comprise the most common languages used to write a GraphQL backend. Developers also use a balanced mix of IDEs to query and test endpoints, including GraphiQL, GraphQL Playground, Postman, Apollo Studio, and Insomnia.

    The report also found relatively high usage and retention for tools like the GraphQL Code Generator schema builder, Apollo Client and Apollo Server. The data shows a crowded solution market with Apollo as an industry-leading outlier—many other clients, servers, API generators and schema builders have medium-to-high retention rates yet experience far less use.

    Final Thoughts

    The 2022 State of GraphQL Report sheds some interesting light on the state of GraphQL, validating a lot of the interest and trends we’ve covered lately on the blog. Of course, there is more to be said about many areas, such as smoothing the transition to GraphQL.

    One key finding is the low number of security features being leveraged by developers. A greater emphasis on API security is required to avoid incidents and retain a zero-trust approach. This emphasis is part and parcel of responding to ongoing software supply chain threats and will require more awareness and thought leadership around GraphQL security best practices.

    The 2022 State of GraphQL survey ran from June 15, 2022, to July 15, 2022, and collected 3,094 responses. The above analysis only scratched the surface and there are many other insights. For more findings, you can read the full results here.

  • GitLab Unfurls Dedicated SaaS Edition in the Cloud

    GitLab Unfurls Dedicated SaaS Edition in the Cloud

    GitLab today made available to a limited number of customers a single-tenant version of the software-as-a-service (SaaS) edition of its continuous integration/continuous delivery (CI/CD) platform.

    David DeSanto, vice president of product at GitLab, said the GitLab Dedicated option provides all the benefits of a cloud platform without running afoul of any potential compliance issues.

    Designed to be deployed on a cloud platform selected by the customer, DeSanto said the single-tenant edition of the platform makes sure that all the data stored in the cloud is isolated. In addition, the access to GitLab Dedicated is provided via a private network connection, he added.

    Initially, GitLab Dedicated is being made available on the Amazon Web Services (AWS) cloud with support for other cloud platforms planned for 2023 once it becomes generally available.

    GitLab is, in effect, trying to strike a balance between a lower-cost multitenant edition of the platform or, alternatively, requiring organizations to deploy an on-premises edition of the platform themselves, DeSanto said.

    In general, GitLab expects this latest version of the platform to appeal most to organizations that operate in highly regulated industries. However, the number of organizations looking to isolate their data in a private cloud to better protect their software supply chains is expanding, he noted.

    In the wake of a series of high-profile breaches and vulnerability disclosures, the number of organizations that are reviewing their software supply chains has increased. Less clear is the degree to which organizations will look to lock down their existing CI/CD platform versus replacing it with a more secure modern alternative that can be more easily accessed via the cloud.

    The challenge, of course, is replacing a CI/CD environment is not trivial, so organizations will need to consider the time and effort made over the years to customize their CI/CD environment. In some instances, that customization provides a meaningful competitive advantage. In other cases, however, the weight of maintaining all those customizations has become more troublesome than it’s worth.

    Each individual organization will need to decide to what degree they will want to manage the DevOps platforms used to construct applications. More organizations are deciding they prefer to devote as much of their resources as possible to writing code instead of managing the underlying CI/CD platform used to create their applications, said DeSanto.

    Regardless of approach, the number of organizations adopting DevOps best practices to build and deploy applications faster continues to increase. A CI/CD platform accessed via the cloud lowers the barrier to entry for smaller organizations that typically don’t have the skills and resources required to manage DevOps platforms.

    In the meantime, SaaS-based approaches should significantly increase the number of applications being constructed using DevOps workflows. The level of DevOps adoption will naturally vary by organization. However, the total number of custom applications being used to drive, for example, digital business transformation initiatives should considerably expand in the months and years ahead as more applications are built and deployed at incredible speed.

  • Datadog Dives Into Universal Service Monitoring

    Datadog Dives Into Universal Service Monitoring

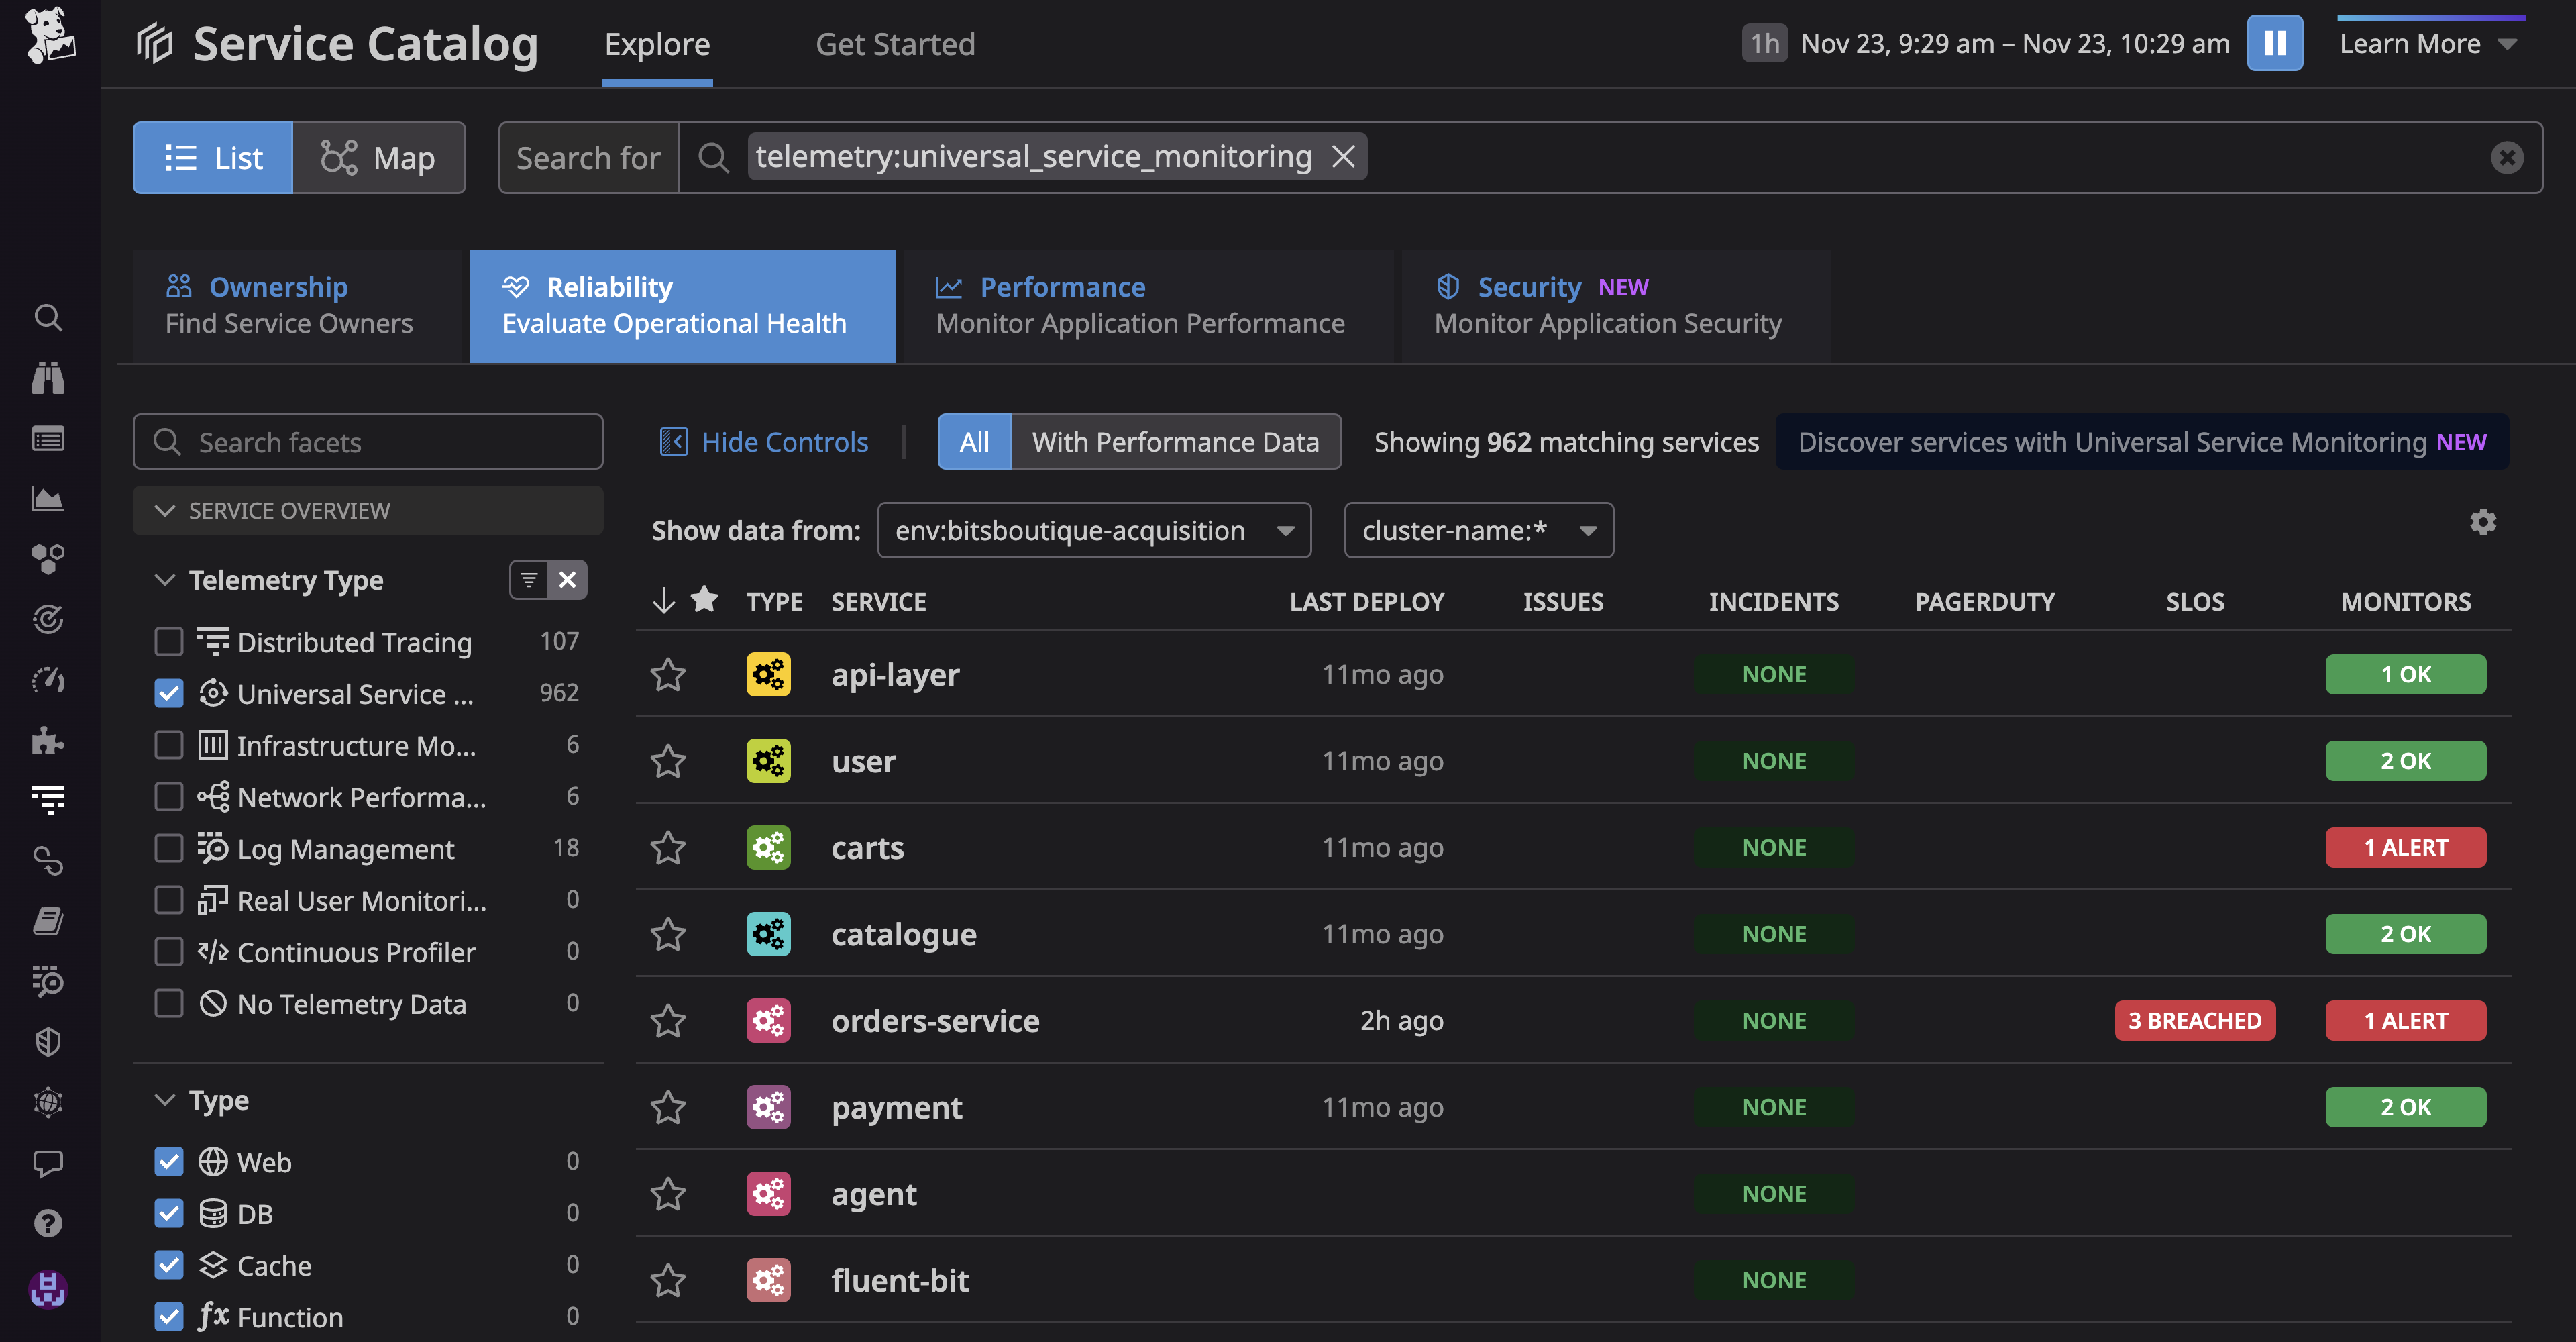
    Datadog, Inc. today made generally available a Universal Service Monitoring service that takes advantage of the extended Berkeley Packet Filtering (eBPF) microkernel in a Linux operating system to automatically detect all the services that make up an application environment without changes to the code used to construct them.

    Yrieix Garnier, vice president of product at Datadog, said as application environments continue to evolve IT teams are now trying to track not just individual microservices but also entire business processes such as order-to-cash. Before those services can be instrumented, however, DevOps teams need a simple way to discover them, he noted.

    Within the Linux operating system, eBPF makes it possible to employ a sandbox environment to identify and map the services that make up an application environment, including both internally developed and third-party services regardless of what programming languages were used to build them, added Garnier.

    DevOps teams also gain visibility into the health of every service and deployment through real-time request rate, error and duration (RED) metrics and correlated infrastructure metrics and application logs. They can then expand monitoring capabilities provided via Datadog agent software to employ distributed traces that can be correlated with observability data.

    The Datadog Universal Service Monitoring service is also integrated with the Service Catalog that Datadog makes available to determine which development team created a specific service.

    The goal is to close a visibility gap that has emerged as more IT organizations align their management efforts around specific application services in the age of digital transformation rather than the components that make up a service, noted Garnier.

    DevOps teams today are simultaneously being tasked with diving deeper into application environments to discover issues before services are disrupted and also tracking the services that span multiple application components. Collectively, the expectation is that DevOps teams will be able to ensure that application services are not just available but also consistently delivered. Ultimately, IT organizations are being tasked with removing much of the guesswork that has historically characterized the management of IT.

    Less clear is how much those shifts will ultimately drive the reorganization of IT teams that are still mostly organized around the platforms they support versus the services being delivered. However, as business leaders increasingly appreciate how dependent the overall organization is on application services, the need to manage them in a more comprehensive manner becomes apparent.

    In the meantime, DevOps teams are evaluating whether their existing tools and platforms enable them to accomplish that goal. Datadog is making a case for employing a service it manages on behalf of DevOps teams versus each DevOps team having to construct and maintain its own observability platform. Datadog, most recently, extended the reach of its namesake cloud-delivered monitoring and observability platform to address continuous testing, application security and cost management.

    It will be up to each organization to decide how best to achieve their observability goals. One thing that is certain is the current level of visibility they have into application environments is not nearly sufficient.

  • Logz.io Unveils Managed Open 360 Observability Platform

    Logz.io Unveils Managed Open 360 Observability Platform

    At the AWS re:Invent 2022 conference, Logz.io launched an Open 360 platform that combines multiple open source technologies to provide observability across both existing monolithic and emerging cloud-native application environments.

    Existing Logz.io offerings included in the Open 360 platform are Logz.io Kubernetes 360, a managed observability platform based on open source tools such as OpenSearch analytics software, Prometheus monitoring tools and Jaeger distributed tracing agents.

    In addition, Open 360 includes Logz.io Telemetry Collector agent software, Logz.io Data Optimization Hub dashboard, Logz.io LogMetrics Index for converting log data into metrics and the Logz.io Trace Sampling Wizard tool for configuring open source OpenTelemetry Collector agent software.

    Logz.io CEO Tomer Levy said rather than requiring organizations to combine a set of disjointed open software tools to create an observability platform, instances of open source tools have been curated by Logz.io. The goal is to streamline the number of tools and platforms that DevOps teams will need to observe multiple classes of applications, he noted.

    It’s still early days as far as the adoption of observability platforms is concerned, but it’s apparent that as application environments become more complex the monitoring tools DevOps teams rely on today will need to evolve. Observability platforms, in general, promise to unify logs, metrics and traces in a way that makes it simpler to launch queries to identify the root cause of an issue rather than simply tracking a set of pre-defined metrics.

    The rate at which DevOps teams will embrace observability will naturally vary, but the choice many DevOps teams are trying to navigate is how much to rely on proprietary observability platforms rather than using open source software to construct their own. Logz.io is making a case for finding a middle ground between those two extremes by relying on a managed service based on open source tools.

    Observability has always been a core DevOps tenet, but achieving and maintaining it is challenging. Most DevOps teams today aspire to maintain some level of continuous monitoring. However, as it becomes easier and less costly to instrument applications, interest is rising in observability platforms that simplify the investigation of anomalies indicative of an issue that could disrupt a distributed application environment.

    More challenging still, DevOps teams are also now managing a much wider range of application types as cloud-native applications based on microservices deployed on Kubernetes clusters are deployed alongside legacy monolithic applications running in the cloud and on-premises IT environments. The Logz.io approach enables DevOps teams to manage those applications at a lower total cost, noted Levy.

    Regardless of the approach to observability, the increasing complexity of application environments has become a major challenge for organizations that are increasingly sensitive to costs. Many of them can’t afford to hire additional DevOps engineers. Instead, the focus is on increasing the productivity of existing DevOps teams using a new generation of observability platforms that should cost less to acquire and deploy than to expand existing teams of DevOps engineers. That may not necessarily eliminate the need to hire additional DevOps engineers, but it should ensure organizations are getting the most out of the DevOps teams they already have.

  • Zilliz Unfurls Managed Vector Database Service

    Zilliz Unfurls Managed Vector Database Service

    Zilliz this week made generally available a managed cloud service that can now be spun up in less than five minutes. The service is based on the company’s open source Milvus vector database.

    Frank Liu, director of operations for Zilliz, said the managed Zilliz Cloud service running on the Amazon Web Services (AWS) cloud will make vector databases much more accessible to a wider range of application developers.

    Vector databases are gaining traction because they provide artificial intelligence (AI) application developers with a more efficient method for managing the unstructured data need to train AI models. Currently, many of those teams are relying on labels and tags to classify and manage data. The Milvus vector database employs deep learning algorithms and its own AI model to create and store, index and manage vectors to more efficiently classify data, said Liu.

    Based on a cloud-native architecture that, for example, employs Kubernetes to scale consumption of cloud resources more efficiently, Zilliz Cloud can also scale to process tens of billions of high-dimensional vector data for data-intensive applications, he added. The company claims Zilliz Cloud delivers up to 10 times greater throughput and five times lower latency for read and write operations for data-intensive workloads.

    Other attributes of the managed Zilliz Cloud include support for multi-language software development kits (SDKs), a web-based graphical user interface to search and explore data, SOC 2 compliance, network isolation using IP whitelists and full data encryption in transit (TLS).

    In the future, Zilliz also plans to add support for Microsoft Azure Cloud and Google Cloud Platform in addition to graphical processor units (GPUs) to optimize the performance of its deep learning algorithms.

    Potential use cases for a vector database span everything from image retrieval and video analysis to fraud detection to drug discovery. Organizations that already use Milvus, which is being advanced under the auspices of the LF AI & Data Foundation, include eBay, Shopee and SmartNews.

    In general, the rise of data-intensive workloads is driving more organizations to embrace DataOps best practices to optimize the management of massive amounts of data. Organizations that build AI models are typically at the forefront of those efforts given the massive amounts of data typically required to train AI models. The challenge organizations have historically faced is not many have the internal expertise required to manage a vector database. The Zilliz Cloud eliminates the requirement by relying on the expertise of a team of database administrators trained by Zilliz to operate a managed service.

    It’s not clear at what rate organizations are embracing vector databases to build AI models. As the next era of applications are constructed, it’s only a matter of time before the machine learning operations (MLOps) practices used to build AI models converge with DevOps practices used to build the applications in which those models will be embedded. The challenge is the data science teams that build AI models tend to also have a distinct DataOps culture all their own; DevOps teams will need to find a way to embrace and extend that.

    In the meantime, the number of types of databases being used to build applications will only continue to expand so it will be up to each DevOps team to know when to manage each one themselves versus relying on a managed service.

  • Five Great DevOps Job Opportunities

    Five Great DevOps Job Opportunities

    DevOps.com is now providing a weekly DevOps jobs report to highlight opportunities for DevOps professionals as part of an effort to better serve our audience.

    Our goal in these challenging economic times is to make it easier for DevOps professionals to advance their careers.

    Of course, the pool of available DevOps talent is still relatively constrained, so when one DevOps professional takes on a new role it tends to create an opportunity for others.

    The five job postings shared this week are selected based on the company looking to hire, the vertical industry segment and, naturally, the pay scale being offered.

    We’re also committed to providing additional insights into the state of the DevOps job market. In the meantime, for your consideration:

    LinkedIn

    Major League Baseball
    New York City
    Senior DevOps Engineer
    $150,000 to $190,000

    SimplyHired

    Coca-Cola
    Atlanta
    Product Lead Data DevOps
    $110,000 to $160,000

    ZipRecruiter

    Sierra Nevada Corp.
    Englewood, Col.
    DevOps Engineer II
    $104,827 to $144,138

    Indeed.com

    Paramount
    New York City
    Azure DevOps Engineer
    $90,000 to $105,000

    Dice.com

    North American Bancard
    Remote
    Google Cloud Platform DevOps Engineer
    $80,000 to $120,000

  • VMware Brings Java 17 Support to Spring Boot Framework

    VMware Brings Java 17 Support to Spring Boot Framework

    VMware this week made a Spring Boot 3.0 update for building microservices-based Java applications that is based on the latest long-term support release for the Java Standard Edition (SE) platform.

    Michael Minella, senior director of software engineering at VMware, said the latest edition of the framework supports Java 17. The hope is that adding this support will encourage organizations to move from Java 8 to the latest long-term release of the platform without requiring multiple upgrades to other previously released editions of Java SE.

    In addition, Spring Boot 3.0 now also natively supports a high-performance Java development kit (JDK) known as GraalVM along with version 6.0 of the Spring framework for building Java applications using OpenJDK, an open source version of Java SE that VMware made available earlier this month.

    VMware added support for Micrometer and Micrometer Tracing to improve the observability of Spring applications that will increasingly include multiple microservices dependencies.

    Finally, VMware also added support for Jakarta Enterprise Edition (EE) 10, an open source extension of Java SE that is being advanced under the auspices of the Eclipse Foundation.

    Minella said support for Java 17 coupled with GraalVM provides a stable foundation for building Java applications that are significantly faster than applications that rely on Java 8—still the most widely used edition of the platform. DevOps teams should begin to adopt a new standard for building and deploying the Java applications that still dominate enterprise IT environments, Minella said.

    There is, of course, no shortage of programming languages being used to build enterprise applications. After three decades, however, Java continues to dominate, in large part because of the sheer number of developers that have Java programming skills.

    It’s less clear how quickly legacy Java applications will be updated to run on Java 17 and the GraalVM. Now that Java 17 is supported in Spring Boot—the most widely used framework for building Java applications—the pace of adoption for the latest long-term release of the Java SE platform should accelerate in 2023.

    In addition, Minella noted the latest edition of the Spring framework will put organizations in a better position to take advantage of forthcoming advances such as Project Loom, an OpenJDK effort to replace threads with a lighter-weight concurrency model based on fibers that are managed via the Java runtime rather than the underlying operating system.

    Collectively, these and other technologies will make it less expensive to run Java applications that are significantly faster than previous generations of applications, he added.

    Most DevOps teams will find themselves managing a mix of Java applications—constructed using multiple variants of the core Java SE platform—for many years to come. However, it’s probable most new Java applications will be based on Java 17. In addition, there will be efforts to modernize legacy applications based on previous iterations of Java SE. As a result, most DevOps teams working in enterprise IT environments should expect to see an increase in the overall number of Java-based projects using microservices moving through their pipelines in the months ahead.

  • Rezilion Adds Windows Support to Dynamic SBOM Tool

    Rezilion Adds Windows Support to Dynamic SBOM Tool

    Rezilion has added support for Windows applications to its tool for dynamically generating software bills of materials (SBOMs).

    Rezilion CEO Liran Tancman said in addition to existing support for Linux applications, it’s now possible to analyze all the components that make up a Windows application runtime environment in real-time.

    That capability also makes it possible to search for and pinpoint the location of components, such as the Log4j vulnerability, across millions of files and on thousands of hosts, containers and applications, he added.

    Rezilion has created a searchable proprietary next-generation vulnerability database (NGVDB) that identifies which issues impact specific classes and functions. In addition to surfacing remediation suggestions, the capability also reduced the number of false positives that IT teams would otherwise have to track down.

    The SBOM tool the company provides builds on that capability to provide insights into the complete attack surface of an application that could be exploited by cybercriminals.

    In general, the components of a Windows application are more challenging to track and analyze because of the many different frameworks created to build them over the last few decades. However, with more than half of all applications running on Windows, the need to create SBOMs for those applications has become a more pressing concern, especially in the wake of an executive order issued by the Biden administration that requires federal agencies to provide SBOMs for every application they use.

    It’s not clear how many enterprise IT organizations will be following suit, but the general expectation is that SBOMs will soon be a lot more prevalent than they have been. In the wake of a series of high-profile cybersecurity breaches, there is now more scrutiny of software supply chains than ever.

    The challenge, of course, is determining which vulnerabilities to remediate first once they are identified in an application. There are simply too many vulnerabilities to patch all at once, so DevOps teams need to be able to identify which vulnerabilities are the most severe. For years, cybersecurity teams have been creating spreadsheets filled with long lists of vulnerabilities, but there is usually no context provided in terms of how severe a vulnerability is. As a result, developers would allocate a small portion of their time to applying patches that are prioritized based on intuition and level of complexity rather than severity.

    It may still be a while before most organizations that build software are able to consistently create accurate SBOMs. It may be even longer before the organizations that consume those SBOMs have the processes in place to operationalize them. In theory, an organization, if necessary, should be able to prevent software from being deployed based on the list of components included in the SBOM. However, that decision is not always straightforward. There is usually a range of reasons for including a potentially vulnerable component in an application that needs to be considered.

    One way or another, the overall security of applications is about to steadily improve. The only issue is how much pain will need to be experienced to achieve that goal.

  • A DevOps Thanksgiving: What Are You Thankful For?

    A DevOps Thanksgiving: What Are You Thankful For?

    As crazy as it seems, here we are on the cusp of another Thanksgiving. This year has gone by so quickly, and as we enter the holiday season and the end of 2022, those of us in the DevOps community have much to be thankful for. First and foremost, I’m so happy to once again see my colleagues and friends in-person at conferences and events around the world. I’m looking forward to resuming travel not just in the U.S. but the rest of the world and seeing DevOps enthusiasts share their knowledge, their experiences and further the state of DevOps.

    While we are thankful for the resumption of a more normal lifestyle, we also need to pause to acknowledge and mourn for those we’ve lost during this terrible pandemic. Their lives and the time taken from all of us during these past years can never be replaced.

    They say every dark cloud has a silver lining; if there was a silver lining for DevOps during the COVID-19 pandemic, it was the unprecedented pace of digital transformation. Make no mistake—digital transformation is powered by software development and DevOps powers software development. It wasn’t just the sheer number of applications or lines of code that were developed and deployed during these past few years, but the accelerated maturity of software supply chain software pipelines that became the de facto standard for how software is developed and deployed; that was greatly accelerated as a result of the push to digital transformation.

    It was not just software development that was accelerated, software supply chain attacks gave rise to an entirely new subset of security. Software supply chain security and SBOMs are now everyday words in the security lexicon. While I’m not happy about an entirely new class of attacks, I’m grateful for the response the White House and the U.S. government gave to our industry as a whole to address software supply chain attacks. I’m also grateful for the continued evolution of tools and techniques, people and processes around DevOps.

    While some look to make marketing hay by proclaiming that DevOps is dead and other such nonsense, the truth is that DevOps is thriving. It is the way software is developed today. In fact, in conjunction with cloud-native, it would seem that we have a whole new stack and an entirely new way that software is created.

    Looking forward, on the horizon we continue to see the development of AI that is making a real impact on observability, testing and application management. I think we’re also on the verge of AI having a profound impact on software development, as well. Low-code/no-code development tools paired with AI promise to take some of the most mundane software development tasks and automate them. This will free up overworked software developers to focus on higher-value software development tasks.

    Despite macroeconomic conditions putting a damper on the entire tech space (if not the entire world economy), I remain enthusiastically bullish about the continued growth and maturation of DevOps and I am excited to see what the weeks, months and years ahead bring. I am grateful to be involved in our industry during these heady times, and I’m grateful to you, our readers, supporters and the community for your continued support of our company.

    To that end, I wanted to announce that we’re trying something new this year at Techstrong Group, and we hope you’ll join us. We want to know what you believe makes tech strong—and we’re asking people to record a quick TikTok video or LinkedIn video with the hashtag #Techstrong. We’ll select the winners and are giving away two (2) Sony PlayStation5 game consoles to the best two entries as selected by our judges. You can get all the details on our social media channels on Twitter, Facebook and LinkedIn.

    So, now you know what I’m grateful for—we really want to hear what you’re grateful for and what you think makes tech strong! Throughout the holidays and the new year, we wish you health and happiness—and know that tech will remain strong!

  • CircleCI Will Use AI to Increase Collective DevOps Intelligence

    CircleCI Will Use AI to Increase Collective DevOps Intelligence

    CircleCI has committed to adding additional collective intelligence capabilities to its continuous integration/continuous delivery (CI/CD) platform that will leverage machine learning and other forms of artificial intelligence (AI) to optimize application development and delivery.

    CircleCI CEO Jim Rose said that as the company’s namesake CI/CD platform continues to collect more telemetry data from multiple customers, it becomes feasible to create AI models that will optimize everything from application testing to reliability and performance.

    As part of that strategy, CircleCI has also added capabilities such as test splitting recommendations that employ machine learning algorithms to estimate the expected time savings of enabling parallelism on test jobs.

    In addition, CircleCI is creating a team of analysts and data scientists to develop additional AI capabilities based on the data collected via the cloud version of the company’s platform.

    The decision to invest more in developing AI capabilities follows the acquisition of Ponicode, a provider of a unit testing platform, earlier this year. That platform uses AI to augment application testers by providing capabilities such as syntax validation, on-hover hints and autocompletion capabilities to improve the accuracy of software developed using Visual Studio Code. The goal is to integrate that AI testing technology within the CircleCI platform to make it possible to apply algorithms to individual developers’ code as well as to code aggregated from multiple developers within a build as it is continuously updated across a DevOps workflow.

    The workflows make up a software supply chain that, in many regards, functions like any other type of supply chain, noted Rose. As such, there is plenty of opportunity to apply AI models to optimize those workflows in the same way AI is being applied to optimize other types of supply chains, he added.

    It’s still early days as far as applying AI to DevOps processes is concerned, but it’s clear there is a need to further automate a wide range of manual processes. It’s not likely that AI is going to replace the need for DevOps engineers any time soon, but it will reduce a lot of the toil that currently hinders productivity. The challenge, of course, is that it takes a lot of telemetry data to train an AI model, which typically can only be efficiently gathered and stored with a cloud platform. Less clear is whether AI capabilities might drive more organizations to shift away from legacy CI/CD platforms deployed in an on-premises IT environment where there might not be enough telemetry data available to effectively train an AI model.

    The one thing that is certain is there is now a race to apply AI to DevOps workflows. Organizations that have adopted DevOps typically are highly committed to automation, but the amount of AI applied to those workflows has been limited thus far. In the coming year, however, chances are good the amount of AI being applied to DevOps workflows will steadily increase, especially as many DevOps teams struggle to keep pace with complex application environments.