Category: Blogs

  • 3 Prerequisites before Jumping on the DevOps Bandwagon

    3 Prerequisites before Jumping on the DevOps Bandwagon

    Top Three Prerequisites before Jumping on the DevOps Bandwagon

    The DevOps frenzy is truly upon us and organizations are under increasing pressure to jump on the bandwagon in order to deliver software faster and faster. However, Agile delivery and DevOps is not a plug-and-play proposition – it requires time, effort and persistence. Also most enterprises, unlike Silicon Valley startups often held out as shining examples, don’t always have the luxury of dealing with newly designed software and freshly minted teams. Implementing DevOps practices is a significant change and often an uncomfortable process for many enterprises. Let me share what I believe are the top pre-requisites that must be in place to ensure success.

    Organizational Commitment

    This may seem obvious, but ensuring alignment and setting the right expectations on the goals and path to DevOps nirvana is a first and important step. Organizational structures, support at a senior level, a clear but flexible roadmap and adoption of common objectives are key concepts to drive organization commitment to this transformation. Let me elaborate on these a bit.

    Overcoming cultural differences between Dev and Ops organizations is essential – and often enterprises create a new “DevOps” organization with personnel drawn from both organizations chartered with instrumenting the handoff from Dev through to production rollout. This new centralized org, however, also runs the risk of becoming yet another silo. Ideally a DevOps group should operate as a center of excellence managing the tools required across the lifecycle and guiding/overseeing the right methodology within the Dev and Ops teams. Similar to the way Agile development practices have driven testing and quality assurance methods deeper into the dev cycle, DevOps methodology demands that configuration and deployment requirements in a true production environment be considered and tested as part of the design and development cycle. On the Ops front, this new methodology demands a shift from managing risk by limiting change towards enabling change while reducing risk by automating repeatable steps for deploying small packets of changes often.

    While DevOps initiatives are typically sponsored by high ranking IT executives, it is essential that senior and mid-level leadership in the Dev and Ops organizations completely support and prioritize the changes that, while benefiting the overall goal of shipping software faster and better, may in the short term seem to impact narrow departmental goals. Continued visibility and focus from management, and joint ownership by Dev and Ops leaders goes a long a way in ensuring the teams stay aligned.

    A clear and well-articulated vision and compelling reason for change communicated clearly through the organization is essential for execution. This must be accompanied by a phased roadmap that enables short-term wins and clear milestones. Besides benefiting the business, the aim is to make the jobs of Ops and Dev personnel easier. Transparent and frequent communication on progress against the roadmap and its impact is key.

    In order to keep the momentum avoid getting bogged down in a particular step in the roadmap, especially early in the process. Most enterprises present target rich environments and a flexible roadmap focused on ensuring demonstrable rapid progress will ensure continuing focus and commitment.

    DevOps relies on a sense of shared responsibility and mutual respect between Dev, Ops and the business. Organizations can encourage and engender this by instituting joint ownership for a common set of objectives that encompass both ‘change velocity’ metrics and ‘quality of service’ metrics.

    Automation with discipline

    DevOps relies on the “automate everything” mantra. However, its important to realize that automation does not simply mean speeding things up because machines are faster than people. Automation is a means to codify repeatable practices and steps to ensure speed with reliability.

    Automating poor practices can actually be counter-productive and hence it is first necessary that the various steps and procedures in the delivery process be rationalized, optimized and made consistent.

    The key to improving velocity is to minimize variability in the process of deployment through the path to production. It’s therefore important to automate the complete configuration and deployment process in the lower environments (dev, test) first, and then clearly track and minimize changes to these in higher environments (stage, production).

    In addition to speeding things up, automation can also serve as a powerful way to ensure adherence to process, and done right can substantially help compliance and audits by ensuring change is made quickly yet consistently and is inherently documented without overhead. It is also important that automation of both the rollout as well as verification go hand in hand.

    Tools and infrastructure

    Easy to adopt tools in a frictionless infrastructure is a critical component of DevOps. Rather than locking in a toolset up front, its important to have to have flexibility as the organization evolves its practices and the tools that enable them. Open source tools are well suited to this. They incorporate new innovation faster, provide the ability to tailor them to meet specific needs, and developers can leverage the community that typically exists around these for best practices and knowhow.

    It is also a good idea to optimize and fine tune the tool chain for the project or program that is the initial focus. Once a degree of repeatable success has been established, and the team has acquired proficiency, the tool chain can be scaled out to more broadly. It’s always harder to adopt a new tool chain, especially when coupled with a change in behavior and approach, if the scope of it is too wide initially. As discussed earlier, establishing a DevOps center of excellence team that owns and evolves the tool chain and its usage is often a good practice for enterprises.

    Summary

    As more enterprises rely on software to drive revenue, the pressure is on to innovate and deliver value faster. While this is indeed exciting, it requires a significant undertaking in rolling out cultural, organizational and methodology changes needed to enable DevOps practices. Ensuring clear alignment and goals for all stakeholders, a common sense of purpose and an achievable yet ambitious roadmap are key to securing organizational commitment for this endeavor. Approaching automation in a complete way and enabling the adoption of the right tool chain can set enterprises on the right path to realize benefits of small, frequent deployments without compromising quality of service and compliance.


    About the Author

    KartikRaghavan

    Kartik Raghavan is the Senior Vice President of World-wide Engineering, Operations and Support at CollabNet where he brings deep experience in ideating, defining, developing and launching products through On Premise and SaaS channels.

  • Time-Sharing to Unicorns: The DevOps Problem Facing Enterprise IT

    Time-Sharing to Unicorns: The DevOps Problem Facing Enterprise IT

    How did we in Enterprise IT get to this point? There’s a lot of talking and writing about the value of adopting DevOps but very little analyzing the problem domain we’re trying to correct. There are some schools that will say we can move forward without looking back, but I believe a key element of the dysfunction that faces many enterprise IT organizations can directly be attributed to their history and how they were formed.

    One of the clear lessons we can learn from businesses that we call “unicorns”–termed this because of their mythical capabilities as an IT organization that can deliver high quality software very quickly–is that they have very little friction in the process from ideation to operation. Startups and greenfield initiatives are practically operating in a vacuum relative to the amount of friction they encounter compared to operations around entrenched decade-old legacy mission-critical applications. In retrospect, this should not be surprising given frictionless delivery is a mandate for many of these efforts and has been from the start.

    You create what you focus on!

    Some will say we don’t require the capability to deliver to production ten times a day (or even a year) for our SAP Enterprise Resource Planning (ERP) system. So they will conclude that perhaps DevOps isn’t right for our needs. This shows the skewed thinking that current literature on DevOps is fostering. It is not the need to deploy changes quickly into production that is at issue, but the ability to deliver business capabilities when they are required as quickly and with little impact as possible. Current processes around changes to the ERP are usually so fraught with friction that when the time comes to fulfill a need for the business so that the business can continue to compete effectively, it takes weeks or months instead of days or hours.

    I researched how the division between development and operations was formed and interestingly, there’s very little history about this division of work. We can trace this division back to the early days of time-sharing systems in which the division of work actually represented the exact advice DevOps prescribes today. Deliver and operate a platform on which developers can build and deliver their applications. In the days of time-sharing systems, operations was not responsible for what developers put into the box, just ensuring that the box was available, secure, and backed up. If developers applications had bugs or crashed, it was the developers that were responsible for repair.

    Then came the era of client/server. Application pieces ended up distributed across application infrastructure like a kid that dumped their Legos all over the floor. Managing these applications became as painful as stepping barefoot on a Lego as well. Developers didn’t work on the complete application, but instead worked on modules and these modules were split across various services each requiring their own levels of expertise to keep running in an optimal manner. The DBA was responsible for ensuring the database could meet transactional requirements and support data design and management, the network professionals dealt with protocols and traffic issues caused by these modules communicating with one another. Each layer of the application had it’s own capacity management and operational concerns. The only chance we had to keep the ship from sinking was to put it all in the hands of the one team that had access to all the components — IT Operations.

    Things have not progressed much since this divergence away from time-sharing to client/server either. Today’s applications are more complex and more distributed than ever before. We have clusters of the same server working in unison to handle scalability exponentially increasing the complexity and difficulty for operations. A single application may now require anywhere from 5 to 25 servers to deliver the required capacity.

    On top of all this we’ve never modified the division of work from the days of time-sharing and continue to push the burden for monitoring and uptime to the operations staff. We have turned IT operations into the Jigsawyer’s–someone who does jigsaw puzzles–and developers into the puzzle makers. Moreover, the puzzle is never the same; the puzzle makers change the picture all the time as they add new piece forcing the Jigsawyers to figure out how to retrofit the new piece into the whole.

    While researching the history of IT operations and trying to figure out the path from computing’s earliest organization until now, I came across a great piece that really helps identify the problem we have created. So What Is A Deployment Really? by Robert van Loghem illustrates what it takes to move from ideation to operation with today’s application platforms. What I really like about this piece is the illustration that even if we want to go back to earliest division of work, it may not be possible. IT operations cannot simply provide a black box for developers to deliver their applications on and expect them to work as planned. Firewalls need updating, web servers need configuration changes to support the new domain requests and the security architecture must now allow these new requests to be routed appropriately based on rights and source.

    Deployment is a team activity!

    So, what have most of us in enterprise IT done? We broke down the tasks of deployment further into divisions of work so that we can apply the necessary level of specialization to ensure the application can be delivered to the end user at the cost of adding a ton of friction into the process slowing things down by a logarithmic factor when compared to our unicorn friends.

    What is surprising is the number of pundits that put forth that the answer to this problem domain is empathy and culture change. Clearly, we have organizationally written ourselves into a corner because this is how large enterprises solve problems. Here’s a simplification of how this decision was most likely made:

    Question: There’s a lot of issues attempting to monitor and operate these distributed applications and the developers don’t have the means or transparency into all the components.

    Retort: Then who does have access and insight into all these components?

    Answer: IT operations can see what’s running and has the tools to monitor the health, let’s give them the task.

    At a time when IT was viewed as an expense versus a strategic advantage, there was no offsite planning to assess what the impact to this answer means to the business ten or twenty years hence. It’s solve the problem and keep moving because that’s what enterprises need to do in non-strategic areas. At the time this answer was formulated most businesses equated this decision with “which office supply vendor should we use?” Moreover, the leaders in client/server barely had any experience with IT operations, they were primarily comprised of application developers. Hence, there was no experience to guide businesses away from this decision. IBM, Unisys, Honeywell, etc. the vendors that were a prime source of guidance at the time were still leading with a time-sharing mentality.

    This entire trip down memory lane was with one purpose in mind, figure out what we created and how it was created so we can consider the means to unwind it and provide a path for enterprise IT to move forward in an agile manner. The history provides the answer. We need to move away from the traditional time-sharing division of work that was formulated before the age of the Internet and realign along frictionless surfaces. What does that mean? Well, that, my friend, is an entire book that happens to be in the works! 😉

  • Waterfall to Agile to DevOps: The State of Stagnant Evolution

    Waterfall to Agile to DevOps: The State of Stagnant Evolution

    DevOps is all the rage. The hot IT buzzword intended to heal the expanding divide between development and IT operations is being used to sell a range of services and solutions to struggling development shops and enterprises, even though DevOps can’t be sold – it’s a cultural shift that nurtures under a strong leadership.

    Prior to DevOps, Agile methodology generated a similar hype that forced businesses to spend millions of dollars in revamping organizational hierarchy, deploying new solutions and hiring self-proclaimed expert consultants. The original values and principles of Agile development to deliver working solutions in small and iterative chunks were quickly forgotten. The methodology was only implemented during development phase and created backlogs for operation teams that failed to push product releases fast enough.

    (more…)

  • The DevOps Scorecard

    The DevOps Scorecard

    Mid-last year our team switched from doing Agile to doing DevOps. As we forayed into the journey trying to learn about DevOps and practice it at the same time,  a lot of questions arose in the team.  How was this different from agile and most importantly How were we going to be successful?

    That’s when we wrote down what would be the success criteria for our team: “Ship code frequently without causing a customer outage“.

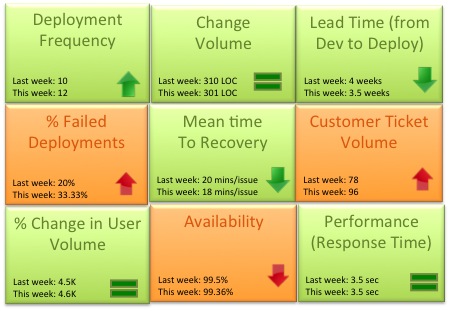
    As the team matured we started evaluating a more granular way to track success.  Could the team mantra be broken down into quantifiable success metrics that could be represented in a scorecard? Based on our experience the DevOps scorecard should contain these 9 metrics to track DevOps team success:

    DevOps Scorecrd

    1. Deployment frequency: How often were we deploying code and getting new code in the hands of our customers? This metric should trend up or remain stable from week to week. Example: Twice a week, 50 times a day
    2. Change volume: For each deployment how many user stories and new lines of code were we shipping?  Example: 3 new features per day, Average 500 lines of new code per week. Another parameter to consider in addition to volume is complexity of change.
    3. Lead Time (from Dev to Deploy): How long does it take on an average to get the code from development complete through a cycle of A/B testing to 100% deploy and upgrade on production? Lead time should reduce as the team gets a better hold of the lifecycle.
    4. Percentage of failed deployments: What percentage of deployments failed causing an outage or a negative user reaction? This metric should decrease over time. Example: 9% deployments failed this month as opposed to 15% last month. This metric should be reviewed in combination with the change volume. If the change volume is low or remained the same but the percent of failed deployments increased, then there maybe a disfunction somewhere.
    5. Mean time to recovery: When we did fail, how long did it take us to recover? This is a true indicator of how good we are getting with handling change and this should ideally reduce over time.  You can expect some spikes in this number due to complex issues not encountered before. Example: On an average it took the team 15 minutes to resolve each last week, 14 minutes this week.
    6. Customer Ticket Volume: Number of alerts generated by customers to indicate issues in the service. This is a basic indicator of customer satisfaction. Example: 54 tickets were generated this week as opposed to 38 while the user volume remained steady is not a good thing
    7. % Change in User Volume: Number of new users signing up, interacting with my service and generating traffic. As new users sign up is my infrastructure able to handle the demand? Example: This week the number of customers spiked by 30% due to an external event causing volume of requests to go up
    8. Availability: What is the overall uptime for my service and did I violate any SLAs? Example: 99.9% uptime consistently for the last 3 months even with change in user volume
    9. Performance (Response Time): Is my service performing within my predetermined thresholds? This metric should remain stable irrespective of % change in user volume or any new deployment. Example: Sub 5 second response time from all geographies and devices

    Would love to hear thoughts on what other critical metrics DevOps teams are using

  • Why “Enterprise DevOps” Doesn’t Make Sense

    Why “Enterprise DevOps” Doesn’t Make Sense

    Recently, some folks have been suggesting that we need a new form of DevOps, something called “Enterprise DevOps” or “Big DevOps.”

    DevOps is great, the argument goes, but large enterprises don’t operate the same way as the agile web startups where DevOps was birthed, and thus they can’t implement the same DevOps methodologies as those startups. Large enterprises have bigger teams, more inherent operational complexity, and greater governance controls (both self-imposed and externally-imposed); therefore, they need a different type of DevOps that caters to their sensibilities and not those of agile web startups.

    While it’s true that large enterprises do operate in a different environment than agile web startups, none of that makes a difference from the point of view of adopting DevOps.

    In short, if you’re advocating for Enterprise DevOps as something different than Plain Ol’ DevOps, then you’re missing the fundamental essence of DevOps.

    Here’s why.

    Early Thinking: DevOps = Tools + Culture

    To best understand DevOps, we need to understand where it came from.

    DevOps started as a bottom-up collection of best practices with few formal underpinnings. System administrators and developers were looking at the successes of agile development practices and trying to apply some of the same ideas to the whole development-to-operations process. Practitioners in the trenches stepped forward and said, “This is what we’re doing and it seems to work for us.”

    One of the earliest and most visible examples of that was John Allspaw’s and Paul Hammond’s presentation at Velocity in 2009, titled “10+ Deploys Per Day: Dev and Ops Cooperation at Flickr.”

    [youtube http://www.youtube.com/watch?v=LdOe18KhtT4]The video is well worth your time, as is the presentation on Slideshare:

    [slideshare id=1628368&doc=allspawhammondvelocity2009-090623161942-phpapp01]

    Note that this presentation predates the actual creation of the name “DevOps.” Allspaw and Hammond talk about how Dev and Ops teams can work productively together, but they never say “DevOps.” Patrick DeBois would coin the term later that year when he created the first DevOpsDays.

    In the presentation, Allspaw and Hammond discussed the success they were able to achieve at Flickr and provided a set of recommendations that they think are important, separated into two buckets:

    1. Tools
    2. Culture

    In the Tools category, they provided six recommendations:

    1. Automated infrastructure
    2. Shared version control
    3. One step build and deploy
    4. Feature flags
    5. Shared metrics
    6. IRC and IM robots

    Along the way, they mentioned that Flickr used:

    • Chef, Puppet, CFEngine, and other automation tools
    • SVN for version control
    • Hudson for builds
    • Ganglia for monitoring

    Finally, in the Culture category, they listed four additional recommendations:

    1. Respect
    2. Trust
    3. Healthy attitude about failure
    4. Avoiding blame

    Unfortunately, most people missed Hammond’s remark ahead of the Tools section of the presentation (timecode 7:40):

    These are some of the tools that work for us. They are not necessarily going to work for everyone, and throughout we’re going to give examples of the specific tools that we use, but the important thing that we’re trying to get across is the concepts that are important.

    In the years following, many self-proclaimed “DevOps engineers” (a bit of an nonsensical title if you understand that DevOps is about bringing Dev and Ops engineers together, not creating new types of engineers focused on nothing but DevOps) insisted that if you were automating your releases using Jenkins and Chef and treating the other members of your team with respect, you were “doing DevOps.”

    While Allspaw’s and Hammond’s presentation was excellent (seriously, spend the time watching it) and the advice was practical and valuable, many people walked away with only a vague notion of what would later be called DevOps.

    For instance, in the “One step build and deploy” recommendation, Allspaw and Hammond describe their automated system that moves code into production. Developers can click a single button to make a build live. The button is jokingly labeled “I’m feeling lucky” (in homage to Google, I’m sure).

    If you’re an agile web startup, that’s par for the course.

    But if you’re a large financial services company, you’re likely to think, “No! Our governance folks will never let developers push code straight to production with a single click, never mind the ‘I’m feeling lucky’ labeling. No way. Not gonna happen.”

    When people suggest that we need “Enterprise DevOps,” they’re typically reacting negatively to the choices that others have made. They recognize that those solutions won’t work for them for any number of reasons, and they say, “I can’t use that. I need something different.”

    But here’s the thing — DevOps isn’t about the specific implementation choices. Those are all optional. You can make a completely different set of choices than Allspaw and Hammond and still be “doing DevOps.”

    Unfortunately, subsequent conferences were filled with DevOps presentations that just reiterated the “DevOps = Tools + Culture” mantra and provided similar sets of recommendations that were often drawn from agile startups rather than from large enterprises.

    So, does that mean Tools and Culture aren’t important for DevOps?

    No, not at all. Both Tools and Culture are critical for DevOps in the long run.

    The problem that DevOps seeks to solve, however, is not a Tools problem or a Culture problem but rather something more fundamental.

    In order to understand DevOps, you need to focus on the ultimate goal.

    The Firm Foundation: The Toyota Production System and Lean Manufacturing

    The Phoenix ProjectIn 2013, Gene Kim, Kevin Behr, and George Spafford wrote The Phoenix Project: A Novel About IT, DevOps, and Helping Your Business Win.

    The trio’s contribution to the DevOps movement was in recognizing that enterprises had confronted a similar set of issues previously, but in a different domain — manufacturing — and that similar solutions could be applied to software engineering and application operations. (The group took another cue from the manufacturing world, copying the novelization technique from Goldratt’s The Goal to create a fictional case study where the characters were allowed to wrestle with the fundamental DevOps truths being discussed.)

    The key takeaway from The Phoenix Project is that DevOps seeks to create a smooth and increasingly speedy flow of change from development into production, with as little waste along the way as possible.

    The GoalThe models here were the Toyota Production System (TPS), Lean Manufacturing, and Goldratt’s Theory of Constraints.

    In the world of manufacturing, we have a physical product that moves through a factory, either on a formal assembly line, or from processing step to processing step, as part of a value stream. Each step along the path is supposed to “add value” to the product until it completes its journey and exits the factory to be shipped to customers.

    If you’re a manufacturing engineer, you need to do everything possible to create a smooth flow through the value stream by identifying constraints in the system and eliminating waste of time or resources.

    In the software world, application artifacts and changes move through the software development and operations value stream, with each step designed to “add value” and get the changes into production.

    If you’re a development or ops engineer, you need to do everything possible to smooth the flow through to production. The techniques you use are similar to a manufacturing engineer — you identify constraints in the system and go about eliminating waste of time and resources.

    The Kata is the Key

    Following Toyota’s success, the TPS and Lean Manufacturing were all the rage in the manufacturing world.

    Consequently, many western manufacturing engineers studied Toyota’s systems in great detail. They noticed a variety of tools and solutions that Toyota used to optimize manufacturing flow, and they recommended their use to their employers and clients. Toyota’s Kanban, for instance, was heavily promoted in the manufacturing world, and later made the jump to software engineering.

    Interestingly, the manufacturing world has suffered much of the same confusion that’s now happening in the DevOps world. When they tried to employ the tools and techniques they had learned from studying Toyota, things didn’t work as expected.

    Toyota KataMike Rother, author of Toyota Kata: Managing People for Improvement, Adaptiveness, and Superior Results, described the situation in the manufacturing world this way:

    Looking back, we naturally put Toyota’s visible tools in focus first. That is where we started— the “door” through which we entered the Toyota topic. It was a step in the learning process (which will also, of course, continue after this book). Since then I went back to the research lab–several factories–to experiment further, and present what I learned in this book. The visible elements, tools, techniques, and even the principles of Toyota’s production system have been benchmarked and described many times in great detail. But just copying these visible elements does not seem to work. Why? What is missing?

    Later, Rother continues:

    Toyota opens its factory doors to us again and again, but I imagine Toyota’s leaders may also be shaking their heads and thinking, “Sure, come have a look. But why are you so interested in the solutions we develop for our specific problems? Why do you never study how we go about developing those solutions?” Since the future lies beyond what we can see, the solutions we employ today may not continue to be effective. The competitive advantage of an organization lies not so much in the solutions themselves—whether lean techniques, today’s profitable product, or any other— but in the ability of the organization to understand conditions and create fitting, smart solutions.

    Focusing on solutions does not make an organization adaptive. For example, several years ago a friend of mine visited a Toyota factory in Japan and observed that parts were presented to production-line operators in “flow racks.” Wherever possible the different part configurations for different vehicle types were all in the flow racks. This way an operator could simply pick the appropriate part to fit the particular vehicle passing down the assembly line in front of him or her, which allows mixed-model assembly without the necessity of changing parts in the racks. Many of us have been copying this idea for several years now.

    When my friend recently returned to the same factory, he found that many of the flow racks along that Toyota assembly line were gone and had been replaced with a different approach. Many of the parts for a vehicle are now put into a “kit” that travels along with the vehicle as it moves down the assembly line. When the vehicle is in an operator’s workstation, the operator only sees those parts , and she always reaches to the same position to get the part.

    My friend was a little upset and asked his Toyota hosts, “So tell me, what is the right approach? Which is better , flow racks or kitting?” The Toyota hosts did not understand his question, and their response was, “When you were in our factory a few years ago we produced four different models on this assembly line. Today we produce eight different models on the same line, and keeping all those different part variations in the flow racks was no longer workable. Besides, we try to keep moving closer to a one-by-one flow. Whenever you visit us, you are simply looking at a solution we developed for a particular situation at a particular point in time.”

    As we conducted benchmarking studies in the 1980’s and 90’s and tried to explain the reasons for the manufacturing performance gap between Toyota and other automobile companies, we saw at Toyota the now familiar “lean” techniques such as kanban, cellular manufacturing, short changeovers, andon lights, and so on. Many concluded— and I initially did too— that these new production techniques and the fact that Western industry was still relying on old techniques were the primary reasons for Toyota’s superior performance.

    Rother concludes that the secret to the Toyota Production System and Toyota’s success was not any one particular tool or technique, but rather the Toyota Improvement Kata, which focused on continuous improvement of everything at Toyota, seeking to establish flow and eliminate waste.

    Toyota Kata is a great book and if you want to understand DevOps, I encourage you to get a copy and read it for yourself. Kevin Behr recommended it to me and I was pleased to see Jez Humble reference Rother’s story, above, in his recent QCon talk on DevOps.

    What is DevOps?

    So, after all that, what are we left with?

    What is DevOps?

    Cue the trumpet fanfare…

    Fundamentally, DevOps is the activity of optimizing the development-to-operations value stream by creating an increasingly smooth, fast flow of application changes from development into operations, with little waste. Optimization of the value stream takes place continuously using various continuous improvement techniques like the Toyota Kata.

    “Is that it?!” I hear you cry.

    Yes, that’s it.

    “No way!”

    Way.

    “But what about Tools and Culture?! What about continuous delivery and Jenkins?! What about automation? What about mutual respect?!”

    Yes, those are all in there, too. But those are the equivalents of Rother’s “kanban, cellular manufacturing, short changeovers, andon lights, and so on.” They are solutions to particular problems that you might be faced with.

    If, during the course of trying to optimize your value stream, you’re faced with the problems that those tools and techniques solve, then you might try them out as solutions. Or you might not, if your situation dictates differently.

    The key is to understand that simply deploying a tool or even a broad solution without thinking through your unique situation and the current state of your value stream and its current constraints is foolish. After all, the specific solutions that are applicable to an agile web startup have a high likelihood of being inapplicable to a large enterprise. And vice-versa.

    Why “Enterprise DevOps” Doesn’t Make Sense

    So, that brings us right back to where we started.

    Enterprise DevOps doesn’t make sense because it confuses the forest for the trees. Those advocating for Enterprise DevOps make the mistake of focusing on specific tools and solutions (Jenkins, Kanban, etc.), then find them wanting for various (extremely valid) reasons in an enterprise context, and then reject DevOps in favor of Enterprise DevOps, which they suggest is somehow different.

    But DevOps is about flow and continuous improvement, not about specific solutions. Flow and continuous improvement are equally applicable to a large enterprise as they are to an agile web startup. And if you miss that, you’re lost, regardless of the tools and solutions you choose.

    To implement DevOps, you need to learn how to map your value stream, identify the constraints in it, and then use a continuous improvement kata to develop specific solutions for your particular problems at this point in time in your particular organization.

    If you’re a large enterprise, the problems and constraints that you face will undoubtedly be different than those of an agile web startup. So, you’ll necessarily need to select different solutions.

    That doesn’t mean you “aren’t doing DevOps!”

    Rather, it means that you’re doing DevOps correctly.

    And remember that whatever solutions you come up with to your particular problems and bottlenecks, they are likely to be temporary. As Toyota said to Rother’s colleague, solutions are only applicable to a particular problem at a particular point in time.

    Epilogue: A Bitter Irony

    Some of the earliest work on what would become DevOps grew out of some ideas that Andrew Shafer was kicking around in late 2008.

    At the Agile 2008 Conference in Toronto, Shafer proposed a birds-of-a-feather session about “Agile Infrastructure.” Only a single person showed up — Patrick DeBois. He found an empty room. It turned out that Shafer skipped his own session because he received such poor feedback about it and thought nobody was interested. Shafer and DeBois later discussed Agile Infrastructure and many ideas that would later become DevOps in the hallways at the Agile 2008 Conference.

    Shafer also presented on Agile Infrastructure at Velocity 2009:

    [slideshare id=1637386&doc=velo09-agile-inf-090625020850-phpapp01]

    Note slides 92 through 97. The key points from this sequence are:

    • Dogma Sucks
    • “Do not seek to follow in the footsteps of the wise. Seek what they sought.” This is a quote from Japanese poet, Matsuo Bashō.
    • The Tao that can be spoken is not the eternal Tao.
    • You are a special snowflake, just like everybody else.

    Even from the start, Shafer was on to the point that a binding set of rules is self-defeating. DevOps cannot be codified in a set of rules. Because it’s bigger than that.

    Note the Matsuo Bashō quote:

    Do not seek to follow in the footsteps of the wise. Seek what they sought.

    The wise DevOps practitioners do not seek to implement any given tool or technique out of adherence to DevOps dogma. Rather, they seek to create a smooth, quick flow of changes through the value stream. Do not try to follow in their footsteps using the exact same set of tools or techniques, but rather seek the same thing that they seek and find your own way to the same destination.

    So, the bitter irony here is that we’ve been warned all along, by Shafer, Allspaw, Hammond, and others, to focus on the foundational problems, not the specific solutions they have employed. Yes, we can learn something from their experiences, but every situation is unique.

    (Unfortunately, I haven’t been able to find video of Shafer’s Velocity 2009 presentation. If you find it, let me know. But you can see a later version of Shafer’s ideas, mixed with those of Paul Nasrat, in a presentation from Agile 2009, made available on InfoQ.)

    Other Resources

    I’ve hopefully salted this post with enough links to key presentations and resources, but there’s one more that should be included. If you’re at all interested in the history of DevOps, and you should be if you really want to understand it better, then you need to view Damon Edwards’ “The (Short) History of DevOps”on YouTube:
    [youtube http://www.youtube.com/watch?v=o7-IuYS0iSE]

    Connect With Me

    Think I’ve left something out or put too much in, got it totally wrong or completely nailed it? Let me know! Continue the conversation by commenting on this post and following me on Twitter.

    About the Author

    dave-roberts-headshot_400x400Dave Roberts brings 25 years of technology experience to his role of Executive Advisor at BMC Software. A thought leader in agile IT and digital transformation, Dave routinely speaks at conferences around the world. Dave is a member of the Twitter #clouderati and blogs at BMC.com and Leverhawk.com. He holds nine patents and has written three books on computer programming and data communications technology.

  • Product Management’s Role in a  DevOps World

    Product Management’s Role in a DevOps World

    When we started Datical, we knew that in order to be successful we needed to practice what we were preaching: DevOps. As the VP of Products and product owner of Datical DB, our flagship Database Lifecycle Management tool, I recognize that Product Management is well positioned to facilitate DevOps adoption across the entire organization. It’s our job to ensure that the solutions we deliver to the market are aligned with our customers needs, valuable, and appropriately represented. To achieve this end, my team has embraced the Three Ways and established practices that map them.

    The First Way: Systems Thinking

    “Systems Thinking” in the product management group goes beyond application development and delivery. Our PM team must also consider how we improve, market, sell, and support our solutions to fully realize our company’s potential. To gain the deep understanding of all aspects of our Product Lifecycle, we’ve agreed upon the following guiding principles:

    • Every Sales Call is a Product Call – My team and I spend a lot of time shadowing calls in all stages of the sales cycle. By attending as many calls as we can we learn what first motivates our market to seek a solution in our space. We get insight into what features resonate most and what areas of our solution are uninteresting to them. We hear how our Sales team is positioning the product and we understand the challenges they face when presenting our solutions to interested parties.
    • We Are a Required Member of our Scrum Teams – The PM & Engineering organizations are highly engaged with one another. Product & Engineering management meet 2-3 times a week to discuss sprint progress, new development stories, and long term product roadmap. Product Managers attend daily development stand ups to answer questions and eliminate roadblocks in the current sprint based on the needs of internal and external customers. We balance technical debt, infrastructure requirements and feature development during sprint planning to ensure high-quality product releases and a reliable delivery chain.
    • We are Marketing’s Lyricist – Our deep understanding of our customers, our market, and our products allow us to arm our marketing group with the content and messaging they need to be heard over the chatter. We influence marketing plans with what we know is working in sales and what we know is coming out of engineering.
    • Everyone is Customer Support – We take reactive and proactive participation in customer support seriously. PM responds directly to customer support requests and we constantly reach out to customers we haven’t heard from to make sure they are getting value from the product and that their needs are being met.

    The Second Way: Amplifying Feedback Loops

    The Second Way, Amplifying Feedback Loops, is where the product group provides the greatest value to the company. By adhering to our guiding principles of Systems Thinking detailed above, the product group has a good handle on all aspects of our business. We know how we sell, we know what we need to do to increase our value, we know the engineering effort involved in delivering new features, we know where our customers are thriving and where they are struggling, and we know what we’re telling the market.

    The physical manifestation of the Second Way in the product group is our Product Roadmap. Too often, roadmaps become little more than flashy marketing tools that promise a lot, but often fail to deliver on the hype. We’ve found that customers respond more favorably to a smaller roadmap that is accurate than they do to a road map that is full of wild, cleverly named features whose delivery is uncertain at best.

    At Datical, we take what we’ve learned from participation in sales and support activities to prioritize our development efforts on real customer needs. We apply what we’ve learned from engineering about the effort involved to deliver on our customer prioritized feature list, balance those estimations with what’s necessary to maintain a smooth operating environment for development, and provide realistic delivery goals for product features. Once we have dates for new feature delivery, marketing can plan their strategies ahead of time and sales can speak with confidence and certainty when discussing our future with prospects and customers. When every person in your organization can speak confidently about your customers, your product, and your market, the deck is stacked in your favor.

    The Third Way: Embracing Experimentation

    Product Managers that know their customer’s problems are crucial to reaping the most reward from Embracing Experimentation. A great example of this is a feature we are releasing in our 3.0 version of Datical DB this Friday. We call it the Rules Engine, and it is the direct result of Datical’s culture of encouraging experimentation.

    Datical DB has a feature called Forecast that allows you to simulate your proposed database updates in memory without actually affecting the database instance. This takes the uncertainty out of the deployment process by identifying errors prior to execution. Customers really liked the feature, but there were always questions about the extent of Forecast’s capability. Typically they would ask about standards and best practices for their specific organization and whether we could modify the Forecast feature to accommodate their specific use cases. If we were to commit to modifying Forecast to suit everyone’s needs, it’s all we would have time to do. We recommended that the customers manually review the changes in those cases before promotion to downstream environments, something they were already doing with piece meal SQL scripts.

    While discussing the frequency and consistency of these feature requests with our VP of Engineering, we had an idea. What if customers didn’t have to rely on us to modify Forecast for their specific needs? If we could deliver on this, we would drastically reduce the time and money companies were spending on reviewing database change prior to approval. We decided to turn our best minds on the idea with a very sparse set of loosely defined requirements.

    Our first attempt failed. We reviewed the results of our research and prototype attempts, refined the story, and tried again. Our second attempt showed promise. We refined it further, built on what we learned, and had a viable solution in sight.

    We began talking to our customers about it. I actually heard a grown DBA giggle with excitement! He had DBAs on his team spending 70% of their time manually reviewing SQL scripts from development to make sure they were in compliance with their standards.

    After collecting customer feedback, we combined it with the results of our technical experimentation, and are very thrilled to be bringing this feature to market at last. By encouraging experimentation and not bowing to initial failures, we’re delivering a great differentiating feature to the market.


    About the Author

    High-Res-Peter-Pickerill-6571-150x150

    Pete Pickerill is Vice President of Products and Co-founder of Datical. Pete is a software industry veteran who has built his career in Austin’s technology sector. Prior to co-founding Datical, he was employee number one at Phurnace Software and helped lead the company to a high profile acquisition by BMC Software, Inc. In addition to managing a development team and product schedule at BMC, Pete worked directly with large financial services institutions to provide the features they needed to achieve greater efficiency and cost savings in their application deployment processes.

  • SDN has a lot to offer to DevOps

    SDN has a lot to offer to DevOps

    When discussing DevOps it’s natural to focus the attention on the one operations  team that focuses on application infrastructure. But when you start digging in to DevOps and its applicability to all four operations groups you’ll find that technological shifts in the network – like software-defined networks (SDN) – are just as important to the overall success of DevOps-related initiatives as the spread of software-defined operations going on across the application infrastructure.

    One of the intersections of network and app infrastructure operations is around speed. Not just speed of deployment of services supporting applications, which is critical, but also the resulting speed of the application itself. Application performance management (APM) is a less often mentioned concern of those looking at DevOps but it is one with which developers and app infrastructure operations alike are very interested in not just monitoring and measuring but improving.

    But here’s the thing: the relationship between the app infrastructure and the network are intertwined when it comes to application performance. Measuring and monitoring in the app infrastructure is all well and good, but it is impacted by network performance. And vice versa. Technically speaking, the app infrastructure folks are going to end up tweaking things like TCP; changing window sizes and timeouts in order to improve poorly performing apps. And they should, as TCP is highly tunable and one of the primary means of changing the performance behavior of an application.

    But tweaking TCP has an impact on network performance. TCP is a reliable transport protocol, meaning its particular about thinks like packet order and its very responsible about making sure each and every packet is received. When one isn’t, it resends it. And resends it. And resends it. Retransmit storms contribute to the congestion of the network, which in turn contributes to the need to retransmit, which in turn… well, I think you see the Catch-22 here. While the app infrastructure team is pointing fingers at network operations, the network operations team is pointing fingers at the app infrastructure team.

    Both are equally responsible for the problem.

    SDN promises, in part, to address the problems associated with speed. Both speed of service deployment (through operationalization) as well as speed of delivery, i.e. application performance. SDN will, ostensibly, provide the means to both recognize application specific performance requirements and adjust, as necessary, the delivery of application data through the network in order to meet those requirements. But what it also implies is the ability to provide visibility into the reason why new routes were necessary. There are plenty of reasons an application might initiate a retransmission storm and some of them are related to the application platform (TCP problems), others to the client or the Internet itself, and still others to the network. Being able to quickly identify what is causing a degradation in application performance gives everyone the ability to react and resolve the problem faster.

    That goes to MTTR (mean-time to resolution), a key DevOps-related metric.

    But for all that to happen, there has to be some collaboration (sharing) going on between network and app infrastructure operations. There has to be less finger pointing and more question asking going on between the two, and the sharing of collected performance data across the entire application delivery chain – from network to platform to the app itself. SDN provides a means through which such measurements can be obtained and shared with other systems – and teams. This ability is important. Puppet Labs 2014 State of DevOps Report named it a “top practice” correlated with MTTR, and CA’s latest report indicated 19% of organizations adopting DevOps have experienced “Improved quality and performance of our deployed applications.”

    Monitoring and measuring application performance is a key component of DevOps, and yet a significant portion of that performance is dependent on and related to the network. Which means app infrastructure operations can’t measure or address poor performance without understanding the network’s contribution to the whole.

    SDN “apps” can be one way in which app infrastructure and network operations can gain insight into how apps are performing and how the network is impacting that performance – for good or bad. Whether it’s simply having the data to share or providing an interface into the network to gather the data, SDN has the potential to enable greater collaboration across network and app infrastructure teams.

    That makes it an excellent player in the wider ecosystem of tools and frameworks that support the need for monitoring and measurement associated with DevOps initiatives.


  • Supporting Production Applications the DevOps Way

    Supporting Production Applications the DevOps Way

    Software applications are more complex than ever. If your application is slow or down for even five minutes customers will blow up on Twitter for the whole world to see. To prevent this, developers and operations have to work together in lockstep when deploying and supporting applications. Preventing and fixing application problems quickly is critical to keep your outage from becoming a trending topic on Twitter.

    The DevOps Movement Begins

    For software developers, ensuring early success of your new application starts with keeping IT operations in the loop. Traditionally a lot of software development teams have worked for months on new projects and then thrown them at the IT operations team at the last minute when it came time to deploy them. If you want a good example of this, look no further than the big healthcare.gov debacle. The DevOps movement started originally to try and solve that problem. It fosters a culture of keeping development and IT operations working together from the beginning to the end of the project so software deployments go more smoothly.

    Long-term success of your application depends on proper maintenance and monitoring of your applications as you continue to roll out new features.  Thanks to agile development, that is usually a weekly or monthly cycle at most companies. A constant stream of new features is awesome, but with that comes some risk in introducing new bugs, performance problems, or instability. This constant stream of change coupled with the overall complexity of today’s applications makes them difficult to support

    Application Support: “It Takes a Village”

    Collaboration between developers and IT operations is needed to keep your applications running and your customers happy. If you only have a couple senior developers who handle all the production support issues they will have little time to deal with more important issues like architecting new features.

    The key to supporting production applications is removing the bottlenecks and getting more people involved in application support. Operations needs to make sure that the development team has visibility of  basic troubleshooting information like errors, logs, and key metrics while ensuring security.. Without this information it is hard for developers to fix basic bugs and improve application performance. They must contact other developers or system administrators for help which creates a huge bottleneck. You could say “It takes a village.”

    Granting access to production data raises both  security concerns and fear of unauthorized changes to the servers without going through proper release processes. However, developers don’t really need administrator level access to servers (jumping between dozens of servers is not very efficient anyways), they just need visibility to the aggregated information. This will allow them to find the source of the problem fast, while not creating any security risks or letting developers create new issues while fixing others.

    DevOps Should Include Production Support

    The goal of DevOps is to create collaboration and improve the working relationships between development and operations. The DevOps movement initially started focusing on software deployment and continuous delivery. However, support of production applications is the second and equally important component in the application lifecycle that is sometimes overlooked. To solve production problems quickly, developers and operations can not be pointing fingers at each other. They need to work together as a team.

    To help support production applications, developer need access to lots of data:

    • Visibility and notifications around all application errors
    • Access to centralized aggregated log files for viewing and searching
    • Basic server utilization trends and stats. (e.g. CPU, memory, etc)
    • Recording and alerting of key application metrics (KPIs)
    • Tracking of application web page load times
    • Ability to access the application database and run test queries

    Most companies utilize several different tools to track all of this data. This makes it difficult to correlate and identify issues. It is also very hard to train all team members on how to effectively use all the available tools, not to mention the economic inefficiency. Companies should look for solutions that combine these features into one dashboard so that solving issues can be done quickly and with minimal training.

    Companies should look for tools that gives developers access to all the data they need to monitor and troubleshoot production applications, without giving them administrator type access to all the servers. One application dashboard that will show them where the app is deployed, the current health, performance stats, recent errors, full logs, and key metrics. This is what we try to do here in Stackify – to make it easy for companies to embrace DevOps when it comes to supporting production applications. Some of our customers have shared with us how DevOps affected their organization. We would love to hear how DevOps has affected your company.


     About the Author/Matt Watson

    2014-11-05 20.36.01

    Matt Watson founded Stackify in 2012 and as CEO provides the vision and leadership for the direction of the company. Prior to founding Stackify, he was the founder and CTO of VinSolutions. VinSolutions’ innovative product offering led to rapid company growth and was even featured on the Inc. 500 (#447) in 2010. Matt is an entrepreneur at heart and excels at product and software development.

    Feature photo by JD Hancock

  • I Like Your Backend

    I Like Your Backend

    Back in the early 80’s, dumb terminal networks ruled enterprise IT. Mammoth mainframe IT infrastructures worked as centralized corporate computing platforms feeding a vast nexus of thin clients performing mundane IT operations as intended. Perhaps that was all what end-users longed for.

    (more…)

  • IBM Webcast Nov 12: Use Discovery to accelerate testing and virtualization

    IBM Webcast Nov 12: Use Discovery to accelerate testing and virtualization

    Many of today’s business applications offer a multitude of services (APIs) across many different technologies. These same applications also reach out into a web of already-existing services in order to retrieve and update information necessary to successfully deliver the end to end business processes. In many cases, these applications are being built by multiple development teams distributed around the world with architectural approaches and middleware changing over time and yet we point test teams at the mere tip of the iceberg and say, “Test it!”. Testers know the benefits service-based testing and service virtualization bring but to successfully use these capabilities they first have to understand not only the application’s architecture but also the way in which it communicates with everything around it. Finding this information can be a forensic-like exercise; even if there is documentation there is only one real truth – the environment itself. Watching and interrogating the real systems allows testers to understand what’s really happening under the surface, sometimes with surprising results.


    Date: Wednesday, November 12th, 2014

    Time: 1:00pm – 2:00pm eastern standard time

    Registration link: https://ibm.biz/BdEqEf

    About the Speakers:

    Join Nick Portalski, IBM Development Manager for Integration Testing and Service Virtualization solutions as he explains the rationale for using various discovery techniques and explains how their use can accelerate project initiation making it possible to reduce testing cycles and mitigate risk. Al Wagner will be your host for this event. Al drives thought leadership, strategic initiatives, and tangible solutions with a specific focus on quality management, test automation, and service virtualization.