Category: Blogs

  • Google Hangout: InterConnect 2015 preview from IBM & Synchrony Systems on #DevOps for Enterprise Systems

    Google Hangout: InterConnect 2015 preview from IBM & Synchrony Systems on #DevOps for Enterprise Systems

    Join us for another exciting Google Hangout* with a distinguished panel of guests as we deep dive into the multiplatform application development challenges related to: Integrating Systems of Record (Mainframe) with new Systems of Engagement (Mobile). Take this opportunity to find out how Bay Area Rapid Transit (BART) leveraged a DevOps approach to deliver an innovative mobile app integrated with their enterprise systems in 15 days. Dig deeper with the experts into what it takes to actually implement DevOps in an Enterprise dependent on traditional Systems of Record and now required to extend these core Systems to support new Cloud and Mobile initiatives.

    With IBM InterConnect 2015 just a few weeks away, three featured presenters will give us an Interconnect preview.

    Our Panelist:
    Hayden Lindsey, IBM Vice President & Distinguished Engineer – DevOps for Enterprise Systems
    Slavik Zorin, President, CEO & Founder, Synchrony Systems, an IBM Business Partner
    Mike Fulton, DevOps for Enterprise Systems CTO

     Date: Tuesday, February 10th, 2015

    Time: 2pm eastern standard time

    Google Event Page:(NO REGISTRATION REQUIRED*) 
    Google Hangouts are FREE. To participate in a Google Hangouts LIVE, 
    a Gmail or Google Profile is required
    

    About Our Guests:

    HaydenLindseyHayden Lindsey, our guest from @IBM

    IBM Vice President & Distinguished Engineer – DevOps for Enterprise Systems


    Hayden’s session @ #IBMInterConnect 

    https://www-950.ibm.com/events/global/interconnect/sessions/preview.html?sessionid=DEM-1779


    MikeFaceMedium

    Mike Fulton

    DevOps for Enterprise Systems CTO

    makingdevelopersliveseasier.wordpress.com


    Mike’s sessions @ #IBMInterConnect

    https://www-950.ibm.com/events/global/interconnect/sessions/preview.html?sessionid=DEM-5873

    https://www-950.ibm.com/events/global/interconnect/sessions/preview.html?sessionid=DSZ-2171

    https://www-950.ibm.com/events/global/interconnect/sessions/preview.html?sessionid=DEM-4536


    slavikSlavik Zorin

    President, CEO & Founder, Synchrony Systems, an IBM Business Partner


    Slavik’s sessions @ #IBMInterConnect

    https://www-950.ibm.com/events/global/interconnect/sessions/preview.html?sessionid=DEM-4399

    https://www-950.ibm.com/events/global/interconnect/sessions/preview.html?sessionid=DEM-5416

  • The Role of a Traditional NOC in the new DevOps World

    The Role of a Traditional NOC in the new DevOps World

    This new question in the devopsy.kinsta.cloud Enterprise DevOps Q&A series comes from a large business, though not what many would recognize as a traditional or legacy enterprise. This organization, like many high-growth businesses, is in a relatively new market segment that only exists due to the rise of cloud computing and digital media. In their business, the network (especially access to and from their public cloud service) is critical to the value they provide their customers.

    So it is no surprise then that, as they contemplate their transformation to an agile environment built on DevOps principles, they are asking me about the role of the Network Operations Center (NOC).

    1. What Role Does a NOC Play in the DevOps World?

    Despite coming from a ‘new tech’ business, this is another of the questions that is typical in a large enterprise. While smaller startups and even many web-scale businesses may have an Application Support team, not many run their own NOC, and even fewer separate out these roles from the rest of the operations team.

    First, some things do not change in a DevOps world. Fundamentally, the NOC is still tasked with maintaining high quality production networks and systems, detecting potential problems as soon as possible, triaging those problems to find root cause, and remediating problems as fast as they can.

    However, the NOC team will gain additional activities and support a broader interlock beyond just the production environment, especially as networking becomes more embedded in application delivery through capabilities like software-defined networks and cloud computing. They will work more closely with teams like app dev, SQA, pre-prod and release; they will provide input to design and development; and they will contribute earlier in the software cycle. This is the logical outcome of a DevOps approach that emphasizes the need to work more collaboratively across the entire end-to-end SDLC.

    So you should consider bringing these network specialists into:

    • development planning, to help architects and engineers to build applications with operable networking by design, including software-defined networks that help make a truly idempotent application
    • testing and QA, so they can provide engineers and SQA teams with tests and analysis that accurately reflect the reality of the prod network, rather than leaving network testing to after production deployment
    • dev/test support (where they may already be acting), to ensure that the environments that dev/test rely on to create new capabilities are just as stable and reliable as the systems they will eventually be deployed to
    • release and deployment, to ensure they have input into determining and defining ‘known good values’ for production monitoring and for problem diagnosis, triage, and escalation – before release, not just after
    • expanding interoperability and self-service, by exposing ‘known-good’ deployment, triage, and (re-)configuration capabilities as automated software-defined processes (or APIs) that dev/test can use without opening a new service ticket
    • a broader role in ensuring the end-to-end quality of the network, alongside traditional operations/infrastructure support as part of a new role commonly referred to as a ‘Site Reliability Engineer’ (SRE)

    Because DevOps is about improving collaboration, remember too that you should also bring dev, test, QA, etc. into the NOC, and even rotate them onto support, so they have an understanding of the core operations of a production network, how their code acts in a real environment, and how their work affects other teams. This will help to build the empathy between teams that is a core tenet of DevOps.

    You may be concerned that asking your NOC to work more upstream is adding a load of work to those teams that they didn’t have before. That may be true, but a significant outcome of Enterprise DevOps in practice is to reduce the ‘busy work’ of such teams, free them up to do more ‘smart work’, and to do it earlier in the software lifecycle.

    For example, recent research has shown that DevOps is correlated with improving the quality of applications (especially before they hit production), reducing the amount of time and effort the NOC team spends on problem detection, triage, and remediation. In fact, in this research, ‘reduction in time spent fixing and maintaining applications’ is one of the strongest outcomes, with an average 21% reduction in this metric.

    Similarly, standardizing on known-good processes, APIs, configurations etc., and enabling other teams to employ self-service and software-defined networking capabilities will allow the NOC team to spend less time on routine responses to things like servicing provisioning and configuration tickets.

    I cannot guarantee they will not be a zero-sum game, especially in the short-term, but over time a DevOps approach should actually spare workload from the NOC team, freeing them up to ‘shift left,’ moving their talents earlier in the SDLC, as they communicate, collaborate, and integrate more closely with upstream teams like dev, test and QA.

  • Evolution Not Revolution – DevOps in the Wild

    Evolution Not Revolution – DevOps in the Wild

    Ever heard these questions:

    • What is DevOps?
    • How do I hire a DevOps Engineer?
    • Should we have a Director of DevOps?
    • Am I doing DevOps?
    • Why is DevOps failing in my organization?

    More and more frequently, I run into engineers, managers and business leaders describing failures in their organization due to “DevOps.”

    Oddly, digging a little deeper, I find that most of these cases are simply failure by substitution. The Operations team was failing, so they rebranded it DevOps. Alas, buzzword compliance was unable to change the trajectory of the team and the buzzword was blamed.

    DevOps today is–still–an ill-defined set of practices closely associated with automation and operations. If you accept this as fact, then DevOps can neither fail or succeed. If we want to measure the success of the DevOps movement in an organization, then we need a definition that leads to accountability.

    A Definition for DevOps

    The DevOps movement, unlike Agile, lacks a manifesto. To fill that gap, I assert that DevOps is a philosophy and that its base definition is:

    DevOps is the way in which a technology organization embeds itself in a business to the benefit of that business.

    The business in question need not be a technology company such at Docker or IBM. Indeed, all companies today are technology companies whether they like it or not. (1)

    In this and future articles I will write about philosophy, models and implementation. In short, a philosophy is what I reason from to create models of behavior. Models inform the actions taken in an implementation. Implementation without philosophy leads to failure. Jingoistic adherence to philosophy without accounting for new technology leads to failure. Balance must be acheived.

    As an example of this sort of failure, take a lesson from project management. Many shops adopt Jira because it can do anything. Since the tool can do anything, that means their workflow is capable of anything! Problem solved, QED. We all know tools are not process. When we look at our own track records of instituting change. too often the change stemmed from tool choice, not critical thinking about what was to be accomplished.

    Tools should reflect the philosophy they are implemented to support. Without that philosophy tools will fail. The more complex the problem or tool, the more spectacular the failure. In this example, Jira did not fail, leadership failed. Specifically the thought leaders entrusted with workflow management.

    Are you Doing IT DevOps Style

    DevOps is about evolution. If you are doing IT DevOps style, then you are asking questions like:

    • What should we change next?
    • How do we create a sandbox to measure the impact of the change?
    • How do we create demand for the change once vetted?
    • Who do we need to be patient zero?
    • What cultural paradigms are we shifting and how do we ease this for teams?

    While automate-all-the-things is often associated with the term DevOps, automation without cultural shift will result in broader failure, rather than success. Like any technology problem, at its core DevOps models account for their impact on people because businesses are composed primarily of people.

    Future Articles

    Over the course of the next few months. I will relate my experiences at several companies. Articles will describe:

    • What we changed.
    • Why we changed what we did.
    • What cultural issues we faced.
    • What technologies we used and why.

    I hope you will join me to learn how the practice of DevOps as a philosophy can lead to millions of dollars on the bottom line, happy bosses, fluffy bunnies and rainbows. If your lucky, you might even become a unicorn, though my own horn has yet to sprout.

    The first case study will describe a failing company with three months capital. An amazing team. Some amazing mistakes and, ultimately, some amazing success. Technology decisions driven by the needs of a sales team. Automation driven by a business model. A successful acquisition.

    References

    (1) The Phoenix Project – Gene Kim, Kevin Behr, George Spafford
    (2) Good to Great – Jim Collins


    About the Author/Boyd E Hemphill

    boyd-hempilBoyd E Hemphill is Director of Evangelism at StackEngine (link). , an enterprise grade, Docker operations management software company. DevOps raconteur and organizer of community events in Austin, find him on Twitter or LinkedIn.

  • Optimize your spend on AWS through Reserved Instances

    Optimize your spend on AWS through Reserved Instances

    Over the last few years Amazon has gradually raised its compute capacity and provided the user with a set of advanced analytical and structural services. For each service, you can expand precisely for the amount of resources you actually need and shall pay for each resource usage at the end of each month.

    In the spotlight, Amazon EC2 instances which carry along an entire surplus of attributes to help you in deploying, managing and scaling up your applications, Reserved Instances(RI) are another feature making itself really useful in resource management. In this blog we will see what actually are these Reserved Instances also known as RI and why are they named so and how are they cost effective.

    Reserved Instances:

    Reserved Instances are the best money saving technique considering cloud costs. Here’s the catch ” they  require  no methodological optimization effort, no Devops wizardry and no auto scaling structure”.

    RI gives you the power to escalate the roof of your savings by encountering all your business’s call.

    1). Term: 1 or 3 years is time period proposed by AWS for Reserved Instances usage.

    2). Region: Reserved Instances are accessible in all AWS regions. They are also obtainable in Amazon VPC and Dedicated Instances.

    3). Operating System: Platforms for which Reserved Instances can be purchased are Microsoft SQL Server, Amazon EC2 running Linux/UNIX, Microsoft Windows Server, SUSE Linux and Red Hat Enterprise Linux.

    4). Payment Option: There are three payment alternatives provided by RI which are as follows:

    a). Upfront Option: With upfront payment you pay in once for whole RI and you get an extensive discount over On-Demand Instance pricing.

    b). Partial Upfront Option: In this payment option, you are charged a discounted hourly rate as a low upfront payment for the Instance for time span of the RI term.

    c). No Upfront Option: This option provides a discounted hourly rate for the time span of the term and does not require any upfront payment.

    Why Is It called “Reserved”?

    These Instances are named as “Reserved Instances” as they reserve the server capacity. They provide you with a formal assurance that you will be able to launch these RI fully whenever you need them without a popup of insufficient capacity, any time you attempt to start an EC2 instance.

    HOW RESERVED INSTANCES WORK:

    I assume the information above makes you well acquainted with what Reserved Instances are and why they are named so. Now lets consider their functioning.

    To work with your reserved capacity, directly launch an EC2 instance with the same configuration as the reserved capacity that you are capable of purchasing. Instance comprises of varying combinations of platform type, memory, storage, availability zone and instance type. As long as you have an active Reserved Instance, AWS will automatically apply the discounted hourly rate for your EC2 instances. If at any point your purchased Reserved Instance gets expired, then at this situation you will be charged on the basis of On-Demand pricing until and unless you purchase new Reserved Instance of the same capacity.

    All these reservations are applied at the infrastructure level. Once you have a single account, your reservation will be shared amongst the different instances based on run-time. Incase you are a multiple account holder under the same parent account, your reservation gets shared across all accounts.

    There’s also an option available to purchase as well as sell these Reserved Instances through the EC2 Reserved Instance Marketplace thus providing you with the flexibility to sell unused Reserved Instances to any other businesses and organizations.

    Benefits:

    1). Cost Effective: RI equips you with a sufficient discount which is nearly around 75% when compared to On-Demand Instance pricing.

    2). Modifiable: If there arises a situation where you are required to change the zone of your RI then it can be easily done by moving your RI to another available Zone within the same region, by changing its Network Platform as well as instance size of your reservation to another size of the same instance type at no extra cost.

    3). Reliable: To build up your confidence, RI supplies you with a capacity reservation to launch the number of instances you have stockpiled when you need them.

    4). Easy to use: RI usage is similar to that of EC2. While evaluating the bill , system will undoubtedly apply RI rates to reduce your costs.

    5). Marketplace Available:If you want to impose any sudden or planned changes than RI marketplace gives you the opportunity to sell these Reserved Instances.

    Reserved Instance Pricing:

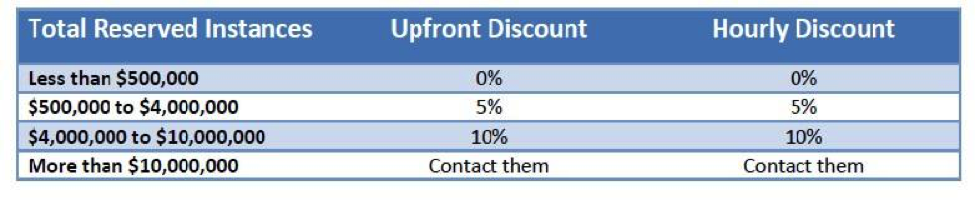
    It’s pretty undoubted that if used with a fair setup, RI helps you to save dollars on AWS in many ways. But if you purchase a massive number of RI in an AWS region, you will automatically be receiving discounts on your upfront fees and hourly fees for future purchase of RI in that AWS region.

    The figure below represents the RI Tiers pricing list:


    RI

           Fig: 1

    So far Amazon Web Services has created exceptionally compelling and powerful features with the Reserved Instances. They not only provide cost benefits but even warranty on the capacity. Though, to be flexible it requires cautious guardianship of your cloud substructure and reservation inventory. So go ahead with reserved instances if you’re looking to deploy a wide scope of apps and websites with a long term no hassle approach.

  • #ChuckNorrisDevOps Winners

    #ChuckNorrisDevOps Winners

    In January we decided to kick the year off by running a contest asking readers to come up with the reasons why Chuck Norris doesn’t need DevOps. We had a lot of fun with this, thanks to everyone who participated!

    Here are the winners we picked:

    Most ReTweeted – @tknerr_de


    Most Humorous – @JerDoug


    Most Original – @devopscouts


    Honorable Mentions


  • Measure Twice. Automate Once.

    Measure Twice. Automate Once.

    “Shipping” code may start with the completion of development but it doesn’t end until after the operational delivery process ends. Just like any fulfillment process, shipping is actually just the kick off of an often arduous journey that ultimately delivers the app to the end user.

    Ship It

    Back in the old days (when they still let me write code) one of our favorite phrases was “ship it” to indicate completeness of a task. That’s because the ultimate goal was, of course, to “ship” the code off to the users so they could start doing whatever it was they were going to do with it*.

    But the reality was, of course, even when we were really ready to “ship it” to users that it didn’t actually get to users for varying amounts of time. Like shipping anything today, it depends on the shipment method. In terms of today’s enterprise IT, “shipping method” is really a metaphor for the operational approach to deploying all the infrastructure – the “middle boxes” – with the services required to actually deliver a secure, fast and available application to its ultimate users.

    app-services-2

    We know from various studies that this takes time. From days to weeks to even months. And we know we don’t like that and we want to improve it. Which is where DevOps comes in, or NetOps or SDN or SDDC or SDO or whatever you want to call it.

    Speeding up the deployment process is certainly one of the goals of operationalizing the network, but without a baseline how do we know if we’ve gotten faster in the first place?

    That’s a piece of the DevOps puzzle we’ve been ignoring – the need to measure the deployment process. You might notice that “measure” is bolded and in red, that a visual clue meant to reinforce the importance of the measurement aspect of DevOps. If you aren’t measuring how long it takes to deliver that app from dev to its destination – production use by an end-user – then you have no idea which pieces of the process are holding you back. You can’t effectively determine where automation might be applied to improve the time it takes to get to market. You don’t know exactly where the obstacles are that need to be addressed in the first place.

    While we can make some assumptions based on long experience and research and point to handoffs across the IT silos, the reality is that there probably isn’t just one handoff between ops and the network and there may be multiple intra-IT group handoffs. For example, the network ops that handles provisioning network services might not be the same team that handles load balancing and performance services. But they’re both within the “network” silo. There may be multiple handoffs back and forth as various services also need networking services on top of the ones required by the app itself.

    Image Credit: Gaping Void
    Image Credit: Gaping Void

    Without some kind of measurement of how long each of the various steps is taking it’s impossible to determine exactly where the bottlenecks in the app deployment process are in your organization. I can not only determine where that Minecraft Lego set I ordered for my son’s birthday is right now, I can see how long it’s taken to get from each point in the process. I know it goes from point A to point B in X days, and from point B to point C in Y days, and I know if there’s a winter storm that it’s going to cause a slowdown in that second step (which is called a movement in the logistics vernacular, in case you were wondering. I knew you were, you’re welcome!)

    Measure Twice. Automate Once.

    The hidden value in setting out to measure the deployment process is in pulling together an understanding of the process itself. It’s in finding redundancies and discovering sub-processes that are running in serial but could be running in parallel to improve them. It’s not necessarily about automating the whole thing up front, it’s about understanding what the process is and making it more efficient – whether through elimination, reorganization or automation (or all three).

    You don’t simply want to be automating things willy nilly without any idea whether it’s going to do any good. As my dad taught me about working with wood, you measure twice and cut once. With DevOps you want to measure twice (at least) and automate once. Otherwise you may be wasting cycles on one-off tasks or tasks so specific to one application that automation has no real value because it’s not the same across applications.

    The key is to start with defining what you’re going to measure, do the measurement and then analyze it to determine what you need to improve.

    Because automating just for automation’s sake isn’t any more fruitful in the end than adopting technology for technology’s sake.


    * I say “whatever” because over the course of my career I’ve worked on tax software, GIS software, communications and transportation and logistics systems. There’s a lot of variance there in what end users might be doing with “the app”.

  • DevOps – It’s all about continuous testing !

    DevOps – It’s all about continuous testing !

    I loved reading Steve Wilson’s blog post “Don’t Fear Testing Team. DevOps is Here!” https://devopsy.kinsta.cloud/blogs/dont-fear-testing-team-devops-is-here/  The idea that DevOps  somehow reduces the need for testing  certainly puts fear in the hearts of QA and test teams who may envision the demise of product quality,  reduced test resources and even their very livelihood.  I understand the sentiment of the idea about testing going away, but this is misleading.

    Testing is important to DevOps. Prior to code integration to trunk, developers pre-flight test their code to make sure it doesn’t blow up the trunk. During the CI cycle and code commits from multiple developers integration testing is used to verify merges.  During the continuous testing phase where nightly and weekend regression runs are automated for trunk and release branches it is testing that does the job of finding problems before the software release.  During the development process the verdicts trends from testing are a primary measurement of progress. During the release deployment phase more testing verifies the release packages are ready for release.  Rest assured test team, you are needed.  What DevOps really does is bring testing into the mainstream of development processes, and avoids the problems created by having “big-bang” testing left to the end of the cycle, such as release delays, and quality issues.

    Testing maturity is a key differentiator of best practices DevOps infrastructures. My experiences with DevOps infrastructures over the years indicate that testing maturity is a key differentiator of overall DevOps infrastructure maturity. Many organizations can automate their integrations, builds and delivery processes but still have trouble with the subtleness of test orchestration and automation.  There is a vital role for testing architects and testing teams to offer their expertise for test design, test automation and test case development with DevOps.   Whether the organization is using a test driven development methodology, behavior based test creation, model-based testing or whatever they use, testing is a vital part of the overall DevOps process — not only to ensure verify code changes work and integrate well — but to ensure the changes do not blow up the product. So clearly testing is still an integral part of product development and delivery.

    At my company Spirent we think testing has a bright future in DevOps. You can read more about our views at http://www.spirent.com/solutions/devops

  • Confident Financial Solutions is cutting edge with ChatOps for log monitoring

    Confident Financial Solutions is cutting edge with ChatOps for log monitoring

    cfs-logo-retina-c0cdab06f0c380b5877a5bf0c779acafIf I told you a company named Confident Financial Solutions is on the front line of adopting DevOps methods to better serve their customers you might say, “Come again?”  Let’s face it Confident Financial Solutions doesn’t sound like the type of company that would be stretching the envelope of technology. But don’t let the name fool you.  Confident Financial Solutions is a web-based SaaS auto repair loan company and part of the Boulder startup scene. Tech is in their DNA as much as finance and cars are.  So the fact they are using ChatOps to monitor and alert based on their logs should not be suprising.

    What CFS does is offer consumers instant approval on auto repair loans. If your car breaks down and the bill is more than what your budget can handle right now, they allow you to finance the repair. Using a web app interface the entire process is handled online. In that regard they are no different than many other SaaS based apps. So why shouldn’t they use the latest and greatest tools.

    Among the tools they use are Slack for ChatOps and Logentries for log and analytics. Using Slack really sped up the communication among the team according to Kyle Lamy, lead software engineer at CFS. So much so that the email alerts and information generated by their cloud based log management system actually slowed the team down.

    Lamy says that communicating via email versus Slack was just dragging everything down. Email with its long threads and back and forth was just not operating at the speed that CFS business demands. Also switching back and forth from email to Slack was a major time drag. He lobbied both Slack and Logentries to integrate.

    Slack and other ChatOps programs of course recognize that the value they deliver is tied to APIs and integrating with 3rd party tools. Otherwise they are little more than instant messengers.  That is the real pay off for ChatOps. Slack is hard at work with API development as well as acquiring new features.  They just announced that they have acquired Screenhero, a YCombinator spawned screen sharing app that will be integrated into Slack. At virtually the same time it was announced by Logentries that they were now integrating with Slack as well.

    In my conversation with Lamy he said having Logentries alerts and analysis in Slack allowed the team to stay in one tool and more importantly put the responsiveness of his team up to warp speed compared to email.

    Kyle says he sees even more ways that ChatOps applications can integrate with other tools to continue to accelerate team performance. He has already given both Slack and Logentries suggestions on things to do to make the integration even better.

    Based on Kyle’s recommendation I signed up and have set Slack up here for our devopsy.kinsta.cloud team. Being virtual and spread out ChatOps has immediately helped. I set up several different groups so as not to overload the entire team and we are already using it. For ongoing communications it is just so much more efficient than long email threads. It really is a no brainer.

    So if you are not using ChatOps at your company what are you waiting for? Go download Slack for free and give it a try. If you don’t see how it helps please tell me why not.

  • The Business Value in Software Quality

    The Business Value in Software Quality

    Software is taking over the world. You would be hard pressed today to find a company without dedicated software development efforts. But even in traditional business models, this is not confined to line-of-business applications. Organizations now have public, contractor and field team applications—as well as end users. And they must consider the results-focused future of software development and the need for faster, higher quality application releases. This is the business value of software quality.

    (more…)

  • Docker tinkers with Docker Hub for performance improvements

    Docker tinkers with Docker Hub for performance improvements

    Docker’s strengthening its infrastructure components to accommodate the volume of use and wide range of use cases that inevitably crop up from such hockey-stick growth. The latest improvements come by way of refinements made to Docker Hub over the last month, according to an announcement made by the company yesterday.

    The Docker Hub team reported that many of the changes were precipitated by performance issues experienced at the end of 2014, following the addition of security enhancements to prevent brute force login attempts. They reported that the enhancements added “overhead to the login process.”

    “Under normal load there wasn’t much difference, but as the number of login attempts increased the site performance started to degrade,” they wrote. “The decreased performance affected not just the Docker Engine logins, push, and pulls, but also the Docker Hub website as a whole.”

    In the process of identifying immediate issues causing the problem, Docker’s engineers audited the entire system and is in the middle of rearchitecting the authorization, push and pull system to improve performance and isolate systems for a bulkhead effect, ensuring that there aren’t cascading problems.

    In the immediate term, some of the fixes already made include bulking out infrastructure capacity, including a tripling of servers in the Docker cluster for four-times the compute power and a production database upgrade for twenty times the RAM. It also improved login infrastructure to include added database indexes and more caching. The team also tuned queries for speed and fixed an issue that was causing database locks. Docker also switch its background worker queue broker from Redis to RabbitMQ and moved background workers to their own server cluster. Additionally, improvements were made to monitoring and metrics gathering, as well as to search functions.

    Meanwhile, down the line they expect to make further improvements that include API throttling,  breaking up larger services to improve scalability, replacing the brute force prevention library with a better performing library and adding API metrics and monitoring to head off performance issues earlier.

    “We have made some good progress, but we are not finished yet, and we still have a lot more planned,” the Docker Hub team wrote. “We will continue to make improvements with every release, so that Docker Hub only gets faster and more reliable as time goes on.”

    Such hiccups as the ones in December are understandable given the meteoric growth of the Docker community. Even just six months ago, the total number of downloads of Docker were under 3 million. By December that number had risen to 100 million. In spite of some questions about the security of Docker containers, Docker’s trajectory seems promising. Just in September the company closed on $40 million in series C investment from Sequoia and over the past few months it has been announcing a number of high-powered partnerships, including those with VMware, Microsoft and AWS.

    Docker’s most recent partnership was announced last week when it teamed up with Google so that the online giant could offer a private registry service for Docker on its cloud platform. Currently in beta, the Google Container Registry will provide Google cloud customers with secure hosting, sharing and management of private container repositories that will include strong access control and server-side encryption.