Category: Blogs

  • DevOps Chat: Instrumentation with Influx Data’s Evan Kaplan

    DevOps Chat: Instrumentation with Influx Data’s Evan Kaplan

    Evan Kaplan, CEO of Influx Data, is someone who knows his way around the technology world. In a lifetime of experience that has seen him found and manage several successful companies from startups to public entities, Evan has had a great track record of success.

    Influx Data is yet another success for Kaplan. Building on the open source InfluxDB, the company boasts more than 200,000 users of Influx today.

    In this DevOps Chat, Evan and I discuss systems instrumentation today and what big data and velocity means for developers and everyone up the stack. It is a very different world from just 15 or 20 years ago.

    As usual, the streaming audio is immediately below, followed by the transcript of our conversation.

    Transcript

    Alan Shimel: Hey, everyone, it’s Alan Shimel, DevOps.com, and you’re listening to another DevOps Chat. Happy to be joined in this episode of DevOps Chat by, actually, someone who grew up in my neighborhood. We knew each other – well, we didn’t know each other way back when, but we’ve come from a very small area of concentrated – lot of people, you know, we know from that area, but, anyway, Evan Kaplan, CEO of InfluxData and of North Woodmere. Evan, welcome.

    Evan Kaplan: [Laughs] Thanks, Alan. Thanks for having me. Look forward to _____ –

    Shimel: My pleasure. So, Evan, it’s been a long, strange trip from North Woodmere. Why don’t you give our audience a little bit of your background and your journey? And  then we’ll jump into –

    Kaplan: Yeah. Sure. Sure. Very long for me. If those of you don’t know, that’s a suburb of New York City, right near Kennedy Airport, that we both grew up. My strange trip took me to Seattle, where I finished up college and worked as a climbing guide for years. And then worked in aerospace and started a company, the first company to develop SSL-based VPNs, called “Aventail,” back in the mid-90s. _____ through the bubble. Ran a public company called “iPass,” and, about two-and-a-half years ago, met Paul Dix, the founder of Influx. And Paul and I really connected about his vision and what he was doing, and we partnered together to start building Influx from 25 employees back then to north of 100 now. So growing fast.

    Shimel: Good stuff. Good stuff. And, Evan, I’m gonna assume most of our audience has at least heard of InfluxData, but, for those who have or even those who haven’t, just to set the level-set, tell us about what InfluxData does.

    Kaplan: Yeah, so InfluxData is an open-source time-series-based data platform. It’s the leading time-series platform out there. Time-series is the fastest growing market in the database, data category. And so Paul, our founder, spun up Influx back in 20 – I think it was late 2013. It received a lot of accolades on GitHub. It was a very popular project and it has grown dramatically since then, from roughly – I don’t know – 1,000 sites running it to, today, we’re approaching 200,000 sites running it.

    Shimel: Wow.

    Kaplan: And, you know, most of the large Global 2000 is running it somewhere, so.

    Shimel: That’s really impressive, man. That’s something to be proud of. So, Evan, we could probably spend our whole 20 minutes talking generally about Influx DB and what’s happening, but I’m wanted to kinda dive in a little bit and talk specifically today around instrumentation in modern software installs, in the modern software factory. This whole term “modern” has become sort of a catchall buzzword, dog whistle, if you will, for when we talk about  things like Agile and DevOps and serverless and microservices and all of these ways that we’re seeing software being written, managed, and deployed today. So talk to us a little bit about it, if you will, Evan. Where’s your take on this?

    Kaplan: Yeah, so I think we’re – we grew up in the industry, going back a couple of decades ago, the common myth for monitoring or instrumentation of systems was you would buy a package from HP OpenView or CA or a mainframe management package, and you’d buy a monitoring-for-a-service package. They were expensive and they were largely horizontal across the stack, and you’d implement those. And what’s happened over – certainly over the last ten years, during the DevOps revolution, is that stuff has fractured and you’ve seen companies, like Splunk and Elastic and a variety of other folks, arise to handle the modern workloads in an open-source sort of fashion. And now, if you take a look a look at DevOps world, most of solutions are dominated by open-source kinds of models.

    If you look at state of the art now, that people are really paying attention to, the revolution that brought you to logs and log views of stuff and the consolidation of logs has moved much closer to metrics and events. And what I mean by “metrics and events,” the instrumentation of real time of these complex systems. And they’re not just software systems that are DevOps things, so – those are obvious, but they’re also hardware systems; they’re IoT things. And so what’s happening is people wanna see these complex systems and they wanna interact with them in real time because the only way to characterize these systems is to watch them behave in real time. And “observability,” as you know, Alan, has become sort of a keyword here. And observability generally means real time and it means metrics and events; it doesn’t mean verbose logs.

    And so what we’re trying to do is help developers, specifically and, up the chain, architects and CTOs, build instrumentation or telemetry natively into these complex systems, so they can view these things in real time. As you can guess, the data loads with this are absurdly high. You’re talking about hundreds of millions of points a second in some of these systems and you’re talking about to visualize those in near real time, you know, control loops in near real time. And you’re talking about this sort of next generation of, lack of a better way to say it, system instrumentation and management.

    Shimel: Sure. Evan, if I could stop you there for a sec, you know what I find interesting? We’re talking about building this instrumentation and to give people insight and who are we giving insight? Well, you mentioned developers and managers and architects and CTOs, et cetera, but you didn’t mention ops. And is that –

    Kaplan: Yeah. Yeah.

    Shimel: Isn’t that a little bit of, you know – I don’t know if it’s Freudian or if it’s just insight into what today’s world looks like for these things.

    Kaplan: You know, that discrete ops, right? That discrete ops role is changing, right, into what you obviously cover, which is this DevOps. And so our view of how our – uptake of our platform into large corporations, companies like IBM and Cisco and SAP and Tesla and PayPal, has been from developer or DevOps people up. So we tend to think of “Make it super easy for developers, right? Get their time to value down to really, really minimal and then it will rise up and be taken as a complete operational system.” So we tend to think of it from developers up. Not to say the operations guys aren’t relevant – they’re super relevant – it’s just, when we enter into a large opportunity or business or that sort of stuff, it’s usually coming from a developer who figures out he can instrument his code, his service, his offering relatively quickly in Influx.

    Shimel: Got it. And I’ll tell you something I – and it goes back to what you mentioned earlier – the sheer volume and the acceleration of data, right, the – so, no, it’s how much data and the speed that it comes at us. With automation and everything that that brings, it easily outstrips the ability of a human, a lot of times, to stay on top of it, so you almost need to build automation, machine learning, AI into these types of instrumentations, that you bring what the human really needs to see and touch or make a decision on to his attention ’cause so much of it is just whizzing by right now.

    In the last week or two, Evan, I’ve probably had a couple of discussions – trying to think of a friend of mine who – CEO at ScienceLogic and another company called “Ravel Systems”; some friends of mine in security just launched something called “DisruptOps.” And they’re all talking about this term, “AIOps.”

    Kaplan: Yeah. Yeah.

    Shimel: And I’m wondering is this something relevant to what you’re talking about, with instrumentation? Where does that fit in? How do we account for just the big data nature of this?

    Kaplan: Yeah, I think, first of all, absolutely. So, if you think about – so the journey. And let’s call it the end state of all of this is true autonomy, which is very rare and, in fact, almost never the case, right? But, if end goal state is true autonomy, what’s that journey look like? It looks like, first and always and most importantly – and, by the way, the stuff that we skipped a lot, when we were in the early stages of our career – it is, in fact, instrumentation, is telemetry. Telemetry always was an afterthought before whether shipping a product or a service or that sort of stuff. Now the ability to drive that cost of instrumentation down so low that the ability to see what’s going on and create the data – not just see as in “human” see but create the data – has changed dramatically.

    So, if you follow that journey, you go from instrumentation; you go to observability; you go to automation in the form of “I’ve observed these sorts of things, whether it’s through AI capability or not. I built control loops because I’ve observed them, so I’ve built control loops to keep it in a relative stasis. Right? To autonomy.” All of that – the last two steps, right, even the last three steps – involves some form of machine processing of learning, whether it’s machine learning or AI or call it, but all of that gets increasingly sophisticated. But it means taking in, as you sort of articulated, you know, millions, hundreds of millions – in some case, billions – of points per second, right?

    Shimel: Yep.

    Kaplan: Think about it. Now that’s just completely – you know, what a different world, than doing server management with your CA Unicenter product 20 years ago.

    Shimel: [Laughs] To say the least.

    Kaplan: Right?

    Shimel: Yeah, I hear ya. I mean, it really is. If we transported – you know, if we could do that – if we could transport someone from not that long ago, Evan, an hour or _____ _____ –

    Kaplan: No. No.

    Shimel: From 1997, ’98, right? I was helping an early ASP, Interliant. We were building – opening data centers, managing Lotus Notes and PeopleSoft and stuff like that.

    Kaplan: Right.

    Shimel: If I could take a NOC guy from there and show him today’s velocity and the fact that we actually do have telemetry and we actually are building tools that allow us to manage at that level, it would be like taking someone from colonial times and showing them highways with cars. I mean, the supports –

    Kaplan: But, Alan, these solutions are still sitting out there. They’re a huge _____ _____ _____ –

    Shimel: No – well, that’s the scary thing. Yeah, I mentioned my friend, ScienceLogic, my friend Dave Link. He was saying that’s his – you know, and they’ve done very, very well, and his thing was just replacing the Tivolis and the Unicenters and that generation, if you will, of network management, of systems management.

    Kaplan: If I could tell you what, back in the late ’90s, is I was building an ASP also, based on the Aventail, the SSL VPNs, what we were standing on Netcool, back in the day, and things like that, _____ _____ –

    Shimel: And Netcool was a new program, right?

    Kaplan: Yeah.

    Shimel: Before IBM bought it, right? It was one of the cool, new kids at the time.

    Kaplan: Exactly. If I could tell you what somebody could take with Influx today and do, relative to what Netcool did back in the day, and the difference, right – first of all, they could do it for nothing. Forget paid licenses. And the amount of scale, the amount of data collection, and the ease of sort of visualization has dramatically – and all those _____ _____ –

    Shimel: It’s phenomenal. Phenomenal, man. It’s just crazy. So, Evan, let’s bring this back to Influx. How does all of this now manifest itself with your business today?

    Kaplan: Yeah. So that’s right. So we look at our businesses in two segments, right? We look at it as the instrumentation of and the collection of data around software, being the platform of record for this next generation of cloud software. And I don’t have to describe to you is is that, if, in the old days, it was an X Windows terminal talking to a Unix server app, today, there is no “there” there. There’s a virtual network; there’s VMs, containers, and microservices that are growing at exponential rate. The whole infrastructure is ephemeral, so the monitoring and the instrumentation workload has dramatically changed. So one side of our business is really focused on that, that opportunity, and we’d call that the “DevOps chain” of the business, right? Because it comes up into organizations through DevOps folks who bring in Influx and instrument.

    The other side is IoT, which is completely different. So, while DevOps is largely metrics-driven, IoT is largely event _____ driven. And that’s the instrumentation of the physical world, right? So our watches, our clothing, our health care, our cars, our homes, are all being instrumented with sensors. The amount of data pouring in through that is driving whole other systems into business. And, while most of our time was spent on the management of software systems back, now it’s this deep, deep integration of software and hardware. Deep. And so our business breaks out into those two categories, largely.

    Shimel: Got it. Got it. Evan, anything – any new news coming out of Influx you wanna share with our audience or –

    Kaplan: You know, where – we have – you know, we’re almost constantly releasing stuff into the community on a regular basis, so no news that I’d share at this moment. We can touch base in three or four weeks. We have our big InfluxDays event. We’ll make some announcements there, but you can look for us to build increasingly sophisticated solutions that allow people to do their machine-learning workloads, their application tracing, their log and metrics, their asset management, on top of Influx. What we want is people to use us as the platform of record for all of these metrics and events pouring in.

    Shimel: You know, we live in interesting times and I can’t wait to see where this all goes as well, so we’re about out of time, though, here. As I mentioned to you, the 15, 20 minutes goes so quickly.

    Kaplan: Yeah, it really does.

    Shimel: And you barely ever – you know, it is what it is. But, Evan, thanks for joining with us. Evan Kaplan, CEO, InfluxData. You know, so, in three, four weeks, you have your event coming up; maybe we’ll have you back. We can talk a little more about that. We’re doing a big – I didn’t even announce it yet, but I’m gonna announce it right here on the show with you – we’re gonna be doing a big virtual event, December 18th, called “Predict 2019,” and we’re gonna –

    Kaplan: [Laughs]

    Shimel: Yeah. We’re gonna be opening up the crystal ball and asking a lot of pundits and experts and so-called experts what their predictions are for what 2019 has in store. Maybe we can have you back then and we can do some crystal-ball gazing.

    Kaplan: That’d be great, Alan. Always a pleasure. Always a pleasure.

    Shimel: All right, my friend.

    Kaplan: Have a great day. All right.

    Shimel: Well, Evan Kaplan of North Woodmere and InfluxData, thanks for being our guest on this episode of DevOps Chat. This is Alan Shimel for DevOps.com, and you’ve just listened to another DevOps Chat. Have a great day.

    Kaplan: Take care.

    — Alan Shimel

  • Metrics, Logs and Traces: The Golden Triangle of Observability in Monitoring

    Metrics, Logs and Traces: The Golden Triangle of Observability in Monitoring

    It isn’t surprising that the job of monitoring infrastructure and application environments has grown more complex as the underlying technologies evolve. Nor is it surprising that the need to get monitoring right has expanded as our business reliance on IT grows ever deeper, so it is important to have a good grasp of the core tools at your disposal.

    What you might call the golden triangle of observability includes metrics, logs and traces. Each plays a specific role in infrastructure and application monitoring so you need to understand what they bring to the table.

    Metrics

    Metrics probably represents the most valuable of the three monitoring tools because:

    • So many resources are designed to spit out various bits of health and performance information (and there are loads of tools to collect this information).
    • They are efficient.
    • They are frequently generated.
    • They are easily correlated across elements of your infrastructure.

    Everything from operating systems to applications generate metrics which, at the least, are going to include a name, a time stamp and a field to represent some value. Since so many resources come ready to tell us about themselves, metrics is an obvious place to start when it comes to monitoring.

    Most all metrics will enable you to tell if a resource is alive or dead, but if the target is valuable enough you’ll want to be able to ascertain what is actually wrong with the system or going wrong.  As you can imagine, the latter will require detailed information about what is happening inside the system, so called white-box monitoring that relies on internal instrumentation.  The more rudimentary black-box approach draws conclusions about the health of a system based on externally visible indicators (is it responding to any system calls?).

    But perhaps the most important thing to understand about metrics is that last bullet about  being able to correlate metrics across infrastructure components.  Given the complex interdependencies common to IT environments today, the ability to stitch together metrics to get a bigger picture view is a real time saver. And it becomes even more critical as we move to cloud-native environments because of the dynamic nature of cloud  infrastructure and the ever-changing relationship between that infrastructure and the applications.

    An initial challenge of harnessing metrics is the variety of the information available and the number of tools needed to collect and make sense of that information. Then there is the question of how you store data in so many formats from so many resources. But the resultant upside more than makes up for the effort required to figure out how to harness the information.

    It is also worth noting that, given there is no standard API for metric collection, many organizations use agents to collect data that is either pushed to a central location for analysis or pulled by that central resource. Gartner says agents frequently referenced by customers include push agents Collectd and Telegraf, while Prometheus is cited as a tool to pull information from targets.

    Logs

    Logs are perhaps the second most important tool in the monitoring toolbox because virtually everything logs information about what they are doing at any given time. What’s more, logs tend to give more in-depth information about resources than metrics.  So, if metrics showed the resource is dead, logs will help tell you why it died.

    The problem with logs is there can be too much of a good thing. With everything in your environment tracking what they are doing and anxious to share that information, it is easy to see how that could result in a mountain of data. Instead of streamlining the monitoring process, you are simply creating a big new centralized haystack.

    And like metrics, differences in log formats and the abundance of tools available to collect and make sense of logs, complicates the job of getting the most out of this rich trove of material. There are, however, a number of common tools used for collecting logs, such as syslog and open source tools such as Fluentd.

    The trick to getting the most out of these tools is limiting what you collect to keep it manageable, and, where possible, to home in on common fields so you can more easily find the needles in the haystack.

    Traces

    Last but not least in the monitoring triangle is application trace data, which “traces” information about specific application operations. With so many application interdependencies these days, these operations will typically involve hops through multiple services (so called spans).

    Traces, then, add critical visibility into the health of an application end-to-end. They are, however, solely focused on the application layer and provide limited visibility into the health of the underlying infrastructure. So, even if you collect traces, you still need metrics to get the full story of your environment. APM tools feed trace information to a centralized metrics store, so traces provide a nice source of data for an app-centric view.

    The need for the viewpoint that traces can provide is exacerbated in container-based microservice architectures that are nothing more than a collection of stitched together services. These environments can be addressed with something called distributed tracing.

    Do You Need All Three?

    There is obviously overlap among metrics, logs and traces. But the quick answer to the question of whether you need all three types of monitoring tools is, It depends. The simpler your environment and the more tolerant you are of performance degradation and outages, the fewer tools you’ll need to keep things running. Basic metrics will probably work fine for you.

    Conversely, more complex environments that have to be up and running at all times or need to be fixed as quickly as possible will require a mix of tools that answer more than the question of, “Is it broken?” Metrics and logs will be base requirements.

    And finally, if your environment consists of a lot of intricately interwoven pieces, then adding traces will save you effort when it comes to birddogging problems. If you’re not there yet, but see containers and microservices playing a bigger role in your future, you’ll probably want to start getting familiar with trace tools today.

    Keep in mind that each of these tools requires storage considerations. Yes, there are options to support multiple tools from the same repository, but you’ll want to consider those needs as you build out your monitoring repertoire. And ultimately, you’ll want analysis and alerting tools that can span the environments, so keep that in mind as you consider the options.

    Together metrics, logs and traces make up the golden triangle of observability and will help you stay on top of the ever-churning IT world driving business today.

    — Apurva Dave

  • DevOps and Cloud: A Symbiotic Relationship

    DevOps and Cloud: A Symbiotic Relationship

    Most companies want to increase their competitiveness in today’s swiftly changing world, and so they cannot ignore digital transformation. DevOps and cloud computing have become two of the ways companies can achieve this needed transformation, though the relationship between the two is not easily reconciled—DevOps is about the process and process improvement, while  cloud computing is about technology and services. It’s important to understand how the cloud and DevOps work together to help businesses achieve their transformation goals.

    DevOps and Cloud

    Different organizations outline DevOps in different ways. This article does not debate which definition is correct, but rather presents them both to focus on the cloud’s benefit to DevOps. That said, DevOps definitions generally fall into two terms:

    1. In organizations it is defined as developer-friendly operations—IT operations are run separately yet in a way that is much more friendly to developers (e.g., self-service catalogs are provided to developers for stipulating infrastructure or providing technology-enabled pipelines for deploying new code).
    2. DevOps as a single consolidated team is habituated in organizations—developers take on operations responsibilities and vice versa.

    While cloud computing itself has several definitions, the most basic explanation of the cloud is a system that allows the provisioning of infrastructure (e.g., VMs or routers). Thus, it allows to being defined as code or templates, enabling the creation of repeatable processes that are not possible without cloud technologies.

    The aesthetics of cloud technologies and services become so easily amalgamated in DevOps vocabulary because they complement DevOps processes, regardless of how your organization defines them—or, regardless of which DevOps routes you travel to digital transformation with the cloud integration.

    Companies that focus on developers for operations often use cloud computing to speed developer productivity and efficiency. Cloud computing permits developers more control over their own components, resulting in smaller wait times. This application-specific architecture makes it easy for developers to own more components. By using cloud tools and services to automate the process of building, managing and provisioning through the code, service teams speed up the development process, eliminate possible human error and establish repeatability.

    Cloud computing also enables users to create self-service methods for provisioning infrastructure through AWS Service Catalog. Developers are able to quickly try new things, fail fast and just easily succeed in getting new products to market faster, without having to wait for IT operations to provision services for them.

    DevOps as a single term is really a mixture of these approaches, in which developers and operations work together using the cloud as a single common language. In this way, both the DevOps and cloud are able to work together, as everyone is learning new definitions and approaches at the same time. Developers and operations are equally cushy with the new language of the cloud, as developers often teach operations about the code aspect and operations can teach developers about infrastructure and security, developing a meeting point that leads to strong team dynamics.

    No matter the definition, the importance of cloud computing to DevOps can’t be accentuated enough. Cloud computing advances IT transformation, and with advanced tools and automation, it can enable companies to double down on their work to streamline and embed DevOps processes for greater efficiencies that are truly transformative.

    Inherently, as process improvement, DevOps also requires a culture change. Cloud computing can play a role here, as it can help codify and automate new processes. For example, if there is a new way in which developers should cluster the components they need to deliver a service—such as code, configuration, libraries and pipeline definitions—advanced automation tools can streamline the process and make it distinctly repeatable.

    The business case for DevOps combined with cloud technology for a successful IT transformation is fivefold:

    1. Bring products to market faster through faster access to development environments and streamlined developer processes.
    2. Automation and architecture as code reduce cloud complexity and even system maintenance.
    3. Add high security with automated, repeatable processes that serve to eliminate inaccurate error and, even more importantly, develop security controls from the very beginning.
    4. Reduce downtime through cloud-based continuous operations. Moreover, in the process of applying automation, developers can build stateless cloud application development, which increases availability and failover ability, in the process increasing business reliability and customer satisfaction.
    5. Increase scalability. One of the main reasons organizations look to cloud computing in the first place is its scalability, which allows organizations to increase capacity with the click of a button. When combined with DevOps, scalability becomes an integral part of applications as they are developed, while reducing the cost of infrastructure and increasing global reach.

    Get Past the Changes

    Together, DevOps and cloud computing are a powerhouse. While each offers greater effectiveness and business impact, together they are able to drive meaningful IT transformation that directly impacts business goals, regardless of the DevOps definition.

    At the same time, culture within the enterprise and among developers must change around the nuances of DevOps and its role in driving cloud development. Finally, IT companies must invest in these technologies and do so without an immediate goal—which, of course, drives corporate leaders and shareholders crazy.

    However, the alternative is doing nothing, which means certain failure. Competitors are likely to pull ahead in terms of time-to-market with solutions and application services. When you can hold up applications and processes in near real-time and do so within an elastic and efficient environment, the market will reward you for putting that effort. If you haven’t commenced on the process yet, it’s time to get started.

    — Jaymin Vyas

  • DataOps: DevOps Plus Big Data

    DataOps: DevOps Plus Big Data

    In traditional DevOps, there are the complimentary forms of development operations (that I call DEVops), and development operations (that I like to call devOPS). Between them they automate the toolchain and bring the people working on getting an application out to users onto the same team—not necessarily the same organizational team, but using their strengths in tandem to meet the needs of the business.

    DataOps is an interesting extension of DevOps. You still need all of the coding side to get data into the system and queries consistently maintained. You still need all of the operations side to get your database/noSQL/whatever up and running. In fact, while the development side in a DataOps environment might be (but isn’t necessarily) lighter, the operations side is almost always more complex. No matter the big data engine in use, it is a complex system in addition to other supported systems in a normal environment. My first installation of a big data environment (Cloudera, as it happens) was a weeks-long learning voyage. Only after I’d completed it did I use an automation tool (which is no longer available) to make it easy. My second round was hours … But it assumed the knowledge I had gained in the first attempt.

    The other bit of DevOps—ongoing monitoring and management—is also more complex in a big data environment, but we’ll come back to that in a moment.

    Once the normal DevOps systems are in place, ETL/data import tools will need to be supported also. The volume that these tools crunch through in a day makes their inclusion in DevOps in a data-heavy environment critical. If the data uptake is slow or the data itself inaccurate, there is an impact on the organization. This step also requires inclusion of data scientists, people who traditionally have not been pulled into the DevOps model. But they are the ones that can gauge the accuracy of data, and normally are responsible for data acquisition anyway.

    Which brings us to the monitoring and management stage of DataOps. Normally when we talk monitoring and management in DevOps, we are talking about tools that ultimately help with things like availability, responsiveness, auto-scaling and recovery. DataOps needs all of these things, like any other application does. And we’ve already mentioned that it has a complex environment embedded in your complex environment. But it also (some would argue more importantly) needs data monitoring. A knowledge of the state of the data is imperative. Whether from a piece of code gone wrong or data poisoning, monitoring the health of big data archives is essential to keep results from getting out of whack. This monitoring will again involve the people who know the data—data scientists by whatever title. This iterative process will need to run relatively constantly, checking on whatever makes the data valuable, normally using cross-field checks to verify that data hasn’t somehow been corrupted, or comparing trending averages to current average to monitor for sudden swings in results.

    Of course, for a system (and in research there are many) that spins up, finds results and spins down, the monitoring part is less essential, but for anything that keeps accessing and adding to the data pool, it is the key to a healthy application or application portfolio based upon the dataset.

    If all that sounds a bit intimidating, you’re not alone. The phrase “DataOps” has been around for a few years, and while data scientists use it, it hasn’t yet gained serious traction in the enterprise. Here’s how I would approach it as CIO: Given that DevOps is running on other projects, that is the low-hanging fruit. Given the rate of change for servers (as queries—particularly long-running ones—increase and decrease, systems needs change is one example), traditional DevOps is a greater benefit to big data than many other corporate systems. So roll out DevOps first without serious concern for DataOps beyond how DevOps impacts ETL—not ETL data quality, but ETL data availability/performance. Only when the system and the team are in place and the software/hardware/code part of the overall system is fully in a DevOps environment, start looking at ways to move data into it. Data monitoring will be the big one, but ETL under the initial round of DevOps implementation will have shown places it could be improved and ETL data integrity can be added, so improving those areas also. A measured, step-by-step approach that builds off of organizational experience is key here. Data monitoring and management will require different tools than normal DevOps monitoring and management, so having the data scientists look into available toolsets and how they mesh with existing tools early on will help with eventual implementation.

    Make no mistake, it is a big job, moving large data driven environments to DevOps. But the benefits are increased awareness of data quality and data quality issues, along with more responsive systems and teams that DevOps offers every business application. The amount of data available to any give organization is currently on a massive increase as IoT, open datasets, partnerships and ML drive greater pools. It is worth getting the automation and cooperation of DataOps into the mix as early as possible.

    — Don Macvittie

  • Cost Per IT Ticket: Think Beyond Opex in Your Cloud Journey

    Cost Per IT Ticket: Think Beyond Opex in Your Cloud Journey

     Globally, organizations have embraced cloud computing and delivery models for their numerous advantages. Gartner predicts  the public cloud market is expected to grow 21.4 percent by the end of 2018, from $153.5 billion in 2017. Cloud computing services provide an opportunity for organizations to consume specific services with delivery models that are most appropriate for them. They help increase the business velocity and reduce the capital expenditure by converting it into operating expenditure.

    Capex to Opex Structure

    Capital expenditure refers to the money spent in purchasing hardware and in building and managing in-house IT infrastructure. With cloud computing, it is easy to access the entire storage and network infrastructure from a data center without any in-house infrastructure requirements. Cloud service providers also offer the required hardware infrastructure and resource provisioning as per business requirements. Resources can be consumed according to the need of the hour. Cloud computing also offers flexibility and scalability as per business demands.

    All these factors help organizations move from a fixed cost structure for capital expenditure to a variable cost structure for the operating expenditure.

    Cost of Assets and IT Service Management

    After moving to a variable cost structure, organizations must look at the components of its cost structure. They include the cost of assets and the cost of service or cost of IT service management. Cost of assets show a considerable reduction after moving the entire infrastructure or assets to cloud. The cost of service remains vital as it depends on the day-to-day IT operations and represents the day-after-cloud scenario. The leverage of cloud computing can only be realized if the cost of IT service management is brought down.

    Growing ITSM or ITOPs Market and High Stakes

    While IT service management (ITSM) has taken a new avatar as IT operations management (ITOM), incident management remains the critical IT support process in every organization. The incident response market is expanding rapidly as more enterprises are moving to cloud every year. According to Markets and Markets, the incident response market is expected to grow to $33.76 billion by the year 2023 from $ 13.38 billion in 2018. The key factors that drive the incident response market are heavy financial losses post incident occurrence, rise in security breaches targeting enterprises and compliance requirements such as the EU’s General Data Protection Regulation (GDPR).

    Service fallout or service degradation can impact key business operations. A survey conducted by ITIC indicates that 33 percent of enterprises reported that one hour of downtime could cost them $1 million to more than $5 million.

    Cost per IT Ticket: The Least Common Denominator of Cost of ITSM

    As organizations have high stakes in ensuring that business services run smooth, IT ops teams have additional responsibility in responding to incidents faster without compromising on the quality of service. The two important metrics for any incident management process are 1) cost per IT ticket and 2) mean time to resolution (MTTR). While cost per ticket impacts the overall operating expenditure, MTTR impacts customer satisfaction. The higher the MTTR, the more time it takes to resolve the tickets and, hence, the lower customer satisfaction.

    Cost per ticket is the total monthly operating expenditure of the IT ops team (IT service desk) divided by its monthly ticket volume. According to an HDI study, the average cost per service desk ticket in North America is $15.56. Cost per ticket increases as the ticket gets escalated and moves up the life cycle. For an L3 ticket, the average cost per ticket in North America is about $80-$100+.

    Severity vs. Volume of IT Tickets

    With our experience in managing the cloud IT ops for our clients, we understand that organizations normally look at the volume and severity of IT tickets. They target the High Severity and High Volume quadrants to reduce the cost of the tickets. However, with our experience, we strongly feel that organizations should start their journey with the low hanging fruits such as the Low Severity tickets, which are repeatable in nature and can be automated using bots.

    In the next blog, we will elaborate on this approach that can help organizations in measuring and reducing the cost of IT tickets.

    — Neeraj Deuskar

  • IBM Survey: Rise of Multi-Cloud Computing to Force DevOps Issue

    IBM Survey: Rise of Multi-Cloud Computing to Force DevOps Issue

    A survey of 1,106 business and technology executives published this week by the IBM Institute for Business Value finds 85 percent of companies are already operating in multi-cloud environments, with 98 percent forecasting they will be using multiple hybrid clouds within three years. But the survey finds that only 39 percent of the respondents have implemented some level of DevOps processes to help streamline the management of multiple cloud computing platforms.

    Blaine Dolph, vice president of Global Business Services for IBM, said it’s clear that DevOps will play a critical role in enabling IT organizations to centralize the management of multiple clouds. But the IBM survey suggests that the management of multiple clouds within organizations is not nearly as efficient as it should be.

    Only 41 percent of survey respondents said they currently have a multi-cloud management strategy in place, and just 38 percent have the procedures and tools in place to operate a multi-cloud environment. Only 30 percent of enterprises have a multi-cloud orchestrator or other multi-cloud management platform to choreograph workloads, while fewer than 40 percent of organizations have cloud configuration management tools that provide information about resource configuration and relationships between resources, the survey found.

    All told, the IBM survey is only able to identify 20 percent of respondents as “multi-cloud maestros” capable of employing multiple clouds to smoothly and routinely deliver one or more business functions. The survey found almost two-thirds of multi- cloud maestros report they employ cloud management platforms.

    The survey also found that multi-cloud maestros are advanced in terms of adoption of microservices and containers. A full 61 percent of multi-cloud maestros predicted that within three years at least 80 percent of new applications will be developed using containers. Currently, 50 percent of multi-cloud maestros are using Docker containers and 63 percent are using containers as a service (CaaS). By 2021, 65 percent expect to use container orchestration. More than half (56 percent) of the multi-cloud maestros are already microservices and 59 percent plan to use serverless cloud services in their cloud environments, according to the survey results.

    Dolph said IT organizations in general would be well-advised to focus on more than just “lifting and shifting” applications into the cloud. They may need to leverage Docker containers to move an application into the cloud. But once there, an effort should be made to modernize that application by turning large swaths of it into a set of microservices that ultimately are easier to maintain and consume by developers building complementary applications, he said.

    The IBM survey makes it apparent that multiple clouds are the new IT normal. Almost half of respondents said they are establishing a multi-cloud architecture to develop new and enhanced products and services. A total of 62 percent of respondents require multiple clouds to create innovative business models, while 52 percent said they need them to produce new revenue streams. Sixty-six percent need them to enhance margin and 46 percent said they need a multi-cloud environment to support agile business processes.

    From a DevOps perspective, more than half (51 percent) of respondents use multiple clouds to cultivate a flexible, modular infrastructure that quickly absorbs and leverages technological advances.

    Obviously, one of the great paradoxes of multi-cloud computing is that in the pursuit of becoming more agile, many organizations are making their IT environments more complex by employing multiple platforms. The challenge they will face next is maturing their DevOps processes to the point where some order is finally brought to that multi-cloud computing chaos.

    — Mike Vizard

  • The Benefits of Test-driven Development

    The Benefits of Test-driven Development

    It sounds like an oxymoron: Create test cases before coding. In the process of writing and using test cases before writing functionality, a developer can produce higher-quality software. That is the concept behind test-driven development (TDD), and it works.

    TDD Snapshot

    TDD has been around since at least 1999, and it is part of the emerging test-first approach to development associated with extreme programming. In 2003, American software developer Kent Beck “rediscovered” TDD and applied it as a way to create simple designs and inspire developer confidence. Fast forward to today’s agile development world, TDD is a software development process using a very short feedback loop in which developers do the following:

    1. Create a test that will fail immediately.
    2. Write the necessary code to pass the test as quickly as possible.
    3. Refactor the code written in step two, using the created test as a reference.

    TDD Benefits

    So why might a long-in-the-tooth software development approach have tangible benefits in an agile development world? Because put in its simplest terms, TDD is a way to develop highly usable software.

    Following the TDD process, a developer must focus on the test cases before actually coding anything. That meansa developer is thinking more about the use of the software and the design of user interfaces to achieve that. As a result, the developer is more interested in the interface than in the implementation—and that leads to more usable software.

    There are several other tangible benefits for taking a TDD approach, including:

    • Creating a metric for the code quality that can be easy and quick.
    • Allowing for a quick visualization to determine if the code base has any functional issues.
    • Living documentation of functionality with new code written.
    • Allowing for safe refactors of code, whether based on attempts to improve code quality or a changed requirement.

    That final point is worth dwelling on for a moment. The TDD approach requires that the evolving code base is cleaned up frequently so that new tests and code are easy to introduce. That usually means that code moves from its current place to where it more logically belongs in the software. That has the effect of reducing any extraneous duplication of code and enforces a strong discipline around objects, classes, modules, etc. In this way, the overall maintainability of the software increases incrementally.

    The improvement in readability and maintainability will pay huge dividends during the expected life cycle of the software. Following a TDD methodology requires developers to focus on writing smaller units of testable code. By following the TDD methodology, this leads to more modularized, flexible and extensible software.

    Where Can TDD Fit?

    A TDD approach is appropriate for both new greenfield software and legacy systems. For a development team that has to deal with existing legacy software, the key is to start small and begin with working on bug fixes. A good practice is that for each bug reported, create a test that addresses the broken bug and then fix the functionality. After several iterations of this, the development team has created a repeatable working test to address bug fixes. When applying this methodology to new software applications, make a point of understanding the testing tools used for the technology stack.

    For example, when working in an Angular application that generally uses the Jasmine testing framework for unit testing, and when using the Angular CLI for creation, unit tests are created alongside modules of code. Using a TDD methodology, the approach would be to:

    1. Determine a portion of the functionality to be created with this component.
    2. Create a unit test that will fail immediately targeting this portion of functionality.
    3. Run the test runner to confirm the failing test (it may be useful here to leave the test runner on to run after each source file save, which speeds the process).
    4. Write code in the Angular component that will make the written test pass.
    5. Make any refactoring changes for the Angular component after confirming passing, using the test as a guideline to ensure code refactoring does not break functionality.

    Measuring Testability with Code Coverage

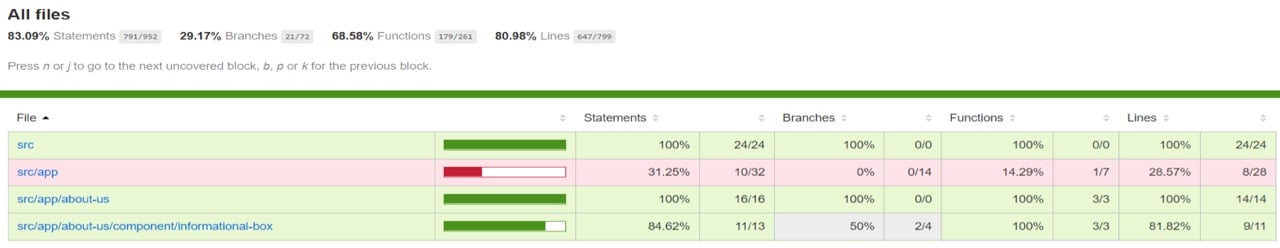
    Another essential consideration when improving testability in code is to use a code coverage tool. Code coverage is a metric to show the percentage of code that has a unit test written for it. Angular applications use Istanbul to calculate code coverage through the application. Running a single run of code coverage in an existing project gives the following output:

    The output provided by Istanbul gives a metric on the overall test coverage and the areas of code that need improvement in testing. Code coverage can be useful in a few ways:
    • Provides an idea of the overall testability, allowing for a threshold to ensure the total software testability does not drop past a certain point.
    • Identifies areas in the code base with poor testing, making them opportunities for refactoring.

    However, as effective as code coverage can sound, it’s important to understand that it’s just a metric. Writing good unit tests is a matter of following what the code will do, and metrics such as these should not drive significant decisions.

    Considerations When Using TDD

    It’s important to note that TDD does not solve all problems. There are many different types of testing required to create a fully comprehensive testing strategy, including acceptance testing. In TDD, the focus is on a single unit of code at a time. A sophisticated software application may have many thousands of units of code and their corresponding tests. That’s why it’s critical to make sure that testing quality stays high when following the TDD methodology. Tests cannot become something bypassed in the pursuit of more functionality or expediency. Avoiding testing generates the risk of test creation becoming a hindrance for developers.

    For example, ignoring failing tests makes it difficult to determine the actual state of the application. It’s also important to have buy-in for a TDD approach form all the teams involved in the effort. Buy-in is particularly true on the business side. Time must be spent up front discussing the nature and benefits of a TDD approach, and the belief that using TDD will improve the resulting software. Otherwise, business management sees writing tests as an activity that doesn’t contribute to the bottom line.

    Conclusion

    TDD emphasizes the importance of an effective and sustainable testing approach. TDD also contributes directly to the overall quality of software. It’s a truism for small or large system development that often goes missing in the day-to-day hustle to get new functionality into production. Quality software gets built when there’s an acknowledgment that quality test code should receive the same amount of attention and resources as quality production code, as they are equally essential in development.

    — Dave Farinelli

  • Log Management: What DevOps Teams Need to Know

    Log Management: What DevOps Teams Need to Know

    One of the most important shifts of this decade is the rise of interconnected data across distributed systems. This explosive growth not only sparked the need to rethink cloud and global IT strategies, but it also disrupted traditional development, DevOps and ITOps practices. These changes are pushing requirements for higher-velocity development of features and products—together with more responsive support requests—onto technology professionals. These new requirements have prompted teams to evaluate new tools and agile processes that help support the needs of a competitive modern business.

    Regardless of the pace of change within your group, basic functions such as infrastructure monitoring are crucial to operating production applications. At this new speed of business, concepts such as observability are important for enabling successful deployments with fewer user interruptions—not only in production, but also in the early stages of your continuous integration/continuous delivery (CI/CD) pipeline. As part of “shifting left,” log and event management in your CI/CD pipeline empowers developers to monitor and observe application behavior before releasing it to production. While some might say this adds additional layers of process, time, effort and due diligence in dev environments, it can help you evolve your organization’s fundamental software development behaviors while reducing preventable issues from post-deployment into production. It can create a smoother, more seamless user experience and reduce the need to fight fires or rearchitect your solution after the application is live in production and at scale.

    Setting the Testing and Dev Stage

    The rapidly evolving technology landscape has increased the need for log management and observability across distributed systems and containers. Changes to how applications and services are created, the ability to deploy applications across combinations of global logging-as-a-service (LaaS) providers and the pervasiveness and volatile lifespan of containers, along with the capacity to build services using various development languages, has increased the need to collect, monitor and trace data points across connected systems, which provide critical end user-facing value.

    Traditionally, many considered log management a tedious task because each instance of a new server required you to run a search command across the logs local to that server. That approach isn’t scalable when every cluster of more than 20 servers is built up in minutes, and each application has independent logging formats. In this scenario, you’d need to run 20 individual searches across multiple systems, compare timestamps across servers residing in different time zones and so forth. With the decreasing cost and increasing prevalence of containers and virtual systems, the number of systems running within a typical organization has grown exponentially as the business prospers.

    In addition to increased usage of virtual systems and containers, independent scrum teams of developers can build in parallel using technologies which are the best fit for the services they are producing, while also sharing environments for builds, staging and production. With these distributed services, aggregated log systems can quickly determine the root cause for debugging their application’s errors, exceptions or performance bottlenecks. A log aggregation system can reduce the element of “personalization” that can often happen when developers are using different technologies with various logging formats, and also reduces the noise by filtering out information that delays the team’s ability to find the source issue. This can cause confusion or slowed productivity when one developer is left to understand another’s non-standardized, yet shared, workload.

    The reduced cost, increased collaboration and prevalence of container services are collectively driving an uptick in virtual environments and containers, often requiring more logs to be created in testing and dev environments, which can force organizational shifts to enable full observability across their infrastructure.

    The 3 Pillars of Observability

    Businesses are in the midst of a shift toward adopting these principles—the three pillars of observability—and using a three-pronged method of monitoring that takes data from several vantage points to depict a more accurate and consumable view of overall health and stability:

    1. External Monitoring: An example of this is health checks run against your internal and external applications and websites to see the “digital experience” of your users.
    2. Metrics and Distributed Tracing: This enables you to trace communications between applications distributed across systems/containers to identify errors and exceptions from your applications and resolve latency quickly.
    3. Events and Logs: Data, which helps provide contextual information about events, enables you to identify issues in the code when combined with information from the first two pillars.

    The above types of information are critical to DevOps to provide elastic and resilient services. Bringing application, system and infrastructure events into logs together with external monitoring and metric collection is quickly becoming the standard. With powerful log-parsing features such as live-tail search accessible from a web browser and the ability to visually pair log insights with added health metrics, the real value of log data is made apparent with little effort.

    Site reliability engineering (SRE) is another area where significant evolution has occurred. ITOps has always been asked to react to fire and run from fire to fire. The evolution from ITOps to DevOps to SRE is forcing the alignment of different types of data to be used very early in a CI/CD pipeline, and enabling SRE teams to get involved in architectural discussion at project inception instead of in the latter stages or at release. The SRE is more involved in monitoring, understanding the development and architectural principles used to develop application services and build in automation, and high availability and circuit breaker patterns from inception.

    This approach has allowed teams to be proactive and responsive rather than reactive. It has equipped our teams (which keep our business running successfully and our customers loving what we do) with the ability to focus on being scalable, elastic and resilient. Instead of troubleshooting systems in production, we auto-scale and replace to minimize disruptions and investigate that incident offline when possible.

    Best Practices

    Given the increasing pace of application development required to support the needs of the business, the spread of containerized applications and virtual environments and the emergence of new disciplines for observability (due to the lowered costs and increased reliability), log and event management has become a critical aspect for all involved in building, supporting and even using mission-critical applications. It’s moving to a defined area where logs should be compartmentalized, and access control should be defined:

    1. Compartmentalizing Logs: Critical as a best practice so we can differentiate development, staging and production environments and segregate logs based on practical grouping. Using a log aggregation service provides you with a consistent experience and a common set of capabilities across all your environments.
    2. Access Control: Another best practice that should be implemented more broadly; for example, developers don’t need access to all of your production logs if approximately 95 percent of their work happens prior to reaching production environment. In other words, even though tech pros are working to “de-silo” log management, we still want to silo access control and manage visibility. This can also help to ensure personally identifiable data (PII) isn’t exposed to anyone it shouldn’t be.

    Looking Toward the Future of Log Management

    As the landscape evolves and best practices become more defined, we should expect revitalized strategies with elevated expectations for the traditional scenarios where basic/free monitoring is leveraged. While the pillars of observability are leveraged more broadly in the ITOps and DevOps communities, we’ll be able to move more efficiently from an end user-facing incident—for example, an application error traced across distributed systems—straight into the logs to find the specific error causing the issue. We’ll be able to see greater correlation between logs and other custom metrics, as well as much broader use of these techniques outside of production environments.

    DevOps teams need an intuitive event and log management system that is as de-siloed as we are. No longer can log management systems be relegated just to one on-premises storage system or one virtual environment; they need to fit the reality of how work is increasingly done today and will be in the future.

    — Keith Kuchler

  • 5 Tips for Creating Blockchain IOS and Android Apps

    5 Tips for Creating Blockchain IOS and Android Apps

    Blockchain development and blockchain technology are playing a major role in the creation of various iOS and Android apps. Blockchain technology has seized the attention of many and when it is utilized properly, mobile app developers are able to achieve results that few thought possible.

    There are no shortage of benefits provided by blockchain development. Data security levels are increased and unnecessary intermediates are removed from the process. Financial organizations have been taking an increased level of interest in blockchain technology in recent years and this creates added opportunities for app developers.

    So, how can app developers properly capitalize on the opportunities that are created by blockchain technology and blockchain development? This guide is here to help. Here are some tips and pointers that are designed to help developers create iOS and Android apps that take advantage of blockchain technology and blockchain development.

    Focus on the Interface

    Blockchain development can be used to create all sorts of valuable iOS and Android apps, but for these apps to reach their full potential, developers must remain focused on the interface. Not considering the user’s experience during the development process could lessen the level of impact of the app.

    Is the front-end programming language operational? Is the blockchain application that is necessary for operating this language included? Has the developer considered the importance of an external database? Is the right application control being included during the development process?

    These are all questions that need to be answered so the app developer can create a quality design for the user interface. Identifying the proper analytics is also crucial. Otherwise, it becomes more difficult for developers to identify the right system. Building an admin console is a key step of the process as well.

    Take a Closer Look at the Importance of Architecture

    If a blockchain app is being created to be used on an iPhone or Android device, developers must take a closer look at the design architecture so that they can avoid common mistakes. Unfortunately, many aspects aren’t always considered, and they often involve additional processes that can add extra time to the process.

    For example, those who are planning on creating a hybrid app will need to obtain certain permissions first. The more developers know about the necessary parameters that have been established, the better their chances of creating an app that will be useful to those who rely on blockchain technology daily.

    The processors, size, memory and operational systems must be configured properly, and these configurations all fall under the architectural umbrella. Great design is crucial, and app developers who aren’t willing to consider the most vital components will come up short when it comes to their design architecture.

    Proper Platform Utilization

    An app that relies on blockchain development and technology needs the proper platform to be successful. This platform should be unique yet accessible. When issues come to the forefront (and they are going to, despite your best efforts), developers’ ability to solve these problems will be determined by the chosen platform.

    For issues to be solved, a consensus must be reached, which is easier when the correct platform has been selected. Now that more platforms are openly sourced, this makes life much easier—developers have the chance to select the platform that best aligns with all of their needs and desires.

    Whether a developer decides to choose Ethereum, Quorum or a different platform entirely, it behooves them to take the time to study the advantages and disadvantages of each, especially when blockchain technology is being utilized.

    Recognizing the Importance of Consensus Mechanisms

    Is the application being decentralized? This is one of the main questions that must be answered before this process can be completed. An iOS or Android app that is reliant on blockchain needs a consensus mechanism to work in the proper manner once it has launched.

    Without decentralization and a consensus mechanism, many of the typical problems and issues that arise are not as easy to solve. The system used to connect and provide a link needs a proper consensus. Without a consensus mechanism, the system’s ability to carry out all of the necessary tasks is severely compromised.

    Apps that are related to blockchain must be developed with the right approach. Are the necessary considerations being made? Is the best method being chosen for delivering proofs? Are the basic requirements being met when these proofs are delivered? A developer looking to take advantage of the current climate needs to be able to answer all of these questions.

    Identification of Objectives

    Last but certainly not least, developers must identify their objectives. What is the goal they are trying to accomplish by creating this app? What role is blockchain technology going to play? Are all of the necessary blockchain development principles being adhered to? Is the issue that is going to be solved being made perfectly clear?

    Answering these questions in a timely manner allows a developer to decide on the correct course of action. The same rules that apply during the creation of any other app still come into play when blockchain apps are being developed for iOS and Android users. The problem that is being solved by the creation of the app must be clearly defined.

    Are the issues being caused by data loss? What resources are being provided that were not previously available? To get the most out of the development process, the issues and the associated goals must be examined closely.

    — Harnil Oza

  • DevSecOps: Critical in Building the Bank of the Future

    DevSecOps: Critical in Building the Bank of the Future

    It is no secret that change in a large organization can be difficult. This is often true within banking, an industry that often has sought predictably instead of agility in software delivery. However, with the right tools, guidance and teams, creating a bank that can be both complaint and responsive may be more attainable than initially it may seem. For a digital bank of the future to emerge from a heritage of independent application, information security and operations departments, an organization should embrace new technologies that can unify these groups and improve the ability to respond to change more quickly.

    Read on to learn why the inclusion of information security within DevOps practices can play a key role in establishing a bank of the future, and why it is important.

    Digital-Only Banks Gaining Ground

    One of the shifts in the distribution of banking products is the movement from primarily branch-based banks to digital-only banks. In fact, Citizens Financial Group launched a digital-only bank in July of 2018 to appeal to a growing number of digital-first customers. JPMorgan Chase also has a new digital banking offering, Finn, aimed at millennial customers.

    While digital-only is meant to simplify the end user experience, it complicates security because it increases the number of attack vectors within the digital channel. In effect, bank security is judged not by how well physical transactions are protected within the branch (think bank notes and checks), but how well digital transactions are protected over the internet. This can require a commitment of applying security controls while also honoring agile delivery practices. In turn, this developmental agility can be more effective when it is part of a responsive organization—one that is willing to adapt and adjust quickly, often requiring institutional culture change to an organization that is more transparent, open and ultimately innovative.

    Incorporating Security from the Get-Go

    To be more responsive while at the same time hardening security, adapting to DevSecOps methods is becoming important in the journey to be a bank of the future. DevOps should never be only about the development (Dev) build and operations (Ops) implementation—it should have security in the middle (Sec). Information security should play an integrated role in the full life cycle of apps. DevSecOps can remove the isolation and boundaries that previously existed between the security team and the rest of the organization, and it brings security smack dab into the conversation, rather than as a part of a deployment checklist. With service level expectations from release cycles going faster—from months to weeks or even days—integrating and automated security into the delivery process can be even more critical. In a DevSecOps application methodology, digital bank initiatives would build security into every touch point from the very start.

    How is Information Security Evolving in Banking?

    Banking, like all other aspects of our lives, seems, to be  transitioning to a smartphone transaction. Deposit and savings accounts can now be fully opened and closed through the digital channel. Information is exchanged digitally and the process is often painless. Information security becomes even more critical to help make  information safe and secure from potential fraudsters.  So while these types of transactions are often expected by consumers, it is important to have proper security measures in place and that can be fully automated and throughout the development process.

    The Organizational Change to Embrace the Future of Banking

    The future of banking will not happen exclusively just by changing technology and tools. It can often be successful when it is adapting organizational change at the same pace as technology and Agile best practices, such as DevSecOps, can also be applied to cultural transitions. To prepare organizations to be successful, there should be clear commitment by leadership across applications, operations and information security; otherwise, the change may never be fully absorbed into the organization. The bank of the future will be more likely to be successful if it functions as part of an ecosystem of interdependent and more securely connected people, processes and technology to have the structural support in place to successfully engage.

    — Eric Marts