Category: Features

  • Could Full-Stack Observability Help Lessen IT’s Burden?

    Could Full-Stack Observability Help Lessen IT’s Burden?

    The year 2020 was a landmark year for many reasons, other than the obvious. The IT world saw the first time that cloud service revenues dwarfed spending on data centers. Across the board, budgets have been increasing around cloud adoption. And in this ‘new normal,’ digital experiences are slated to remain just as crucial of a touchpoint as ever. In fact, new findings show that for 85% of users, digital applications are absolutely essential to their daily lives.

    Rising digital demands mean reliance on the cloud is here to stay. But if organizations don’t right-size their cloud workloads, expenses could get out of control. Plus, maintaining world-class user experiences requires a keen insight into the overall performance of apps, systems and solutions. If teams aren’t continually monitoring application performance and business KPIs, the bottom line could suffer.

    I recently met with Joe Byrne, AppDynamics Regional CTO, to discover what full-stack observability (FSO) means for today’s cloud-heavy applications. According to Byrne, DevOps and SRE teams should be maintaining a holistic view of the entire pulse of the application—including non-functional metrics (NFM) alongside traditional security and functional monitoring. Doing so could reduce time spent on root cause analysis and help ensure code is continually meeting business objectives.

    What is Full-Stack Observability (FSO)?

    In the classic definition, observability focuses on measuring the internal status of a system based on external outputs. Application performance monitoring (APM) typically tracks telemetry around logs, metrics and dependencies. IBM, for example, calls the observability trend “a natural evolution of APM data collection methods.”

    Full-stack observability (FSO), said Byrne, takes this one step further to track business-related key performance indicators (KPIs) alongside additional, more traditional software metrics. “FSO helps understand that software is performing optimally and that it is meeting business objectives,” said Byrne. In this way, FSO takes a holistic view to determine not only if an application is functionally sound but if it’s meeting its end goals.

    FSO would consider critical performance actions, such as user experience telemetry. For example, Byrne explains, an e-commerce website could find value in tracking performance levels such as login time, check out time and payment initiation. Tracking such metrics is necessary to pinpoint roadblocks and create actionable steps to remediate holes in the user journey, said Byrne. Increased visibility here could also help engineers quickly respond to issues to better optimize the user experience. In addition, aggregating information at a higher level—to view total products sold per day or total revenue per day, for instance—could inform overall progress.

    How FSO Could Reduce IT Stress

    “We’ve reached a point where people have moved away from brick and mortar and are going online,” said Byrne. These online spaces are more omnipresent — and valuable — than ever. The AppDynamics 2021 App Attention Index found that the average digital consumer uses 42 applications daily. Furthermore, 85% of people now say digital services are a critical part of how they get by in life.

    Mounting digital reliance has resulted in rising digital complexity. Therefore, said Byrne, companies have been moving to the cloud for the ease of scalability, elasticity and the capability of cloud functions. Cloud-native abilities like serverless, Kubernetes, identity and access management (IAM) and other add-on services are helpful perks to avoid reinventing the wheel.

    But of course, lifting and shifting all your current architecture to the cloud is costly; plus, it won’t necessarily eliminate application bugs. The user journey is increasingly vast, and broken touchpoints along the way could hinder performance. This is complicated by increasing third-party dependencies. Yet, more often than not, it is the application’s custom code that is having the issue, explained Byrne.

    Perhaps the most significant benefit of full-stack observability is a reduction of remediation time. “If you don’t have perspective, it can take a long time to run down an issue,” said Byrne. “The cost of finding a root cause can be so expensive.” Having a quick window into network, application and infrastructure hiccups is necessary to quickly address issues and save potentially lost revenue.

    Shifting Performance Monitoring Left

    An Amazon study found that every 100ms of latency costs companies a 1% loss in sales. Knowing the reality of high user expectations, software companies must be especially proactive in how they scale to meet the needs of consumers. As 72% of users believe application problems are the brand’s responsibility, the onus is on companies to avoid negative brand reputation.

    To spot performance hangups early on, Byrne encourages a shift-left attitude toward observability around business outcomes. To date, the shift-left mantra has focused more on code validation and security—necessary elements to rapidly deploy software updates. Now, adding performance testing could be the next iteration to further correlate each software push with end business outcomes.

    “You want to see and validate as much as possible before production,” said Byrne. “Performance testing is a key piece in the overall success of an application.”

    This could involve testing the load time for a specific endpoint—if a key action doesn’t meet a certain threshold, then it would not be promoted. Incorporating performance monitoring within a CI/CD process is a burgeoning practice also referred to as BizDevSecOps.

    There’s No Going Back

    The new normal is upon us, and it’s hard to imagine going back to any semblance of a world where there’s a decreased reliance on technology. From airline bookings to banking and grocery orders—software applications are now intrinsic to nearly every facet of modern life. To compete in such an economy, finely-tuned modular customer experiences that continually optimize business outcomes will truly set companies apart from the rest.

    In short, to maintain high software standards, it’s essential to break down operational silos and work together as a team—the DevOps creed. End-to-end ecosystem visibility could help enable that, ensuring, in Byrne’s words, that “applications perform in a way that meets the needs of the business.”

  • Swinging the Pendulum of IT Back to QA

    Swinging the Pendulum of IT Back to QA

    I was reading Nuria Manuel’s excellent article about quality assurance (QA), and it got me thinking about the wide variety of ‘pendulums’ that impact IT. I call them pendulums because they follow the rule of “every action has an equal and opposite reaction,” and they work on fundamental truths of IT. For example, the one that has probably been going on the longest is centralization/decentralization of IT and its assets. No sooner is everything consolidated and cost savings realized than adaptability concerns and needs of individual business units start the process of decentralization. Then, once decentralization is realized, everyone is painfully aware of the chaos that fifteen miniature IT departments, each going their own way, can cause … and centralization begins again.

    Quality assurance is another such pendulum. Much like soldiers in peacetime, most people don’t recognize the value of QA efforts when things are going well. And when they’re not going well, then it is considered a QA failure—assuming there is a true QA function. Otherwise, it becomes the impetus to launch a formalized QA function … until things are going well and budgets are tight. The problem with QA is that for years, timelines, budgets and Agile management styles have all conspired to swing that pendulum away from a formal QA function. Oh, companies pay the price, but they quite often don’t see it as a cry for a valid QA function, and just treat this particular issue as a one-off that they should make sure doesn’t happen again. Unfortunately, issues in production have become both commonplace and accepted because of this. The only issues in production that seem to actually generate angst are ones that keep users from accessing the product. Anything short of that and workarounds or delayed fixes are seen as okay.

    But the apps you are rush-building today will still be around in 10 years—or, at least, some of them will. Some of them won’t for a variety of reasons–including quality issues. Those that are around in 10 years are going to have to be maintained. QA now can save you over the years, so why all the resistance to it? QA might delay the release of new app. It is understandable that delays are to be avoided if possible, but so are bugs, so maybe constraining how long QA can delay the release and building that number right into the schedule would be a decent compromise.

    That way, QA is looking at the most important/used parts of the app, but not getting buried in the weeds (where there might be bugs, but the ROI for addressing them probably isn’t there). The app will be delivered on time because QA’s time was built into the schedule. This does require that we not allow the traditional and abhorrent practice of shortening the QA window to make up for developers not meeting deadlines. Let us be very clear about this: when developers are rushed because they missed deadlines, that is precisely the time that you want QA to look very closely at their code before release. The last thing you should do is less testing in this scenario. The absolute last thing.

    This is completely doable in your environment. The only really difficult part is holding the line on QA. Business owners are going to want to meet their original timeline, but cutting any phase of testing to get there is just a bad idea, so the struggle will be to hold the line. And figure out why devs missed the deadline in the first place so that the issue can be avoided for the next project.

    You all are rocking it. Make sure all that sweet code-and-deploy work is not undermined by quality issues! Go ahead, implement a QA policy and make it an actual policy. Keep rocking it, get accolades from the rest of us. Maybe even from your employer. Maybe. But definitely from us. Because you’re killing it, month after month.

  • Puppet Survey Suggests DevOps Adoption is Stagnant

    Puppet Survey Suggests DevOps Adoption is Stagnant

    Puppet today published an annual State of DevOps report that suggests overall adoption of DevOps practices has stagnated.

    The survey of 2,650 IT, development and information security professionals finds 83% are implementing DevOps practices, to a degree. However, only 18% of respondents are working for organizations that have highly evolved, automated DevOps processes in place. More than three-quarters of respondents (78%) are somewhere along the path toward achieving that goal.

    A full 90% of highly evolved DevOps teams have automated most repetitive tasks compared to only 67% of mid-level organizations, the survey found. In addition, 91% of highly evolved teams report a clear understanding of their responsibilities.

    Not surprisingly, the biggest hurdles identified are more cultural than technical. The most common culture blockers at mid-level organizations include a culture that discourages risk (21%), unclear responsibilities (20%), deprioritizing fast flow optimization (18%) and insufficient feedback loops (17%). In contrast, less than 2% of highly evolved organizations report resistance to DevOps from the executive level, the Puppet report found.

    Nigel Kersten, a field CTO at Puppet, said during an online panel that, after more than a decade of DevOps advocacy, people continue to be the biggest limiting factor when it comes to adoption. Specifically, from a compensation perspective, many IT operations personnel tend to feel undervalued compared to developers, noted Kersten.

    Another challenge enterprises encounter is trying to balance the need to create a standardized IT environment that can be managed and secured consistently and the desire of DevOps teams to embrace new tools as they see fit. Senior IT executives often tend to make platform decisions based on cost criteria that don’t always account for the need to enable agile development methodologies. Most of those platforms are designed to be managed by an IT administrator using a graphical tool rather than via a command line interface (CLI) and application programming interfaces (APIs) that appeal to DevOps teams.

    As a result, individual pockets of DevOps teams that select and maintain a platform of their choosing are emerging within enterprise IT organizations. Those teams often view their chosen platform as a better alternative for advancing developer productivity. Finding and retaining site reliability engineers (SREs), for example, to manage those DevOps platforms is a major challenge for most enterprise IT organizations. Most IT administrators lack the programming skills needed to become an SRE, and it’s not clear how many IT administers are inclined to acquire those skills.

    Conversely, it’s not clear how many programmers want to programmatically manage IT infrastructure at the expense of time they would otherwise devote to writing code. Organizations that can only hire a limited number of developers may not want to shift responsibility for managing IT operations to the proverbial left simply because they need more code to be written faster. Finding and retaining developers, in many cases, is just as much a challenge as hiring and retaining SREs.

    Advances in automation and artificial intelligence (AI) should make it easier for organizations to embrace DevOps best practices in the months and years ahead. However, it should be apparent to all that adoption of those best practices across an entire enterprise still requires a significant amount of time and effort, and will for many years to come.

  • Cycloid Brings Open DevOps Framework to the US and UK

    Cycloid Brings Open DevOps Framework to the US and UK

    Cycloid, a Paris, France-based provider of an open framework for implementing DevOps best practices, today announced it is expanding its operations into the U.S. and United Kingdom.

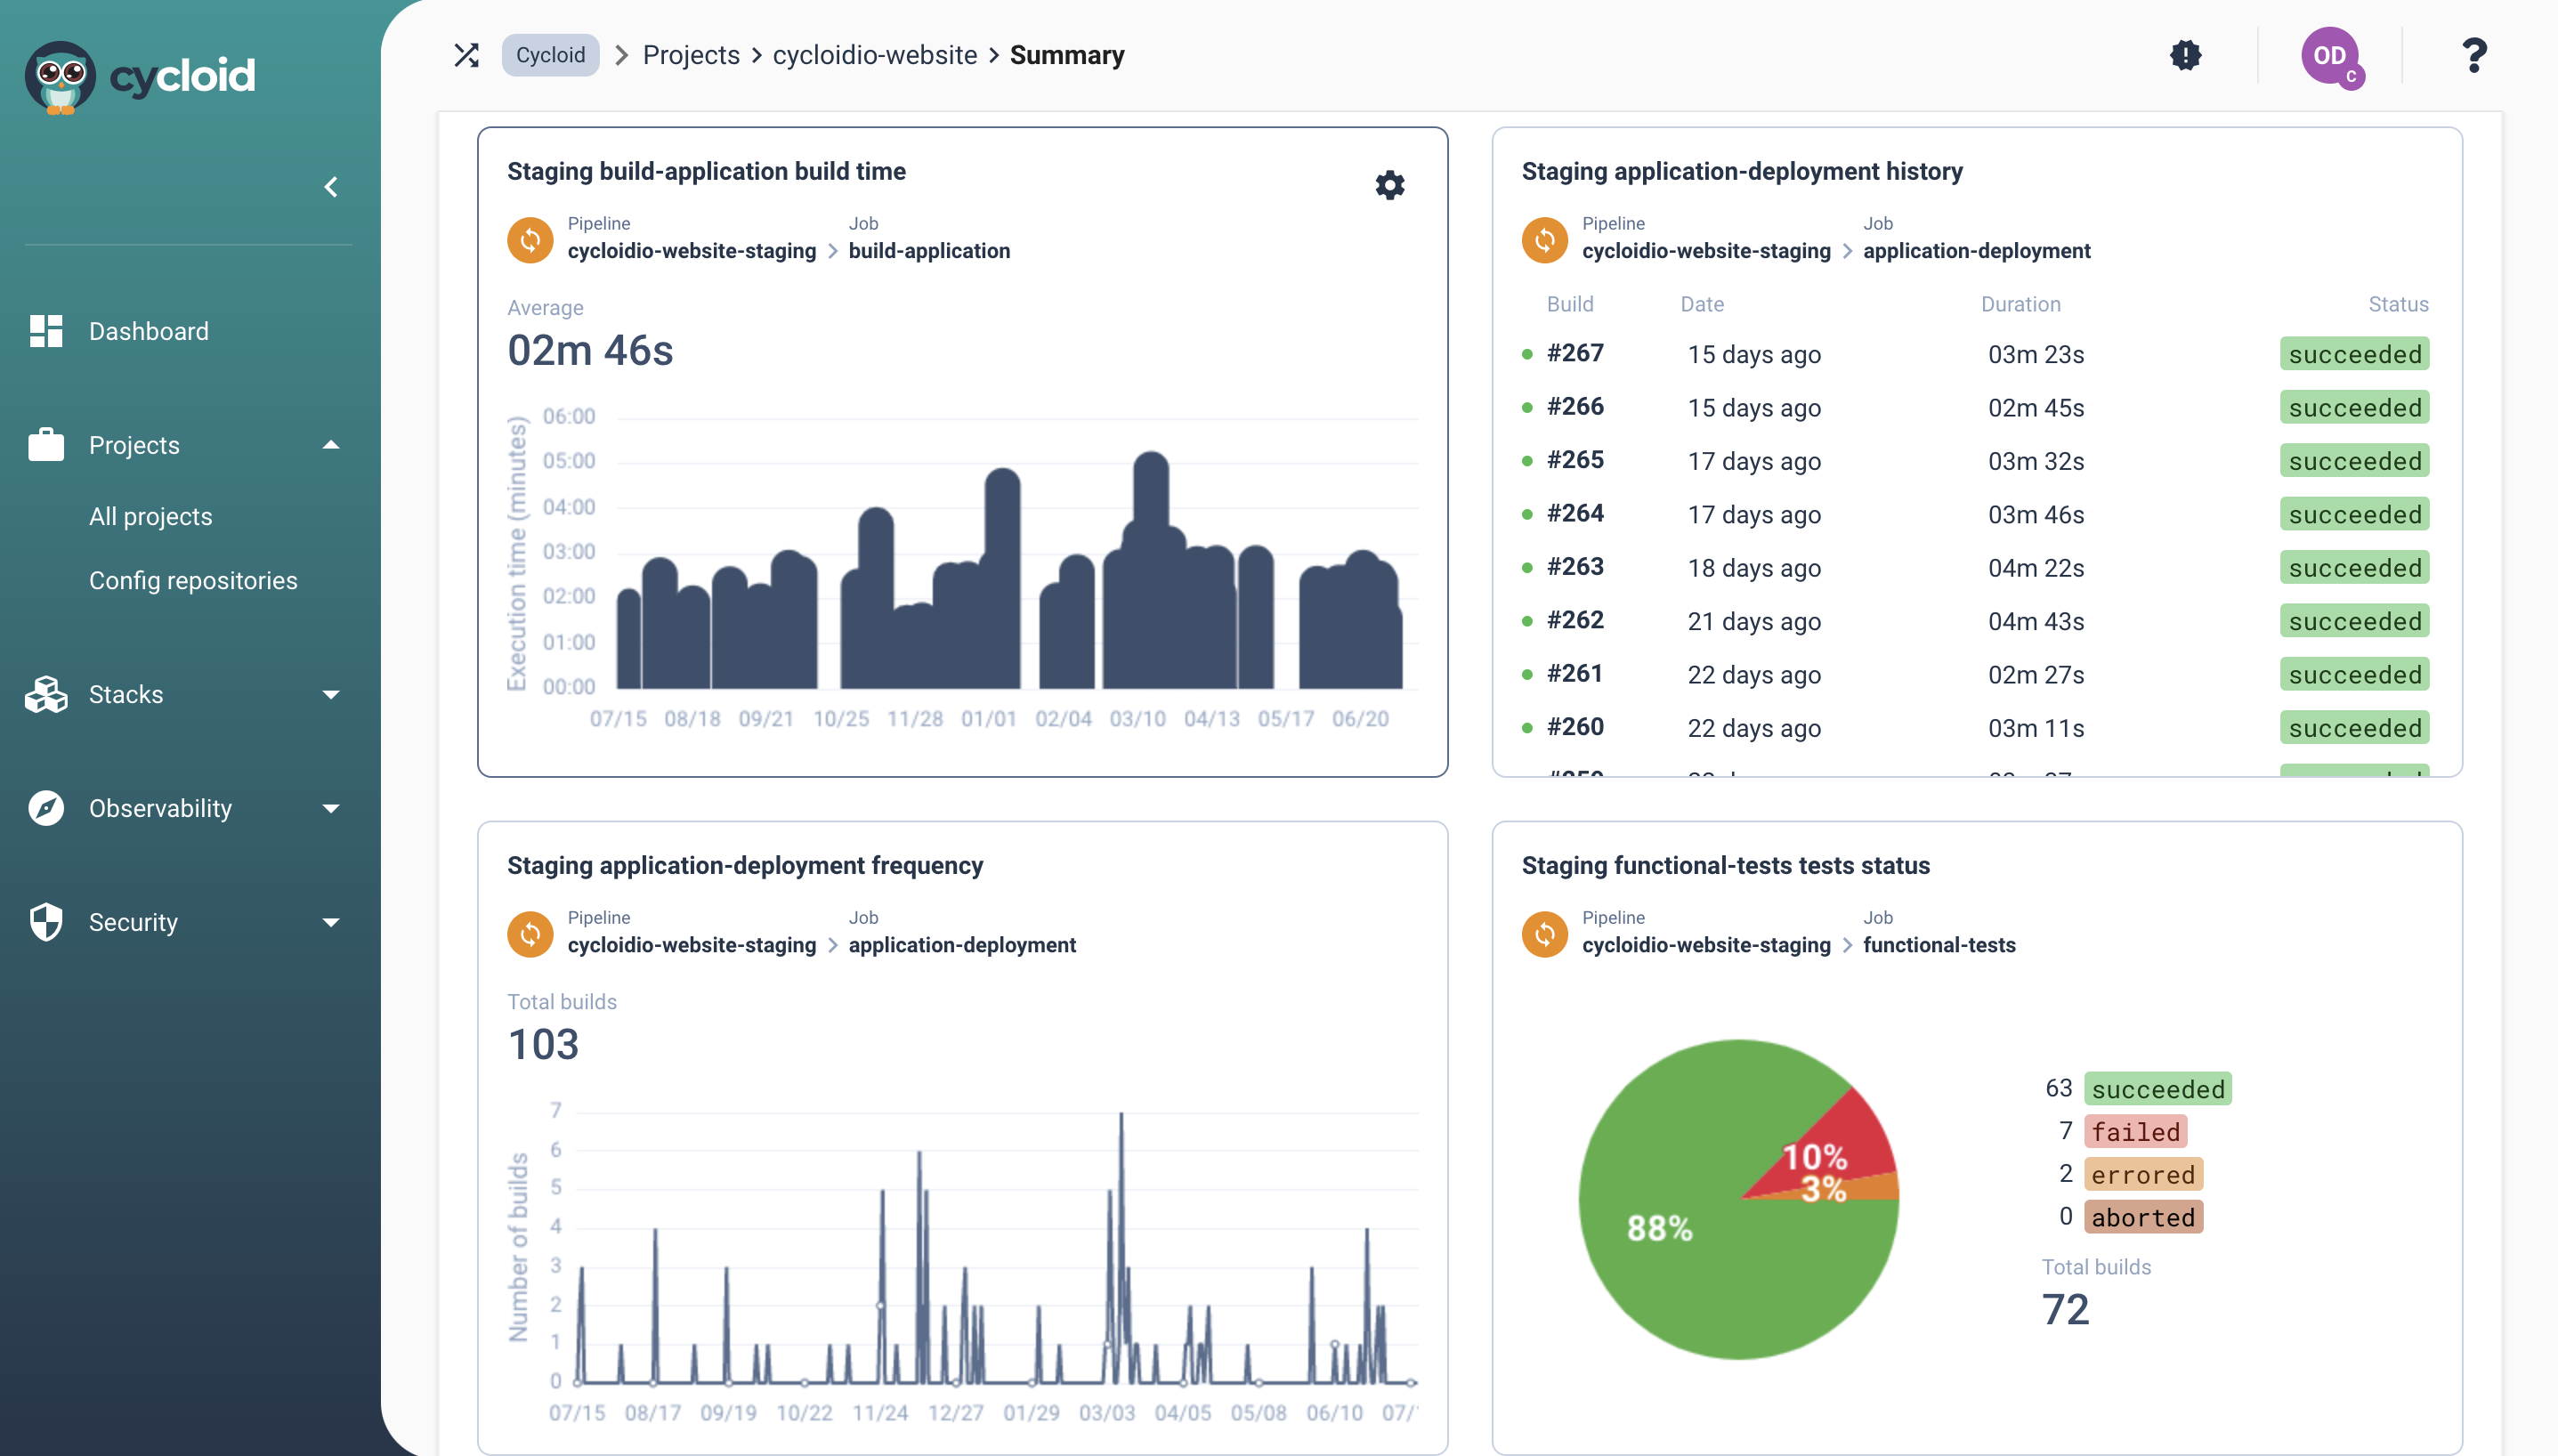
    Benjamin Brial, founder of Cycloid, said the Cycloid framework provides a lightweight approach to striking a balance between enabling developers to employ the tools they prefer and the need for centralized governance. The framework allows roles and policies to be pre-defined to ensure governance while service catalogs are used to deploy software using a set of drag-and-drop visual interfaces. There are also a set of management tools and features that provide additional visibility, automation, monitoring and financial controls to DevOps workflows.

    In effect, the portal that Cycloid provides to manage those workflows also serves to make DevOps more accessible to a wider range of IT professionals, added Brial.

    Cycloid

    Many organizations that embrace DevOps wind up building their own custom portal to achieve that same functionality. Rather than devoting resources to building and maintaining such a portal, Brial said Cycloid maintains and updates a portal platform that can be employed across any combination of tools that developers prefer. Other DevOps frameworks are often rejected because they require developers to adopt a specific set of tools, noted Brial. Without support from developers, it becomes nearly impossible to adopt DevOps best practices at scale, he added.

    After more than a decade of advocacy, adoption of DevOps within most organizations remains spotty. A significant factor in the lack of adoption is cultural issues involving skillsets. Many IT administrators lack the programming skills required to programmatically manage DevOps workflows. Cycloid is trying to establish a middle ground that enables IT operations teams to manage and govern DevOps workflows without having to acquire programming skills. The goal is to make it simpler for developers and IT operations teams to collaborate, said Brial.

    It’s not clear to what degree such an approach might increase adoption of DevOps best practices within enterprise IT organizations. However, it’s already apparent that the cost of hiring and retaining, for example, a small army of site reliability engineers (SREs) to manage IT environments at scale is often cost-prohibitive for many organizations.

    There’s no shortage of DevOps frameworks, but most organizations generally wind up crafting their own as part of an effort to tailor a DevOps workflow to meet their specific requirements. However, if there is a readily available framework that is highly customizable, Cycloid is betting more organizations would rather buy than build and maintain the entire framework themselves. Otherwise, DevOps teams would spend half their time performing the same repetitive manual tasks over and over, said Brial.

    One way or another, DevOps as a methodology for building and deploying applications needs to become more accessible. Proponents of DevOps have made a case for the methodology for the better part of a decade, with mixed success. The challenge continues to be finding a way to scale DevOps processes across the entire enterprise versus allowing each individual development team to define application development and deployment processes that, today, vary widely in terms of efficiency.

  • 3 Reasons Your Digital Transformation Stalled

    3 Reasons Your Digital Transformation Stalled

    The more a company modernizes, the more value it gets from the cloud, but not all digital transformation efforts are created—and executed—equally. According to Gartner, “87% of senior business leaders say digitalization is a company priority, yet only 40% of organizations have brought digital initiatives to scale … [and] without a shared vision across the organization, digital transformation efforts will continue to stall.”

    CIOs and other senior technology leaders are constantly looking for the best way to lead and scale modernization efforts that positively impact the business and generate the most value from the cloud. Here are three factors to consider to make sure digital transformation efforts don’t start to slow or stall out entirely.

    The Price of Ignoring Technical Debt

    Any CIO should be able to say how much of their development efforts are invested in innovation and how much is going into maintenance. A harder number to take into account is how much their innovation development effort is slowed down by technical debt.

    A good way to gauge this for CIOs—if you can say that your development organization dedicates more than 50% of its effort to innovation and that your development velocity is exactly where it was a couple of years back, then technical debt is not dragging you down. However, chances are that’s not the case.

    Why is that? A major reason is that the vast majority of business applications and business logic still reside on-premises in legacy applications and infrastructure with a once-solid software architecture that is now showing signs of wear.

    The technical debt these applications accumulated takes a toll. It is a ‘tax’ that many CIOs know they need to pay; know what is required, but choose to ignore until it’s too late.

    Many organizations delay modernization because they believe that it reduces the capacity for effort that can be spent on innovation, assuming that legacy maintenance can just carry on as usual. With the potential for a lengthy and risky modernization project, delaying innovation for that length of time is not even an option. The only way to stop ignoring technical debt is to find a way to reduce the risk of modernization and accelerate the modernization project so you can go back to doing what you love about tech: innovating.

    Managing App Modernization as a Tactical Project

    It’s amazing that application modernization is so often viewed as a tactical project—time- and materials-based, cost-focused—versus a strategic imperative driven by business goals. This approach also explains why many projects fail to meet expectations, are half-finished or abandoned or never even get started in the first place.

    The business logic and processes embedded in your legacy application estate are your core intellectual property and competitive advantage, and they need to be treated as such. These applications, and the business processes they encapsulate, require a strategy that continually modernizes them, starting now and continuing into the future. A one-and-done approach is a recipe for disaster and disappointment.

    So be strategic, make sure your modernization plan is aimed at reducing technical debt, restoring velocity and focusing on innovation. Once you get there, make sure you continuously manage your technical debt and keep your velocity high.

    Reliance on Lift and Shift for Cloud Migrations

    Cloud migration projects are most often critical parts of digital transformation initiatives, and yet, many outside advisors or quick-win focused insiders will push for the “easiest” approach.

    A rational plan to transform and modernize your applications for the cloud requires a critical assessment of your application estate to determine which applications should be refactored, lifted and shifted (rehosted or platformed), rewritten or just retired. Skipping this critical step and categorizing the majority of your apps into the “lift and shift” category is a common mistake that too many enterprises later regret. A lift and shift strategy may be fine for a subset of your applications, but for the most important ones it will result in a transfer of your technical debt to the cloud, increase your maintenance costs and take another bite out of your organization’s ability to innovate.

    Digital transformations are getting bogged down by technical debt, tactical decisions and modernization shortcuts. Organizations need to directly address these issues and reduce the significant drag they are incurring on modern transformation initiatives. By attacking them head-on, enterprises can accelerate their cloud migrations, application modernizations and business agility goals.

  • NS1 Touts a Common Delivery Platform for Devs and Ops

    NS1 Touts a Common Delivery Platform for Devs and Ops

    NS1 has extended the capabilities of its DNS and network management platform with the release of NS1 Connect. The platform is designed to serve as a delivery platform that integrates developer and network operations teams’ tasks for the creation and management of applications across highly distributed cloud-native and on-premises environments.

    While DevOps teams typically rely on dozens of tools for the deployment of software and the management of the network connections on which the software runs, NS1 was created to—among other things—reduce the number of different tools DevOps teams require by improving visibility, automation and management for these processes.

    In this way, NS1 Connect provides a unified API framework to automate DNS, traffic optimization and network services management across heterogeneous networks, Sanjay Ramnath, vice president of products at NS1, told DevOps.com. NS1 Connect’s reach covers internal and external applications deployed via on-premises, cloud or hybrid infrastructure. This enables NetOps and DevOps teams to integrate NS1 solutions into their infrastructure and CI/CD pipelines with lower complexity and enables NetOps teams to accelerate management and minimize the risk of misconfiguration, Ramnath said. “Prior to this, teams had to deal with complex manual processes or disparate API frameworks that slowed down their ability to develop, deploy and deliver applications.”

    In his talk, Your Business Depends on Eliminating Boundaries Between Applications, Users, Infrastructure, and Data during INS1GHTS 2021, NS1’s annual user conference, Ramnath described how a number of NS1 products and services are integrated into a single platform under the NS1 Connect umbrella. They include cloud-native network services for DNS, DHCP and IPAM (DDI), edge-to-cloud networking for NS1’s managed DNS, dedicated DNS, private DNS and DNS for China and application traffic automation for VPN traffic steering, pulsar active traffic steering and general traffic management. Other commonly used network services are provided as well, including IP address management that can be centralized across the network, said Ramnath.

    The idea was to remove many of the roadblocks DevOps teams face when seeking to deploy on highly distributed infrastructures. “The goal here is to remove some of those boundaries and barriers that are talked about on the infrastructure side,” says Ramnath. “[This helps to make sure] that our control plane is centrally provided and centrally consumable as a cloud solution and that our products can be deployed wherever they are needed in a zero-touch way, in a lightweight fashion, making sure that we are aligned with cloud-native operations.”

    The need to maintain low latency across distributed infrastructures is also key. As David Coffey explained during the conference in The Future of Application Traffic Intelligence and Automation session, low latency is essential for creating “that great experience for users.”

    “Low latency is not an attribute of this feature, it is a top, tier-one priority for people to accomplish, but it’s an incredibly complicated aspect, given all of the frameworks that are out there—the tools, the DevOps capabilities and the components required to support and deploy these modern-day applications,” said Coffey. “That’s what enables application companies to deliver that low latency and treat it as an attribute in the system; not having to go out of their way to create this. We want to enable all developers to embed this into their system—and we can provide them with a degree of success for delivering that great experience to their customers and to their networks.”

  • Why You Should Embrace Incidents and Ditch MTTR

    Why You Should Embrace Incidents and Ditch MTTR

    The cliché is that everyone in IT hates incidents, and the natural reaction when assembling incident response metrics is to look for numbers that you can lower over time. Fewer incidents and shorter incident response times must be better, we think. You might already be familiar with the common metrics associated with these goals, including mean time-to-resolution (MTTR) and total incident count.

    As it turns out, however, these metrics actually work against your company’s resilience goals. To understand why, let’s look at the industry that birthed most of our modern incident management practices and has learned the most about how to properly apply them: the airline industry.

    What the Airlines Can Teach Us

    From the 1950s to the 1990s, the airline industry built and refined best practices for incident management that we have since simplified and that have been widely adopted across the tech industry. What’s often termed “modern incident management” simply means the predictable and repeatable approach to handling unexpected disasters and the learnings-driven remediation steps that are prized when building a DevOps or SRE practice.

    One of the most important findings to come out of this research is the somewhat surprising fact that incidents weren’t being declared often enough. Instead, incident reports were created and the carefully assembled response and cataloging process was only followed after catastrophic events, which meant earlier opportunities to catch the underlying problem during a less severe incident were being missed.

    So why did an industry with such incredibly high stakes take so long to realize that more incidents were actually a good thing? You guessed it: a misguided desire to decrease the incident count. In chasing this goal of “lowering the number,” pilots and mechanics were often reluctant to file incident reports for anything less than the most critical situations, which meant the powerful, learnings-focused response and remediation process was only triggered in response to relatively rare and critical situations.

    This is a textbook example of Goodhart’s Law in action. To paraphrase, Charles Goodhart posited that any metric created will ultimately become the goal. In other words, if the incentives are aligned to reduce incidents, no matter how good your response and learning process is, it will only be executed in the most dire and unavoidable circumstances. After discovering this, the industry rapidly moved their focus towards expanding the use of the incident process by working to expand the spectrum of situations that could be classified as incidents with the goal of triggering the formal incident response process more often, distributing learnings for more incidents of lower relative severity and, yes, ultimately resetting the goal to increase the number of incidents.

    This approach effectively turned Goodhart’s Law to the airlines’ advantage—any effort to game the metric(s) meant more learning, not less. Filing incidents became directly and heavily incentivized and these metrics were never used as a justification for punitive action. This resulted in the safest decade of commercial aviation on record, with over 12 billion passengers traveling and no fatal accidents.

    What IT Can Learn About Successful Incident Response

    As technology companies, there is much for us to learn from this exercise in achieving resilience versus chasing “lower numbers.” The primary learning is this: increasing your incident count by incentivizing the use of your incident management process for more non-critical incidents—likely your SEV2s and below—and focusing your metrics and incentives on that goal, is likely the best way to reduce your overall count of catastrophic failures.

    For most companies, this means putting MTTR on the back burner and instead focusing on making the incident process itself more accessible throughout your company and across your organizations. It means leaders should talk about impactful and recent postmortems publicly and that postmortem distribution should be a priority; it should also be something that’s measured. Most importantly, it means opening up the incident management process more widely. Ideally, everyone at your company should have access to systems that allow them to file incidents, read incidents in progress and review postmortems from previous incidents.

    I like to reference the “big red button” philosophy of factory floors, where the decision-making power to declare an incident is in the hands of every employee. An unsafe situation shouldn’t be up for discussion, debate or approval before being acted on, even if the situation is later determined to be less severe than originally thought. The context of why that incident was filed—why that big red button was pressed—may prevent larger, more catastrophic failures in the future.

    So if you’re just getting started building out an incident management practice at your company, or you’ve been chasing MTTR metrics and focusing on pushing your incident count down as a primary goal, consider taking these learnings to heart and creating a positive incident culture with positive metrics meant to encourage and reward incident responders and reporters. Your company’s future depends on it.

  • Engineering Applications for DevOps (Part 6)

    Engineering Applications for DevOps (Part 6)

    This blog series explains how to engineer applications for DevOps.

    Topics covered in this blog series include:

    • Factors used to decide whether an application is a good candidate for DevOps.
    • Practices to engineer designs for DevOps.
    • DevOps applied to enterprise apps and software services.
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • Five levels of application maturity.

    This blog covers five levels of application maturity. You can read part one here, part two here, part three here, part four here and part five here.

    Five Levels of Application Maturity

    Why is it that younger applications are more mature than older applications? DevOps works best with incremental changes rather than large complex changes that are time-consuming to change, build, test and deploy. DevOps also works best in ephemeral cloud computing infrastructures that can be scaled up and down quickly depending on short-term workload demands of supporting build, test and deployment requirements.

    While existing applications will eventually be modernized to take advantage of the cloud, greenfield applications should be designed to exploit recent advancements in cloud-based platforms and application delivery.

    The following paragraphs describe the characteristics of five levels of application maturity.

    Spaghetti applications are older, monolithic legacy application designs that tend to be large and complex, like a big messy bowl of spaghetti. This complexity occurs partly because these older apps accumulate a massive amount of code and patches over time and partly because the architectural approaches at the time they were conceived did not have modular, cloud-oriented requirements in mind. Spaghetti applications are the least capable of taking advantage of cloud infrastructures.

    Modular applications emphasize architecture designs that separate application components into functionally independent, interchangeable modules, such that each contains everything necessary to execute only one aspect of the desired functionality.

    A module interface expresses the elements that are provided and required by the module. The elements defined in the interface are detectable by other modules. Modules often use a design style known as service-oriented architecture (SOA), where services are self-contained black boxes that provide capabilities to the other application modules, as a service, through a network protocol. SOA may be confused with microservices architecture.

    There are key differences between SOA and microservices architecture that are important to DevOps. Microservices are preferred over SOA architecture because microservices are more fine-grained and restricted in what they can do. SOA uses an enterprise service bus for communication, whereas microservices use more lightweight stateless protocols and APIs managed as a product.

    Changes to SOA modules usually require a new application release, while a change to a microservice usually only requires the microservice to be replaced. Migration of modular applications to the cloud may require rework to take advantage of cloud features such as autoscaling.

    Cloud-ready applications that use the twelve-factor application modular design principles are more advanced. These modular designs emphasize declarative formats for automation, clean contracts with the underlying operating system and portability between execution environments. Deployment on modern cloud platforms obviates the need for servers and systems administration, minimizing divergence between development and production and enabling continuous deployment for maximum agility.

    These characteristics and capabilities enable the application to scale up without significant changes to tooling, architecture or development practices. Cloud-ready applications can be easily mapped to virtual machines (VMs) available through cloud infrastructure services (IaaS) for VMs based on VMware vSphere or Microsoft Hyper-V.

    Cloud-ready apps do not require rearchitecting or refactoring. They offer least-effort migration to the cloud with a lower availability rate. However, workloads such as legacy databases, third-party applications and homegrown business applications that are typically not designed for clustering or high availability suffer from a single point of failure.

    Cloud-ready apps are expensive to maintain. This is primarily due to the way they consume computing, storage and network resources, even when idle. Each component of an app runs in a dedicated VM with no scope for optimization. Upgrading or patching results in downtime and makes maintenance complex and expensive. Ultimately, cloud-ready apps derive less value from the cloud than cloud-optimized or cloud-native applications.

    Cloud-optimized applications take advantage of managed services offered by cloud providers. For example, instead of running a database in a VM, they consume database-as-a-service (DBaaS). Cloud-optimized apps typically target the platform-as-a-service (PaaS) delivery model of the cloud. They are portable and can be deployed in IaaS or PaaS. This reduces the deployment footprint, offering flexibility to IT teams. These apps are elastic, with the ability to easily scale in and scale out which results in optimal utilization of resources. Upgrading, patching and maintaining cloud-optimized apps is more manageable when compared to cloud-ready apps.

    The downside of cloud-optimized apps is the learning curve involved in migrating to the cloud. Developers, operators and system administrators will have to learn new ways of deploying and managing workloads. Line-of-business applications with access to source code are great candidates for being cloud-optimized apps. They can be redesigned and rearchitected to take advantage of the cloud. Cloud-optimized apps can integrate and interoperate with cloud-ready applications.

    Cloud-native applications are the most recent iteration of applications that are born in the cloud. They take full advantage of the cloud by exploiting capabilities such as elasticity, event-driven resource optimization and faster release cycles. Apps that are in the early stages of design and architecture are perfect candidates for cloud-native.

    Cloud-native applications are designed as federated microservices, packaged and deployed as containers and managed through modern DevOps processes. When your organization needs to scale to thousands of services in the cloud, microservices application architectures offer major benefits over monolithic modular architectures, including the following:

    • Separate microservices are better suited to different technology stacks.
    • Federated microservices enable independent deployment of different parts of the system.
    • Isolated deployments add to the resilience and fault-tolerance of the system.
    • Scaling characteristics may be different for each microservice.
    • APIs are used as connectors.
    • Stateless protocols help assure seamless recovery.
    • Event-driven programming reduces overhead and process latency.
    • Antifragile practices inoculate against unanticipated failure modes.

    The target deployment environment for cloud-native applications includes containers-as-a-service (CaaS) and functions-as-a-service (FaaS). This breed of apps delivers ultimate scalability and availability. Combined with continuous integration and continuous deployment, software is delivered rapidly, which accelerates time-to-market. It brings closed-loop feedback among developers, testers, operators and end users.

    Cloud-native apps demand new skills of containerization, microservices and build and release management. However, the ROI is higher when compared to other app models. Greenfield applications that are still in the design phase are ideal for adopting the cloud-native pattern.

    Diverse Applications for Cloud Migrations

    Large enterprises moving to the cloud will deal with a diverse set of applications. Through hybrid connectivity and integration, spaghetti, modular, cloud-ready, cloud-optimized and cloud-native applications will co-exist and interoperate with each other. If you are after the benefits of modularity, make sure you do not trick yourself into a microservices-only mindset.

    Explore the in-process modularity features or frameworks of your favorite technology stack. You will get support to enforce modular design instead of having to just rely on conventions to avoid spaghetti code. Then, make a deliberate choice whether you want to incur the complexity penalty of microservices. Sometimes you have no choice, but often, you can find a better way forward.

    What This Means

    This blog is one of a series that explained how to engineer applications to be most suitable for DevOps. Topics covered in this blog series include:

    • Factors used to decide whether an application is a good candidate for DevOps.
    • Practices to engineer designs for DevOps.
    • DevOps applied to enterprise apps and software services.
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • Five levels of application maturity.

    This blog covers five levels of application maturity. You can read part one here, part two here, part three here, part four here and part five here.

    For more information regarding how to engineer applications for DevOps refer to my book Engineering DevOps.

  • Engineering Applications for DevOps (Part 5)

    Engineering Applications for DevOps (Part 5)

    This blog series explains how to engineer applications for DevOps.

    Topics covered in this blog series:

    • Factors to decide whether an application is a good candidate for DevOps.
    • Practices to engineer designs for DevOps.
    • DevOps applied to enterprise apps and software services.
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • Five levels of application maturity.

    This blog covers DevOps applied to manufactured (embedded) systems software. You can read part one here, part two here, part three here and part four here.

    DevOps Applied to Manufactured (Embedded) Systems Software

    In the late 1970s (yes, forty years ago!) as a young engineer, I was given an assignment to figure out how to accelerate the software development and delivery cycles for an innovative packet switch called SL-10, (predecessor to the more recent model called Data Packet Node [DPN]) manufactured by Northern Telecom. Each SL-10 “node” consisted of millions of lines of original embedded software source code and custom hardware configured with many interconnected processors and protocols interfacing with other nodes, host devices, and terminal devices.

    Given the complexity of the system and lack of automated build, test and deployment tools, it was taking more than twelve months to generate each release of the system, and there typically were lots of bugs even after the release. Without knowing much about DevOps (the word “DevOps” was not invented for another twenty-nine years), we proceeded to implement a continuous delivery system that included automated build, test and delivery tools and workflows.

    The result was remarkable. Lead times for releases to manufacturing were reduced more than tenfold, from twelve months to one month, and quality, measured as defects found by customers per release, also reduced tenfold. This dramatic shift in performance and capabilities made it possible for the engineering and manufacturing teams to accelerate the rate of innovation and trample the competition. The SL-10 product, and its rebranded DPN version, quickly dominated the connection-oriented packet switch market, and it became the pride of the Nortel corporation and the Canadian nation. Even cooler, I got a nifty president’s pin and promotion which paved the way for my career that led to writing a book and this series of blogs! If this real-life example is not sufficient to demonstrate that DevOps can be applied to manufactured embedded software products, then I don’t know what is.

    There have been many other examples published that show how DevOps practices applied to embedded manufactured systems have reaped similar benefits. A notable example was published in 2013 by Gary Gruver in A Practical Approach to Large-Scale Agile Development: How HP Transformed LaserJet FutureSmart Firmware.

    That is not to say that DevOps applied to manufactured software embedded systems is the same as applying DevOps to enterprise applications or COTS systems. A paper published on the CloudBees blog, Five Aspects that Make Continuous Delivery for Embedded Different, explained some of the key DevOps practices used with embedded systems.

    DevOps Benefits for Embedded Systems

    Benefits of DevOps for embedded systems are summarized as follows:

    • Retrofitting the huge code base typically found in legacy embedded software systems into a DevOps model is not easy. It is likely to be expensive, but it is almost guaranteed to be a worthwhile effort, especially if you have a longer-term vision and intend for your product to stay competitive in the future.
    • Developers of embedded software need access to massive amounts of computer resources for testing their real-time embedded code on powerful hardware simulators.
    • Developers and testers need access to physical product hardware to run their binaries for system tests that cannot be run on simulators alone. Lab-as-a-service (LaaS) systems that orchestrate testing topologies of real devices can improve sharing of critical resources. LaaS systems provide a test framework that can be integrated through APIs into a continuous delivery pipeline.
    • Long build and test processes may need to be reengineered to reduce serialized lead times into quicker build times made possible by scaling build and test resources.
    • Long compliance and conformance test processes for embedded systems need to be accelerated with automation and resource scaling.
    • Focus on continuous delivery rather than continuous deployments in which shippable product versions are frequently delivered to manufacturing for verification, but the frequency of deployments to end customers is determined by other business factors.

    What This Means

    This blog is one of a series explaining how to engineer applications to be most suitable for DevOps. This blog series explains how to engineer applications for DevOps including:

    • Factors to decide whether an application is a good candidate for DevOps.
    • Practices to engineer designs for DevOps.
    • DevOps applied to enterprise apps and software services.
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • Five levels of application maturity.

    This blog covers DevOps applied to manufactured (embedded) systems software. You can read part one here, part two here, part three here and part four here.

    For more information regarding how to engineer applications for DevOps refer to my book Engineering DevOps.

  • Engineering Applications for DevOps (Part 4)

    Engineering Applications for DevOps (Part 4)

    This blog series explains how to engineer applications for DevOps.

    Topics covered in this blog series:
    • Factors to decide whether an application is a good candidate for DevOps.
    • Practices to engineer designs for DevOps.
    • DevOps applied to enterprise apps and software services.
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • Five levels of application maturity.

    This blog covers DevOps applied to commercial off-the-shelf (COTS) systems. You can read part one here, part two here and part three here.

    DevOps Applied to COTS Systems

    I often hear that DevOps does not apply to systems that use commercial off-the-shelf (COTS) software. The idea that DevOps cannot be used with COTS systems is, frankly, a cop-out. Just because someone else designed and developed an application’s source code is not a sufficient reason to avoid engineering a DevOps solution.

    Consider the value stream chain of activities from the source vendor through integration and deployment in your environment. There are limitations and constraints to the level of automation allowed, the return on investment in automation and influence over the development life cycle that DevOps practices can introduce when dealing with COTS applications.

    COTS applications will typically have predefined and supported interfaces for managing configuration or accessing data. These endpoints may not be accessible or compatible with your existing toolchain or automated change management practices.

    Types of COTS Applications

    COTS applications typically come in one of three flavors; namely, closed, open and platform, and each should be evaluated differently.

    Closed COTS applications allow little to no customization to their functionality and/or interfaces. They typically have predefined management consoles and a published list of commands or APIs that will allow external applications to interact with the COTS applications. A good example of a closed COTS application is Microsoft Exchange.

    Key considerations for DevOps with closed COTS applications are as follows:

    • Can configurations be scripted and integrated with existing automation and orchestration toolchains?
    • Can configuration scripts be managed and maintained in external version control systems?
    • How are updates, patches and service packs applied and managed? Can these practices be automated?
    • What developer tools (APIs, software development kits [SDKs], etc.) are available to extend and/or interact with the application and/or data?
    • Are these tools compatible with existing tools and expertise in the enterprise?
    • Can these developer tools be integrated within the existing toolchain?
    • How frequently are changes made to the base product?

    If these applications can be managed by external systems and code developed to automate deployment and configuration and/or integration can be managed through a version-controlled pipeline, closed COTS applications make good candidates for DevOps and continuous delivery (CD). By applying CD principles, COTS binaries are versioned and stored in an artifact repository; installation and configuration scripts are managed through version control and IaaS workflows and applications and integration endpoints are auto-tested through deployment pipelines.

    This is only made possible when consumers of the COTS application collaborate with operators of the COTS platform to ensure that the solution is aligned with enterprise goals, objectives and standards related to portfolio management.

    Open COTS applications allow significant modifications to functionality, data and/or interfaces. These platforms typically have rich SDKs, APIs and embedded developer utilities that enable users and developers to modify all layers of the applications; namely presentation, business logic and data. Open COTS applications typically have a large, complex footprint consisting of core services, data and/or GUI customizations, embedded applications, etc. Classic examples of open COTS solutions include ERP/ CRM platforms (like SAP or Oracle) or portal platforms (like SharePoint, ServiceNow or WebSphere).

    Key questions to ask when considering whether DevOps can be applied to an open COTS application:
    • How are customizations (created through internal design editors, logic builders or data schema extensions) version controlled? Are these configurations stored in a database or code?
    • How are customizations created through internal tools and packaged, installed and configured in higher-level environments like staging or production?
    • What does the development life cycle for customization created with internal tools look like? What quality gates are required? How about architectural standards?
    • How are custom, embedded applications/applets packaged, installed and configured?
    • Can these custom applications/applets be run and tested separately from the underlying COTS application?
    • What does the development life cycle for customizations created with external tools look like? What quality gates are required? How about architectural standards?
    • Does the COTS application provide testing frameworks, mocks and/or stubs for testing external dependencies?
    • What automated test suites are supported by the platform (unit, functional, regression, capacity tests, etc.)?
    • What is the upgrade path for customizations (historically)? As you can imagine, open COTS applications add layers of complexity.

    When considering DevOps and CD with open COTS solutions, it is recommended that you build multiple pipelines to support each layer of the application in the dev or continuous integration (CI) stage of the value stream. Subsequent stages, like staging and production, will use a converged pipeline built from known good artifacts of the dev and CI stages.

    Before implementing a solution, it is important to study the development life cycle and practices of the target COTS application before building your toolchain. Understanding how the end-state platform is created and how change is introduced will strongly influence your toolchain and pipeline design.

    Platform COTS Applications provide a set of services and tools, as well as proprietary runtimes, that enable users to build and run custom applications on the platform. These are the most difficult type of applications to integrate into existing DevOps practices and CD toolchains because common practices like version control, testing and build are done through the platform rather than using external tools.

    Platform COTS are packaged applications that enable customers to build applications on top of the base platform. As a blend of closed and open systems, all the previous considerations are valid. In most cases, the base platform acts as a closed system, whereas the custom-developed applications on top act like open systems.

    For this type of application, it is critical to understand what hooks and services are available to support DevOps practices and CD. Many of these platforms are not going to fit within your existing toolchain and may not be able to employ the workflows, dashboards and reporting you have grown accustomed to from your current toolchain.

    What This Means

    This blog one of a series that explains how to engineer applications to be most suitable for DevOps. This blog series explains how to engineer applications for DevOps including:

    • Factors used to decide whether an application is a good candidate for DevOps.
    • Practices to engineer designs for DevOps.
    • DevOps applied to enterprise apps and software services.
    • DevOps applied to COTS systems.
    • DevOps applied to manufactured (embedded) systems software.
    • Five levels of application maturity.

    This blog covered DevOps applied to COTS systems. You can read part one here, part two here and part three here.

    For more information regarding how to engineer applications for DevOps refer to my book Engineering DevOps.