In an era where software is at the heart of every business, deploying applications securely and efficiently has never been more critical.
From cloud-based systems that manage sensitive customer data to mobile apps that drive consumer engagement, software deployments come with a wide array of security challenges. Missteps in the deployment process can lead to disastrous consequences, ranging from data breaches to system outages.
This article covers the risks involved in software deployment and provides best practices to mitigate these dangers effectively.
What is Software Deployment?
Software deployment refers to all the processes involved in making a software system available for use. It’s a broad term that includes various stages like installation, configuration, testing and optimization. In simple terms, software deployment is the bridge that connects software developers with the end-users, allowing them to use the software product.
The primary goal of software deployment is to make a software application ready for use in a specific environment, be it a test environment, a staging environment or a production environment. It starts with installing the software system, which involves copying and configuring the software application on the servers where it will run. It then proceeds to the configuration of the software system, which involves setting the system parameters to meet the specific needs of the environment it will be running in.
Software deployment doesn’t end once the software system is up and running. It also includes monitoring and optimizing the software system to ensure it runs smoothly and efficiently. Moreover, it involves the implementation of updates and patches to fix bugs and enhance the software’s performance.
Risks in Software Deployment
Like any other process in the SDLC, software deployment comes with a set of risks that can potentially disrupt your software development projects:
Code Tampering
One of the risks in software deployment is code tampering. This happens when unauthorized individuals access the software code and alter it for malicious purposes. Code tampering can lead to the introduction of bugs, the loss of functionality or even the creation of security vulnerabilities.
To mitigate the risk of code tampering, it’s important to implement access controls that limit who can access your software code. Additionally, you should use version control systems that track changes made to your software code, allowing you to identify and rectify any unauthorized changes.
Third-Party Vulnerabilities
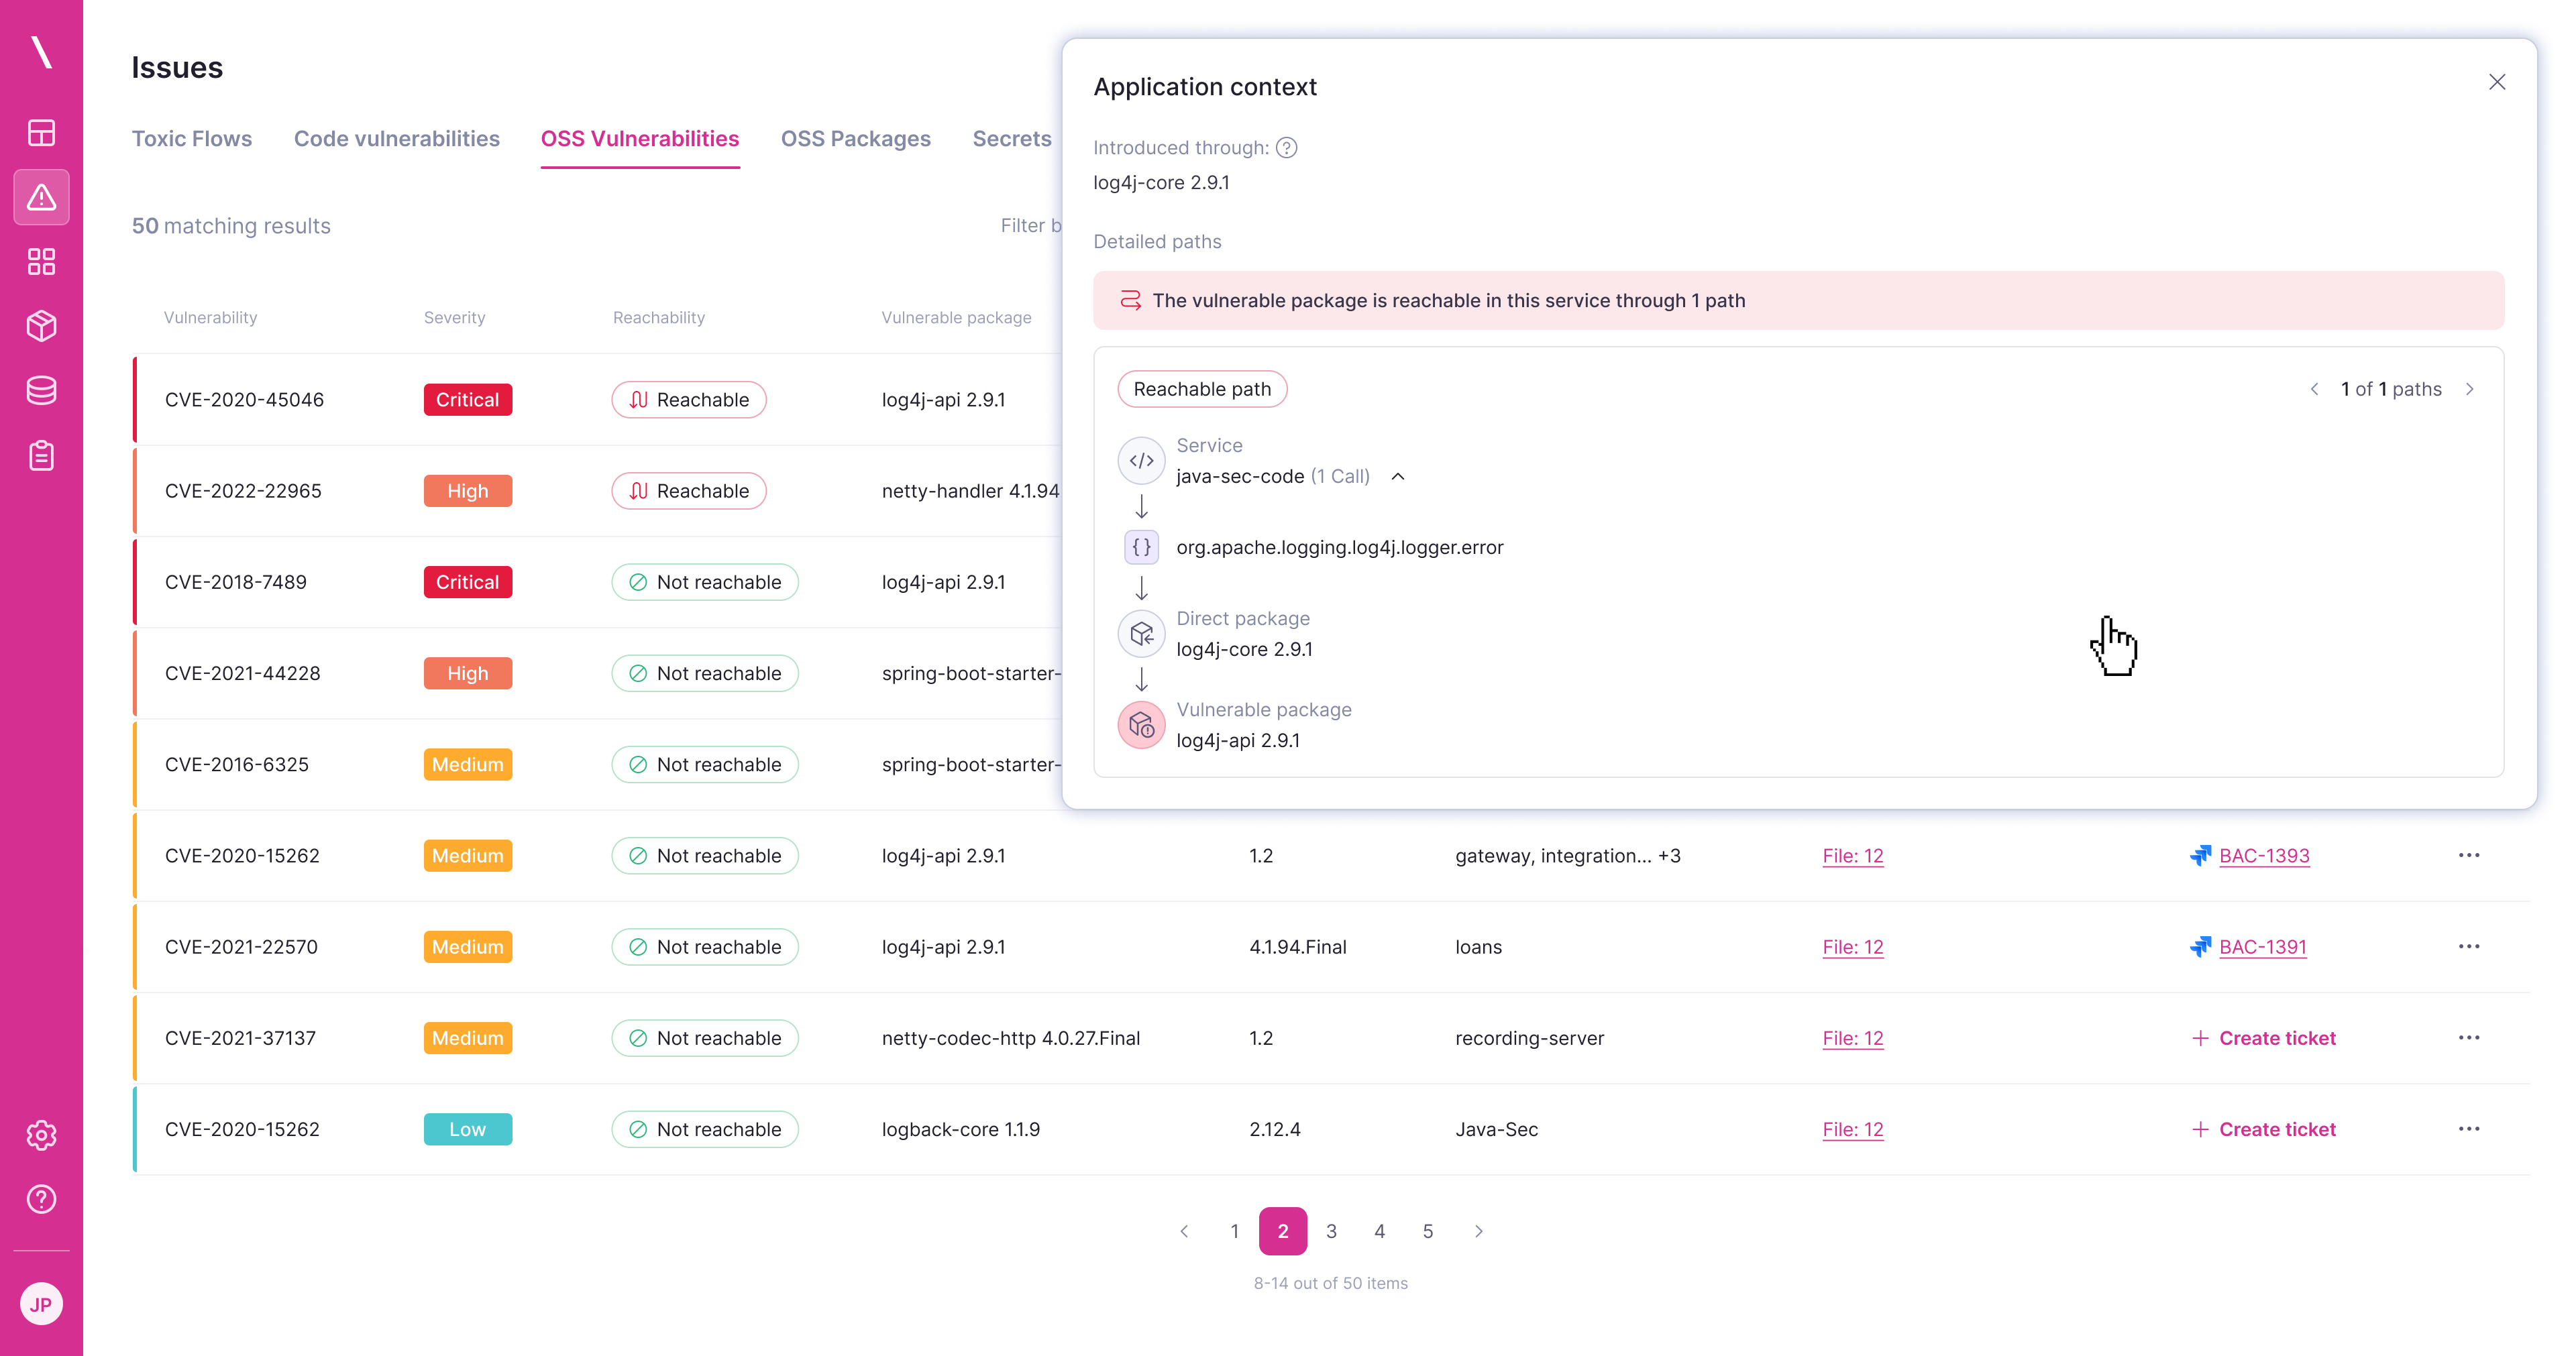
Third-party vulnerabilities are another risk in software deployment. These are vulnerabilities in third-party libraries and components used in your software application. If these vulnerabilities are exploited, they can compromise your software application.
To mitigate the risk of third-party vulnerabilities, it’s important to keep your third-party libraries and components up-to-date. Furthermore, you should regularly audit your third-party libraries and components for vulnerabilities and take the necessary steps to patch them.
Configuration Errors
Configuration errors are one of the most common risks in software deployment. These are errors in the configuration of the software system that can lead to the system not functioning as intended.
To mitigate the risk of configuration errors, it’s important to have a thorough testing process. This should include both functional testing to ensure the system works as intended and configuration testing to ensure the system’s configuration is correct.
Inadequate Environment Isolation
Inadequate environment isolation is another risk in software deployment. This happens when the test, staging and production environments are not properly isolated, leading to issues like data leakage or the unintentional deployment of untested code to the production environment.
To mitigate this risk, you should ensure that your test, staging, and production environments are properly isolated. This includes having separate servers for each environment and implementing access controls to prevent unauthorized access.
Lack of Monitoring
Lastly, the lack of monitoring is a risk in software deployment. Without proper monitoring, it’s difficult to identify and rectify issues in your software system.
To mitigate this risk, you should implement a robust monitoring system that allows you to track the performance of your software system. This should include error tracking to identify and rectify issues and performance monitoring to ensure your software system runs efficiently.
Common Deployment Strategies and Their Security Implications
Blue-Green Deployment
Blue-Green Deployment is a release management strategy designed to reduce downtime and risk by running two identical production environments, known as Blue and Green. At any time, only one of these environments is live, with the live environment serving all production traffic.
The primary security implication of the Blue-Green deployment is the risk of data inconsistency during the switchover. If not properly managed, sensitive data could be exposed, lost or corrupted. Furthermore, because two environments are maintained, security measures must be duplicated, potentially leading to inconsistencies and vulnerabilities if not properly managed.
Canary Deployment
Canary deployment is a strategy where new software versions are gradually rolled out to a small subset of users before being deployed to the entire infrastructure. This strategy allows teams to test and monitor the performance of the new release in a live environment with less risk.
Canary deployment can potentially expose new software versions to a smaller user base, potentially exposing vulnerabilities before a full-scale release. If a vulnerability is exploited during this stage, it could lead to a security breach affecting a subset of users. There is also the risk of vulnerabilities or malware “leaking” from the canary environment to the main production environment.
Feature Toggles
Feature toggles, also known as feature flags, allow developers to enable or disable features in a live environment. This means that new features can be deployed into the production environment but kept hidden from users until they are ready for release.
The main security risk with feature toggles is that if they are not correctly implemented, they can potentially expose unfinished or untested features to end-users, leading to potential vulnerabilities being exposed.
Rolling Deployment
Rolling deployment is a strategy where the new version of software is gradually deployed across all servers or nodes in the infrastructure, one after the other. This strategy ensures that there is always a version of the software available to users.
The primary security implication with rolling deployment is that there will be a period where different versions of the software are running concurrently. This could lead to potential vulnerabilities if the newer version has security improvements that the older version lacks.
A/B Testing Deployment
A/B testing deployment is a strategy where two versions of the software are run concurrently, with some users directed to the new version and others to the old version. This allows teams to test the performance and user acceptance of the new version before a full release.
The primary security implication of A/B testing deployment is similar to that of rolling deployment: different versions of the software running concurrently could potentially expose vulnerabilities. Additionally, directing users to different versions could potentially expose them to different levels of risk.
7 Best Practices for Secure Software Deployment
1. Code Reviews
Code reviews, also known as peer reviews, enable developers to learn from each other, enhance code quality and ensure adherence to coding standards. It’s a practice where multiple eyes scrutinize the code, spotting potential sources of vulnerabilities that a single developer might overlook.
However, code reviews are not just about hunting for bugs. They also foster knowledge sharing and collaboration amongst team members. A thorough code review process can help in identifying reusable code, reducing code complexity and increasing overall code efficiency.
2. Automated Security Scans
Automated security scans are another essential tool in your arsenal for secure software deployment. They help in identifying vulnerabilities in your code, such as SQL injection, cross-site scripting (XSS), and cross-site request forgery (CSRF) that attackers can exploit.
Implementing automated security scans in your deployment process can save you a significant amount of time and resources. It allows you to detect and fix vulnerabilities before the software is deployed, reducing the potential for security breaches.
3. Environment Hardening
Environment hardening involves taking measures to secure your system against potential threats by reducing its attack surface. It includes practices like removing unnecessary software, services, and users, setting up firewalls and configuring system permissions.
One of the most critical aspects of environment hardening is system patching. Timely patching ensures that your system is not vulnerable to known security flaws.
Moreover, environment hardening also includes measures like regular system audits and continuous monitoring. It’s not a one-time process but an ongoing effort to ensure the security of your software deployment.
4. Principle of Least Privilege
The principle of least privilege (PoLP) is a crucial principle in secure software deployment. It stipulates that a user or a process should only have the minimum privileges necessary to perform its function. This limits the potential damage in a security breach.
Implementing PoLP requires a clear understanding of your system and the roles and responsibilities of each user or process. Regular audits can help ensure that PoLP is being followed and that unnecessary privileges are revoked promptly.
5. Secure Configuration Management
Secure configuration management is an essential practice in ensuring the security of your software deployment. It involves maintaining a standard, secure configuration for your system and regularly checking and updating it to address evolving threats.
The first step in secure configuration management is establishing a baseline configuration that adheres to industry best practices. This configuration should then be applied to all systems.
Regular audits should be conducted to ensure systems adhere to the baseline configuration. Any deviations should be promptly identified and rectified.
6. Immutable Deployments
In an immutable deployment, once a version of the software is deployed, it is never modified—any changes cause a new version of the software to be deployed. This approach reduces the risk of configuration drift and makes your deployments more predictable and reliable.
While implementing immutable deployments may require a shift in your deployment practices, the security and reliability benefits are significant. It can also help simplify the deployment process and make it more efficient.
Mastering the art of software deployment is a journey that involves the careful implementation and continuous improvement of various practices. While the road may seem long and winding, the destination—a secure and efficient software deployment process—is well worth the effort.