Category: DevOps Practice

  • New Relic Adds App Security Testing Tool to Observability Platform

    New Relic Adds App Security Testing Tool to Observability Platform

    New Relic today made available a public preview of an application security testing tool that will be integrated into its observability platform.

    Esteban Gutierrez, CISO and vice president of information security for New Relic, said the New Relic Interactive Application Security Testing (IAST) will provide DevSecOps teams with the context needed to identify the root cause of a cybersecurity issue down to specific lines of code.

    DevSecOps teams will be able to take advantage of IAST to identify vulnerabilities both in code as it is written and after it has been deployed in a production environment without any false positives, he noted.

    New Relic achieves that goal using deterministic testing techniques that surface an actual proof-of-exploit using observability data collected from both applications and the underlying infrastructure upon which they depend, said Gutierrez. DevSecOps teams are then provided with guided remediation suggestions, guardrails and tracking tools to both remediate the issue at hand and prevent it from reoccurring, he noted.

    New Relic IAST takes advantage of the agent software New Relic provides to collect observability data, which reduces the total cost of DevSecOps by providing IT teams that have adopted the New Relic platform with an integrated set of application security testing tools that doesn’t require them to acquire and manage a separate additional platform, added Gutierrez.

    That approach also ensures that application security testing is integrated with the continuous integration/continuous delivery (CI/CD) platforms that New Relic already observes, he added.

    The reason most vulnerabilities are not remediated in a timely fashion is the DevOps teams responsible for creating and deploying the required patches lack any context. They often don’t know, for example, how many instances of a vulnerability there might be or the actual level of severity. Without those insights, it becomes exceedingly difficult to prioritize remediation efforts, noted Guttierrez.

    As application security requirements become more stringent in the wake of forthcoming legislation, it’s now more of a question of when than if organizations will be required to better secure their software supply chains. The issue DevOps teams face now is finding a way to integrate application security testing tools into existing DevOps workflows without slowing down the pace at which applications are being developed.

    Of course, not every vulnerability discovered requires the same level of attention. Depending on its severity and likelihood of being exploited, DevOps teams need to prioritize which vulnerabilities need to be remediated first. There simply are not enough resources available today to fix every vulnerability an application might have. For the foreseeable future, there will remain technical debt involving vulnerabilities that will need to be addressed after an application is deployed in a production environment.

    The issue, of course, is that cybercriminals are getting more adept at exploiting those vulnerabilities. The amount of time any DevOps team has to resolve issues before they result in a breach continues to dwindle.

  • Automation or Concatenation?

    Automation or Concatenation?

    We’ve been in a period of mergers and acquisitions for a while in the DevOps and DevSecOps spaces, and it seems to be heating up even more. Combined with products expanding to cover a more broad segment of the software development life cycle (SDLC) and strategic partnerships to cover more of the SDLC, it is starting to look like our automation efforts are going to be increasingly driven by vendors. Those efforts will be more concatenation than automation–though technically the same in perception, they vary wildly in implementation, and we should be planning for it.

    Build Versus Buy

    We have always struggled with build versus buy, and we have always struggled with best-of-breed versus overarching solution set. The entire hype of Every. Single. Vendor. Claiming to be a platform is partially driven by the latter argument. Putting “platform” in your marketing does not make a vendor better at those things outside its historical strengths, though, so that movement is doomed to fail for most organizations. Some were already moving to be a platform and had assembled–by M&A or by internal development–an impressive platform already, and those were successful because they were good at a breadth of things. The best of them are continuing this trend. I try to avoid plugging vendors here, but I think an example is in order in this case.

    Akamai’s recent purchase of NeoSec is the poster child for vendors doing the platform thing super well but not resting on their laurels. I’ve followed Akamai’s security offerings for years, and the platform has impressive functionality, but NeoSec is exactly what they needed. It plugs a couple of holes in their security offerings and brings a whole customer base into the Akamai fold. That’s what I’m talking about when I refer to the good ones.

    The problem is the acquisition and expansion of offerings trend is starting to gain a lot of steam, and not every vendor jumping on the bandwagon does the job as well as Akamai does.

    This leaves enterprise IT staff responsible for DevOps and DevSecOps – even straight security staff – with a new set of issues. Best-of-breed is taking a hit again, and overarching solutions are on the rise. The difference is the breadth that some of these new “platforms” offer is massive. And we know that even the good ones will have better and worse parts of the overall solution. So IT now has to start considering what vendors call a feature and how it individually compares to the competition. This will require more up-front work for evaluators. Now, a larger (and growing) list of “features” that were once “products” has to be considered piece-by-piece against the competition, and organizations must evaluate the feasibility (and cost) of implementing two (or even multiple) massive platforms to get the most critical functionality needed.

    As of this writing, point solutions that do one thing extremely well are holding up, but the trend is obvious. Those markets will be subsumed into larger offerings that may not do as well at other parts of the overall problem. Evaluators will have to be more careful and consider their options with an eye to the larger infrastructure and problem domain. Do you want a single vendor doing all of the steps of DevOps or responsible for every aspect of application security? That will be an individual decision and, if not, how the final solution/architecture looks will be a more complex discussion.

    Integration and Automation

    In our quest for integration and automation, many vendors are responding with the concatenation of tools to solve the automation part. You’ll be stuck figuring out if they’re doing it well enough for the org.

    But that’s not a problem you can’t resolve. You’ve been rocking it through staffing issues, lockdowns, growth and shrinking… Just keep rocking it. Choose the solution that makes the overall best sense for your organization, get it running and take a break; head to the beach for some relaxation time. Or whatever you do to clear your head – because the next problem will still be there when you get back, and it’s better to be relaxed when you tackle it.

  • Dynatrace Adds Generative AI Capabilities to Davis Engine

    Dynatrace Adds Generative AI Capabilities to Davis Engine

    Dynatrace today revealed it has added generative artificial intelligence (AI) capabilities to its Davis engine it uses to apply machine learning algorithms to its observability platform.

    Steve Tack, senior vice president for product management at Dynatrace, said that hypermodal approach to AI will allow DevOps teams to take advantage of probabilistic AI capabilities provided by Davis CoPilot that are enabled by large language models (LLMs) originally developed by OpenAI.

    The generative AI capabilities effectively provide DevOps teams with a tool that surfaces workflow recommendations via a natural language interface. The recommendations are based on historical data such as sales and customer experience trends, seasonality and cloud application health. It is also able to analyze dependencies across large sets of data while retaining context accessed via the Dynatrace Grail data lakehouse and the Dynatrace Smartscape application visualization and mapping framework.

    Dynatrace is now making a case for a multimodal AI platform that uses a common set of metrics, traces, logs, user behavior and topology to enable machine learning algorithms to predict anomalies and causal-AI dependencies to determine the root cause of an IT issue and then leverage generative AI to provide recommendations to resolve it. The company is forecasting IT teams will achieve 10% to 20% productivity improvements year-over-year as a result.

    It’s too early to determine the full extent to which a multimodal approach to AI will transform IT management, but it’s clear that as IT operation teams become more productive, more time will be freed up for innovation, noted Tack. Many of the manual tasks that IT teams still need to perform divert time away from building and deploying additional applications, he added.

    Naturally, there’s a lot of speculation concerning the impact AI will have on DevOps. Some contend it’s only a matter of time before the entire software engineering process is automated. As those advances are made, the cost of building applications will effectively drop to zero. Others argue that AI will augment DevOps teams in a way that makes it simpler to manage IT at scale using either the same number or possibly even fewer engineers.

    The one thing that is certain is that AI will soon be pervasive, which will drive the adoption of automation frameworks as organizations look to operationalize the insights surfaced by AI platforms. As rich as the insights any AI model surfaces might be, they only provide real value when integrated with an automation framework, noted Tack.

    Ultimately, most DevOps professionals will not want to work for organizations that don’t provide them with AI tools that make it more likely for them to be successful. Organizations that embrace AI may not have a sustainable competitive advantage when every other organization is doing the same, but those that don’t will soon be left behind. Those that succeed will benefit from managing application environments at a previously unprecedented level of scale at minimal additional cost. The challenge is determining which tasks will be automated with an eye toward planning how DevOps roles will need to evolve.

  • Harnessing AI for Automated and Toil-Free SRE

    Harnessing AI for Automated and Toil-Free SRE

    In my recent blog Revolutionizing the Nine Pillars of SRE With AI-Engineered Tools, I indicated that AI can help reduce toil by automating more complex tasks that were previously challenging to automate. Machine learning models can predict system behavior, enabling proactive responses. In this blog, I explain in more detail how AI-engineered tools can be used to improve toil reduction and automation.

    AI Use Cases for Toil Reduction and Automation

    In each of the following use cases, AI not only reduces toil but also contributes to improving system reliability, efficiency and scalability, forming a critical part of modern site reliability engineering (SRE) practices.

    Anomaly Detection and Predictive Maintenance: AI can monitor system logs and operational metrics to detect anomalies, predict system failures and schedule maintenance. This leads to fewer unexpected issues and lower downtime. Tools such as Splunk‘s Machine Learning Toolkit and Elastic’s Machine Learning features can be used for this purpose.

    Automated Testing: AI can be used to automate testing procedures, ensuring code reliability before deployment and reducing the toil of manual testing. Tools like Mabl or Testim use machine learning to create, execute and maintain tests, reducing the need for human intervention.

    Incident Triage and Resolution: AI can analyze incident data, diagnose issues, suggest solutions and, in some cases, automate the resolution process. Tools such as PagerDuty’s Event Intelligence or BigPanda help automate these processes and reduce resolution times.

    Capacity Planning and Resource Allocation: AI can predict system load and adjust resources accordingly to ensure optimal performance and scalability. Dynatrace and Datadog are examples of AI-driven platforms that can provide predictive analytics and capacity planning.

    Proactive Fault Isolation: AI can help isolate faults before they escalate into significant issues, reducing downtime and maintaining system reliability. IBM’s Watson AIOps and Moogsoft’s AIOps platform use AI to quickly isolate and remediate faults.

    Security and Threat Detection: AI can monitor system activity, detect threats and prevent security incidents, reducing the toil of manual monitoring and intervention. Tools like Darktrace and CrowdStrike Falcon use AI for cybersecurity.

    Network Optimization: AI can analyze network traffic and performance data to optimize network configurations and improve system performance. Tools such as Mist (from Juniper Networks) and Cisco’s DNA Center can provide these functionalities.

    Code Review and Technical Debt Management: AI can analyze code changes and identify issues and potential technical debt, providing guidance for incremental code improvements. Tools like DeepCode and CodeClimate can help manage and reduce technical debt.

    Overcoming Challenges

    Organizations must overcome challenges with their people, processes or technologies when transforming SRE practices to using AI tools for toil reduction and automation.

    Lack of Skilled Personnel: AI technologies often require a level of expertise that may not exist within current teams. This lack of skill can be a significant barrier to the successful implementation and usage of AI tools. Invest in training existing staff and consider hiring new team members with the necessary skill sets. There are plenty of resources and courses available online to train your teams on AI tools and technologies.

    Data Quality Issues: AI tools rely on quality data to deliver reliable insights. Data might be unclean, unstructured or siloed across different systems, which can hinder the effectiveness of AI. Implement robust data management and governance practices to ensure your data is clean, structured and accessible. AI tools can also be used to assist in data cleansing and structuring processes.

    Resistance to Change: People can be resistant to new technologies, especially when it comes to something as transformative as AI. This resistance can slow down or even halt the transition to AI-based SRE practices. Develop a strong change management strategy, which could involve regular communication about the benefits and importance of the change, provide training and support and gradually integrate AI tools into existing workflows to allow for a smoother transition.

    Integration with Existing Systems: AI tools need to work in tandem with existing IT systems, tools and processes. Integration issues can prevent AI tools from accessing necessary data or functioning as expected. Plan the integration process carefully, ensuring that the selected AI tools are compatible with your existing systems. Where possible, choose AI solutions that offer flexible APIs and other integration options.

    High Costs: Implementing AI tools can require substantial investment, including purchasing or subscribing to the tools, integrating them into your existing systems and training staff. Calculate the return on investment (ROI) before implementation to understand the potential benefits and savings the AI tools can provide in the long run. Look for scalable solutions that allow you to start small and increase your investment as you see value.

    Compliance and Security Concerns: The use of AI tools, particularly those that leverage cloud computing, may raise concerns about data security and compliance with various regulations. Conduct a thorough risk assessment before implementing any AI tool. Choose vendors that adhere to industry-standard security protocols and offer comprehensive security features. Consider working with a third-party auditor to ensure compliance.

    Summary

    As organizations journey toward greater operational efficiency and reliability through SRE, the transformative potential of AI is becoming increasingly clear. AI-driven tools are revolutionizing various facets of SRE, including toil reduction, automation and defining service-level indicators, objectives and agreements. These innovative technologies can automate complex tasks, predict system behavior, refine performance targets, optimize deployments and aid in effective incident management. For example, AI tools such as Datadog, Dynatrace and New Relic can provide actionable insights into your systems, while others like Nobl9 can use machine learning to define SLOs based on historical performance data.

    However, the road to this AI-infused future is not without its challenges. Teams might grapple with issues such as a lack of skilled personnel, data quality, resistance to change, system integration, high costs and security concerns. Yet, with the right approach, these hurdles can be overcome. By investing in training and hiring skilled personnel, implementing robust data management practices, fostering a culture receptive to change and carefully planning the integration of AI tools, organizations can leverage the power of AI. Calculating ROI before implementation and choosing vendors who adhere to stringent security protocols can further ensure success. The use of AI in SRE represents a powerful convergence of technology and practice that is reshaping the landscape of modern IT operations.
  • Five Great DevOps Job Opportunities

    Five Great DevOps Job Opportunities

    DevOps.com is now providing a weekly DevOps jobs report through which opportunities for DevOps professionals will be highlighted to better serve our audience.

    Our goal in these challenging economic times is to make it easier for DevOps professionals to advance their careers.

    Of course, the pool of available DevOps talent is still relatively constrained, so when one DevOps professional takes on a new role it tends to create an opportunity for others.

    The five job postings shared this week are selected based on the company looking to hire, the vertical industry segment and, naturally, the pay scale being offered.

    We’re also committed to providing additional insights into the state of the DevOps job market. In the meantime, for your consideration:

    Indeed.com

    SAP
    San Francisco, California
    DevOps Engineer
    $141,378 to $162,000

    CareeerBuilder.com

    Citigroup
    Tampa, Florida
    DevOps Lead Engineer
    $110,090 to $165,130

    Dice.com

    Cognizant Technology Solutions
    Seattle, Washington
    xStore DevOps Lead
    $114,365 to $127,538

    LinkedIn

    J.Crew
    New York, New York
    Lead DevOps Engineer
    $108,800 to $136,000

    SimplyHired.com

    Hearst Media Services
    New York, New York
    DevOps Engineer
    $98,900 to $125,000

  • Syslogs in Linux: Understanding Facilities and Levels

    Syslogs in Linux: Understanding Facilities and Levels

    Recently, I found myself in the position of investigating the root cause of a booting failure in an embedded device. To diagnose the problem effectively, I relied on syslogs, which proved to be invaluable. Syslogs, or system logs, are a crucial element of Linux systems, as they capture and retain important data about different events and actions. In this article, we will emphasize the importance of syslogs in Linux and examine the various facilities and levels utilized to classify and prioritize log messages.

    Understanding Facilities

    Facilities in syslogs are used to categorize log messages based on their sources or purposes. They provide a way to differentiate between various components of a Linux system.

    Photo from RFC5424

    Understanding Levels

    Syslog levels indicate the severity or importance of log messages. They help prioritize and filter log entries based on their significance.

    Photo from RFC5424

    An Example

    For easier debugging, you can clear out the syslog before running the user application for investigation and to get fewer lines of logs. To clear out the syslogs, you can either truncate or delete them.

    Remember that clearing syslogs removes log history, so ensure you don’t require the information for troubleshooting, analysis, or compliance purposes before clearing the logs. Additionally, clearing logs may require administrative privileges, so you may need to use the command or run the commands as the root user.

    After clearing the syslog, remember to restart the rsyslog. Otherwise, your application won’t be able to log your user-level messages. Below is an example in Ubuntu on how to truncate, remove and restart the service.

    This is a simple C++ code that generates a log message for the facility user that indicates an informational message.

    In this example, we include the <syslog.h> header file, which provides the necessary functions and constants for syslog logging. The <openlog() function is used to open a connection to the syslog service, specifying a custom identifier (“SyslogSampleApp”) for our application, the logging options (LOG_PID to include process ID), and the facility (LOG_USER for user-level messages).

    We then use the syslog() function to generate log messages of different levels. In this case, we create a user-level message using LOG_INFO. You can adjust the log levels based on your specific needs.

    Finally, we close the syslog connection closelog() to release any resources associated with the syslog service.

    Viewing your syslog depends on the Linux distribution that you’re using. /var/log/syslog is used for Debian and Ubuntu while /var/log/messages is used for Red Hat and CentOS.

    Conclusion

    Syslogs are an integral aspect of Linux systems, serving as a foundation for efficient monitoring, troubleshooting and analysis. They play a crucial role in capturing and organizing log messages across various facilities and levels. This categorization allows for valuable insights into system behavior, promotes effective issue resolution, and contributes to the overall maintenance of system health and security. It is essential to utilize the appropriate log level, such as LOG_INFO, to ensure that the syslog remains uncluttered and focused on the relevant scenario, avoiding the unnecessary inclusion of LOG_ERR entries.

  • AI ‘is Getting Worse’ ¦ AI ‘Will Lose India Jobs’ (Probably Isn’t ¦ Probably Won’t)

    AI ‘is Getting Worse’ ¦ AI ‘Will Lose India Jobs’ (Probably Isn’t ¦ Probably Won’t)

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week, a conundrum: On the one hand, researchers say ChatGPT is losing the plot; and on the other, we hear outsourced coding jobs in India will be replaced by AI. (more…)

  • Google Announces Availability of iPaaS Service

    Google Announces Availability of iPaaS Service

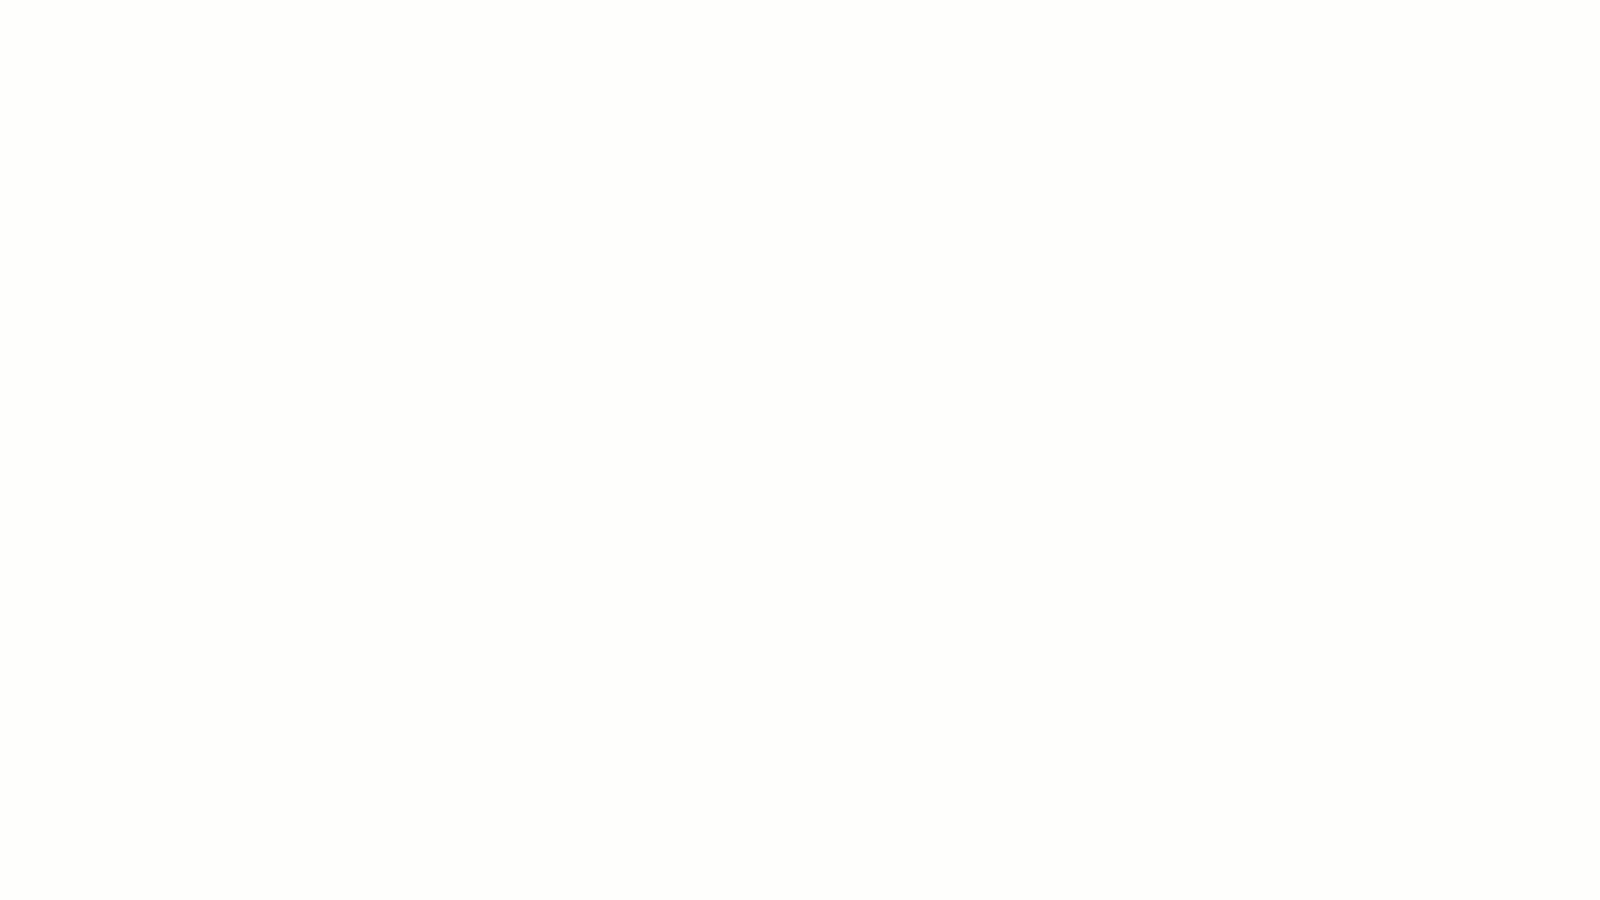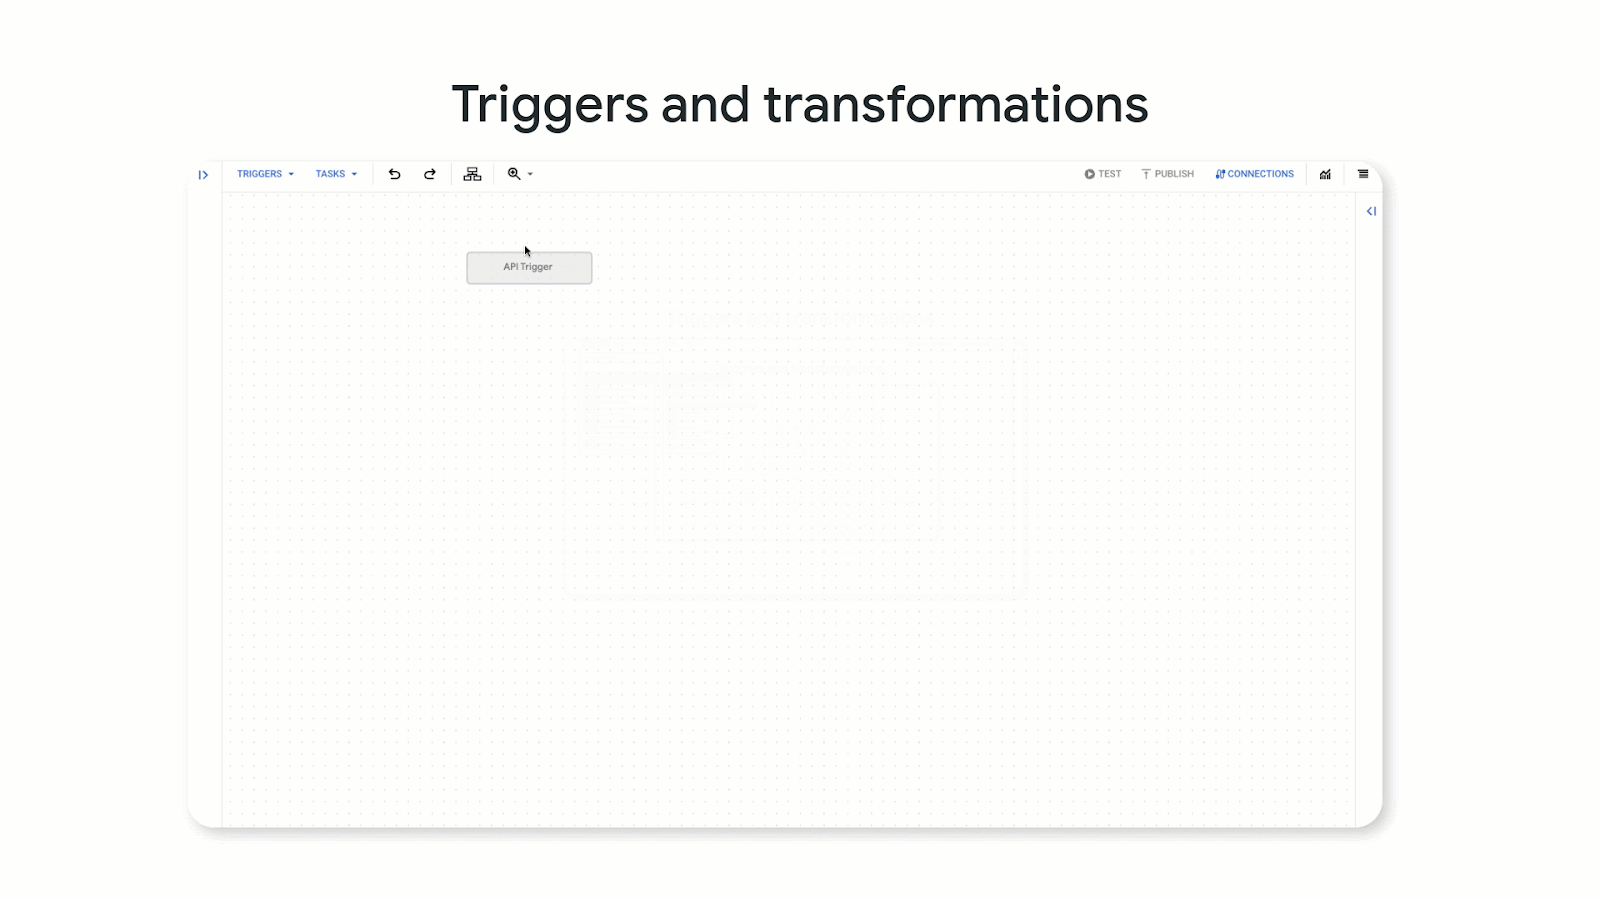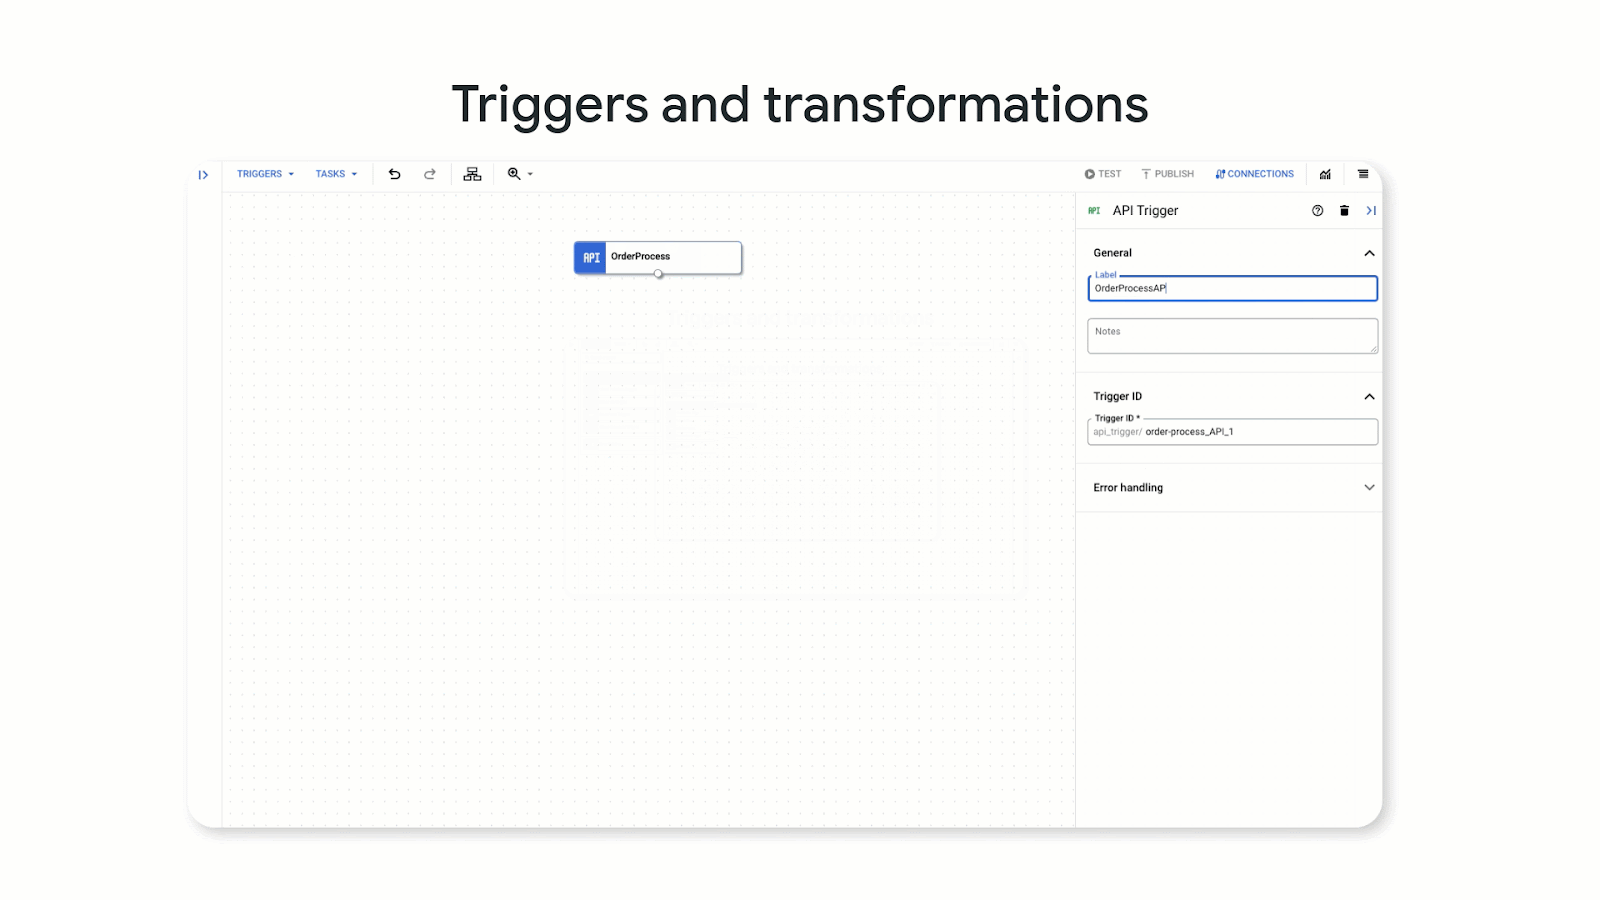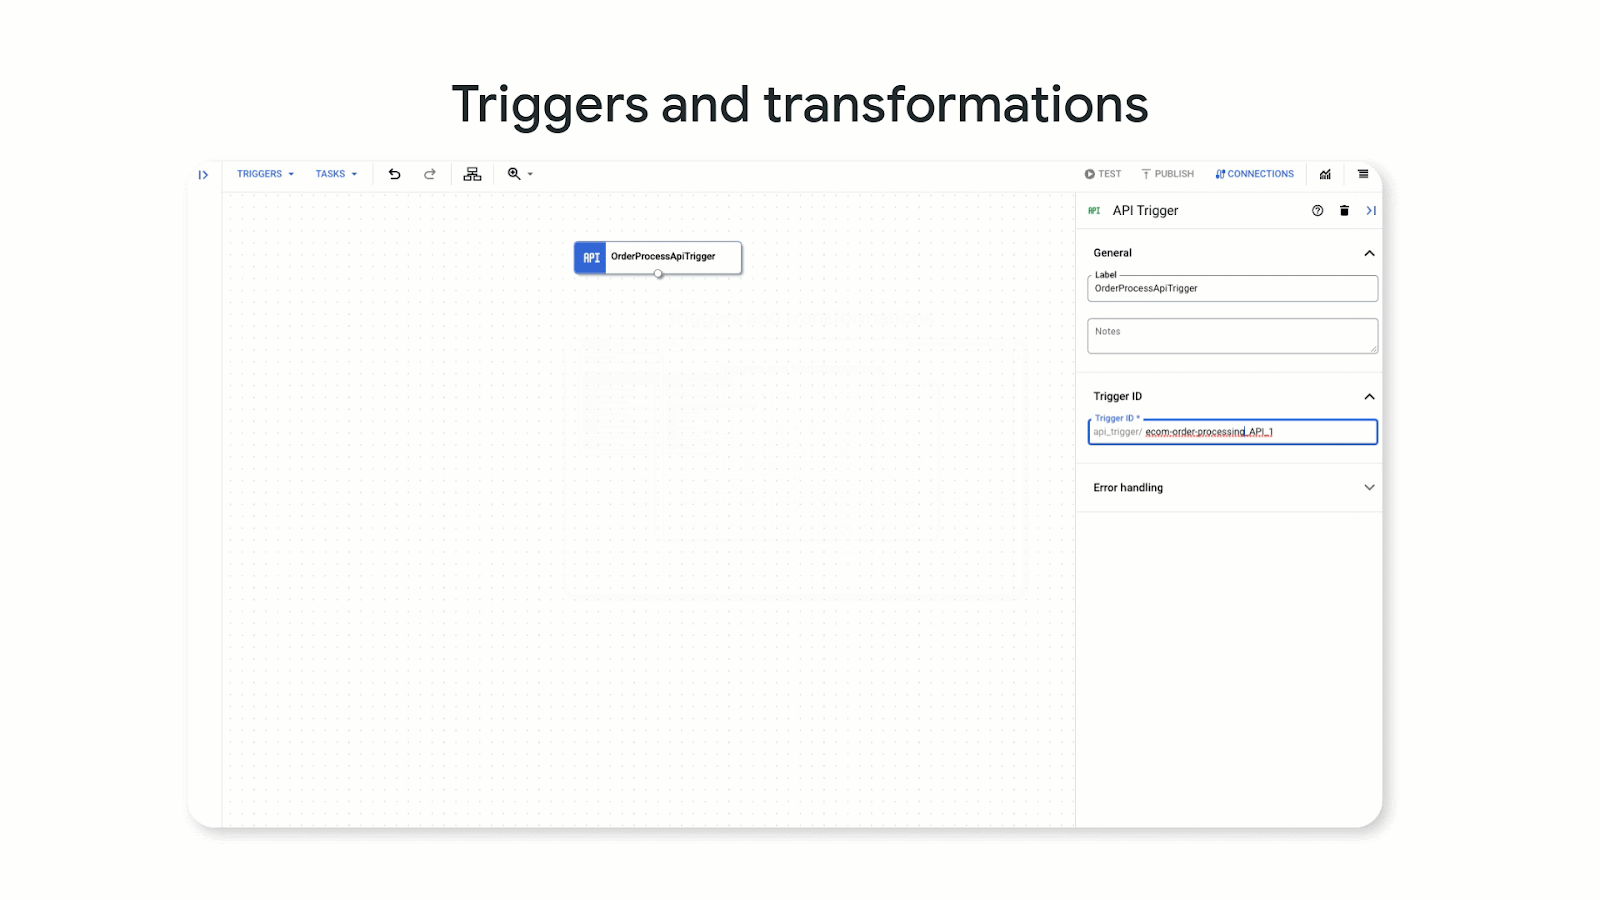
    Google today made available an integration platform-as-a-service (iPaaS) capable of invoking a range of methods to integrate applications.

    Initially developed for the Apigee application programming interface (API) management platform Google acquired in 2016, the Application Integration service can now, for example, also consume a publish and subscribe event or an event driven through a Salesforce platform.

    Amit Zavery, vice president and general manager for Google Platform, said the Application Integration service provides IT organizations with all the benefits of an iPaaS without requiring them to stand up and manage an integration platform themselves.

    The Google Application Integration service also provides access to a Visual Integration Designer tool that can be used to build workflows using a low-code tool. In total, there are now more than 75 connectors that can be used to integrate multiple Google Cloud services and third-party platforms that can run in either a cloud or on-premises IT environment, said Zavery.

    In general, visual tools are transforming how integrations are created and expanded within organizations, noted Zavery. Rather than using lower-level procedural code, a visual tool enables developers to employ low-code to create integrations. That makes it simpler to collaborate with business users that can now more easily participate in developing workflows.

    In fact, in some cases, business users, otherwise known as citizen developers, have enough technical acumen to create their own workflows using low-code tools.

    There are, naturally, going to be plenty of complex integration challenges that will require procedural code, but the bulk of the integrations required today are not especially complex.

    Regardless of who creates the integration, the number of them being employed across an enterprise organization continues to increase as more digital business transformation initiatives are launched. Developers are not going to be able to keep pace with the demand for those integrations if they rely solely on procedural code. The only way to effectively reduce the backlog for integrations is to rely more on visual tools to construct them. In most cases, the integration being created is relatively trivial. The only reason it wasn’t created sooner is there are not enough developers available to complete that task using procedural code.

    There are, of course, no shortage of iPaaS options available. As more workloads are deployed in the cloud, Google is betting the center of gravity for integration will shift toward the places where modern microservices-based workloads are deployed to reduce overall latency.

    It’s not clear whether organizations still view integration as an afterthought versus employing an integration platform around which all applications revolve. That latter approach tends to reduce the total cost of integration when compared to using multiple point products that are not managed via single framework, noted Zavery.

    Ultimately, IT teams that adopt an iPaaS are able to focus more on higher-value IT tasks. The issue is determining which integration projects really require professional developers with lots of integration expertise and which, via a low-code tool, can be handled by almost any developer.

  • Postman Acquires Akita Software to Gain API Observability

    Postman Acquires Akita Software to Gain API Observability

    Postman today announced it has acquired Akita Software to gain access to a platform for monitoring and observing application programming interfaces (APIs).

    The first integration of the respective products offered by both companies will arrive in beta this fall.

    Postman CEO Abhinav Asthana said the acquisition of Akita Software will make it much simpler for organizations to discover what APIs are being employed across an enterprise. A recent Postman survey found that 28% of developers are now deploying APIs at least once per week.

    The Akita Software platform will make it simpler for organizations to discover both rogue APIs that have been created by a shadow IT project and zombie APIs that have been inadvertently left exposed long after they are needed.

    Akita Software’s CEO Jean Yang said the integration with Postman’s API management platform will provide a rich source of data that can be used to add artificial intelligence (AI) capabilities to Akita’s API observability platform. For example, generative AI capabilities should make it simpler to create summaries in natural language that explain the calls an API is making to specific data sources.

    In addition, the combined company will be in a better position to enable organizations to better secure their APIs after deployment by surfacing anomalous behavior indicative of an API that is being used to exfiltrate data, she added.

    The merger with Postman will, in effect, enable the combined entity to provide a complete ecosystem for managing APIs, noted Yang.

    Most APIs are used primarily to interconnect internal-facing applications and systems, with a subset used to integrate partners. Only a relatively small percentage of APIs are externally facing in the sense that they expose data to the internet. Many organizations, however, fail to appreciate how quickly an internally facing API can become externally facing over the course of its life cycle. As such, IT teams need tools and platforms that can manage and secure APIs as they evolve.

    As APIs continue to play a crucial role in advancing business goals, there is a clear need for increased visibility as the types of APIs employed also continue to expand. Most APIs in use today are based on the REST format, but there are also APIs based on GraphQL, event-driven architecture and various messaging platforms. None of these newer APIs will supplant REST APIs any time soon. Rather, they are being applied to drive additional processes alongside REST APIs.

    In the longer term, it’s not clear how many APIs will be managed by the developers that created them versus a centralized DevOps team. However, the more APIs that are deployed in a production environment, the less feasible it becomes for developers to manage their life cycle. The challenge is making sure there is some type of structured workflow in place that, at the very least, makes everyone involved in the process aware that a new API has been created and deployed.

  • Defining ‘Best’

    Defining ‘Best’

    (Note: For the last few years, I’ve been sparse with naming vendors in blogs. This one will have more than usual as examples.)

    We all have a ton of tools at our disposal. From installed tools to products to open source, we can solve any given problem in fifteen different ways. Several years ago, I wrote a blog about using what you have to get the most out of your purchases. There are several “platforms” that solve a lot more problems than just what you are currently using them for. At the time, my shining example was F5’s BIG-IP. That thing can do everything: Networking in your data center and probably cooking your breakfast, too. At the time, most people used the box to handle load balancing but then were concerned about the cost. Duh? I mean, you have a tool that can solve a fistful of problems … and you’re using it for load balancing. I mean, it’s very good at load balancing, don’t get me wrong. But I feel like quoting Marvin from The Hitchhiker’s Guide to the Galaxy. “Here I am with a brain the size of a planet and they ask me to pick up a piece of paper. Call that job satisfaction? I don’t.” (Interestingly, at the rate that generative AI is advancing, it is only a question of time before a machine throws that quote out there.)

    The thing is, investors and the hype machine told all of your vendors three things. First, that they needed a recurring revenue stream. Second, that you wanted everything as-a-service and third, that they needed to be a platform. That means that those fifteen SaaS products you’re on the hook for now want to solve all of your problems because “they’re a platform.” Some of them do a kick-arse job of it and you might very well have a SaaS license that covers whatever you need to do today.

    This is screamingly obvious for some vendors. If you’re an Akamai customer, for example, the breadth of things you can do through them is stunning. Most customers do not seem to take advantage of that to the extent they should. This is no different than that BIG-IP in your DC; it’s just as-a-service. You’re already paying for both. You should make the most of them.

    Other vendors might surprise you but  they have done the same through M&A or expanding their “platform” from marketware to reality. I have hinted at this in the not-too-distant past but will say it point-blank here. Know what your products are capable of. Tomorrow you might need some of that functionality, and knowing if it’s already in the organization (but not being used) is a big deal. Also, if the “platform” already fits into your organization, then choosing a ‘best’ solution leans toward that product line already–less integration is the best integration.

    And keep those lights on. You may have more tools than you need, but you’re managing them and keeping the organization online. You should be getting kudos for that, so I’ll offer them. Thank you. I replaced my phone this weekend and had to reconnect everything and to all of those orgs I had to log back into, reinstall or reconfigure, let me say: I am grateful for each IT person there. Even my bank, who honestly pisses me off—I’m still grateful for their IT.