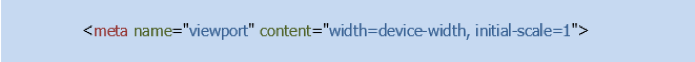Category: DevOps Practice

  • LogDNA Survey Surfaces Observability ROI Concerns

    LogDNA Survey Surfaces Observability ROI Concerns

    A Harris Poll of 200 senior engineering professionals suggests it may be a while before most DevOps teams are able to achieve true observability in their IT environments.

    The survey was conducted on behalf of LogDNA, a provider of an observability platform, and found nearly three-quarters of respondents (74%) are struggling to achieve their observability goals despite investing hundreds of thousands of dollars. In fact, well over a third (38%) said they are already investing $300,000 annually on observability tools.

    Despite those investments, less than half of respondents are very satisfied with their ability to use log data. Key areas of frustration include the challenges of collaboration with colleagues spanning multiple teams (67%), the fact that the tools are not easy to use (66%) and the routing of security events (58%).

    Nevertheless, the bulk of survey respondents said they are optimistic about observability. A full 85% of participants said they believe true observability is possible.

    LogDNA CEO Tucker Callaway said the core issue that many organizations fail to recognize is that observability is really a data literacy and management challenge. Organizations are collecting logs, metrics and traces from a wide range of tools and platforms without thinking through optimal data pipeline construction. The result is an aggregation of data that has not been normalized to simplify surfacing actionable intelligence, he said. In fact, many organizations quickly discover that all they’ve really accomplished is increase their data storage costs, said Callaway.

    In the absence of that data normalization, Callaway noted it becomes exceedingly difficult for cross-functional teams to query all the data being collected within a repository.

    At its core, observability promised to make it easier to identify IT issues before they cause a disruption. Observability in one form or another has always been a core tenet of any DevOps best practice. Initially, DevOps teams focused on continuous monitoring as the most effective way to proactively manage application environments. However, it can still take days, sometimes weeks, to discover the root cause of an issue. Observability platforms make it possible to correlate events in a way that makes it easier for analytics tools to identify anomalous behavior that might be indicative of the root cause of an IT issue.

    In contrast, traditional IT monitoring focuses on predefined metrics to identify when a specific platform or application is performing within expectations. Observability platforms combine metrics, logs and traces—a specialized form of logging—to make it easier for IT professionals to interrogate data being generated by a wide range of DevOps tools and platforms.

    Of course, the assumption is that DevOps teams actually know what queries to launch to determine what the root cause of an IT issue might be. In the longer term, machine learning algorithms should make it easier to identify anomalies within IT environments. In the meantime, however, achieving observability still requires a fair amount of DevOps expertise that is not always readily available.

    Eventually, observability will become much more automated than it generally is today. As that transition occurs, IT teams should find the ROI of observability is steadily improving.

  • New Relic: Observability Tops 2022 DevOps Agenda

    New Relic: Observability Tops 2022 DevOps Agenda

    If 2021 was the year when IT organizations became aware of the need for observability, then the coming year should see observability aspirations realized.

    A report published by observability platform provider New Relic postulates that there are no less than 11 factors converging in a way that will make observability an absolute requirement for organizations.

    At the top of that list is a simple fact: Observability is now required to drive digital business transformation initiatives that typically span multiple processes. In fact, a global survey of 1,300 IT leaders, software engineers and developers conducted by New Relic found 90% of respondents view observability as critical to the business.

    Second, as a result, observability is now starting to be applied in both pre- and post-production environments as organizations take a more holistic approach to managing the software development life cycle, the report noted.

    Third, the report suggested that IT teams are looking to make better-informed decisions based more on facts than intuition. To do this, teams are using data collected from across the enterprise application environment. In fact, the fourth factor advancing observability in the enterprise is that the cost of instrumenting application environments is dropping, which the report notes is making it easier to collect relevant data.

    The fifth and sixth factors reflect a desire to rationalize the number of monitoring tools that IT teams currently use and the fact that usage-based pricing has simultaneously made it less expensive to leverage observability platforms as needed.

    The seventh factor is the overall shift toward open source software that enables observability platform providers to collectively leverage innovations faster. The eighth factor, closely linked to the open source trend, is the rise of more complex open source platforms such as Kubernetes that require much higher visibility to successfully deploy and manage.

    The ninth trend identified in the report is increased adoption of DevOps best practices that encourage IT teams to view observability as a core tenet of any IT management strategy. The tenth factor cited by the report is the need to drive increased collaboration among IT professionals.

    Finally, the eleventh factor driving further adoption of observability is the need for increased application reliability as more organizations appreciate their dependence on software to deliver essential services.

    Buddy Brewer, a group vice president and general manager for New Relic, said now that observability platforms are becoming more accessible, the next big challenge will be teaching IT professionals what questions to ask as they troubleshoot both legacy monolithic applications and a wide range of emerging microservices-based applications. The results of those queries then need to be easily shared with both developers and internal IT operations teams that must work together to maximize application performance and availability, he added. The latter requirement is why New Relic decided to acquire CodeStream to make telemetry data available with integrated development environments (IDEs), noted Brewer.

    There is, of course, no shortage of observability platforms for IT teams to adopt. In fact, the biggest challenge now is getting every application stakeholder to agree to standardize on an observability platform—no small feat, as many DevOps teams may already have a preference for one approach over another.

  • Best of 2021 – How to Revoke JSON Web Tokens (JWTs)

    Best of 2021 – How to Revoke JSON Web Tokens (JWTs)

    As we close out 2021, we at DevOps.com wanted to highlight the most popular articles of the year. Following is the seventeenth in our series of the Best of 2021.

    One of the most common questions about JSON Web Tokens (JWTs): Once they’re issued, how can they be revoked?

    What Are JWTs?

    JSON Web Tokens are portable, industry-standard identity tokens. They are issued after a login request by a central identity server and used to identify and credential a user and grant access to resources. They can be presented by clients such as browsers and external programs. Applications and APIs can examine them to ensure the caller is properly authenticated and authorized.

    The Challenges Involved

    One of the most common questions is how to revoke them. The problem is that once they are issued, no further communication is needed with the identity server. That’s one major benefit of JWTs decentralization.

    Let’s say you use RSA public/private key signing for secure data transmission. After the IdP signs a JWT using the private key, any service that has the public key can verify the integrity of the token.

    Let’s use the Todo-Backend API as an example. The architecture might look something like this:

    Todo API

    Now, Todo-Backend can use JWT and the public key to verify the user’s ID and other attributes, and then use that ID to perform operations on that user’s data. Once the JWT has been issued, Todo-Backend doesn’t communicate with the identity provider at all. As a result, if an administrator has locked or deleted that user’s account in the identity provider, Todo-Backend won’t know about it.

    Managing Revocations Using a Distributed Event System

    The most common way to revoke access to resources protected by a JWT involves setting its duration to a short period of time and revoking the refresh token so that the user can’t generate a new token. This does not revoke the JWT per se; it does solve the root issue, which is to limit access.

    In other words, you can set the JWT’s expiration duration to a short period (e.g., anywhere from a few seconds to, say, ten minutes) and set the refresh token’s expiration duration to a longer period (e.g., a two-week or two-month window).

    During the normal flow, the Todo API would accept the JWT until it expires, at which time access would be denied. At that time the client could present the refresh token to the identity provider, which would send a new JWT to the client. That new JWT would be valid for another ten minutes.

    An administrator can, at the identity provider, revoke the refresh token at any time. Any subsequent request for a new JWT by a client holding that refresh token would fail and access to the Todo API would be lost.

    However, while ten minutes isn’t long, this timeframe still comes with risks.

    One strategic way to handle this challenge is to set up a distributed event system that notifies services when refresh tokens have been revoked. Upon receiving this event broadcast, backends/services would update a local cache that lists users with revoked refresh tokens. After a JWT is verified, this cache would then be checked to determine whether or not access should be revoked.

    This distributed event method truly revokes the JWT, rather than simply waiting for it to expire, as mentioned above.

    An Example of Revoking JWTs

    Here’s a sample solution that provides support for events and webhooks that can be used to implement this revocation strategy. In this example, when a user logs out or has their refresh token otherwise revoked, a jwt.refresh-token.revoke event is emitted. This includes the user ID and the application for which the revocation occurred. It also includes the JWT lifespan for this application (in the below case, 600 seconds). Any JWT for this user that was issued before 600 seconds from the point in time when this event was received is thus revoked.

    For example:

    • User logs in, and JWT ‘abc’ is issued at 1:11pm. JWT is good until 1:21
    • User logs out at 1:15. Entry is added stating that any JWT for this application and user expiring before 1:25 is revoked.
    • Application tries to use JWT ‘abc’ at 1:16. Todo-Backend does not deliver data because this JWT is on the denylist.
    • User logs in, and a new JWT ‘def’ is issued at 1:18. JWT is good until 1:28.
    • Application tries to use JWT ‘def’ at 1:19. Todo-Backend delivers data because this JWT is good until 1:28 and is therefore not on the denylist.

    JWT Revoke

    What you need to do is write a simple webhook that will receive this event and inform JWTManager that the refresh token for applicationId for this user has been revoked.

    JWT webhook

    JWTManager maintains a list of user IDs whose JWTs are revoked. You could also use JWT IDs (the `jti` claim), which, in some cases, might be simpler. JWTManager also launches a thread to clean up the cache to remove expired users and avoid running out of memory.

    Is valid

    For each API call, in addition to all the other checks that should be performed against a JWT (verifying the signature, expiration, issuer and so on), the backend needs to check validity with JWTManager.

    configure webhook

    As a final step, configure the webhook:

    JWT webhook

    The Revocation Process, Simplified

    Using the process described above, you can revoke a user’s refresh token and broadcast the event using a webhook. The webhook receivers then update JWTManager, which will render JWTs for that user unusable.

    The good news is that you can use a webhook and event system to build this feature into your application quickly. You can also write JWTManager implementations into Java, Node and other client libraries for future use. Other languages, such as Ruby, have denylist implementations already written.

    Ultimately, all that’s required are the use of refresh tokens, an API that enables revocation of refresh tokens and a system for distributing the revocation event. This solution should work well with most systems, even large systems with numerous backends.

  • Best of 2021 – Transform Legacy Java Apps to Microservices

    Best of 2021 – Transform Legacy Java Apps to Microservices

    As we close out 2021, we at DevOps.com wanted to highlight the most popular articles of the year. Following is the sixteenth in our series of the Best of 2021.

    Velocity is one of the major tenets of DevOps, and anything that maintains or improves velocity benefits the overall process. Yet, there are still many speed bumps in the DevOps process that threaten to derail progress and slow DevOps processes to a crawl. One of the biggest speed bumps arises when transforming legacy monolithic applications into something more cloud-friendly—namely, microservices.

    Microservices are clearly the future of applications developed for the cloud; research giant IDC predicts that 90% of all new apps deployed by 2022 will feature microservices architectures. IDC also notes the primary benefits of microservices are the improvements to developers’ ability to design, debug, update and leverage third-party code. Although DevOps tends to be about developing internal code, the benefits offered by a microservices architecture remain much the same.

    Microservices: Getting There

    Moving toward a microservices architecture can be straightforward or complex, depending on the path an organization is taking and where they begin. For example, if the goal is to transform legacy applications into microservices, the process can be complex and tedious. Transformation of legacy applications often means manually disassembling legacy code and breaking it up into standalone code elements that will run as microservices. That greatly complicates things for the DevOps pipeline, where fast iteration of existing code is the norm, not the exception.

    However, there are tools coming to market that can ease the process. One such tool is vFunction, which recently came out of stealth with the mission to transform monolithic Java apps into microservices. 

    microservices

    vFunction has an interesting approach to that process. The vFunction platform is deployed locally, where the vFunction Java virtual machine (JVM) agent examines legacy applications and gathers data which is then collected on the vFunction server. From there, software architects can further investigate the collected information about the legacy applications, and start designing a microservices architecture to modernize the codebase. “Once developers are satisfied with the design, vFunction generates a service specification file, which contains all the information required to create the microservice,” said vFunction CEO and co-founder Moti Rafalin. “That file is used by our automation engine, which scans the original code and copies the relevant artifacts to create the new service.”

    Rafalin said that vFunction leverages supervised learning techniques, graph theory and clustering algorithms to identify dead code and code anomalies that could prevent a clean breakdown, or “decomposition,” of the legacy application. Ultimately, vFunction has the potential to automate many of the manual steps that DevOps engineers used to perform to break monolithic applications into microservices. According to Rafalin, vFunction makes the process as much as 15 times faster and can achieve somewhere between 80% to 95% automation. Currently, vFunction is focused solely on Java, which it deems the biggest opportunity today. However, the company has plans to support applications written in other languages in the future.

    Beyond newcomer vFunction, there are other ways to deal with moving legacy Java applications into the cloud. One example is Anthos, which is a managed application platform that extends Google Cloud services into DevOps environments. Another is IBM’s Mono2Micro, which is an AI-based, semi-automated toolset to assist with refactoring monolithic Java applications. 

    For those looking to build microservices-based applications from scratch, numerous tools exist. Most interesting are the development environments that use rapid application development (RAD) techniques and leverage low-code models. There are dozens of RAD platforms available; prime examples being WaveMaker , OutSystems and AgilePoint.

    In most cases, those moving legacy applications to a microservices model will usually select numerous tools, based on the particular use case. For some, it may be easier to rewrite smaller legacy applications; for others, refactoring may be the only way to capture the intellectual property in legacy applications. Either way, carefully selecting the appropriate tools goes a long way towards maintaining velocity in the DevOps realm. Maintaining that velocity proves critical for building cloud-friendly applications on budget and on time. 

    “Unless one modernizes those monolithic applications to be cloud-native, they end up requiring very large machines and often end up paying more to the cloud providers,” Rafalin said. “Organizations now understand that, if they want the true benefits of the cloud, they need to modernize these apps. And this starts with adopting an architecture that includes microservices, APIs, and modern design principles.”

    The lesson is to choose wisely, and select toolsets that support scale as well as growth, and that can support the requirements of microservices.

  • Best of 2021 – Nine Pillars of DevOps Best Practices

    Best of 2021 – Nine Pillars of DevOps Best Practices

    As we close out 2021, we at DevOps.com wanted to highlight the most popular articles of the year. Following is the fourteenth in our series of the Best of 2021.

    In a prior blog I explained my 27-factor DevOps assessment model which includes nine pillars of DevOps and three dimensions of people, process and technology.

    The nine pillars represent categories of practices. In this blog, I include examples of practices for each of the nine pillars. In a future blog I will explain how to use these practices to conduct a gap assessment for your DevOps practices.

    Leadership Practices for DevOps

    • Leaders demonstrate a long-term vision for organizational direction and team direction.
    • Leaders intellectually stimulate the team by encouraging them to ask new questions and question basic assumptions about the work.
    • Leaders provide inspirational communication that inspires pride in being part of the team, says positive things about the team, inspires passion and motivation and encourages people to see that change brings opportunities.
    • Leaders demonstrate support by considering others’ personal feelings before acting, being thoughtful of others’ personal needs and caring about individuals’ interests.
    • Leaders promote personal recognition by commending teams for better-than-average work, acknowledging improvements in the quality of work and personally complimenting individuals’ outstanding work.

    Collaborative Culture Practices for DevOps

    • The culture encourages cross-functional collaboration and shared responsibilities and avoids silos between Dev, Ops and QA.
    • The culture encourages learning from failures and cooperation between departments.
    • Communication flows fluidly across the end-to-end cross-functional team using collaboration tools where appropriate (for example Slack, HipChat, Yammer).
    • The DevOps system is created by an expert team, and reviewed by a coalition of stakeholders including Dev, Ops and QA.
    • Changes to end-to-end DevOps workflows are led by an expert team, and reviewed by a coalition of stakeholders including Dev, Ops and QA.
    • DevOps system changes follow a phased process to ensure the changes do not disturb the current DevOps operation. Examples of implementation phases include: proof of concept (POC) phase in a test environment, limited production and deployment to all live environments.
    • Key performance indicators (KPIs) are set and monitored by the entire team to validate the performance of the end-to-end DevOps pipeline, always. KPIs include the time for a new change to be deployed, the frequency of deliveries and the number of times changes fail to pass the tests for any stage in the DevOps pipeline.

    Design-for-DevOps Practices for DevOps

    • Products are architected to support modular independent packaging, testing and releases. In other words, the product itself is partitioned into modules with minimal dependencies between modules. In this way, the modules can be built, tested and released without requiring the entire product to be built, tested and released all at once.
    • Applications are architected as modular, immutable microservices ready for deployment in cloud infrastructures in accordance with the tenets of 12-factor apps, rather than monolithic, mutable architectures.
    • Software source code changes are pre-checked with static analysis tools, prior to commit to the integration branch. Static analysis tools are used to ensure the modified source code does not introduce critical software faults such as memory leaks, uninitialized variables, and array-boundary problems.
    • Software code changes are pre-checked using peer code reviews prior to commit to the integration/trunk branch.
    • Software code changes are pre-checked with dynamic analysis tests prior to committing to the integration/trunk branch to ensure the software performance has not degraded.
    • Software changes are integrated in a private environment, together with the most recent integration branch version, and tested using functional testing prior to committing the software changes to the integration/trunk branch.
    • Software features are tagged with software switches (i.e., feature tags or toggles) during check-in to enable selective feature-level testing, promotion and reverts.
    • Automated test cases are checked in to the integration branch at the same time code changes are checked in, together with evidence that the tests passed in a pre-flight test environment.
    • Developers commit their code changes regularly, at least once per day.

    Continuous Integration Practices for DevOps

    • A software version management (SVM) system is used to manage all source code changes. (Git, Perforce, Mercurial, etc.)
    • A software version management (SVM) system is used to manage all versions of code images changes used by the build process. (Git, Perforce, Mercurial, etc.)
    • A software version management (SVM) system is used to manage all versions of tools and infrastructure configurations and tests that are used in the build process. (Git, Perforce, Mercurial, etc.)
    • All production software changes are maintained in a single trunk or integration branch of the code.
    • The software version(s) for supporting each customer release are maintained in a separate release branch to support software updated for each release.
    • Every software commit automatically triggers a build process for all components of the module that has code changed by the commit. The system is engineered such that resources are always sufficient to execute a build.
    • Once triggered, the software build process is fully automated and produces build artifacts, provided the build time checks are successful.
    • The automated build process checks include unit tests.
    • Resources for builds are available on-demand and never block a build.
    • CI builds are fast enough to complete incremental builds in less than an hour.
    • The build process and resources for builds scale up and down automatically according to the complexity of the change. If a full build is required, the CI system automatically scales horizontally to ensure the builds are completed as quickly as possible.

    Continuous Testing Practices for DevOps

    • Development changes are pre-flight tested in a clone of the production environment prior to being integrated to the trunk branch. (Note: “production environment” means “variations of customer configurations of a product.”)
    • New unit and functional regression tests that are necessary to test a software change are created together with the code and integrated into the trunk branch at the same time the code is. The new tests are then used to test the code after integration.
    • A test script standard is used to guide test script creation, to ensure the scripts are performing the intended test purpose and are maintainable.
    • Tests are selected automatically according to the specific software changes. CT is orchestrated dynamically, whereby the execution of portions of the CT test suites may be accelerated, or skipped entirely, depending on how complex or risky the software changes are.
    • Test resources are scaled automatically according to the resource requirements of specific tests selected and the available time for testing.
    • Release regression tests are automated. At least 85% of the tests are fully automated and the remaining are auto-assisted if portions must be performed manually.
    • Release performance tests are automated to verify that no unacceptable degradations are released.
    • Blue/green testing methods are used to verify deployments in a staging environment before activating the environment to live. A/B testing methods are used together with feature toggles to try different versions of code with customers in separate live environments. Canary testing methods are used to try new code versions on selected live environments.
    • The entire testing life cycle, which may include pre-flight, integration, regression, performance and release acceptance tests are automatically orchestrated across the DevOps pipeline. The test suites for each phase include a predefined set of tests that may be selected automatically according to predefined criteria.

    Elastic Infrastructure Practices for DevOps

    • The data and executable files needed for building and testing builds are automatically archived frequently and can be reinstated on demand. Archives include all release and integration repositories. If an older version of a build needs to be updated, then the environment for building and testing that version can be retrieved and reinstated on demand and can be accomplished in a short time (for example, minutes to hours.)
    • Build and test processes are flexible enough to automatically handle a wide variety of exceptions gracefully. If the build or test process for a component is unable to complete, then the process for that failed component is reported and automatically scheduled for analysis, but build and test processes for other components continue. The reasons for the component failure are automatically analyzed and rescheduled if the reason for the failure can be corrected by the system; if not, then it is reported and suspended.
    • System configuration management and system inventory is stored and maintained in a configuration management database (CMDB).
    • Infrastructure changes are managed and automated using configuration management tools that assure idempotency.
    • Automated tools are used to support immutable infrastructure deployments.
    • Equal performance for all. The user performance experience of the build and test processes by different teams are consistent for all users, independent of location or other factors. There are SLAs and monitoring tools that ensure the user performance experience is consistent for all users.
    • Fault recovery mechanisms are provided. Build and test system fault monitoring, fault detection, system and data monitoring and recovery mechanisms exist. They are automated and are consistently verified through simulated failure conditions.
    • Infrastructure failure modes are frequently tested.
    • Disaster recovery procedures are automated.

    Continuous Monitoring Practices for DevOps

    • Logging and proactive alert systems make it easy to detect and correct DevOps system failures. Logs and proactive system alerts are in place for most DevOps component failures, and are organized in a manner to quickly identify the highest-priority problems.
    • Snapshot and trend results of each metric from each DevOps pipeline stage (for example, builds, artifacts, tests) are automatically calculated in process and visible to everyone in the Dev, QA and Ops Teams.
    • Key performance indicators (KPIs) for the DevOps infrastructure components are automatically gathered, calculated and made visible to anyone on the team that subscribes to them. Example metrics are availability (uptime) of computing resources for CI, CT and CD processes, time to complete builds, time to complete tests, number of commits that fail and number of changes that need to be reverted due to serious failures.
    • Metrics and thresholds for DevOps infrastructure components are automatically gathered, calculated and made visible to anyone on the team that subscribes to them. Example metrics are availability (uptime) of computing resources for CI, CT and CD processes, time to complete builds, time to complete tests, number of commits that fail and number of changes that need to be reverted due to serious failures.
    • Process analytics are used to monitor and improve the integration, test and release process. Descriptive build and test analytics drive process improvements.
    • Predictive analytics are used to dynamically adjust DevOps pipeline configurations. For analysis of test results, data may indicate a need to concentrate more testing in areas that have a higher failure trend.

    Continuous Security Practices for DevOps

    • Developers are empowered and trained to take personal responsibility for security.
    • Security assurance automation and security monitoring practices are embraced by the organization.
    • All information security platforms that are in use expose full functionality via APIs for automation capability.
    • Proven version control practices and tools are used for all application software, scripts, templates and blueprints that are used in DevOps environments.
    • Immutable infrastructure mindsets are adopted to ensure production systems are locked down.
    • Security controls are automated so as not to impede DevOps agility.
    • Security tools are integrated into the CI/CD pipeline.
    • Source code for key intellectual property on build or test machines are only accessible by trusted users with verified credentials. Build and test scripts do not contain credentials for access to any system that has intellectual property. Intellectual Property is divided such that not all of it exists on the same archive and each archive has different credentials.

    Continuous Delivery Practices for DevOps

    • Delivery and deployment stages are separate. The delivery stage precedes the deployment pipeline.
    • All deliverables that pass the delivery metrics are packaged and prepared for deployment using containers.
    • Deliverable packages include sufficient configuration and test data to validate each deployment. Configuration management tools are used to manage configuration information.
    • Deliverables from the delivery pipeline are automatically pushed to the deployment pipeline, once acceptable delivery measures are achieved.
    • Deployment decisions are determined according to predetermined metrics. The entire deployment process may take hours, but usually less than a day.
    • Deployments to production environments are staged such that failed deployments can be detected early and impact to customers isolated quickly.
    • Deployments are arranged with automated recovery and self-healing capabilities in case a deployment fails.

    What This Means

    DevOps is a powerful tool that enables many benefits for organizations that use it. Achieving performance efficiently with DevOps depends on following best practices. By following the nine pillars of practices enumerated in this blog, organizations can achieve the performance potential that DevOps has to offer.

  • Best of 2021 – How to Combine DevOps and Agile

    Best of 2021 – How to Combine DevOps and Agile

    As we close out 2021, we at DevOps.com wanted to highlight the most popular articles of the year. Following is the thirteenth in our series of the Best of 2021.

    In recent years, application development and deployment have become an increasingly critical part of business operations. Because of this, various entities have sought to optimize their product development process.

    This has led to a rise in the popularity of DevOps, which is designed for that purpose. In simple words, the DevOps application during the software development process reduces the number of steps necessary to bring software to market. These faster releases and streamlined processes mean swift user feedback.

    DevOps implementation focuses also on the software scalability, how well it could be deployed and also its monitoring and maintenance after the future releases However, there is also a downside to traditional DevOps benefits. The system does not include the kind of continuous testing and improvement that Agile offers. 

    This has led to Agile practices being overwhelmingly focused on what you might define as the development aspects of software delivery. Though, there is less focus on operational aspects.

    Hence, both practices are quite critical to be implemented in the SDLC of any product. 

    Separating Agile and DevOps approaches to software development leads to the building of the product but its deployment, work automation, as well as infrastructure management fail as it’s “somebody else’s problem” when the Agile team is looking at it. Moreover, “operability” disappears into the background.

    The solution is combining Agile sprints with the integrated teamwork offered by DevOps. By doing so, you can optimize incrementally the development lifecycle and maintenance of your product both. It helps to correct an imbalance but has little influence over the practices that happen during the continuous development phase.

    What is Accomplished by DevOps and Agile Integration?

    The integration of DevOps and Agile helps in the following areas:

    • Streamlines the release process and improves product offerings.
    • Allows for better collaboration.
    • More value and fewer risks in each release. 
    • Fewer bugs and faster fixes.
    • Increased visibility.
    • Higher user satisfaction rates as the products are more qualitative.

    What to Pay Attention to When Integrating DevOps and Agile

    To simplify the process of implementing DevOps into Agile product development we have gathered the most common pitfalls that might happen during this process and how to avoid them making your process working smoothly.

    Improve Teamwork Flow

    Using the DevOps framework and Agile approach together makes it crucial that team members have a broader understanding of all development aspects. You get DevOps business value and the practicality of Agile together. 

    Team members such as the Product Owner, Scrum Master and the PM, along with operations, infrastructure and sysadmin roles need to consider not only the software development process but also delivery and maintenance. Your teams should be equipped with the knowledge of release, service and change management, environment provisioning, automation and tools, and application deployment. Build-and-run product-centric teams solve the problem of the Agile development-to-operations hand-off.

    Defining the Lifecycle

    Successfully attempting a DevOps implementation plan with an Agile framework means defining the product lifecycle. This increases consistency, reduces cost by minimizing waste and speeds up a time to market. Teams now inherit more of the operational concern within the entire lifecycle. Therefore, it’s ideal if you start to implement some of the DevOps principles right at the beginning of your development process. 

    DevOps Adoption in Sprints

    Agile workflow assumes the software development process divided into sprints, therefore it’s strategic to integrate DevOps management while handling sprints.

    Follow these instructions as you start working the DevOps approach into your Sprints.

    • Invite ops/infrastructure/support personnel to planning sessions.
    • Discuss product functionality and operability features.
    • Include them in the upcoming sprint.
    • Involve the DevOps team in sprint backlog planning and daily meeting, as well as sprint review and scrum and plan alignment.

    The engagement and collaboration of your development team and operations team also keeps the ops team abreast of functionality release timelines. The ops team can then help the dev team in planning the release schedule with greater accuracy and can assist the dev team in shipping the product faster.

    Including QA in Each Phase

    Making the QA part of the entire development lifecycle is another essential factor when integrating DevOps and Agile. Testing assumes a vital position when combining the two. Besides functional testing applied in Agile, DevOps approach requires performance and load testing of the software. Hence, constant testing is equally as important as continuous development.

    Implement Service Backlog Under DevOps

    When implementing DevOps and Agile together, you need to rebuild your service backlogging process. As under DevOps framework, it should include: 

    • Scalability of the software.
    • Deployment capability.
    • Service monitoring.
    • Logging.
    • Setting alerting. 
    • Software testing. 
    • Security and compliance aspects.
    • Operational performance.

    Leveraging the Right Tools

    Using the right tools is the key to successful Agile and DevOps adoption into your software development. Keep in mind that applies to your software development process configuration management tools to create and replicate infrastructure using the Infrastructure as a Code (IaaC) concept needed for DevOps. This helps developers to deploy the application on different types of platforms without any reworking efforts.

    Automation

    Automation of workflow is another part of Agile combining with DevOps. Try to automate all the code scanning processes and avoid any potential vulnerabilities. Build artifacts in a repository, or automate the release out the door. Automate these elements entirely so your end-to-end goalposts are the one possible places where someone has to manually check for issues.

    Documentation 

    While in the Agile approach, teams don’t document their meeting minutes or other communications. Instead, they prefer lo-fi methods such as pen and paper. DevOps, on the other hand, requires entire design documentation and specs to understand a software release.

    Measurement and Analysis

    Well, after building DevOps into Agile project management to keep track of its progress, you need to care about establishing the metrics to measure its effectiveness. This allows for the successful enablement of multiple releases to production faster. As under the Scrum Alliance Organization recommendations, some of these could be:

    • Percentage of release date adherences.
    • Percentage increase in release numbers.
    • Time taken for release to production.
    • Defects attributable to platform/support requirements.
    • Percentage of NFRs met.

    Though you can define other metrics during DevOps implementation to measure that have higher business value.

    Why DevOps and Agile both matter should be obvious now. Though these practices serve to streamline and simplify the product creation and deployment processes, combining Agile and DevOps requires a shift in the organizations. But putting efforts in combining Agile and DevOps management in the right way, you will see how it can improve your development process and deliver results in reliable, scalable and maintainable applications.

    — Slava Vaniukov

  • Best of 2021 – Why DevOps Will Cease to Exist

    Best of 2021 – Why DevOps Will Cease to Exist

    As we close out 2021, we at DevOps.com wanted to highlight the most popular articles of the year. Following is the twelfth in our series of the Best of 2021.

    Nowadays I feel like there is no need to explain why DevOps as a methodology exists, as it is widely understood and accepted.

    But the reason DevOps engineers exist is not to ensure the success of its namesake methodology, nor, if we’re being honest, is the practice evolving into a role that’s viable for future progress. Rather, it’s on the verge of becoming obsolete.

    Surprisingly, in many cases having a DevOps engineer can actually get you further from the DevOps methodology objectives, rather than closer.

    How Does One Become a DevOps Engineer?

    I only recently stumbled upon DevOps courses in high-tech academies.

    Before it was an actual field of study, I’m pretty sure no one’s first step into the software development world was in a DevOps role.

    I personally started as a NOC engineer and later became a Linux administrator – developing a passion for the cloud and automation. Only years later did I dive into my first DevOps position. Others have made even lengthier journeys, starting from helpdesk support roles managing organizations’ PCs, printers and networks.

    The thing is, the starting point for people who choose a software development career starts exactly there: developing software.

    Typically, they either go to college or university or learn development online or via a bootcamp, where Linux, networking, virtualization, high availability and scaling are barely taught. And, of course, some extraordinary senior developers become infrastructure experts, but personally, I would call those folks architects and not DevOps engineers. This is probably the reason why almost every organization is in need of someone who’ll take on those responsibilities as a DevOps engineer.

    Signs of the End

    The number of cloud solutions is steadily growing every year, with cloud services becoming the dominant method of consuming business services. Gartner estimated a 40% increase in cloud services business revenue from 2020 to 2022.

    “Software as a service (SaaS) remains the largest market segment and is forecast to grow to $104.7 billion in 2020 (see table, below). The continued shift from on-premises license software to subscription-based SaaS models,” according to the firm.

    Worldwide Public Cloud Service Revenue Forecast (Millions of U.S. Dollars)

    New PaaS, SaaS and IaaS products are launched every year to make the development and maintenance of other applications easy and effortless.

    Hell, some SaaS products go as far as making it unnecessary, with platforms like WIX, Shopify, and Auth0, resulting in fewer developers being required to develop those kinds of applications. On top of that, there are already products that run almost entirely on Serverless services. Recently the term Storageless was coined and started to pop up here and there.

    At the same time, the number of developers is increasing every year. According to Statista between the years 2018 and 2019 the number of developers grew by almost a million. So, while the number of developers is growing, a big part of their responsibilities are being automated.

    This gradually frees up more time for developers to deal with DevOps challenges, which are also being automated by services like Coralogix, Datadog, JFrog, CircleCI, Gitlab and many more.

    Some companies, like Monday.com, have already acknowledged that it is not optimal to have a separate team or a single person in charge of all of the operations and maintenance of applications and that it is better to have developers responsible for their application stack from end to end.

    Although I opened by saying there is no need to explain why DevOps as a methodology exists, sometimes what gets forgotten is that DevOps evolved as a way to break down the silos between development and operations. But many organizations don’t recognize the irony of then having a separate team in charge of all operations and maintenance – that just defeats the purpose.

    Hopefully, as this trend grows, universities and coding courses will acknowledge these issues as core challenges in software development and include these subjects and principles in their curriculum.

    The Future As I See It

    This could be wishful thinking on my part, but I believe sometime in the future we will reach a point where all developers will be required to understand and practice DevOps. A developer who understands the cost of running their application, how Kubernetes assures it is always available and resilient and how to build more scalable and more secure application stacks will simply be better at their job and more valuable to their company. The opposite is also true; a DevOps engineer will be able to build better CI/CD pipelines, better monitoring solutions and cloud architectures if they are taking an active role in development and actually knows the application stack and his team’s pains and needs.

    Even if I’m wrong – and I do hope I am – I would argue that if you are a DevOps engineer or a tech lead of any sort, promoting the idea that DevOps is a part of every developer’s job is in your best interest.

    The developers who understand how to support their own environments, run internal services on private networks and understand the solutions that are available to them will simply be better at their job, enabling companies to let automated processes do their thing and focusing talent where it’s needed most to make the best use of our skill sets. Thankfully, this standard of excellence is becoming easier to reach every day; and (Do I dare say it?) perhaps, in the near future, DevOps will become less of a role and more of a service waiting for its eventual, unpreventable automation.

    Reading this, you might think that I am a self-loathing DevOps engineer who wishes to become a developer. Nothing could be further from the truth. Development Operations is my field, and I believe it’s full of talented individuals who I’m proud to call colleagues and friends. However, at the end of the day, we need to be realistic. Now that the “Operations” part of the work is mostly automated, we must focus our skills on the “Development” part.

  • Best of 2021 – From Agile to DevOps to DevSecOps: The Next Evolution

    Best of 2021 – From Agile to DevOps to DevSecOps: The Next Evolution

    As we close out 2021, we at DevOps.com wanted to highlight the most popular articles of the year. Following is the ninth in our series of the Best of 2021.

    As the workforce shifts to remote locations, networks are becoming more diffuse as the edge gets farther away. At the same time, the number of devices and applications on those networks continues to rise. Some estimates suggest that, by 2030, there will be 15 connected devices for every person on the planet.

    The rapid expansion of the remote workforce and their associated application needs has created a significant challenge for both application developers and the IT professionals tasked with deployment and maintenance of applications. Finding the right balance between speed of release and stability and reliability of applications – never an easy task – is paramount for the success of any organization.

    Agile and DevOps evolved to help organizations strike this balance, providing the best possible customer experience in the shortest realistic time frame. But have Agile and DevOps fulfilled that promise?

    The Promise of the Agile Manifesto

    While Agile as a methodology has been known and followed for nearly two decades, the ways in which organizations have applied Agile have been as varied as the organizations themselves.

    The Agile manifesto set out four basic values when it was first written in 2001:

    • Individuals and interactions take precedence over processes and tools.
    • Working software takes precedence over comprehensive documentation.
    • Customer collaboration takes precedence over contract negotiation.
    • Response to change takes precedence over mindlessly following plans.

    Agile processes are applied across a range of development activities, from development of standalone applications to development of cloud-native business applications. The Agile Manifesto also contains several more principles that further explain what the values mean when put in practice.

    These Agile principles can be condensed into a few areas of focus:

    Prioritize the customer over the product

    Agile development requires continuous customer engagement throughout the entire development process, with the end goal being frequent product delivery based on specific customer feedback. While this can present challenges for an Agile team, particularly when customers demand changes late in the development cycle, Agile maintains that the best way to elevate customer experience is to make the customer part of the development process.

    Trust Agile Teams to Self-Organize and Self-Manage

    Agile focuses on smaller teams that remain in constant communication with customers, as well as with each other. These teams should include both developers and those with knowledge of the larger business requirements being met through development. For these teams to work effectively, trust is key. Agile posits that self-organized teams, given leeway to pursue their projects in the way they see fit, result in the shortest development cycles.

    Keep it Simple

    Agile teams require simplicity. This correlates with Agile’s disdain for overuse of process. Agile seeks to minimize the total amount of work required, thus minimizing overall development time.

    Agility Leads to Agility

    Just as Agile teams continuously improve their product and the customer experience, they also constantly improve themselves. Constant evolution of teams and the processes they employ (remember, teams before processes) improves team agility itself.

    While the Agile values and principles seem simple, effective application of the values and principles is another story entirely. Indeed, at times, the implementation of Agile development has violated the very first value of the manifesto by focusing on which tools and processes should be used. But, in an environment where more users are clamoring for more products and services, implementation of Agile methodologies is not just important, it is imperative.

    Building on Agile with DevOps

    The precise meaning of the term itself and the scope of DevOps remain a source of debate. At a high level, DevOps is the marriage of the development cycle with post-development activities, such as deployment and maintenance.

    According to open source contributor Barbara Ericson of Cloud Defense, “Instead of IT operations and software development being siloed off from each other, DevOps breaks down the traditional boundaries that previously existed between them in order to achieve continuous integration and continuous delivery (CI/CD) of quality software features and applications to end users.”

    Just as with Agile, the effective implementation of DevOps requires cultivating a DevOps culture within the organization. However, Agile and DevOps are also not mutually exclusive. That is to say, DevOps is not merely a replacement for or an evolution of Agile. Although Agile and DevOps differ in their structures and approaches, they can work in unison to achieve the ultimate goals of speedy deployment and enhanced customer experience.

    While Agile and DevOps share common goals, they have not always agreed on how to achieve those goals. DevOps differs in many respects from Agile, but, at its best, DevOps applies Agile methodologies, along with lean manufacturing principles, to speed up software deployment.

    One area of particular tension between Agile and DevOps is that the latter relies heavily on tools; in particular, when it comes to the automation of testing and deployment processes. But DevOps can overcome the resistance of Agile developers to tool usage simply by applying Agile principles themselves.

    Effectively, DevOps proponents must convince Agile teams that dogmatic adherence to the underlying principles of Agile is actually inconsistent with Agile in the first place. Ironically, Agile developers who insist that the process is always bad actually violate Agile principles by refusing to acknowledge the benefits offered through change, another Agile principle.

    The challenge is to have the Agile development teams trust in the automation efforts of DevOps, while at the same time encouraging the DevOps team to consider the business goals of deployment rather than pursuing speed of deployment for its own sake.

    With constant communication between the Agile team and DevOps team (another Agile principle), development can achieve a degree of comfort with DevOps tasks and processes. This means that testing and deployment automation can proceed quickly, resulting in a decreased time to market, overall.

    Ultimately, Agile and DevOps can work together most effectively when they recall their shared goals: smaller change increments based on feedback resulting in faster delivery cycles.

    Continued Evolution: DevSecOps

    As networks expand and businesses continue to integrate cloud-based services (in many cases, building multi-cloud environments), security issues become more and more complex. One area in which Agile is lacking is in integrating security into the development process. Unfortunately, in an Agile environment, application security is often an issue addressed after development, rather than as part of the process. Enter the next iteration of DevOps: DevSecOps.

    DevSecOps revolves around three basic principles: ensuring data security while minimizing inconvenience for users in accessing data, using development tools that identify risks as early as possible in the development process and ensuring data encryption using technologies such as secure sockets layer (SSL) and virtual private networks (VPNs).

    While DevSecOps and Agile may also disagree about the priority of tools, security must become an integral part of any development project. This is why Agile, DevOps and DevSecOps must all work together to ensure not only rapid deployment but secure deployment.

    The Next Evolution

    Agile and DevOps were both important evolutions of the software development process, but DevSecOps is the next evolutionary step. Despite a few disparate characteristics, Agile, DevOps and DevSecOps can and should work in unison to achieve their shared goal: the best possible customer experience and short deployment cycles.

  • Best of 2021 – The Next Evolutions of DevOps

    Best of 2021 – The Next Evolutions of DevOps

    As we close out 2021, we at DevOps.com wanted to highlight the most popular articles of the year. Following is the seventh in our series of the Best of 2021.

    As society continues to recover from the global COVID-19 pandemic and some semblance of normal starts to return, technology continues to move forward. The pandemic certainly changed what normal means and people, processes and technologies all have adapted and evolved to meet those challenges. The narrative that the pandemic caused of your organization’s digital transformation is true for many practitioners. With 2022 just around the corner, DevOps is on the cusp of maturation of previously bleeding-edge paradigms and a focus on engineering efficiency. Here are five DevOps evolutions you should keep an eye on going forward.

    Engineering Efficiency is Front and Center 

    Engineering efficiency is a particularly broad umbrella term. At the foundational level, engineering efficiency focuses on making someone (for example, an engineer) more productive. There are a multitude of disciplines that intersect, from organizational design to engineering/developer experience. Engineering efficiency is increasingly critical for organizations today. The pandemic had two major impacts on the technology sector in terms of resources and staffing. The first, at the start of the pandemic, was the unprecedented and unpredictable availability of resources; physical locations were being shut down because of the medical severity of the pandemic and the “getting hit by a bus” factor was playing out in real life. Second, during the recovery period, the Great Resignation began, and with it, a fight for resources that has become increasingly intense. Both have meant that the availability of resources, especially ramped resources, is scarce. 

    The Spotify model of tribes/guilds of engineering resources is a promising evolution; folks can frequently move around, reducing the toil that engineering resources face and allowing for engineering resources to not only ramp up more quickly but also increasing engagement and retention. The industry continues to march toward standardization in areas that were typically bespoke, such as the release process, and I think we’ll see that continue to evolve, as well.

    Git is Ubiquitous

    Leveraging a source code management (SCM) solution used to be reserved for software engineers. But as the proliferation of “something-as-code” has touched multiple levels of the technology stack from networking, storage and, ultimately, a development pipeline, the march of operations-focused engineers adopting many of the traits of software engineers continues. Having iteration in your infrastructure stack with more ephemeral/disposable infrastructure is becoming the norm. Saving and packaging the multitude of configurations for the “something-as-code” source control is a natural area of evolution. 

    Building off of source control are the package managers—your Docker registries, Helm chart repositories, etc.—for more deployable artifacts; that said, getting those artifacts to production is a process. Because Git is becoming ubiquitous across the technology landscape, this leads to the continued adoption of GitOps. Since the seminal piece was written by Weaveworks in 2017 defining the GitOps paradigm, leveraging GitOps is seen as a viable paradigm for many organizations five years later, especially when starting with greenfield initiatives. 

    Kubernetes is No Longer Bleeding Edge

    In 2022, Kubernetes will celebrate the eighth birthday of its first commits on GitHub. Taking a jog down technology memory lane, eight years before Kubernetes (in 2006), VMware was still a private company and it would be a few years before vSphere was even released (remember how it felt to run a workload on a virtual machine in 2014?). The Kubernetes ecosystem still moves quickly, but placing workloads on Kubernetes is not a novel concept anymore. As application infrastructure and architecture have adopted the Kubernetes way (in other words, being idempotent and ephemeral), there is maturity around running a suitable workload on Kubernetes.  

    Kubernetes by design is highly pluggable. If you do not like the opinion or implementation of something inside Kubernetes, you can replace that opinion. Don’t like how Kubernetes handles ingress traffic? Then choose from one of the many ingress controllers available today. That is just one example of dozens of pluggable areas. Because of this, Kubernetes is viewed as a dynamic, non-static resource. Using Kubernetes takes trial and error and getting your cluster to be robust, performant and reliable is an ongoing journey that requires ongoing iteration. 

    Authors Can Be the Enforcers

    There is no question that in a modern software stack, we are inundated with data. The metrics soup and the continued science of and exploration of observability (metrics, traces, logs) provide us with a lot to work with. Making decisions, even automated ones, based on that data continues to be critical. With the rise of site reliability engineering (SRE) practices, reacting or anticipating spikes in usage, failures and even security-related items are par for the course for modern teams. 

    These decisions can be authored into policies that specific platforms understand, such as autoscaling rules for a cloud vendor or something like Open Policy Agent in the Kubernetes ecosystem. With so many items shifting left toward the development team, finding the right resource, skillset or institutional knowledge to author these rules can involve the input of several teams. Because of the rise of “something-as-code,” regardless of whether the author of these rules is a software engineer, DevOps engineer, platform engineer or anyone in between, that author has the ability to enforce. 

    Shifting Left … But Complexity Shifts Left, Too

    The old adage is that complexity is like an abacus: You can shift complexity around, but it never really goes away. With the movement to shift responsibility left to development teams, this also means that associated complexity is shifting to the development teams. Modern platform engineering teams provide the infrastructure (compliant Kubernetes clusters) to teams and any workload that is run on those clusters is up to the development team that owns it.  Typically, development teams then focus on features and functionality. Managing lots of non-functional requirements—and even core infrastructure requirements such as networking—can be a burden; think about how your organization would handle a service mesh.

    If you are a DevOps or platform engineer, making your internal customers—your development teams—successful is a great goal to work toward. Crucial to this is disseminating expertise. This can be in the form of automation and education. A common practice with the DevSecOps movement is to have some sort of scanning step as part of the build or deployment process, disseminating the internals as far as how the scan is performed, what happens if something is found, etc. Gaining internal adoption is a journey and having a good developer experience built around clarity and stability are important. 

    Evolution in 2022

    Even with all of the challenges, bumps and learnings that the last year has given us, technology continues to evolve and advance and even lower the barriers of entry to continually become more inclusive. Focusing on improving engineering efficiency and reducing toil will allow for more participation and lower the barriers to entry.


  • Best of 2021 – How to Scale Your Website to Perform on Mobile Devices

    Best of 2021 – How to Scale Your Website to Perform on Mobile Devices

    As we close out 2021, we at DevOps.com wanted to highlight the most popular articles of the year. Following is the sixth in our series of the Best of 2021.

    We all surf the internet mostly on our mobile devices because they are so handy and easily accessible. A vast majority of mobile device users are making online purchases and paying their utility bills using these devices. A recent study by Forrester, “The Digital Business Imperative,” showed that in a three-month period, 43% of the banking customers in the United States had used mobile phones for online banking transactions.

    The growth year over year of the volume of online business transactions via mobile devices has been significant, encouraging companies to get conscious about building websites and e-commerce sites that look, feel, function and perform identically on computers as well as smart mobile devices. However, most of the time, the experience of browsing a website on a smartphone isn’t the same as doing so on a computer. The fundamental causes of this varied behavior across different platforms should be understood to be able to develop websites that scale effectively/smoothly across different devices.

    Web pages are usually composed with one or more of the following components: header and footer, main content (text), images, forms, videos and tables. Devices differ in screen dimension (length x width), screen resolution (pixel density), compute power (CPU and memory) and operating system (iOS, Android, Windows etc.). These differences contribute significantly to the overall performance and rendering of web components such as images, videos and text across different devices. Another important point to note is that most mobile users are not always connected to a high-speed network; hence, web pages should be carefully designed so that they also work effectively on low bandwidth connections.

    Most Troublesome Issues with Websites on Mobile Platforms

    A variety of issues that pertain to the performance and scalability of websites across devices exist, and we will now discuss a few of the important ones as outlined below:

    • Websites not adapting to different screen sizes automatically. Some sites are designed to format for variable screen sizes, but their elements may not auto-scale. This would result in the site automatically adjusting itself for various screen sizes, but the elements inside may look awfully large on smaller devices. Some sites may not be designed to adjust for variable screen sizes, causing the elements of such websites to look extremely small on devices with smaller screens.
    • Websites with too much content for mobile devices. Some websites are loaded with too much content just to fill the empty space when opened on a desktop. Websites developed without being conscious of mobile users generally fall under this category. These sites take more time and bandwidth to load and if the pages aren’t designed appropriately for mobile devices, then part of the content may not even appear on the devices.
    • Sites that take too long to load images. Websites with too many images or heavy image files are likely to take a long time to load if the images were not optimized during the design phase.
    • Data in tables look very complex and take too long to load. Many websites present data in a tabular fashion (ex. A comparison of competing products, air fares from different travel booking sites, flight schedules etc.), and on mobile devices, these tables look too complicated, are difficult to comprehend and/or take too long to load.
    • Websites hosting videos that don’t play on some devices. Not all video formats are supported by all mobile devices. Sometimes websites host media that require licenses or Adobe Flash and other specific players that some mobile devices may not support. This causes frustration among users and a poor overall experience with the website.

    Design Your Sites to Adapt to Different Devices

    All commonly encountered issues with websites on mobile devices can be addressed through proper design that takes those issues into consideration. The most highly recommended practice is the “mobile-first” approach. When working with several limitations such as screen size, bandwidth, etc., the need to concentrate on the right quantity and quality of content should be of high priority. The mobile-first approach places content as the primary object and aims at producing a design for the smallest of  devices to ensure that they have only the most essential features. It addresses the design challenges for mobile devices first and then makes it easier to progressively enhance the design for other larger devices.

    Here are a few best practices to consider when designing web sites that intend to scale on different devices.

    Adapting to any screen size: At a minimum, a web page needs to be scaled to fit the screen size of any mobile device. Nowadays, mobile devices come with very high screen resolutions. The pixel density on mobile devices is much higher than that of desktop screens. So it is important to format a page to match the mobile screen’s width in device-independent pixels. The “meta viewport” tag included in the <head> of the HTML document addresses this requirement.

    The meta viewport value as shown above helps format the entire HTML page and render the content to match any screen size.

    ‘Content Is King’: Web designers must remember that content should determine the design of their website and not vice versa. Websites with too many elements such as tables, forms, charts etc., become challenging when they need to scale on mobile devices. Developers end up hiding content for mobile users and as a result, the desktop version and the mobile version of the website become inconsistent. The goal of the design should be to focus on the core structure and content rather than to incorporate decorative elements on the website. As recommended by the mobile-first methodology, designers should ensure a single version of content for both desktop and mobile users. So web designers should carefully consider, craft and optimize the content so that it not only satisfies the business goals but also appeals to the mobile users. Content that doesn’t appear in the mobile version may not even need to appear in the desktop version.

    Responsive images. The design should consider small, handheld devices operating in areas with low signal strength. Large photos and complex graphics are not suitable for mobile devices operating under such conditions. Designers need to make sure that the images used in websites are optimized for different sizes of viewports and pixel densities. A recommended approach is to use “resolution switching,” with which it is possible to instruct the browser to select and use an appropriate size image file depending on the screen size of a device. Switching the image according to the resolution is accomplished by using two attributes: srcset and sizes. With these attributes (included in the code snippet shown below), the browser will use the device width to select the most suitable media condition provided in the sizes list, choose the slot size based on that condition and load the image referenced in the srcset that closely matches the chosen slot size.

    For example, if a device with a viewport of 320px loads the page, the media condition (max-width: 320px) in the sizes list will be true and hence the corresponding 280px slot will be chosen. The first image listed in srcset (elephant-320w.jpg) has a width that is the closest to this slot Browsers that don’t support resolution switching will display the image listed in the src attribute as the default image. This approach not only picks the right image for your device viewport but also prevents loading unnecessarily large images that will consume significant bandwidth.

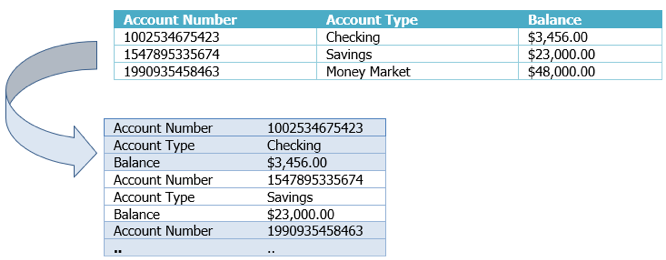
    Responsive Tables: The world is getting highly data-driven. Bringing critical and time-sensitive data to people’s handheld devices gives a lot of power and freedom for decision-making to the end users. The challenge is to present data to the user in a fashion that is easy to load onto a mobile device and read. Most often data needs to be presented in the form of tables, but when data tables get too large and unwieldy they can be frustrating to interpret on a mobile device with a small screen. The screen could be much narrower than the width of the table forcing the user to have to zoom out just to fit the table on their screen, making the text appear extremely small. Likewise, the screen could be much wider than the width of the table, forcing users to zoom in to view the data, requiring constant vertical and horizontal scrolling. There are several approaches to building responsive tables, the most important of which will be mentioned below:

    The table will not be treated like a table as the columns will be transposed to rows. Each column will be sized to be just as wide as the screen to prevent the need to scroll horizontally. By using appropriate coloring, (1 row of data) each row of data can be distinguished from another. In this case, for each “cell”, the CSS generated content (:before) should be used to apply the label so that each piece of data can be identified clearly.

    The second approach is to display the data in two forms based on screen width: 1. chart form in narrow screens and 2. complete table form in wider screens. If the mobile user wants to click the chart to see the complete table, then the approach discussed in (a) can be used to show the data in tabular form.

    The third approach is to show a mini graphic in a narrow screen to indicate the presence of a table, which upon the user’s click will allow the table to be expanded and displayed.

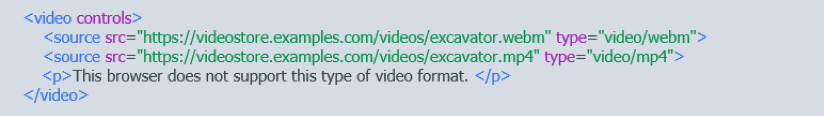
    A video that always plays: Usually video files don’t play on mobile devices if their  formats are unsupported or if they need a proprietary video player to play the content. The recommended approach is to use standard HTML5 tags for videos and animations. The video element in HTML5 can be used to load, decode and play videos on your website. Producing the video in multiple formats to suit different mobile platforms is highly recommended. It is also important to size the videos appropriately so that they play within their containers.

    The example below shows the use of <video controls> in which the <source> tags let the developer specify several different types of video formats (indicated by the type element) that the browser can choose from. In this approach, the switch to the right format happens at the client-side and only one request is made to the server. This reduces network latency and lets the browser select the most appropriate video format without having to download a video first to check its format.

    The videoWidth and videoHeight properties of the video element help identify the encoded size of a video. Video dimensions can be controlled using JavaScript or CSS. The max-width: 100 percent helps to size the videos to fit the screen. CSS media queries can be used to set the size based on the viewport dimensions. There are also several JavaScript libraries and plugins that can be used to maintain the aspect ratio and size of videos.

    All Things Considered…

    With the exponential growth in the number of mobile users, smart phones and tablets are used regularly to surf the web and perform business transactions. Online business is turning out to be the primary business channel for several businesses worldwide. Consequently, it is important for businesses to develop websites that work and scale well on mobile devices to enhance the mobile user experience and mirror the functionality and performance of websites on desktop computers and large monitors.

    The ‘mobile-first” approach helps web designers create sites that operate well on small mobile devices. Web designers need to be careful about deciding the appropriate content that satisfies business requirements, while considering the devices’ technical limitations, such as screen sizes, processor speeds, memory and operating conditions (eg. poor network signal strength). Care should be taken to ensure that pictures, videos and data that are presented on mobile devices are designed to be responsive. Designers also need to be sensitive to breakpoints, touch targets, etc.

    A well-designed website that works and scales well on a small device can always be progressively enhanced to work on larger devices.

    Originally published in 2018.

    — Sridhar Asvathanarayanan