Category: DevOps and Open Technologies

Editorial Calendar for February 2016

  • Majority of Organizations Now Adopt Multi-Cloud

    Majority of Organizations Now Adopt Multi-Cloud

    As IT’s digital footprint grows, its cloud footprint is rising both in size and complexity. As a result, most organizations have matured into multi-cloud operators. A multi-cloud approach empowers different divisions with the autonomy to select the right computing environment for their needs. It also enables a lift-and-shift ability to port workloads across cloud service providers (CSPs) when needed. Adopting a multi-cloud model could bring performance benefits, cost savings or better scalability, all while encouraging a more vendor-neutral stance.

    We’re in a multi-cloud world. A recent HashiCorp study found three out of every four organizations are already multi-cloud. This is a staggering increase from just a few years ago when mono-cloud was more accepted, and operators had zombie-like allegiance to AWS. The uptick in multi-cloud signals the maturity of offerings at other CSPs, like Azure and GCP. It also signals differentiation among clouds as each hones in their unique value propositions.

    HashiCorp’s inaugural State of Cloud Strategy Survey offers some very clear results about the state of multi-cloud adoption. Below, I’ll review major takeaways from the report to better understand the state of multi-cloud adoption. To sum it up, large organizations tend to benefit most from multi-cloud adoption, as there are still significant roadblocks to truly reaping a sizable return from a multi-cloud status. Yet, more infrastructure automation may help companies of all sizes respond to multi-cloud complexities.

    The Multi-Cloud Era

    DevOps truly operates in a multi-cloud era. The report revealed 76% of organizations are already multi-cloud; that leaves only one in four companies leveraging a single cloud. And, that trend won’t stop—within two years, 86% predict they will be multi-cloud operators. The study also confirms that the larger a company is, the more likely it will adopt multi-cloud—94% of large enterprises with 5,000 or more employees are multi-cloud.

    So, what’s driving this cloud fragmentation? Well, 34% of respondents cite digital transformation as a top driver for multi-cloud adoption. In the race to meet new digital innovation demands, multi-cloud has emerged as a strategic force. To enact this rapid change, many organizations are investing in a cloud center of excellence (CCoE) to guide cloud transformation efforts. A CCoE is most common within large companies with a cloud budget of $5 million or more.

    Speaking of budgets, cloud spending is going through the roof. In 2020, only half of companies met their projected cloud spend, and 39% of companies overspent their allotted cloud budgets. As I’ve covered before, cloud-native costs are notoriously difficult to identify and trim. Without the proper guardrails to manage spending, surprise data egress fees or hidden server costs can strain the cloud checkbook. As it stands now, 40% of companies lie in the $100,000 to $2 million per year range, and 6% of enterprises are investing $50 million a year or more into multi-cloud. This spending will likely increase in the coming years as cloud reliance expands.

    Enterprises Benefit Most

    So, which clouds are companies using? If we compare cloud adoption, AWS is a clear market leader; 88% of companies use AWS, 74% use Azure and 61% use GCP. AWS’s hegemony is not expected to fade in the next two years. Yet, while AWS usage will remain the same, competing CSPs will experience modest increases. This is likely due to Azure and GCP making gains in geographical zones outside North America, such as Asia-Pacific and Africa.

    In terms of technology used in cloud environments, open source software (OSS) is a popular choice. Cloud-native open source projects, such as Kubernetes, OpenStack and Terraform, have taken on a life of their own, with vibrant community support. However, not all shops build upon OSS and run it themselves. Somewhat ironically, we’re seeing more managed OSS emerge. One stand-out area is provisioning, where 42% of organizations build with open source and run it themselves.

    On the whole, multi-cloud is working at most enterprises, with 53% of survey respondents saying multi-cloud has helped achieve their business goals. The top benefit of multi-cloud is digital transformation, at 34%. This is followed by avoiding lock-in (30%), reducing cost (28%) and scalability (25%). But multi-cloud does not treat all companies as equals; the likelihood of multi-cloud success increases as the company size increases. Less than half (42%) of small companies say they have multi-cloud success, which jumps to 64% for large enterprises. With fewer resources for support, multi-cloud may be less beneficial for startups and small to medium businesses. In fact, 41% of professionals say a lack of in-house skills inhibits their cloud success.

    Challenges in a Hybrid Multi-Cloud World

    An ongoing talent gap is just one potential challenge to cloud success. Just over half (51%) say cost concerns are a top inhibitor to their cloud program success. Hybrid cloud complexity is another prominent challenge, with 35% of organizations citing it as a major cloud obstacle. Many enterprises are still grappling with the remnants of legacy on-premises estates. But technical debt is not the only reason for hybrid modalities. Surprisingly, large platforms even have constructed their own data centers or used colocation as an intentional strategy.

    Security is a top cloud inhibitor, according to 47% of IT professionals. The leading cloud security concerns include data protection (40%), data theft (33%) and regulatory compliance (31%). The myriad cybersecurity threats evolve each day, and cloud technologies are not immune; for example, web APIs are now a significant threat vector. A separate report found a 300% increase in malicious API traffic in the past six months. Other issues, such as exposed keys, insecure defaults and misconfigurations are known to hamper cloud-native infrastructure.

    Contrary to popular belief, nearly half (46%) of companies reported that COVID-19 has not quickened their cloud adoption. This reality could indicate that cloud migration has been planned for years, and recent adoption is only part of an ongoing trend. The study found that the pandemic did, however, accelerate things like infrastructure-as-code (IaC), container orchestration, compliance and governance and other operational factors.

    Infrastructure Automation Supports Multi-Cloud

    Multi-cloud feels like an inevitable result of accelerating cloud adoption in a more diversified market. Rising multi-cloud use is also arguably in line with Conway’s Law. As organizations develop more and more digital experiences across new verticals, the platforms and backend processes to support these initiatives will inevitably grow more and more complex.

    To mitigate some of the issues posed by multi-cloud, many organizations are turning toward increased infrastructure automation. In fact, 70% of those surveyed said infrastructure automation tools are extremely important to their organization. Of these tools, provisioning automation (75%) is the most popular kind in use. Automation for other areas, like networking (58%), security (50%) and app development (69%) follow.

    Hashicorp’s State of Cloud Strategy Survey boldly announces, “Welcome to the Multi-Cloud Era,” and its findings back up that sentiment. For further insights, you can view the results freely on this website.

  • Site Reliability Engineers to the DevOps Fore

    Site Reliability Engineers to the DevOps Fore

    [pdf-embedder url=”https://devopsy.kinsta.cloud/wp-content/uploads/2022/02/site-reliability-engineers-to-the-devops-fore.pdf”]

  • Cosmonic Contributes WebAssembly Runtime to CNCF

    Cosmonic Contributes WebAssembly Runtime to CNCF

    Cosmonic today revealed it has donated its universal application runtime for building cloud-native applications using the WebAssembly (Wasm) development framework to the Cloud Native Computing Foundation (CNCF).

    The Cosmonic wasmCloud runtime makes it possible to run applications built using WebAssembly on any platform. In comparison, applications built using containers are not as portable because IT teams can’t take a container application developed for Linux and run it on Windows. The container technologies for each operating system are implemented differently.

    The CNCF will make wasmCloud available as a sandbox project and will invite other organizations to start making contributions as part of an effort to eventually put wasmCloud on par with other projects such as Kubernetes. There are already nearly 80 contributors to a wasmCloud runtime that was launched last November.

    Cosmonic

    The CNCF is trying to advance other WebAssembly technologies including Krustlet, a tool for Kubernetes environments that listens for event streams from new pods so that the scheduler can then assign workloads.

    However, the CNCF is now not the only organization looking to promote adoption of WebAssembly technologies. The Bytecode Alliance has launched WebAssembly (Wasm) and WebAssembly System Interface (WASI) initiatives as part of an effort to promote standards that would make it easier to run Wasm applications anywhere. Originally founded by Fastly, Intel, Mozilla and Microsoft, the Bytecode Alliance now also includes Arm, DFINITY Foundation, Embark Studios, Google, Shopify and University of California at San Diego.

    At its core, Wasm is a portable binary instruction format for building software that describes a memory-safe, sandboxed execution environment. That approach might one day replace the current predominant method for building software that relies on the aggregation of software components that tend to lack distinct security boundaries between them. As a result, it becomes relatively simple for malware to infect all the components of an application.

    Liam Randall, CEO of Cosmonic, said even though Wasm, in effect, provides another type of virtualization for applications, IT teams should not view it as a set of technologies that will one day obviate the need for containers. Applications developed using Wasm will be layered on top of various container platforms, he said.

    There is, for example, already a Wasm project that creates a server-side Wasm runtime that enables applications to be deployed on a secure container architecture that is more efficient than Docker containers.

    The World Wide Web Consortium (W3C) drove the development of Wasm as part of an effort to create a common format for browsers executing JavaScript code. Wasm is now being extended beyond browsers and JavaScript to enable developers to ultimately create a set of universal binaries that could work on any platform without modification.

    It may be a while before the fruits of those labors are realized. However, it’s apparent the walls that have separated one IT platform from another are starting to crumble. Once applications become much more portable, the reasons why one organization may choose one platform over another will have a lot less to do with what developers prefer.

  • F5 Networks Planning Open Source Projects Beyond NGINX

    F5 Networks Planning Open Source Projects Beyond NGINX

    F5 Networks today revealed plans to launch multiple projects in the months ahead that will extend its commitment to open source beyond the NGINX proxy software the company acquired in 2019.

    The announcement was made during an online NGINX Sprint event; two of the projects are extensions of NGINX that will address networking requirements between microservices-based applications in addition to the management of fleets of NGINX instances. The third project is a platform-agnostic open source developer tool for building modern applications that does not necessarily require NGINX proxy software.

    At the same time, F5 Networks also unveiled an open source NGINX Modern Apps Reference Architecture that gives IT teams access to a complete, fully operational microservices-based application that can be deployed in minutes on a Kubernetes cluster. Based on a modular approach made up of open source components that come pre-wired and pre-integrated, F5 Networks is committing to extending this framework in collaboration with multiple third-party vendors and organizations.

    F5

    Rob Whiteley, general manager for the NGINX product group at F5 Networks, said the company is also committing to modernizing its NGINX proxy software to leapfrog rival open source Envoy proxy software being advanced under the auspices of the Cloud Native Computing Foundation (CNCF). NGINX is still more widely employed than Envoy largely because it is lighter-weight and easier to deploy, but Whiteley conceded that Envoy has more advanced capabilities.

    Envoy, of course, is at the core of the Istio service mesh. F5 Networks supports both Istio as well as a service mesh it has developed on top of NGINX. Depending on the number of application programming interfaces (APIs) that an organization needs to support, an IT team might make use of proxy software, ingress controller or an API gateway for a service mesh to manage them.

    Finally, F5 Networks said it will participate in the Kubernetes ingress project and that it is joining the gateway API community as its implements its own NGINX-based gateway controller to ensure its proxy software and Kubernetes remain tightly aligned in the future.

    In general, Whiteley said F5 Networks also is making a commitment to be clearer about where the line between the open source and commercial editions of its offerings is drawn. As a rule, the open source editions are designed for developers and small teams while the commercial version is designed to scale within enterprise IT environments. The overall goal is to promote innovation without enabling cloud service providers to reap all the revenue benefits of F5’s research and development by creating a service based on that open source software, said Whiteley.

    As part of that effort, F5 Networks is expanding the number of open source projects it supports to make it easier for developers to contribute code beyond the core NGNIX proxy software, said Whiteley.

    It’s not clear to what degree F5 Networks will be able to rally the open source community to advance additional projects beyond NGINX. The company is promising to provide additional details at an unspecified future date. However, Whiteley said there is still plenty of room for innovations not only in emerging technologies such as service meshes but also proxy software that is already widely employed within many enterprise IT organizations. Especially since most of them are embracing microservices-based applications that will ultimately change every aspect of IT.

  • Kentik Open Sources Five Projects to Advance Network Observability

    Kentik Open Sources Five Projects to Advance Network Observability

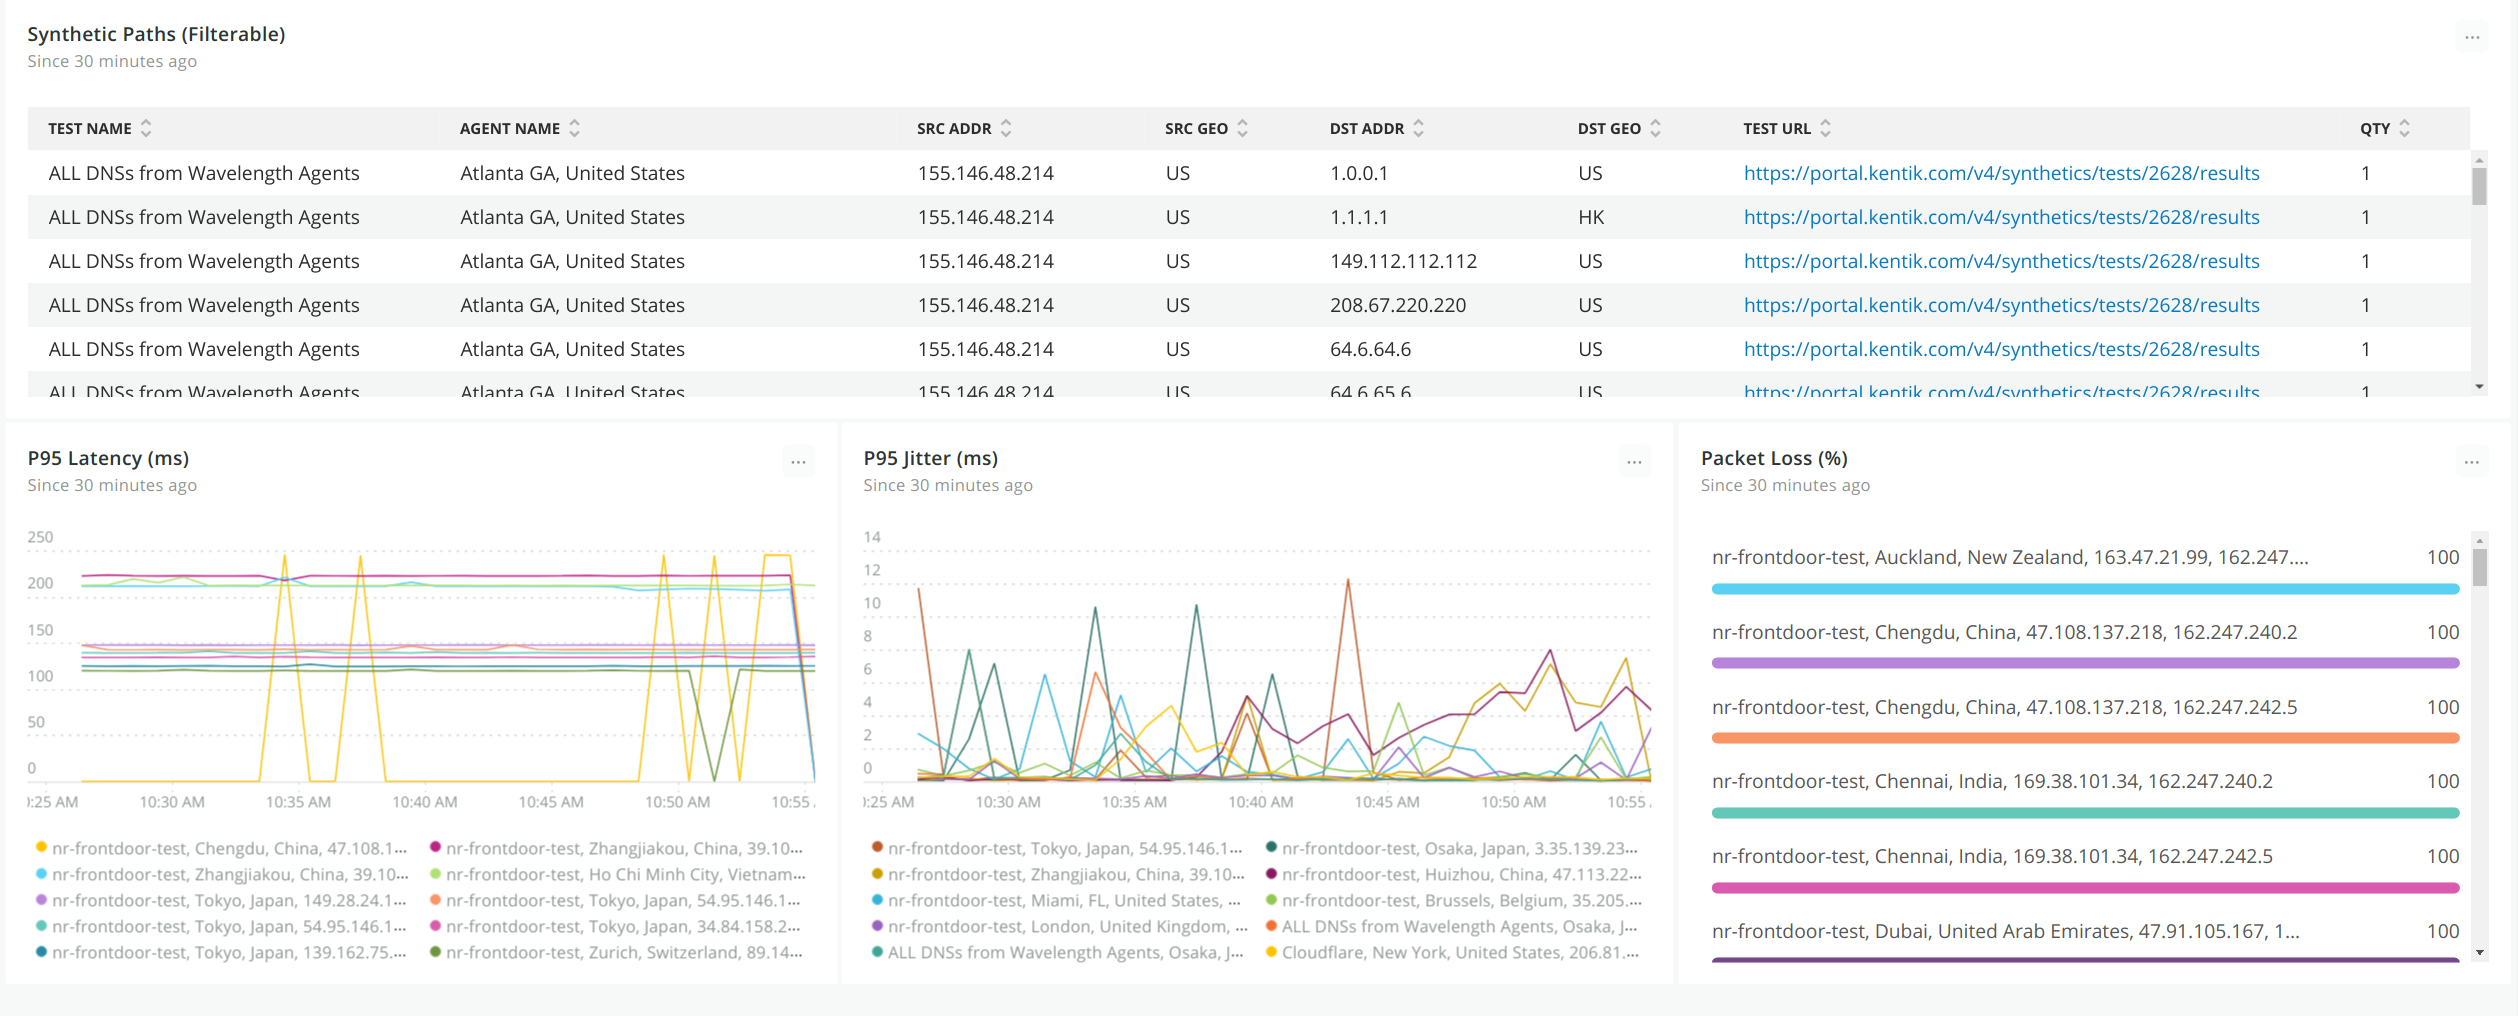
    Kentik today unfurled a developer hub, dubbed Kentik Labs, through which it is making five open source projects available as part of an effort to advance observability across network operations (NetOps).

    The five projects are:

    kTranslate: A system for pulling and pushing network data that is the basis of the Kentik Firehose integration the company created for the New Relic observability platform

    NetDiag: Scalable, asynchronous implementations of low-level network diagnostics

    Convis: Example code showing how to attribute process and container information to network traffic via the Linux kernel using eBPF

    kProbe: A high-performance host and sensor network probe (PCAP)

    Grafana App: A real-time tool for ingesting and querying network data

    Nick Stinemates, vice president of business development at Kentik and co-chair of Kentik Labs, said the goal is to enable DevOps teams to incorporate NetOps within the workflows already being employed to programmatically manage the rest of IT.

    Stinemates noted that, as IT environments become more distributed, managing NetOps has become more challenging. If there is a failure, it can be difficult for DevOps teams to determine if the issue is due to application code, the underlying infrastructure or some other root cause. Kentik Labs is committed to providing tools that will help DevOps teams reduce their mean time to recovery (MTTR), he added.

    Most NetOps teams increasingly rely on software to manage distributed networks either in the form of graphical tools provided by router and switch vendors or by using the Python programming language and the open source Ansible automation framework that enables IT teams to declaratively manage IT infrastructure.

    As the teams that manage network operations gain more proficiency with those tools, it becomes simpler to incorporate them within the construct of a larger DevOps team. While DevOps teams have been programmatically managing IT infrastructure-as-code (IaC) for years, network management has largely remained in a separate silo. However, as more applications are deployed in the cloud, it’s clear NetOps needs to become more integrated with the rest of the workflows employed to deploy and manage a highly distributed IT environment, said Stinemates.

    Less clear is to what degree the networks that make up a hybrid cloud computing environment will continue to be managed by network administrators versus site reliability engineers (SREs) that are starting to assume responsibility for managing compute and storage.

    Regardless of who manages the network, the next generation of microservices-based applications that are dependent on application programming interfaces (APIs) to call various services are much more latency-sensitive than previous generations of applications. Many of those applications will regularly experience performance issues due to networking issues that are often not readily apparent to DevOps teams. The goal should be to, at the very least, arm those DevOps teams with the tools required to confirm the source of those issues before a “war room” is convened to determine how to address the issue.

  • Micronaut Taps Moderne to Automate Java Framework Updates

    Micronaut Taps Moderne to Automate Java Framework Updates

    Micronaut, a provider of a framework for building applications based on microservices and serverless computing platforms, today revealed it is allying with Moderne, a provider of a tool for refactoring code, to create a “recipe” that will automatically update the Micronaut framework.

    Moderne CEO Jonathan Schneider said the open source OpenRewrite refactoring tool for code, originally developed at Netflix, makes it possible to automate updates to codebases, remediate vulnerabilities and provide a foundation for high-level building blocks that will make authoring custom transformations simpler. That approach will eventually be embraced by other providers of application development frameworks.

    Fresh from raising $4.7 million in initial funding, Moderne makes OpenRewrite available via a software-as-a-service (SaaS) platform to enable IT teams to search and transform millions of lines of code in minutes. OpenRewrite currently supports Java, but the company is working toward adding support for additional languages, including infrastructure-as-code (IaC) tools such as Kubernetes, YAML and XML.

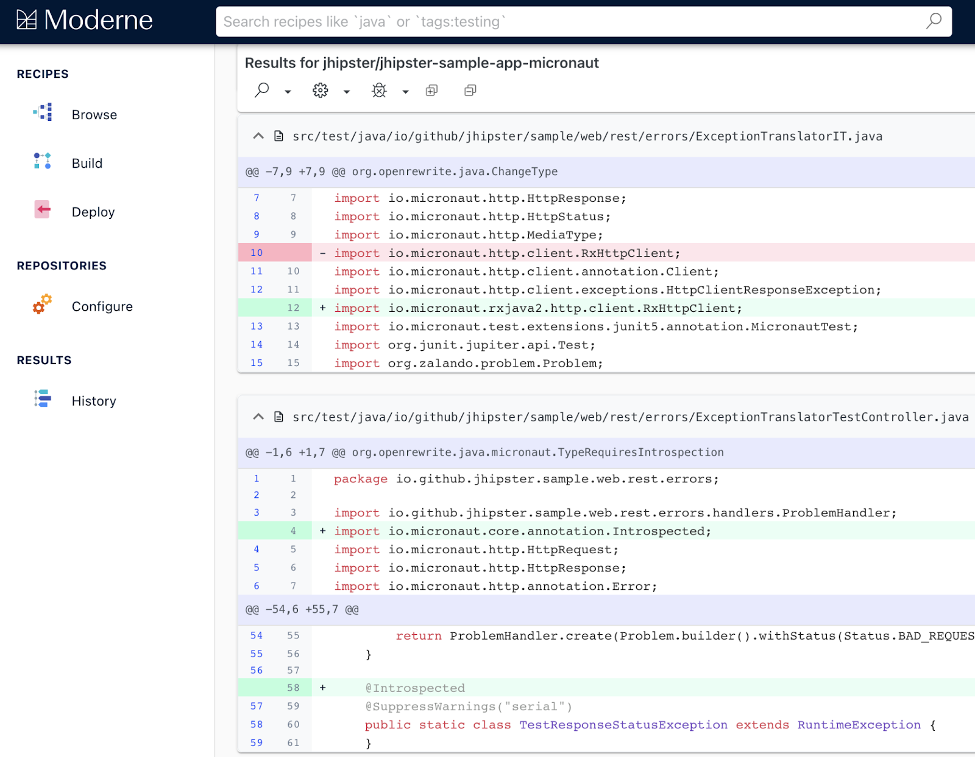
    Moderne has also developed “recipes” for common search and refactoring operations that can be assembled into more complex recipes for framework migrations involving, for example, an upgrade from Java 8 to Java 11. Micronaut is the first provider of a development framework to create a recipe for its own framework using OpenRewrite.

    At a time when applications are more distributed than ever, updating codebases is a major challenge. In fact, the manual effort involved in making those migrations is one of the primary reasons many organizations continue to employ older versions of frameworks such as Java 8. OpenRewrite is designed to automate that process at scale in a way that leaves it up to the individual developer to determine how involved they want or be or if they simply prefer to have a DevOps team manage the upgrade process on their behalf, said Schneider.

    In the longer term, Schneider said he expects recipes will be created to address everything from mass migrations to remediating specific types of vulnerabilities across an entire codebase.

    Too much reliance on legacy development frameworks generally stymies innovation. The latest versions of Java, for example, are designed to make it simpler for developers to build microservices-based applications.

    It remains to be seen to what degree DevOps teams will embrace automation to upgrade code. Many developers are hesitant to rely on automated tools of any kind. However, given the need for most developers to spend more time writing new code, it’s only a matter of time before most of them come to terms with automated approaches to updating existing code.

    In the meantime, the cost of supporting legacy frameworks should decline as organizations begin to migrate their codebases faster. One of the reasons there is so much technical debt in the enterprise is because different development teams tend to adopt different framework versions at different times. DevOps teams can find themselves being asked to simultaneously support multiple versions of the same framework. There may always be multiple versions of those frameworks, but, over time, DevOps teams should eventually see the bulk of deployed applications all using the same framework as the upgrade cycle becomes more automated.

  • Accelerate Your SDLC With DevSecOps

    Accelerate Your SDLC With DevSecOps

    DevOps has been the answer to rising software development complexity, but the granularity and multiplicity of actors, technologies and environments brings added security requirements. Moving to DevSecOps will not only help with these requirements but also accelerate the software development life cycle (SDLC).

    As development projects mature, more developers get involved, the code base grows and architecture becomes more complex; consequently, the SDLC slows down. This is why Agile, microservices and DevOps have emerged—to solve this specific problem by separating big teams into smaller ones and monoliths into more nimble components.

    But this granularity and multiplicity of teams, work environment, technologies, services and repositories makes integrating security even more complex. In fact, developers now face multiple SDLCs and often, the gains achieved in velocity can be nullified by security issues. You want a process that works, and preferably, a process that works fast.

    This is what DevSecOps attempts to solve; adding security into DevOps actually accelerates the SDLC. Here’s why and how.

    DevSecOps During the Planning Phase

    The planning phase is key as it answers essential questions at the time when architectural decisions are made. Some of these decisions are relative to access control, network infrastructure and data security. For each, adding automation—and therefore, security—allows fast replication.

    For access control, you can leverage infrastructure-as-code (IaC) tools (Terraform, for example) to easily define different groups, roles and permissions with code. By adding various plugins, you can even use your IaC tool to manage users on other platforms, as in GitHub. When you have all the groups, roles and permissions defined as code, you are only one commit away from access control updates.

    If you need to onboard a new team member not only to, say, a specific AWS group but also to a GitHub group, instead of doing it manually in two places, you can do it “as-code” to both with minimal changes.

    The complexity of organizations and the need for better security implies the need for more role-based access controls, but automation tools exist, and they are also less error-prone.

    When it comes to network infrastructure, you can also use IaC, but you will also need to add a security layer on top of it to mitigate any errors in the code. As an example, you can use tfsec and terrascan on Terraform. This will scan your code statically and, based on predefined rules, generate alerts and give you advice on improving your security. If you prefer CloudFormation, use cfnlint, which even allows you to define your own security rules.

    When you have your infrastructure ready, the next big thing to think about is your data. You need to put data encryption in place to make sure data is securely stored at rest. You also need to add transport layer security (TLS) for the databases to secure the traffic in transit. Besides using static code analysis tools and ready-to-use services, you can even automate your own pipeline. This is very useful when you have multiple agile teams.

    Let’s take S3 buckets as an example. You could build a generic solution where the S3 event triggers a serverless function that checks the bucket’s permission. If a policy is violated, it can be fixed right away and the owner notified automatically.

    Moving to Development

    During the development phase, you need to address three major security areas: Code repository security, continuous integration (CI) security and container image security.

    Code repository security needs to address questions around the repository access control, considering the principle of least privilege but also checking that no repository is made public by accident or that they do not contain sensitive elements, such as secrets.
    With a multi-team, agile and microservices setup, you need automation to skip time-consuming and error-prone tasks but also to avoid slowing your SDLC to a crawl. We already mentioned git user management automation, but there are also a number of tools for static code analysis and secrets detection. You can even include this detection in your CI pipeline and integrate it with your alerting workflow to eliminate the risk from the origin.

    CI security is often overlooked, but this is a very important element; if your CI is not set up correctly it can generate data leaks. Access to your CI needs to be controlled to give the proper permissions and access rights. Doing this manually will definitely impact your SDLC velocity so, again, there’s a need to automate. You can integrate your CI with your Git or company single sign-on (SSO) solution for authentication. For authorization, you may rely on the groups’ information provided by those SSO services.

    Secrets are also critical for CI. Modern CI pipelines allow you to store secrets at a project level. Once configured, you can use it directly in the build without putting the sensitive data in clear text format. Even if you try to print the variable containing sensitive data, it will not show up. For instance, to use secrets directly from a Jenkins pipeline, you can store your secrets in a Kubernetes cluster and use Kubernetes Credentials Provider or HashiCorp Vault Plugin.

    Now, let’s talk about containers. While containers have simplified the deployment, scaling and failover capabilities within the SDLC, they also introduce some challenges. If the container image has some known vulnerabilities, your containers could be exploited, and the integrity of the whole machine—or even the entire system—can be compromised. Automation is, again, the go-to solution to ensure the images you build don’t contain vulnerabilities. Some CLI-based tools like Trivy can be easily integrated into your CI pipelines.

    Automation will significantly reduce your operational overhead. No more managing machines (physical or virtual), no more configuration management, no more patching. If everything is automated, that means less toil—and that means all means your SDLC is not only more secure but also faster.

    Integration and Deployment

    Kubernetes (container orchestration) is the current solution to streamline integration and deployment in our agile world. But Kubernetes is a complex system and comes with its own security challenges, of which the most important is secrets.

    The worst thing you could do is define secrets in YAML files and store them in Git repos. You could use Kubernetes’ secrets as the single source of truth, but what about secrets created by people who don’t need access to Kubernetes? This is where a secrets manager is a good choice: It acts as a single source of truth to store your sensitive data. You will get an automated process that eliminates the toil of manual labor but also guarantees security and speed.

    DevSecOps for Incident Response

    Incident response playbooks are a crucial component of DevSecOps. Playbooks are a set of generalized and summarized processes that provide a consistent way of handling issues for quicker response and resolution. Learning from every incident is also part of the playbook, whether it’s a security issue or a new vulnerability.

    The content can include everything from runbooks and checklists to templates, training exercises, security attack scenarios and simulation drills. The goal is simple: A set of policies, processes and practices for quickly responding to and resolving unplanned outages, thus helping teams fix online issues more quickly to reduce the size of the blast radius.

    We have only scratched the surface of security automation capabilities and their potential impact on the SDLC. But it’s clear that adding (automated) security into DevOps has a positive impact on the overall velocity of the SDLC and, of course, on its security posture.

  • Making Blockchain-Based App Dev More Accessible

    Making Blockchain-Based App Dev More Accessible

    Blockchain has many potential uses cases outside of cryptocurrency. Established sectors such as financial, automotive, supply chain, and mobility could soon move to adopt decentralized applications and distributed ledgers. The technology has even been hailed as the ideal foundation to maintain a connected economy once humans go interplanetary.

    Recently, spectators note a swelling interest in decentralized, peer-to-peer, autonomous development approaches. Eyeing the excitement around cryptocurrency and blockchain, many developers are eager to start experimenting with their own blockchain-based applications. This incoming disruption could remove the middle man and give power back to people, says blockchain and cryptocurrency entrepreneur Max Kordek.

    However, building your own blockchain from scratch is incredibly difficult. So, I recently met with Max Kordek, co-founder, Lisk, to understand how to make blockchain-based app development more accessible. According to Kordek, there are many benefits to creating your own blockchain, but simplifying the creation process will be necessary to empower new startups and enable this new paradigm to flourish.

    Potential Use Cases

    The decentralized, tamper-proof nature of blockchain has disruptive potential to remove central authority and give more data control to the collective hive. “For me, it’s all about removing the middle man,” said Kordek. “It gives power back to the people.” Cryptocurrency is obviously the most widespread use case; Bitcoin is proof that a blockchain-based system can see mass adoption. But there are many other use cases outside of cryptocurrency where similar record-keeping is important.

    For example, the automotive industry could link data across manufacturers or share data between vehicles. NFTs are using blockchain to represent one-of-a-kind digital art objects. The airline industry is looking to blockchain to synchronize partner ecosystems. Blockchain is also transforming online gaming by substantiating in-game value systems.

    From insurance to supply chains to transportation, most industries hold a potential blockchain use case. But blockchain isn’t constrained to only terrestrial scenarios. Information systems engineers foresee blockchain powering future in-space economies. With significant funding going toward asteroid mining and Mars missions, an interplanetary humanity seems inevitable. Compared to Bitcoin, “Ethereum is a better choice for the interplanetary economy,” said David Vandervort. Gathering transactions in blocks and pinging satellites could enable monetary transactions from planet to planet. “An interplanetary financial system would have to be built on blockchain technology,” Kordek said.

    There is ripe potential in countless areas. But who will be leading this shift? According to Kordek, we may see corporations augmenting existing structures with blockchain. However, established enterprises will find it challenging to unshackle themselves from legacy systems. Instead, new startups are more likely to have a bigger say in the blockchain revolution. “It’s much more realistic that an entirely new startup adopts blockchain and structures their entire business around blockchain,” said Kordek.

    The State of Blockchain Development

    After Bitcoin was established, other developers forked the project and changed parameters to introduce new cryptocurrencies, such as Litecoin and Dogecoin. Eventually, Ethereum came along, which was unique as it enabled developers to build apps with smart contracts. However, “the developer ecosystem was horrible at the beginning,” explained Kordek. “It was the wild west of development.” To this day, it’s still very complicated to develop on Ethereum, he added. Plus, since it is open source and immutable, it’s vulnerable to security threats. “It’s like the biggest bounty program in the world—if there’s one bug, contracts are drained.” Ethereum also has scalability issues — it can only run 30 transactions per second, equating to 1 million transactions per day.

    For these reasons, it may be better to build your own blockchain. However, doing so is a difficult task. From a research perspective, this requires a lot of theoretical knowledge, Kordek explained. Blockchain also introduces new maintenance concerns—since the infrastructure is always on, it is unstoppable, making patching a bug or pushing an update tenuous at best. If hundreds of millions of dollars are dependent upon a stable network, one mistake could have drastic repercussions. The high development and QA roadblocks make prototyping blockchain-based systems from scratch challenging. “Experimentation is essential to bring an industry forward,” said Kordek. “It’s important we simplify blockchain development so more experimentation can happen.”

    Open-Source SDKs Make Blockchain More Usable

    So, how do we make blockchain more accessible so that experimentation can occur? Well, a lot of progress has already been made via ready-made open source language-specific SDKs. For example, there’s Polkadot (Rust), Cosmos (Go) and Lisk (JavaScript). Kordek is an advocate for language-specific libraries that fit a team’s programming preferences. Out of these, he favors JavaScript, as it’s generally easier to learn and already supports many web-based interfaces.

    These projects are not about the smart contracts themselves; they’re about improving your own blockchain creation process. According to Kordek, going down this route grants more control in the early days. If something is broken, you can fix and push and update. If tokens are hacked, you could roll back and adjust things, he said.

    As companies get bigger and bigger, the technology could have a centralizing effect. “How can we somehow bring power back to people?” asks Kordek. Blockchain is one profound answer, empowering new entrants to alleviate problems across industries — it could even help us boldly go where no one has gone before.

  • EP 12: DevOps Unicorns

    EP 12: DevOps Unicorns

    What should you look for when choosing a DevOps vendor? What criteria are others in your industry using to inform their decisions? How do you choose a vendor that is a good fit for your organization? And how do you know if you made the right choice? In this episode of DevOps Unbound, host Alan Shimel welcomes Larry Maccherone of Comcast, John Willis of Red Hat, Ravyn Manuel of the Smithsonian, Garima Bajpai of Capital Carbon Consulting and Mitch Ashley of Accelerated Strategies Group for a panel on DevOps unicorns. The video is below, followed by a transcript of the conversation.

    Alan Shimel: Hello, everyone. Welcome to another edition of DevOps Unbound, where we talk about DevOps, hence the title. Thanks for joining us. This episode is titled DevOps Unicorns: The Quest for End-to-End DevOps.

    You know, I’ve been in IT 30-plus years and there’s always been this tension or this pendulum that swings between the one throat to choke versus the best of breed solutions in any area. Today it’s DevOps and software delivery and deployment. But in anything, in the security world, in everything, in hosting, in infrastructure it’s always been a common theme. But it’s really, really becoming acute within the DevOps sector now. And we’ve assembled what we think is a great panel to discuss this issue. Let me introduce you to them and we will go from there.

    First of all I want to welcome, well, to a panel for the first time in a long time, my friend Larry Maccherone. Larry, welcome to DevOps Unbound. Give people a little background, if you don’t mind.

    Larry Maccherone: Sure. Thanks for having me here, Alan. First of all I want to say so I launched the Dev PsychOps Transformation Program at Comcast and grew that for five years. And I’m a developer at heart, though, so I was sort of the ideal person to take what was actually becoming more common outside of big enterprises, Dev PsychOps, and try to actually do a diverse approach inside of a large enterprise like Comcast. And so all of my experience is around that recently, the last five years or so, around that.

    Shimel: Excellent. Next let me introduce you, she’s a repeat visitor to DevOps Unbound. Garima, if I mess up your last name I apologize in advance, but Garima Bajpai. Close?

    Garima Bajpai: Almost. Yeah. So I’m Garima Bajpai. I’m based in _____, Canada and I’m the founder for the DevOps Community of Practice here in Canada, which has three chapters: Toronto, Ottawa, and Edmonton. I’m also the organizer of the DevOps Summit in Canada, which happens in November 8th and 9th. And I’m also associated with organizations like DevOps Institute as an ambassador, as well as CD Foundation as an ambassador.

    Shimel: Fantastic. And, Garima, I apologize on your last name. My bad. I’m trying to read it and the monitor’s too far away from me without my glasses. But thank you for correcting me, and welcome.

    Next up, another good friend of mine, my actually business partner on Digital Anarchist. And though that’s not his full-time gig these days; he’s very busy with his red hat career. The one and only Botchagalupe, John Willis. John, welcome.

    John Willis: Thank you, sir. Thank you, Alan. Hey, yeah, John Willis, Botchagalupe on Twitter. My current day job is in a team called Global Transformation Office at Red Hat. I’m sort of blessed to be on a team with Andrew Clay Shafer; Kevin Behr, the co-author of The Phoenix Project; and Jabe Bloom. Just quickly, you know, I’ve been in the industry for 40-plus years, 10 or 11 startups, 12 books, if somebody’s counting. Probably the most notable is the co-author of DevOps Handbook.

    Also was involved in basically the starting and building of the original DevOps Days. Was the only American at first DevOps Days and Damon Edwards and I created the first DevOps Days event in the USA.

    Shimel: Yep. And that’s only a partial list, John. Thanks for joining us today, man.

    And then I want to introduce – she’s off-camera right now, but hopefully when you’re watching this at least you’ll get to see her picture, but she was having some video difficulties, but happy to have her on audio, my friend, Ravyn Manuel. Ravyn, welcome. And if you wouldn’t mind, give people a little background.

    Ravyn Manuel: Thank you, Alan. I do appreciate being on your show. It is awesome. It makes me laugh. I am the senior application developer for the National Museum of African-American History and Culture. And I’m also the DevOps engineer for that particular unit. As a developer I implement some of the hands-on interactive that you play with in the museum, and as a DevOps engineer I am in charge of just about everything that’s DevOps, from the cloud solutions and how we – from the application development side, how we’re using cloud and the tools and writing strategies and keeping my leadership informed of all the good things that are out there.

    Shimel: Fantastic. Ravyn, welcome and thanks for joining us today.

    Last but not least, my co-host here on DevOps Unbound, Mitch Ashley. Hey, Mitchell, welcome. You want to just introduce yourself?

    Mitchell Ashley: Great. Great to be here. Man, what a panel. I am so excited to be with these folks on today. Yeah, I head up Accelerated Strategies Group, analysts from focusing on, of course, DevOps and digital transformation, full cybersecurity and cloud. And I also serve as CTO with MediaOps, so heading up the platform strategy and technology, so we used to deliver programs like this.

    Like John, I think we’ve been probably in the industry about the same amount of time and have zero books to my credits, so he’s made a lot more progress in those areas, but also a startup person and run a lot of software projects, product, as well as IT groups, as well as on the vendor side. So this will be a fun discussion.

    Shimel: Absolutely. I should mention DevOps Unbound is sponsored by our friends at Tricentis. To give you an idea of what a great sponsor they are, they don’t even have anyone on our panel today. But they do enable this show to go forward every other week, so many, many thanks to Tricentis.

    So, John, I laid it out, right, it’s the one throat to choke versus best of breed, how many vendors can we support, how do I package solutions that are more than just point solutions, or maybe I just want point solutions. What’s the answer here, John?

    Willis: The answer is, Alan, I would say if I had the right answer I’d be on a Grady-White right now in the Gulf of Mexico.

    Shimel: Exactly. And I’d be right with you.

    Willis: But no, I think this is a great panel. I agree with Mitch; I’m excited about just the discussions we can all have. I think the question – you know, I was thinking just that sort of Chinese curse translation, “May you live in interesting times,” right? And that’s clearly where we are right now. And I think your question starts with a shift, right? Like there was this – talking about you, Mitchell, some of us have been here forever, and like back in the day there was this question of one throat to choke versus should I do an ELA with computer associates versus piecemeal things, right? And probably less than one-percent of the enterprises were do-it-yourselfs.

    Now today you will find probably – I’m just going to swag the number, but it’s probably north of 10, maybe 15-percent, maybe even higher of companies that are now being challenged to do it yourself. You know, Kubernetes is a great example. That’s a can opener for companies to make a decision of are my vendors keeping up with what comes from basically sort of upstream technology that I should build myself.

    So I think that’s the sort of question we move into, is more about do you build internally to solve your problems, to keep up with the changes in the market and the technology, or do you try to find a pair of vendors or a single vendor – and there really is very few single vendors that can give you the whole scope of what’s going on in modern technology today. But I think that’s the question that I think we’ll have fun just talking about today. _____.

    Shimel: I don’t disagree. Panel?

    Manuel: So, Alan, this is Ravyn. I agree with you, John. I think one of the things – because that’s a struggle for me and my organization, is we need help with implementing DevOps, but I think the vendors are very tool-focused and the tools are like the third priority in the stack of there. And what I’ve been doing when I’m building the strategy for how we’re going to implement DevOps, I looked, and we’re talking about tools. I look at the standards, because if they’re making standards and the tool has to follow that standard then it’s plug-and-play, you don’t get – like if Docker decides that they’re going to go out of business then you can have another container-type technology to do that.

    So when we are looking at benders we actually kind of do a piecemeal, because we’re really unicorns. We’re not a software company, we don’t have software products; we have digital products, and they’re all one-offs. And so it really just depends on what fits for us. So we don’t really go for the one vendor solution; we actually go for who can help us get to where we need based on our business problem.

    Bajpai: Excellent. And I wanted to add a few things, because when we drill deeper into this conversation we will find out that there are two sides of this coin. One part is where an organization from a maturity perspective is. And the second thing is what are the vendors and key capabilities you’re looking at. But if you look at both sides of the coin there are three things which are needed to calibrate these DevOps tools in the overall context. The first thing, and this is – I want to reiterate the fact, because I come from a very large complex organization background, that it is very essential to have an enterprise architecture view. So I would suggest and recommend that before even, you know, taking this approach of single vendor or multivendor discussion, we need to kind of break down what are the key capabilities which are needed. So whether it’s a single vendor which can provide you that enterprise IT architecture capability, or it will be your organization who will be doing it. So that’s essential.

    The second thing I think which is also essential is orchestration layer. You know, you will have to have that governance of total cost of ownership, compliance, security, identity access management, and that orchestration layer has to be there to stitch all you calibrated DevOps tools. So it’s a question of whether you want to kind of build it in house in that organization or you kind of have a vendor-centric approach where this capability should be or could be brought in.

    So these are like two things, and then you start calibrating these DevOps tools. So you don’t have to look at the foundation aspects of compliance, security, governance, total cost of ownership, and the job becomes much more easier. The question is that, you know, how to bring these DevOps tools and enable business value.

    Maccherone: So I want to riff off of that orchestration layer idea, but I want to backtrack a little bit on sort of the – we have a binary sort of difference here between unicorn and best of breed. But I think within the unicorn bucket there’s really two major flavors of unicorn that are wildly different, and so I want to sort of bring that out. You have these Frankenstein vendors that are piecing together acquisitions into this monster and those are not pleasant experiences. The only benefit you get out of one vendor in that case is really the contracting benefit of having a single master service level agreement. You’re not getting an integrated product that really allows you to actually smoothly do the workflow, insist in the workflow that developers are using to produce value for your company.

    And then you have this other class of unicorns in the DevOps world, but less so in the security world, and I’ll talk about that in a second, which have taken a marketplace approach. And this is not a DevOps vendor, but I think the first vendor to really pull off this marketplace approach was Atlassian. You know, they had one product that was really great, but they said, “Okay, plug into this product” and they created APIs and they created toolkits and they created a whole community. Most of those people did it for free and they just sort of did it for themselves and then they shared it with the community. But some of those people became vendors and sold their product in the Atlassian marketplace, and then Atlassian acquired those. They were already pre-integrated with Atlassian’s other offerings when they got acquired, and so their acquisition unicorn approach doesn’t look like a Frankenstein’s Monster in the end, because they were built with the APIs of the vendor in place.

    And I think Github is definitely taking that marketplace approach and pulling it off really well, even into the security space. And so I think that kind of unicorn – and Github to a lesser degree, that kind of unicorn doesn’t suffer from that Frankenstein Monster’s sort of problem. No one in the security space has really pulled off the marketplace approach yet, though. We have some Frankensteins and Frankenstein Monsters over there, but we don’t have a full sort of marketplace approach. And I’m waiting for somebody to do that. I think that’s going to be the big win, somebody _____.

    Willis: I’d like to do a whole podcast on that, because that’s all I’ve been thinking about right now, is what is the end-to-end on security. But like if I got into it now it would take up way too much time. So I did want to comment on some of the things. You know, the first, Ravyn, I think the interestingly about standards, I agree, right? The problem we have right now is figuring out which standards are actually going to last, are malleable. I mean that’s one of the things I’ve really been working hard on and looking at like OSCAL versus OVAL versus S-CAT versus, you know, just NIST _____ – in order for – I mean there’s just so many things and they all sort of have a little bit of different approach.

    So I agree, the question we have to deal with now in these sort of, you know, may we live in interesting times is it’s like picking sort of an early vendor, like I like this vendor technology, but are they going to be around? Are they going to be acquired by a company that I don’t really want to do business with? I think the standards is just it’s such complicated.

    Just the other thing I wanted to say is I think that for vendors, you know, and I’m not _____ ’cause I work for Red Hat. Because I will say right now the thing that like in the grand scheme of technology, if you’re going to go all in a vendor, look around. You know, I’m going to say this. I’d love to be corrected and I’m not saying, you know, Red Hat because I work at Red Hat. Anybody that knows me, I’m not a shill for any vendor I’ve ever worked for. But it’s VMware and Red Hat, right? They can keep up with – because you’ve got to – in this world you have to have people on staff, their full-time job are contributors to an open source project.

    And if you think about what’s going on with like Kubernetes and clusters and server list, you know, you think of the two companies that are positioned really well at that sort of scale version to be able to keep up with the complexity and change of technology because they’ve put the resources in. I mean a longer list that you can probably make after that. And I’m not including the cloud providers either, ’cause that’s a different story.

    But anyway, those are the two comments I wanted to make on some of the things people talked about.

    Ashley: I just wanted to jump in. What’s fascinating about this conversation is how diverse and complex it is. There are a lot of aspects to consider, whether it’s an enterprise architecture like Garima is talking about, John’s talking about, who are the vendors that can pull it off. Larry is too, if you’re talking about this sort of roll-up strategy, but retro-ally integrated strategy.

    I think another dimension to consider is every organization has a DNA about how they think and operate when it comes to vendors and software and tools. And while I’m not always an advocate of go with the flow, sometimes when you’re thinking about how do we have something adopted, think about how the organization operates. If you are kind of a large tool vendor, let’s work with, you know, Red Hat or VMware or Broadcom or whoever might be – think about that. That’s oftentimes, you know, save yourself some brain cells and live a little longer.

    There’s also the innovation curve, and some of the best ways to ride the innovation curve is the open source route and the vendors that are built around that kind of a strategy. There’s combinations of all those.

    So I guess the thing I would add to the consideration of the conversation here is think about how you match up your strategy with the DNA of the organization so you can accomplish as much without killing as few brain cells as possible.

    Bajpai: And thank you, Mitch, for bringing up this point of DNA of an organization. I think that this is a pathway of dialogue which we are having. I do believe that the mindset is shifting, and even I see in large legacy enterprises that they have started to realize that, you know, this vendor-based approach is something that needs to shift, and they need to bring people as partners in this context. Because when you think about DevOps it’s basically exploring your opportunities, breaking the barrier for, you know, your technology onboarding, the gaps – the alignment and outcome gaps you have created in the past.

    I think this is the opportunity where the organizations can shift and bring more access to innovation through these partners. So I truly believe that there are softer aspects of this conversation as well which we need to kind of consider that traditionally how contracts are _____, you know, how we look at these DevOps tools from a vendor perspective, how can we bring them as partners, what we need to change if we start doing that.

    It’s not kind of done overnight, right? So we have to kind of set what kind of modeling practices we need to bring in. And this opens up another door of possibilities. And probably during this conversation we will have some opportunity to discuss these SLA constraints which we have built in the organizations which steer us to a specific vendor or steer us to like a specific window through which we can outsource a lot of capabilities and just, you know, a choke the throat approach, right?

    So let’s maybe in the upcoming discussions we also can bring these points and highlight.

    Shimel: Ravyn, I know Smithsonian is sort of quasi-government, or it’s not true government. But to Garima’s point about SLA and being able to only deal with chosen vendors like that, it is; it is a real governor on your ability to choose best of breed, on your ability to have choice in how you want to do things. Interested in your experiences around that.

    Manuel: It’s been difficult. I’ve been listening to this conversation and it just hit – I don’t know why it just hit me, but the vendors – and I love Red Hat, so I’m not trying to talk Red Hat or anything, and open-ship. But when you get a vendor that you have worked with and you trust, and Smithsonian, we use Red Hat a lot in our OCIO. Red Hat is doing open shift and Kubernetes and they are driving their tools to these specific tools. And for me, as a unit within the Smithsonian, I may not want to use open shift and I may not want to use Kubernetes, but I don’t actually have a choice, right? Because that vendor is a great vendor and they’ve got great tools, but they have chosen for me what I am going to be using, and that makes it really hard for me to say “Does that really fit what I really need? Is that too much?”

    Because I can tell you that a lot of the vendors that I talk to, they’re expecting us to use this like suite of products, and it’s too much for what we want to do, and so I’m left with I either go with this vendor and overspend and use tools that I don’t really need, or I have to do it myself because I can’t really find somebody that can customize that for me. So it’s a challenge.

    Shimel: Yeah, it sounds like it.

    Willis: You know, one of the things I struggle with, you know, I sort of love committees and hate committees, right? Because like I so – HashiCorp has this cluster manager called Nomad, and I’ve actually seen people use it effectively with like incredibly less toil, 80-percent of the features of it, but it’s never going to get any escape velocity. It hasn’t and it won’t.

    And I fear for our industry that we’re like so focused on there’s just only one way to do cluster management today where like – so to Ravyn’s point, like whether it’s Red Hat or whatever, it seems like you’re not even able to explore possible emerging containerized cluster management solutions because all of the oxygen in our industry right now is consumed by Kubernetes.

    Manuel: Amen.

    Shimel: Thoughts on that? I’d like to jump in with some thoughts on that. I mean this is sort of a dream/nightmare scenario. Right? I’ll take it – let’s take it off Kubernetes, let’s go back to PC operating systems. It was great that we had only Windows to develop on, and this way if you were an inept developer you only had to worry about developing on Windows. You had one operating system, you could make your app on it and it worked and you got 90-percent market share with it. What a fantastic thing for app developers. Of course, it gave Microsoft the inside track on Office and everything they did. And from a security point of view what a big, fat juicy payload that was, right, to go attack.

    So then we started seeing, for as long as I’m in IT, “This is going to be the year of the Linux desktop.” Right? How long have we heard that? And so, you know, and then of course Mac resurfaced.

    But this is we strive for some uniformity. We strive for Kubernetes to be the standard, ’cause it’s open source and it’s run by a foundation, and we want a standard. But then we chafe that, “Hey, we all can’t fit into that same standard. We want to be our own unicorn.” And that’s really what we’re talking about here today. If you go back to early, John, you sold the company to Docker before Kubernetes dominance, right? And there were several cluster management solutions vying. Right? There was Mesosphere and Rancher out there _____.

    Willis: Mesosphere and _____, yeah. [Laughs]

    Shimel: You remember. Yeah, _____ of these, exactly. So, you know, this is – but this is the world we – you know, to quote Hyman Roth in the Godfather II, “This is the world we chose to live in,” right? We strive for these single kind of standards that one-size-fits-all. And maybe that’s a huge mistake; I don’t know. Maybe it is a mistake. Larry, what do you think?

    Maccherone: Yeah, I do see that problem, John, you’re sort of focused on here, that sometimes the de facto standard is not the best technical choice. You can go all the way back to Betamax versus VHS, for those of you who are old enough to remember that, right? VHS won out, but Betamax was considered by everyone to be a superior technology. Why?

    You know, so I think if you’re going to take a best-of-breed approach you’re going to have to – when you have a true de facto standard like Kubernetes you don’t have to isolate yourself from it, but when you’re making a bet on which one is going to win out – and John is really good at this; John talks about this all the time. John sort of like doesn’t want to put his chips down on something that’s not going to survive long-term, so he wants to think about what’s going to survive.

    So in order to hedge your bet there I think you need this orchestration layer that was talked about earlier. You need to sort of isolate the tool vendor from the way it’s consumed to a certain degree, so you can plug-and-play a little bit as time goes on. And this is what we did at Comcast, we built a layer between all of the tool vendors for security tools, because they don’t have a good unicorn solution there. There is no good unicorn solution there anyway, even if I wanted to. And so we had more than one vendor in every tool category competing internally, and sometimes we had three tool vendors. But from the developer’s perspective it was really easy for them to switch out from one to the other, and they got the same feedback channels, they got the same visualization, it aggregated and scored the same way across all these different vendors.

    I think that orchestration layer is really key when you have a best-of-breed approach, and I think you have to build it yourself. I don’t think you can buy it today. I really don’t think you can do that.

    Willis: I’ll try to shut up quickly. I just want to make a comment. I think there’s two books that help us understand our world. One is Guns, Germs, and Steel by Jared Diamond, which actually shows you why we get into these predicaments. If you haven’t read it, it’s a fabulous book. And then Start With Why by Simon Sinek is the sort of anti-pattern to that, which I would say like there’s clusters – atomic computed things like sort of serverless or functions or containers will be around for 10, 15 years. Clusters of those things will be around for 10 years. So if you think in those terms instead of thinking about Kubernetes and Docker – and Docker is already slowly dying, then you get that sort of start with why isolation against these sort of Guns, Germs, and Steel trends.

    Bajpai: Right. Then I also wanted to kind of bring another aspect of this, which is connected, but I think companies might start looking at it from a scaling perspective. We talk about a lot of tools and how to calibrate these tools in our DevOps pipeline. Of course when you have a large organization you have multiple product lines, and these product lines will choose to be flexible, so they need to have that flexibility to deploy their DevOps pipeline in the way they choose. And that’s the whole power of DevOps, right?

    But I also feel that the conversation in this discussion is leading us to a point where we start looking at our technical oversight committee from a governance perspective, where we can stitch the dots, we can actually lay that common foundation which is required in order for people not to kind of rewind the _____ over and over again. So I think that’s the key here.

    And of course when we talk about a specific random _____ with huge capabilities it has pros and cons, right? So one pro would be like they can mutually enforce new capabilities. So when they bring one feature in one product it’s mutually enforcing another product, which is a beautiful advantage they bring in. But that also limits our possibility to look beyond what the vendor is bringing in. So we are kind of essentially not exploiting our own innovation cycles to introduce more capabilities around how we want to experiment, how we want to kind of build innovative new features into that life cycle.

    So these are kind of good considerations to look at and I truly believe that the technical oversight committee is something that you will see in large organizations a wave kind of starts in a bigger way when it comes to DevOps.

    Ashley: And there’s interesting too, when you think about different sizes of companies that are in the market for technologies, you know, Larry mentioned what he did at Comcast or what he was part of that was created as sort of an architecture where tools can be plugged in, unplugged, replaced, etcetera. It sounds simple, but I know that they have an architecture to do that. And some organizations have the wherewithal to create those things. What we see in the data, looking at the market, is in the small business, the kind of sub-200 people or so companies, they have really good high-performance teams that can work to create software or set up their own environments, kind of create a very productive setup for themselves, tool chains, etcetera.

    Then on the high end or the large end, the enterprises, you know, they have a lot of resources available to them that they can potentially marshal to figure out how to do some of those things. The mid-tier market, the medium-sized company is often where they’re most challenged to – they want to do what the enterprise can do, but they just don’t have the resources. They don’t have the money or the vendor relationships across the board to do all those things and they’re expected to deliver at almost an enterprise-class level, but they don’t have all of the resources to be able to do that. And that’s often where somebody – the non-Frankenstein vendors that do a good job of kind of delivering a suite of solutions can work in those situations. Not that they can’t work in the others; they can, too.

    But depending where you are in that kind of a company, that size of a company, makes a big difference on what strategy you can take.

    Maccherone: I think that’s a great point and my recent experience last five years has really been enterprise. But prior to that I was talking to lots of companies, and you’re right, the mid-sized companies are the ones that are sort of in that no-man’s land sometimes, where they need some standardization, they need some consistency, but they don’t have the wherewithal to put it all together. And a vendor unicorn approach might actually be better in those circumstances.

    Shimel: Hey, guys, I want to – Ravyn, I’m going to let you in a second. John, the name of the first book that you mentioned – I want to put these books in the notes somewhere.

    Willis: Oh yeah. I did a presentation with Josh Corman way back with Guns, Germs, and Steel. Anyway, it’s an amazing book about how civilizations move from sort of – you know, how they go from sort of agriculture and they move into these clusters. If you can see the forest beyond the trees you can see how we get into these like Kubernetes is the only word we can use. Anyway, Jared Diamond, Guns, Germs, and Steel, it’s incredible.

    Shimel: All right, we’ll try to get it in there. Ravyn, did you want to say something and I cut you off?

    Manuel: No, I don’t think that was me.

    Shimel: Garima?

    Bajpai: Yeah. I wanted to actually enhance what Larry was saying about midsized companies. This is totally based on my experience and exposure with the Canada DevOps Community of Practice. We are seeing more and more of these midsized companies, not only the consulting companies, as well as the companies who want to build a DevOps capability coming to the community of practice and starting to steer this discussion of evaluation and assessment of tools. And I’m also seeing that the winter side. You know, specifically we are talking about tier two companies here. The winters and coming and exposing the tool capabilities in the community of practice, and they want some support and help for us to kind of steer this conversation “Is this a good tool? Is this a good capability where they are in their context?”

    And it’s a very interesting discussion because the technical side is one side of the story. I would also like to kind of emphasize the fact that the questions we ask these vendors and these companies are like, “Okay, do you have a product owner for this product?” Because essentially, you know, what it means is that how accountability is built in a specific tool perspective. I also kind of ensure that we ask them what kind of themes they have, like what kind of cross-functional themes they have, so that we do not miss out on the point of interoperability, integration, automation, all these like are important points.

    So I just wanted to mention that how we take that approach from the community of practice perspective when we’re asked to kind of assess.

    Willis: You know, I totally agree with all of that. One of the things I was thinking about, I’ve had this luxury of being involved in these different communities. Like I’m in Alan’s community, you know, so I’ve gotten hooked into usually what’s interesting and going on in Alan’s world, which is a pretty big world. I’ve been hooked into Gene’s world pretty heavily, you know, DevOps Enterprise Forum/Committee. And then, you know, I’m one of the co-founders and advisors for the DevOps Days.

    And one of the things that I get to see is true leaders. And I don’t want to put all this sort of weight and gravity on like you have to have a great leader to be successful, but like as I think about the people – Larry is a great example. Like, you know, you can talk all day long about what Comcast does. I’ve seen Larry in action. Like that’s the kind of guy you want in your enterprise.

    Courtney Kissler now, you know, was at Nike and now she’s moved on to a startup. Ross Clanton now at American Airlines, Heather Mickman. I mean I can go on on the list, but these are people that impact change in larger organizations that where it’s incredibly hard. And there’s just something about that.

    Maccherone: There is an immune system at large enterprises, though, that makes it hard for someone like me to actually be hired and be successful. You know, the idea of disruptive change is not something that enterprises are sort of seeking out ever. And so if you’re sort of like grassroots and you’re sort of like ground up and you get a few pilots going, that’s easy; there’s not a lot of resistance. It’s when you get enough momentum that somebody feels like their domain is threatened that you get the political pushback in an enterprise. And, you know, that’s really hard to overcome. Companies have to be very conscious about that. And Comcast has done a great job of that for me in the past, but I see it in the nature of the enterprise immune system essentially.

    Ashley: We probably could take any one of those last three comments and turn that into a whole other dialogue. Maybe we can get some help from the folks in the production department for pulling us back together.

    Alan, do you want to close this out?

    Shimel: One thing’s for sure, is we’ve got a lot more to talk about on this subject. I’d love to – I invite you all back to continue the conversation. But for now, Ravyn, I appreciate you soldiering through this on audio only. If we do it again we’ll make sure to get that video working. Garima, always a pleasure to have you on here; you bring so much. Larry and John, what can I say, it’s a pleasure to see you guys. I can’t wait till we can see each other in person. I know a lot of us have gotten our shots; it won’t be long. But thank you so much for adding so much. Mitchell, fantastic job.

    Most of all, hey, thank you people that are watching this, because that’s why we do this, is for you guys to get something out of it, join in the conversation, let us hear what you’re thinking. Many thanks to Tricentis for sponsoring DevOps Unbound.

    Until next time, though, this is Alan Shimel, Media Ops for DevOps Unbound. Have a great day, everyone. Bye-bye.

    [End of Audio]

  • Rocky Linux Emerges as a CentOS Replacement

    Rocky Linux Emerges as a CentOS Replacement

    Rocky Linux was created to offer the community an alternative following Red Hat’s recent decision to shift its focus away from CentOS—the open source version of Red Hat Enterprise Linux (RHEL). However, the Linux distro’s popularly can also be attributed to how its creator sought to offer a superior alternative based on lessons learned during CentOS’ development—and less as a perceived backlash to Red Hat’s controversial move, said Gregory Kurtzer, Rocky Linux’s creator, who is also founder and CEO of Ctrl IQ.

    “As one can probably imagine, there were a lot of lessons learned from the founding of CentOS—we did a lot of things correctly, but we made some mistakes, as well, that set into motion some of the difficulties the project went through,” said Kurtzer. “I was not—nor am I now—upset at Red Hat or anyone else. It’s important to understand that companies have a legal responsibility to do what they need to do. But I will say, this is why open source communities should not be controlled by a single company, especially if that company has a competing product to the open source project.”

    In addition to applying experience gained from the CentOS project to help “recreate the initial goals of CentOS in a new project,” Kurtzer said he was prompted to create Rocky Linux following Red Hat’s decision to end-of-life (EOL) CentOS. The move “affected my company, our customers, as well as the entire industry,” said Kurtzer.

    “To be blunt, my knowledge—in terms of doing it myself is severely dated. Luckily, after I made the announcement that I was considering recreating CentOS, thousands of people reached out to me wanting to be part of the project and contribute,” said Kurtzer. “From that, our development team and open source community was born.”

    Additionally, CentOS Stream offers value to the community by allowing “us and others” to take part in developing the upstream Enterprise Linux standard, said Kurtzer, who added that his team will continue to debug Rocky Linux so that solutions are properly integrated into the Enterprise Linux Standard.

    “The necessity was absolutely clear, so I founded Rocky Linux and the Rocky Enterprise Software Foundation (RESF),” Kurtzer explained. “Together with our contributors, sponsors and partners, we all have united for a common goal: to create an open source community that will provide us all with an enterprise operating system to stand the test of time, attrition and commercial agendas.”

    Interest in the development of a CentOS alternative was strong when Kurtzer first floated the idea of the project to the community. Since its release in June, the total number of ISO downloads is 56,000, according to Rocky Linux Tier0 mirror data.

    “We have zero visibility as to any other ISO downloads from any of our other mirrors, but if I were to guess, I’d say it would be about two to three times more, in total,” said Kurtzer. “When we all get a moment to breathe, it will be fun to see how many people are using Rocky Linux, and take in all the feedback the community has provided,” he said.

    With this team of developers,  Kurtzer said it took about seven months to build the general availability  (GA) release. “We didn’t just jump right into building the operating system because the goal was to create an infrastructure where many contributors and developers can take part without putting the security of the product at risk. Building that infrastructure took about four months,” Kurtzer said. “Once the infrastructure was completed, we spent about two months building the first-release beta candidate and then spent the following month ensuring that we did everything correctly.”